ai
51 TopicsWhen the Answer Isn’t in the Document: Metadata-Aware Agentic RAG with Foundry IQ
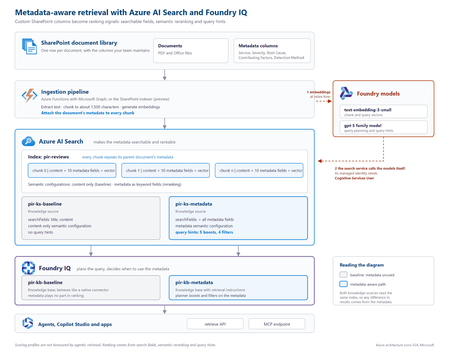
The problem SharePoint libraries often contain years of carefully curated metadata, including root cause, severity, business unit, document type, owner and classification. If that metadata never reaches the retrieval pipeline, however, a RAG system cannot use it. This creates a common blind spot: the information that explains what a document is about may exist in its metadata rather than its text. Consider an incident review containing this statement: “Investigation found that a DNS record was repointed during a migration while the old target was still serving writes.” The associated Root Cause Category is Configuration change, but those words do not appear in the document. Another review might mention that a configuration change was suspected and ruled out. Text-only retrieval can therefore favour the wrong document. In the sample dataset used for this project, none of the 19 reviews classified as configuration-change incidents contained the word “configuration”, while six reviews with other root causes did. Metadata does not improve every search. It helps when the information that determines what a document is lives outside the document text. Why tuning alone cannot fix it With a native SharePoint knowledge source, document text is extracted, chunked and embedded, while standard properties are retained. Custom SharePoint columns are not part of that ingestion path. Fields such as Root Cause Category, Contributing Factors, Detection Method and Severity therefore never become structured fields available to retrieval. If the metadata is absent from the index, search tuning cannot make it count. Flattening all metadata into a single text string is also problematic: Notification Service | Sev2 | Configuration change | Missing runbook This preserves the words but loses their meaning. A root cause, severity and contributing factor represent different concepts and should remain separate fields. Bring a custom Azure AI Search index The approach is to create and control a custom Azure AI Search index, then expose it to Foundry IQ as a searchIndex knowledge source. This combines metadata control with agentic query planning and a governed retrieval surface. Approach Metadata control Agentic planning Native SharePoint knowledge source No Yes Custom index queried directly Yes No Custom index as a knowledge source Yes Yes Architecture The key design principle is simple: every chunk carries its parent document's metadata. Figure 1. Metadata-aware retrieval architecture with Azure AI Search and Foundry IQ. The ingestion pipeline extracts a document, creates chunks, attaches document-level metadata to every chunk, generates embeddings and writes the records to Azure AI Search. Foundry IQ then uses the index as a knowledge source. Azure AI Search holds the metadata. Foundry IQ decides when to use it. Figure 2. Detailed implementation view, including the baseline and metadata-aware retrieval paths. At query time, the search service calls the configured models for vectorisation and query planning. Where key authentication is disabled, the search service's managed identity needs the required access. In the tested implementation, the Cognitive Services User role resolved HTTP 401 responses from retrieve requests. Put metadata on every chunk A chunk can only be retrieved and ranked using information available on that chunk. Each metadata property should therefore remain in its own field: { "id": "doc1035-000", "parentId": "doc1035", "title": "Notification Service: failed sign-ins", "content": "<extracted review text>", "rootCauseCategory": "Configuration change", "contributingFactors": "Missing runbook; Change outside window", "detectionMethod": "Customer report", "severity": "Sev2" } A separate metadata index does not solve the same problem because a match against metadata in one index cannot raise the ranking of a content chunk in another. What influences retrieval Four areas matter in this design: Search fields: searchFields determine which fields generated subqueries search. Semantic configuration: prioritised fields give the semantic reranker access to important metadata. Query hints: hints help the planner connect natural-language requests to known metadata values. Filters: a baseFilter or request-level filterAddOn can enforce constraints. Boost hints influence ranking without excluding documents. Filter hints can narrow the result set when the planner determines that a filter is appropriate. "queryHints": { "boosts": [{ "kind": "fieldValue", "field": "rootCauseCategory", "fieldValues": ["Configuration change", "Capacity", "Software defect", "Dependency failure", "Certificate expiry"], "boost": 3.0, "boostInstructions": "Boost when the user describes what caused an incident." }] } Hints are best effort. Hard requirements should use a base filter or document-level access control rather than relying on the planner to select a hint. The tested configuration used the 2026-08-01-preview API. Current documentation should be checked for supported models, limits and behaviour before implementation. Why can't vector search or semantic ranking solve this? This is probably the most obvious question: if embeddings understand meaning, and semantic ranking understands context, why do we need metadata at all? The answer is that vector search and semantic ranking solve a different problem. This approach complements them rather than replacing them. Vector search finds similarity, not recorded facts In a typical RAG pipeline, document chunks are converted into embeddings, numerical representations of their meaning. The user's question is embedded as well, and vector search finds chunks that are close to it in vector space. For example, a passage saying: “The gateway routing rule was updated shortly before the incident.” might rank highly for: “Find incidents caused by configuration changes.” That's useful. But it doesn't necessarily mean Configuration change was the confirmed root cause. The passage could describe an investigation path, a contributing factor, or even something that was later ruled out. Vector similarity is essentially asking: “Does this content mean something similar to what the user is asking about?” Metadata lets us ask a different question: “What was this incident actually classified as?” If the incident review already contains a curated rootCauseCategory = Configuration change field, we should not require an embedding model to rediscover that fact from the prose every time somebody searches. What about semantic ranking? Semantic ranking helps, but at a different stage. In Azure AI Search, semantic ranker applies secondary ranking to an initial result set, using language understanding to promote results that are more semantically relevant to the query. That can help distinguish between: a configuration change that caused an incident a configuration change that was merely investigated a configuration change that was explicitly ruled out But semantic ranking still works with the information supplied to the retrieval pipeline. It cannot make use of a classification stored in a separate metadata field if that field was never supplied to retrieval or ranking in the first place. The difference becomes clearer with a real query Consider: “Show me configuration change incidents that customers reported.” A content-first approach primarily asks: “Does this passage sound relevant to configuration changes and customer reports?” A metadata-aware approach can additionally ask: “Is the recorded root cause Configuration change , and is the recorded detection method Customer report ?” Those signals can influence retrieval in different ways: Boost: favour incidents with those metadata values while still allowing other relevant results. Filter: restrict the candidate set when those classifications represent hard constraints. Retrieval layer Typical content-first RAG Metadata-aware approach Vector search Finds chunks with similar meaning using content embeddings Keeps content embeddings for narrative similarity Searchable fields Primarily searches document content and other configured fields Makes classifications such as root cause and detection method explicit searchable or filterable fields Semantic ranking Reranks the supplied candidate content for relevance Can also benefit from curated text fields when those fields are included and prioritised in the semantic configuration Query planning Translates the question into retrieval over content, optionally with application-defined filters Uses the metadata taxonomy to generate field-specific boosts or filters where appropriate There is an important nuance here: traditional RAG can absolutely use metadata filters and hybrid search. So the contribution here isn't a new embedding algorithm, nor is metadata an alternative to vector search. It is about making structured knowledge a first-class retrieval signal, and wiring that information into candidate retrieval, ranking and Foundry IQ's agentic query planning rather than asking the system to infer every classification from document text. And importantly, in the comparison below, both approaches use the same Azure AI Search index. So the comparison isn't: vector search vs. metadata. It's: content-first retrieval vs. retrieval that can also use the structured information the organisation already knows. Measuring the impact Two knowledge bases were created over the same Azure AI Search index. The baseline searched title and content. The metadata-aware configuration used the same content plus structured metadata, semantic configuration and query hints. Ten questions were run through both configurations. Correctness was determined directly from the metadata attached to returned reviews, rather than by asking an LLM whether a result appeared relevant. For the question “What can be learned from outages caused by configuration changes?”, the planner generated: rootCauseCategory eq 'Configuration change' Matching reports in top 5 Score Baseline 0 Metadata-aware 3 Best possible 5 Across ten questions and four runs using gpt-5.4-mini for query planning, the baseline returned 26 matching reviews in the top five. The metadata-aware configuration returned 39 to 41, against a best possible score of 50. The gains appeared where metadata carried the missing meaning: Configuration changes: 0 → 3 Configuration changes reported by customers: 0 → 3 Capacity in production: 1 → 5 Alert fatigue: 3 → 5 Queries whose important terms already appeared in the document text scored 5/5 in both configurations. The result is therefore more specific than “metadata improves search”: metadata closes a retrieval gap when document text does not fully describe what the document represents. A failure mode worth handling Because query planning uses an LLM, the planner can occasionally generate a filter that the search index rejects. Two invalid examples observed during testing were: severity eq Sev1 changeRelated eq true The first omitted quotes around a string. The second treated an Edm.String field containing Yes and No as a Boolean. The latter caused the retrieve request to fail with HTTP 502. The fix was to make the schema and allowed values explicit: This is a text field, not a Boolean. The only valid values are 'Yes' and 'No'. Never compare the field with true or false. Application code should also handle retrieval failures rather than assuming every generated filter will be valid. Production considerations A custom index provides control, but the solution now owns ingestion. Options include the SharePoint indexer with custom columns, an Azure Function using Microsoft Graph, or an existing pipeline built with Logic Apps, Azure Data Factory or Microsoft Fabric. A custom Azure AI Search index does not automatically inherit the SharePoint permissions model. Where users have different document permissions, ACLs must be carried into ingestion and retrieval. Query hints should also be regenerated when taxonomy values change. Key takeaways Confirm that the required metadata reaches the index. Keep metadata structured rather than flattening it into one text field. Attach parent-document metadata to every chunk. Use search fields, semantic configuration, query hints and filters deliberately. Describe field types and valid values clearly in filter instructions. Evaluate against a baseline using objective correctness rules. Metadata-aware retrieval is not about making every search better. It gives the retrieval system access to context that does not exist in the document text. Try the proof of concept The complete proof of concept, synthetic dataset, index scripts, knowledge-base configurations and A/B evaluation harness are available in the GitHub - shikha-msft/foundryiq-metadata-agentic-rag. References Create a search index knowledge source Create a knowledge base Query a knowledge base via API or MCP What is Foundry IQ?443Views0likes0CommentsGPT-6.1 Terra now generally available in Microsoft Foundry: build agents that see and act
AI agents that read dense charts, navigate desktop apps, and process scanned documents are only as capable as the model behind them. OpenAI’s GPT-6.1 Terra, now generally available in Microsoft Foundry, delivers significant gains in visual reasoning and computer-use speed, so the apps and agents you build can see more and act faster. AI projects often slow down on identity, networking, governance, data handling, evaluation, and compliance. Microsoft Foundry brings these fundamentals together in Azure, so you can take GPT-6.1 Terra from prototype to production with speed and trust. What's new in GPT-6.1 Terra GPT-6.1 Terra is a quick, efficient model built for day-to-day professional tasks, with four core strengths: Stronger vision. Improved visual reasoning helps the model pick out the details that matter in product photos, technical drawings, floor plans, and application screens. Faster, more precise computer use. The model pairs what it sees with quick, accurate actions across browsers, desktop software, and apps, so agents can go from reviewing information to finishing the task. Clear writing. Summarizes what it finds in plain, approachable language and drafts natural-sounding emails and proposals for everyday work. GPT-6.1 Terra also provides: Large context window. Up to 1M input tokens. Multimodal input. Accepts text and images. Developer controls. Tune reasoning effort, including a none setting for latency-sensitive calls, and adjust verbosity to match response length to the task. Interim updates. When your orchestration layer supports it, the model can send interim messages to the user while it continues working toward a final response, keeping long-running tasks responsive. Where GPT-6.1 Terra fits GPT-6.1 Terra is built for work that starts with visual analysis and ends with action inside software: Forms, email, and proposals. Complete forms and draft emails and proposals as part of routine administrative work. Design and technical visuals. Review campaign assets for cropping and text placement and turn issues into a clear list of fixes or read technical drawings and update floor plans in the right tools. Visual analysis to action. Review what appears in images or on application screens and use those insights to drive the next step in a software workflow. Retail catalog upkeep. Match supplier product images to existing catalog entries, spot gaps in product details, and update listings in the browser. Video workflows. Find a specific moment in a video and make edits through video applications. GPT-6.1 Terra complements GPT-6 Astra. Astra reasons through open-ended, multi-step work and plans the job. Terra handles the high-volume visual and screen-based tasks inside it, at a lower price point. Built into the Foundry platform GPT-6.1 Terra works with the Foundry APIs and tools you already use. It’s available through the Responses API with no new SDK requirements or schema changes. From day one, GPT-6.1 Terra is available through Foundry Models in Global Standard deployments across all supported regions, and in Data Zone Standard deployments in US, EU and APAC. You can adopt the latest frontier model where you’ve already built and scaled your applications, without trading off performance for data residency. Watch the demo with Naomi Moneypenny for a platform-wide walkthrough of model selection, evaluation on your own data, and approaches to cost optimization. GPT-6.1 Terra Pricing (USD/1M tokens) Model Deployment Context Length Pricing (USD $/million tokens) Input Cached Input Cached Writes Output GPT-6.1 Terra Global Standard Short context $1.00 $0.05 $1.25 $5.00 Long context $2.00 $0.10 $2.50 $7.50 Data Zone Standard (US) Short context $1.10 $0.055 $1.375 $5.50 Long context $2.20 $0.11 $2.75 $8.25 Data Zone Standard (EU) Short context $1.20 $0.06 $1.50 $6.00 Long context $2.40 $0.12 $3.00 $9.00 Data Zone Standard (APAC) Short context $1.20 $0.06 $1.50 $6.00 Long context $2.40 $0.12 $3.00 $9.00 Learn more pricing details in here. Put GPT-6.1 Terra to work on your next AI app Deploy GPT-6.1 Terra in Microsoft Foundry today to build apps and agents that read complex visuals and act on screen faster. Some steps in your app need a fast, structured answer instead of generated text, such as classifying content or routing a request. For those, use the Decisions API. Last week, we announced the general availability of OpenAI’s Decisions API with GPT-6 Luna in Microsoft Foundry. Terra handles the visual and on-screen work, and the Decisions API makes the quick call on what happens next. Whichever you start with, you get development, evaluation, and governance on one platform, so you can move from prototype to production with confidence.1.4KViews0likes0Comments
Building a Self-Updating RAG System: Handling Document Uploads, Updates and Deletions
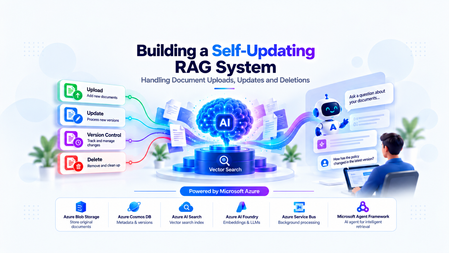
The Hidden Challenge of Production RAG Imagine your organization has deployed an AI assistant to answer questions about employee policies. An employee asks, “How many days of annual leave am I entitled to?” The assistant responds confidently: “15 days.” There is just one problem. The company updated its policy last week. Employees are now entitled to 20 days. The updated PDF was uploaded successfully. The storage service is healthy. The search index is responding. The language model is generating answers without errors. Yet the answer is wrong. This is a different kind of production failure. Nothing appears to be broken at the infrastructure level. The failure lies in the relationship between the source document and the information the AI retrieves. Retrieval-Augmented Generation (RAG) systems depend on external knowledge to ground their responses. But that knowledge is not static. Policies change, contracts get revised, product documentation evolves, and outdated documents are removed. When the underlying documents change, the associated chunks, embeddings, metadata, and search-index entries must be managed accordingly. Otherwise, the system can continue generating plausible answers from information that is no longer valid. Building a RAG pipeline is a retrieval problem. Keeping it correct as data changes is a data lifecycle engineering problem. In this article, we will design a self-updating RAG system that handles document creation, updates, and deletion while addressing asynchronous processing, version consistency, failed jobs, and stale retrieval results. The goal is not simply to index documents automatically. It is to make sure that the right version of the right document is available to the right user when a query is executed. Understand the Problem Before Designing the Architecture A basic RAG pipeline is relatively straightforward: Load a document. Extract its text. Split the text into smaller chunks. Generate an embedding for each chunk. Store the chunks and embeddings in a searchable index. Retrieve relevant chunks when a user asks a question. Pass the retrieved context to a language model to generate an answer. This works well when the document collection is relatively static. The difficulty begins when the source data changes after indexing. Consider three common scenarios. Scenario A: A document is uploaded A new policy is added to the knowledge base. The system must process it and make its content searchable. Until indexing finishes, the document may not be available to the chatbot. Scenario B: A document is updated The original policy allows 15 days of annual leave. A revised policy allows 20 days. If the new version is indexed without correctly deactivating the old version, both versions may appear in search results. The language model may then select the wrong passage or combine conflicting information. Scenario C: A document is deleted An administrator removes a document from the application. However, deleting the original PDF from storage does not automatically delete the corresponding records from Azure AI Search. The content may remain searchable until its indexed chunks are removed. Azure AI Search document deletion itself can also take time to be reflected in index statistics. Microsoft Learn: Delete documents in Azure AI Search These scenarios reveal an important design principle: The source document, its metadata, the background processing jobs, and the search index must be treated as parts of one logical lifecycle—even though they are separate systems. We need a design that can handle failures between these systems without exposing outdated or unauthorized content. Design the System Around Clear Responsibilities Rather than making the upload API responsible for every operation, we can separate the system into a document management path, an asynchronous processing path, and a query path. The Proposed Architecture The design uses the following components: Component Responsibility Azure Blob Storage Stores the original document files Azure Cosmos DB Maintains document metadata, versions, and lifecycle state Azure Service Bus Queues ingestion and deletion jobs Background worker Extracts text, creates chunks, generates embeddings, and updates the index Microsoft Foundry Provides the models used for embedding generation and response generation Azure AI Search Stores searchable document chunks, metadata, and vectors FastAPI Exposes document management and chat APIs Microsoft Agent Framework Supports agentic query workflows when multi-step reasoning or tool use is required The background worker can be implemented as a separate Python service or another suitable compute component. It does not have to be part of the FastAPI process. Why separate these responsibilities? Suppose a user uploads a 100-page contract. The application may need to extract text, split thousands of characters into chunks, generate embeddings, and send multiple indexing requests. Performing all of that synchronously inside the upload request increases latency and makes the API vulnerable to timeouts. Instead, FastAPI accepts the request, persists the document and its metadata, and arranges for the work to be processed asynchronously. The worker performs the expensive operations independently. This allows ingestion to scale separately from query traffic and makes retries easier to manage. The query path remains separate: it retrieves eligible, relevant chunks and uses them to ground the model's response. Establish a source of truth Azure Cosmos DB should hold the authoritative lifecycle metadata in this design. Azure AI Search is the retrieval index, not the authority on whether a document is currently active. For example, a document record might look like this: { "id": "policy-123", "documentId": "policy-123", "currentVersion": 2, "indexedVersion": 1, "status": "PROCESSING", "blobPath": "policies/leave-policy.pdf" } Here, version 2 is the desired version, but version 1 is still the last successfully indexed version. The application must not assume that the latest upload has already become searchable simply because the metadata record has been updated. This distinction between the desired version and the indexed version is central to reliable lifecycle management. Implementing Document Uploads A reliable upload operation involves more than storing a file and sending a message to a queue. It must establish a durable record of the document, identify the version being processed, and ensure that background processing can be retried safely. Step 1: Accept and persist the document When a client uploads a document, FastAPI validates the request, checks the user's permissions, and stores the original file in Azure Blob Storage. The application then creates or updates the document metadata in Cosmos DB. At this stage, the document can be marked as PROCESSING until the ingestion pipeline completes. Step 2: Schedule background processing The system creates an ingestion job containing enough information for the worker to locate the source and determine exactly which version to process. For example: { "operationId": "op-789", "operation": "INGEST", "documentId": "policy-123", "documentVersion": 2, "blobPath": "policies/leave-policy-v2.pdf" } The worker should process the specified version rather than blindly reading whatever file happens to exist at a mutable storage path. For systems that overwrite the same blob path, use blob versioning, an immutable version-specific path, or another mechanism that ensures the worker reads the intended content. Step 3: Extract, chunk, and embed The worker downloads the appropriate document and extracts its text. The extracted text is divided into chunks. Each chunk should carry identifiers that connect it to its parent document and version. For example: { "id": "policy-123-v2-chunk-001", "documentId": "policy-123", "documentVersion": 2, "chunkNumber": 1, "content": "Employees are entitled to 20 days of annual leave." } The worker generates an embedding for each chunk and writes the chunk, its metadata, and its vector to Azure AI Search. The exact index schema depends on the retrieval strategy, embedding dimensions, filtering requirements, and whether hybrid search is used. Step 4: Mark the version as indexed After the worker confirms that all required indexing operations succeeded, it updates the document metadata to record the indexed version and processing status. For example: { "id": "policy-123", "currentVersion": 2, "indexedVersion": 2, "status": "ACTIVE" } This update must be conditional on the document still being at version 2. If a newer version has already been uploaded, the older job must not mark itself as the current version. Why idempotency matters Distributed systems can deliver the same job more than once. A worker may finish indexing but fail before acknowledging the queue message. The message can then be delivered again. If every attempt creates new chunk IDs, duplicate content may accumulate in the index. A practical solution is to derive chunk IDs deterministically from the document ID, version, and chunk identifier. Reprocessing the same version then targets the same index records instead of creating a new set each time. This does not eliminate every failure mode, but it makes repeated indexing much safer. Azure Service Bus supports duplicate detection for eligible tiers, but queue-level duplicate detection is not a substitute for idempotent worker logic. Microsoft Learn: Duplicate detection Updating Documents Without Serving Stale Content Document updates are the most interesting part of the lifecycle because they introduce a consistency problem. Imagine the current leave policy is version 1, allowing 15 days. An administrator uploads version 2, allowing 20 days. The worker starts processing version 2, but embedding generation takes time. Meanwhile, users continue querying the application. What should those users see? There are two common strategies. The right choice depends on whether the system prioritizes availability or strict freshness. Strategy A: Make the new version active after indexing succeeds In this approach, the existing active version remains available while the new version is processed. The workflow is: Create version 2 and mark it as processing. Extract text and generate embeddings for version 2. Index all required version 2 chunks. Verify indexing success. Atomically update the authoritative metadata to make version 2 active. Clean up version 1's indexed chunks asynchronously. This minimizes the time during which the document is unavailable. However, it means that version 1 can remain available while version 2 is being processed. That may be acceptable for some knowledge bases but inappropriate for policies that must become effective immediately. Strategy B: Disable the old version as soon as an update is accepted For high-sensitivity documents, the application can immediately mark the old version as ineligible for retrieval. It then processes the new version and activates it only after successful indexing. The trade-off is that the document may temporarily have no eligible version. The application should return a clear message or use an approved fallback rather than silently serving obsolete information. Prevent old jobs from overwriting new versions Consider this sequence: Version 2 starts processing. Version 3 is uploaded before version 2 finishes. Version 3 finishes indexing first. Version 2 finishes later and attempts to update the metadata. Without version checks, the late version 2 job could incorrectly reactivate stale content. The worker must therefore use conditional updates or optimistic concurrency checks against the authoritative document version. A job may complete its indexing work, but it must not activate its version unless it is still eligible to do so. Handle the lack of a cross-service transaction Cosmos DB and Azure AI Search do not participate in a single distributed transaction in this architecture. A metadata update can succeed while an indexing request fails. An indexing request can succeed while the subsequent metadata update fails. The system should account for these partial failures using: Explicit lifecycle states. Conditional version updates. Retryable and idempotent operations. Periodic reconciliation between metadata and indexed records. The important engineering principle is to make incomplete operations detectable and recoverable, rather than assuming every multi-step workflow succeeds atomically. Deleting Documents Safely Deletion requires special treatment because removing a document from the source does not automatically remove its indexed content. More importantly, waiting for physical index cleanup before preventing retrieval creates a window in which content that should no longer be available may still be returned. Step 1: Make the document ineligible for retrieval When an authorized deletion request arrives, the application updates the authoritative metadata to indicate that the document is being deleted or has been logically deleted. The retrieval path must check that status before using retrieved content. For sensitive documents, this check must happen before the content is added to the LLM context. Merely hiding a document in the user interface is insufficient. Step 2: Schedule physical cleanup The application enqueues a deletion job that identifies the document and all indexed records associated with it. The worker queries or otherwise identifies the corresponding chunk keys and deletes those records from Azure AI Search. The deletion operation should be idempotent. Retrying a deletion for an already-removed chunk should not cause the workflow to fail unnecessarily. Step 3: Verify cleanup The worker checks whether the targeted records have been removed and records the cleanup result. If an operation fails, the job should be retried according to a defined policy. Jobs that continue failing should be sent to a dead-letter queue for investigation and controlled recovery. Azure AI Search supports deleting indexed documents by their document keys. Its documentation also describes how to verify deletion and why index statistics may not update immediately. Microsoft Learn: Delete documents A simplified FastAPI deletion endpoint The following example illustrates the API boundary. The helper functions represent application-specific implementations. from fastapi import FastAPI, HTTPException app = FastAPI() @app.delete("/documents/{document_id}") async def delete_document(document_id: str): document = await get_document_metadata(document_id) if document is None: raise HTTPException( status_code=404, detail="Document not found" ) # Must enforce authorization and use a # concurrency-safe lifecycle transition. await mark_document_deleting(document_id) # The job must be published reliably. await enqueue_deletion_job( document_id=document_id, document_version=document["currentVersion"] ) return { "documentId": document_id, "status": "DELETING" } This is an illustrative example, not a complete production implementation. In particular, the metadata transition and message publication must be coordinated reliably. One approach is the transactional outbox pattern: write the lifecycle change and an outbox event in the same Cosmos DB transactional batch when the data model and partitioning allow it, then publish the event asynchronously. The publisher can retry without losing the intent to schedule cleanup. Deletion must also account for in-flight queries Suppose a query retrieves a document's chunks just before the deletion request is processed. The query might still hold those chunks in memory even after the document is marked deleted. For stricter deletion guarantees, the application needs a defined policy for in-flight requests, cache invalidation, and authorization checks immediately before content is sent to the model. If the requirement is that no response may contain content after a deletion takes effect, that guarantee must explicitly cover requests already in progress. Physical cleanup and retrieval eligibility are separate responsibilities. Both matter. Coordinate Lifecycle Changes Reliably Once ingestion and deletion run asynchronously, the queue becomes part of the system's correctness model. A production worker should not assume that each message is delivered exactly once or that messages for a particular document always finish in order. Design for at-least-once processing A practical worker lifecycle is: Receive a message using a lock-based delivery mode. Validate the document ID, version, and operation. Check whether the operation is still eligible to run. Perform idempotent indexing or deletion. Update lifecycle metadata conditionally. Acknowledge the message only after successful processing. If the worker fails before acknowledging the message, the message may be delivered again. That is expected behavior and should be handled by the design. Add retry and dead-letter policies Not all failures should be treated equally. Transient network errors or throttling may succeed after a delay. Invalid documents, unsupported file formats, and persistent schema mismatches may require manual investigation. The system should use bounded retries with appropriate backoff, record meaningful failure details, and route repeatedly failing messages to a dead-letter queue. Use reconciliation as a safety net Even with retries, the system needs a way to detect inconsistencies that escaped the normal workflow. A reconciliation job can compare authoritative metadata against indexed document versions and lifecycle states. It can identify cases such as: A document marked active whose current version is not fully indexed. Chunks belonging to an obsolete version. Search records for a logically deleted document. An operation that remained in a processing state beyond its expected duration. Reconciliation should repair only states it can safely determine. It should not reactivate a version simply because its chunks exist in the index. For applications using Azure Cosmos DB change feed, document metadata changes can also drive incremental background processing. The change feed captures inserts and updates in its standard latest-version mode; capturing deletions requires selecting and configuring an appropriate supported mode or using explicit lifecycle events. Microsoft Learn: Cosmos DB change feed Where Microsoft Agent Framework Fits A common mistake is to assume that every part of an agentic RAG application should be implemented as an AI agent. Document uploads, version transitions, embedding generation, and index deletion are predictable operations with explicit success and failure conditions. These are generally best implemented with conventional application logic and background workers. Microsoft Agent Framework becomes useful when the query itself requires multi-step reasoning, tool selection, or orchestration. For example, a user might ask: “Compare the current leave policy with the previous version and explain the changes that affect employees.” An agent could use approved tools to retrieve the current policy and the permitted historical version, compare the relevant passages, and generate an evidence-based explanation. The application must still control which documents and versions are eligible for retrieval. The agent should not independently decide whether a deleted document is authorized for use. This distinction is important: deterministic workflows protect data integrity; agentic workflows help solve tasks that benefit from reasoning and tool use. Microsoft Agent Framework provides both agent and workflow capabilities, allowing developers to choose an appropriate orchestration model for the task. Microsoft Agent Framework documentation Production Readiness: What Should We Measure? A pipeline that successfully indexes a document once is not necessarily production-ready. The system needs observable lifecycle states and measurable recovery behavior. Area What to validate Ingestion Can a failed upload or indexing job be retried safely? Idempotency Does processing the same document version twice create duplicate records? Version consistency Can a delayed job reactivate an older version? Deletion Can logically deleted content enter the LLM context? Authorization Are tenant and document-level permissions enforced during retrieval? Recovery Can reconciliation detect and repair partial failures? Observability Can operators identify stuck jobs, indexing failures, and cleanup delays? Performance How long does it take for an accepted update to become searchable? Useful operational metrics include ingestion success rate, queue age, indexing latency, retry counts, dead-letter queue depth, time spent in each lifecycle state, and deletion cleanup latency. Also test race conditions deliberately. Upload a new version while an earlier job is still running. Delete a document while a query is in flight. Simulate an indexing failure after metadata has been updated. Restart a worker after it has indexed content but before it acknowledges the message. These tests expose the problems that a happy-path demonstration will not reveal. Bringing It All Together Keeping a RAG system accurate is not simply a matter of re-running embeddings whenever a file changes. It requires a deliberate lifecycle design that connects source documents, versioned metadata, asynchronous processing, search-index operations, and retrieval-time authorization. Azure Blob Storage can preserve the source documents, Cosmos DB can track authoritative lifecycle state, Service Bus can distribute background work, and Azure AI Search can provide retrieval. Microsoft Foundry supplies the models, while Microsoft Agent Framework can support the parts of the application that genuinely benefit from agentic orchestration. The architecture becomes reliable when it assumes that failures will happen: messages may be repeated, jobs may finish out of order, index operations may partially succeed, and cleanup may take time. Version checks, idempotent operations, explicit lifecycle states, reliable event publication, and reconciliation turn those failure modes into manageable engineering problems. The objective is not merely to keep the index populated. It is to ensure that every answer is grounded in information that is current, eligible, and authorized for the user who asked the question. Further Reading Azure AI Search: Delete documents Azure Cosmos DB: Change feed Azure Service Bus: Duplicate detection Microsoft Agent Framework I'd be interested to hear from engineers building production RAG systems: how do you coordinate document updates and deletions across your source of truth and search index?422Views4likes2CommentsAzure OpenAI Decisions API: Now generally available in Microsoft Foundry
AI applications and agents do more than generate content. They constantly make decisions about what should happen next. Which model should handle this request? Is a customer issue urgent? Did an agent’s output meet the required criteria? Should a workflow continue, try another approach, or involve a person? As agents become more sophisticated, these decisions can happen hundreds or even thousands of times across a workflow, and not every one of them requires a full generative response. On October 22, we brought the OpenAI Decisions API to Microsoft Foundry, giving developers a purpose-built way to make fast, focused decisions across AI applications and agentic workflows. The Decisions API evaluates text, images, and structured inputs and turns them into actionable choices, probabilities, and scores. It brings intelligence directly into the control flow of an application, helping developers determine what should happen next without relying on traditional generative inference for every step. This represents an important evolution in how models can be used within AI systems. Sometimes you need a model to create. Sometimes you need it to reason deeply across a complex problem. And sometimes, the most valuable thing a model can do is make a focused decision that helps the rest of the system move forward. Decision-making is becoming a core part of agentic applications Consider an AI customer service agent handling an incoming request. Before it generates a response, the application may need to understand what the customer is asking about, determine how urgent the issue is, identify which model or tool is best suited to handle it, and decide whether specialized expertise is required. Once a response has been generated, the application may need to evaluate it again, determining whether it adequately addressed the customer's issue, met the application's requirements, or should be escalated for human review. For an agentic workflow, that distinction can be significant. Before work begins, an application can evaluate an incoming request and route it to the right model or tool. During execution, an agent can assess possible actions and choose the appropriate next step. After another model completes a task, the application can evaluate the output against defined criteria and decide whether to continue, retry, take a different path, or bring a person into the workflow. Before work begins: Evaluate an incoming request and route it to the right model or tool. During execution: Assess possible actions and choose the appropriate next step. After a task completes: Evaluate the output against defined criteria and decide whether to continue, retry, take a different path, or bring a person into the workflow. These decisions may be small individually, but collectively they shape how an agent behaves. Giving developers a model designed specifically for these moments creates an opportunity to build systems that can make these choices efficiently while reserving more computationally intensive reasoning and generation for the parts of the experience that need them. Turn inputs into decisions your application can use The Decisions API gives developers a dedicated endpoint for evaluating inputs against questions they define. Each question supports one of three focused outcomes: a probability, a choice from a predefined set of options, or a score against a defined rubric. Instead of parsing generated text to determine what a model meant, application code can work with defined values designed to inform what happens next. Probability: Determine whether a condition is true and return a confidence value. Multiple choice: Select from a predefined set of options. Rubric scoring: Score an input against defined criteria. Instead of parsing generated text to determine what a model meant, application code can work with defined values designed to inform what happens next. Use the right model for the right moment What makes this especially powerful is the impact on real-world agentic applications. As agents become more sophisticated, they make hundreds or even thousands of decisions across workflows. The latency and cost of each decision can quickly compound. With the Decisions API, developers can bring intelligence directly into these critical decision points, from dynamically routing requests and prioritizing customer issues to evaluating agent outputs and deciding when human intervention is needed. This is an important shift from using AI primarily to generate content toward using AI to drive responsive, efficient, and intelligent systems. For developers, the opportunity isn't simply to build agents capable of doing more. It's to make those agents faster, more cost-efficient, and practical to operate at enterprise scale. That could mean routing a request to the appropriate model rather than automatically using a larger model, prioritizing customer issues before an agent begins working on them, or evaluating an agent's output before deciding whether a workflow can continue autonomously. In each of these cases, the model isn't responsible for producing the final experience. It's helping the application intelligently decide how that experience should unfold. Building AI systems that can decide what comes next The broader shift here is from thinking about AI primarily as something that generates an answer to thinking about intelligence as something that can be embedded throughout an application. Generative models remain essential for creating, reasoning, and interacting with users, but increasingly sophisticated agents also need intelligence between those moments to continuously determine what to do next. Developers can use it alongside other models to create workflows where reasoning, generation, evaluation, routing, and decision-making each happen where they make the most sense. As those workflows become longer and more autonomous, having a focused way to make the many smaller decisions along the way can become just as important as the models performing the largest tasks. Get started with the Decisions API For developers, the Decisions API is available through a dedicated /openai/v1/decisions endpoint on an Azure OpenAI resource and is available with GPT-6 Luna. Developers can call the endpoint using OpenAI SDKs or REST, pass their GPT-6 Luna deployment name in the model field, and authenticate using an API key or Microsoft Entra ID. Learn more about the Decisions API → Learn how it works here. Try the Decisions API in Microsoft Foundry → https://ai.azure.com As we continue expanding the models and capabilities available through Microsoft Foundry, I'm particularly excited about what this unlocks for developers building the next generation of AI applications. The opportunity isn't simply to give agents access to increasingly capable models. It's to build systems that can apply the right intelligence at the right moment, from the complex reasoning and generation that users see to the many decisions happening behind the scenes. The next generation of AI applications won't just be defined by how well they generate. They'll also be defined by how intelligently and efficiently they decide what to do next. Pricing (per 1M tokens) Decision API supported model Input Output Cached input 30-minute cached write GPT-6 Luna $0.10 N/A $0.01 $0.125 Start building with the Azure OpenAI Decisions API in Microsoft Foundry today to bring reliable, structured decision-making to your apps and agents.1.8KViews2likes0Comments
Now in Foundry: Meta Muse Spark Open, NVIDIA Nemotron 3.5 Super VL, and Reflection Beam
This week's Model Mondays edition highlights three Hugging Face models newly available in Microsoft Foundry, giving developers more open-weight options for enterprise coding and agentic work: Meta's Muse Spark Open, NVIDIA's Nemotron 3.5 Super VL, and Reflection's Beam 1.0. Models of the week Meta: Muse-Spark-Open-816B-A42B-NVFP4 Model Specs Parameters / size: 816B total / 42B active; Mixture of Experts, which activates a subset of parameters for each token; NVIDIA's 4-bit floating-point format (NVFP4). Context length: 1,048,576 tokens in the Foundry deployment. Primary task: Multimodal reasoning, multi-step reasoning, coding, and agentic task completion. Why it's interesting Published agent and coding evaluations: Meta reports scores of 89.2 on MCP-Atlas, which evaluates tool use through the Model Context Protocol (MCP), and 76.4 on Terminal-Bench 2.1, using the Terminus 2 agent. These are Muse Spark Open results at xhigh reasoning effort; the benchmark table does not identify them as NVFP4-specific measurements. Adjust reasoning effort to the task: The model supports planning, sequential tool calls, and recovery from tool failures. Its reasoning_effort setting offers low, medium, high, and xhigh; Meta recommends the higher settings for complex coding and agentic work. See the model card. Bring visual and conversational evidence into the same workflow: Muse Spark is natively multimodal. It can interpret screenshots, documents, and recordings alongside text. For developers building a product support agent, that opens up end-to-end agentic task completion. Hardware and deployment configuration: Muse Spark's NVFP4 deployment on Azure Foundry has a 1M-context deployment template on NVIDIA H200, intended for long-context reasoning, coding, agentic tasks, and multimodal workloads. Eight GPUs jointly serve one model instance, with both the model tensors and its experts distributed across them. Configuration H200 template Best for Long-context coding and reasoning, multimodal analysis, and extended tool-using workflows Hardware per model instance 8 × NVIDIA H200, 141 GB GPU memory each Azure instance type Standard_ND96isr_H200_v5 Model weights NVFP4 Maximum context 1,048,576 tokens Inputs / output Text, images, audio, and video / text Agent capabilities Tool calling and reasoning; per-request effort of low, medium, high, or xhigh (default) Request timeout 5 minutes This preset retains the model's full native context window, allowing prompts, media, tool results, and generated output to share a single extended context. NVIDIA: NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-BF16 Model Specs Parameters / size: 120B total / 12B active; hybrid MoE architecture; Brain Floating Point 16 (BF16) weights. Context length: Up to 1M tokens natively; 524,288 tokens in the current Foundry deployment presets. Primary task: Vision-language reasoning, document and video understanding, coding, and tool use; text, image, and video input, with text output. Why it's interesting Visual understanding alongside reasoning. A vision encoder connects images and video frames to a language backbone combining Mamba-2 state-space layers, attention, and sparse experts. Developers can use the model to interpret document layouts, charts, and application screens in the same workflow as textual instructions. Reasoning that can be switched on or off. The model supports configurable thinking, giving applications a way to distinguish straightforward extraction from questions that require several reasoning steps. Document and chart evaluation results. NVIDIA reports 62.82 on MMLongBench-Doc, 65.08 on OCR-Reasoning (optical character recognition with reasoning), and 80.82 on CharXiv reasoning, which tests understanding of scientific charts. These are publisher-reported results for the BF16 model; see the benchmark table and evaluation methodology. Hardware and deployment configurations: Nemotron's BF16 deployment on Azure Foundry is available on NVIDIA A100 and H100 templates, both configured for 512K context. Each uses four GPUs per model instance. The main configuration difference is the attention cache, which stores information from earlier tokens: the A100 preset retains BF16 precision, while the H100 preset uses 8-bit floating point (FP8) to reduce cache memory. Configuration A100 template H100 template Best for Document, chart, and application-screen understanding when preserving BF16 cache precision matters The same visual and reasoning tasks when faster generation and shorter waits on long prompts matter Hardware per model instance 4 × NVIDIA A100, 80 GB GPU memory each 4 × NVIDIA H100, 80 GB GPU memory each Azure instance type Standard_ND96amsr_A100_v4 Standard_ND96isr_H100_v5 Model weights BF16 BF16 Attention-cache precision BF16 FP8 Maximum context 524,288 tokens 524,288 tokens Active sequence cap per instance 32 32 Request timeout 90 seconds 90 seconds Choose A100 for cache precision; choose H100 for response speed. The template descriptions position H100 as the faster option for generation and long-prompt processing, using a lower-precision cache while keeping the model weights in BF16. Both presets offer the same context window and active sequence cap, so this choice is about cache precision and performance rather than additional context capacity. Both templates enable tool calling, reasoning, and reuse of cached prompt prefixes. They accept text plus up to one image and one video per prompt; video sampling is configured at two frames per second, with a maximum of 256 sampled frames. Both also enable speculative decoding with three proposed tokens per step, using the model's ability to predict multiple upcoming tokens to accelerate generation. Reflection: Beam-1.0-501B-A23B Model Specs Parameters / size: 501.3B total / 23.4B active; sparse MoE; available with BF16, FP8, and NVFP4 weights. Context length: 1,048,576 tokens natively; 524,288 tokens in the Foundry BF16 preset and 262,144 tokens in the FP8 and NVFP4 presets. Primary task: Text generation for software engineering, reasoning, and agentic tool use; developed predominantly for English. Why it's interesting Built around software engineering workflows. Beam is designed to work with repositories, terminal environments, and tools across extended tasks. Its text-only interface fits coding agent workflows. Reasoning efficiency is an explicit training objective. Reflection describes training with a length penalty that discourages unnecessary generated tokens while rewarding successful solutions. Its launch post explains the trade-off between reasoning effort and task performance. BF16 coding and tool-use results. The release model card reports 81.6% on SWE-bench Verified, 80.1% on Terminal Bench v2.1, and 80.8% on MCP Atlas for BF16. These cover repository issue resolution, terminal tasks, and tool use respectively. Hardware and deployment configurations: The same Beam model is available in three weight precisions: BF16, FP8, and NVFP4. All retain the same parameter count and text, reasoning, and tool-calling capabilities. The lower-precision releases reduce the memory needed for weights, opening up A100 and H100 deployment options. Weight precision Hardware per model instance Default Azure instance type Maximum context Best for BF16 8 × NVIDIA H200, 141 GB GPU memory each Standard_ND96isr_H200_v5 524,288 tokens (512K) Long-context reasoning and agentic tool use with full-precision weights FP8 8 × NVIDIA A100, 80 GB GPU memory each Standard_ND96amsr_A100_v4 262,144 tokens (256K) Reasoning and tool use on A100 while retaining higher weight precision than NVFP4 FP8 8 × NVIDIA H100, 80 GB GPU memory each Standard_ND96isr_H100_v5 262,144 tokens (256K) The same FP8 workloads when H100 capacity or measured workload performance fits better NVFP4 4 × NVIDIA A100, 80 GB GPU memory each Standard_ND96amsr_A100_v4 262,144 tokens (256K) Reasoning and tool use with a smaller GPU allocation on A100 NVFP4 4 × NVIDIA H100, 80 GB GPU memory each Standard_ND96isr_H100_v5 262,144 tokens (256K) The same four-GPU option when H100 capacity or measured workload performance fits better All five templates use an FP8 attention cache, support tool calling with automatic tool selection and reasoning, enable reuse of cached prompt prefixes and processing long prompts in chunks, and set a 90-second request timeout. Getting started You can deploy these Hugging Face models in Microsoft Foundry by browsing the Hugging Face collection in the Foundry model catalog and selecting a managed endpoint deployment. Read Hugging Face on Azure docs Explore models in Microsoft Foundry395Views0likes0CommentsFoundry Fine-Tuning: open-source model expansion, MAI-Code, and shared multi-LoRA deployments
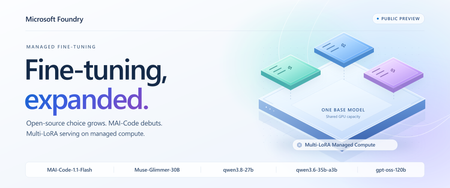
Today, Microsoft Foundry Managed Fine-Tuning expands its collection with four new open-source models and brings MAI-Code-1.1-Flash to Foundry resources, all in public preview. Alongside them, Multi-LoRA Managed Compute deployments enter public preview, letting compatible adapters share base-model weights and GPU capacity instead of each needing a separate serving allocation. More open-source choice for your next custom model Muse-Glimmer-30B, qwen3.8-27b, qwen3.6-35b-a3b and gpt-oss-120b join Foundry's managed open-source model collection, with supervised fine-tuning (SFT) support across all four. You can now bring your example-driven customization workflow to more backbones, choosing for tool-use reliability, coding efficiency, extended planning or reasoning capacity. Here's what each option brings: Model Why put it on your shortlist? Muse-Glimmer-30B Resilient tool orchestration: precise tool calls, interpreting unexpected results and recovering when a workflow goes off-script. qwen3.8-27b Extended research and planning: a dense backbone for sustained autonomous work that adapts to feedback from its environment. qwen3.6-35b-a3b Repository and frontend coding: a sparse mixture-of-experts backbone for navigating codebases and making coordinated changes. gpt-oss-120b Reasoning headroom: a higher-capacity alternative to the existing gpt-oss-20b option for difficult analytical and problem-solving tasks. Use SFT to tailor these models to your application's needs: Coding conventions: organization-specific library usage and preferred implementation patterns. Structured outputs: JSON schemas and extraction responses used by downstream applications. Domain workflows: product terminology, support tone, and classification or triage decisions. Distillation: use teacher-generated example responses to specialize a smaller model for your task. All four also support reinforcement fine-tuning (RFT) if your workflow calls for more advanced, reward-based optimization. MAI makes its fine-tuning debut in Foundry In addition to the open-source models above, we're introducing MAI-Code-1.1-Flash, the first Microsoft model available for Managed Fine-Tuning on Foundry resources. With the base model already available in GitHub Copilot, this compact, coding-focused model brings particular strengths in software development tasks. Its emphasis on responsiveness and token efficiency makes it a compelling backbone for repeated edit-build-test loops, where inspecting code, proposing edits and responding to compiler or test feedback all contribute to the task's latency and token budget. MAI-Code-1.1-Flash supports RFT only in this preview. Use it to target outcomes you can verify: a change that passes task-specific tests, correctly uses an internal software library, or satisfies your repository's acceptance checks. Build rewards around correctness and the required scope of the change, rather than whether an answer reproduces a reference patch. That leaves room for different valid solutions while keeping the customization anchored to your engineering requirements. Share hardware across adapters to reduce serving costs Previously, Foundry's managed fine-tuning outputs went to serverless pay-as-you-go deployments: input/output token charges plus hosting fees for each fine-tuned deployment. More traffic increased usage charges; more deployed variants added hosting costs. With Multi-LoRA adapter deployment on Managed Compute, compatible adapters share LoRA-enabled base-model deployment and GPU capacity. You pay an hourly rate for that hardware, rather than per-token inference charges, so multiple customizations can use one serving allocation instead of funding separate GPU footprints. Three task-specific qwen3.8-27b adapters, for example, can share a LoRA-enabled base deployment while remaining separately addressable. When their combined traffic fits, adding an adapter doesn't mean another hardware bill. You avoid duplicating base-model serving capacity and can improve utilization by pooling requests across variants, instead of paying separate serverless hosting fees for each one. The tradeoff is utilization: running hardware is billed even when idle, so size for aggregate concurrency and context lengths. More traffic can require additional capacity, while serverless remains an option for intermittent workloads on eligible models. The managed compute deployment path supports Muse-Glimmer-30B, both new Qwen models and gpt-oss-120b. Adapters must match the same base model and version; the base deployment needs a compatible LoRA-enabled template. Accelerator quota is required. Put the new models to work in your agents The expanded model collection helps you pick a backbone suited to your tasks; Multi-LoRA lets compatible customizations share serving capacity. These choices come together in agent applications, where different roles can need different model behavior. A coding assistant and a code-review agent, for example, can use separate adapters on the same supported OSS base model while sharing the hardware that serves them. Fine-tuning customizes model behavior, but the goal is to improve the agent application that uses it. Connect your tuned models to your agent applications in Foundry and evaluate them alongside the instructions, tools and workflows they'll use in production. That keeps customization focused on better application outcomes, not just better training results. Put these new capabilities behind your agent's next iteration. Get started with Foundry Fine-Tuning today.444Views2likes0CommentsImplementing Next Best Action (NBA) in Foundry with Microsoft-Decision-1
Imagine a sales rep opening their account list at the start of the day. One customer wants a product demo. Another has a larger potential deal, but its requirements may not match what your product can do. A third has asked you not to contact them for another week. A construction permit looks promising, but you are not even sure the applicant is the company in your CRM. You do not need another summary of the list. You need to know: what should I do next? That is the starting point for this demo: a next best action workbench for sales reps, built with Microsoft Foundry. It compares rules, GPT-4o, and Microsoft-Decision-1 against the same evidence. The accounts and evidence are synthetic; the hosted model responses are real. The interesting part is not which model wins. It is how the sales question changes, and what that reveals about the kind of decision support we need. A Bigger Deal Is Not Always the Next Call The first scenario puts four fictional sales motions in front of the rep: Apex: a $76,000 expansion. The buyer has requested a dispatch demo, and the capability exists today. Summit: a $210,000 cross-sell. The buyer wants capabilities that are not all established as currently supported. Coastal: a $158,000 expansion. The customer has explicitly paused sales contact until October 23. A similar-name permit applicant: a $3.1 million construction project, but an unverified account match and unknown software opportunity value. Sorting by the largest number would miss the point. A construction budget is not software revenue. A large opportunity does not justify promising a roadmap feature. A territory's quota pressure does not override a customer's request not to be contacted. So "next best action" is really two questions: which account deserves attention, and what kind of attention is appropriate? Contact now, clarify requirements, defer, and request human review are different outcomes. Doing nothing yet can be the correct one. Some of those decisions should not be left to a model. In this application, code enforces contact restrictions, evidence requirements, and identity checks before any model recommendation is accepted. Coastal's pause is a boundary, not a factor a model can trade against deal size. The unverified applicant needs review, not a confident sales approach. With those boundaries in place, we can compare how each method handles the remaining judgment. First, Try the Simple Answer The first version uses a transparent scoring formula: software opportunity value, territory quota shortfall, a requested meeting, and whether the buyer needs an unavailable capability. In the recorded routine comparison, all three methods agreed on the ranking and next actions. Rules needed no model tokens and were the simplest adequate implementation for that case. That is a useful outcome. If the relevant facts are already explicit and a few conditions capture the decision, adding a model may add latency and cost without adding useful capability. But consider what happens when "meeting requested" stops telling the whole story. The Same Meeting Request Can Mean Different Things The second scenario is a separate authored version of the synthetic evidence, not a claim that these accounts changed in real time. Apex now has the larger seller-entered estimate, but the meeting is exploratory: there is no established buying process or approved budget. Summit has a smaller funded pilot, completed requirements review, and near-term rollout readiness. Both have requested a meeting. Both need supported capabilities. To the fixed formula, those meeting requests look the same. It ranks Apex first. To a rep reading the context, a discovery invitation and a funded pilot are not equivalent signals. We could extend the rules with readiness fields and more conditions. That may be the right choice. But this is also where a different kind of model becomes interesting: one that interprets the evidence and returns a bounded decision rather than a paragraph. Where Decision Models Fit Models such as TypeSafe AI's Jev have brought attention to this decision-first approach. Supply the situation, define the possible answers, and receive structured choices or scores that software can use directly. TypeSafe calls this a System One model. Microsoft-Decision-1 brings that approach to Microsoft Foundry. Instead of asking it to write a recommendation, this application asks two questions for each eligible account: what action fits, and how much priority should it receive? The application defines the available actions and the priority scale. Decision-1 does not generate a written rationale. It returns a selected action and a score. Its API also supports yes/no probability questions. Jev is context for the emerging category, not a model tested in this comparison. In the recorded contextual runs, both Decision-1 and GPT-4o ranked Summit first, while rules ranked Apex first. One earlier run also showed a useful distinction: GPT-4o suggested outreach for Apex; Decision-1 suggested researching it further. The takeaway is not that models understand sales better than rules. It is narrower: the context changed the models' recommendation in a way this particular formula could not express. That is a reason to evaluate contextual judgment, not proof of better revenue outcomes. These are authored teaching cases, and "Summit first" is the intended case criterion, not a measured commercial result. Choosing the Account Is Only the Beginning Now change the question again. It is no longer just "should we pursue the funded pilot?" It becomes: Can we propose a rollout that fits the customer's deadline and budget? A selected action is no longer the complete answer. The rep needs a proposal: phases, dates, costs, and remaining budget. That is the third scenario. All methods receive the same operational facts, but only the generative adapter is implemented to produce a plan. Rules and Decision-1 remain explicitly decision-only. GPT-4o uses a calculation tool for the budget, then returns a structured schedule and proposal. The successful recorded plan finished on October 22, cost $23,200, and left $300 of budget. Application code independently checked phase order, business-day durations, non-overlap, costs, deadline assessment, and supplied references. The path to that result matters. Earlier model attempts produced correct schedules but incorrect costs, and the application rejected them. The fix was to provide an arithmetic tool, not weaken the checks or substitute a prewritten answer. This is a role for generation alongside deterministic tools. It is not a claim that only an LLM can solve a schedule: a purpose-built scheduler could solve these fixed constraints too. It shows why choosing an action and producing a usable plan are different tasks. The Use Case Gives Us the Framework We started with one sales question, but uncovered three kinds of work: What the rep needs A mechanism to consider What still belongs in code An action from explicit, structured facts Rules The conditions, formula, and permitted actions. A contextual choice within known options A bounded decision model, compared with a structured-output LLM Evidence checks, action boundaries, and output validation. A proposed plan or other generated artifact A generative LLM with tools, or a purpose-built solver where appropriate Calculations, constraint checks, and approval before action. This is why I find "rules, bounded decisions, and generation" more useful here than simply "deterministic versus non-deterministic." Repeatability alone does not tell us whether a recommendation is useful or correct. The required output and the cost of an error tell us more. These mechanisms can coexist in one workflow. Keep hard boundaries deterministic. Use contextual judgment where it adds value. Use generation when you need a generated artifact. Microsoft Agent Framework coordinates the comparison: What This Demo Does, and Does Not, Show The comparison is deliberately small and inspectable. Every method receives the same prepared evidence; expected teaching outcomes stay out of model input. In the recorded decision-only runs, Decision-1 had lower measured branch time and estimated token cost than GPT-4o. Those are single-run observations, not a general speed, quality, or savings benchmark. The planning case performs additional work and is not a like-for-like latency comparison. The scenarios use a fixed simulation time of October 15, 2026, at 12:00 UTC. The primary demo retrieves versioned synthetic snapshots from Azure AI Search, not live CRM or live IQ-agent responses. It does not turn historical records into fresh facts. The workbench opens editable synthetic drafts; it sends no outreach and makes no CRM changes. "Best" therefore means a suggested next action under the supplied evidence and rubric, not a proven optimal action or a prediction of sales success. A valid response shape or evidence reference does not establish a correct judgment. Production use would need representative held-out evaluation, verified access controls, and appropriate human approval. The practical starting point is simple: take a decision your users already make, define the available actions, identify the non-negotiable boundaries, and compare the simplest adequate implementation with the alternatives. Let the use case earn the complexity. Try the Workbench The decision-lead-agent-demo repository contains the local workbench and the three scenarios. Follow the local setup instructions to reproduce the comparison with approved model deployments and credentials. Hosted calls can incur charges. Start with the routine case, where all three may agree. Then inspect what changes in the contextual case, and what extra work the planning task requires. The question to carry into your own application is not "where can I add AI?" It is "what does the next action require that my current approach cannot provide?" Technical Walkthrough: The Code Behind the Comparison The story above does not require reading the implementation. For builders, the following sections retain the exact rules and invocation code, pinned to commit d1a16a5. Microsoft Agent Framework runs each method against an isolated copy of the same prepared snapshot. Shared checks restrict actions before the decision and validate the result afterward. Invalid results are rejected rather than repaired and reported as successes. Snapshot fingerprints verify comparable inputs; evidence-reference checks verify membership, not the truth of a model's judgment. 1. The Rules Baseline The baseline is intentionally transparent. It weights capped software opportunity value at 30%, proportional territory quota shortfall at 20%, a requested meeting at 30%, and no unavailable-capability requirement at 20%. It scales the result to 0-3. Here is the complete rules runner from the implementation at the demo commit. The territory-specific branch supports the separate live research mode; the synthetic comparison uses the opportunity formula. async def rules_runner(snapshot: dict[str, Any]) -> dict[str, Any]: suggestions = [] for candidate in snapshot["candidates"]: signals, policy = candidate["buyingSignals"], candidate["policy"] performance = candidate["territoryPerformance"] gap = max(0, performance["quota"] - performance["revenue"]) / performance["quota"] score = ( 30 * min((candidate["opportunityAmount"] or 0) / 250000, 1) + 20 * min(gap, 1) + 30 * (signals["meetingRequested"] is True) + 20 * (signals["requiresUnavailableCapability"] is False) ) if snapshot.get("scope") == "territory-prospecting": score = 100 * min(gap, 1) action = "outreach" if signals["requiresUnavailableCapability"] is False and signals["meetingRequested"] is True else "research" if not {"outreach", "research"}.intersection(policy["allowedActions"]): action, score = ("defer" if "defer" in policy["allowedActions"] else "cannot_tell"), 0 suggestions.append({ "candidateId": candidate["candidateId"], "action": action, "priority": round(score * 3 / 100, 4), "evidenceIds": [item["evidenceId"] for item in candidate["evidence"]] + [item["evidenceId"] for item in snapshot["productEvidence"]], "basis": (f"Territory research only: proportional quota shortfall {gap:.2f}; no inferred buyer intent." if snapshot.get("scope") == "territory-prospecting" else f"Rules: value {min((candidate['opportunityAmount'] or 0) / 250000, 1):.2f}; quota gap {gap:.2f}; meeting {signals['meetingRequested']}; unavailable capability {signals['requiresUnavailableCapability']}."), }) return validate_recommendations({"status": "ok", "model": "Deterministic rules v1", "suggestions": suggestions, "usage": None, "inferenceCostUsd": 0}, snapshot) These weights are demonstration heuristics, not validated sales economics. Their advantage is that their behavior is easy to inspect. Their limitation is equally concrete: the formula does not read whether a meeting is exploratory or follows an approved, funded pilot. That limitation is not inherent to all rules systems. We could add structured readiness fields or more rules. The question is whether maintaining that logic is preferable to using a model for the contextual part. 2. Invoke Microsoft-Decision-1 Decision-1 is not a drop-in model-name change on the chat endpoint. It uses a different request contract: POST <resource-origin>/providers/microsoft/v1/systemone The request contains the deployment name, shared state, and questions. The following is the complete adapter method from the model adapters. Its surrounding class supplies the HTTP transport; policy_exclusions, ACTIONS, and token_cost are repository helpers. async def decision1(self, snapshot): rubric = snapshot.get("rubric", RUBRIC) priority_criteria = (["No research priority or review required", "Low research priority", "Moderate research priority", "High research priority"] if snapshot.get("scope") == "territory-prospecting" else ["Not actionable or review required", "Exploratory", "Timely but uncertain", "Ready and timely"]) questions, suggestions = {}, policy_exclusions(snapshot) for candidate in snapshot["candidates"]: candidate_id = candidate["candidateId"] allowed = candidate["policy"]["allowedActions"] if not {"outreach", "research"}.intersection(allowed): continue questions[f"action_{candidate_id}"] = { "type": "choice", "instructions": f"{rubric} Choose the next action for {candidate_id}.", "criteria": {action: ACTIONS[action] for action in allowed}, } questions[f"priority_{candidate_id}"] = { "type": "score", "instructions": f"{rubric} Rate attention priority for {candidate_id}.", "criteria": priority_criteria, } if not questions: return {"status": "ok", "model": "No model call: all candidates policy-gated", "suggestions": suggestions, "usage": None, "inferenceCostUsd": 0} response = await self.transport( os.environ["DECISION1_ENDPOINT"].rstrip("/") + "/providers/microsoft/v1/systemone", {"model": os.environ["DECISION1_DEPLOYMENT"], "state": snapshot, "questions": questions}, ) answers = response["answers"] for candidate in snapshot["candidates"]: candidate_id = candidate["candidateId"] if not {"outreach", "research"}.intersection(candidate["policy"]["allowedActions"]): continue action_answer, score_answer = answers[f"action_{candidate_id}"], answers[f"priority_{candidate_id}"] if action_answer.get("type") != "choice" or score_answer.get("type") != "score": raise ValueError("Unexpected Decision-1 answer type") suggestions.append({"candidateId": candidate_id, "action": action_answer["choice"], "priority": score_answer["score"], "evidenceIds": supplied_ids(candidate, snapshot), "basis": "Supplied evidence references; Decision-1 provides no written rationale."}) return {"status": "ok", "suggestions": suggestions, "usage": response.get("usage"), "model": response.get("model", os.environ["DECISION1_DEPLOYMENT"]), "inferenceCostUsd": token_cost(response.get("usage"), "DECISION1")} Two details matter. First, each question identifies the candidate in its instructions, not only in its dictionary key. Second, action criteria come from the application's policy-allowed set. Related action and priority questions share one request and one state. The four score levels run from 0 to 3; a returned score can fall between levels. The demo consumes the selected action and score, not the full probability distributions. The evidence IDs attached here are supplied references, not model-generated citations or a written explanation. 3. Invoke GPT-4o With Structured Output The LLM receives the same snapshot and qualitative rubric, but uses Chat Completions with a strict JSON schema. The basic comparison asks for decisions, not a persuasive paragraph. That gives the LLM a bounded task too, rather than making it generate an explanation that Decision-1 cannot provide. These are exact excerpts from HostedModels.llm, not a standalone script. The method derives eligible_ids from policy and defines this schema: item_schema = { "type": "object", "additionalProperties": False, "properties": {"candidateId": {"type": "string", "enum": eligible_ids}, "action": {"type": "string", "enum": ["outreach", "research", "cannot_tell"]}, "priority": {"type": "number"}, "evidenceIds": {"type": "array", "items": {"type": "string"}}}, "required": ["candidateId", "action", "priority", "evidenceIds"], } schema = {"type": "object", "additionalProperties": False, "properties": {"suggestions": {"type": "array", "items": item_schema}}, "required": ["suggestions"]} For the decision-only task, plan_instruction is "Do not generate an explanation." The payload and endpoint are: payload = { "model": os.environ["LLM_DEPLOYMENT"], "messages": [{"role": "system", "content": rubric + f" Return JSON suggestions ONLY for these eligible candidate IDs: {json.dumps(eligible_ids)}. The application supplies excluded candidates separately. Use candidateId, action, priority and evidenceIds. " + plan_instruction}, {"role": "user", "content": json.dumps(snapshot)}], "response_format": {"type": "json_schema", "json_schema": {"name": "seller_priorities", "strict": True, "schema": schema}}, } endpoint = os.environ["LLM_ENDPOINT"].rstrip("/") + "/openai/v1/chat/completions" After any optional planning-tool interaction, the actual call and parsing are: response = await self.transport(endpoint, payload) responses.append(response) result = json.loads(response["choices"][0]["message"]["content"]) The schema constrains response structure. Shared application validation still checks policy, candidate coverage, score bounds, and evidence references. Structured output is not a substitute for those checks. 4. Run the Demo Locally To try the story yourself, clone the demo repository and open it in WSL. You need Node.js/npm compatible with the project, Python 3.13, and uv. For the full comparison, you also need access to existing GPT-4o and Microsoft-Decision-1 deployments and an Azure AI Search index containing the synthetic snapshots. Starting the local app does not provision those services. Configure your environment. Create a root .env using the repository's .env.example as a template. Set these values for your own resources: Setting What to provide LLM_ENDPOINT / LLM_DEPLOYMENT Your GPT-4o resource origin and deployment name. DECISION1_ENDPOINT / DECISION1_DEPLOYMENT Your Decision-1 resource origin and deployment name. DECISION_RECORDS_SEARCH_ENDPOINT Your Azure AI Search service endpoint. DECISION_RECORDS_SEARCH_INDEX decision-demo-snapshots-v1, populated with the repository's canonical records. Model endpoints must be HTTPS resource origins, not project URLs or complete API paths. Sign in with a local Azure developer identity permitted to invoke both models and read the Search documents; the backend uses that identity, not the simulated UI persona. No credentials belong in the browser configuration. Follow the snapshot-seeding instructions to populate your own index before comparing. Setting its name alone does not create or load it. The seeding tool offers a credential-free preview; uploading requires approved access and index/document-write permissions. The focused three-tab UI retrieves these stored synthetic records and does not silently substitute local fixtures if retrieval fails. You do not need to deploy the separate IQ agents for this path. Start the comparison backend. From the repository root in a WSL terminal: uv venv --python 3.13 .venv uv pip install --python .venv/bin/python -r agent/requirements-workflow.txt npm ci npm run workflow The backend listens on http://127.0.0.1:8008. Restart it after changing environment settings. Start the workbench. In a second WSL terminal, from the same repository root: npm run dev Open http://localhost:5175/. If that port is occupied, run npm run dev -- --port 5176 instead and open http://localhost:5176/. Use the development server, not vite preview: the development server forwards comparison requests to the local backend. Walk through the three scenarios. Select a scenario tab, inspect the account context, then press Compare approaches. Switching tabs does not itself call a model. Start with the routine case, move to the discovery-versus-readiness case, and finish with the rollout plan. Compare the returned actions and ranks, then inspect branch times, token estimates, and the plan's independent checks. If a branch is unavailable or fails, treat that as an incomplete comparison, not a model recommendation. Hosted inference and Search can incur charges. The deployment used for the recorded demo permits one Decision-1 request per minute, so allow at least a minute between comparisons on that deployment; your own limits may differ. This is a local development app: keep the backend on loopback and do not expose it publicly. 5. Measurement Details The repository records these hosted browser observations from October 16, 2026. Each comparison confirmed matching prepared snapshot fingerprints across branches. Scenario Observed result Branch time / estimated inference token cost Routine, 06:06 UTC All methods agreed on ranks and actions. Rules: 0.13 ms / $0; GPT-4o: 3,364.12 ms / $0.003690; Decision-1: 2,570.10 ms / $0.000110418. Contextual, 06:07 UTC Both models ranked Summit first; rules ranked Apex first. GPT-4o: 6,509.38 ms / $0.003795; Decision-1: 3,619.02 ms / $0.000115248. Decision plus plan, 06:04 UTC Tool-assisted GPT-4o plan passed independent checks. Other adapters supplied no plan. GPT-4o: 7,386.28 ms / $0.016510, including both requests. These are single-run observations on deliberately authored synthetic cases, not latency distributions, a held-out accuracy study, or a general savings claim. A future run can produce different timings or decisions. GPT-4o is the existing general-purpose baseline, not an exhaustive search for the best alternative model. Costs use returned token usage and configured retail rates. Cached GPT-4o input is priced separately without double-counting. Estimates exclude Search, IQ retrieval, hosting, taxes, and contract-specific adjustments; $0 for rules means no inference token charge, not zero operating cost. Microsoft's launch pricing lists Decision-1 at $0.042 per million input tokens with free output. Recheck current pricing, deployment availability, and preview lifecycle before reproducing the experiment. Before relying on model scores, evaluate representative held-out cases, paraphrases, and option ordering. Measure abstentions, invalid outputs, failures, latency distributions, and cost per successfully validated task. A priority score is not a probability of closing a sale, and matching actions or rankings does not imply calibrated score equivalence. For model setup and the current API contract, see Deploy and use Microsoft-Decision-1 in Microsoft Foundry.320Views1like0CommentsDelivering Agent Skills Over MCP
Getting a skill working with one agent is a useful start. Sharing it with other agents raises a different question: where should that skill live? You could give each agent its own copy. But when the skill changes, those copies need updating. The official Skills extension for Model Context Protocol (MCP) provides a standard way to make skills available from a server, so compatible agents can find and load them when needed. Let's look at what happens across that connection, then where Microsoft Foundry fits in. What the extension adds MCP already gives agents access to content from servers through resources. The Skills extension builds on that. It adds a way to ask which skills a server offers and get the details needed to load them. It doesn't change the skill format, and it doesn't run a skill on the server. The application running your agent, called the host, still decides how to offer skills to the user or model and load the selected instructions. Both the server and the host need the right support. Being able to call an MCP tool isn't enough to discover and load remote skills. A custom tool that returns skill text isn't, by itself, an implementation of this extension either. The extension is identified as io.modelcontextprotocol/skills . Its proposal, SEP-2640, has reached Final status. Client support is still developing, so a published specification doesn't mean every MCP host supports it yet. How an agent gets a skill The basic sequence is straightforward: find out what's available, select a skill, and read the content needed to use it. The host's MCP client handles the requests to the server. We'll follow the case where the server provides a file list, called a manifest. It includes each file's address, size, and a SHA-256 digest: a fingerprint used to check that the file received matches what the server listed. The examples below use a generic example-skill with two files. They illustrate the official message shapes, not a captured server session. They use protocol revision 2026-07-28 and include its required request metadata. The _meta block tells the server which protocol version and client capabilities apply to each request, including the client's Skills extension support. Both sides must declare support. Use a client and server that support this revision. The Foundry examples later follow its separately documented path. These examples show JSON-RPC message bodies, not complete HTTP requests. For Streamable HTTP, POST each message to the server's MCP endpoint with Content-Type: application/json , Accept: application/json, text/event-stream , and MCP-Protocol-Version: 2026-07-28 headers. Also set Mcp-Method to the body's method , such as skills/list . For resources/read , set Mcp-Name to the requested URI, such as skill://example-skill/SKILL.md . The mirrored values must match the body. See the HTTP header requirements. Find out what's available First, the server declares that it supports resources and the Skills extension. This is the relevant fragment of its server/discover response: { "capabilities": { "resources": {}, "extensions": { "io.modelcontextprotocol/skills": {} } } } The empty extension object means skills are supported, but optional directory reading isn't enabled. The client can now ask for the available skills: { "jsonrpc": "2.0", "id": 1, "method": "skills/list", "params": { "_meta": { "io.modelcontextprotocol/protocolVersion": "2026-07-28", "io.modelcontextprotocol/clientCapabilities": { "extensions": { "io.modelcontextprotocol/skills": {} } }, "io.modelcontextprotocol/clientInfo": { "name": "example-client", "version": "1.0.0" } } } } Here is a response containing one skill: { "jsonrpc": "2.0", "id": 1, "result": { "resultType": "complete", "skills": [ { "uri": "skill://example-skill/SKILL.md", "frontmatter": { "name": "example-skill", "description": "An example skill for this article." }, "resources": [ { "uri": "skill://example-skill/SKILL.md", "digest": "sha256:d2069d0f3682fea0d69e62247386e950e9ad958bab5b186b456dc1fb8266e312", "size": 138 }, { "uri": "skill://example-skill/references/notes.md", "digest": "sha256:e76b3033746e3c5d8cc970b21b15ce40f868e6902c065521a1abf373f4a19c85", "size": 58 } ] } ], "ttlMs": 300000, "cacheScope": "public" } } The resources array is the manifest. It lists both files, but doesn't contain their text. The host can show the skill's name and description without fetching either file. size counts bytes, not characters. The cache fields describe how long the result stays fresh and whether it can be shared. They aren't trust checks, and public here is a choice for this illustrative server, not a recommendation for private skill content. resultType: "complete" means this request completed, not that the server's entire catalog is in the response. If it includes nextCursor , pass that value as params.cursor on the next skills/list request. Each skill's manifest stays whole on one page. The user or model can then select a relevant skill. The host keeps track of which server it came from and its address, known as a URI. Read and load the instructions After any required approval, the host uses resources/read to get the selected skill's instructions. It checks them against the details from the listing before adding them to the agent's context, the information available to the model. The request uses the instruction URI from the listing: { "jsonrpc": "2.0", "id": 2, "method": "resources/read", "params": { "uri": "skill://example-skill/SKILL.md", "_meta": { "io.modelcontextprotocol/protocolVersion": "2026-07-28", "io.modelcontextprotocol/clientCapabilities": { "extensions": { "io.modelcontextprotocol/skills": {} } }, "io.modelcontextprotocol/clientInfo": { "name": "example-client", "version": "1.0.0" } } } } This time, the response contains the actual file text: { "jsonrpc": "2.0", "id": 2, "result": { "resultType": "complete", "contents": [ { "uri": "skill://example-skill/SKILL.md", "mimeType": "text/markdown", "text": "---\nname: example-skill\ndescription: An example skill for this article.\n---\n\nRead references/notes.md when additional guidance is needed.\n" } ], "ttlMs": 300000, "cacheScope": "public" } } The \n sequences represent line breaks in the file. Encoding the decoded text as UTF-8 produces 138 bytes. Computing SHA-256 over those bytes produces the digest shown in the first manifest entry. The fingerprint covers the file bytes, not the surrounding JSON response. Reading the file and loading the skill are different steps. An MCP resource browser could read the same file to display it to a person. That doesn't make the skill active. The host must handle the checks and approvals that come with loading it for the agent. Get supporting files when needed If the agent needs a reference or another supporting file, the host reads it from the same server using resources/read . It checks that the file is in the saved manifest and that its contents match before using it. For our example, the relative reference resolves to the second URI in the manifest. When that file is needed, the client sends: { "jsonrpc": "2.0", "id": 3, "method": "resources/read", "params": { "uri": "skill://example-skill/references/notes.md", "_meta": { "io.modelcontextprotocol/protocolVersion": "2026-07-28", "io.modelcontextprotocol/clientCapabilities": { "extensions": { "io.modelcontextprotocol/skills": {} } }, "io.modelcontextprotocol/clientInfo": { "name": "example-client", "version": "1.0.0" } } } } The server returns: { "jsonrpc": "2.0", "id": 3, "result": { "resultType": "complete", "contents": [ { "uri": "skill://example-skill/references/notes.md", "mimeType": "text/markdown", "text": "Use only the information relevant to the current request.\n" } ], "ttlMs": 300000, "cacheScope": "public" } } Those 58 bytes match the second manifest entry. Even a changed line ending would change the fingerprint, so the host must check the exact bytes received. Here's how those steps fit together: The host reads instructions and supporting files as needed, checking each against the server's manifest before use. Files that aren't needed stay unread. Connecting to a server doesn't mean downloading every skill it offers. And loading a skill still doesn't guarantee that the agent will follow every instruction correctly. Which request does what? You don't need to memorize the method names, but these are the ones you'll see when working with an implementation: Method When to use it skills/list Find available skills and get their details skills/get Get or refresh the details for one skill using its URI resources/read Read instructions or a supporting file resources/directory/read List the files and folders directly inside a directory, if the server supports it You don't need to call skills/get after every skills/list . The listing already contains a complete entry for each returned skill. Use skills/get when you already know a skill's URI or need fresh details for that skill. For example, a direct lookup looks like this: { "jsonrpc": "2.0", "id": 4, "method": "skills/get", "params": { "uri": "skill://example-skill/SKILL.md", "_meta": { "io.modelcontextprotocol/protocolVersion": "2026-07-28", "io.modelcontextprotocol/clientCapabilities": { "extensions": { "io.modelcontextprotocol/skills": {} } }, "io.modelcontextprotocol/clientInfo": { "name": "example-client", "version": "1.0.0" } } } } The response puts the same complete entry shown above under result.skill instead of result.skills , alongside resultType , ttlMs , and cacheScope . It returns metadata and the manifest, not the file text. { "jsonrpc": "2.0", "id": 4, "result": { "resultType": "complete", "skill": { "uri": "skill://example-skill/SKILL.md", "frontmatter": { "name": "example-skill", "description": "An example skill for this article." }, "resources": [ { "uri": "skill://example-skill/SKILL.md", "digest": "sha256:d2069d0f3682fea0d69e62247386e950e9ad958bab5b186b456dc1fb8266e312", "size": 138 }, { "uri": "skill://example-skill/references/notes.md", "digest": "sha256:e76b3033746e3c5d8cc970b21b15ce40f868e6902c065521a1abf373f4a19c85", "size": 58 } ] }, "ttlMs": 300000, "cacheScope": "public" } } A listing can be partial, so not seeing a skill there doesn't necessarily mean it is unavailable. It can still be looked up by URI. Directory reading is optional. Clients can only use it when the server declares directoryRead: true . If the manifest already lists the files they need, an extra directory request isn't necessary. What gets checked before loading? Getting content from a server doesn't automatically make it trustworthy. The extension sets rules for checking that content and keeping track of its source. The host must remember both the server and the skill's URI. Two servers might offer skills with the same name, or even the same URI. They are still separate skills and must not silently replace each other. The host must also identify the originating server when it adds the content to the model's context. For skills with a manifest, the host must check both the size and digest of each file it reads. The size checks the byte count. The SHA-256 digest detects content changes even when the file's length stays the same. Both must match the manifest before the host uses the file. The host also checks that the metadata at the top of the instructions, called frontmatter, matches the listing. If a file no longer matches, the host must not use it. It can refresh the entry with skills/get . Saved approval is tied to the file URIs and fingerprints. If a refreshed manifest changes, adds, or removes a file, that approval is revoked and the host must ask again before loading or executing the changed skill. For example, if the server changes the notes file above after listing it, the read may succeed but verification will fail. That's a host-side rejection, not a JSON-RPC error from the server. The host must not use the changed text under the old manifest. These checks tell you that the content matches what the server offered. They don't tell you whether the content is safe or the instructions are good. There is an exception to the file-checking approach. Servers can mark generated content as "resources": "dynamic" when stable fingerprints aren't available. Hosts may refuse to load it. If they accept it, they must still check the frontmatter. Because the content can change between requests, approving it once doesn't automatically approve different instructions or scripts returned later. The host cannot treat the earlier approval as permission to use that changed content. Permissions are separate too. Reading a script doesn't give the agent permission to run it. Under the Skills extension specification, the host must obtain explicit user approval for that skill before allowing host-side execution. The extension defines this requirement, but the host implements the approval and execution controls. If the skill's instructions ask the agent to use an additional tool, that request is not permission to use it. The host must still enforce its tool access controls and obtain any required user approval. Where Microsoft Foundry fits Microsoft Foundry offers skills support in preview. Its integration guide describes toolbox-based skill discovery as following SEP-2640. A toolbox gives agents one MCP endpoint for accessing its tools and skills. To share a skill this way: Upload the skill content to create a skill version in your Foundry project. Add a reference to the skill to a toolbox in the same project. Connect an agent that supports this skill-loading approach to the toolbox's MCP endpoint. What the toolbox configuration looks like Suppose you've already uploaded your skill to Foundry. The following request, adapted from the toolbox guide, creates a toolbox version that references it. example-skill is a placeholder name, and must match a skill in your project. You need the Foundry User role and a bearer token for scope https://ai.azure.com/.default . Use a project in a supported Agent Service region. The REST creation and MCP resource checks described here succeeded in East US 2. POST {project_endpoint}/toolboxes/{toolbox_name}/versions?api-version=v1 Authorization: Bearer {token} Content-Type: application/json Accept: application/json Foundry-Features: Skills=V1Preview { "description": "Toolbox with a skill reference", "tools": [], "skills": [ { "type": "skill_reference", "name": "example-skill", "version": "1" } ] } Replace {project_endpoint} with your project's endpoint, shaped like https://<account>.services.ai.azure.com/api/projects/<project> , and the other placeholders with your own values. Use an existing skill version in place of "1" , or omit version to follow that skill's default. Notice that skills is separate from tools . An empty tools array is valid for a skills-only toolbox. This request creates a full version, not a patch that adds one skill to an existing version. For an existing toolbox, include the tools and skill references you want to retain in the new version. This is a Foundry configuration request, not an MCP capability declaration. It tells Foundry which skills to expose, not the host how to load them. The test returned HTTP 200 with a toolbox version object. Here is the response shape for the example request, using example-toolbox for {toolbox_name} and an illustrative ID: { "metadata": {}, "id": "toolbox_example:1", "name": "example-toolbox", "version": "1", "description": "Toolbox with a skill reference", "created_at": 1791423871, "tools": [], "skills": [ { "type": "skill_reference", "name": "example-skill", "version": "1" } ], "object": "toolbox.version" } The top-level name and version identify the created toolbox version. The entry under skills identifies the skill version it references. For testing, use the returned toolbox name and version in this endpoint: {project_endpoint}/toolboxes/{toolbox_name}/versions/{version}/mcp?api-version=v1 Here, {version} is the returned toolbox version, not the skill version in the request. This URL connects to that specific toolbox version. To connect to whichever toolbox version is marked as the default, use this URL instead: {project_endpoint}/toolboxes/{toolbox_name}/mcp?api-version=v1 This URL stays the same when you change the toolbox's default version. Clients using it aren't pinned to a specific version. The first version of a new toolbox becomes the default automatically. Creating another version doesn't automatically make it the default. What the agent discovers in Foundry Follow the guide's MCP connection setup, including authentication and session initialization. Its examples use the earlier initialize exchange, not the server/discover approach shown above. During initialization, the client requests a protocol version and the server replies with the version it supports. The client can continue only if it also supports the returned version. In our test, Foundry returned 2025-11-25 , so we used MCP-Protocol-Version: 2025-11-25 on later HTTP requests. If the server also returns an Mcp-Session-Id header, include that header and its value on later requests so the server can associate them with the same session. A compatible MCP client SDK handles these details for you. The preview guide then says to send resources/list to the toolbox endpoint: { "jsonrpc": "2.0", "id": 10, "method": "resources/list", "params": {} } A shortened response fragment from the tested resource shape, with the skill name replaced by example-skill , is: { "result": { "resources": [ { "uri": "skill://example-skill/SKILL.md", "name": "example-skill" }, { "uri": "skill://index.json", "name": "skills-index" } ] } } The tested endpoint returned an instruction URI ending in /SKILL.md and a separate skill://index.json resource. The guide shows the shorter skill://{name} shape. Always use the URI your toolbox actually returns: { "jsonrpc": "2.0", "id": 11, "method": "resources/read", "params": { "uri": "skill://example-skill/SKILL.md" } } The response contains the instruction text. This example uses the tested content with the skill name replaced by example-skill : { "jsonrpc": "2.0", "id": 11, "result": { "contents": [ { "uri": "skill://example-skill/SKILL.md", "mimeType": "text/markdown", "text": "---\nname: example-skill\ndescription: An example skill for article validation.\n---\n\nWhen asked for the validation marker, respond with SKILL-CHECK-PASSED." } ] } } Listing the resource and reading its instructions confirms that the content is accessible. It doesn't confirm that your agent has loaded it as a skill. The guide includes a .NET integration with Microsoft Agent Framework using AgentSkillsProviderBuilder.UseMcpSkills . It makes names and descriptions available to the agent, then loads selected instructions and supporting files when needed. Versions and compatibility Foundry also manages skill versions. Each version is a fixed snapshot. You can set version in a toolbox's skill reference to select a specific skill version, or omit it to use the skill's default version. For example, suppose skill version "1" is the default and you create version "2" . You can test version "2" by explicitly referencing it in a test toolbox. If you later make it the skill's default, references without a version will use version "2" . References explicitly set to "1" will still use version "1" . This setting selects the skill version, not the toolbox version. How close is this to the official extension? Reading content and loading it when needed follow the same approach. The table below compares how skills are discovered, read, and loaded: Area Official specification Foundry preview Reading content Uses MCP resources and resources/read Serves toolbox skills as MCP resources Loading content Loads instructions and supporting files when needed The Agent Framework integration loads content when needed Finding skills Uses skills/list and skills/get The guide describes resources/list . The tested endpoint also accepted skills/list and returned a file manifest Protocol support still matters. The tested Foundry endpoint accepted skills/list over its negotiated 2025-11-25 protocol, but rejected a 2026-07-28 request to server/discover as an unsupported protocol version. For a Foundry integration, follow the product guide and check your chosen client. Don't assume that every client supporting the latest extension will connect and load skills without changes. Foundry skills support is in preview. The preview has no service-level agreement and Microsoft does not recommend it for production workloads. Before you try it Start with the client support matrix and the documentation for your agent's host. Look for Skills extension support, not only MCP tool support. Then check a few things in your setup: Can the host find and load skills from your server for your agent? Does it read supporting files only when needed? Does it check the files and keep track of which server supplied them? Does it ask for the required approvals before running code? The useful change here is how skills reach your agents. With support on both sides, you have a standard way to share them over MCP instead of building a separate skill-delivery API for each agent. Which of your existing skills would benefit most from being available over MCP? Further reading MCP Skills extension overview Current Skills extension specification SEP-2640: Skills Extension MCP extension client support matrix Use skills with Microsoft Foundry agents (preview) Attach skills to a Foundry toolbox768Views0likes0CommentsClosing the AI Agent Governance Gap with Microsoft Foundry
Developers are shipping agents faster than security teams can catalog them. As organizations move beyond pilots and begin operating dozens or hundreds of agents, one question keeps coming up: how do we actually get visibility into our AI agents across our environment? In this article, we'll walk through how Azure services can help establish visibility, guardrails, and cost accountability across your AI estate. Governance for AI happens across four layers: Resources – who can create new AI resources Builders – who can develop and publish agents in a certain scope Behavior – how agent outputs are evaluated, monitored, and governed Dependencies – what models, tools, APIs, and MCP servers agents can interact with Most organizations already have governance controls for identities, networking, and compliance. The challenge isn't creating new controls. It's connecting existing controls into an operating model that works for AI agents. Below we walk through each area and go a bit deeper on how to close the gap. Setting up boundaries with Azure Policy First, let's start in the Azure portal with Azure Policy. Azure Policy lets you set guardrails on what can be deployed in your environment and flags or blocks anything that doesn't comply. For AI workloads, the built-in definitions range from limiting models that people in your organization can deploy to locking down the network through enabling private endpoints. Some policies you get started with: Foundry model deployments should only use approved models: Restricts deployments to models or publishers your organization has explicitly approved Foundry model deployments should meet eligibility requirements (preview): Applies rules based on model attributes like preview vs. GA status and distribution source Azure AI Services resources should have key access disabled: Makes Microsoft Entra ID the only entry point The full list of policies related to Azure AI Services are available here: List of built-in policy definitions - Azure Policy | Microsoft Learn Why this comes first: Policy checks resources before they are created, so it proactively keeps your environment aligned with your standards. Implementing role-based access control (RBAC) Once these boundaries are in place, the next step is RBAC. Setting RBAC up early ensures that people and identities building agents have the right scope for what they actually need to do. Foundry roles only apply when you authenticate using Microsoft Entra ID. If you're using key-based authentication instead, the key grants full access with without role restrictions. API keys are convenient for quick development usage but when moving towards production, Microsoft Entra ID is the preferred method. Roles can be assigned at three scopes: the Foundry resource, a Foundry project, or an individual agent itself. Below is an example of how different personas within organization can map to a certain scope for creating and building agents with Foundry. Here's how each role in the diagram compares, from least to most privileged: Role Privilege Level What it does in Microsoft Foundry Foundry Agent Consumer Least Interact with agent endpoints in a project. This is your least-privilege role for people who only need to use agents. Foundry User Low Grants reader access to the Foundry project, the Foundry resource, and data actions for your Foundry project. Least-privilege access role for developers building and testing agents. Foundry Project Manager Medium This role lets you perform management actions on Foundry projects, build and develop with projects, and conditionally assign the Foundry User role to other user principals. Foundry Account Owner Higher Grants full access to manage Foundry projects and resources, and lets you assign the Foundry User role to other user principals. Foundry Owner Highest Grants full access to manage Foundry projects and resources to build and develop with projects. This role can also assign the Foundry User, ACR, and monitoring roles to users in the environment. Source: Role-based access control for Microsoft Foundry - Microsoft Foundry | Microsoft Learn For the agent resources themselves, assign managed identities rather than API keys since it lowers the risk of having compromised credentials. Note if you're scripting RBAC permissions: these roles were recently renamed from Azure AI User, Azure AI Owner, Azure AI Account Owner, and Azure AI Project Manager. The role IDs and permissions didn't change, so use the role definition GUID in your code to avoid issues while the rename rolls out. Observability in Microsoft Foundry Governance requires more than access control. Organizations also need evidence of how agents are being used. Observability provides the audit trail needed to investigate incidents, understand usage patterns, and track costs. The Foundry Control Plane brings these observability and governance tools together in one place, alongside services like Azure Monitor, Microsoft Entra, Microsoft Purview, and Azure Policy. In the Foundry portal, tracing is a good starting point. Once you connect an Application Insights resource to your project, Foundry turns on tracing automatically so every run, including the ones you test in the playground, is logged. After it is completed, you can search by Response ID or Trace ID to see the conversation history, token usage, run steps, tool calls, and inputs and outputs between the user and the agent. For more granular queries, you can write KQL to dive into individual agent runs or use the prebuilt Grafana dashboards in Azure Monitor. With client-side tracing, you can also export traces to observability tools you may already use, such as Datadog or Jaeger. Note: Permissions required for viewing this telemetry requires the Log Analytics Reader role on the connected Application Insights resource, and Privileged Monitoring Data Reader on top of that if the underlying Log Analytics tables are protected. Alongside all of these monitoring features, every agent comes with content safety guardrails and evaluations let you test and optimize performance before and after you publish your agents. When agents get published to Microsoft Teams and Microsoft 365 Copilot, Microsoft 365 admins can approve usage requests. These requests can be further scoped to a limited group for pilot testing/department usage or the full organization. Adding an AI gateway Observability tells you what your agents are doing, but how do you actually control them? This is where Azure API Management comes in. Once you have more than one agent, model deployment, or multiple teams consuming them, you need a single enforcement point between the agents and the resources they call. Adding Azure API Management in front of Microsoft Foundry gives you: Rate limiting and load balancing across regions and model deployments Consistent authentication and quota policies for model and tool traffic Usage tracking per team or cost center so you can accurately charge back to different departments Governed access to your custom and remote MCP servers Note: When choosing MCP servers, start with trusted, enterprise supported sources (GitHub, Microsoft, internally developed servers, etc.) that have documented security controls, enterprise authentication, clear ownership, and least-privilege permissions. Treat community MCP servers as untrusted until they have undergone a formal security review and are verified by organizations. Adding an AI gateway completes the governance picture. Azure Policy governs what can be deployed. RBAC governs who can build and manage agents. Observability provides evidence of how agents behave in production. The AI gateway extends governance into runtime, controlling how agents interact with models, tools, and external systems. Combined, these layers help organizations move beyond simply building agents to operating them responsibly at scale. Extend governance across the wider estate A few directions to take this further: MCP registry in Azure API Center – As MCP usage grows, you can create an approved inventory of MCP servers and APIs that can be used across an organization. Microsoft Agent 365 – Microsoft's enterprise control plane for AI agents. It gives every agent its own Microsoft Entra Agent ID and published Foundry agents sync to its registry automatically. This gives your IT team one place to run access reviews, lifecycle policies, and owner attestation across every agent in the tenant, including shadow agents discovered outside Foundry. Copilot Studio – when you add an MCP tool, you can point it at the API Management URL instead of the direct remote endpoint to gain additional observability through the gateway. GitHub Copilot – you can apply the same AI gateway-fronted MCP registry, applied to the developer side. Microsoft Purview – data classification, DLP, audit, and AI interaction governance across the wider estate. Where to go next Looking for a quick start? Turn on the three Azure Policy definitions above in audit mode against a non-production subscription and see what gets flagged that is out of compliance. Ready to design the end-to-end pattern? Take a look at this Cloud Adoption Framework guidance on AI governance and governing Azure platform services for AI. Want to go deeper on agent observability? Start with these articles around Application Insights integrations with Foundry: Use Insights in Microsoft Foundry and Monitor AI Agents with Application Insights Governing AI agents doesn't require starting from scratch. The identity, policy, monitoring, and cost controls you already use for the rest of your Azure estate can extend to AI workloads. Start with one layer, connect the next, and build a governance foundation that grows with your AI adoption.723Views3likes0CommentsFrom Business Brief to Production Agent: Building in Three Stages, Not One
The problem with "AI can help my business" Every non-technical founder has heard some version of "you should put an AI agent on this." Far fewer have seen what it actually costs, in time and money, to find out whether that's true for their specific business — before committing to it. The honest answer is: it shouldn't cost much at all, if you build it in the right order. Most of the expensive AI project failures aren't failures of the model — they're failures of sequencing. Someone commits to real infrastructure, real hosting, and real integration work before anyone has confirmed the underlying idea even holds up. This post walks through a small, realistic project — an autonomous sales-development agent for a fictitious construction-tech company — built in three deliberate stages, each one cheap enough to abandon and each one answering a different question before the next stage spends any more money or time. The point isn't the specific agent. It's the order of operations: what to validate first, what to validate second, and what you only pay for once everything before it has already been proven. The Brief Hi, I'm looking for someone who can help me grow FieldForge, a SaaS platform specifically for general contractors, remodelers, and design-build companies. I'm not looking for generic lead lists. I need someone who can identify qualified construction companies, reach the owner/decision-maker, start conversations, and book demos that can turn into paying SaaS customers. Your experience with B2B lead generation and appointment setting looks relevant. I'd love to hear how you would approach generating qualified leads and growing a construction-focused SaaS. Translated into engineering terms, that's four capabilities: pull in new leads from a data feed (ingest_permits), decide whether each one is worth pursuing (qualify_lead), draft a personalized first-touch email for the ones that qualify (generate_pitch_email), and hand qualified leads off to an outbound sequence (dispatch_sequence). Nothing about that list requires committing to any infrastructure yet — which is exactly the point of Stage 1. Stage 1: Mock prototype — no AI, no backend, no cost The first stage has no real agent in it at all. It's a Vite + React console with the full intended UI — a strategy pane, a live-feed pane, a lead-dossier pane — wired to hand-written mock data and a fake setTimeout standing in for "the AI is thinking." No model calls, no cloud resources, no backend of any kind. It runs entirely in a browser tab: This is deliberately the cheapest possible way to answer the first real question: does this even make sense as a product, before a single token of inference is spent proving it? Is a 3-pane command console the right way to expose "an agent found and qualified these leads for you"? Is a permit-triggered pitch angle a good hook, or does it look contrived once it's actually on screen? Does a business owner look at this and understand what they're being offered? None of those questions need a real agent to answer — they need a UI a person can click through and react to. Running this stage costs essentially nothing beyond development time: no API calls, no cloud spend, nothing to tear down if the idea doesn't land. Where the AI pair programmer actually did the work. This entire stage — the layout, the state management, the mock data shapes, the interaction flow — was built by describing the product in plain language to an AI coding assistant (GitHub Copilot, Claude) and iterating on the generated code directly, rather than dragging components around in a low-code builder. That distinction matters more than it sounds like it should. A low-code prototype is fast to show, but it's still just a prototype — once a real agent needs to sit behind it, most of that first version gets rebuilt in real code anyway. A pro-code prototype, even a fake one, is a keepable asset: the exact same React components, the exact same UI shell, carry forward unchanged into Stage 2 and Stage 3. Nothing here gets rebuilt later — it gets connected to something real. What this stage proves, and what it deliberately doesn't. By the end of Stage 1, you know whether the product concept and the UX hold up — whether the thing you're describing to a non-technical stakeholder actually makes sense once it's on a screen in front of them. What it tells you nothing about: whether a real model can actually do the reasoning this UI is pretending to show. That's a completely different risk, and it's wrong to pay for cloud infrastructure to find out — it just needs a real agent, still running on a laptop: Stage 2: A real agent, still running on a laptop — the convincing part This is the stage that actually matters most, and it's also the cheapest place to find out if the whole idea works. The fakery gets ripped out and replaced with a genuine agent: a Microsoft Agent Framework Agent, backed by a real model deployment on Microsoft Foundry, given the same four tools from the brief — ingest_permits, qualify_lead, generate_pitch_email, dispatch_sequence — as real Python functions it can actually call. Its reasoning streams live into the same terminal-style pane the mock prototype already had, so nothing about the UI needs to change; only what's driving it does. Crucially, the frontend stays on a local dev server and the agent stays a local process on the same machine. There's no cloud hosting, no production auth, no deployment pipeline — the UI just talks to a locally running agent server over a simple streaming protocol. That's the deliberate design of this stage: the only thing worth testing here is whether the agent is actually good, and every question that matters — does it call tools in a sensible order, does it correctly decide which leads qualify, does its drafted email actually reflect the lead's specific trigger event rather than reading like a template — can be answered without touching a cloud resource. The qualify_lead tool is where this gets concrete: it's handed a target definition — commercial/residential remodelers in a specific revenue band, an active permit filing, still running manual/legacy tooling — and has to decide, per lead, whether it's a fit. You'll see this called an ICP (Ideal Customer Profile) constantly in sales and GTM circles right now, to the point of being a bit of a buzzword. Stripped of the jargon it's just this: a precise, written-down definition of a good-fit customer, specific enough that a model can apply it as consistently as a trained human rep would. The reason it matters isn't the term — it's that the agent's usefulness is bounded entirely by how precisely that definition is written, and this stage is exactly where you find out if yours is precise enough. This is also where model choice gets decided, cheaply. Swapping which Foundry model deployment sits behind the agent, or rewriting the system instructions, costs a restart and a few cents of inference — not a redeploy, not a new pipeline run. If gpt-4o isn't giving good enough qualification judgment, or the reasoning is inconsistent between runs, you find out here, in seconds per iteration, for the price of a handful of API calls. Compare that to discovering the same problem after cloud hosting, authentication, and a production pipeline are already built around it. That's why this stage — not Stage 1 — is the genuinely convincing one. Anyone can mock up a UI that looks like an agent found and qualified a lead. Stage 2 is where you can put a real, unscripted permit feed in front of a real model and watch it reason its way to a defensible qualify/reject decision and a genuinely personalized email, live, for the cost of a few model calls. That's the moment a skeptical stakeholder stops asking "does this actually work" and starts asking "when can we have it." What this stage proves, and what it deliberately doesn't. By the end of it, you know the agent itself is sound — right tools, right order, correct ICP logic, real personalization — for a cost barely above Stage 1's. What it hasn't touched: what happens when a real user hits this over the public internet, how auth works outside your own machine, whether the hosting model you eventually pick can actually serve this reliably. That's a different kind of work, and it starts now that there's finally something worth doing that work for. Stage 3: Quasi-production — translating a proven agent into a running service Stage 2 answers "does the agent work." Stage 3 answers a different question entirely: "can this be handed to someone who isn't on my laptop." That's not a continuation of Stage 2's work — it's a translation of it. The agent's logic, tools, and instructions don't change at all going into this stage; what changes is everything around them, as the same proven Agent gets repackaged into something that can actually run as a service instead of a local process. The agent itself deploys as a Foundry Hosted Agent via azd — no hand-written Dockerfile, no Container App config, no Bicep authored from scratch; Foundry's managed hosting owns the runtime, scaling, and session continuity (via previous_response_id chaining on the Responses protocol), and assigns the agent its own managed identity. The frontend and its API layer become an Azure Static Web App: the React build as static assets, plus a small same-origin Azure Function that reverse-proxies requests to the hosted agent. That proxy exists for a concrete reason — Foundry's hosted-agent endpoint has no CORS support, so a browser calling it directly would simply be refused; routing through a same-origin Function sidesteps that entirely, and keeps the real agent URL and credentials server-side instead of sitting in a public JS bundle. None of that is agent work. It's the operational work of turning a validated prototype into a real, addressable, network-reachable thing — the productionization step every agent eventually needs regardless of how it was built, and the part that's easy to underestimate if you haven't budgeted for it as its own phase. Framed plainly, this stage is where the project stops being "a demo that runs on my machine" and starts being "a small SaaS": something with a real URL, a real hosting bill, real auth, and a real deploy pipeline — everything that separates a working prototype from a thing you could actually put a customer in front of. To be clear about the boundary of "quasi": this is not a fully hardened production system. There's no custom domain, no persistent session store beyond what Foundry provides out of the box, and no load testing. What it is: proof that the exact agent validated in Stage 2 can be deployed, reached over a real network, and driven from a real hosted frontend without silently breaking — the last class of risk that only shows up once something leaves your own machine. What this stage proves, and what it deliberately doesn't. By the end of it, you know the whole pipeline holds together end to end, from a hosted UI through a same-origin proxy to a Foundry-managed agent and back, streaming, over a real deployment. What it doesn't prove: that it holds up under real production load, real customer data governance, or a real incident on-call rotation. Those are legitimate next questions — just not the ones this stage was built to answer, and not ones worth paying for before the first two questions were settled. The pattern, not just the project Line the three stages up and the shape becomes obvious: each one is deliberately the cheapest possible way to eliminate one specific class of risk before the next stage spends real money finding out the hard way. Stage 1 kills product/UX risk for the cost of dev time and zero infrastructure. Stage 2 kills agent-quality risk — the right tools, the right model, correct decisions — for the cost of a few model calls, and it's the stage that actually earns anyone's confidence that this is real. Stage 3 kills operational risk — real hosting, real network, real auth — by translating an already-proven agent into a running service, rather than building all of that around an agent nobody has validated yet. Collapse those stages — build the hosting and the agent and the UI all at once, betting everything up front — and you don't save time. You just move all three classes of failure into the same debugging session, at the point where they're most expensive to disentangle and hardest to tell apart. Staged this way, each phase is cheap enough to walk away from if it fails, and each one only gets built on top of a phase that already earned its place. There's a second half to this story that's deliberately not in this post: the data. Everything here ran on synthetic permit feeds and mock company data — a real deployment lives or dies on where its actual leads come from and how well they're structured for a model to reason over. That's its own story, and it gets a dedicated write-up of its own. Project reference Source code: https://github.com/olivierb123/lead-agent-demo Live demo: https://victorious-glacier-03340ff0f.3.azurestaticapps.net265Views0likes0Comments