ai
15 TopicsAzure Storage Discovery now offers advanced capacity insights
Azure Storage Discovery is introducing advanced capacity insights to help customers gain deeper visibility into their data estate, identify inactive or inefficiently stored data, understand storage composition and retention considerations, and pinpoint resources for further investigation and optimization.691Views0likes1CommentAccelerated AI & Analytics workload on Azure Blob Storage: Up to 25x faster List Blobs operations
Today Azure Storage introduces in preview a new List Blobs optimization that accelerates listing operations by up to 25x with up to 15x lower client-side CPU utilization allowing customers to return millions of objects per second in List Blobs results. The list results are now returned in Apache Arrow format, a highly optimized and compact columnar response format that allows more efficient parsing and reduced client-side CPU utilization. Clients can now parallelize object list operations efficiently across multiple concurrent requests, while maintaining the same strong consistency of listing results that applications require. This increased performance and lower client CPU utilization is delivered within the existing List Blobs API via just a simple header change and is automatically invoked when using the updated Azure Blob Storage SDK’s. Why we built this Object storage was originally designed to provide low-cost, resilient data access through simple REST APIs. Early systems contained only a few million objects and were listed infrequently, so listing performance was not a priority. Cloud, big data, mobile, and cloud-native computing steadily increased data volumes and access demands. Since 2020, foundation models, LLMs, and large GPU fleets have pushed object storage to trillions of objects, making it an active data layer for AI. Modern AI and analytics workloads operates at the scale of trillions of objects. These workloads must repeatedly discover and inventory vast datasets for pre-training, analytics, fine-tuning, and inference, making frequent listing operations a significant source of storage-system pressure and client-side CPU consumption. Downstream AI training and data analytics jobs are gated by the time required to enumerate immense datasets, while parsing the results consumes client-side CPU that could otherwise run the workload. To meet these rapidly growing demands of AI workloads, we’ve built the next generation of Azure Blob Storage listing capabilities that deliver the performance required at this massive scale. Next, we will dive deeper into the details of how List Blobs performance and scalability have been accelerated and how simple it is for customers to take advantage of this new level of performance. Faster, more efficient, listing results with lower client CPU utilization The Apache Arrow format was selected as the most efficient new way to deliver the performance and scalability gains required for efficiently listing millions of objects per second. Apache Arrow is an open-source, compact columnar format that returns List Blobs results in an optimized response roughly one third the size of the XML format used by most cloud object-storage listing APIs, making parsing faster and easier. The new format is enabled with a simple request-header change. The List Blobs API then packages and accelerates results automatically while preserving strong consistency, so newly written objects remain immediately visible. Because Apache Arrow is compact and efficient to parse, client-side CPU utilization per object listed decreased by up to 15x, freeing compute resources for the workload itself. Submitting multiple List Blobs requests concurrently further improves performance, delivering up to a 25x increase in enumeration speed with a single request-header change, while preserving schema consistency and compatibility with existing XML responses. This new List Blobs performance enhancement via Apache Arrow remains an additive, opt-in extension of the existing List Blobs API, not a replacement. The existing XML-based List Blobs API remains unchanged, and current clients not adopting the new header continue to work with no breaking changes, but without the performance and lower CPU-utilization benefits. The next figure shows the comparison of a parallelized listing operation using Apache Arrow format compared with the XML baseline on 16 clients and 48 threads per client. rclone accelerates listing of 100K objects from 24 seconds to 1.1 seconds rclone is a popular command-line program to manage, copy, move and replicate files on and between cloud storage destinations. rclone is a widely used open-source tool for moving and syncing data across almost all types of cloud storage. Listing is a critical part of rclone’s synchronization workflow. To perform these data management operations at scale for large numbers of objects, rclone must enumerate the objects that are intended to be copied, moved, or replicated. For example, before and after syncing Azure Blob Storage containers, rclone performs a large-scale listing to compare the source and target states. After updating rclone to incorporate the simple header change for the enhanced Apache Arrow-based List Blobs API calls, rclone was able to reduce their List Blobs time-to-completion by 21.7x from 24 seconds to 1.1 seconds on 100K object datasets. The chart below shows rclone's measured wall clock time for listing a single container with 100,000 entries (columns, left axis) alongside the resulting speedup versus the classic XML path (line, right axis). Two things stand out in the results: Apache Arrow is an immediate win on its own: With no parallelism at all, sequential Arrow listing is 3.5× faster than the current XML-based List Blobs results, reducing listing operation time to completion from 23.9 seconds to 6.9 seconds . Parallel enumeration compounds the gains: Throughput climbs steadily with concurrency, reaching a 21.7× speedup at a parallelism of 30 and completing the same listing of 100,000 entries in just 1.1 seconds. The accelerated List Blobs results are returned with the same consistency using the same List Blobs API but now returned much faster with no breaking changes for existing clients. That is exactly the outcome we set out to deliver with this new capability. In rclone's own words about these results: " rclone has to list containers before it can sync them; with Apache Arrow and parallelism enabled this will make a sync of a directory with millions of files get going 20x faster. The Azure Storage team has been very responsive to our feedback during the preview which made the integration straightforward. The new Go SDK works very well and required very few code changes. Our Azure Blob Storage users are going to love this!" Nick Craig-Wood, rclone Lead Developer To get started, you can download rclone from the official rclone website. If you are running rclone v1.74.0 or later you can enable the Apache Arrow listing with the --azureblob-use-arrow-list flag and enable listing parallelism with --azureblob-list-parallelism. As described in the testing, if you set “--azureblob-list-parallelism 30” this will get you the most performance listing from Azure with Arrow listing also enabled. A sincere thank you to the rclone community for adopting List Blobs with Apache Arrow early and sharing such clear, quantified results. Feedback like that is invaluable as we advance toward general availability. Happy listing rcloners! How to get started At the REST layer, the Arrow response is negotiated with the Accept: application/vnd.apache.arrow.stream header on a minimal x-ms-version of 2026-06-06 or later. This will return a response content that will be an Apache Arrow IPC stream that can be decoded and used to instantiate a RecordBatchStreamReader using Apache Arrow SDKs in any language. An example of decoding from Rest API response is provided below using Apache Arrow Python SDK for decoding: table = pa.ipc.open_stream(resp.content).read_all() print(table.schema) print("\nrows:", table.num_rows, " columns:", table.num_columns) Name: string not null Creation-Time: timestamp[s] Last-Modified: timestamp[s] BlobType: string ResourceType: string not null Etag: string Content-Length: uint64 Content-Type: string Content-MD5: string AccessTier: string AccessTierInferred: bool LeaseState: string LeaseStatus: string ServerEncrypted: bool -- schema metadata -- NumberOfRecords: '100' NextMarker: '' rows: 100 columns: 14 import pandas as pd df = table.to_pandas() df[["Name", "BlobType", "Content-Length", "size_mb", "AccessTier"]].head(6) Name BlobType Content-Length AccessTier 0 train_chunk10_shard1.jsonl.zst BlockBlob 215 Hot 1 train_chunk10_shard10.jsonl.zst BlockBlob 216 Hot 2 train_chunk10_shard2.jsonl.zst BlockBlob 215 Hot 3 train_chunk10_shard3.jsonl.zst BlockBlob 215 Hot 4 train_chunk10_shard4.jsonl.zst BlockBlob 215 Hot 5 train_chunk10_shard5.jsonl.zst BlockBlob 217 Hot This new accelerated performance for List Blobs listing via Apache Arrow can be transparently enabled on Python, Java, .NET, C++ and Go SDKs with a simple option in the container listing function. Enabling via Azure Blob SDKs allows the performance benefits to be achieved without changing the listing interface and returned object formats in the Azure Storage SDK. This new accelerated performance for List Blobs is available in public preview across the Azure Storage client libraries listed below. To evaluate the capability, use the corresponding minimum preview version for your preferred language. SDK Minimum version (preview) .NET 12.30.0-beta.1 Python 12.31.0b1 Java 12.36.0-beta.1 Go v1.8.1-beta.1 C++ 12.19.0-beta.1 JavaScript 12.34.0-beta.1 To get started, update to a preview enabled SDK for your language and start testing the new feature with our samples, or add the new listing options to your existing REST calls Parallelizing listing operations unlocks the double-digit performance gains described in this article. The optimal strategy depends on the namespace layout and distributes listing requests across multiple threads. The two most common approaches are: Use delimiter parameter to recursively fan out additional threads for each BlobPrefix, walking the namespace. Partition the namespace with startFrom and endBefore, then process the ranges across multiple threads. This is the approach used by rclone. The best approach depends on the specific namespace layout and can be optimized by tuning both the algorithm and the level of parallelism. Limitations This new Apache Arrow-powered performance optimization for List Blobs is today supported on flat namespace (FNS) Azure Blob Storage accounts. In scenarios where the account is Hierarchical Namespace (HNS) enabled, if the List Blobs REST API is called with the new header, it will return a 409 (Conflict) error code. This error code can be used to fallback on the client application to standard XML listing. Public preview is where your input shapes the product. Try it on your largest containers, tell us what you measure, and let us know what would make it even better through this form. References List Blobs (REST API) - Azure Storage | Microsoft Learn List Blobs with Apache Arrow Samples940Views1like0CommentsBringing Enterprise File Data to Users with Azure NetApp Files, Microsoft Foundry, and M365 Copilot
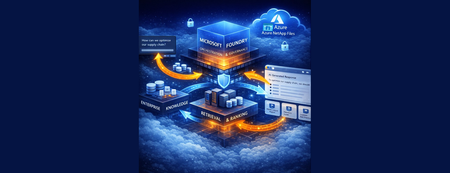
This is Part 3 of a 3-part series on extending AI to enterprise file data, showing how the knowledge pipeline is surfaced through enterprise AI agents and user experiences including Microsoft 365 Copilot.687Views0likes0CommentsFrom Enterprise File Storage to an AI-Ready Data Foundation using Azure NetApp Files and OneLake
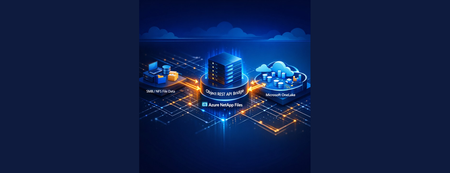
This 3-part series shows how to extend AI to enterprise file data – without migration – by combining Azure NetApp Files, OneLake, and a RAG-based architecture that surfaces grounded insights through enterprise AI agents. This is Part 1 of a 3-part series covering the data foundation, knowledge pipeline, and user experience layers.687Views0likes0CommentsFrom File Data to AI‑Powered Knowledge Pipelines using Azure NetApp Files object REST API
This is Part 2 of a 3-part series on extending AI to enterprise file data hosted on Azure NetApp Files, building on the data foundation to create a knowledge pipeline that makes enterprise file data usable by AI systems.574Views0likes0Comments
File share migrations simplified with Azure Copilot Migration Agent
Building on our earlier announcement of discovery and assessment support for SMB and NFS file shares in Azure Migrate, we are extending the experience to support end-to-end file share migrations within the same workflow. With Azure Copilot Migration Agent, customers can move from discovery and assessment to migration through a single guided experience in Azure Migrate. By bringing planning and execution together, the agent helps organizations streamline migration activity, reduce handoffs, and maintain continuity across stages. Overview Since the release of file share discovery and assessment in Azure Migrate earlier this year, customers have indicated that while visibility into their file share estate improved, the transition to execution remained fragmented. In many cases, teams still had to work across separate workflows for inventory, readiness planning, and migration, increasing operational friction and the risk of losing context between stages. Azure Copilot Migration Agent helps address this gap by bringing discovery, assessment, planning, and execution into a single guided journey. Azure Migrate provides visibility and recommendations, while Azure Storage Mover supports execution in a connected, agentic experience. The result is a more consistent migration path that reduces complexity, preserves context, and helps teams move file shares to Azure with greater operational confidence. Customer Value This update streamlines the migration journey by connecting each stage of the process and reducing operational overhead. Natural language guidance helps teams start and manage migration activities much faster, often in hours or days instead of weeks. The experience supports the following scenarios: End-to-end discovery, assessment, and migration for on-premises Windows and Linux file shares (SMB) to Azure Files. Discovery and assessment for on-premises Windows and Linux file shares (NFS). Data transfers from one Azure Blob container to another container. Design principles The experience preserves continuity across inventory, readiness insights, and execution planning, enables direct movement of validated shares when heavyweight orchestration is unnecessary, maintains approval and sequencing controls, and supports the file and object movement patterns commonly required in production environments. Getting Started with Storage Migration in Azure Copilot Migration Agent (ACMA) Launch Azure Migrate: Sign-in to the Azure portal, open Azure Migrate. From the Getting Started page, open Azure Copilot Migration Agent, then select or create an Azure Migrate project. Describe the migration in natural language. The agent detects storage migration intent and assists with storage migration planning and routes execution requests seamlessly. Examples scenarios and prompts Migration of on-premises Windows Server data over SMB to Azure Files 2. Prompt: Help me transfer data from one Azure blob container to another blob container Call to action Storage integrated capability is launching in Limited Preview at Microsoft Build. Sign up for the Preview here. For questions, contact storagemigrationcopilotagent@microsoft.com. Learn More File share discovery and assessment in Azure Migrate Azure Copilot Migration Agent Azure Storage Mover783Views2likes0CommentsSimpler, scalable file share management in Azure - now generally available
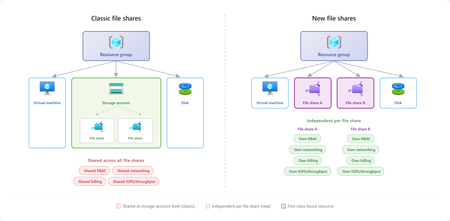
Linux workloads in Azure are scaling faster than ever, powering everything from container platforms, analytics pipelines, SAP environments to line-of-business applications. As these workloads grow, infrastructure teams commonly run into challenges with scale, cost management, complexity and compliance. IT organizations need more granular control over management and isolation boundaries for file shares independent of storage accounts, to prevent multiple application teams sharing the same capacity pools, limits, and configuration surface across different storage services. Infrastructure administrators seek operational simplicity with managing access control, policy and networking isolation for file shares, so application teams can focus on business logic and development agility. We are announcing the general availability of a new service management experience for premium SSD file shares (NFS) which allows each file share to be created, secured, scaled, and billed independently, without being tied to a storage account. Key benefits include: Familiar and intuitive file share management: Aligns user experience with on-premises NAS and file server paradigms, improving usability compared to the classic model. Infrastructure-as-Code: Define naming, capacity, IOPS, networking, tags, and security in Bicep or ARM templates for simplified automation with your favorite DevOps tools. Scale to match the workload: Support for up to 10,000 file shares per subscription per region, with 2.5x faster file share provisioning experience. Share-level security and networking: Network restrictions, snapshots, and encryption scoped to the individual share, making isolation boundaries match workload boundaries. Per-share cost visibility: Billing meters emit under the file share resource, teams can crossbill accurately, track per-workload costs, and improve chargeback without workarounds. Independent performance, security, and billing per share Combined with the provisioned v2 model, each file share is independently provisioned with its own storage, IOPS, and throughput. This allows organizations to align file shares directly to application or tenant boundaries, rather than grouping them under shared infrastructure constructs. For multi-tenant SaaS platforms, this enables a natural one-to-one mapping between tenants and file shares. Each tenant operates within its own performance envelope, allowing steady workloads and bursty workloads to scale independently without contention. This reduces the need for capacity planning tradeoffs or overprovisioning to accommodate peak usage across tenants. This isolation extends beyond performance; each file share carries its own encryption in transit settings, RBAC, policy, and network boundaries. For example, production tenants can be isolated with dedicated private endpoints, while development environments can operate under more flexible configurations. These boundaries align directly with application design, making systems easier to reason about and manage at scale. Finally, treating each file share as its own resource simplifies cost management. Teams can tag and track usage at the workload or tenant level, enabling more accurate chargeback and better visibility into resource consumption. This makes it easier to understand how individual workloads contribute to overall spending without introducing additional tracking mechanisms. Start easy, scale big Cloud-native Linux applications often scale dynamically, so the underlying storage platform must provide resources quickly and support higher scale limits to keep pace with workload demand and enable teams to quickly provision infrastructure and keep pace of development. The new file share experience supports up to 10,000 file shares per subscription per region, making it practical to use a dedicated share for each application, environment, or tenant without running into platform limits. It also provides faster provisioning, with time to first share 2.5x times faster than classic file shares, so teams can spend less time waiting on infrastructure and more time building, testing, and shipping. “Provisioning is fast and integrates seamlessly with Linux environments through NFS.” - Siam Commercial Bank Data protection with snapshots Linux workloads using shared file storage require robust data protection. With the new service management experience, customers can continue to leverage point-in-time incremental snapshots with up to 200 snapshots per share. You can also now edit metadata on individual snapshots, making it easier to organize and identify recovery points. Whether you need short term restore points or need to retain data for compliance requirements, snapshots provide an easy and cost-effective recovery mechanism. Get started today The new file share experience is available for NFS 4.1 file shares on SSD storage, using the provisioned v2 billing model with LRS and ZRS options. Whether the deployment model is ARM templates, Bicep, MCP server, or custom CI/CD pipelines, file shares are scriptable, repeatable, and automatable through the same tooling used for the rest of Azure infrastructure. Explore our documentation for step-by-step guidance. We're continuously enhancing the new file share experience with the goal of achieving full feature parity while delivering improved scale and performance limits. We would love to hear your feedback, please fill out the survey to share your thoughts. Learn more Planning for an Azure Files deployment How to create a file share Scalability & performance targets For questions or feedback, contact us at azurefiles@microsoft.com.1.8KViews3likes0CommentsAHEAD helps us launch the Strategic Azure Storage Services Partner Program
AHEAD becomes the first Azure Storage Strategic Channel Partner by demonstrating their expertise in helping customers select the ideal Azure Storage, or Azure Storage ISV, Service to offer the ideal price / performance solution for their application and helping customers to migrate to Azure quickly and safely.869Views0likes0CommentsTransforming Data migration using Azure Copilot
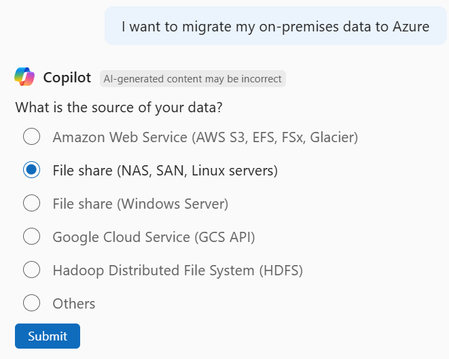
Introduction Data migration is critical, yet it is one of the most complex tasks in any cloud adoption journey. Whether you’re moving workloads from on-premises environments, consolidating hybrid deployments, or transitioning from other cloud providers, the migration process involves multiple tools, intricate planning, and risk management. What’s New in Azure Copilot With the new “Storage Migration Solutions Advisor” capability in Azure Copilot, Microsoft is transforming this experience into a conversational, AI-driven workflow that accelerates decision-making and reduces operational friction. Why This Matters Traditionally, customers faced challenges such as: Weeks of advisory time spent choosing the right migration tool amongst the many (Azure Storage Mover, AzCopy, Data Box, File Sync etc., and various Partner solutions). High support overhead due to missteps during migration if a sub-optimal tool or service is used. The Storage Migration Solutions Advisor feature introduces: Conversational Guidance: Share your migration needs with Copilot, like talking with an Azure advisor. Scenario-Based Recommendations: Tailored suggestions based on transfer data size, protocol, and bandwidth. Expanded Coverage: Supports on-premises to Azure, cloud-to-cloud (AWS/GCP to Azure), and hybrid scenarios. Native and Partner solutions: Copilot can recommend Microsoft-native (1P) solutions and third-party (3P) tools for specialized scenarios —ensuring flexibility for enterprise needs. User Workflow: Step-by-Step Initiate Migration: Start with a prompt like “How can I migrate my data into Azure?” or “What’s the best tool for moving 1 PB from AWS S3 to Azure Blob?” Provide Details: Copilot will guide you by asking for details about your requirement, such as source type (e.g., NAS, SAN, AWS S3, GCS), protocol (e.g., NFS, SMB, S3 API), target (e.g., Azure Blob, Files, Elastic SAN), data size, and bandwidth. Azure and Partner Solutions: Based on your requirements, Copilot recommends the best-fit Azure solution. If a partner solution is better suited to your requirement, Copilot will also select and recommend the appropriate solution with links to its documentation and/or its Azure marketplace page. Examples Copilot generates recommendations for migrating an on-premises file share to Azure Files. Figure 1 Prompt from user invokes Copilot Migration recommendation workflow Figure 2 Copilot understanding protocols that customer environment has access to Figure 3 Copilot asking user's target Storage type Figure 4 Copilot gathering inputs on data size, network bandwidth availability and transfer direction Figure 5 Copilot recommendation for user scenario Copilot recommends Partner solutions for specialized migration scenarios Figure 1 Prompt from user invokes Copilot Migration recommendation workflow Figure 2 Copilot understanding protocols that customer environment has access to Figure 3 Copilot asking user's target Storage type Figure 4 Copilot gathering inputs on data size, network bandwidth availability and transfer direction Figure 5 Copilot recommendation for user scenario Pro Tips Run a small proof-of-concept migration to estimate throughput and timing, especially for large datasets or small file sizes. Combine Copilot’s recommendations with Azure Storage Discovery for visibility into your storage estate after migration. Getting Started Navigate to Azure Portal → Copilot. Try prompts like: o “Help me migrate an NFS share to Azure Files.” o “What’s the best tool for moving 1 PB from AWS S3 to Azure Blob?” Explore Manage and migrate storage accounts using Azure Copilot | Microsoft Learn for detailed guidance. Ready to simplify your migration journey? Start using Azure Copilot’s Storage Migration Solutions Advisor today and experience AI-driven efficiency for your cloud transformation.739Views1like0Comments
Public Preview of Azure Native Dell PowerScale
Dell and Microsoft are extending their partnership by bringing Dell's flagship unstructured data product, OneFS, to Azure as a new fully managed offering – now in Public Preview. Dell PowerScale for Microsoft Azure packs all the well-known benefits from OneFS in an Azure Native ISV service. This is a result of a co-development effort to create an easy-to-deploy and easy-to-manage filesystem-as-a-service. Power of choice Microsoft customers can now choose between two flavors of Dell PowerScale. One is the existing customer managed version, and the other is the newly released Dell managed PowerScale for Microsoft Azure. Both solutions allow customers to run OneFS in Azure, an enterprise-grade software-defined solution that integrates scale-out PowerScale and Microsoft's public cloud platform. PowerScale offers an end-to-end data solution for many AI, HPC and enterprise use cases with keeping simplicity top of mind. Both solutions offer efficiency, performance, resiliency, multi-petabyte scalability and feature set expected from an enterprise storage solution like PowerScale to Azure. You can replicate your data estate between on-premises and Azure-based deployments and optimize your hybrid data estate with data reduction through compression, deduplication and file tiering to scalable, cost-effective Azure Blob Storage with Cloud Pools. Rich Azure ecosystems for AI and Analytics services, cloud-based disaster recovery, or application bursting are now easily accessible for existing and new PowerScale customers. The only difference is the way you deploy and manage your storage solution. In a customer managed Dell PowerScale for Azure solution, customers deploy and manage the entire software and infrastructure stack. All the compute, networking and storage resources are in a customer’s tenant. If this is the preferred option, you can start with the deployment guide and provision a standalone PowerScale cluster now. However, if you are looking for a fully managed solution, Dell PowerScale for Microsoft Azure is the right choice. As a managed service, Dell implements and manages the underlying infrastructure stack, and is responsible for support activities, including platform upgrades and maintenance tasks. What is Dell PowerScale for Microsoft Azure, An Azure Native ISV Service Dell PowerScale for Microsoft Azure is a fully managed service, implemented as an Azure Native ISV service (LINK). It is deployed and managed through the Azure Portal and transactable through Azure Marketplace. This allows all Microsoft customers to use their existing Azure commitments and contracts to easily pay for and use this new offering. Unlike existing customer managed Dell PowerScale for Azure, this implementation runs in a Dell managed environment. The responsibility for service deployment and maintenance belongs to Dell while the customers consume the service in a cloud-native manner. The same ease-of-use typically tied to SaaS services, now applies to a traditional, enterprise grade storage system, like PowerScale. Customers can simply deploy the resource with the familiar Azure portal experience and start consuming a new petabyte scale OneFS cluster. As an Azure Native ISV service, Dell PowerScale for Microsoft Azure allows customers to manage their solution with a well-known Azure user interface. Customers can choose between Azure Portal, Azure CLI, or PowerShell. “Two industry leaders, one powerful solution raising the bar for enterprise cloud storage. Dell PowerScale for Microsoft Azure offers seamless scalability up to 8.4PB in a single namespace, versatile multi-protocol support, robust security, and is fully managed by Dell. This integration simplifies hybrid cloud operations while maintaining consistent high performance for data-intensive workloads like AI/ML, and EDA, helping you stay ahead to unlock your next breakthrough." Travis Vigil, SVP, Infrastructure Storage Group, Product Management at Dell Technologies. Dell PowerScale for Microsoft Azure provides up to 8.4PB in a single namespace and is available in 9 Azure regions. Supported regions: US East US South Central US West 2 West Europe North Europe UK South Germany West Central Australia East Southeast Asia How to take the next step Azure Marketplace Listing Request a Dell Reference Number for Public Preview Dell Documentation1KViews1like0Comments