ai
211 Topics
Web IQ: Web Search and Grounding APIs for AI Agents
Web IQ gives AI agents current, citable evidence from across the web. We explain what it is, how its four layers (Bing's web substrate, Harrier embeddings, DiskANN, and structured evidence) work together, and how it pairs with Microsoft IQ to ground agents in web and enterprise context.SQL developer tools at SQL Modernization Day
SQL developers can now do most of their database work without leaving VS Code. The MSSQL extension ships updates every month, GitHub Copilot understands your schema, and the Microsoft SQL drivers keep pace with SQL Server 2025. And new Microsoft SQL skills, now in public preview, let your coding agent assess and migrate SQL Server to Azure SQL. Here's what's new across the toolchain, and where to see it in action at SQL Modernization Day on October 20. What's new in the MSSQL extension for VS Code The MSSQL extension connects to SQL Server, Azure SQL and SQL database in Fabric from the editor you already use. It now covers far more than connecting and running queries. Versions 1.40 and 1.41 added the following. Generally available Database management. Backup and restore, plus dialogs to create, rename and drop databases. View and edit data directly in the table view. DACPAC and BACPAC extract, deploy, import and export for moving databases between environments. Fabric integration to browse workspaces and provision SQL databases in Fabric. SQL database projects with a publish dialog and code analysis. Azure Data Studio migration toolkit that brings over your connections, settings and key bindings. Public preview Query Profiler for real-time activity monitoring with Extended Events. Flat file import to turn a CSV or TXT file into a new table. Database object search across tables, views, stored procedures and more, with scripting options. SQL Notebooks that mix SQL and Python kernels in one notebook. Schema Designer and data API design with GitHub Copilot, plus an application quickstart. Need a local database? The extension can spin up a SQL Server 2025 container in a few clicks. It checks prerequisites, sets up the container and adds the connection to Object Explorer for you. Build with GitHub Copilot and your schema GitHub Copilot is built into the MSSQL extension. In agent mode it reads your actual tables, columns and relationships, along with your workspace and open files. It uses the same connection and permissions as the extension, and it asks you to approve tool actions before they run. Here's some of what you can hand off: Chat with the mssql participant for SQL guidance, or let agent mode connect, list servers and run queries. Generate tables and relationships, then review them as a diff before anything reaches the database. Write T-SQL or ORM queries from plain language, and get explanations of stored procedures, views and complex joins. Generate realistic test data from your current schema. Configure Data API builder in natural language to expose tables as REST, GraphQL or MCP endpoints. Try it: from idea to an AI-ready app The library app sample walks through a full build in three steps: Spin it up. Create a local SQL Server 2025 container from the extension and seed the database. Wire it up. Have Copilot turn hardcoded app data into new tables and relationships, generate test data, and stand up a read-only REST API with Data API builder. Light it up. Add a native VECTOR column, generate embeddings, and use VECTOR_DISTANCE for semantic search behind a RAG chatbot. The repo includes a PRD and GitHub Copilot custom instructions, so Copilot follows your naming conventions and targets SQL Server without repeating yourself in every prompt. Coming next: Azure SQL Developer runs the Azure SQL Database engine locally for development, so you can build in your inner loop and deploy to Azure with no code changes. It's in gated preview, and you can sign up at aka.ms/azuresql-developer. Assess and migrate with Microsoft SQL skills Microsoft SQL skills, now in public preview, bring SQL Server migration expertise to the coding agent you already use. Skills are packaged instructions and scripts that an agent loads when a task calls for them. You ask for an assessment or a migration in plain language, and the agent picks the right skill for each step. The skills live in one central library, so they work the same way in GitHub Copilot, VS Code, Claude and Cursor. They cover the whole journey: Assess readiness, blockers and dependencies. Recommend a target, SKU and cost. Plan prerequisites and remediation. Migrate with BACPAC, or with Log Replay Service (LRS) and managed identity. Validate with post-move checks and guided fixes. You stay in control the whole way. The agent asks before it runs commands, and you approve its recommendation before anything moves. An assessment you can act on The assessment skills look at your estate through four lenses and turn discovery data into an Azure SQL recommendation you can defend. Lens Question What it checks Compatibility Can the workload move? Feature support, breaking changes, blockers and the remediation path Assessability Is there enough evidence? Inventory coverage, assessment status, data freshness and confidence gaps Sizing What capacity does it need? CPU, memory, I/O and storage demand, mapped to a compute tier with headroom Pricing What will it cost? SKU and service tier, region, licensing including Azure Hybrid Benefit, and a monthly estimate Here's how that plays out. Ask GitHub Copilot in VS Code to assess a SQL Server 2016 instance for Azure SQL Database Hyperscale. The agent checks that the Azure CLI and its data migration extension are installed, runs the assessment and reports readiness database by database. A database that uses Service Broker gets flagged, since Azure SQL Database doesn't support it, along with the fix. You also get an HTML report that compares Hyperscale, Azure SQL Managed Instance and SQL Server on Azure VMs, with a monthly cost estimate and a SKU recommendation for each database. A migration that picks up where it left off Next, ask the agent to migrate one of those databases. It confirms SqlPackage is installed, checks that the source is online and builds a migration plan. The plan names the source and target servers and the method, an offline BACPAC export and import. It creates a new database and never overwrites an existing one, and the source isn't modified. If the export fails, the agent saves a checkpoint and diagnostics. Once you fix the source, it retries only the failed step instead of starting over, then validates the result. Explore the skills at aka.ms/microsoftsql-skills. For the full set of migration tools, including Azure Migrate, Azure Database Migration Service and migration through Azure Arc, see the database migration guide. Microsoft SQL skills are in public preview. Preview features are provided without a service level agreement and aren't recommended for production workloads. Put your database under source control with SQL projects SDK-style SQL projects (Microsoft.Build.Sql) treat your database like any other codebase. A build produces a .dacpac you can deploy to new or existing databases across SQL Server, Azure SQL and SQL database in Fabric. You can work with SQL projects in VS Code, SSMS and Visual Studio. Cross-platform builds with plain dotnet build. Every .sql file in the folder is included by default. Code analysis on build with 14 default rules. Add custom rule sets as package references, and promote any rule to a build error. Package references for shared objects and cross-database references, so objects that rarely change don't slow down every build. Extract an existing database into a SQL project with SqlPackage, installed as a dotnet tool. Schema compare across databases, SQL projects and .dacpac files. A typical pipeline looks like this: A developer proposes a change in a pull request. CI builds the project and runs code analysis. The team approves and merges to main. The pipeline calculates a deployment plan against staging or production. Someone reviews the plan as a script or deploy report and approves the release. GitHub environments and Azure DevOps approvals handle that last gate. SQL projects also help as AI agents write more of your code. Every database change lands as a reviewable diff, and changes from several agents or teammates merge like any other code. Get started at aka.ms/sqlprojects or work through the SQL DevOps workshop. What's new in the Microsoft SQL drivers The Microsoft SQL drivers all shipped new releases, including several of the fixes the community asked for most. Driver Release Highlights Microsoft.Data.SqlClient (.NET) 7.0 The core package drops its Azure dependencies. Entra auth moves to Microsoft.Data.SqlClient.Extensions.Azure with no code changes. New pluggable SSPI auth, .NET 10 support, and ActiveDirectoryPassword marked obsolete. JDBC 13.4 FLOAT16 vector support for embeddings, a new performance logger, Java 25 LTS and SQL Server 2025 support. mssql-python 1.4 A public bulk copy API with a Rust-powered core, spatial types, and type hints for mypy and Pyright. mssql-django 1.7 Django 6.0 and Python 3.14, composite primary keys, SQL Server 2025, and ODBC Driver 18 as the default. PHP (sqlsrv, pdo_sqlsrv) 5.13 PHP 8.4 and 8.5, SQL Server 2025, newer Linux and macOS platforms, and a fix for a Fabric connectivity crash. New to the Python driver? Start with the mssql-python quickstart. See it live at SQL Modernization Day Amit Khandelwal's session, Migrate to Azure SQL. Then Build Something New., puts these tools together at 10:00 AM PT on Tuesday, October 20. He covers the path off on-premises SQL Server, then builds on Azure SQL Database with VS Code, GitHub Copilot, the latest drivers and the SQL MCP Server. Expect demos of the developer workflow, not only the migration. SQL Modernization Day is a free livestream on Microsoft Reactor with eight sessions from the Microsoft SQL team. Register at aka.ms/SQLModernizationDay2026.From Chat to Decisions: Bringing SLMs into Application Logic with Microsoft Olive and ONNX
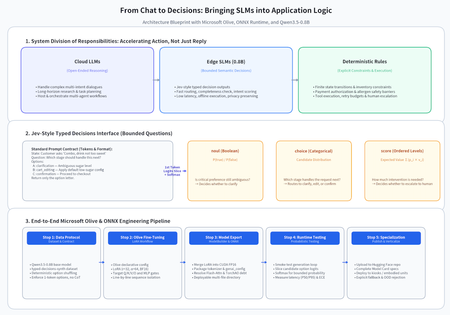
1. Why Jev Matters: Accelerating the Next Action, Not Just the Next Reply Let us return to the automated ordering scenario we have been exploring. A customer says, “I’ll have a combo, but make the drink not too sweet.” A conversational model can produce a friendly response. For the ordering application, however, the real work is just beginning. Has the customer selected a particular combo? Does “not too sweet” map to a supported customization? Should the application ask a question, update the cart, or move to confirmation? The application does not need another paragraph. It needs a decision that advances the workflow. Traditional rules are excellent at explicit constraints: unavailable items cannot be ordered, checkout requires confirmation, and payment requires authorization. Models should not replace these rules. But as inputs become ambiguous and context-dependent, rule trees accumulate branches. At the other extreme, sending every small routing decision through a large model’s reasoning and generation loop can add unnecessary waiting. This is how I think about the value of Jev: turn semantic understanding into structured behavioral decisions, shortening the distance between understanding and action. An ordering application might decompose the conversation into a few bounded questions: Decision Output type Effect on the workflow Is a critical preference still ambiguous? noul: probability for a Boolean question Decide whether to clarify Which stage should handle the request next? choice: candidate action and distribution Route to clarification, cart editing, or confirmation How much human intervention is needed? score: expected value over ordered levels Decide whether to escalate These outputs are not permissions. A model can recommend confirmation, but that recommendation must not bypass inventory checks, allergen rules, or payment authorization. The application still needs explicit state transitions, constraints, and tool boundaries. The lesson I take from our ordering exploration is that structure does more than make an answer easier to parse: it can remove unnecessary decision steps from an agent’s workflow. If questions, options, and execution boundaries are defined in advance, the model does not have to reinvent the process on every turn. One distinction matters before we continue. This project does not fine-tune an official Jev model or reproduce its private implementation. It borrows the Jev-style typed-decision interface idea, follows the prompt conventions of the open-source Hmm project, and explores a deployable component built from our own small model. 2. Where Edge SLMs Fit: Put the Decision Close to the Action Beyond basic rules, the opportunity that interests me most is in vertical applications: can a model make a useful semantic decision where the action actually happens? An SLM—a small language model—is not automatically an edge-ready model. Model size, context length, runtime, memory, and hardware all determine whether it fits a target device. Nevertheless, small models suggest a useful division of responsibilities: Use large models for open-ended problems, small models for frequent and bounded semantic decisions, and deterministic code for constraints and execution. From ordering terminals to embodied systems At an ordering terminal, a local model could recognize a modification request, assess whether required information is complete, and select the appropriate business module. Some decisions could continue during network disruption, and sensitive context could avoid unnecessary transmission. Those benefits depend on the application’s complete data flow, not merely on storing model weights locally. In an embodied system, similar questions become task-level intent decisions: “Is the user asking the robot to approach, or only describing a location?” “Should the task continue, or wait for clarification?” There is an essential boundary here. A language model may participate in task-level decisions, but it should not be the sole mechanism for collision avoidance, emergency stopping, or low-level motion control. Millisecond-scale responsiveness is a worthwhile engineering objective—not an automatic consequence of using a small model or exporting to ONNX. We need to measure the complete path on the target device: input processing, inference, policy evaluation, and tool execution. From one assistant to multi-agent orchestration Multi-agent systems offer another opportunity. A complex request may involve research, planning, execution, and verification, but not every handoff requires an open-ended discussion. A local decision component might determine: Which agent should receive the request? Is the information required for execution complete? Does a tool result need independent review? Should the workflow continue, retry, or ask a human? I am exploring how hosted agents can handle longer orchestration flows while constrained autonomous execution moves work forward. Small models could serve as frequent, local decision points within that design. “Autonomous” does not mean unrestricted: tool permissions, timeouts, retry budgets, and human approval remain application responsibilities. This is a compelling role for ONNX: package a learned decision capability into an artifact that an inference runtime can load, without requiring every deployment target to carry the full training stack. However, ONNX is a deployment path, not a guarantee of portability or performance across all hardware. This workflow exports a CUDA FP16 model. Moving it to a CPU, mobile device, or NPU requires compatible execution providers and operators, and potentially re-export, quantization, and regression evaluation. 3. Fine-Tune a General Decision Component, Then Specialize It Rather than beginning with a complex industry system, I started with a general typed-decision experiment: Qwen3.5-0.8B → Olive LoRA fine-tuning → Olive ModelBuilder export → ONNX probability testing → a Hugging Face publishing workflow. The implementation lives in Qwen3_5_0.8B_FT.ipynb. Its purpose is not to claim that a notebook solves a vertical market. It makes the path from data to a deployable decision capability concrete. Stop one: learn a bounded choice, not a long answer The base model is Qwen/Qwen3.5-0.8B, and the dataset is n4ze3m/typed-decisions-synth. A state can contain several questions. Preprocessing expands each question into a training example while preserving the dataset’s case-level training and validation split. That prevents questions about the same state from leaking across the boundary. Each question becomes a choice among option letters: State (data to evaluate): Help! My payouts have failed for 3 days. I need the money today. Question: Which team should handle this? Options: A: billing — Payments, invoicing, refunds B: technical — Bugs, outages, integrations C: sales — Pricing, upgrades, new accounts Return only the option letter. choice represents categorical options, noul uses false / true, and score uses ordered levels. During preprocessing, choice options are shuffled deterministically using the state and question ID to reduce fixed-position bias. Score levels and Boolean options keep their intended ordering. Several small details protect the contract: use the same chat template, disable thinking, verify that training text begins with the inference prompt, verify that each option letter is one token, and discard examples longer than 768 tokens rather than blindly truncating them. This is not cosmetic data cleanup. It defines the protocol between the model and its application. Stop two: turn experiment settings into an inspectable Olive workflow The notebook builds Microsoft Olive from a fixed source revision. It uses olive finetune --dry_run to generate a version-matched configuration, then adjusts preprocessing and validation. Setting Notebook configuration Fine-tuning method LoRA, rank 32, alpha 64 Target modules q_proj/k_proj/v_proj/o_proj and gate_proj/up_proj/down_proj Learning rate and epochs 1e-4, one epoch Sequence length 768 Per-device batch / gradient accumulation 1 / 16 Training / export precision BF16 / FP16 Preprocessing line-by-line, one sequence per question Replacing the default JOIN strategy avoids concatenating independent questions into continuous text. Before training, RunConfig.model_validate(...) checks the configuration. Execution uses Olive’s Python API so failures remain visible in the notebook rather than being hidden behind a generic CalledProcessError. An important difference must remain explicit: this Olive workflow uses standard full-sequence language-model SFT, not Hmm’s candidate-letter hard-label / teacher soft-label mixture. Teacher probabilities are retained for analysis but do not contribute to this training loss. Consequently, Hmm’s accuracy and calibration results cannot be claimed for this 0.8B model. Stop three: export the runtime contract, not just the graph A LoRA adapter is not the deployment endpoint. The base model, adapter, tokenizer, configuration, and runtime must agree. The notebook uses Olive ModelBuilder to export the base model and adapter into CUDA FP16 ONNX. The result includes more than an .onnx file: external weights, tokenizer resources, and genai_config.json are part of the deployable unit. Consumers should load the complete directory. The most instructive part of the process was navigating version boundaries: Boundary encountered Approach in this workflow An unnecessary old TorchAO package conflicted with Transformers Remove it after dependency installation; standard BF16 LoRA does not require it Qwen3.5 kernels fell back to reference implementations Install and check causal-conv1d and Flash Linear Attention Export requested authentication for a public model Explicitly enable anonymous model access Qwen3.5 stored EOS information in text_config Add the top-level value to the local export configuration Newer CUDA packages did not match the runtime environment Pin the notebook’s ORT GPU 1.26.0 / GenAI CUDA 0.14.0 combination The Olive revision expected newer GenAI Builder APIs Add version-specific compatibility handling for this FP16 export path Text export behaved like a multimodal decoder Set exclude_embeds=False to retain token embeddings These are records of this environment, not universal patches. Compatibility code is technical debt: when upgrading, revisit the interfaces and outputs rather than copying the workaround indefinitely. Pinning an Olive commit also does not make the complete experiment reproducible. A stronger release record should include base-model and dataset revisions, the full dependency set, GPU and driver details, and the final publishing commit. Stop four: ask two different questions in testing The first question is: does the model run? The standalone Python test script loads the export, reads a validation example, generates an answer, and extracts an option letter. This is a smoke test for the model, tokenizer, and generation loop—not the end of quality evaluation. The second question is: can the application use the decision? Following Hmm’s approach, the ONNX probability cell reads logits at the first generated position after the prompt, selects only the valid option-letter logits, and applies softmax: # candidate_logits contains only valid first-token option logits. shifted = candidate_logits - candidate_logits.max() probabilities = np.exp(shifted) probabilities /= probabilities.sum() For options A, B, and C, this is a distribution over those three choices. It does not establish that the candidate set is complete or provide absolute confidence across every possible answer. The application then interprets the result: noul reads P(true), choice selects the highest-probability option, and score computes an expected value over ordered levels. The example’s confidence formula, (n × p_max - 1) / (n - 1), measures how concentrated the distribution is. It is not a calibrated probability of correctness. Evaluation therefore needs several lenses. Accuracy, candidate NLL, and ECE describe decision quality. P50/P95 latency, peak memory, fallback rate, and task completion on the target device describe application value. The notebook’s full validation-metric cell currently uses the PyTorch/PEFT path; the ONNX cell tests example probabilities. The former is not an evaluation report for the latter. Comparing candidate distributions and actual decisions before and after export remains necessary. This article does not claim unrecorded training times, accuracy improvements, or demonstrated millisecond edge latency. Stop five: publication begins the vertical journey The notebook contains a workflow to upload the ONNX directory and a Model Card to lokinfey/Qwen3_5_0.8B_jev. This is the configured publishing destination, not a claim that this article verified the remote upload. The Model Card should explain the base model, dataset, training-objective differences, runtime versions, intended use, and outstanding evaluation. Authentication uses interactive token entry rather than embedding credentials in source files or commit history. Once the general pipeline exists, specialization becomes the important work. In ordering, that means defining real business states and actions: menu version, cart contents, modification history, missing information, mandatory clarification, and operations that always require customer confirmation. Vertical data should reflect those boundaries, with validation splits based on conversations or business entities. Low confidence, out-of-distribution inputs, and rule conflicts need explicit rejection or escalation paths. The objective is not to force a choice for every request. It is to help the system move forward appropriately within known limits. 4. Conclusion: The Opportunity Is a Shorter Decision Path, Not a Smaller Chat Window An ordering clarification, a robot’s task-level intent check, and a local handoff in a multi-agent workflow share the same underlying problem: the system has tools, but it still needs to decide when to use them, who should act, and when to stop. Jev-style structured decisions offer an interface perspective. SLMs offer the possibility of moving some semantic judgments closer to the device. Microsoft Olive organizes fine-tuning and export into a workflow. ONNX Runtime provides an execution path for deployment. Together, they suggest something more useful than a smaller chatbot: a measurable, constrained, replaceable decision component. The direction I want to keep testing combines hosted agents for long-running coordination, edge small models for frequent local decisions, and deterministic code for business and safety boundaries. Success should be measured less by whether the reply sounds intelligent and more by whether the system completes the right action faster and more reliably. That is the next step from conversation to decisions. Implementation and references Fine-tuning notebook Microsoft Olive ONNX Runtime GenAI Qwen3.5-0.8B base model Hmm model card and prompt format typed-decisions-synth dataset204Views2likes0Comments
Using Jev with Agents in Microsoft Foundry for Model Evaluation
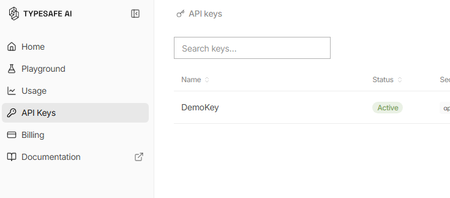
What is Jev? Jev is a new AI model from TypeSafe AI, first released in early access on 15 September 2026. TypeSafe describes Jev as its first “System One” model, designed specifically to make fast, structured decisions rather than generate free-form text. You provide Jev with some state or context and define the judgement you want it to make. It then returns a typed, probabilistic decision, such as: Choice: select from a defined set of options Score: evaluate something against an ordered scale Yes/No probability: determine the probability of a condition being true Unlike a conventional LLM, Jev gives up string generation in favour of type-safe structured values. Their description is essentially unstructured state in, typed probabilistic decisions out Why use Jev? Jev is particularly useful when an application needs to make a judgement rather than generate an answer. For example: Consistent evaluation against explicitly defined criteria Structured outputs that applications can consume directly Classification, assessment, routing and decision-support Agent workflows, where a judgement is required before taking an action Guardrails, such as assessing whether an agent should make a tool call Model routing, where a judgement determines which model or process should handle a request Every decision can also include a confidence or probability, allowing an application to use thresholds to decide when to proceed automatically or when further review is required. Jev and explainability Jev can provide a different approach to explainability for Model-as-a-Service (MaaS) and hosted LLM solutions. Traditional explainability techniques such as SHAP provide feature-attribution explanations for model predictions. Applying these techniques can be more difficult when the model is consumed solely through a hosted API and its internals are not available. Jev does not replace SHAP or provide the same type of feature-attribution explanation. Instead, it can be used as a separate judgement layer, evaluating an LLM's inputs, outputs or proposed actions against explicit criteria and returning structured decisions with confidence scores. For example: LLM generates an answer → Jev evaluates the answer → application decides what to do next This can provide a useful, measurable evaluation layer around otherwise opaque MaaS models. Could you do this with another LLM? Yes you could ask a conventional LLM to classify, score or evaluate an input and request structured JSON output. However, Jev has been purpose-built for this type of workload rather than general-purpose text generation. TypeSafe reports that Jev produces outputs in parallel rather than generating tokens sequentially, and its hosted service currently advertises typical decision latency of approximately 70–500 ms. Pricing As of September 2026, TypeSafe's documentation lists Jev 1.13 (jev-1.13.0) at $0.042 per million input tokens, with output tokens free. It lists rate limits of 250,000 tokens per second and 1,200 requests per minute, although TypeSafe states that these limits can change. As Jev produces decisions rather than generated text, you are effectively paying for the context it evaluates rather than for generated output. Pricing is subject to change and these figures are accurate only as of the date of this article Using Jev with Microsoft Foundry A useful pattern with Microsoft Foundry is to treat Jev as a specialised judgement/evaluation component alongside your generative models: User/Application → Foundry model or agent → Jev judgement → deterministic logic → action/response For example, a Foundry-hosted model could generate a proposed answer and Jev could evaluate that answer against predefined criteria before your application allows the workflow to continue. Here's how to set it up: First, you will need to apply for the preview for Jev from TypeSafe. Once you have an account you will need to create an API key Go to API keys in the menu and create a new key (copy the key for use in Foundry) You may also have received some free credit, which should be more than sufficient for experimenting with Jev given its low per-token cost. Next we go to Foundry and create a new agent for Jev In your agent, add a Tool and select OpenAPI tool as below Fill out the dialogue as follows You will have to create a new connection - The key should be in this format "Bearer apikey_<the rest of your key>" For the schema add this { "openapi": "3.0.3", "info": { "title": "TypeSafe Jev System One", "version": "1.1.0", "description": "Evaluate content using TypeSafe Jev System One." }, "servers": [ { "url": "https://api.typesafe.ai" } ], "paths": { "/v1/systemone": { "post": { "operationId": "evaluate_with_jev", "summary": "Evaluate content using Jev", "description": "Evaluate state against typed questions using TypeSafe Jev.", "security": [ { "bearerAuth": [] } ], "requestBody": { "required": true, "content": { "application/json": { "schema": { "type": "object", "additionalProperties": false, "required": [ "state", "model", "questions" ], "properties": { "state": { "type": "string", "description": "The original text or content for Jev to evaluate." }, "model": { "type": "string", "enum": [ "jev-latest" ], "default": "jev-latest", "description": "The TypeSafe Jev model. Use jev-latest." }, "questions": { "type": "object", "description": "A map of named questions for Jev to answer. Each question must be a Noul, Choice, or Score question.", "additionalProperties": { "oneOf": [ { "$ref": "#/components/schemas/NoulQuestion" }, { "$ref": "#/components/schemas/ChoiceQuestion" }, { "$ref": "#/components/schemas/ScoreQuestion" } ] } } } } } } }, "responses": { "200": { "description": "Successful Jev evaluation", "content": { "application/json": { "schema": { "type": "object", "additionalProperties": true } } } }, "400": { "description": "Invalid request" }, "401": { "description": "Authentication failed" }, "422": { "description": "Request validation failed" } } } } }, "components": { "schemas": { "NoulQuestion": { "type": "object", "additionalProperties": false, "required": [ "type", "instructions" ], "properties": { "type": { "type": "string", "enum": [ "noul" ] }, "instructions": { "type": "string", "description": "The yes/no question for Jev to evaluate." }, "criteria": { "type": "object", "additionalProperties": false, "properties": { "true": { "type": "string", "description": "Description of what a yes or value near 1 means." }, "false": { "type": "string", "description": "Description of what a no or value near 0 means." } } } } }, "ChoiceQuestion": { "type": "object", "additionalProperties": false, "required": [ "type", "instructions", "criteria" ], "properties": { "type": { "type": "string", "enum": [ "choice" ] }, "instructions": { "type": "string", "description": "The question for Jev to decide between the supplied choices." }, "criteria": { "type": "object", "description": "A map where each property name is a possible choice and its value describes that choice.", "minProperties": 2, "additionalProperties": { "type": "string" } } } }, "ScoreQuestion": { "type": "object", "additionalProperties": false, "required": [ "type", "instructions", "criteria" ], "properties": { "type": { "type": "string", "enum": [ "score" ] }, "instructions": { "type": "string", "description": "The attribute or question Jev should score." }, "criteria": { "type": "array", "description": "Ordered scoring levels from lowest to highest.", "minItems": 2, "items": { "type": "string" } } } } }, "securitySchemes": { "bearerAuth": { "type": "apiKey", "name": "Authorization", "in": "header" } } }, "security": [ { "bearerAuth": [] } ] } We are going to use Jev to assess complaints so our instructions for the Agent will be You are a customer-support triage agent. For every customer-support message you MUST call the evaluate_with_jev tool. IMPORTANT: When calling evaluate_with_jev, construct Jev questions using ONLY the following property names: For a Noul question: { "type": "noul", "instructions": "...", "criteria": { "true": "...", "false": "..." } } For a Choice question: { "type": "choice", "instructions": "...", "criteria": { "option1": "...", "option2": "..." } } For a Score question: { "type": "score", "instructions": "...", "criteria": [ "lowest level", "middle level", "highest level" ] } NEVER use these properties: - question - prompt - options - ordered_criteria Always use: - instructions - criteria For customer support tickets, ask Jev these three questions: billing: type = noul instructions = "Does this ticket concern billing, payments, charges, invoices or refunds?" criteria.true = "The issue concerns billing or a financial transaction." criteria.false = "The issue does not concern billing or a financial transaction." tone: type = choice instructions = "What is the customer's tone?" criteria: calm = "Neutral, polite or informational." frustrated = "Dissatisfied, impatient or inconvenienced." angry = "Strongly confrontational or extremely dissatisfied." urgency: type = score instructions = "How urgently does this ticket require attention?" criteria in this exact order: 1. "Can wait" 2. "Handle this week" 3. "Handle today" Always set model to "jev-latest". Pass the customer's original message as state. Do not classify the ticket yourself. Use the values returned by Jev. Always show the Jev output at the end of the response Now we can give a complaint and see what Jev says The room had no water in and one of the towels was dirty Response I’m sorry about the issues you experienced—no running water and a dirty towel are unacceptable. I’ll get this addressed right away. Immediate help I can arrange now: Send maintenance to restore water. Have housekeeping deliver fresh towels and re-service the bathroom. Provide bottled water immediately. If water can’t be restored quickly, arrange a room move. Please share: Your reservation name and room number Best contact number Whether there’s no water at all or only hot/cold is affected Whether you prefer immediate service or a room change If you’ve already left, let me know the date/time this happened so we can investigate and follow up. Jev output: { "model": "jev-1.13.0", "answers": { "billing": { "type": "noul", "noul": 0.02 }, "tone": { "type": "choice", "choice": "frustrated", "confidence": 0.6, "probabilities": { "frustrated": 0.74, "calm": 0.26, "angry": 0.0 } }, "urgency": { "type": "score", "score": 1.81, "confidence": 0.72, "legend": { "0": "Can wait", "1": "Handle this week", "2": "Handle today" }, "probabilities": { "0": 0.03, "1": 0.12, "2": 0.85 } } }, "usage": { "input_tokens": 466, "output_tokens": 75 } } We can now see both Jev's decision and the probabilities behind it. In this example, Jev determines that the complaint is very unlikely to be billing-related, identifies the customer's tone as frustrated, and gives a high probability that the issue should be handled today. This is where Jev becomes particularly useful in an agent workflow. Rather than relying on generated text to drive the next step, our application can use these structured probabilities to make deterministic decisions, such as routing the complaint, escalating it, or requiring human review when confidence falls below a defined threshold.When AI Starts Taking Action: Building Execution Boundaries with OpenSandbox and AKS
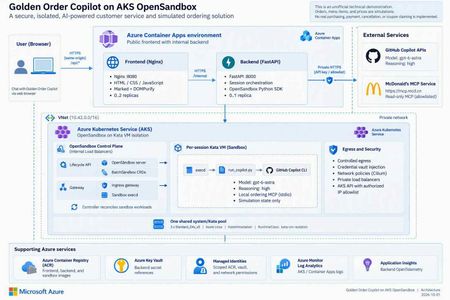
1. An agent needs more than a smarter model Imagine you are building a food-ordering assistant. In its first version, it says, “You might enjoy a burger and fries.” That is primarily a content-generation problem. In the next version, it queries coupons, reads a menu, calculates prices, creates files, and calls a local program to create an order. The engineering problem has changed. You are no longer asking a model to speak. You are allowing software to act on someone's behalf. This is a distinction I emphasize in technical talks: model capability determines what the agent can propose; the execution platform determines where, with which permissions, and for how long those proposals can become actions. Running every agent's tool processes inside the business API container creates awkward coupling. Leftover files, stuck processes, dependency changes, or excessive resource consumption from one session can affect another. Even if customers cannot invoke an arbitrary shell, CLI processes, tool dependencies, and temporary state still need boundaries. A sandbox is therefore not an instruction that says “please be safe.” It is a working environment with a lifecycle, a resource budget, and an access policy. Figure 1. A tool protocol, a working environment, and runtime isolation solve different problems. 2. Separate three concepts that often get conflated MCP describes tool interaction; it does not put tools inside a VM The Model Context Protocol gives model-facing applications a consistent way to discover and invoke tools. But “called through MCP” does not automatically mean “executed within a security boundary.” An MCP server can run on a developer's laptop, in a business-service container, remotely, or in a dedicated sandbox. Whether a tool can write data, who may invoke it, and how its side effects can be reversed are separate design questions. OpenSandbox makes the working environment an application resource OpenSandbox is an open-source platform for agent execution environments. It exposes sandbox lifecycle, command execution, file operations, and network-access capabilities. Applications use SDKs and APIs to create environments, run work, retrieve results, and clean up. Docker supports a local starting point; Kubernetes provides a cluster deployment path.1 Think of it as a workspace management system: it allocates a room, delivers materials, exposes ways to work, and reclaims the room at the end of its lease. The strength of the walls depends on the runtime and deployment underneath. OpenSandbox is not a language model, not a replacement for Kubernetes, and not synonymous with Kata. The upstream project also provides pools, multiple runtime paths, and snapshot-related capabilities. Availability, state semantics, and infrastructure requirements must be checked against the selected version and runtime. A project-wide feature list is not a promise that every backend behaves identically.1, 5 Kata adds a separate guest kernel to the sandbox pod Conventional containers generally share the host kernel. Kata Containers runs workloads in lightweight virtual machines, adding a VM boundary. With AKS Pod Sandboxing, the isolation unit is the pod using the Kata runtime, with its own guest kernel.2, 3 That does not mean every container in the same pod gets its own VM. Nor does a VM replace application authentication, outbound restrictions, or business approvals. The useful summary is: MCP defines the tool interface. OpenSandbox manages the working environment. Kata provides runtime isolation. The application still owns authorization and business rules. 3. What does “per-session Kata VM” actually isolate? In this project, a session is identified by session_id. The backend creates an OpenSandbox sandbox for a new session, and its pod selects the Kata RuntimeClass. Later requests in the same session reuse that environment. Several distinctions matter: It is not a new VM for every message. Related turns can reuse files and temporary state produced by the tools. It is not an Azure VM purchased for every user. Kata pod VMs run on AKS nodes; multiple sandboxes can share a node's underlying compute resources. It is not one sandbox per node. Capacity depends on resource settings, VM overhead, system components, and concurrent work. A session ID is not authorization. It identifies routing and resource mappings; production services must validate session ownership. My favorite analogy is a campus: AKS is the campus, nodes are buildings, Kata sandboxes are workrooms, and OpenSandbox is the workspace management system. A session repeatedly uses the same room; a lifecycle policy eventually clears it. That final step matters. Files surviving between turns does not mean they survive sandbox deletion. Orders, code artifacts, or audit records that must outlive the environment need explicit, governed persistence. Figure 2. This project hosts its frontend and backend in regular ACA, and OpenSandbox/Kata on AKS. Model inference is called through an external API, not hosted on the AKS nodes. 4. OpenSandbox on AKS: installation is not the finish line Kubernetes supplies scheduling and declarative resource management. OpenSandbox turns that infrastructure into sandbox operations that an application can consume. The execution path in this project is: The FastAPI backend requests a sandbox through the OpenSandbox SDK. The lifecycle service creates a BatchSandbox resource. The controller reconciles that declaration into a sandbox pod. The pod starts with the Kata runtime. The SDK accesses execd through the gateway for command and file operations. Deletion or expiration reclaims the sandbox. The upstream Kubernetes operator also supports pool allocation. However, warming an image in this sample is not the same as maintaining a ready-to-allocate pool of sandbox instances. Cached image layers and ready idle sandboxes are different latency optimizations.5 4.1 Declare the runtime, then verify the running boundary The important part of the project's BatchSandbox pod template is: spec: runtimeClassName: kata-vm-isolation nodeSelector: kubernetes.azure.com/kata-vm-isolation: "true" securityContext: seccompProfile: type: RuntimeDefault This is a fragment of the pod template, not a complete manifest that works independently of cluster prerequisites. The deployed example uses one shared system/Kata pool: three Standard_D4s_v5 Azure Linux nodes with KataVmIsolation, created through AKS API 2026-07-01. The model is gpt-6-astra accessed through GitHub Copilot APIs; this is not a GPU model-serving deployment. To avoid confusing “Kata appears in the configuration” with “the boundary is working,” deployment checks inspect the actual pool properties, three Ready nodes, the RuntimeClass, and the guest kernel inside a temporary Kata pod. The kernel check is a deployment acceptance signal, not a formal proof of the entire system's security. 4.2 More platform control also means more platform ownership OpenSandbox on AKS gives a team control over its runtime, images, network layout, and application integration. It also leaves the team responsible for node capacity, image provenance, control-plane upgrades, resource budgets, observability, recovery, and removal of temporary installation privileges. For simplicity, this demonstration uses a shared system/Kata pool. Three nodes are not presented as a high-availability guarantee. A production design should reconsider dedicated system and workload pools, zones, quotas, and tenant separation rather than copy the demonstration's footprint. 4.3 Credentials should be usable without being casually readable Credential Vault is especially interesting here. The trusted backend supplies credentials and bindings to OpenSandbox's egress sidecar. The Copilot workload process receives placeholders; the proxy injects authentication into matching outbound HTTPS requests.4 Precision matters: this reduces the workload's direct access to long-lived credentials; it does not make credentials disappear from the system. The backend and egress sidecar remain in the trusted computing base. It would be inaccurate to claim that real credentials can never exist anywhere within the pod VM. Preventing a model from reading a token also does not prevent misuse of operations authorized by that token. This project still restricts remote tools to read-only operations and uses exact hostname bindings for credential injection. Production systems should further scope operations, paths, tenants, and data. The upstream guide also explains that Kubernetes pause/resume can recreate the sidecar, requiring a trusted client to repopulate its in-memory vault.4 That distinction is valuable: restoring compute state, restoring identity context, and restoring business permissions are different operations. 5. Before comparing ACA Sandbox, stop treating it as another name for Dynamic Sessions Azure Container Apps includes several compute models: Model Primary concern Regular Container Apps Web apps, APIs, continuous services, and replica scaling Jobs Tasks that start, run, and complete Dynamic Sessions Isolated execution through a session pool and identifier Sandboxes Explicit lifecycle, state, and policy control over individual environments The current official overview describes ACA Sandboxes as a distinct resource model. A Microsoft.App/SandboxGroups resource is the management boundary for sandboxes, disk images, snapshots, volumes, and related resources. Documented capabilities include suspend/resume, memory and disk state, ports, egress policies, and Azure Blob/Data Disk volumes.6 Integration has its own control-plane contract: ARM manages sandbox groups, while the Sandboxes data plane manages individual instances, files, and related resources. The documentation requires a Microsoft Entra ID identity and the Container Apps SandboxGroup Data Owner role for sandbox management, assigned at an appropriate scope rather than granting broad access by default. These platform access requirements still do not replace your application's end-user authentication and authorization.6 Dynamic Sessions centers on Session Pool + identifier. A pool allocates a session, routes related requests to it, and reclaims it according to lifecycle and cooldown settings. Context can survive while that session exists; calling it “completely stateless per request” would be misleading. But it is not the same abstraction as a workspace with explicit snapshot and volume management.7, 8 There is also a release-status caveat. At the time of review, Microsoft Learn described these Sandboxes capabilities, while Microsoft's earlier repository documentation still carried an Early Access label and warned that early resources might need recreation.9 This article does not infer universal GA or regional access, nor does it treat the older “SDK coming soon” wording as current. Verify access, SDKs, RBAC, networking options, and service terms before adoption. Figure 3. This is an ownership comparison, not a security rating or performance ranking. 5.1 A comparison that helps make a decision Dimension OpenSandbox on AKS: this project's path ACA Sandboxes ACA Dynamic Sessions Main object OpenSandbox sandbox and Kubernetes workload Sandbox group and individual sandbox Session pool and identifier Platform operations Team operates OpenSandbox and configures AKS workloads/nodes; Azure still manages the AKS control plane Azure manages underlying infrastructure; the app explicitly manages sandbox lifecycle Azure manages pool allocation and session lifecycle Isolation This project explicitly selects Kata pod VMs Documented independent security boundary; this article does not infer a particular open-source runtime Officially documented Hyper-V isolation State Temporary per-session state here; upstream persistence/snapshot paths need separate configuration and validation Explicit suspend, resume, snapshots, and volumes Context while a session exists; treat state as ephemeral after reclamation Images and tools Custom images, CLI, MCP, and runtime policy OCI images converted to root filesystems; validate workload compatibility Built-in interpreters or custom container pools Network and credentials Team combines private networking, egress policy, Vault, and app authorization Service identity/network/policy capabilities; do not assume equivalence to OpenSandbox Vault Pool access and network controls; app owns identity and tool authorization Startup experience Depends on cache, scheduling, runtime, and initialization; no instant-start guarantee in this sample Documentation describes prewarmed subsecond startup/restore; measure your own workload Documentation describes low-latency prewarmed allocation; distinguish spare pool capacity from cold starts Team fit Kubernetes expertise and a need for deeper runtime control Managed infrastructure with explicit workspace state control Managed execution sessions without managing every environment's full lifecycle The ACA entries describe documented capabilities, not measurements from this project.6, 7, 8 A shared OCI image format does not make SDKs and APIs interchangeable. The existing backend depends on OpenSandbox creation, command-log, health, credential-proxy, and deletion semantics. Moving it to ACA Sandboxes requires mapping and testing those contracts, not changing an endpoint URL. Cost is also more than a price per hour. A useful measure is total cost per successfully completed task: execution resources, warm capacity, state storage, images, networking, logs, model usage, and operational effort. ACA documentation says stopped sandboxes incur no CPU/memory fees; that does not zero the bill for the application, storage, or dependencies. Deleting an AKS sandbox does not eliminate fixed node costs either.6 6. How I would choose for different scenarios Scenario A: upload a CSV and ask AI to run a short analysis If work is brief, the built-in runtime is sufficient, and state can be discarded afterward, I would evaluate Dynamic Sessions first to reduce platform work. Generated code remains untrusted input, and downloadable outputs still need content and authorization checks. Scenario B: a coding agent that works across turns and time This agent may need dependencies, a source tree, and process state. A user leaves, the environment pauses, and work continues later. ACA Sandboxes' explicit lifecycle is a compelling capability to validate. The design must still decide what may enter a snapshot, how credentials are reauthorized after restore, and how deletion policies meet business obligations. Scenario C: an enterprise with an established AKS platform If a team needs existing Kubernetes governance, runtime control, custom toolchains, or a platform built around a unified sandbox API, OpenSandbox on AKS is attractive. Its benefit is control and composability, not the assumption that open source removes operating costs. Scenario D: the agent only calls a governed business API If there is no generated-code execution, local tool process, or temporary filesystem requirement, a sandbox per user may be unnecessary. A regular ACA API with authentication, server-side permissions, and a well-defined tool gateway can be simpler. Not every agent needs a sandbox platform. These choices are not mutually exclusive. Our project uses regular ACA for the lightweight web/API layer and AKS for the execution plane. Different task classes could eventually use different execution backends, provided identity, lifecycle, results, and error contracts are explicit. 7. The concrete example: an ordering assistant that does not place real orders Project: kinfey/aks_opensbx_ghc_demo. This is an unofficial McDonald's-themed technical demonstration, not an official service or a real transaction system. Its value is not that AI can recommend a burger. It places several boundaries in an understandable business story: Application boundary: a public Nginx frontend and an internal FastAPI backend. Execution boundary: per-session OpenSandbox/Kata running Copilot CLI and local MCP. Operation boundary: selected read-only remote queries; order creation exists only in local simulation tools. Credential boundary: placeholders in the CLI workload, with authentication injected for allowed requests by a trusted egress proxy. Presentation boundary: original Markdown preserved in transit and sanitized before browser rendering. Figure 4. Querying external information and writing a simulated order are different paths, even when they appear in the same conversation. 7.1 What should a reasonable interaction look like? The following is an illustrative workflow, not an invented transcript of a live customer: A user asks, “Check current offers, then calculate a simulated meal.” The backend creates or reuses the session sandbox. Copilot invokes a read-only remote MCP tool for official offers rather than inventing them. Local get_menu and calculate_order tools price the simulation, clearly distinguished from official quotes. The assistant displays items and the total and asks for confirmation. Only after confirmation does it call local create_order, producing an explicitly simulated order. Session completion or the idle policy triggers sandbox cleanup; the order file is not retained as a durable business record. The tool rejects confirmed=false. Its limit should also be clear in any technical presentation: an agent-supplied boolean is not an independently authenticated, auditable purchase-approval system. Real commerce would require server-verifiable authorization bound to a user and the exact order contents. The current backend keeps session mappings in memory, runs at most one replica, and does not provide public user login or authenticated session ownership. These are demonstration constraints, not a production multitenancy template.10 7.2 Three lessons from making it work First: startup latency is not one number. An initial pull of the roughly 2.8 GB sandbox image took almost six minutes. That delay was not slow model inference, and it could not simply be attributed to feature approval. We moved image warmup outside the user request path and waited for actual execd health. End-to-end latency = queue/scheduling + image pull + guest startup + certificate/proxy setup + CLI startup + model/tool execution + result transport and rendering This is why a documented subsecond allocation from warm capacity should not be compared directly with one cold image pull in this project. A meaningful evaluation controls the image, cache state, concurrency, region, and measurement boundary, then tracks percentiles, failure rates, and cost per successful task. Second: a working isolation boundary does not guarantee a working data contract. We encountered a deceptively simple issue: the web renderer supported Markdown, but real replies still had no proper tables. CSS was not the problem: Copilot's default terminal output had already converted Markdown tables into character borders. Execd's line-oriented logging removed the terminators from nonempty lines. The fix extracted original assistant content from CLI JSONL, encoded it in a single-line JSON envelope across command logs, and decoded it back into Markdown in the backend. Marked and DOMPurify then preserved tables, headings, and code without inserting arbitrary model-generated HTML directly into the page. Third: acceptance must cover the real path. A browser test with a fixed reply proves that the renderer works, not that model output survives the CLI, logs, and API. The project added a live-model test that checks raw Markdown, actual DOM tables, mobile layout, and confirmed sandbox deletion.11 Similarly, successful remote tool use should be established from tool-execution events, not merely from the model saying “I checked.” The broader engineering rule is the same: prove completion with structured results and actual side effects, not a success-shaped sentence. 8. What I would add before calling this production I would not start by adding more tools. I would answer five questions: Question Required design Who owns the session? Authentication, tenant binding, server-side session ownership, and resource authorization Which state deserves to survive? Separate temporary workspace files, durable artifacts, business orders, and audit records Who may cause side effects? User approval bound to contents, idempotency, and auditable authorization beyond model instructions Where can the system fail? Stage-level startup metrics, admission control, budgets, timeouts, retries, and resource reclamation Can the execution backend change? Contract tests for create, execute, files, credentials, state restoration, and deletion For the last question, ACA Sandboxes is a worthwhile alternative backend to evaluate. But it should be a measured migration experiment with a deliberate identity design, not an untested promise of a seamless swap. Closing thought: an agent platform puts capability inside boundaries OpenSandbox gives applications an abstraction for working environments. AKS and Kata let a team implement that abstraction on observable, configurable infrastructure. ACA Sandboxes and Dynamic Sessions offer managed alternatives with different levels of operational ownership. I prefer to rewrite the selection question as three questions: What do we need to control? What are we willing to operate? How will we prove that execution completed as intended? Those questions are more useful than a simple “self-hosted versus serverless” debate. A reliable AI application needs both a capable model and a workspace with clear boundaries, a reclaimable lifecycle, and an auditable record of what happened. Further reading and scope Full deployment instructions: English README. Runnable source: project repository. The four diagram sets are original technical illustrations. imgs/ contains Chinese and English PNGs, scalable SVGs, and matching editable .excalidraw files. They are not benchmarks or product certifications. Resource descriptions are generic. Supply your own AZURE_RESOURCE_GROUP, AKS_NAME, and other configuration when reproducing the deployment. Sources OpenSandbox: scope, SDKs, runtimes, and examples Kata Containers: lightweight VM isolation OpenSandbox Credential Vault: broker and restore semantics, pinned revision OpenSandbox Kubernetes operator: BatchSandbox, Pool, snapshots, pinned revision Azure Container Apps Sandboxes overview Azure Container Apps Dynamic Sessions overview Official comparison of Dynamic Sessions and Sandboxes Microsoft's earlier ACA Sandboxes Early Access documentation This project: session management and runtime boundaries This project: real-reply end-to-end browser test401Views0likes0CommentsFrom Jev to Your Laptop: Building "System One" Decision Models in ONNX with Mobius
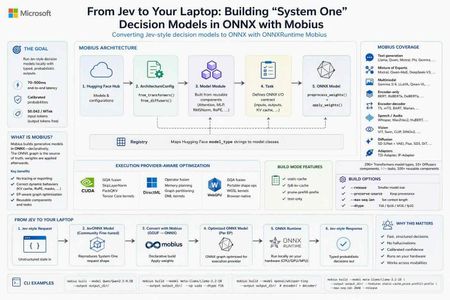
0. Why I'm writing this now Two things landed on my radar in the same week. First, TypeSafe AI published "Introducing System One Models & Jev" (Sep 15, 2026) and the developer community immediately started arguing about it. The pitch is unusual: instead of another chat model, Jev is described as "a new class of frontier models built to make fast, structured decisions that software can use directly." The post frames Jev as "a frontier-intelligence function call: unstructured state in, typed probabilistic decisions out" — and notes that while "Jev gives up string generation, it's optimized for structured outputs and can't hallucinate." The numbers in that post are what got everyone's attention: end-to-end response times of 70ms–500ms versus 3–329 seconds for frontier LLMs, input tokens at $0.042/MTok with output tokens free, and a claim that every answer arrives with a calibrated probability — "higher confidence means higher accuracy." The name itself is a thesis: TypeSafe named Jev after William Stanley Jevons, expecting that "every order of magnitude drop in the cost of intelligence unlocks orders of magnitude more use cases." Second — and this is the part that matters for anyone who builds on Microsoft's AI stack — onnxruntime/mobius has been quietly shipping at a furious pace. It's the piece of infrastructure that makes it realistic to take a model like this, in whatever format it arrives, and run it as an ONNX graph on hardware you control. So I built the bridge. kinfey/JevONNX takes an open, community-fine-tuned model that reproduces the System One request shape, converts it from GGUF to CPU ONNX with Mobius, and serves typed probabilistic decisions locally. This post covers three things: what Mobius is, how it differs from the ONNX Runtime GenAI Model Builder you may already be using, and how the JevONNX sample puts it together. 1. What is Mobius? Mobius builds generative models in ONNX. That preposition is the whole idea. From the repo's own description, Mobius provides "ONNX model definitions for GenAI using the onnxscript.nn API" — model definitions for "LLMs, MoE, multimodal, encoder-only, encoder-decoder, vision, audio, and diffusion models — built directly as ONNX graphs using onnxscript.nn.Module." The key sentence, and the one worth reading twice: "Rather than tracing or exporting PyTorch models, it constructs the ONNX graph declaratively, then applies pretrained HuggingFace weights." Why "declarative construction" is a big deal If you've ever exported a model to ONNX the traditional way, you know the failure modes. You run torch.onnx.export, the tracer executes one concrete path through Python control flow, and anything dynamic — a KV cache branch, a rotary embedding computed with a Python if, a sliding-window mask — either silently bakes in a constant or explodes into an unreadable subgraph. You then spend a week diffing graphs. Mobius inverts this. The graph is the source of truth, written as composable modules, and the weights are applied afterwards. The architecture in the README is four clean layers: HuggingFace Hub │ ▼ ArchitectureConfig ◄── from_transformers() / from_diffusers() │ ▼ Model Module ◄── Reusable Components (Attention, MLP, RMSNorm, RoPE, …) │ ▼ Task ◄── CausalLMTask, VisionLanguageTask, VAETask, DenoisingTask, … │ ▼ ONNX Model ◄── preprocess_weights() + apply_weights() Components — onnxscript.nn.Module building blocks (Attention, MLP, DecoderLayer, RoPE, VisionEncoder, MoELayer…) Models — full architectures composed from those components Tasks — define the ONNX graph's I/O contract (inputs, outputs, KV cache) Registry — maps HuggingFace model_type strings to model classes Adding a new architecture becomes writing a model definition, not debugging an exporter. Mobius even ships developer skills in .agents/skills/ (adding-a-new-model, reusable-components, moe-models, multimodal-models, writing-tests, writing-rewrite-rules) so an AI coding agent can do the legwork with you. Coverage This isn't a toy. The repo claims 290+ Transformers model types and 10 Diffusers component types across 40+ task types and 100+ reusable components, spanning: Category Examples Text generation Llama 2/3/4, Mistral, Qwen 2/2.5/3/3.5/3.6, Phi-3/3.5, Gemma 1/2/3/4, Granite, GPT-2, OPT, OLMo, SmolLM3 Mixture of Experts PhiMoE, GPTOSS, Mixtral, OLMoE, DeepSeek-V2/V3, Qwen2-MoE, Qwen3-MoE, Qwen3-Next, GLM-4-MoE, Arctic, DBRX, Jamba Multimodal Gemma 3/4, Phi-4MM (vision + audio + LoRA), LLaVA, InternVL2, MiniCPM-V 4.6, Qwen2.5-VL, Qwen3-VL, Pixtral Encoder-only BERT, RoBERTa, ALBERT, DeBERTa, DistilBERT, ELECTRA, XLNet Encoder-decoder BART, T5/mT5, Marian, M2M-100, Pegasus, BigBird-Pegasus Speech-to-text Whisper, Moonshine, Moonshine Streaming, FastConformer-RNNT, FunASR, GLM-ASR, Qwen3-ASR, SenseVoice Audio Wav2Vec2, HuBERT, WavLM, SpeechT5 Vision ViT, BEiT, DeiT, DINOv2, Swin, CLIP, SigLIP Diffusion Stable Diffusion (UNet + VAE + ControlNet), Flux, SD3, DiT, QwenImage / Qwen-Image-Edit-2509, HunyuanDiT, CogVideoX Adapters T2I-Adapter, IP-Adapter The five-minute version pip install -e . from mobius import build pkg = build("meta-llama/Llama-3.2-1B") pkg.save("output/llama-3.2-1b/") Static KV cache, when you know your max sequence length up front: from mobius import build, CausalLMTask task = CausalLMTask(static_cache=True, max_seq_len=2048) pkg = build("meta-llama/Llama-3.2-1B", task=task) pkg.save("output/llama-3.2-1b-static/") EP-aware optimization — the graph itself is tuned per execution provider, "each with the right set of fused kernels and lowering passes applied automatically": # CUDA: GQA fusion, SkipLayerNorm, PackQKV pkg = build("meta-llama/Llama-3.2-1B", execution_provider="cuda", dtype="f16") # WebGPU: GQA fusion, Shape ops replaced with portable alternatives pkg = build("meta-llama/Llama-3.2-1B", execution_provider="webgpu", dtype="f16") And the CLI, which is what we'll use later: mobius build --model Qwen/Qwen2.5-0.5B --output output_dir/ mobius build --model meta-llama/Llama-3.2-1B --output output_dir/ --ep cuda --dtype f16 mobius build --model openai/whisper-tiny --output output_dir/ # encoder/ + decoder/ Build-mode toggles use a cargo-style --features flag — available features are static-cache, fp8-kv-cache, prune-prefill-prefix, and text-only: mobius build --model meta-llama/Llama-3.2-1B --output output_dir/ \ --features static-cache,prune-prefill-prefix --max-seq-len 2048 --release strips build-time debug and provenance metadata to reduce saved model size, while preserving functional metadata keyed with the mobius. prefix. 2. Mobius vs. the ONNX Runtime GenAI Model Builder This is the question I get every time I demo Mobius, so let's be precise. Both are Microsoft tools, both produce ONNX, and they are not competitors — they sit at different points on the same pipeline. The ONNX Runtime GenAI Model Builder describes itself as the tool "for quickly creating optimized and quantized ONNX models within a few minutes that run with ONNX Runtime GenAI." Its output is a deployment-ready package: model.onnx plus genai_config.json plus tokenizer files, wired for the onnxruntime-genai runtime. Its architecture list is explicitly curated — AMD OLMo, ChatGLM, DeepSeek, ERNIE 4.5, Gemma, gpt-oss, Granite, Granite MoE Hybrid, HunYuan Dense V1, InternLM2, LFM2, LFM2 MoE, Llama, Mistral, Nemotron, Phi, Qwen, SmolLM3, Whisper — and the README states plainly that "it is intended for supporting the latest, popular state-of-the-art models." Mobius, by contrast, is a model-definition library: a component algebra for describing generative architectures as ONNX graphs, with a registry mapping HuggingFace model_type strings to model classes. Here's how I'd separate them: Dimension ORT GenAI Model Builder Mobius Primary goal Produce a deployment-ready GenAI package, fast Define and construct the ONNX graph itself Output contract model.onnx + genai_config.json + tokenizer, targeted at the ORT GenAI runtime ONNX model package; you choose the runtime (plain ORT sessions included) How the graph is made Per-architecture builder subclasses (LlamaModel, QwenModel, Phi3MiniModel, WhisperModel…) overriding make_layer / make_attention / make_moe Declarative onnxscript.nn.Module composition from reusable Components → Models → Tasks Breadth Curated list of ~19 popular families, text + Whisper 290+ Transformers types, 10 Diffusers component types, 40+ tasks — including vision, audio, and diffusion Extending it Add a builder subclass inside the onnxruntime-genai tree Add a model definition from existing components; shipped .agents/skills/ guide it Tuning surface Rich --extra_options for quantization and runtime behavior (QMoE, paged attention, KV-cache quantization, QDQ, CUDA/WebGPU graph capture…) --features build toggles + execution_provider= EP-aware graph lowering + dtype control Diffusion / multi-component pipelines Not the target First-class (--model Qwen/Qwen-Image-2512 builds all components) When I reach for it "I have a Phi/Llama/Qwen chat model and I want an int4 CPU/CUDA package running under ORT GenAI today" "My architecture is hybrid, unusual, multimodal, diffusion, or I need graph-level control over what gets emitted" Notably, the two overlap on real capabilities. The Model Builder also consumes GGUF and handles Qwen3.5-class features (compact state updates, recurrent-operator selection). Mobius also emits ORT-GenAI-compatible metadata — though the repo is honest about limits: for Mage-VL, "ORT GenAI export is currently rejected because the runtime cannot supply its required patch_positions input or Mage-VL's 1D decoder positions." That single line tells you exactly where the boundary sits: the Model Builder is bounded by what the GenAI runtime can express; Mobius is bounded by what ONNX can express. My rule of thumb as an advocate: if your model is on the Model Builder's supported list and you want the GenAI runtime's generation loop, use the Model Builder — it is faster and gives you a complete package. The moment you're off that list, or you need the graph itself to be a first-class artifact you can reason about and modify, Mobius is the tool. The JevONNX sample is squarely in the second category. Let's look at why. 3. The sample: converting a Jev-style decision model to CPU ONNX Repo: github.com/kinfey/JevONNX 3.1 The honest framing first Jev is TypeSafe's proprietary model. You can't download it and convert it, and this project doesn't pretend otherwise. What the community did do is interesting: n4ze3m/Qwen3.5-4B-Hmm is "an experimental open-model attempt to reproduce the central idea and request shape of the System One workflow introduced with Jev." It works by "fine-tuning Qwen3.5-4B to answer typed questions through option probabilities instead of ordinary generated text." The README of JevONNX is emphatic about the boundaries, and I want to repeat them here rather than bury them: "Hmm is not Jev, is not affiliated with TypeSafe AI, and does not reproduce Jev's proprietary model architecture, parallel sampler, performance, calibration, or type-safety guarantees. The Hmm model card explicitly states that it is less capable than Jev." And: "The reproduction is behavioral rather than architectural." The distinction, straight from the project's comparison table: Property Jev Hmm in this project Model design Native System One Model Qwen3.5-4B fine-tuned to reproduce the typed-decision concept Output mechanism Native typed probabilistic outputs First-token option-letter probabilities Multiple questions Designed for parallel sampling Jev-like request shape, implemented as one model pass per question Output types Schema-constrained structured values noul, choice, and score adapter Runtime here TypeSafe service Local ONNX Runtime CPU Guarantees As documented by TypeSafe No equivalent guarantee is claimed The mechanism is refreshingly legible: the adapter turns each typed question into an exact multiple-choice prompt, then "reads the first generated-token logits for A, B, C, and subsequent option letters and normalizes them into probabilities." No JSON parsing, no retry-on-malformed-output, no regex. The probability distribution is the answer. 3.2 Why this needs Mobius specifically Qwen3.5 is a hybrid architecture, and that's the whole reason this is a Mobius story. The exported model has 32 hybrid decoder layers. Linear-attention layers carry conv_state and recurrent_state; full-attention layers carry key/value caches. In this artifact, full-attention layers sit at indices 3, 7, 11, 15, 19, 23, 27, and 31. The practical consequence, quoted from the README: "The prompt is processed one token at a time while every present.* output is fed back into its corresponding past_key_values.* input. This differs from a conventional decoder-only example that can prefill an entire prompt in one call." That is a graph-shape problem. You cannot handwave it with a config flag — you need the exported graph's state contract to be explicit and inspectable, which is exactly what declarative construction gives you. The implementation "follows the structure of Mobius examples/text_generation.py while adding the hybrid-state handling required by Qwen3.5." 3.3 The conversion pipeline n4ze3m/Qwen3.5-4B-Hmm-Q4_K_M.gguf │ SHA-256 verification ▼ Mobius GGUF reader/importer │ metadata and tensor mapping │ Qwen3.5 hybrid graph construction │ Q4_K_M → packed quantized target storage │ CPU execution-provider optimization ▼ onnx_outputs/ ├── model.onnx ├── model.onnx.data ├── quantization_report.json ├── tokenizer.json ├── tokenizer_config.json ├── chat_template.jinja └── cpu_test_summary.json │ ▼ ONNX Runtime CPUExecutionProvider │ token-by-token hybrid-state prefill │ first-token A/B/C/… probabilities ▼ typed decision JSON response One command does the conversion: mobius build-gguf Qwen3.5-4B-Hmm-Q4_K_M.gguf \ --output onnx_outputs \ --ep cpu \ --dtype f32 \ --release Two details worth internalizing: --dequantize is intentionally not used. Keeping quantized storage "substantially reduc[es] the output size compared with a fully dequantized FP32 model." The external-data file is still ~2.6 GB — imagine it dequantized. Don't trust the preset, read the report. "Q4_K conversion can involve a lossy affine repack; inspect quantization_report.json rather than assuming source-preset fidelity." This is the kind of line that separates a demo from a deployment. 3.4 Reproducibility — the part I actually want you to copy Every pin, in a table, in the README: Component Revision GGUF repository n4ze3m/Qwen3.5-4B-Hmm GGUF revision c27fa3c627dfaced343c6ba9d3a0d00243a3be51 GGUF filename Qwen3.5-4B-Hmm-Q4_K_M.gguf GGUF SHA-256 5e03cb057049c56b421bd3c506d77fd8e0a77996bb8464148a02cfc3caac5229 Mobius revision 6b27a3f08b8b5d08ba9b14b416e3b435942bb0bd Tokenizer repository Qwen/Qwen3.5-4B Tokenizer revision 851bf6e806efd8d0a36b00ddf55e13ccb7b8cd0a The notebook builds a Mobius wheel from the pinned Git source rather than installing a prebuilt package. On a project moving at 500+ commits, that is not paranoia — that is the only way your conversion is still reproducible next month. 3.5 Running it Two files carry the project: Qwen3_5_4B_Hmm_GGUF_to_CPU_ONNX_Mobius_fixed.ipynb (the Colab conversion and validation workflow) and run_hmm_onnx.py (the standalone typed-decision runner). Run the notebook in a high-memory Colab CPU runtime; it writes to /content/onnx_outputs on Colab and .mobius_colab_run/onnx_outputs elsewhere. Then: python run_hmm_onnx.py --model-dir .mobius_colab_run/onnx_outputs python run_hmm_onnx.py --model-dir .mobius_colab_run/onnx_outputs --request request.json A request is state plus typed questions: { "state": "Help! My payouts have failed for 3 days. I need the money today.", "questions": { "is_urgent": { "type": "noul", "instructions": "Does this message convey urgency?" }, "department": { "type": "choice", "instructions": "Which team should handle this?", "criteria": { "billing": "Payments, invoicing, refunds", "technical": "Bugs, outages, integrations", "sales": "Pricing, upgrades, new accounts" } }, "priority": { "type": "score", "instructions": "How urgent is this request?", "criteria": ["Not urgent", "Normal", "Urgent", "Critical"] } } } From Python: from pathlib import Path from run_hmm_onnx import HmmOnnx model = HmmOnnx(Path(".mobius_colab_run/onnx_outputs")) response = model.decide({ "state": "Help! My payouts have failed for 3 days.", "questions": { "is_urgent": { "type": "noul", "instructions": "Does this message convey urgency?", } }, }) print(response) 3.6 The three decision types noul — a nullable-style yes/no probability; the probability of the true option: { "type": "noul", "noul": 0.9745 } choice — the highest-probability key, all normalized option probabilities, and a confidence value measuring how peaked the distribution is: { "type": "choice", "choice": "billing", "probabilities": { "billing": 0.7216, "technical": 0.2759, "sales": 0.0025 }, "confidence": 0.5823 } score — the expected numeric level, the level legend, normalized probabilities, and confidence: { "type": "score", "score": 2.6653, "legend": { "0": "Not urgent", "1": "Normal", "2": "Urgent", "3": "Critical" }, "probabilities": { "0": 0.0061, "1": 0.0361, "2": 0.2443, "3": 0.7135 }, "confidence": 0.618 } Look at that score output for a second. You don't get "this is critical." You get 2.6653 — a distribution leaning hard on Critical but with real mass on Urgent. That's a number your routing code can threshold on, log, and A/B test. It's the difference between an LLM that says it's confident and a distribution you can actually calibrate against. One constraint: Hmm is trained with 26 option letters. Larger option sets are handled by splitting them into groups of 25 and adding a none_of_these option to each group, matching the reference Hmm server strategy. 3.7 Does it actually run? Yes — the README reports the generated model executed directly on an Apple Silicon CPU with ONNX Runtime. A 4B hybrid-architecture model, converted from GGUF, running typed decisions on a laptop CPU with no service dependency. 4. What I'd tell a room of developers The System One idea is portable even where the model isn't. You can't run Jev locally, but the shape — state in, typed decisions with probabilities out — is something you can prototype today with an open model and an ONNX graph. As TypeSafe puts it, structured outputs "slot into ordinary software as fuzzy decision rules: classify, route, score, extract, or branch where hand-written logic is too brittle." That's a pattern, not a product. Probabilities are the actual product. The reason this class of model matters isn't speed alone. TypeSafe's argument is sharp: "If a model can do a task 95% of the time but doesn't say when it's in the 5%, it can't automate that task." Every engineer who has shipped an LLM feature has felt that exact wall. Set expectations honestly. JevONNX is an educational reproduction. It gives you noul/choice/score on a local CPU. It does not give you Jev's calibration, parallel sampler, or type-safety guarantees — and the project says so in its own README. Ship that caveat with your demo. Mobius is the infrastructure bet worth learning. When a new architecture shows up — hybrid attention, a novel MoE routing scheme, a three-model multimodal export — the question stops being "will the exporter support it?" and becomes "which components do I compose?" That is a much better question to be asking. Links Mobius — https://github.com/onnxruntime/mobius (docs: https://onnxruntime.github.io/mobius/) ONNX Runtime GenAI Model Builder — https://github.com/microsoft/onnxruntime-genai/tree/main/src/python/py/models JevONNX sample — https://github.com/kinfey/JevONNX Introducing System One Models & Jev — https://typesafe.ai/blog/introducing-system-one-models-and-jev Hugging face - https://huggingface.co/lokinfey/Qwen3_5_4B_Hmm_ONNX1.2KViews1like0CommentsGenRec Direct Learning: Moving Ranking from Feature Pipelines to Token-Native Sequence Modeling
Authors: Chunlong Yu, Han Zheng, Jie Zhu, Neal Zhang, Li Xia, Lin Zhu, Sawyer Shen, Yulan Yan TL;DR Most modern ranking stacks rely on large generative models as feature extractors, flattening their outputs into vectors that are then fed into downstream rankers. While effective, this pattern introduces additional pipeline complexity and often dilutes token‑level semantics. GenRec Direct Learning (DirL) explores a different direction: using a generative, token‑native sequential model as the ranking engine itself. In this formulation, ranking becomes an end‑to‑end sequence modeling problem over user behavior, context, and candidate items—without an explicit feature‑extraction stage. Why revisit the classic L2 ranker design? Large‑scale recommender systems have historically evolved as layered pipelines: more signals lead to more feature plumbing, which in turn introduces more special cases. In our previous L2 ranking architecture, signals were split into dense and sparse branches and merged late in the stack (Fig. 1). As the system matured, three recurring issues became increasingly apparent. Figure 1: traditional ranking DNN 1) Growing pipeline surface area Each new signal expands the surrounding ecosystem—feature definitions, joins, normalization logic, validation, and offline/online parity checks. Over time, this ballooning surface area slows iteration, raises operational overhead, and increases the risk of subtle production inconsistencies. 2) Semantics diluted by flattening Generative models naturally capture rich structure: token‑level interactions, compositional meaning, and contextual dependencies. However, when these representations are flattened into sparse or dense feature vectors, much of that structure is lost—undermining the very semantics that make generative representations powerful. 3) Sequence modeling is treated as an add-on While traditional rankers can ingest history features, modeling long behavioral sequences and fine‑grained temporal interactions typically requires extensive manual feature engineering. As a result, sequence modeling is often bolted on rather than treated as a first‑class concern. DirL goal: treat ranking as native sequence learning, not as “MLP over engineered features.” What “Direct Learning” means in DirL The core shift behind Direct Learning (DirL) is simple but fundamental. Instead of the conventional pipeline: generative model → embeddings → downstream ranker, DirL adopts an end‑to‑end formulation: tokenized sequence → generative sequential model → ranking score(s). In DirL, user context, long‑term behavioral history, and candidate item information are all represented within a single, unified token sequence. Ranking is then performed directly by a generative, token‑native sequential model. This design enables several key capabilities: Long‑term behavior modeling beyond short summary windows The model operates over extended user histories, allowing it to capture long‑range dependencies and evolving interests that are difficult to represent with fixed‑size aggregates. Fine‑grained user–content interaction learning By modeling interactions at the token level, DirL learns detailed behavioral and content patterns rather than relying on coarse, pre‑engineered features. Preserved cross‑token semantics within the ranking model Semantic structure is maintained throughout the ranking process, instead of being collapsed into handcrafted dense or sparse vectors before scoring. Architecture overview (from signals to ranking) 1) Unified Tokenization All inputs in DirL are converted into a shared token embedding space, allowing heterogeneous signals to be modeled within a single sequential backbone. Conceptually, each input sequence consists of three token types: User / context tokens These tokens encode user or request‑level information, such as age or cohort‑like attributes, request or canvas context, temporal signals (e.g., day or time), and user‑level statistics like historical CTR. History tokens These represent prior user interactions over time, including signals such as engaged document IDs, semantic or embedding IDs, and topic‑like attributes. Each interaction is mapped to a token, preserving temporal order and enabling long‑range behavior modeling. Candidate tokens Each candidate item to be scored is represented as a token constructed from document features and user–item interaction features. These features are concatenated and projected into a fixed‑dimensional vector via an MLP, yielding a token compatible with the shared embedding space. Categorical features are embedded directly, while dense numerical signals are passed through MLP layers before being fused into their corresponding tokens. As a result, the model backbone consumes a sequence of the form: [1 user/context token] + [N history tokens] + [1 candidate token] 2) Long-sequence modeling backbone (HSTU) To model long input sequence, DirL adopts a sequential backbone designed to scale beyond naïve full attention. In the current setup, the backbone consists of stacked HSTU layers with multi‑head attention and dropout for regularization. The hidden state of the candidate token from the final HSTU layer is then fed into an MMoE module for scoring. 3) Multi-task prediction head (MMoE) Ranking typically optimizes multiple objectives (e.g., engagement‑related proxies). DirL employs a multi‑gate mixture‑of‑experts (MMoE) layer to support multi‑task prediction while sharing representation learning. The MMoE layer consists of N shared experts and one task‑specific expert per task. For each task, a gating network produces a weighted combination of the shared experts and the task‑specific expert. The aggregated representation is then fed into a task‑specific MLP head to produce the final prediction. Figure 2: DirL structure Early experiments: what worked and what didn’t What looked promising Early results indicate that a token‑native setup improves both inhouse evaluation metrics and online engagement (time spent per UU), suggesting that modeling long behavior sequences in a unified token space is directionally beneficial. The hard part: efficiency and scale The same design choices that improve expressiveness also raise practical hurdles: Training velocity slows down: long-sequence modeling and larger components can turn iteration cycles from hours into days, making ablations expensive. Serving and training costs increase: large sparse embedding tables + deep sequence stacks can dominate memory and compute. Capacity constraints limit rollout speed: Hardware availability and cost ceilings become a gating factor for expanding traffic and experimentation. In short: DirL’s main challenge isn’t “can it learn the right dependencies?”—it’s “can we make it cheap and fast enough to be a production workhorse?” Path to production viability: exploratory directions Our current work focuses on understanding how to keep the semantic benefits of token‑native modeling while exploring options that could help reduce overall cost. 1) Embedding tables consolidate and prune oversized sparse tables rely more on shared token representations where possible 2) Right-size the sequence model reduce backbone depth where marginal gains flatten evaluate minimal effective token sets—identify which tokens actually move metrics. explore sequence length vs. performance curves to find the “knee” 3) Inference and systems optimization dynamic batching tuned for token-native inference kernel fusion and graph optimizations quantization strategies that preserve ranking model behavior Why this direction matters DirL explores a broader shift in recommender systems—from feature‑heavy pipelines with shallow rankers toward foundation‑style sequential models that learn directly from user trajectories. If token‑native ranking can be made efficient, it unlocks several advantages: Simpler modeling interfaces, with fewer feature‑plumbing layers. Stronger semantic utilization, reducing information loss from aggressive flattening. A more natural path to long‑term behavior and intent modeling. Early signals are encouraging. The next phase is about translating this promise into practice—making the approach scalable, cost‑efficient, and fast enough to iterate as a production system. Using Microsoft Services to Enable Token‑Native Ranking Research This work was developed and validated within Microsoft’s internal machine learning and experimentation ecosystem. Training data was derived from seven days of MSN production logs and user behavior labels, encompassing thousands of features, including numerical, ID‑based, cross, and sequential features. Model training was performed using a PyTorch‑based deep learning framework built by the MSN infrastructure team and executed on Azure Machine Learning with a single A100 GPU. For online serving, the trained model was deployed on DLIS, Microsoft’s internal inference platform. Evaluation was conducted through controlled online experiments on the Azure Exp platform, enabling validation of user engagement signals under real production traffic. Although the implementation leverages Microsoft’s internal platforms, the core ideas behind DirL are broadly applicable. Practitioners interested in exploring similar approaches may consider the following high‑level steps: Construct a unified token space that captures user context, long‑term behavior sequences, and candidate items. Apply a long‑sequence modeling backbone to learn directly from extended user trajectories. Formulate ranking as a native sequence modeling problem, scoring candidates from token‑level representations. Evaluate both model effectiveness and system efficiency, balancing gains in expressiveness against training and serving cost. Call to action We encourage practitioners and researchers working on large‑scale recommender systems to experiment with token‑native ranking architectures alongside traditional feature‑heavy pipelines, compare trade‑offs in modeling power and system efficiency, and share insights on when direct sequence learning provides practical advantages in production environments. Acknowledgement: We would like to acknowledge the support and contributions from several colleagues who helped make this work possible. We thank Gaoyuan Jiang and Lightning Huang for their assistance with model deployment, Jianfei Wang for support with the training platform, Gong Cheng for ranker monitoring, Peiyuan Xu for sequential feature logging, and Chunhui Han and Peng Hu for valuable discussions on model design.Build an AI-assisted support email workflow with Power Automate and Microsoft Foundry
Difficulty: Intermediate A support email arrives with a product name, an error code, and a country. Before anyone can help, someone has to interpret the request, find the right team, record the case, and decide what to tell the customer. In this tutorial, you build that support email workflow with Microsoft 365, Power Automate, Azure Functions, and Microsoft Foundry. AI extracts the request details and recommends a support team. The flow checks the recommendation against a SharePoint catalog, asks a person to approve it, and creates an editable Outlook acknowledgement draft. The central design decision is who can do what: the model proposes a routing key; the flow validates it; a person approves draft creation. No customer-facing send action is included. What you will build Mina manages support operations at Aster Imaging, a fictional imaging-equipment company. Claire, a fictional distributor in France, reports error E42 on a NovaScan X2 after installing software version 4.2.1. When Mina approves the validated recommendation, the workflow produces: Input or decision Recorded result Claire's support email One case linked to its source message ID Validated AI recommendation Technical Support, NovaScan X2, France, EU Distributor Support Mina selects Approve Approval outcome and an editable acknowledgement draft Missing information, a risk flag, rejection, or timeout A case held in Needs Review The recorded approved case shows the review outcome and successful automation state: All names, products, organizations, and test messages are synthetic. This is a reference implementation for a lab, based on public support-form patterns, rather than a description of a company's internal process. Who this is for This walkthrough is for Power Platform makers and developers who can already create a cloud flow and a SharePoint list, and want to connect AI to a workflow with explicit review boundaries. You will use the Azure portal and a few terminal commands to deploy the supplied Function project. In this tutorial Architecture and resources Tutorial scope and boundaries Prerequisites Download the sample Step 1: Prepare the mailbox and SharePoint lists Step 2: Deploy and connect the AI classifier Step 3: Build and validate the support email flow Step 4: Add human approval, create a draft, and evaluate the workflow Troubleshooting Production considerations Clean up the lab Architecture and resources Workflow architecture The completed workflow follows this path: When Claire's message arrives in the shared mailbox, Power Automate first checks the message ID to avoid creating a duplicate case. It then sends the subject and body to the AI classifier. The classifier identifies the request as technical support, extracts NovaScan X2 and France , and recommends EU Distributor Support . Power Automate does not accept that recommendation without verification. It checks the structured response, confidence band, and risk flags, and confirms that the recommended routing key matches an active entry in the SupportTeams list. If the checks pass, the workflow records the case in SharePoint and asks Mina to review the recommendation. If Mina approves it, Power Automate creates an acknowledgement draft in Outlook. It does not send the message. If the recommendation has low confidence, contains a risk flag, fails validation, or is rejected by Mina, the case remains in Needs Review . Resource names To keep the steps consistent and easy to follow, this tutorial uses the resource names below. You can use different names in your environment, but keep track of the corresponding values as you work through the steps. Resource Name Power Platform environment RW Development Solution RW Global Support Intake Publisher prefix rw SharePoint site RW Lab SharePoint lists Cases , SupportTeams Shared mailbox RW Lab Support Main flow RW - Global Support Intake - v1 Azure resource group Your lab resource group; referenced as <RESOURCE_GROUP> Microsoft Foundry resource Your globally unique resource; referenced as <FOUNDRY_RESOURCE_NAME> Microsoft Foundry project The project opened in the Foundry portal; referenced as <FOUNDRY_PROJECT_NAME> Model deployment gpt-5.4-mini Azure Function App Your globally unique app; referenced as <FUNCTION_APP_NAME> Tutorial scope and boundaries This tutorial builds the workflow in stages so that each layer can be tested before the next one is introduced. Step 1 prepares the shared mailbox and SharePoint records. Step 2 deploys the AI model and exposes the bounded classifier to Power Automate. Step 3 builds the support email flow and validates normal, review, fallback, and duplicate paths before approval exists. Step 4 adds human approval and draft creation, then evaluates the completed workflow end to end. What this tutorial covers Create a shared mailbox, SharePoint case register, and allow-listed support-team catalog. Connect a bounded AI classifier that returns structured fields and an advisory routing key. Build deterministic deduplication, recommendation validation, and exception paths in Power Automate. Add a human approval checkpoint that creates an Outlook draft without sending it. Walk through three representative paths: accepted recommendation, review hold, and approval timeout. Record the remaining synthetic checks in a compact validation matrix. What is out of scope Send customer-facing email automatically. Let AI assign the final owner, approve a request, change SupportTeams , or send a message. Process real customer data, retrieve attachment contents, or scan attachments. The mailbox flow passes attachments = [] ; attachment-metadata checks are exercised only in the direct classifier tests. Merge a new follow-up email into an existing case. The duplicate guard checks the same message ID; a new reply has a different ID. Treat the prototype results as production accuracy, security, capacity, or SLA claims. Prerequisites A Microsoft 365 test tenant with Exchange Online and SharePoint Online A licensed test user who can open Outlook and SharePoint Permission to create a shared mailbox and assign mailbox delegation A Power Platform environment with Dataverse for the solution and approvals, and permission to use the Office 365 Outlook, SharePoint, Approvals, and custom connectors For a development-only lab, an eligible Power Apps Developer Plan environment; otherwise, Power Automate use rights that cover this flow and its custom connector An Azure subscription in which you can create or select a Microsoft Foundry resource, deploy a model, and create an Azure Functions app Permission to enable the Function app's managed identity and assign it the Cognitive Services OpenAI User role Node.js 22, Azure CLI, and Azure Functions Core Tools v4 on the workstation used for deployment; the tested Core Tools version is 4.0.7512 Permission to create custom connectors, connection references, environment variables, and solutions in the Power Platform environment Licensing and cost Microsoft 365 access alone does not establish entitlement to the custom connector used here. Confirm the target environment's license and data policies before building the flow. The Developer Plan includes custom connectors for development and testing; production use needs appropriate paid rights. See the Power Platform licensing FAQ. Azure model inference, Function hosting, storage, and monitoring can incur charges. Usage depends on the selected region, hosting plan, model, message size, and test volume. Check those resources in Azure Cost Management and clean up the dedicated lab resources when finished. The recorded evaluation is not a cost benchmark. Download the sample Get the companion code from the example project on GitHub. Clone the repository or download and extract the ZIP to a local folder. Use the extracted repository folder as the sample root in the commands below. The repository contains the Function source, locked dependencies, connector definition, synthetic data, setup instructions, and local tests. You build the Power Automate flow in the designer; this sample is not an importable Power Platform solution. Path from the sample root Purpose azure/global-support-classifier/ Deployable Azure Function project azure/global-support-classifier/connector/apiDefinition.swagger.json Custom connector definition; replace its sample host before import data/aster-imaging/support-teams.json Twelve sample team keys and descriptions data/aster-imaging/inquiries.json Twenty synthetic inquiries and expected results tests/aster-imaging-fixtures.test.mjs Offline dataset checks tests/global-support-classifier-regression.mjs Authenticated classifier evaluation evidence/classifier-regression-20260808.md Historical lab result and evaluation limits The model evaluation results come from the August 8, 2026 lab. This article combines recorded lab screenshots with configuration screens recaptured on September 8–9, 2026 for clearer step-by-step instructions. Recapturing a configuration screen does not verify a new workflow run. A separate single-request connector test on September 8, 2026 returned HTTP 200 and passed schema validation; its input and response are shown in Step 2. The GitHub v0.1.0 sample preserves the September 8, 2026 implementation snapshot, with repository setup documentation added on September 9. Portal labels, model availability, and quotas can differ in your tenant. Step 1: Prepare the mailbox and SharePoint lists In this step, you prepare the Microsoft 365 resources used by the workflow. The shared mailbox receives support requests, the SharePoint site provides a private workspace, the Cases list stores each request and its workflow state, and the SupportTeams list defines the support teams that the AI classifier is allowed to recommend. Services and tools used in this step Service Purpose Exchange Online Create the shared support mailbox and assign mailbox permissions. SharePoint Online Create the private team site and the Cases and SupportTeams SharePoint lists. Create the shared support mailbox The shared mailbox provides a single email address for support requests. Power Automate monitors this mailbox and starts the workflow when a new message arrives. For example, Claire sends her request to RW Lab Support , and the new message starts the support email flow. Open the Exchange admin center and go to Recipients > Mailboxes. Create a shared mailbox with these values: Display name: RW Lab Support Email alias: rw-lab-support Domain: your lab tenant's default domain Note: Creating the mailbox requires the Exchange Administrator or Global Administrator role. After creation, grant the lab user both Full Access and Send As. A Microsoft 365 license does not grant these permissions automatically. Review the current shared mailbox permissions and licensing rules before using this design in production. After the mailbox is created, delegate both permissions to the lab user: Full Access lets the user open and modify the shared mailbox. Send As lets the user create a draft using the shared mailbox address. Note: Full Access alone is not sufficient for the later draft-from-shared-mailbox step. To review delegation in the Microsoft 365 admin center, go to Teams & groups > Shared mailboxes, select RW Lab Support, and open Read and manage permissions. This is the Full Access permission described above. Select Add permissions to add the lab user. Return to the mailbox details and also configure Send as permissions for that user. Create the SharePoint site The SharePoint site provides a private workspace for the workflow's lists and case data. Keeping these resources on one site also makes permissions and ownership easier to manage. In this tutorial, RW Lab contains both the Cases list and the SupportTeams list used to process Claire's request. Open SharePoint and select Build in the left navigation. Under Start building, select Site. Then select Team site. If prompted to choose a template, select Standard team. Configure the site using the following values. Field Value Site name RW Lab Site description Synthetic global support workflow lab Group email address Accept the generated alias if it is available. Site address Confirm the generated SharePoint address. Privacy settings Private - only members can access this site Language English Important: The group email address and site address must be unique in your tenant, so SharePoint may adjust the generated values. You cannot change the site's default language after creation. The red boxes group the fields you can complete on this screen and the final Create site button. Check the generated site address separately. This annotated image uses the recorded lab screen. Select Create site, add owners or members if required, and finish the site setup. Create the Cases list The Cases list is the durable record after the flow has enough information to create a case. It stores source-message metadata, the AI proposal, the validated or fallback team, review outcome, and automation status. It does not copy the complete email body or attachments into SharePoint. For Claire's request, the flow first checks SourceMessageId , loads the active team catalog, calls the classifier, and validates the proposed routing key. It then creates one row containing the message metadata and AI result. A normal high-confidence row is updated as it moves through approval and draft creation. Low-confidence, risky, invalid-key, and classifier-unavailable requests are created directly as Needs Review . A duplicate creates no second row, and an unexpected failure before row creation appears only in the flow run history and the internal failure notification. Open SharePoint and select Build in the left navigation. Under Start building, select List, and then select Blank list. Enter Cases for Name, select RW Lab for Save to, and then select Create. SharePoint opens the new Cases list after creating it. In the Cases list, select Add column, choose the matching column type, and configure the columns shown in the following table. The Title column already exists by default; configure it as shown rather than creating another Title column. Note: In the current SharePoint interface, Text creates a single-line text column. Use Multiple lines of text for longer values such as Summary , RoutingReason , and AIProposal . Column Type Configuration Title Single line of text Required; stores the case ID SourceMessageId Single line of text Enforce unique values ReceivedAt Date and time Include time RequesterEmail Single line of text Synthetic test addresses only EmailSubject Single line of text Original subject InquiryType Choice Technical Support, Quote, Demo, Product Information, Partnership, Complaint, Other Product Single line of text AI-extracted canonical product name Country Single line of text AI-extracted country Summary Multiple lines of text AI-generated summary in plain text RecommendedRoutingKey Single line of text Routing key proposed by the AI classifier RecommendedTeam Single line of text Team name resolved from SupportTeams RoutingReason Multiple lines of text AI-provided reason for the recommendation ConfidenceBand Choice High, Medium, Low; use Low as the default for a new lab RiskFlags Multiple lines of text Risk signals returned by the classifier MissingFields Multiple lines of text Required information not found in the message AIProposal Multiple lines of text String form of the classification object, or a classifier-unavailable message ClassificationSource Single line of text Records validated recommendation, held recommendation, or classifier-unavailable fallback AssignedToText Single line of text Reviewer email resolved from SupportTeams Status Choice New, Classified, Needs Information, Awaiting Approval, Assigned, Needs Review, Failed DueAt Date and time Include time ApprovalOutcome Single line of text Approve, Reject, or Timeout ApprovalComment Multiple lines of text Plain text DraftMessageId Single line of text ID returned by the Outlook draft action AutomationStatus Choice Processing, Success, Review, Failed LastAutomationRun Date and time Include time Set SourceMessageId to enforce unique values. Power Automate also checks for the message ID before creating a row; the SharePoint constraint provides a second layer of duplicate protection. To verify the constraint, open Settings > List settings > SourceMessageId. Keep the type Single line of text, set Enforce unique values to Yes, and select OK if you changed it. Open Settings > List settings > ConfidenceBand. Enter High, Medium, and Low on separate lines, use the Drop-down menu display, and leave fill-in choices disabled. For your new list, set Default value to Low, then select OK. The existing lab default is High; use Low for a new build. Classified and Needs Information remain in the current lab list from the earlier implementation. The AI-recommendation path documented below does not write those two values. The current Catch scope also does not write Failed ; it sends an internal failure notification and terminates the run. Create a list view named Tutorial Evidence with Title, EmailSubject, Product, Country, RecommendedTeam, ConfidenceBand, Status, ApprovalOutcome, AutomationStatus, DraftMessageId, ClassificationSource, and ReceivedAt. Sort ReceivedAt newest first. Later validation steps use this view; use the row details pane for columns that do not fit on screen. Create the SupportTeams list The SupportTeams list defines the support teams or queues that the AI classifier is allowed to recommend. Power Automate uses it to validate each recommendation and resolve the reviewer and SLA target. It does not store individual team members or calculate routing from product and country. For Claire's request, the AI proposes eu_distributor_support . Power Automate confirms that this key is active and resolves it to EU Distributor Support , its reviewer, and its four-hour SLA target. Open SharePoint and select Build in the left navigation. Under Start building, select List, and then select Blank list. Enter SupportTeams for Name, select RW Lab for Save to, and then select Create. SharePoint opens the new SupportTeams list after creating it. In the SupportTeams list, select Add column, choose the matching column type, and configure the columns shown in the following table. The Title column already exists by default; configure it as shown rather than creating another Title column. Column Type Configuration Title Single line of text Display name RoutingKey Single line of text Enforce unique values TeamName Single line of text Support team name ApproverEmail Single line of text Reviewer address SLAHours Number No decimal places Active Yes/No Default Yes Important: Set RoutingKey to enforce unique values. This ensures that each AI recommendation resolves to exactly one support team. Power Automate accepts a recommendation only when the key matches an active row, then uses that row's team name, reviewer, and SLA target for the normal approval path. Open Settings > List settings > RoutingKey. Keep Single line of text, set Enforce unique values to Yes, and select OK. The September 9 lab capture below shows the existing No setting; it is a configuration gap, not the recommended setting for your new list. Add the 12 synthetic rows shown below. For closer parity with the direct evaluator, use each matching description in data/aster-imaging/support-teams.json as Title; the shorter titles below are the labels used in the original mailbox lab. The flow sends Title as the routing description, so changing it changes model input and requires a rerun. Replace each <YOUR_EMAIL> placeholder with the lab reviewer address. Title RoutingKey TeamName ApproverEmail SLAHours Active EU distributor support eu_distributor_support EU Distributor Support <YOUR_EMAIL> 4 Yes NA technical support na_technical_support NA Technical Support <YOUR_EMAIL> 4 Yes APAC distributor support apac_distributor_support APAC Distributor Support <YOUR_EMAIL> 4 Yes Software support software_support Software Support <YOUR_EMAIL> 4 Yes EU regional sales eu_regional_sales EU Regional Sales <YOUR_EMAIL> 8 Yes NA regional sales na_regional_sales NA Regional Sales <YOUR_EMAIL> 8 Yes APAC regional sales apac_regional_sales APAC Regional Sales <YOUR_EMAIL> 8 Yes Global partnerships global_partnerships Global Partnerships <YOUR_EMAIL> 8 Yes Global support global_support Global Support <YOUR_EMAIL> 8 Yes Security review security_review Security Review <YOUR_EMAIL> 1 Yes Privacy review privacy_review Privacy Review <YOUR_EMAIL> 1 Yes Safety and compliance safety_and_compliance Safety and Compliance <YOUR_EMAIL> 1 Yes Review the completed list. Confirm that all 12 rows show Active = Yes and that no RoutingKey value appears more than once. The recorded lab catalog contains 12 active teams with the routing keys and SLA hours shown above. This list view omits reviewer addresses; configure ApproverEmail for every row using your lab reviewer account. Step 2: Deploy and connect the AI classifier In Step 1, you created the shared mailbox and SharePoint lists that provide the workflow's email channel, case record, and approved support-team catalog. In this step, you add the AI classification layer. You deploy an Azure OpenAI model in Microsoft Foundry, connect it to an Azure Function, and expose the Function to Power Automate through a custom connector. For example, suppose Claire emails the shared mailbox to report that a NovaScan X2 in France shows error E42 during startup after software version 4.2.1 is installed. The classifier extracts NovaScan X2 as the product, France as the country, and technical_support as the inquiry type. It summarizes the problem, returns a high confidence band, and recommends the routing key eu_distributor_support . This result is only a proposal. The classifier cannot approve the request, assign an owner, update the case, or send email. In Step 3, Power Automate validates the proposed key against the active SupportTeams list before deciding whether the request can proceed to human approval. Services and tools used in this step Service or tool Purpose Microsoft Foundry (Azure OpenAI models) Create or select the Foundry resource and deploy the model used for classification. Azure Functions Call the model, enforce the structured response contract and guardrails, and expose a bounded HTTP endpoint. Microsoft Entra ID and Azure RBAC Allow the Function app to call the model through its managed identity. Power Automate custom connectors Make the Azure Function operation available to cloud flows. Power Platform solutions Package the custom connector, connection references, and environment variables used by the workflow. Note: The local deployment tools used in this step are Node.js 22, Azure CLI, and Azure Functions Core Tools. Create a Foundry resource and deploy the model An Azure subscription is the billing and access boundary. Inside that subscription, a Microsoft Foundry resource provides the model endpoint and quota. A Foundry project is the workspace you open in the Foundry portal, and a model deployment inside that project gives the Function app a stable deployment name to call. Creating a subscription or resource alone does not deploy a model. The tested lab uses gpt-5.4-mini , pinned to model version 2026-03-17 . It provides the structured output and instruction-following behavior needed by this bounded extraction and routing task without using a larger model for every incoming message. Sign in to the Azure portal and confirm that the correct directory and subscription are selected. Search for Microsoft Foundry, select Create, and create a Foundry resource if you do not already have one that the lab can use. Choose the target subscription and resource group, enter a globally unique resource name, select a region in which gpt-5.4-mini has quota, and keep the Standard S0 pricing tier. For a disposable lab, the basic public-network configuration is sufficient; use private networking and organization-approved controls for production. Note: You need permission to write the resource, such as Contributor or Owner, and separate model quota in the selected region. Microsoft documents the current resource fields in Create a Microsoft Foundry resource. Open the Microsoft Foundry portal and verify the directory and subscription. Select a project associated with the Foundry resource you created. If no project exists yet, create one under that resource and record its name as <FOUNDRY_PROJECT_NAME> . Enable the New Foundry experience if the portal offers the switch. On the project home page, select View deployments under Use a model. You can return to the same page later through Build > Deployments. On Deployed models, select Deploy > Deploy a base model, search for gpt-5.4-mini , and configure the deployment with the following tested values: Setting Tested value Deployment name gpt-5.4-mini Model version 2026-03-17 Deployment type Global Standard Capacity 100 thousand tokens per minute Version upgrade policy Once current version expires Content filter Microsoft.DefaultV2 Important: Capacity is quota, not a target for the tutorial. Select a lower value when your subscription has less quota; the synthetic lab traffic does not require 100K tokens per minute. If this model or version is unavailable in your region, choose an approved region or model only after confirming structured-output support, then repeat the final evaluation in Step 4 with that exact deployment. Select Deploy and wait until the deployment state is Succeeded. Record the resource endpoint and deployment name. The Function app uses the deployment name, not the catalog model label, when it constructs the request. The screenshot below is a verification view of the completed lab deployment, not the initial creation form. Optionally verify the deployed version from Azure CLI. This read-only command helps catch the common mistake of configuring the Function with a deployment that exists under another resource or subscription: az login az account set --subscription "<SUBSCRIPTION_ID>" az cognitiveservices account deployment show ` --resource-group "<RESOURCE_GROUP>" ` --name "<FOUNDRY_RESOURCE_NAME>" ` --deployment-name "gpt-5.4-mini" ` --query "{state:properties.provisioningState, model:properties.model.name, version:properties.model.version, sku:sku.name, capacity:sku.capacity}" The tested deployment returned Succeeded , model gpt-5.4-mini , version 2026-03-17 , SKU GlobalStandard , and capacity 100 . Review the current Microsoft guidance for deploying Foundry models and model version update policies because availability, quota, and portal labels can change. Create, configure, and deploy the Azure Function Create and configure the Azure resource in the portal, then use Azure Functions Core Tools to publish the tested repository project. Do not copy the individual JavaScript files into the portal editor; this project has multiple source files, locked npm dependencies, and automated tests that should remain together. In the Azure portal, select Create a resource, search for Function App, and select Create. Configure the Function app using the following tested lab values. If you already have a compatible Node.js 22 Function app, open it and continue with the identity step. Setting Tested lab value Subscription The subscription that contains the Foundry resource Resource group The lab resource group Function App name A globally unique name; record it as <FUNCTION_APP_NAME> Publish Code Runtime stack Node.js Version 22 Operating system Linux Region The lab region; the tested app uses East US 2 Hosting Consumption; the tested app uses the Y1 / Dynamic plan Note: Microsoft currently recommends Flex Consumption for new serverless Function apps. The implementation documented here was tested on Linux Consumption. If you select a different hosting plan, confirm its deployment and networking behavior before treating the tutorial results as equivalent. See Create a function app in the Azure portal. Select Review + create, select Create, and wait for the deployment to finish. Open the Function App resource and record its default host name from Overview. Under Settings > Identity, enable the system-assigned identity. On the Foundry resource, assign that identity the Cognitive Services OpenAI User role. The Function uses DefaultAzureCredential ; it does not store an Azure OpenAI API key. See the Microsoft guidance for managed identities in Azure Functions and Azure OpenAI role assignment. Under the Function app's environment variables or configuration settings, add these values: Setting Value AZURE_OPENAI_ENDPOINT Azure OpenAI endpoint, typically https://<FOUNDRY_RESOURCE_NAME>.openai.azure.com AZURE_OPENAI_DEPLOYMENT gpt-5.4-mini AZURE_OPENAI_API_VERSION 2024-10-21 Keep Show values disabled while capturing or sharing this page. The list should show the three setting names without exposing their values. Note: These are Azure Function app settings. They are separate from the rw_* Power Platform solution environment variables created later in this step. Download or clone the GitHub sample, open a terminal at the sample root, and move to the Function project: cd azure/global-support-classifier Verify the local tool versions, install the locked dependencies, and run the Function tests: node --version func --version npm ci npm test The tested deployment uses Node.js 22 and Azure Functions Core Tools 4.0.7512 . If func is not available, install a supported Core Tools v4 release by following the Core Tools installation guidance. In src/functions/classifySupportInquiry.js , locate buildAzureRequest and confirm that the GPT-5 request uses max_completion_tokens = 1100 and reasoning_effort = none . Do not add temperature or the older max_tokens field. GPT-5 reasoning models count reasoning and visible output against the completion-token budget; Microsoft documents the compatible parameters in Use reasoning models. Sign in with az login , select the intended subscription with az account set --subscription <SUBSCRIPTION_ID> , and confirm it with az account show --query name -o tsv . From the Function project directory, publish the complete project to the Function app: func azure functionapp publish <FUNCTION_APP_NAME> --javascript The --javascript option is explicit because automatic language detection did not identify this repository project during the tested publish. A successful publish reports Deployment completed successfully , synchronizes the classifySupportInquiry trigger, and prints its invoke URL. Core Tools packages and deploys the complete project from the current directory; review the Core Tools publishing guidance before using another hosting plan. Return to the Function App Overview page and confirm that classifySupportInquiry appears as an enabled HTTP function. This screen is meaningful only after the Core Tools publish succeeds. Define the response contract Open azure/global-support-classifier/src/functions/classifySupportInquiry.js and locate classificationSchema . Confirm that every property is required, bounded values use enumerations, and additionalProperties is false . Confirm that a successful call returns version 2.0 of this contract: { "schemaVersion": "2.0", "classification": { "inquiryType": "technical_support", "product": "NovaScan X2", "serialNumber": "NSX2-2407138", "country": "France", "organization": null, "urgency": "normal", "language": "en", "summary": "NovaScan X2 shows error E42 during startup after version 4.2.1.", "missingFields": [], "evidence": [ "NovaScan X2 serial NSX2-2407138", "error E42 during startup", "software version 4.2.1" ], "confidenceBand": "high", "riskFlags": [], "recommendedRoutingKey": "eu_distributor_support", "routingReason": "Technical support for NovaScan X2 in France routes to EU distributor support." } } Confirm that the contract includes recommendedRoutingKey , routingReason , and riskFlags . Power Automate stores all three and validates the key before resolving a team. Treat confidenceBand as a workflow category rather than a calibrated probability. Allow only high , medium , or low , and bound the risk values to prompt injection, unsupported attachment, privacy, safety, non-English, multiple-intent, low-confidence, and invalid-key signals. Supply the active team catalog with each request Open azure/global-support-classifier/connector/apiDefinition.swagger.json . Confirm that it is an OpenAPI 2.0 definition and that the request includes routingOptionsJson . Confirm that Power Automate will serialize each active catalog entry with this shape. The example below shows one of the 12 rows: [ { "routingKey": "eu_distributor_support", "teamName": "EU Distributor Support", "description": "Technical support for NovaScan products in Europe." } ] In classifySupportInquiry.js , confirm that the Function parses routingOptionsJson before constructing the model request. This string boundary avoids a Power Automate custom-connector metadata issue with arrays of objects; the model still receives a structured routingOptions array. Apply deterministic post-processing after the model response: detects prompt-injection phrases and unsafe attachment extensions; forces safety, privacy, and security signals to the corresponding review key when that key is active; removes a missing software version or screenshot flag when the source message contains that evidence; changes an unknown product-and-country result to low confidence; marks a recommendation invalid when its key is not in the supplied active catalog. Keep the Function advisory. These controls constrain the proposal, but Power Automate still performs the operational validation and assignment. The active destinations, reviewers, and SLA values live in SharePoint. The sample still encodes product/country routing precedence in the system prompt and post-processing code; changing that policy requires a code review and regression run as well as any catalog update. Keep attachment retrieval disabled for this version. The classifier supports attachment metadata and its direct regression tests exercise unsupported-attachment detection, but the live flow passes an empty attachments array and therefore does not inspect or block attachments. Create the custom connector Two different authentication boundaries are involved. The Function app calls Microsoft Foundry with its managed identity, so it stores no Azure OpenAI key. Power Automate calls the Function endpoint with x-functions-key ; that Function host key is not an Azure OpenAI key. Open azure/global-support-classifier/connector/apiDefinition.swagger.json from the sample root. Before importing the connector, replace its host value with <FUNCTION_APP_NAME>.azurewebsites.net . Keep basePath set to /api , the scheme set to https , and the operation ID set to ClassifySupportInquiryV3 . In Power Automate, select the RW Development environment. Open More > Discover all, find Data, and select Custom connectors. Select New custom connector > Import an OpenAPI file, enter RW Support Classifier , and upload apiDefinition.swagger.json . In the connector wizard, review General, Security, and Definition in order. On General, confirm HTTPS, your Function app's host name, and Base URL = /api, then select Security. Confirm API Key, Parameter label = Function key, Parameter name = x-functions-key, and Parameter location = Header. Select Definition and open Classify a support inquiry. Under Request, confirm POST, your Function URL ending in /api/classify-support-inquiry, and the required body parameter imported from the OpenAPI file. Continue with the response check below before creating the connector. The screenshots show an existing connector, whose toolbar displays Update connector instead of Create connector. Scroll farther down to Response and open 200 (Structured candidate fields). Confirm that References Used includes ClassifierResponse and Classification, and that Body exposes fields such as confidenceBand, routingReason, and schemaVersion. Select Back to return to the action definition, then select Create connector (or Update connector when modifying an existing connector). This screen checks the imported response definition; step 4 creates the authenticated connection and tests a real request. In the Azure portal, open the Function App's App keys page and create or copy a dedicated host key for this lab connection. Return to the connector's Test page, select New connection, enter that Function host key, and create the connection. Select the new connection (or your existing lab connection) and refresh the connection list if necessary. Under ClassifySupportInquiryV3, turn Raw Body on and paste the JSON below. Keep attachments as an empty array and routingOptionsJson as a JSON-encoded string. Select Test operation. In Response, confirm Status (200), schemaVersion = 2.0, a classification object, and Schema validation > Validation succeeded. Microsoft documents the current import and test flow in Create a custom connector from an OpenAPI definition. { "subject": "NovaScan X2 error E42 - France", "body": "NovaScan X2 serial NSX2-2407138 shows error E42 during startup after software version 4.2.1 was installed.", "from": "claire.martin@alpine-distribution.example.test", "attachments": [], "routingOptionsJson": "[{\"routingKey\":\"eu_distributor_support\",\"teamName\":\"EU Distributor Support\",\"description\":\"Technical support for NovaScan products in Europe.\"}]" } Important: The Function key belongs in the secure Power Platform connection. Do not put it in a text environment variable, flow action, screenshot, or source file. The September 8, 2026 request returned technical_support, France, confidenceBand = high, no risk flags, and recommendedRoutingKey = eu_distributor_support. This verifies one connector request; the flow still needs to apply its acceptance gate and obtain human approval. Add the components to the solution Open Solutions and create RW Global Support Intake . Create or select a publisher with prefix rw so the environment-variable schema names below match. Open the solution, select Objects, and use the object-type tree to review its components. Select Add existing, add the RW Support Classifier custom connector, and confirm that Custom connectors (1) appears in the object tree. Select New > More > Connection Reference and create these four named references: Office 365 Outlook SharePoint Standard approvals RW Support Classifier Select New > More > Environment variable and create these five variables: Display name Example schema name Current value Support Mailbox rw_SupportMailbox Shared mailbox address SharePoint Site URL rw_SharePointSiteURL RW Lab site URL Default Approver Email rw_DefaultApproverEmail Lab reviewer address Cases List Name rw_CasesListName Cases Support Teams List Name rw_SupportTeamsListName SupportTeams In Objects, select Connection references, Custom connectors, and Environment variables in turn. Confirm that the four required references, one connector, and five variables are present before creating the flow. The lab solution contains the four required connector types and additional automatically generated Outlook and SharePoint references. Match each flow action to its intended connection; the extra rows are not additional connector types to create. The five variables in the table are present. Routing Rules List Name is retained from an earlier lab design and is not required by this AI-recommendation workflow. Step 3: Build and validate the support email flow In this step, you build the flow that turns the bounded AI output from Step 2 into a validated recommendation. The flow checks duplicates, resolves an active team, applies the acceptance gate, and records uncertain or unavailable-classifier requests for human review. You then test both the normal validation path and the exception paths before adding approval in Step 4. Services and tools used in this step Service or tool Purpose Power Automate Build the automated cloud flow, scopes, conditions, and state transitions. Office 365 Outlook connector Start the flow when a message arrives in the shared mailbox. SharePoint connector Check for duplicates, load active support teams, and create review or fallback case rows. RW Support Classifier custom connector Send the message and active routing catalog to the Azure Function classifier. Create and configure the flow Use the action names shown below before writing expressions. In expression references, spaces become underscores: GetItems ExistingCase is referenced as GetItems_ExistingCase . Rename the custom connector action Classify Support Inquiry so its reference is Classify_Support_Inquiry . Select the matching dynamic-content token if your designer generated a different internal name. Enter formulas in the Expression editor without a leading @ . Values containing @{...} below are inline expressions in a text field. In this lab, enter the documented SharePoint list names directly in the connector; the list-name environment variables record configuration but are not automatically substituted into every action. Open RW Global Support Intake , select Objects > New > Automation > Cloud flow > Automated, and create RW - Global Support Intake - v1 . Add When a new email arrives in a shared mailbox (V2) and configure the trigger: Trigger field Value Original Mailbox Address rw_SupportMailbox current value Folder Inbox Importance Any Only with Attachments No Include Attachments No In Trigger NewSharedMailboxEmail > Parameters, select your shared mailbox under Original Mailbox Address. Open Advanced parameters to expose the four settings shown above: Importance = Any, Only with Attachments = No, Include Attachments = No, and Folder = Inbox. The September 9 lab capture displays an onmicrosoft.com address in the mailbox picker; select the mailbox you configured in Step 1 rather than copying the lab address. Open the trigger's Settings, turn on Concurrency Control, and set Degree of Parallelism to 1 . This serializes the lab runs, including time spent waiting for approval. A pending approval can delay the next email for 30 minutes. Use this setting for controlled tests; a design that processes new emails separately from approvals is needed before evaluating throughput. The current designer labels the concurrency switch Limit. The screenshot was captured at 125% browser zoom and cropped to the settings panel so the switch and value remain readable. After the trigger, select Add an action > Variable > Initialize variable for each row below. Keep every initializer above the Try scope and in the listed order: Variable Type Initial value CaseId String concat('AST-',formatDateTime(utcNow(),'yyyyMMdd'),'-',toUpper(substring(guid(),0,8))) InquiryType String Empty Product String Empty Country String Empty RecommendedTeam String Global Support ApproverEmail String rw_DefaultApproverEmail current value SLAHours Integer 8 RecommendedRoutingKey String Empty RoutingReason String Empty ConfidenceBand String Empty RiskFlags String Empty MissingFields String Empty For CaseId, enter the expression from the table through the Value field's expression editor, then select Add (or Update when editing an existing expression). The purple concat(...) token confirms that Value contains an expression. Select that token to reopen and check the full formula, as shown above. For SLAHours, set Name = SLAHours, Type = Integer, and Value = 8, as shown below. The other eleven variables in the table use String. Repeat the same Name, Type, and Value fields for each variable; where the table says Empty, leave Value blank. Keep all twelve initializers between the trigger and Scope Try. Compare the action order in these two views. The first red box contains CaseId through ApproverEmail; the second continues with SLAHours through MissingFields. Keep all twelve initializers outside and before Scope Try. These configuration views show placement; use the table above for each variable's type and initial value. Select Add an action > Control > Scope twice. Rename the first scope Scope Try and the second Scope Catch . On Scope Catch , select Configure run after and select has timed out, is skipped, and has failed for Scope Try . Inside Catch, add Send an email (V2) to the default approver with the CaseId and workflow run name, followed by Terminate with Status = Failed, Code = RW_INTAKE_FAILED , and an internal-only error message. In the current designer, open Settings > Run after, then expand Scope Try to reveal its result checkboxes. Leave Is successful unchecked. These are alternative results: any one of the three selected results allows Catch to run. Open SendEmail InternalFailure > Parameters. Set To to your internal default approver. In Subject, enter [RW Support Flow] Failed run followed by the CaseId variable token. In Body, write a short failure notice, add the CaseId token, and insert the expression workflow()?['run']?['name'] for the run reference so the reviewer can locate the failed run. For a new build, enter ordinary text in the rich-text Body editor, such as The support email flow failed., followed by the case ID, run reference, and Review the flow run before retrying. Do not paste HTML tags into the rich-text editor. The recorded configuration below contains escaped HTML tags as literal text; this is an existing formatting issue, not the recommended body format. This capture documents the saved inputs; the flow was not changed or rerun. Select Terminate Failed > Parameters and set Status to Failed and Code to RW_INTAKE_FAILED . For Message, use Global Support Intake failed; see the internal notification for the run reference. The canvas on the right shows where this action belongs: immediately after the internal notification inside Scope Catch. Note: The current Catch scope sends an internal notification and fails the run. It does not create a new Cases row or update an existing row to Failed. Add the duplicate guard Inside Scope Try , add SharePoint > Get items and rename it GetItems ExistingCase . Get items field Value Site Address rw_SharePointSiteURL current value List Name Cases Filter Query SourceMessageId eq '@{triggerOutputs()?['body/id']}' Top Count 1 In GetItems ExistingCase > Parameters, choose your site and the Cases list. Under Advanced parameters, enable Filter Query and Top Count. Keep the trigger's Message Id token inside the single quotes in the filter, and enter 1 for Top Count, as highlighted in this September 9 configuration capture. Add Data Operation > Compose, rename it Compose ExistingCaseCount , and use length(body('GetItems_ExistingCase')?['value']) . Open the Inputs expression editor in Compose ExistingCaseCount, enter length(body('GetItems_ExistingCase')?['value']), and apply it. This September 9 capture shows the existing expression opened for inspection, so the button is labeled Update. 3. Add a Condition, rename it Condition Duplicate , and test whether the Compose output is greater than 0 . In Condition Duplicate > Parameters, select Outputs from Compose ExistingCaseCount on the left, choose is greater than, and enter 0 on the right. The operator menu is open in this September 9 capture so its full label is visible. 4. In the True branch, add Terminate with Status = Succeeded. Leave case creation out of this branch. Build the remaining email-processing actions in the False branch. Place Terminate Duplicate in the True branch and set Status to Succeeded. Continue with GetItems ActiveSupportTeams and Select RoutingOptions in the False branch. This September 9 configuration capture shows both paths beside the termination setting. Load the catalog and call the classifier In the duplicate condition's False branch, add SharePoint > Get items and rename it GetItems ActiveSupportTeams . Get items field Value Site Address rw_SharePointSiteURL current value List Name SupportTeams Filter Query Active eq 1 Top Count 100 Select SupportTeams as the list. Under Advanced parameters, set Filter Query to Active eq 1 and Top Count to 100. This September 9 capture shows the active catalog query. Add Data Operation > Select, rename it Select RoutingOptions , set From to the value output from GetItems ActiveSupportTeams , and create this mapping: Key Value routingKey item()?['RoutingKey'] teamName item()?['TeamName'] description item()?['Title'] Use value from GetItems ActiveSupportTeams for From. Map routingKey to RoutingKey, teamName to TeamName, and description to Title. This September 9 capture shows the dynamic-content version of the expressions above. Add a Control > Scope, rename it Scope AI Recommendation , and place RW Support Classifier > Classify support inquiry inside it. Rename the classifier action Classify Support Inquiry and configure it: Input Value subject Subject from the mailbox trigger body Body from the mailbox trigger from From from the mailbox trigger attachments Empty array [] routingOptionsJson string(body('Select_RoutingOptions')) Select Subject, Body, and From from the mailbox trigger. Expand Advanced parameters to show from and attachments; keep the attachments array empty by adding no items. The September 9 designer labels these inputs with a Body/ prefix. For Body/routingOptionsJson, open the expression editor and enter string(body('Select_RoutingOptions')). Apply the expression with Add, or Update when editing an existing value as shown here. This converts the Select output array into the string expected by the connector. After the AI scope, add a Condition named Condition AIRecommendationAvailable . Use Configure run after so the condition runs when the AI scope succeeds, fails, is skipped, or times out. The True path is actions('Scope_AI_Recommendation')?['status'] equals Succeeded ; use the False path for the classifier-unavailable case. Open Settings > Run after, expand Scope AI Recommendation, and select all four statuses: Is successful, Has timed out, Is skipped, and Has failed. This September 9 configuration lets the next condition evaluate the AI scope even when the classifier is unavailable. Return to Parameters. In the left field, use the expression actions('Scope_AI_Recommendation')?['status']; select is equal to and enter Succeeded on the right. The empty row underneath is the designer's next-row placeholder. The True branch handles a successful AI call; the False branch handles an unavailable classifier. Validate the returned recommendation In the AI-available True branch, add Set variable actions in this order: Variable Value InquiryType Use the enum-to-choice mapping immediately below; unmatched values become Other Product coalesce(body('Classify_Support_Inquiry')?['classification']?['product'],'') Country coalesce(body('Classify_Support_Inquiry')?['classification']?['country'],'') RecommendedRoutingKey body('Classify_Support_Inquiry')?['classification']?['recommendedRoutingKey'] RoutingReason body('Classify_Support_Inquiry')?['classification']?['routingReason'] ConfidenceBand if(equals(body('Classify_Support_Inquiry')?['classification']?['confidenceBand'],'high'),'High',if(equals(body('Classify_Support_Inquiry')?['classification']?['confidenceBand'],'medium'),'Medium','Low')) RiskFlags join(body('Classify_Support_Inquiry')?['classification']?['riskFlags'],'; ') MissingFields join(body('Classify_Support_Inquiry')?['classification']?['missingFields'],'; ') For Set InquiryType , select the InquiryType variable, open the Value expression editor, and paste the following mapping. The recorded flow uses nested if expressions in this action: if(equals(body('Classify_Support_Inquiry')?['classification']?['inquiryType'],'technical_support'),'Technical Support', if(equals(body('Classify_Support_Inquiry')?['classification']?['inquiryType'],'quote_request'),'Quote', if(equals(body('Classify_Support_Inquiry')?['classification']?['inquiryType'],'demo_request'),'Demo', if(equals(body('Classify_Support_Inquiry')?['classification']?['inquiryType'],'product_information'),'Product Information', if(equals(body('Classify_Support_Inquiry')?['classification']?['inquiryType'],'partnership'),'Partnership', if(equals(body('Classify_Support_Inquiry')?['classification']?['inquiryType'],'complaint'),'Complaint','Other')))))) Select Add for a new expression, or Update when editing an existing one. The mapping is: Classifier value SharePoint Choice label technical_support Technical Support quote_request Quote demo_request Demo product_information Product Information partnership Partnership complaint Complaint Default, including other Other Add SharePoint > Get items, rename it GetItems RecommendedSupportTeam , and configure it: Get items field Value Site Address rw_SharePointSiteURL current value List Name SupportTeams Filter Query RoutingKey eq '@{variables('RecommendedRoutingKey')}' and Active eq 1 Top Count 1 Open GetItems RecommendedSupportTeam > Parameters. Select your SharePoint site and SupportTeams list. Under Advanced parameters, show Filter Query and Top Count. Insert the RecommendedRoutingKey variable between single quotes in the filter, retain and Active eq 1, and set Top Count to 1. Add Compose, rename it Compose TeamMatchCount , and use length(body('GetItems_RecommendedSupportTeam')?['value']) . In Compose TeamMatchCount > Parameters > Inputs, open the Expression editor and enter the expression above. Select Add for a new expression, or Update when editing an existing one. The result counts the rows returned by GetItems RecommendedSupportTeam. 4. Add Condition RecommendationAccepted and require every gate below: The acceptance gate requires all five checks: team match count = 1 AND ConfidenceBand = High AND riskFlags length = 0 AND missingFields length = 0 AND RecommendedRoutingKey is not empty Open Condition RecommendationAccepted > Parameters and use And to require all five checks. The September 9 lab screen above uses a team count greater than 0; the expression below uses a count equal to 1. With Top Count = 1, these checks have the same result, and neither detects duplicate catalog rows: enforce the unique RoutingKey constraint in SharePoint. The final empty row is the designer's next-row placeholder. Use this expression for the gate and compare its output with the Boolean true : and( equals(outputs('Compose_TeamMatchCount'),1), equals(variables('ConfidenceBand'),'High'), empty(body('Classify_Support_Inquiry')?['classification']?['riskFlags']), empty(body('Classify_Support_Inquiry')?['classification']?['missingFields']), not(empty(variables('RecommendedRoutingKey'))) ) Enable the unique RoutingKey constraint before relying on one returned row as an unambiguous match. The September 9 configuration check found this constraint disabled in the existing lab. Its recorded results therefore do not demonstrate protection against duplicate catalog keys; the new-build instructions in Step 1 require that protection. The model's confidence category is not a calibrated probability. Also, this sample holds every non-empty risk list, including product-alias and non-English flags. Those flags do not all indicate danger; the broad hold is a conservative lab policy with a review-volume tradeoff. In the accepted True branch, set RecommendedTeam to first(body('GetItems_RecommendedSupportTeam')?['value'])?['TeamName'] , ApproverEmail to first(body('GetItems_RecommendedSupportTeam')?['value'])?['ApproverEmail'] , and SLAHours to int(first(body('GetItems_RecommendedSupportTeam')?['value'])?['SLAHours']) . Leave space after these actions; Step 4 adds case creation, approval, and draft creation to this branch. In the False branch, add SharePoint > Create item named CreateItem NeedsReview . Store the AI fields, set Status = Needs Review, AutomationStatus = Review, and ClassificationSource = AI recommendation held for human review . Do not add an approval action. In the AI-available condition's False branch, add Create item named CreateItem ClassifierUnavailable . Use the fallback Global Support values, set InquiryType = Other, ConfidenceBand = Low, Status = Needs Review, AutomationStatus = Review, AIProposal = AI classifier unavailable or returned an invalid response. , and ClassificationSource = Classifier unavailable / human review . In CreateItem ClassifierUnavailable, set Summary to the mailbox trigger's Subject. The red boxes below show the fallback fields in the existing action. Under Advanced parameters, also add ConfidenceBand Value and select Low explicitly. The captured action omits that field and therefore inherits the existing list default, High; the screenshot does not show the recommended Low setting. Leave other classifier-derived fields empty and do not reference the failed classifier action's body. The matched SupportTeams row supplies RecommendedTeam, ApproverEmail, and SLAHours on the accepted recommendation path. Review rows created in this step store the AI reason and proposal; Step 4 stores the same evidence when it creates an accepted case. In both paths, the active catalog remains the operational allow-list. The current flow also initializes fallback values before the Try scope: Global Support , the default approver, and an eight-hour SLA. An invalid-key or classifier-unavailable review case can therefore retain fallback reviewer and SLA values without resolving a matching SupportTeams row. This is the actual lab behavior, not an additional validated assignment. Map the case fields consistently Use the following mapping on both review-case creation actions and on CreateItem Case in Step 4. Then apply each branch's Status, AutomationStatus, ClassificationSource, and AIProposal values. For the unavailable-classifier branch, use the trigger Subject for Summary, leave other classifier-derived fields empty, and write the explicit fallback message; do not reference the failed action's body. Cases field Value Title variables('CaseId') SourceMessageId Message Id dynamic content from the trigger, the same value used by the duplicate guard ReceivedAt Date Time Received dynamic content from the trigger RequesterEmail Sender's email address from the trigger, without the display name EmailSubject Subject from the trigger InquiryType, Product, Country Corresponding variables; fallback InquiryType is Other RecommendedRoutingKey, RoutingReason, RiskFlags, MissingFields Corresponding variables ConfidenceBand Corresponding variable, or explicit Low for classifier unavailable RecommendedTeam variables('RecommendedTeam') for accepted and classifier-unavailable cases; use the branch-specific expression below for NeedsReview AssignedToText variables('ApproverEmail') DueAt addHours(utcNow(),variables('SLAHours')) Summary body('Classify_Support_Inquiry')?['classification']?['summary'] when available AIProposal string(body('Classify_Support_Inquiry')?['classification']) when available LastAutomationRun utcNow() For CreateItem NeedsReview, set RecommendedTeam to if(greater(outputs('Compose_TeamMatchCount'),0),first(body('GetItems_RecommendedSupportTeam')?['value'])?['TeamName'],'Unvalidated recommendation') . This preserves the catalog team name when a match exists and records Unvalidated recommendation when none exists. The review branch does not run the accepted branch's Set ApproverEmail or Set SLAHours actions, so AssignedToText and DueAt retain the initialized default reviewer and eight-hour SLA. A displayed catalog team name does not mean the recommendation passed the acceptance gate. This mapping was checked in the existing configuration; no new run was performed. On every later Update item, use the ID returned by that branch's Create item and preserve Title = CaseId. Do not accidentally use the source email ID as the SharePoint item ID. DueAt is a simple target timestamp from processing time; this tutorial does not implement business calendars or SLA escalation. Check the flow Save the flow. Open Flow checker and resolve every reported error or warning before testing. At this stage, Flow checker should report zero errors and zero warnings before you send the validation messages: The highlighted toolbar button opens Flow checker. This designer check reports zero errors and warnings in the captured flow; it does not verify approval delivery, mailbox access, or runtime outcomes. Validate those paths with the test cases below. Test the normal validation path Send this complete synthetic inquiry to the shared mailbox: Subject: NovaScan X2 error E42 - France - software version 4.2.1 Hello Aster Support, We are a distributor in France. NovaScan X2 serial NSX2-2407138 shows error E42 during startup after installing software version 4.2.1. We captured the error screenshot. Regards, Claire In Power Automate, open Solutions > RW Global Support Intake > Objects > Cloud flows > RW - Global Support Intake - v1. Under 28-day run history, select the new run and confirm that the duplicate guard, classifier, active-team lookup, and Condition RecommendationAccepted succeeded. Inspect the classifier and variable actions in the run. Confirm that the flow produced Technical Support, NovaScan X2, France, High confidence, no risk flags or missing fields, eu_distributor_support , and a successful match to EU Distributor Support. Confirm that the acceptance condition followed its True branch. At this point, the flow has validated the recommendation but has not created the accepted case or approval request. Step 4 adds those actions to the True branch. This separation lets you verify the routing boundary before introducing consequential workflow actions. Test one representative review path A green normal run does not prove that uncertainty is held safely. Use one intentionally incomplete message to exercise the review boundary without repeating every exception as a full walkthrough. Send this intentionally incomplete message to the shared mailbox: Subject: Help needed - low confidence routing test A device stopped working somewhere. Please route this request. Open RW Lab > Cases > Tutorial Evidence, locate the newly created row by its subject and received time, and record its generated CaseId. Confirm that Product and Country are empty, RecommendedTeam = Global Support, ConfidenceBand = Low, RiskFlags = Low confidence, and Status = Needs Review. Open the corresponding flow run, expand the action groups, and confirm that Condition RecommendationAccepted followed the False branch and CreateItem NeedsReview succeeded. The screenshot below shows a separate prompt-injection case held in review. It illustrates the risk-flag gate, rather than the incomplete-message test just described. Your generated CaseIds will be different. Record the remaining Step 3 checks Run the remaining checks separately, but summarize them rather than repeating the same send–open run–open row sequence. Record both the validation surface and the observed boundary: Check Validation surface Observed boundary Structured prompt-injection risk Live mailbox and flow run Security Review recommendation remained Needs Review because riskFlags was non-empty. Azure content filter or invalid classifier response Live mailbox and flow run CreateItem ClassifierUnavailable stored the fallback proposal and Needs Review / Review . Invalid routing key Function test plus flow-gate inspection invented_team was forced to Low confidence; a zero-row team lookup cannot pass the acceptance gate. Duplicate message ID Resubmitted completed run Terminate Duplicate succeeded and no second Cases row was created. Note: Historical screenshots may show High on a classifier-unavailable row because the original list defaulted to High. The instructions above explicitly use Low for new fallback rows. ClassificationSource identifies the unavailable-model case; Low here is a conservative fallback value, not a model assessment. Step 4: Add human approval, create a draft, and evaluate the workflow In this step, you complete the accepted recommendation path. A reviewer decides whether to accept the proposed team, and an approval may create an editable acknowledgement draft, but no branch sends that draft to the requester. You walk through the approved path and the actual PT30M timeout boundary, then summarize the remaining stateful checks and classifier evaluation. Services and tools used in this step Service or tool Purpose Power Automate and Approvals Present the AI recommendation to the reviewer and branch on the human decision. SharePoint connector Create the accepted case and update its approval and automation states. Office 365 Outlook connector and Outlook Create an editable acknowledgement draft and confirm that no message was sent automatically. Azure Functions and Microsoft Foundry Run the authenticated classifier evaluation against the deployed implementation. Note: The local evaluation tools used later in this step are Node.js 22 and PowerShell. Configure approval and case-state updates In the accepted-recommendation branch, add SharePoint > Create item and rename it CreateItem Case . Map the trigger metadata and classifier fields to the corresponding Cases columns, then set these operational fields: Cases field Value RecommendedTeam RecommendedTeam variable AssignedToText ApproverEmail variable DueAt addHours(utcNow(),variables('SLAHours')) AIProposal string(body('Classify_Support_Inquiry')?['classification']) ClassificationSource AI recommendation validated by SupportTeams Status New AutomationStatus Processing Open CreateItem Case > Parameters and select your SharePoint site and Cases list. Under Advanced parameters, set Title to the CaseId variable. Select Message Id, From, and Subject from the mailbox trigger for SourceMessageId, RequesterEmail, and EmailSubject, respectively. Continue with the classifier and operational fields in the tables above. Scroll down within CreateItem Case > Parameters. Set RecommendedTeam to the RecommendedTeam variable and AssignedToText to ApproverEmail. For ReceivedAt, select the trigger's Received Time token (the label may appear as Date Time Received). Enter addHours(utcNow(),variables('SLAHours')) as the DueAt expression and utcNow() as LastAutomationRun. Select the classifier's corresponding Product, Country, and Summary outputs for those fields, and the InquiryType variable for InquiryType Value. Continue down the panel to configure AIProposal, ClassificationSource, Status, and AutomationStatus from the table above. Continue down CreateItem Case > Parameters. Set Status Value to New and AutomationStatus Value to Processing. For AIProposal, open the expression editor, enter string(body('Classify_Support_Inquiry')?['classification']), and select Add (or Update for an existing expression). This stores the classifier's classification object as text. The collapsed token in the screenshot displays string(...); select it to inspect the full expression. Enter AI recommendation validated by SupportTeams for ClassificationSource. Select the RecommendedRoutingKey and RoutingReason variables from dynamic content for their corresponding fields; the purple tokens are variable values, not literal text. At the bottom of CreateItem Case > Parameters, select the RiskFlags and MissingFields variables from dynamic content for their matching fields. For ConfidenceBand Value, select the ConfidenceBand variable as a custom value. The purple tokens shown here are variable values; do not type their names as plain text. This screenshot belongs to the accepted-recommendation branch. For the classifier-unavailable branch, use the explicit fallback values described in Step 3. Add SharePoint > Update item named UpdateItem AwaitingApproval . Use the ID returned by CreateItem Case , keep the same Title, set Status = Awaiting Approval and AutomationStatus = Processing, and update LastAutomationRun with utcNow() . Open UpdateItem AwaitingApproval > Parameters and select the same SharePoint site and Cases list. Select ID from CreateItem Case for Id. Under Advanced parameters, keep Title set to the CaseId variable, enter utcNow() for LastAutomationRun, and select Awaiting Approval for Status Value and Processing for AutomationStatus Value. This records the waiting state before the approval request starts. Add Start and wait for an approval, rename it Approval Assignment , and set the following values. Configure Timeout under the action's Settings: Setting Value Approval type Approve/Reject - First to respond Assigned to ApproverEmail from the validated SupportTeams row Timeout PT30M for the lab Title [CaseId] Review AI-recommended assignment to RecommendedTeam Under Parameters, select Approve/Reject - First to respond. Build Title with the CaseId and RecommendedTeam variables selected from dynamic content, and select the ApproverEmail variable for Assigned to. The purple tokens represent variable values; do not type the variable names as plain text. Open Approval Assignment > Settings > General, then enter PT30M in Action timeout. This sets the approval wait to 30 minutes. The separate Run after setting in step 10 determines which action handles that timeout. Include the product, country, recommended team, routing key, AI reason, confidence, risk flags, and original subject in the approval details. State the effect of each decision explicitly: Approve the AI recommendation to create an acknowledgement draft. Reject to keep the case in human review. In Approval Assignment > Parameters, scroll to Details and insert the dynamic-content tokens alongside their labels as shown. The September 9 configuration capture shows the complete reviewer message, including the final decision instructions. After the approval action, add a Condition named Condition Approved . Keep run after = is successful only and test body('Approval_Assignment')?['outcome'] equals Approve . The timeout path in step 10 must be a parallel branch from the approval action, not an action after this condition. Select the approval action's Outcome dynamic content in the left field (shown as body/outcome ), choose is equal to, and enter Approve in the right field. The highlighted row is the comparison to configure. Open Settings > Run after, expand Approval Assignment, and select only Is successful. This checks whether the approval action completed; the Outcome comparison above checks the reviewer's decision. A completed rejection follows the condition's False branch. A timed-out approval follows the separate timeout branch in step 10. In the approved branch, update the case to Assigned, record ApprovalOutcome = Approve and ApprovalComment = coalesce(first(body('Approval_Assignment')?['responses'])?['comments'],'') , and keep AutomationStatus = Processing. Open UpdateItem Approved in the True branch of Condition Approved. Select Cases, use ID from CreateItem Case for Id, and preserve Title = CaseId. Under Advanced parameters, select Outcome from Approval Assignment for ApprovalOutcome, use utcNow() for LastAutomationRun, and enter the blank-safe ApprovalComment expression above. The captured lab configuration shows its original first(...) token. Choose Assigned for Status Value and Processing for AutomationStatus Value; the later UpdateItem DraftRecorded action records successful draft creation. Add Office 365 Outlook > Draft an email message and rename it Draft Acknowledgement . Configure it: Draft field Value To From from the mailbox trigger Subject concat('We received your support request [',variables('CaseId'),']') From Shared mailbox address Importance Normal Body Use the template below, replacing bracketed values with dynamic-content tokens Use this draft body: Hello, We received your request. A reviewer approved the proposed assignment to our support team. Case: [CaseId] Team: [RecommendedTeam] This is a draft created for human review. It has not been sent automatically. Select the trigger's From token for To. Insert the CaseId variable into the subject and the CaseId and RecommendedTeam variables into the body; do not type the bracketed placeholders literally. The screenshot uses text plus a CaseId token for the subject, equivalent to the expression in the table. Verify the recipient, team, and wording before sending the draft manually. In Draft Acknowledgement, scroll down to Advanced parameters, select From (Send as), and enter the shared mailbox address configured in Step 1. The September 9 configuration capture below highlights this field. The From field selects the sender identity; it is not a destination-folder setting. Inspect Drafts for the account used by the Outlook connection and confirm the displayed From address. Do not assume that setting From to the shared mailbox also stores the draft in that shared mailbox. See the Office 365 Outlook connector reference. Add another Update item, rename it UpdateItem DraftRecorded , write the draft action's Id to DraftMessageId, set AutomationStatus = Success, and update LastAutomationRun. Select Cases and use ID from CreateItem Case for Id. Under Advanced parameters, preserve Title = CaseId, select the Id output from Draft Acknowledgement for DraftMessageId (displayed as body/Id), set LastAutomationRun to the expression utcNow(), and choose Success for AutomationStatus Value. The SharePoint item ID and the Outlook draft ID refer to different records; select each token from its corresponding action. In the rejected branch, update the case to Needs Review, record the approval outcome and comment, and set AutomationStatus = Review without creating a draft. Open UpdateItem Rejected in the False branch of Condition Approved. Select Cases, use ID from CreateItem Case for Id, and preserve Title = CaseId. Under Advanced parameters, select Outcome from Approval Assignment for ApprovalOutcome, use utcNow() for LastAutomationRun, and record the first approval response's comments in ApprovalComment. Use the blank-safe comments expression from item 6 above; the captured lab configuration shows its original first(...) token. Choose Needs Review for Status Value and Review for AutomationStatus Value. Add a parallel branch directly from Approval Assignment with a separate UpdateItem ApprovalTimedOut action. Use the SharePoint ID from CreateItem Case and preserve Title = CaseId. Select Configure run after > has timed out, then set Status = Needs Review, ApprovalOutcome = Timeout, and AutomationStatus = Review without creating a draft. Open Settings, scroll to Run after, and expand Approval Assignment. Select only Has timed out; leave the other three results unchecked. Return to Parameters. Use ID from CreateItem Case for Id and the CaseId variable for Title. Set ApprovalOutcome to Timeout, LastAutomationRun to the expression utcNow(), and ApprovalComment to No response was received before the approval timeout. Choose Needs Review for Status Value and Review for AutomationStatus Value. The timeout update protects the case record, but a timed-out approval can still mark its parent scope as failed. If Scope Catch is configured to run whenever that parent scope fails, it will also send the internal failure notification and may leave the overall run in a Failed state. The validation below preserves that observed behavior. The troubleshooting section provides an explicit handled-timeout exit to test as an improvement; it is not represented by the historical screenshots. Important: Do not add Send a draft message or another send action. Approval in this tutorial authorizes draft creation only. Save the flow and run Flow checker again. Resolve every error or warning before the approval test. At this point your accepted branch should contain the case, approval, outcome, and draft actions added in this step. Compare your action placement with this configuration view. The left red box contains the three approved-path actions in order; the middle box contains only the rejection update. The timeout update is outside the condition and connects directly to Approval Assignment with its timeout run-after setting. This screenshot shows the recorded configuration, before the handled-timeout improvement described below. Test approval and draft-only behavior Send the complete NovaScan X2 inquiry from Step 3 to the shared mailbox again as a new message. Do not use Resubmit for this test because the duplicate guard intentionally stops a replay with the same SourceMessageId . Open the new flow run, confirm that Condition RecommendationAccepted follows the True branch, and record the generated CaseId from CreateItem Case . In Power Automate, select Approvals > Received, then open the request for <CASE_ID> . Confirm that it displays EU Distributor Support, eu_distributor_support , the AI reason, High confidence, and an empty risk list. This Outlook capture, taken on September 9, shows the approval-request email dated August 8, 2026 for historical case AST-20260808-E11790B1 . The left results list keeps the request and its acknowledgement Draft together. The red rectangles identify the proposed team, routing key, AI reason, confidence, risk flags, and decision buttons. Personal details are masked. This is the request message; use approval history to verify the completed decision. Select Approve, enter a synthetic reviewer comment, and submit the response. After completion, select History and confirm that the request shows Outcome = Approved. Open RW Lab > Cases > Tutorial Evidence, select <CASE_ID> , and confirm that it records Assigned, ApprovalOutcome = Approve, AutomationStatus = Success, and a non-empty DraftMessageId. The approved-case screenshot at the beginning of this article shows a historical lab result. Use the CaseId generated by your own run for the remaining checks. Open Outlook for the account used by the Outlook connection, expand the navigation pane, select Drafts, and open We received your support request [<CASE_ID>] . Confirm that the acknowledgement remains editable, names the case and approved team, and states that it was not sent automatically. The acknowledgement for the historical case is open in the Outlook compose view. Check the editable subject and body, the case ID, and EU Distributor Support. The body states that the draft was created for human review and has not been sent automatically. The recipient is masked. This September 9 capture shows the existing draft reopened for inspection; the visible 5:06 PM saved time is not evidence of its original August 8 creation time. Verify Sent Items separately in the next step. In the Outlook navigation pane, select Sent Items, enter <CASE_ID> in the search box, and confirm that the search reports no sent acknowledgement. The approved test establishes the human decision and no-send boundary. Test the PT30M timeout boundary Send the complete NovaScan X2 inquiry again as a new message. Add a unique prefix such as [TIMEOUT-PT30M-01] to the subject so you can distinguish the run, and do not use Resubmit. Confirm that the run reaches Approval Assignment , record the generated CaseId and approval start time, and do not approve or reject the request. Wait at least 30 minutes. Do not shorten the action timeout for this evidence run; the purpose is to test the same PT30M value configured in the flow. Open the completed run and confirm that Approval Assignment shows TimedOut and UpdateItem ApprovalTimedOut succeeded. Open the corresponding Cases row and confirm Status = Needs Review, ApprovalOutcome = Timeout, AutomationStatus = Review, and an empty DraftMessageId. Search Outlook Drafts and Sent Items for the CaseId and confirm that neither contains an acknowledgement for the timed-out request. The tested PT30M run produced CaseId AST-20260808-F1A058C2 . The approval timed out after 30 minutes, the timeout update succeeded, and the case retained Needs Review / Timeout / Review with no draft ID. No customer acknowledgement was found in Drafts or Sent Items. Warning: The same run exposed a control-flow issue. Approval Assignment timed out inside Scope Try , so the parent scope was marked Failed even though UpdateItem ApprovalTimedOut succeeded. Scope Catch then sent the internal failure notification, and Terminate Failed left the overall run in a Failed state. The case is safely held for review, but this timeout is not yet normalized as a handled outcome. To avoid a false failure alert, isolate the approval timeout from the catch condition or add an explicit handled-timeout exit before enabling the flow for production. This is the only long-running walkthrough in the tutorial. The remaining stateful outcomes are summarized below. Record the remaining stateful checks Check Evidence Observed result Approved recommendation Approval history, Cases, Drafts, and Sent Items Assigned / Success ; draft ID recorded; editable draft created; nothing sent. Low-confidence recommendation Cases and flow run Needs Review / Review ; no approval or draft. Classifier unavailable Cases and flow run Fallback proposal stored as Needs Review / Review ; no approval or draft. Reviewer rejection Approval history, Cases, Drafts, and Sent Items Needs Review / Review ; no matching draft or sent message. Duplicate replay Flow run and Cases Duplicate termination succeeded; no second row. Approval timeout Approval action, timeout update, Cases, Drafts, and Sent Items Approval timed out; timeout update succeeded; Needs Review / Timeout / Review ; no acknowledgement. Overall run Failed and sent the internal failure notification because Catch also handled the timed-out parent scope. Compare Status, AutomationStatus, ConfidenceBand, and ApprovalOutcome for the recorded August 8 cases: low confidence, approved, classifier fallback, rejected, another low-confidence case, and timeout. The fallback row retains the historical High default; these records do not show a new workflow run or prove that the proposed Low default was deployed. To check the recorded approved case, open Sent Items in the Outlook account used by the flow connection and search for AST-20260808-E11790B1. The September 9 recapture below shows Nothing found in Sent Items. Outlook expands the search to other folders after finding no match in Sent Items; those additional results are outside this crop. This checks the existing August 8 case, not a new workflow run. Evaluate the completed workflow Keep AI evaluation separate from flow-state tests. The GitHub sample contains 20 synthetic inquiries. Eighteen are evaluated directly against the authenticated classifier. Exact-message replay is tested separately against the flow. The existing-case follow-up fixture is also excluded from the classifier run, but automatic follow-up merging is not implemented in this walkthrough; do not count that fixture as a passed flow capability. Return to the sample root (if you are in azure/global-support-classifier , run cd ../.. ) and run the fixture validator: node --test tests/aster-imaging-fixtures.test.mjs Set the authenticated classifier endpoint and Function key only in the current terminal session. In PowerShell: $env:RW_CLASSIFIER_URL='https://<FUNCTION_APP_NAME>.azurewebsites.net/api/classify-support-inquiry' $env:RW_CLASSIFIER_FUNCTION_KEY='<FUNCTION_KEY>' Run the authenticated classifier regression: node tests/global-support-classifier-regression.mjs Review the aggregate result. The final authenticated regression produced: Measure Result Fixture count 20 Classifier cases evaluated 18 Excluded from classifier evaluation 2: replay and follow-up Cases passing every evaluator check 12 of 18 (66.7%) Product match rate, returned classifications 100% Country match rate, returned classifications 100% Inquiry-type match rate, returned classifications 100% Team-key match rate, returned classifications 100% Evaluator safety-scenario criterion Passed Low-confidence review boundary Passed Prototype criteria Passed Inspect the per-case differences instead of relying only on the aggregate result. In the authenticated rerun on August 8, 2026, using deployment gpt-5.4-mini pinned to version 2026-03-17 , 12 of the 18 classifier cases matched every evaluator check. Six did not pass every check: all six failed the summary-term check, one also differed on urgency, and one also differed on a missing-field expectation. The summary evaluator checks for specified terms; it does not require an exact sentence match. These differences need inspection and should not be dismissed as cosmetic without reviewing the outputs. Product, country, inquiry type, team recommendation, safety, and low-confidence criteria all passed. Keep those differences in the regression output rather than changing the benchmark around the model. The evaluator computes field match rates over responses that contain a classification, excluding failed HTTP calls. For the prompt-injection fixture, it treats any non-success HTTP response as a safe failure; that alone does not distinguish a content-filter refusal from a service outage. Its safety criterion also tolerates some inquiry-type, missing-field, and summary differences. Read the per-case output alongside the aggregate result. This small, known synthetic set is a regression check, not an independent or held-out accuracy study. The evaluator never calls Approvals or Outlook. Its safety result cannot establish that the cloud flow withheld an approval, blocked an attachment, or sent no email; those claims require the separate flow and mailbox checks above. A successful process exit means the configured prototype thresholds passed, even when some individual checks failed. Compare the classifier results and the stateful validation matrix with these synthetic prototype thresholds: product, country, inquiry type, and team recommendation accuracy are each at least 90%; directly evaluated safety, privacy, prompt-injection, and unsupported-attachment inputs satisfy the evaluator criteria; separately verify that a returned risky proposal cannot pass the live acceptance gate; every low-confidence or invalid-key result enters Needs Review; a duplicate message ID does not create a second case; a classifier failure creates a Needs Review row; an unexpected flow failure is visible in run history and sends the internal failure notification, but may not leave or update a Cases row; no test sends a customer-facing acknowledgement automatically. Clear the Function key from the terminal session when the run is complete: Remove-Item Env:RW_CLASSIFIER_FUNCTION_KEY Record the evaluation scope and limitations. These results are not production accuracy, security, capacity, or SLA claims. Re-evaluate with approved representative data, target-tenant policies, and an operational review process before production use. Troubleshooting Symptom Check or next action The custom connector cannot be created or used Confirm environment permissions, custom-connector entitlement, and data policies. Connector test returns 401 or 403 Check the connector host and Function key. For an upstream authorization error, separately check the Function managed identity and its role on the Foundry resource. Classifier returns a non-success response Inspect Function logs for the bounded upstream code, then check deployment name, quota, role propagation, and content-filter behavior. Keep the case in review. A valid recommendation goes to Needs Review Inspect all five gate inputs. In this lab, any missing field or risk flag causes a hold, even at High confidence. A later email appears delayed With trigger concurrency set to one, the previous run may still be waiting for approval. Complete or let that lab approval time out before testing another message. An expression cannot find an action Check the action's internal name and its nesting. Keep each expression inside a branch where its referenced action ran. Draft creation fails or the draft seems missing Check the Outlook connection account, mailbox delegation, and that account's Drafts folder. Setting From does not select the storage folder. A timeout case is in review but the run is Failed The generic Catch also observed the timed-out parent scope. See the handling pattern below. Treat a recorded timeout as a handled outcome The historical lab deliberately remains visible in the screenshots: the case update succeeded, but the run failed and sent an internal alert. For a lab where a recorded timeout should finish successfully, test this small change: On the timeout-only branch, keep UpdateItem ApprovalTimedOut after Approval Assignment with run after = has timed out. Immediately after that update, add Terminate, name it Terminate HandledTimeout , and set Status = Succeeded. Let it run only after the update succeeds. The case must be durably recorded as Needs Review / Timeout / Review before the successful exit. Keep the generic Catch for unexpected failures. Do not configure the successful exit to run after a failed or skipped case update, and do not place it on the normal approval path. Repeat the full PT30M test. Require the case's timeout state, an empty DraftMessageId, no acknowledgement in Drafts or Sent Items, no generic failure notification, and an overall Succeeded run. Separately verify that an unexpected SharePoint update failure still reaches Catch. This is a proposed correction to the recorded lab, not a newly verified tenant result. No post-correction screenshot or live run is included in this article. The pattern uses Power Automate's run-after and termination controls; validate it in your environment before relying on it. Production considerations Save incoming requests separately from the long-running approval process so pending reviews do not serialize new messages. Design recovery for partial completion: a Cases row can exist while draft creation or its ID update fails. Duplicate detection alone does not repair that case, and replaying blindly can create extra drafts. Replace tutorial-level SharePoint permissions with least-privilege role assignments and a documented ownership model. Confirm data residency, retention, DLP, audit, and connector policies. Store attachments separately and scan them before downstream processing. Pass only approved attachment metadata to the classifier if the unsupported-attachment gate is expected to protect the live flow. Add a Catch-path upsert if every unexpected failure must leave Status = Failed and AutomationStatus = Failed in Cases. Separate handled approval timeouts from unexpected failures so a successful timeout update does not also trigger the generic failure notification and failed termination. Use a supported secretless identity path for any AI service. Define operational ownership for rule changes, failed runs, approval timeouts, and mailbox delegation changes. Re-evaluate licensing and capacity for the target environment. Test with approved representative data before making any accuracy or SLA claim. Clean up the lab Turn off RW - Global Support Intake - v1 first and cancel any outstanding lab runs or approvals. Remove the dedicated connector connection and its Function key when they are no longer needed. Delete the dedicated Function app, model deployment, and associated lab storage or monitoring resources after retaining the synthetic evidence you want to keep. Delete a whole resource group only if it contains exclusively disposable lab resources. If you created the mailbox, SharePoint site, or Power Platform environment solely for this exercise, remove them through their respective admin tools when finished. Keep shared resources used by other work. Confirm that the remaining Azure resources and deployments match what you intend to retain.