ai
205 Topics
Using Jev with Agents in Microsoft Foundry for Model Evaluation
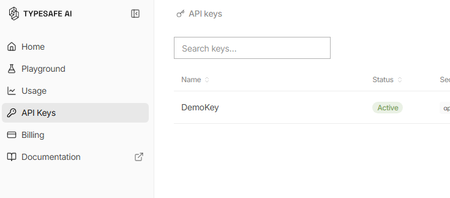
What is Jev? Jev is a new AI model from TypeSafe AI, first released in early access on 15 September 2026. TypeSafe describes Jev as its first “System One” model, designed specifically to make fast, structured decisions rather than generate free-form text. You provide Jev with some state or context and define the judgement you want it to make. It then returns a typed, probabilistic decision, such as: Choice: select from a defined set of options Score: evaluate something against an ordered scale Yes/No probability: determine the probability of a condition being true Unlike a conventional LLM, Jev gives up string generation in favour of type-safe structured values. Their description is essentially unstructured state in, typed probabilistic decisions out Why use Jev? Jev is particularly useful when an application needs to make a judgement rather than generate an answer. For example: Consistent evaluation against explicitly defined criteria Structured outputs that applications can consume directly Classification, assessment, routing and decision-support Agent workflows, where a judgement is required before taking an action Guardrails, such as assessing whether an agent should make a tool call Model routing, where a judgement determines which model or process should handle a request Every decision can also include a confidence or probability, allowing an application to use thresholds to decide when to proceed automatically or when further review is required. Jev and explainability Jev can provide a different approach to explainability for Model-as-a-Service (MaaS) and hosted LLM solutions. Traditional explainability techniques such as SHAP provide feature-attribution explanations for model predictions. Applying these techniques can be more difficult when the model is consumed solely through a hosted API and its internals are not available. Jev does not replace SHAP or provide the same type of feature-attribution explanation. Instead, it can be used as a separate judgement layer, evaluating an LLM's inputs, outputs or proposed actions against explicit criteria and returning structured decisions with confidence scores. For example: LLM generates an answer → Jev evaluates the answer → application decides what to do next This can provide a useful, measurable evaluation layer around otherwise opaque MaaS models. Could you do this with another LLM? Yes you could ask a conventional LLM to classify, score or evaluate an input and request structured JSON output. However, Jev has been purpose-built for this type of workload rather than general-purpose text generation. TypeSafe reports that Jev produces outputs in parallel rather than generating tokens sequentially, and its hosted service currently advertises typical decision latency of approximately 70–500 ms. Pricing As of September 2026, TypeSafe's documentation lists Jev 1.13 (jev-1.13.0) at $0.042 per million input tokens, with output tokens free. It lists rate limits of 250,000 tokens per second and 1,200 requests per minute, although TypeSafe states that these limits can change. As Jev produces decisions rather than generated text, you are effectively paying for the context it evaluates rather than for generated output. Pricing is subject to change and these figures are accurate only as of the date of this article Using Jev with Microsoft Foundry A useful pattern with Microsoft Foundry is to treat Jev as a specialised judgement/evaluation component alongside your generative models: User/Application → Foundry model or agent → Jev judgement → deterministic logic → action/response For example, a Foundry-hosted model could generate a proposed answer and Jev could evaluate that answer against predefined criteria before your application allows the workflow to continue. Here's how to set it up: First, you will need to apply for the preview for Jev from TypeSafe. Once you have an account you will need to create an API key Go to API keys in the menu and create a new key (copy the key for use in Foundry) You may also have received some free credit, which should be more than sufficient for experimenting with Jev given its low per-token cost. Next we go to Foundry and create a new agent for Jev In your agent, add a Tool and select OpenAPI tool as below Fill out the dialogue as follows You will have to create a new connection - The key should be in this format "Bearer apikey_<the rest of your key>" For the schema add this { "openapi": "3.0.3", "info": { "title": "TypeSafe Jev System One", "version": "1.1.0", "description": "Evaluate content using TypeSafe Jev System One." }, "servers": [ { "url": "https://api.typesafe.ai" } ], "paths": { "/v1/systemone": { "post": { "operationId": "evaluate_with_jev", "summary": "Evaluate content using Jev", "description": "Evaluate state against typed questions using TypeSafe Jev.", "security": [ { "bearerAuth": [] } ], "requestBody": { "required": true, "content": { "application/json": { "schema": { "type": "object", "additionalProperties": false, "required": [ "state", "model", "questions" ], "properties": { "state": { "type": "string", "description": "The original text or content for Jev to evaluate." }, "model": { "type": "string", "enum": [ "jev-latest" ], "default": "jev-latest", "description": "The TypeSafe Jev model. Use jev-latest." }, "questions": { "type": "object", "description": "A map of named questions for Jev to answer. Each question must be a Noul, Choice, or Score question.", "additionalProperties": { "oneOf": [ { "$ref": "#/components/schemas/NoulQuestion" }, { "$ref": "#/components/schemas/ChoiceQuestion" }, { "$ref": "#/components/schemas/ScoreQuestion" } ] } } } } } } }, "responses": { "200": { "description": "Successful Jev evaluation", "content": { "application/json": { "schema": { "type": "object", "additionalProperties": true } } } }, "400": { "description": "Invalid request" }, "401": { "description": "Authentication failed" }, "422": { "description": "Request validation failed" } } } } }, "components": { "schemas": { "NoulQuestion": { "type": "object", "additionalProperties": false, "required": [ "type", "instructions" ], "properties": { "type": { "type": "string", "enum": [ "noul" ] }, "instructions": { "type": "string", "description": "The yes/no question for Jev to evaluate." }, "criteria": { "type": "object", "additionalProperties": false, "properties": { "true": { "type": "string", "description": "Description of what a yes or value near 1 means." }, "false": { "type": "string", "description": "Description of what a no or value near 0 means." } } } } }, "ChoiceQuestion": { "type": "object", "additionalProperties": false, "required": [ "type", "instructions", "criteria" ], "properties": { "type": { "type": "string", "enum": [ "choice" ] }, "instructions": { "type": "string", "description": "The question for Jev to decide between the supplied choices." }, "criteria": { "type": "object", "description": "A map where each property name is a possible choice and its value describes that choice.", "minProperties": 2, "additionalProperties": { "type": "string" } } } }, "ScoreQuestion": { "type": "object", "additionalProperties": false, "required": [ "type", "instructions", "criteria" ], "properties": { "type": { "type": "string", "enum": [ "score" ] }, "instructions": { "type": "string", "description": "The attribute or question Jev should score." }, "criteria": { "type": "array", "description": "Ordered scoring levels from lowest to highest.", "minItems": 2, "items": { "type": "string" } } } } }, "securitySchemes": { "bearerAuth": { "type": "apiKey", "name": "Authorization", "in": "header" } } }, "security": [ { "bearerAuth": [] } ] } We are going to use Jev to assess complaints so our instructions for the Agent will be You are a customer-support triage agent. For every customer-support message you MUST call the evaluate_with_jev tool. IMPORTANT: When calling evaluate_with_jev, construct Jev questions using ONLY the following property names: For a Noul question: { "type": "noul", "instructions": "...", "criteria": { "true": "...", "false": "..." } } For a Choice question: { "type": "choice", "instructions": "...", "criteria": { "option1": "...", "option2": "..." } } For a Score question: { "type": "score", "instructions": "...", "criteria": [ "lowest level", "middle level", "highest level" ] } NEVER use these properties: - question - prompt - options - ordered_criteria Always use: - instructions - criteria For customer support tickets, ask Jev these three questions: billing: type = noul instructions = "Does this ticket concern billing, payments, charges, invoices or refunds?" criteria.true = "The issue concerns billing or a financial transaction." criteria.false = "The issue does not concern billing or a financial transaction." tone: type = choice instructions = "What is the customer's tone?" criteria: calm = "Neutral, polite or informational." frustrated = "Dissatisfied, impatient or inconvenienced." angry = "Strongly confrontational or extremely dissatisfied." urgency: type = score instructions = "How urgently does this ticket require attention?" criteria in this exact order: 1. "Can wait" 2. "Handle this week" 3. "Handle today" Always set model to "jev-latest". Pass the customer's original message as state. Do not classify the ticket yourself. Use the values returned by Jev. Always show the Jev output at the end of the response Now we can give a complaint and see what Jev says The room had no water in and one of the towels was dirty Response I’m sorry about the issues you experienced—no running water and a dirty towel are unacceptable. I’ll get this addressed right away. Immediate help I can arrange now: Send maintenance to restore water. Have housekeeping deliver fresh towels and re-service the bathroom. Provide bottled water immediately. If water can’t be restored quickly, arrange a room move. Please share: Your reservation name and room number Best contact number Whether there’s no water at all or only hot/cold is affected Whether you prefer immediate service or a room change If you’ve already left, let me know the date/time this happened so we can investigate and follow up. Jev output: { "model": "jev-1.13.0", "answers": { "billing": { "type": "noul", "noul": 0.02 }, "tone": { "type": "choice", "choice": "frustrated", "confidence": 0.6, "probabilities": { "frustrated": 0.74, "calm": 0.26, "angry": 0.0 } }, "urgency": { "type": "score", "score": 1.81, "confidence": 0.72, "legend": { "0": "Can wait", "1": "Handle this week", "2": "Handle today" }, "probabilities": { "0": 0.03, "1": 0.12, "2": 0.85 } } }, "usage": { "input_tokens": 466, "output_tokens": 75 } } We can now see both Jev's decision and the probabilities behind it. In this example, Jev determines that the complaint is very unlikely to be billing-related, identifies the customer's tone as frustrated, and gives a high probability that the issue should be handled today. This is where Jev becomes particularly useful in an agent workflow. Rather than relying on generated text to drive the next step, our application can use these structured probabilities to make deterministic decisions, such as routing the complaint, escalating it, or requiring human review when confidence falls below a defined threshold.From Jev to Your Laptop: Building "System One" Decision Models in ONNX with Mobius
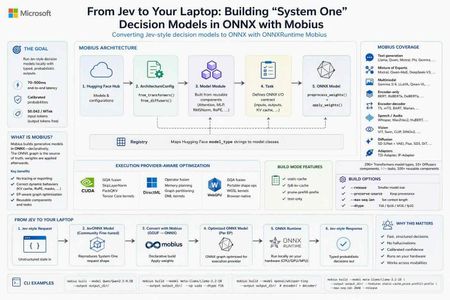
0. Why I'm writing this now Two things landed on my radar in the same week. First, TypeSafe AI published "Introducing System One Models & Jev" (Sep 15, 2026) and the developer community immediately started arguing about it. The pitch is unusual: instead of another chat model, Jev is described as "a new class of frontier models built to make fast, structured decisions that software can use directly." The post frames Jev as "a frontier-intelligence function call: unstructured state in, typed probabilistic decisions out" — and notes that while "Jev gives up string generation, it's optimized for structured outputs and can't hallucinate." The numbers in that post are what got everyone's attention: end-to-end response times of 70ms–500ms versus 3–329 seconds for frontier LLMs, input tokens at $0.042/MTok with output tokens free, and a claim that every answer arrives with a calibrated probability — "higher confidence means higher accuracy." The name itself is a thesis: TypeSafe named Jev after William Stanley Jevons, expecting that "every order of magnitude drop in the cost of intelligence unlocks orders of magnitude more use cases." Second — and this is the part that matters for anyone who builds on Microsoft's AI stack — onnxruntime/mobius has been quietly shipping at a furious pace. It's the piece of infrastructure that makes it realistic to take a model like this, in whatever format it arrives, and run it as an ONNX graph on hardware you control. So I built the bridge. kinfey/JevONNX takes an open, community-fine-tuned model that reproduces the System One request shape, converts it from GGUF to CPU ONNX with Mobius, and serves typed probabilistic decisions locally. This post covers three things: what Mobius is, how it differs from the ONNX Runtime GenAI Model Builder you may already be using, and how the JevONNX sample puts it together. 1. What is Mobius? Mobius builds generative models in ONNX. That preposition is the whole idea. From the repo's own description, Mobius provides "ONNX model definitions for GenAI using the onnxscript.nn API" — model definitions for "LLMs, MoE, multimodal, encoder-only, encoder-decoder, vision, audio, and diffusion models — built directly as ONNX graphs using onnxscript.nn.Module." The key sentence, and the one worth reading twice: "Rather than tracing or exporting PyTorch models, it constructs the ONNX graph declaratively, then applies pretrained HuggingFace weights." Why "declarative construction" is a big deal If you've ever exported a model to ONNX the traditional way, you know the failure modes. You run torch.onnx.export, the tracer executes one concrete path through Python control flow, and anything dynamic — a KV cache branch, a rotary embedding computed with a Python if, a sliding-window mask — either silently bakes in a constant or explodes into an unreadable subgraph. You then spend a week diffing graphs. Mobius inverts this. The graph is the source of truth, written as composable modules, and the weights are applied afterwards. The architecture in the README is four clean layers: HuggingFace Hub │ ▼ ArchitectureConfig ◄── from_transformers() / from_diffusers() │ ▼ Model Module ◄── Reusable Components (Attention, MLP, RMSNorm, RoPE, …) │ ▼ Task ◄── CausalLMTask, VisionLanguageTask, VAETask, DenoisingTask, … │ ▼ ONNX Model ◄── preprocess_weights() + apply_weights() Components — onnxscript.nn.Module building blocks (Attention, MLP, DecoderLayer, RoPE, VisionEncoder, MoELayer…) Models — full architectures composed from those components Tasks — define the ONNX graph's I/O contract (inputs, outputs, KV cache) Registry — maps HuggingFace model_type strings to model classes Adding a new architecture becomes writing a model definition, not debugging an exporter. Mobius even ships developer skills in .agents/skills/ (adding-a-new-model, reusable-components, moe-models, multimodal-models, writing-tests, writing-rewrite-rules) so an AI coding agent can do the legwork with you. Coverage This isn't a toy. The repo claims 290+ Transformers model types and 10 Diffusers component types across 40+ task types and 100+ reusable components, spanning: Category Examples Text generation Llama 2/3/4, Mistral, Qwen 2/2.5/3/3.5/3.6, Phi-3/3.5, Gemma 1/2/3/4, Granite, GPT-2, OPT, OLMo, SmolLM3 Mixture of Experts PhiMoE, GPTOSS, Mixtral, OLMoE, DeepSeek-V2/V3, Qwen2-MoE, Qwen3-MoE, Qwen3-Next, GLM-4-MoE, Arctic, DBRX, Jamba Multimodal Gemma 3/4, Phi-4MM (vision + audio + LoRA), LLaVA, InternVL2, MiniCPM-V 4.6, Qwen2.5-VL, Qwen3-VL, Pixtral Encoder-only BERT, RoBERTa, ALBERT, DeBERTa, DistilBERT, ELECTRA, XLNet Encoder-decoder BART, T5/mT5, Marian, M2M-100, Pegasus, BigBird-Pegasus Speech-to-text Whisper, Moonshine, Moonshine Streaming, FastConformer-RNNT, FunASR, GLM-ASR, Qwen3-ASR, SenseVoice Audio Wav2Vec2, HuBERT, WavLM, SpeechT5 Vision ViT, BEiT, DeiT, DINOv2, Swin, CLIP, SigLIP Diffusion Stable Diffusion (UNet + VAE + ControlNet), Flux, SD3, DiT, QwenImage / Qwen-Image-Edit-2509, HunyuanDiT, CogVideoX Adapters T2I-Adapter, IP-Adapter The five-minute version pip install -e . from mobius import build pkg = build("meta-llama/Llama-3.2-1B") pkg.save("output/llama-3.2-1b/") Static KV cache, when you know your max sequence length up front: from mobius import build, CausalLMTask task = CausalLMTask(static_cache=True, max_seq_len=2048) pkg = build("meta-llama/Llama-3.2-1B", task=task) pkg.save("output/llama-3.2-1b-static/") EP-aware optimization — the graph itself is tuned per execution provider, "each with the right set of fused kernels and lowering passes applied automatically": # CUDA: GQA fusion, SkipLayerNorm, PackQKV pkg = build("meta-llama/Llama-3.2-1B", execution_provider="cuda", dtype="f16") # WebGPU: GQA fusion, Shape ops replaced with portable alternatives pkg = build("meta-llama/Llama-3.2-1B", execution_provider="webgpu", dtype="f16") And the CLI, which is what we'll use later: mobius build --model Qwen/Qwen2.5-0.5B --output output_dir/ mobius build --model meta-llama/Llama-3.2-1B --output output_dir/ --ep cuda --dtype f16 mobius build --model openai/whisper-tiny --output output_dir/ # encoder/ + decoder/ Build-mode toggles use a cargo-style --features flag — available features are static-cache, fp8-kv-cache, prune-prefill-prefix, and text-only: mobius build --model meta-llama/Llama-3.2-1B --output output_dir/ \ --features static-cache,prune-prefill-prefix --max-seq-len 2048 --release strips build-time debug and provenance metadata to reduce saved model size, while preserving functional metadata keyed with the mobius. prefix. 2. Mobius vs. the ONNX Runtime GenAI Model Builder This is the question I get every time I demo Mobius, so let's be precise. Both are Microsoft tools, both produce ONNX, and they are not competitors — they sit at different points on the same pipeline. The ONNX Runtime GenAI Model Builder describes itself as the tool "for quickly creating optimized and quantized ONNX models within a few minutes that run with ONNX Runtime GenAI." Its output is a deployment-ready package: model.onnx plus genai_config.json plus tokenizer files, wired for the onnxruntime-genai runtime. Its architecture list is explicitly curated — AMD OLMo, ChatGLM, DeepSeek, ERNIE 4.5, Gemma, gpt-oss, Granite, Granite MoE Hybrid, HunYuan Dense V1, InternLM2, LFM2, LFM2 MoE, Llama, Mistral, Nemotron, Phi, Qwen, SmolLM3, Whisper — and the README states plainly that "it is intended for supporting the latest, popular state-of-the-art models." Mobius, by contrast, is a model-definition library: a component algebra for describing generative architectures as ONNX graphs, with a registry mapping HuggingFace model_type strings to model classes. Here's how I'd separate them: Dimension ORT GenAI Model Builder Mobius Primary goal Produce a deployment-ready GenAI package, fast Define and construct the ONNX graph itself Output contract model.onnx + genai_config.json + tokenizer, targeted at the ORT GenAI runtime ONNX model package; you choose the runtime (plain ORT sessions included) How the graph is made Per-architecture builder subclasses (LlamaModel, QwenModel, Phi3MiniModel, WhisperModel…) overriding make_layer / make_attention / make_moe Declarative onnxscript.nn.Module composition from reusable Components → Models → Tasks Breadth Curated list of ~19 popular families, text + Whisper 290+ Transformers types, 10 Diffusers component types, 40+ tasks — including vision, audio, and diffusion Extending it Add a builder subclass inside the onnxruntime-genai tree Add a model definition from existing components; shipped .agents/skills/ guide it Tuning surface Rich --extra_options for quantization and runtime behavior (QMoE, paged attention, KV-cache quantization, QDQ, CUDA/WebGPU graph capture…) --features build toggles + execution_provider= EP-aware graph lowering + dtype control Diffusion / multi-component pipelines Not the target First-class (--model Qwen/Qwen-Image-2512 builds all components) When I reach for it "I have a Phi/Llama/Qwen chat model and I want an int4 CPU/CUDA package running under ORT GenAI today" "My architecture is hybrid, unusual, multimodal, diffusion, or I need graph-level control over what gets emitted" Notably, the two overlap on real capabilities. The Model Builder also consumes GGUF and handles Qwen3.5-class features (compact state updates, recurrent-operator selection). Mobius also emits ORT-GenAI-compatible metadata — though the repo is honest about limits: for Mage-VL, "ORT GenAI export is currently rejected because the runtime cannot supply its required patch_positions input or Mage-VL's 1D decoder positions." That single line tells you exactly where the boundary sits: the Model Builder is bounded by what the GenAI runtime can express; Mobius is bounded by what ONNX can express. My rule of thumb as an advocate: if your model is on the Model Builder's supported list and you want the GenAI runtime's generation loop, use the Model Builder — it is faster and gives you a complete package. The moment you're off that list, or you need the graph itself to be a first-class artifact you can reason about and modify, Mobius is the tool. The JevONNX sample is squarely in the second category. Let's look at why. 3. The sample: converting a Jev-style decision model to CPU ONNX Repo: github.com/kinfey/JevONNX 3.1 The honest framing first Jev is TypeSafe's proprietary model. You can't download it and convert it, and this project doesn't pretend otherwise. What the community did do is interesting: n4ze3m/Qwen3.5-4B-Hmm is "an experimental open-model attempt to reproduce the central idea and request shape of the System One workflow introduced with Jev." It works by "fine-tuning Qwen3.5-4B to answer typed questions through option probabilities instead of ordinary generated text." The README of JevONNX is emphatic about the boundaries, and I want to repeat them here rather than bury them: "Hmm is not Jev, is not affiliated with TypeSafe AI, and does not reproduce Jev's proprietary model architecture, parallel sampler, performance, calibration, or type-safety guarantees. The Hmm model card explicitly states that it is less capable than Jev." And: "The reproduction is behavioral rather than architectural." The distinction, straight from the project's comparison table: Property Jev Hmm in this project Model design Native System One Model Qwen3.5-4B fine-tuned to reproduce the typed-decision concept Output mechanism Native typed probabilistic outputs First-token option-letter probabilities Multiple questions Designed for parallel sampling Jev-like request shape, implemented as one model pass per question Output types Schema-constrained structured values noul, choice, and score adapter Runtime here TypeSafe service Local ONNX Runtime CPU Guarantees As documented by TypeSafe No equivalent guarantee is claimed The mechanism is refreshingly legible: the adapter turns each typed question into an exact multiple-choice prompt, then "reads the first generated-token logits for A, B, C, and subsequent option letters and normalizes them into probabilities." No JSON parsing, no retry-on-malformed-output, no regex. The probability distribution is the answer. 3.2 Why this needs Mobius specifically Qwen3.5 is a hybrid architecture, and that's the whole reason this is a Mobius story. The exported model has 32 hybrid decoder layers. Linear-attention layers carry conv_state and recurrent_state; full-attention layers carry key/value caches. In this artifact, full-attention layers sit at indices 3, 7, 11, 15, 19, 23, 27, and 31. The practical consequence, quoted from the README: "The prompt is processed one token at a time while every present.* output is fed back into its corresponding past_key_values.* input. This differs from a conventional decoder-only example that can prefill an entire prompt in one call." That is a graph-shape problem. You cannot handwave it with a config flag — you need the exported graph's state contract to be explicit and inspectable, which is exactly what declarative construction gives you. The implementation "follows the structure of Mobius examples/text_generation.py while adding the hybrid-state handling required by Qwen3.5." 3.3 The conversion pipeline n4ze3m/Qwen3.5-4B-Hmm-Q4_K_M.gguf │ SHA-256 verification ▼ Mobius GGUF reader/importer │ metadata and tensor mapping │ Qwen3.5 hybrid graph construction │ Q4_K_M → packed quantized target storage │ CPU execution-provider optimization ▼ onnx_outputs/ ├── model.onnx ├── model.onnx.data ├── quantization_report.json ├── tokenizer.json ├── tokenizer_config.json ├── chat_template.jinja └── cpu_test_summary.json │ ▼ ONNX Runtime CPUExecutionProvider │ token-by-token hybrid-state prefill │ first-token A/B/C/… probabilities ▼ typed decision JSON response One command does the conversion: mobius build-gguf Qwen3.5-4B-Hmm-Q4_K_M.gguf \ --output onnx_outputs \ --ep cpu \ --dtype f32 \ --release Two details worth internalizing: --dequantize is intentionally not used. Keeping quantized storage "substantially reduc[es] the output size compared with a fully dequantized FP32 model." The external-data file is still ~2.6 GB — imagine it dequantized. Don't trust the preset, read the report. "Q4_K conversion can involve a lossy affine repack; inspect quantization_report.json rather than assuming source-preset fidelity." This is the kind of line that separates a demo from a deployment. 3.4 Reproducibility — the part I actually want you to copy Every pin, in a table, in the README: Component Revision GGUF repository n4ze3m/Qwen3.5-4B-Hmm GGUF revision c27fa3c627dfaced343c6ba9d3a0d00243a3be51 GGUF filename Qwen3.5-4B-Hmm-Q4_K_M.gguf GGUF SHA-256 5e03cb057049c56b421bd3c506d77fd8e0a77996bb8464148a02cfc3caac5229 Mobius revision 6b27a3f08b8b5d08ba9b14b416e3b435942bb0bd Tokenizer repository Qwen/Qwen3.5-4B Tokenizer revision 851bf6e806efd8d0a36b00ddf55e13ccb7b8cd0a The notebook builds a Mobius wheel from the pinned Git source rather than installing a prebuilt package. On a project moving at 500+ commits, that is not paranoia — that is the only way your conversion is still reproducible next month. 3.5 Running it Two files carry the project: Qwen3_5_4B_Hmm_GGUF_to_CPU_ONNX_Mobius_fixed.ipynb (the Colab conversion and validation workflow) and run_hmm_onnx.py (the standalone typed-decision runner). Run the notebook in a high-memory Colab CPU runtime; it writes to /content/onnx_outputs on Colab and .mobius_colab_run/onnx_outputs elsewhere. Then: python run_hmm_onnx.py --model-dir .mobius_colab_run/onnx_outputs python run_hmm_onnx.py --model-dir .mobius_colab_run/onnx_outputs --request request.json A request is state plus typed questions: { "state": "Help! My payouts have failed for 3 days. I need the money today.", "questions": { "is_urgent": { "type": "noul", "instructions": "Does this message convey urgency?" }, "department": { "type": "choice", "instructions": "Which team should handle this?", "criteria": { "billing": "Payments, invoicing, refunds", "technical": "Bugs, outages, integrations", "sales": "Pricing, upgrades, new accounts" } }, "priority": { "type": "score", "instructions": "How urgent is this request?", "criteria": ["Not urgent", "Normal", "Urgent", "Critical"] } } } From Python: from pathlib import Path from run_hmm_onnx import HmmOnnx model = HmmOnnx(Path(".mobius_colab_run/onnx_outputs")) response = model.decide({ "state": "Help! My payouts have failed for 3 days.", "questions": { "is_urgent": { "type": "noul", "instructions": "Does this message convey urgency?", } }, }) print(response) 3.6 The three decision types noul — a nullable-style yes/no probability; the probability of the true option: { "type": "noul", "noul": 0.9745 } choice — the highest-probability key, all normalized option probabilities, and a confidence value measuring how peaked the distribution is: { "type": "choice", "choice": "billing", "probabilities": { "billing": 0.7216, "technical": 0.2759, "sales": 0.0025 }, "confidence": 0.5823 } score — the expected numeric level, the level legend, normalized probabilities, and confidence: { "type": "score", "score": 2.6653, "legend": { "0": "Not urgent", "1": "Normal", "2": "Urgent", "3": "Critical" }, "probabilities": { "0": 0.0061, "1": 0.0361, "2": 0.2443, "3": 0.7135 }, "confidence": 0.618 } Look at that score output for a second. You don't get "this is critical." You get 2.6653 — a distribution leaning hard on Critical but with real mass on Urgent. That's a number your routing code can threshold on, log, and A/B test. It's the difference between an LLM that says it's confident and a distribution you can actually calibrate against. One constraint: Hmm is trained with 26 option letters. Larger option sets are handled by splitting them into groups of 25 and adding a none_of_these option to each group, matching the reference Hmm server strategy. 3.7 Does it actually run? Yes — the README reports the generated model executed directly on an Apple Silicon CPU with ONNX Runtime. A 4B hybrid-architecture model, converted from GGUF, running typed decisions on a laptop CPU with no service dependency. 4. What I'd tell a room of developers The System One idea is portable even where the model isn't. You can't run Jev locally, but the shape — state in, typed decisions with probabilities out — is something you can prototype today with an open model and an ONNX graph. As TypeSafe puts it, structured outputs "slot into ordinary software as fuzzy decision rules: classify, route, score, extract, or branch where hand-written logic is too brittle." That's a pattern, not a product. Probabilities are the actual product. The reason this class of model matters isn't speed alone. TypeSafe's argument is sharp: "If a model can do a task 95% of the time but doesn't say when it's in the 5%, it can't automate that task." Every engineer who has shipped an LLM feature has felt that exact wall. Set expectations honestly. JevONNX is an educational reproduction. It gives you noul/choice/score on a local CPU. It does not give you Jev's calibration, parallel sampler, or type-safety guarantees — and the project says so in its own README. Ship that caveat with your demo. Mobius is the infrastructure bet worth learning. When a new architecture shows up — hybrid attention, a novel MoE routing scheme, a three-model multimodal export — the question stops being "will the exporter support it?" and becomes "which components do I compose?" That is a much better question to be asking. Links Mobius — https://github.com/onnxruntime/mobius (docs: https://onnxruntime.github.io/mobius/) ONNX Runtime GenAI Model Builder — https://github.com/microsoft/onnxruntime-genai/tree/main/src/python/py/models JevONNX sample — https://github.com/kinfey/JevONNX Introducing System One Models & Jev — https://typesafe.ai/blog/introducing-system-one-models-and-jev Hugging face - https://huggingface.co/lokinfey/Qwen3_5_4B_Hmm_ONNXBuild an AI-assisted support email workflow with Power Automate and Microsoft Foundry
Difficulty: Intermediate A support email arrives with a product name, an error code, and a country. Before anyone can help, someone has to interpret the request, find the right team, record the case, and decide what to tell the customer. In this tutorial, you build that support email workflow with Microsoft 365, Power Automate, Azure Functions, and Microsoft Foundry. AI extracts the request details and recommends a support team. The flow checks the recommendation against a SharePoint catalog, asks a person to approve it, and creates an editable Outlook acknowledgement draft. The central design decision is who can do what: the model proposes a routing key; the flow validates it; a person approves draft creation. No customer-facing send action is included. What you will build Mina manages support operations at Aster Imaging, a fictional imaging-equipment company. Claire, a fictional distributor in France, reports error E42 on a NovaScan X2 after installing software version 4.2.1. When Mina approves the validated recommendation, the workflow produces: Input or decision Recorded result Claire's support email One case linked to its source message ID Validated AI recommendation Technical Support, NovaScan X2, France, EU Distributor Support Mina selects Approve Approval outcome and an editable acknowledgement draft Missing information, a risk flag, rejection, or timeout A case held in Needs Review The recorded approved case shows the review outcome and successful automation state: All names, products, organizations, and test messages are synthetic. This is a reference implementation for a lab, based on public support-form patterns, rather than a description of a company's internal process. Who this is for This walkthrough is for Power Platform makers and developers who can already create a cloud flow and a SharePoint list, and want to connect AI to a workflow with explicit review boundaries. You will use the Azure portal and a few terminal commands to deploy the supplied Function project. In this tutorial Architecture and resources Tutorial scope and boundaries Prerequisites Download the sample Step 1: Prepare the mailbox and SharePoint lists Step 2: Deploy and connect the AI classifier Step 3: Build and validate the support email flow Step 4: Add human approval, create a draft, and evaluate the workflow Troubleshooting Production considerations Clean up the lab Architecture and resources Workflow architecture The completed workflow follows this path: When Claire's message arrives in the shared mailbox, Power Automate first checks the message ID to avoid creating a duplicate case. It then sends the subject and body to the AI classifier. The classifier identifies the request as technical support, extracts NovaScan X2 and France , and recommends EU Distributor Support . Power Automate does not accept that recommendation without verification. It checks the structured response, confidence band, and risk flags, and confirms that the recommended routing key matches an active entry in the SupportTeams list. If the checks pass, the workflow records the case in SharePoint and asks Mina to review the recommendation. If Mina approves it, Power Automate creates an acknowledgement draft in Outlook. It does not send the message. If the recommendation has low confidence, contains a risk flag, fails validation, or is rejected by Mina, the case remains in Needs Review . Resource names To keep the steps consistent and easy to follow, this tutorial uses the resource names below. You can use different names in your environment, but keep track of the corresponding values as you work through the steps. Resource Name Power Platform environment RW Development Solution RW Global Support Intake Publisher prefix rw SharePoint site RW Lab SharePoint lists Cases , SupportTeams Shared mailbox RW Lab Support Main flow RW - Global Support Intake - v1 Azure resource group Your lab resource group; referenced as <RESOURCE_GROUP> Microsoft Foundry resource Your globally unique resource; referenced as <FOUNDRY_RESOURCE_NAME> Microsoft Foundry project The project opened in the Foundry portal; referenced as <FOUNDRY_PROJECT_NAME> Model deployment gpt-5.4-mini Azure Function App Your globally unique app; referenced as <FUNCTION_APP_NAME> Tutorial scope and boundaries This tutorial builds the workflow in stages so that each layer can be tested before the next one is introduced. Step 1 prepares the shared mailbox and SharePoint records. Step 2 deploys the AI model and exposes the bounded classifier to Power Automate. Step 3 builds the support email flow and validates normal, review, fallback, and duplicate paths before approval exists. Step 4 adds human approval and draft creation, then evaluates the completed workflow end to end. What this tutorial covers Create a shared mailbox, SharePoint case register, and allow-listed support-team catalog. Connect a bounded AI classifier that returns structured fields and an advisory routing key. Build deterministic deduplication, recommendation validation, and exception paths in Power Automate. Add a human approval checkpoint that creates an Outlook draft without sending it. Walk through three representative paths: accepted recommendation, review hold, and approval timeout. Record the remaining synthetic checks in a compact validation matrix. What is out of scope Send customer-facing email automatically. Let AI assign the final owner, approve a request, change SupportTeams , or send a message. Process real customer data, retrieve attachment contents, or scan attachments. The mailbox flow passes attachments = [] ; attachment-metadata checks are exercised only in the direct classifier tests. Merge a new follow-up email into an existing case. The duplicate guard checks the same message ID; a new reply has a different ID. Treat the prototype results as production accuracy, security, capacity, or SLA claims. Prerequisites A Microsoft 365 test tenant with Exchange Online and SharePoint Online A licensed test user who can open Outlook and SharePoint Permission to create a shared mailbox and assign mailbox delegation A Power Platform environment with Dataverse for the solution and approvals, and permission to use the Office 365 Outlook, SharePoint, Approvals, and custom connectors For a development-only lab, an eligible Power Apps Developer Plan environment; otherwise, Power Automate use rights that cover this flow and its custom connector An Azure subscription in which you can create or select a Microsoft Foundry resource, deploy a model, and create an Azure Functions app Permission to enable the Function app's managed identity and assign it the Cognitive Services OpenAI User role Node.js 22, Azure CLI, and Azure Functions Core Tools v4 on the workstation used for deployment; the tested Core Tools version is 4.0.7512 Permission to create custom connectors, connection references, environment variables, and solutions in the Power Platform environment Licensing and cost Microsoft 365 access alone does not establish entitlement to the custom connector used here. Confirm the target environment's license and data policies before building the flow. The Developer Plan includes custom connectors for development and testing; production use needs appropriate paid rights. See the Power Platform licensing FAQ. Azure model inference, Function hosting, storage, and monitoring can incur charges. Usage depends on the selected region, hosting plan, model, message size, and test volume. Check those resources in Azure Cost Management and clean up the dedicated lab resources when finished. The recorded evaluation is not a cost benchmark. Download the sample Get the companion code from the example project on GitHub. Clone the repository or download and extract the ZIP to a local folder. Use the extracted repository folder as the sample root in the commands below. The repository contains the Function source, locked dependencies, connector definition, synthetic data, setup instructions, and local tests. You build the Power Automate flow in the designer; this sample is not an importable Power Platform solution. Path from the sample root Purpose azure/global-support-classifier/ Deployable Azure Function project azure/global-support-classifier/connector/apiDefinition.swagger.json Custom connector definition; replace its sample host before import data/aster-imaging/support-teams.json Twelve sample team keys and descriptions data/aster-imaging/inquiries.json Twenty synthetic inquiries and expected results tests/aster-imaging-fixtures.test.mjs Offline dataset checks tests/global-support-classifier-regression.mjs Authenticated classifier evaluation evidence/classifier-regression-20260808.md Historical lab result and evaluation limits The model evaluation results come from the August 8, 2026 lab. This article combines recorded lab screenshots with configuration screens recaptured on September 8–9, 2026 for clearer step-by-step instructions. Recapturing a configuration screen does not verify a new workflow run. A separate single-request connector test on September 8, 2026 returned HTTP 200 and passed schema validation; its input and response are shown in Step 2. The GitHub v0.1.0 sample preserves the September 8, 2026 implementation snapshot, with repository setup documentation added on September 9. Portal labels, model availability, and quotas can differ in your tenant. Step 1: Prepare the mailbox and SharePoint lists In this step, you prepare the Microsoft 365 resources used by the workflow. The shared mailbox receives support requests, the SharePoint site provides a private workspace, the Cases list stores each request and its workflow state, and the SupportTeams list defines the support teams that the AI classifier is allowed to recommend. Services and tools used in this step Service Purpose Exchange Online Create the shared support mailbox and assign mailbox permissions. SharePoint Online Create the private team site and the Cases and SupportTeams SharePoint lists. Create the shared support mailbox The shared mailbox provides a single email address for support requests. Power Automate monitors this mailbox and starts the workflow when a new message arrives. For example, Claire sends her request to RW Lab Support , and the new message starts the support email flow. Open the Exchange admin center and go to Recipients > Mailboxes. Create a shared mailbox with these values: Display name: RW Lab Support Email alias: rw-lab-support Domain: your lab tenant's default domain Note: Creating the mailbox requires the Exchange Administrator or Global Administrator role. After creation, grant the lab user both Full Access and Send As. A Microsoft 365 license does not grant these permissions automatically. Review the current shared mailbox permissions and licensing rules before using this design in production. After the mailbox is created, delegate both permissions to the lab user: Full Access lets the user open and modify the shared mailbox. Send As lets the user create a draft using the shared mailbox address. Note: Full Access alone is not sufficient for the later draft-from-shared-mailbox step. To review delegation in the Microsoft 365 admin center, go to Teams & groups > Shared mailboxes, select RW Lab Support, and open Read and manage permissions. This is the Full Access permission described above. Select Add permissions to add the lab user. Return to the mailbox details and also configure Send as permissions for that user. Create the SharePoint site The SharePoint site provides a private workspace for the workflow's lists and case data. Keeping these resources on one site also makes permissions and ownership easier to manage. In this tutorial, RW Lab contains both the Cases list and the SupportTeams list used to process Claire's request. Open SharePoint and select Build in the left navigation. Under Start building, select Site. Then select Team site. If prompted to choose a template, select Standard team. Configure the site using the following values. Field Value Site name RW Lab Site description Synthetic global support workflow lab Group email address Accept the generated alias if it is available. Site address Confirm the generated SharePoint address. Privacy settings Private - only members can access this site Language English Important: The group email address and site address must be unique in your tenant, so SharePoint may adjust the generated values. You cannot change the site's default language after creation. The red boxes group the fields you can complete on this screen and the final Create site button. Check the generated site address separately. This annotated image uses the recorded lab screen. Select Create site, add owners or members if required, and finish the site setup. Create the Cases list The Cases list is the durable record after the flow has enough information to create a case. It stores source-message metadata, the AI proposal, the validated or fallback team, review outcome, and automation status. It does not copy the complete email body or attachments into SharePoint. For Claire's request, the flow first checks SourceMessageId , loads the active team catalog, calls the classifier, and validates the proposed routing key. It then creates one row containing the message metadata and AI result. A normal high-confidence row is updated as it moves through approval and draft creation. Low-confidence, risky, invalid-key, and classifier-unavailable requests are created directly as Needs Review . A duplicate creates no second row, and an unexpected failure before row creation appears only in the flow run history and the internal failure notification. Open SharePoint and select Build in the left navigation. Under Start building, select List, and then select Blank list. Enter Cases for Name, select RW Lab for Save to, and then select Create. SharePoint opens the new Cases list after creating it. In the Cases list, select Add column, choose the matching column type, and configure the columns shown in the following table. The Title column already exists by default; configure it as shown rather than creating another Title column. Note: In the current SharePoint interface, Text creates a single-line text column. Use Multiple lines of text for longer values such as Summary , RoutingReason , and AIProposal . Column Type Configuration Title Single line of text Required; stores the case ID SourceMessageId Single line of text Enforce unique values ReceivedAt Date and time Include time RequesterEmail Single line of text Synthetic test addresses only EmailSubject Single line of text Original subject InquiryType Choice Technical Support, Quote, Demo, Product Information, Partnership, Complaint, Other Product Single line of text AI-extracted canonical product name Country Single line of text AI-extracted country Summary Multiple lines of text AI-generated summary in plain text RecommendedRoutingKey Single line of text Routing key proposed by the AI classifier RecommendedTeam Single line of text Team name resolved from SupportTeams RoutingReason Multiple lines of text AI-provided reason for the recommendation ConfidenceBand Choice High, Medium, Low; use Low as the default for a new lab RiskFlags Multiple lines of text Risk signals returned by the classifier MissingFields Multiple lines of text Required information not found in the message AIProposal Multiple lines of text String form of the classification object, or a classifier-unavailable message ClassificationSource Single line of text Records validated recommendation, held recommendation, or classifier-unavailable fallback AssignedToText Single line of text Reviewer email resolved from SupportTeams Status Choice New, Classified, Needs Information, Awaiting Approval, Assigned, Needs Review, Failed DueAt Date and time Include time ApprovalOutcome Single line of text Approve, Reject, or Timeout ApprovalComment Multiple lines of text Plain text DraftMessageId Single line of text ID returned by the Outlook draft action AutomationStatus Choice Processing, Success, Review, Failed LastAutomationRun Date and time Include time Set SourceMessageId to enforce unique values. Power Automate also checks for the message ID before creating a row; the SharePoint constraint provides a second layer of duplicate protection. To verify the constraint, open Settings > List settings > SourceMessageId. Keep the type Single line of text, set Enforce unique values to Yes, and select OK if you changed it. Open Settings > List settings > ConfidenceBand. Enter High, Medium, and Low on separate lines, use the Drop-down menu display, and leave fill-in choices disabled. For your new list, set Default value to Low, then select OK. The existing lab default is High; use Low for a new build. Classified and Needs Information remain in the current lab list from the earlier implementation. The AI-recommendation path documented below does not write those two values. The current Catch scope also does not write Failed ; it sends an internal failure notification and terminates the run. Create a list view named Tutorial Evidence with Title, EmailSubject, Product, Country, RecommendedTeam, ConfidenceBand, Status, ApprovalOutcome, AutomationStatus, DraftMessageId, ClassificationSource, and ReceivedAt. Sort ReceivedAt newest first. Later validation steps use this view; use the row details pane for columns that do not fit on screen. Create the SupportTeams list The SupportTeams list defines the support teams or queues that the AI classifier is allowed to recommend. Power Automate uses it to validate each recommendation and resolve the reviewer and SLA target. It does not store individual team members or calculate routing from product and country. For Claire's request, the AI proposes eu_distributor_support . Power Automate confirms that this key is active and resolves it to EU Distributor Support , its reviewer, and its four-hour SLA target. Open SharePoint and select Build in the left navigation. Under Start building, select List, and then select Blank list. Enter SupportTeams for Name, select RW Lab for Save to, and then select Create. SharePoint opens the new SupportTeams list after creating it. In the SupportTeams list, select Add column, choose the matching column type, and configure the columns shown in the following table. The Title column already exists by default; configure it as shown rather than creating another Title column. Column Type Configuration Title Single line of text Display name RoutingKey Single line of text Enforce unique values TeamName Single line of text Support team name ApproverEmail Single line of text Reviewer address SLAHours Number No decimal places Active Yes/No Default Yes Important: Set RoutingKey to enforce unique values. This ensures that each AI recommendation resolves to exactly one support team. Power Automate accepts a recommendation only when the key matches an active row, then uses that row's team name, reviewer, and SLA target for the normal approval path. Open Settings > List settings > RoutingKey. Keep Single line of text, set Enforce unique values to Yes, and select OK. The September 9 lab capture below shows the existing No setting; it is a configuration gap, not the recommended setting for your new list. Add the 12 synthetic rows shown below. For closer parity with the direct evaluator, use each matching description in data/aster-imaging/support-teams.json as Title; the shorter titles below are the labels used in the original mailbox lab. The flow sends Title as the routing description, so changing it changes model input and requires a rerun. Replace each <YOUR_EMAIL> placeholder with the lab reviewer address. Title RoutingKey TeamName ApproverEmail SLAHours Active EU distributor support eu_distributor_support EU Distributor Support <YOUR_EMAIL> 4 Yes NA technical support na_technical_support NA Technical Support <YOUR_EMAIL> 4 Yes APAC distributor support apac_distributor_support APAC Distributor Support <YOUR_EMAIL> 4 Yes Software support software_support Software Support <YOUR_EMAIL> 4 Yes EU regional sales eu_regional_sales EU Regional Sales <YOUR_EMAIL> 8 Yes NA regional sales na_regional_sales NA Regional Sales <YOUR_EMAIL> 8 Yes APAC regional sales apac_regional_sales APAC Regional Sales <YOUR_EMAIL> 8 Yes Global partnerships global_partnerships Global Partnerships <YOUR_EMAIL> 8 Yes Global support global_support Global Support <YOUR_EMAIL> 8 Yes Security review security_review Security Review <YOUR_EMAIL> 1 Yes Privacy review privacy_review Privacy Review <YOUR_EMAIL> 1 Yes Safety and compliance safety_and_compliance Safety and Compliance <YOUR_EMAIL> 1 Yes Review the completed list. Confirm that all 12 rows show Active = Yes and that no RoutingKey value appears more than once. The recorded lab catalog contains 12 active teams with the routing keys and SLA hours shown above. This list view omits reviewer addresses; configure ApproverEmail for every row using your lab reviewer account. Step 2: Deploy and connect the AI classifier In Step 1, you created the shared mailbox and SharePoint lists that provide the workflow's email channel, case record, and approved support-team catalog. In this step, you add the AI classification layer. You deploy an Azure OpenAI model in Microsoft Foundry, connect it to an Azure Function, and expose the Function to Power Automate through a custom connector. For example, suppose Claire emails the shared mailbox to report that a NovaScan X2 in France shows error E42 during startup after software version 4.2.1 is installed. The classifier extracts NovaScan X2 as the product, France as the country, and technical_support as the inquiry type. It summarizes the problem, returns a high confidence band, and recommends the routing key eu_distributor_support . This result is only a proposal. The classifier cannot approve the request, assign an owner, update the case, or send email. In Step 3, Power Automate validates the proposed key against the active SupportTeams list before deciding whether the request can proceed to human approval. Services and tools used in this step Service or tool Purpose Microsoft Foundry (Azure OpenAI models) Create or select the Foundry resource and deploy the model used for classification. Azure Functions Call the model, enforce the structured response contract and guardrails, and expose a bounded HTTP endpoint. Microsoft Entra ID and Azure RBAC Allow the Function app to call the model through its managed identity. Power Automate custom connectors Make the Azure Function operation available to cloud flows. Power Platform solutions Package the custom connector, connection references, and environment variables used by the workflow. Note: The local deployment tools used in this step are Node.js 22, Azure CLI, and Azure Functions Core Tools. Create a Foundry resource and deploy the model An Azure subscription is the billing and access boundary. Inside that subscription, a Microsoft Foundry resource provides the model endpoint and quota. A Foundry project is the workspace you open in the Foundry portal, and a model deployment inside that project gives the Function app a stable deployment name to call. Creating a subscription or resource alone does not deploy a model. The tested lab uses gpt-5.4-mini , pinned to model version 2026-03-17 . It provides the structured output and instruction-following behavior needed by this bounded extraction and routing task without using a larger model for every incoming message. Sign in to the Azure portal and confirm that the correct directory and subscription are selected. Search for Microsoft Foundry, select Create, and create a Foundry resource if you do not already have one that the lab can use. Choose the target subscription and resource group, enter a globally unique resource name, select a region in which gpt-5.4-mini has quota, and keep the Standard S0 pricing tier. For a disposable lab, the basic public-network configuration is sufficient; use private networking and organization-approved controls for production. Note: You need permission to write the resource, such as Contributor or Owner, and separate model quota in the selected region. Microsoft documents the current resource fields in Create a Microsoft Foundry resource. Open the Microsoft Foundry portal and verify the directory and subscription. Select a project associated with the Foundry resource you created. If no project exists yet, create one under that resource and record its name as <FOUNDRY_PROJECT_NAME> . Enable the New Foundry experience if the portal offers the switch. On the project home page, select View deployments under Use a model. You can return to the same page later through Build > Deployments. On Deployed models, select Deploy > Deploy a base model, search for gpt-5.4-mini , and configure the deployment with the following tested values: Setting Tested value Deployment name gpt-5.4-mini Model version 2026-03-17 Deployment type Global Standard Capacity 100 thousand tokens per minute Version upgrade policy Once current version expires Content filter Microsoft.DefaultV2 Important: Capacity is quota, not a target for the tutorial. Select a lower value when your subscription has less quota; the synthetic lab traffic does not require 100K tokens per minute. If this model or version is unavailable in your region, choose an approved region or model only after confirming structured-output support, then repeat the final evaluation in Step 4 with that exact deployment. Select Deploy and wait until the deployment state is Succeeded. Record the resource endpoint and deployment name. The Function app uses the deployment name, not the catalog model label, when it constructs the request. The screenshot below is a verification view of the completed lab deployment, not the initial creation form. Optionally verify the deployed version from Azure CLI. This read-only command helps catch the common mistake of configuring the Function with a deployment that exists under another resource or subscription: az login az account set --subscription "<SUBSCRIPTION_ID>" az cognitiveservices account deployment show ` --resource-group "<RESOURCE_GROUP>" ` --name "<FOUNDRY_RESOURCE_NAME>" ` --deployment-name "gpt-5.4-mini" ` --query "{state:properties.provisioningState, model:properties.model.name, version:properties.model.version, sku:sku.name, capacity:sku.capacity}" The tested deployment returned Succeeded , model gpt-5.4-mini , version 2026-03-17 , SKU GlobalStandard , and capacity 100 . Review the current Microsoft guidance for deploying Foundry models and model version update policies because availability, quota, and portal labels can change. Create, configure, and deploy the Azure Function Create and configure the Azure resource in the portal, then use Azure Functions Core Tools to publish the tested repository project. Do not copy the individual JavaScript files into the portal editor; this project has multiple source files, locked npm dependencies, and automated tests that should remain together. In the Azure portal, select Create a resource, search for Function App, and select Create. Configure the Function app using the following tested lab values. If you already have a compatible Node.js 22 Function app, open it and continue with the identity step. Setting Tested lab value Subscription The subscription that contains the Foundry resource Resource group The lab resource group Function App name A globally unique name; record it as <FUNCTION_APP_NAME> Publish Code Runtime stack Node.js Version 22 Operating system Linux Region The lab region; the tested app uses East US 2 Hosting Consumption; the tested app uses the Y1 / Dynamic plan Note: Microsoft currently recommends Flex Consumption for new serverless Function apps. The implementation documented here was tested on Linux Consumption. If you select a different hosting plan, confirm its deployment and networking behavior before treating the tutorial results as equivalent. See Create a function app in the Azure portal. Select Review + create, select Create, and wait for the deployment to finish. Open the Function App resource and record its default host name from Overview. Under Settings > Identity, enable the system-assigned identity. On the Foundry resource, assign that identity the Cognitive Services OpenAI User role. The Function uses DefaultAzureCredential ; it does not store an Azure OpenAI API key. See the Microsoft guidance for managed identities in Azure Functions and Azure OpenAI role assignment. Under the Function app's environment variables or configuration settings, add these values: Setting Value AZURE_OPENAI_ENDPOINT Azure OpenAI endpoint, typically https://<FOUNDRY_RESOURCE_NAME>.openai.azure.com AZURE_OPENAI_DEPLOYMENT gpt-5.4-mini AZURE_OPENAI_API_VERSION 2024-10-21 Keep Show values disabled while capturing or sharing this page. The list should show the three setting names without exposing their values. Note: These are Azure Function app settings. They are separate from the rw_* Power Platform solution environment variables created later in this step. Download or clone the GitHub sample, open a terminal at the sample root, and move to the Function project: cd azure/global-support-classifier Verify the local tool versions, install the locked dependencies, and run the Function tests: node --version func --version npm ci npm test The tested deployment uses Node.js 22 and Azure Functions Core Tools 4.0.7512 . If func is not available, install a supported Core Tools v4 release by following the Core Tools installation guidance. In src/functions/classifySupportInquiry.js , locate buildAzureRequest and confirm that the GPT-5 request uses max_completion_tokens = 1100 and reasoning_effort = none . Do not add temperature or the older max_tokens field. GPT-5 reasoning models count reasoning and visible output against the completion-token budget; Microsoft documents the compatible parameters in Use reasoning models. Sign in with az login , select the intended subscription with az account set --subscription <SUBSCRIPTION_ID> , and confirm it with az account show --query name -o tsv . From the Function project directory, publish the complete project to the Function app: func azure functionapp publish <FUNCTION_APP_NAME> --javascript The --javascript option is explicit because automatic language detection did not identify this repository project during the tested publish. A successful publish reports Deployment completed successfully , synchronizes the classifySupportInquiry trigger, and prints its invoke URL. Core Tools packages and deploys the complete project from the current directory; review the Core Tools publishing guidance before using another hosting plan. Return to the Function App Overview page and confirm that classifySupportInquiry appears as an enabled HTTP function. This screen is meaningful only after the Core Tools publish succeeds. Define the response contract Open azure/global-support-classifier/src/functions/classifySupportInquiry.js and locate classificationSchema . Confirm that every property is required, bounded values use enumerations, and additionalProperties is false . Confirm that a successful call returns version 2.0 of this contract: { "schemaVersion": "2.0", "classification": { "inquiryType": "technical_support", "product": "NovaScan X2", "serialNumber": "NSX2-2407138", "country": "France", "organization": null, "urgency": "normal", "language": "en", "summary": "NovaScan X2 shows error E42 during startup after version 4.2.1.", "missingFields": [], "evidence": [ "NovaScan X2 serial NSX2-2407138", "error E42 during startup", "software version 4.2.1" ], "confidenceBand": "high", "riskFlags": [], "recommendedRoutingKey": "eu_distributor_support", "routingReason": "Technical support for NovaScan X2 in France routes to EU distributor support." } } Confirm that the contract includes recommendedRoutingKey , routingReason , and riskFlags . Power Automate stores all three and validates the key before resolving a team. Treat confidenceBand as a workflow category rather than a calibrated probability. Allow only high , medium , or low , and bound the risk values to prompt injection, unsupported attachment, privacy, safety, non-English, multiple-intent, low-confidence, and invalid-key signals. Supply the active team catalog with each request Open azure/global-support-classifier/connector/apiDefinition.swagger.json . Confirm that it is an OpenAPI 2.0 definition and that the request includes routingOptionsJson . Confirm that Power Automate will serialize each active catalog entry with this shape. The example below shows one of the 12 rows: [ { "routingKey": "eu_distributor_support", "teamName": "EU Distributor Support", "description": "Technical support for NovaScan products in Europe." } ] In classifySupportInquiry.js , confirm that the Function parses routingOptionsJson before constructing the model request. This string boundary avoids a Power Automate custom-connector metadata issue with arrays of objects; the model still receives a structured routingOptions array. Apply deterministic post-processing after the model response: detects prompt-injection phrases and unsafe attachment extensions; forces safety, privacy, and security signals to the corresponding review key when that key is active; removes a missing software version or screenshot flag when the source message contains that evidence; changes an unknown product-and-country result to low confidence; marks a recommendation invalid when its key is not in the supplied active catalog. Keep the Function advisory. These controls constrain the proposal, but Power Automate still performs the operational validation and assignment. The active destinations, reviewers, and SLA values live in SharePoint. The sample still encodes product/country routing precedence in the system prompt and post-processing code; changing that policy requires a code review and regression run as well as any catalog update. Keep attachment retrieval disabled for this version. The classifier supports attachment metadata and its direct regression tests exercise unsupported-attachment detection, but the live flow passes an empty attachments array and therefore does not inspect or block attachments. Create the custom connector Two different authentication boundaries are involved. The Function app calls Microsoft Foundry with its managed identity, so it stores no Azure OpenAI key. Power Automate calls the Function endpoint with x-functions-key ; that Function host key is not an Azure OpenAI key. Open azure/global-support-classifier/connector/apiDefinition.swagger.json from the sample root. Before importing the connector, replace its host value with <FUNCTION_APP_NAME>.azurewebsites.net . Keep basePath set to /api , the scheme set to https , and the operation ID set to ClassifySupportInquiryV3 . In Power Automate, select the RW Development environment. Open More > Discover all, find Data, and select Custom connectors. Select New custom connector > Import an OpenAPI file, enter RW Support Classifier , and upload apiDefinition.swagger.json . In the connector wizard, review General, Security, and Definition in order. On General, confirm HTTPS, your Function app's host name, and Base URL = /api, then select Security. Confirm API Key, Parameter label = Function key, Parameter name = x-functions-key, and Parameter location = Header. Select Definition and open Classify a support inquiry. Under Request, confirm POST, your Function URL ending in /api/classify-support-inquiry, and the required body parameter imported from the OpenAPI file. Continue with the response check below before creating the connector. The screenshots show an existing connector, whose toolbar displays Update connector instead of Create connector. Scroll farther down to Response and open 200 (Structured candidate fields). Confirm that References Used includes ClassifierResponse and Classification, and that Body exposes fields such as confidenceBand, routingReason, and schemaVersion. Select Back to return to the action definition, then select Create connector (or Update connector when modifying an existing connector). This screen checks the imported response definition; step 4 creates the authenticated connection and tests a real request. In the Azure portal, open the Function App's App keys page and create or copy a dedicated host key for this lab connection. Return to the connector's Test page, select New connection, enter that Function host key, and create the connection. Select the new connection (or your existing lab connection) and refresh the connection list if necessary. Under ClassifySupportInquiryV3, turn Raw Body on and paste the JSON below. Keep attachments as an empty array and routingOptionsJson as a JSON-encoded string. Select Test operation. In Response, confirm Status (200), schemaVersion = 2.0, a classification object, and Schema validation > Validation succeeded. Microsoft documents the current import and test flow in Create a custom connector from an OpenAPI definition. { "subject": "NovaScan X2 error E42 - France", "body": "NovaScan X2 serial NSX2-2407138 shows error E42 during startup after software version 4.2.1 was installed.", "from": "claire.martin@alpine-distribution.example.test", "attachments": [], "routingOptionsJson": "[{\"routingKey\":\"eu_distributor_support\",\"teamName\":\"EU Distributor Support\",\"description\":\"Technical support for NovaScan products in Europe.\"}]" } Important: The Function key belongs in the secure Power Platform connection. Do not put it in a text environment variable, flow action, screenshot, or source file. The September 8, 2026 request returned technical_support, France, confidenceBand = high, no risk flags, and recommendedRoutingKey = eu_distributor_support. This verifies one connector request; the flow still needs to apply its acceptance gate and obtain human approval. Add the components to the solution Open Solutions and create RW Global Support Intake . Create or select a publisher with prefix rw so the environment-variable schema names below match. Open the solution, select Objects, and use the object-type tree to review its components. Select Add existing, add the RW Support Classifier custom connector, and confirm that Custom connectors (1) appears in the object tree. Select New > More > Connection Reference and create these four named references: Office 365 Outlook SharePoint Standard approvals RW Support Classifier Select New > More > Environment variable and create these five variables: Display name Example schema name Current value Support Mailbox rw_SupportMailbox Shared mailbox address SharePoint Site URL rw_SharePointSiteURL RW Lab site URL Default Approver Email rw_DefaultApproverEmail Lab reviewer address Cases List Name rw_CasesListName Cases Support Teams List Name rw_SupportTeamsListName SupportTeams In Objects, select Connection references, Custom connectors, and Environment variables in turn. Confirm that the four required references, one connector, and five variables are present before creating the flow. The lab solution contains the four required connector types and additional automatically generated Outlook and SharePoint references. Match each flow action to its intended connection; the extra rows are not additional connector types to create. The five variables in the table are present. Routing Rules List Name is retained from an earlier lab design and is not required by this AI-recommendation workflow. Step 3: Build and validate the support email flow In this step, you build the flow that turns the bounded AI output from Step 2 into a validated recommendation. The flow checks duplicates, resolves an active team, applies the acceptance gate, and records uncertain or unavailable-classifier requests for human review. You then test both the normal validation path and the exception paths before adding approval in Step 4. Services and tools used in this step Service or tool Purpose Power Automate Build the automated cloud flow, scopes, conditions, and state transitions. Office 365 Outlook connector Start the flow when a message arrives in the shared mailbox. SharePoint connector Check for duplicates, load active support teams, and create review or fallback case rows. RW Support Classifier custom connector Send the message and active routing catalog to the Azure Function classifier. Create and configure the flow Use the action names shown below before writing expressions. In expression references, spaces become underscores: GetItems ExistingCase is referenced as GetItems_ExistingCase . Rename the custom connector action Classify Support Inquiry so its reference is Classify_Support_Inquiry . Select the matching dynamic-content token if your designer generated a different internal name. Enter formulas in the Expression editor without a leading @ . Values containing @{...} below are inline expressions in a text field. In this lab, enter the documented SharePoint list names directly in the connector; the list-name environment variables record configuration but are not automatically substituted into every action. Open RW Global Support Intake , select Objects > New > Automation > Cloud flow > Automated, and create RW - Global Support Intake - v1 . Add When a new email arrives in a shared mailbox (V2) and configure the trigger: Trigger field Value Original Mailbox Address rw_SupportMailbox current value Folder Inbox Importance Any Only with Attachments No Include Attachments No In Trigger NewSharedMailboxEmail > Parameters, select your shared mailbox under Original Mailbox Address. Open Advanced parameters to expose the four settings shown above: Importance = Any, Only with Attachments = No, Include Attachments = No, and Folder = Inbox. The September 9 lab capture displays an onmicrosoft.com address in the mailbox picker; select the mailbox you configured in Step 1 rather than copying the lab address. Open the trigger's Settings, turn on Concurrency Control, and set Degree of Parallelism to 1 . This serializes the lab runs, including time spent waiting for approval. A pending approval can delay the next email for 30 minutes. Use this setting for controlled tests; a design that processes new emails separately from approvals is needed before evaluating throughput. The current designer labels the concurrency switch Limit. The screenshot was captured at 125% browser zoom and cropped to the settings panel so the switch and value remain readable. After the trigger, select Add an action > Variable > Initialize variable for each row below. Keep every initializer above the Try scope and in the listed order: Variable Type Initial value CaseId String concat('AST-',formatDateTime(utcNow(),'yyyyMMdd'),'-',toUpper(substring(guid(),0,8))) InquiryType String Empty Product String Empty Country String Empty RecommendedTeam String Global Support ApproverEmail String rw_DefaultApproverEmail current value SLAHours Integer 8 RecommendedRoutingKey String Empty RoutingReason String Empty ConfidenceBand String Empty RiskFlags String Empty MissingFields String Empty For CaseId, enter the expression from the table through the Value field's expression editor, then select Add (or Update when editing an existing expression). The purple concat(...) token confirms that Value contains an expression. Select that token to reopen and check the full formula, as shown above. For SLAHours, set Name = SLAHours, Type = Integer, and Value = 8, as shown below. The other eleven variables in the table use String. Repeat the same Name, Type, and Value fields for each variable; where the table says Empty, leave Value blank. Keep all twelve initializers between the trigger and Scope Try. Compare the action order in these two views. The first red box contains CaseId through ApproverEmail; the second continues with SLAHours through MissingFields. Keep all twelve initializers outside and before Scope Try. These configuration views show placement; use the table above for each variable's type and initial value. Select Add an action > Control > Scope twice. Rename the first scope Scope Try and the second Scope Catch . On Scope Catch , select Configure run after and select has timed out, is skipped, and has failed for Scope Try . Inside Catch, add Send an email (V2) to the default approver with the CaseId and workflow run name, followed by Terminate with Status = Failed, Code = RW_INTAKE_FAILED , and an internal-only error message. In the current designer, open Settings > Run after, then expand Scope Try to reveal its result checkboxes. Leave Is successful unchecked. These are alternative results: any one of the three selected results allows Catch to run. Open SendEmail InternalFailure > Parameters. Set To to your internal default approver. In Subject, enter [RW Support Flow] Failed run followed by the CaseId variable token. In Body, write a short failure notice, add the CaseId token, and insert the expression workflow()?['run']?['name'] for the run reference so the reviewer can locate the failed run. For a new build, enter ordinary text in the rich-text Body editor, such as The support email flow failed., followed by the case ID, run reference, and Review the flow run before retrying. Do not paste HTML tags into the rich-text editor. The recorded configuration below contains escaped HTML tags as literal text; this is an existing formatting issue, not the recommended body format. This capture documents the saved inputs; the flow was not changed or rerun. Select Terminate Failed > Parameters and set Status to Failed and Code to RW_INTAKE_FAILED . For Message, use Global Support Intake failed; see the internal notification for the run reference. The canvas on the right shows where this action belongs: immediately after the internal notification inside Scope Catch. Note: The current Catch scope sends an internal notification and fails the run. It does not create a new Cases row or update an existing row to Failed. Add the duplicate guard Inside Scope Try , add SharePoint > Get items and rename it GetItems ExistingCase . Get items field Value Site Address rw_SharePointSiteURL current value List Name Cases Filter Query SourceMessageId eq '@{triggerOutputs()?['body/id']}' Top Count 1 In GetItems ExistingCase > Parameters, choose your site and the Cases list. Under Advanced parameters, enable Filter Query and Top Count. Keep the trigger's Message Id token inside the single quotes in the filter, and enter 1 for Top Count, as highlighted in this September 9 configuration capture. Add Data Operation > Compose, rename it Compose ExistingCaseCount , and use length(body('GetItems_ExistingCase')?['value']) . Open the Inputs expression editor in Compose ExistingCaseCount, enter length(body('GetItems_ExistingCase')?['value']), and apply it. This September 9 capture shows the existing expression opened for inspection, so the button is labeled Update. 3. Add a Condition, rename it Condition Duplicate , and test whether the Compose output is greater than 0 . In Condition Duplicate > Parameters, select Outputs from Compose ExistingCaseCount on the left, choose is greater than, and enter 0 on the right. The operator menu is open in this September 9 capture so its full label is visible. 4. In the True branch, add Terminate with Status = Succeeded. Leave case creation out of this branch. Build the remaining email-processing actions in the False branch. Place Terminate Duplicate in the True branch and set Status to Succeeded. Continue with GetItems ActiveSupportTeams and Select RoutingOptions in the False branch. This September 9 configuration capture shows both paths beside the termination setting. Load the catalog and call the classifier In the duplicate condition's False branch, add SharePoint > Get items and rename it GetItems ActiveSupportTeams . Get items field Value Site Address rw_SharePointSiteURL current value List Name SupportTeams Filter Query Active eq 1 Top Count 100 Select SupportTeams as the list. Under Advanced parameters, set Filter Query to Active eq 1 and Top Count to 100. This September 9 capture shows the active catalog query. Add Data Operation > Select, rename it Select RoutingOptions , set From to the value output from GetItems ActiveSupportTeams , and create this mapping: Key Value routingKey item()?['RoutingKey'] teamName item()?['TeamName'] description item()?['Title'] Use value from GetItems ActiveSupportTeams for From. Map routingKey to RoutingKey, teamName to TeamName, and description to Title. This September 9 capture shows the dynamic-content version of the expressions above. Add a Control > Scope, rename it Scope AI Recommendation , and place RW Support Classifier > Classify support inquiry inside it. Rename the classifier action Classify Support Inquiry and configure it: Input Value subject Subject from the mailbox trigger body Body from the mailbox trigger from From from the mailbox trigger attachments Empty array [] routingOptionsJson string(body('Select_RoutingOptions')) Select Subject, Body, and From from the mailbox trigger. Expand Advanced parameters to show from and attachments; keep the attachments array empty by adding no items. The September 9 designer labels these inputs with a Body/ prefix. For Body/routingOptionsJson, open the expression editor and enter string(body('Select_RoutingOptions')). Apply the expression with Add, or Update when editing an existing value as shown here. This converts the Select output array into the string expected by the connector. After the AI scope, add a Condition named Condition AIRecommendationAvailable . Use Configure run after so the condition runs when the AI scope succeeds, fails, is skipped, or times out. The True path is actions('Scope_AI_Recommendation')?['status'] equals Succeeded ; use the False path for the classifier-unavailable case. Open Settings > Run after, expand Scope AI Recommendation, and select all four statuses: Is successful, Has timed out, Is skipped, and Has failed. This September 9 configuration lets the next condition evaluate the AI scope even when the classifier is unavailable. Return to Parameters. In the left field, use the expression actions('Scope_AI_Recommendation')?['status']; select is equal to and enter Succeeded on the right. The empty row underneath is the designer's next-row placeholder. The True branch handles a successful AI call; the False branch handles an unavailable classifier. Validate the returned recommendation In the AI-available True branch, add Set variable actions in this order: Variable Value InquiryType Use the enum-to-choice mapping immediately below; unmatched values become Other Product coalesce(body('Classify_Support_Inquiry')?['classification']?['product'],'') Country coalesce(body('Classify_Support_Inquiry')?['classification']?['country'],'') RecommendedRoutingKey body('Classify_Support_Inquiry')?['classification']?['recommendedRoutingKey'] RoutingReason body('Classify_Support_Inquiry')?['classification']?['routingReason'] ConfidenceBand if(equals(body('Classify_Support_Inquiry')?['classification']?['confidenceBand'],'high'),'High',if(equals(body('Classify_Support_Inquiry')?['classification']?['confidenceBand'],'medium'),'Medium','Low')) RiskFlags join(body('Classify_Support_Inquiry')?['classification']?['riskFlags'],'; ') MissingFields join(body('Classify_Support_Inquiry')?['classification']?['missingFields'],'; ') For Set InquiryType , select the InquiryType variable, open the Value expression editor, and paste the following mapping. The recorded flow uses nested if expressions in this action: if(equals(body('Classify_Support_Inquiry')?['classification']?['inquiryType'],'technical_support'),'Technical Support', if(equals(body('Classify_Support_Inquiry')?['classification']?['inquiryType'],'quote_request'),'Quote', if(equals(body('Classify_Support_Inquiry')?['classification']?['inquiryType'],'demo_request'),'Demo', if(equals(body('Classify_Support_Inquiry')?['classification']?['inquiryType'],'product_information'),'Product Information', if(equals(body('Classify_Support_Inquiry')?['classification']?['inquiryType'],'partnership'),'Partnership', if(equals(body('Classify_Support_Inquiry')?['classification']?['inquiryType'],'complaint'),'Complaint','Other')))))) Select Add for a new expression, or Update when editing an existing one. The mapping is: Classifier value SharePoint Choice label technical_support Technical Support quote_request Quote demo_request Demo product_information Product Information partnership Partnership complaint Complaint Default, including other Other Add SharePoint > Get items, rename it GetItems RecommendedSupportTeam , and configure it: Get items field Value Site Address rw_SharePointSiteURL current value List Name SupportTeams Filter Query RoutingKey eq '@{variables('RecommendedRoutingKey')}' and Active eq 1 Top Count 1 Open GetItems RecommendedSupportTeam > Parameters. Select your SharePoint site and SupportTeams list. Under Advanced parameters, show Filter Query and Top Count. Insert the RecommendedRoutingKey variable between single quotes in the filter, retain and Active eq 1, and set Top Count to 1. Add Compose, rename it Compose TeamMatchCount , and use length(body('GetItems_RecommendedSupportTeam')?['value']) . In Compose TeamMatchCount > Parameters > Inputs, open the Expression editor and enter the expression above. Select Add for a new expression, or Update when editing an existing one. The result counts the rows returned by GetItems RecommendedSupportTeam. 4. Add Condition RecommendationAccepted and require every gate below: The acceptance gate requires all five checks: team match count = 1 AND ConfidenceBand = High AND riskFlags length = 0 AND missingFields length = 0 AND RecommendedRoutingKey is not empty Open Condition RecommendationAccepted > Parameters and use And to require all five checks. The September 9 lab screen above uses a team count greater than 0; the expression below uses a count equal to 1. With Top Count = 1, these checks have the same result, and neither detects duplicate catalog rows: enforce the unique RoutingKey constraint in SharePoint. The final empty row is the designer's next-row placeholder. Use this expression for the gate and compare its output with the Boolean true : and( equals(outputs('Compose_TeamMatchCount'),1), equals(variables('ConfidenceBand'),'High'), empty(body('Classify_Support_Inquiry')?['classification']?['riskFlags']), empty(body('Classify_Support_Inquiry')?['classification']?['missingFields']), not(empty(variables('RecommendedRoutingKey'))) ) Enable the unique RoutingKey constraint before relying on one returned row as an unambiguous match. The September 9 configuration check found this constraint disabled in the existing lab. Its recorded results therefore do not demonstrate protection against duplicate catalog keys; the new-build instructions in Step 1 require that protection. The model's confidence category is not a calibrated probability. Also, this sample holds every non-empty risk list, including product-alias and non-English flags. Those flags do not all indicate danger; the broad hold is a conservative lab policy with a review-volume tradeoff. In the accepted True branch, set RecommendedTeam to first(body('GetItems_RecommendedSupportTeam')?['value'])?['TeamName'] , ApproverEmail to first(body('GetItems_RecommendedSupportTeam')?['value'])?['ApproverEmail'] , and SLAHours to int(first(body('GetItems_RecommendedSupportTeam')?['value'])?['SLAHours']) . Leave space after these actions; Step 4 adds case creation, approval, and draft creation to this branch. In the False branch, add SharePoint > Create item named CreateItem NeedsReview . Store the AI fields, set Status = Needs Review, AutomationStatus = Review, and ClassificationSource = AI recommendation held for human review . Do not add an approval action. In the AI-available condition's False branch, add Create item named CreateItem ClassifierUnavailable . Use the fallback Global Support values, set InquiryType = Other, ConfidenceBand = Low, Status = Needs Review, AutomationStatus = Review, AIProposal = AI classifier unavailable or returned an invalid response. , and ClassificationSource = Classifier unavailable / human review . In CreateItem ClassifierUnavailable, set Summary to the mailbox trigger's Subject. The red boxes below show the fallback fields in the existing action. Under Advanced parameters, also add ConfidenceBand Value and select Low explicitly. The captured action omits that field and therefore inherits the existing list default, High; the screenshot does not show the recommended Low setting. Leave other classifier-derived fields empty and do not reference the failed classifier action's body. The matched SupportTeams row supplies RecommendedTeam, ApproverEmail, and SLAHours on the accepted recommendation path. Review rows created in this step store the AI reason and proposal; Step 4 stores the same evidence when it creates an accepted case. In both paths, the active catalog remains the operational allow-list. The current flow also initializes fallback values before the Try scope: Global Support , the default approver, and an eight-hour SLA. An invalid-key or classifier-unavailable review case can therefore retain fallback reviewer and SLA values without resolving a matching SupportTeams row. This is the actual lab behavior, not an additional validated assignment. Map the case fields consistently Use the following mapping on both review-case creation actions and on CreateItem Case in Step 4. Then apply each branch's Status, AutomationStatus, ClassificationSource, and AIProposal values. For the unavailable-classifier branch, use the trigger Subject for Summary, leave other classifier-derived fields empty, and write the explicit fallback message; do not reference the failed action's body. Cases field Value Title variables('CaseId') SourceMessageId Message Id dynamic content from the trigger, the same value used by the duplicate guard ReceivedAt Date Time Received dynamic content from the trigger RequesterEmail Sender's email address from the trigger, without the display name EmailSubject Subject from the trigger InquiryType, Product, Country Corresponding variables; fallback InquiryType is Other RecommendedRoutingKey, RoutingReason, RiskFlags, MissingFields Corresponding variables ConfidenceBand Corresponding variable, or explicit Low for classifier unavailable RecommendedTeam variables('RecommendedTeam') for accepted and classifier-unavailable cases; use the branch-specific expression below for NeedsReview AssignedToText variables('ApproverEmail') DueAt addHours(utcNow(),variables('SLAHours')) Summary body('Classify_Support_Inquiry')?['classification']?['summary'] when available AIProposal string(body('Classify_Support_Inquiry')?['classification']) when available LastAutomationRun utcNow() For CreateItem NeedsReview, set RecommendedTeam to if(greater(outputs('Compose_TeamMatchCount'),0),first(body('GetItems_RecommendedSupportTeam')?['value'])?['TeamName'],'Unvalidated recommendation') . This preserves the catalog team name when a match exists and records Unvalidated recommendation when none exists. The review branch does not run the accepted branch's Set ApproverEmail or Set SLAHours actions, so AssignedToText and DueAt retain the initialized default reviewer and eight-hour SLA. A displayed catalog team name does not mean the recommendation passed the acceptance gate. This mapping was checked in the existing configuration; no new run was performed. On every later Update item, use the ID returned by that branch's Create item and preserve Title = CaseId. Do not accidentally use the source email ID as the SharePoint item ID. DueAt is a simple target timestamp from processing time; this tutorial does not implement business calendars or SLA escalation. Check the flow Save the flow. Open Flow checker and resolve every reported error or warning before testing. At this stage, Flow checker should report zero errors and zero warnings before you send the validation messages: The highlighted toolbar button opens Flow checker. This designer check reports zero errors and warnings in the captured flow; it does not verify approval delivery, mailbox access, or runtime outcomes. Validate those paths with the test cases below. Test the normal validation path Send this complete synthetic inquiry to the shared mailbox: Subject: NovaScan X2 error E42 - France - software version 4.2.1 Hello Aster Support, We are a distributor in France. NovaScan X2 serial NSX2-2407138 shows error E42 during startup after installing software version 4.2.1. We captured the error screenshot. Regards, Claire In Power Automate, open Solutions > RW Global Support Intake > Objects > Cloud flows > RW - Global Support Intake - v1. Under 28-day run history, select the new run and confirm that the duplicate guard, classifier, active-team lookup, and Condition RecommendationAccepted succeeded. Inspect the classifier and variable actions in the run. Confirm that the flow produced Technical Support, NovaScan X2, France, High confidence, no risk flags or missing fields, eu_distributor_support , and a successful match to EU Distributor Support. Confirm that the acceptance condition followed its True branch. At this point, the flow has validated the recommendation but has not created the accepted case or approval request. Step 4 adds those actions to the True branch. This separation lets you verify the routing boundary before introducing consequential workflow actions. Test one representative review path A green normal run does not prove that uncertainty is held safely. Use one intentionally incomplete message to exercise the review boundary without repeating every exception as a full walkthrough. Send this intentionally incomplete message to the shared mailbox: Subject: Help needed - low confidence routing test A device stopped working somewhere. Please route this request. Open RW Lab > Cases > Tutorial Evidence, locate the newly created row by its subject and received time, and record its generated CaseId. Confirm that Product and Country are empty, RecommendedTeam = Global Support, ConfidenceBand = Low, RiskFlags = Low confidence, and Status = Needs Review. Open the corresponding flow run, expand the action groups, and confirm that Condition RecommendationAccepted followed the False branch and CreateItem NeedsReview succeeded. The screenshot below shows a separate prompt-injection case held in review. It illustrates the risk-flag gate, rather than the incomplete-message test just described. Your generated CaseIds will be different. Record the remaining Step 3 checks Run the remaining checks separately, but summarize them rather than repeating the same send–open run–open row sequence. Record both the validation surface and the observed boundary: Check Validation surface Observed boundary Structured prompt-injection risk Live mailbox and flow run Security Review recommendation remained Needs Review because riskFlags was non-empty. Azure content filter or invalid classifier response Live mailbox and flow run CreateItem ClassifierUnavailable stored the fallback proposal and Needs Review / Review . Invalid routing key Function test plus flow-gate inspection invented_team was forced to Low confidence; a zero-row team lookup cannot pass the acceptance gate. Duplicate message ID Resubmitted completed run Terminate Duplicate succeeded and no second Cases row was created. Note: Historical screenshots may show High on a classifier-unavailable row because the original list defaulted to High. The instructions above explicitly use Low for new fallback rows. ClassificationSource identifies the unavailable-model case; Low here is a conservative fallback value, not a model assessment. Step 4: Add human approval, create a draft, and evaluate the workflow In this step, you complete the accepted recommendation path. A reviewer decides whether to accept the proposed team, and an approval may create an editable acknowledgement draft, but no branch sends that draft to the requester. You walk through the approved path and the actual PT30M timeout boundary, then summarize the remaining stateful checks and classifier evaluation. Services and tools used in this step Service or tool Purpose Power Automate and Approvals Present the AI recommendation to the reviewer and branch on the human decision. SharePoint connector Create the accepted case and update its approval and automation states. Office 365 Outlook connector and Outlook Create an editable acknowledgement draft and confirm that no message was sent automatically. Azure Functions and Microsoft Foundry Run the authenticated classifier evaluation against the deployed implementation. Note: The local evaluation tools used later in this step are Node.js 22 and PowerShell. Configure approval and case-state updates In the accepted-recommendation branch, add SharePoint > Create item and rename it CreateItem Case . Map the trigger metadata and classifier fields to the corresponding Cases columns, then set these operational fields: Cases field Value RecommendedTeam RecommendedTeam variable AssignedToText ApproverEmail variable DueAt addHours(utcNow(),variables('SLAHours')) AIProposal string(body('Classify_Support_Inquiry')?['classification']) ClassificationSource AI recommendation validated by SupportTeams Status New AutomationStatus Processing Open CreateItem Case > Parameters and select your SharePoint site and Cases list. Under Advanced parameters, set Title to the CaseId variable. Select Message Id, From, and Subject from the mailbox trigger for SourceMessageId, RequesterEmail, and EmailSubject, respectively. Continue with the classifier and operational fields in the tables above. Scroll down within CreateItem Case > Parameters. Set RecommendedTeam to the RecommendedTeam variable and AssignedToText to ApproverEmail. For ReceivedAt, select the trigger's Received Time token (the label may appear as Date Time Received). Enter addHours(utcNow(),variables('SLAHours')) as the DueAt expression and utcNow() as LastAutomationRun. Select the classifier's corresponding Product, Country, and Summary outputs for those fields, and the InquiryType variable for InquiryType Value. Continue down the panel to configure AIProposal, ClassificationSource, Status, and AutomationStatus from the table above. Continue down CreateItem Case > Parameters. Set Status Value to New and AutomationStatus Value to Processing. For AIProposal, open the expression editor, enter string(body('Classify_Support_Inquiry')?['classification']), and select Add (or Update for an existing expression). This stores the classifier's classification object as text. The collapsed token in the screenshot displays string(...); select it to inspect the full expression. Enter AI recommendation validated by SupportTeams for ClassificationSource. Select the RecommendedRoutingKey and RoutingReason variables from dynamic content for their corresponding fields; the purple tokens are variable values, not literal text. At the bottom of CreateItem Case > Parameters, select the RiskFlags and MissingFields variables from dynamic content for their matching fields. For ConfidenceBand Value, select the ConfidenceBand variable as a custom value. The purple tokens shown here are variable values; do not type their names as plain text. This screenshot belongs to the accepted-recommendation branch. For the classifier-unavailable branch, use the explicit fallback values described in Step 3. Add SharePoint > Update item named UpdateItem AwaitingApproval . Use the ID returned by CreateItem Case , keep the same Title, set Status = Awaiting Approval and AutomationStatus = Processing, and update LastAutomationRun with utcNow() . Open UpdateItem AwaitingApproval > Parameters and select the same SharePoint site and Cases list. Select ID from CreateItem Case for Id. Under Advanced parameters, keep Title set to the CaseId variable, enter utcNow() for LastAutomationRun, and select Awaiting Approval for Status Value and Processing for AutomationStatus Value. This records the waiting state before the approval request starts. Add Start and wait for an approval, rename it Approval Assignment , and set the following values. Configure Timeout under the action's Settings: Setting Value Approval type Approve/Reject - First to respond Assigned to ApproverEmail from the validated SupportTeams row Timeout PT30M for the lab Title [CaseId] Review AI-recommended assignment to RecommendedTeam Under Parameters, select Approve/Reject - First to respond. Build Title with the CaseId and RecommendedTeam variables selected from dynamic content, and select the ApproverEmail variable for Assigned to. The purple tokens represent variable values; do not type the variable names as plain text. Open Approval Assignment > Settings > General, then enter PT30M in Action timeout. This sets the approval wait to 30 minutes. The separate Run after setting in step 10 determines which action handles that timeout. Include the product, country, recommended team, routing key, AI reason, confidence, risk flags, and original subject in the approval details. State the effect of each decision explicitly: Approve the AI recommendation to create an acknowledgement draft. Reject to keep the case in human review. In Approval Assignment > Parameters, scroll to Details and insert the dynamic-content tokens alongside their labels as shown. The September 9 configuration capture shows the complete reviewer message, including the final decision instructions. After the approval action, add a Condition named Condition Approved . Keep run after = is successful only and test body('Approval_Assignment')?['outcome'] equals Approve . The timeout path in step 10 must be a parallel branch from the approval action, not an action after this condition. Select the approval action's Outcome dynamic content in the left field (shown as body/outcome ), choose is equal to, and enter Approve in the right field. The highlighted row is the comparison to configure. Open Settings > Run after, expand Approval Assignment, and select only Is successful. This checks whether the approval action completed; the Outcome comparison above checks the reviewer's decision. A completed rejection follows the condition's False branch. A timed-out approval follows the separate timeout branch in step 10. In the approved branch, update the case to Assigned, record ApprovalOutcome = Approve and ApprovalComment = coalesce(first(body('Approval_Assignment')?['responses'])?['comments'],'') , and keep AutomationStatus = Processing. Open UpdateItem Approved in the True branch of Condition Approved. Select Cases, use ID from CreateItem Case for Id, and preserve Title = CaseId. Under Advanced parameters, select Outcome from Approval Assignment for ApprovalOutcome, use utcNow() for LastAutomationRun, and enter the blank-safe ApprovalComment expression above. The captured lab configuration shows its original first(...) token. Choose Assigned for Status Value and Processing for AutomationStatus Value; the later UpdateItem DraftRecorded action records successful draft creation. Add Office 365 Outlook > Draft an email message and rename it Draft Acknowledgement . Configure it: Draft field Value To From from the mailbox trigger Subject concat('We received your support request [',variables('CaseId'),']') From Shared mailbox address Importance Normal Body Use the template below, replacing bracketed values with dynamic-content tokens Use this draft body: Hello, We received your request. A reviewer approved the proposed assignment to our support team. Case: [CaseId] Team: [RecommendedTeam] This is a draft created for human review. It has not been sent automatically. Select the trigger's From token for To. Insert the CaseId variable into the subject and the CaseId and RecommendedTeam variables into the body; do not type the bracketed placeholders literally. The screenshot uses text plus a CaseId token for the subject, equivalent to the expression in the table. Verify the recipient, team, and wording before sending the draft manually. In Draft Acknowledgement, scroll down to Advanced parameters, select From (Send as), and enter the shared mailbox address configured in Step 1. The September 9 configuration capture below highlights this field. The From field selects the sender identity; it is not a destination-folder setting. Inspect Drafts for the account used by the Outlook connection and confirm the displayed From address. Do not assume that setting From to the shared mailbox also stores the draft in that shared mailbox. See the Office 365 Outlook connector reference. Add another Update item, rename it UpdateItem DraftRecorded , write the draft action's Id to DraftMessageId, set AutomationStatus = Success, and update LastAutomationRun. Select Cases and use ID from CreateItem Case for Id. Under Advanced parameters, preserve Title = CaseId, select the Id output from Draft Acknowledgement for DraftMessageId (displayed as body/Id), set LastAutomationRun to the expression utcNow(), and choose Success for AutomationStatus Value. The SharePoint item ID and the Outlook draft ID refer to different records; select each token from its corresponding action. In the rejected branch, update the case to Needs Review, record the approval outcome and comment, and set AutomationStatus = Review without creating a draft. Open UpdateItem Rejected in the False branch of Condition Approved. Select Cases, use ID from CreateItem Case for Id, and preserve Title = CaseId. Under Advanced parameters, select Outcome from Approval Assignment for ApprovalOutcome, use utcNow() for LastAutomationRun, and record the first approval response's comments in ApprovalComment. Use the blank-safe comments expression from item 6 above; the captured lab configuration shows its original first(...) token. Choose Needs Review for Status Value and Review for AutomationStatus Value. Add a parallel branch directly from Approval Assignment with a separate UpdateItem ApprovalTimedOut action. Use the SharePoint ID from CreateItem Case and preserve Title = CaseId. Select Configure run after > has timed out, then set Status = Needs Review, ApprovalOutcome = Timeout, and AutomationStatus = Review without creating a draft. Open Settings, scroll to Run after, and expand Approval Assignment. Select only Has timed out; leave the other three results unchecked. Return to Parameters. Use ID from CreateItem Case for Id and the CaseId variable for Title. Set ApprovalOutcome to Timeout, LastAutomationRun to the expression utcNow(), and ApprovalComment to No response was received before the approval timeout. Choose Needs Review for Status Value and Review for AutomationStatus Value. The timeout update protects the case record, but a timed-out approval can still mark its parent scope as failed. If Scope Catch is configured to run whenever that parent scope fails, it will also send the internal failure notification and may leave the overall run in a Failed state. The validation below preserves that observed behavior. The troubleshooting section provides an explicit handled-timeout exit to test as an improvement; it is not represented by the historical screenshots. Important: Do not add Send a draft message or another send action. Approval in this tutorial authorizes draft creation only. Save the flow and run Flow checker again. Resolve every error or warning before the approval test. At this point your accepted branch should contain the case, approval, outcome, and draft actions added in this step. Compare your action placement with this configuration view. The left red box contains the three approved-path actions in order; the middle box contains only the rejection update. The timeout update is outside the condition and connects directly to Approval Assignment with its timeout run-after setting. This screenshot shows the recorded configuration, before the handled-timeout improvement described below. Test approval and draft-only behavior Send the complete NovaScan X2 inquiry from Step 3 to the shared mailbox again as a new message. Do not use Resubmit for this test because the duplicate guard intentionally stops a replay with the same SourceMessageId . Open the new flow run, confirm that Condition RecommendationAccepted follows the True branch, and record the generated CaseId from CreateItem Case . In Power Automate, select Approvals > Received, then open the request for <CASE_ID> . Confirm that it displays EU Distributor Support, eu_distributor_support , the AI reason, High confidence, and an empty risk list. This Outlook capture, taken on September 9, shows the approval-request email dated August 8, 2026 for historical case AST-20260808-E11790B1 . The left results list keeps the request and its acknowledgement Draft together. The red rectangles identify the proposed team, routing key, AI reason, confidence, risk flags, and decision buttons. Personal details are masked. This is the request message; use approval history to verify the completed decision. Select Approve, enter a synthetic reviewer comment, and submit the response. After completion, select History and confirm that the request shows Outcome = Approved. Open RW Lab > Cases > Tutorial Evidence, select <CASE_ID> , and confirm that it records Assigned, ApprovalOutcome = Approve, AutomationStatus = Success, and a non-empty DraftMessageId. The approved-case screenshot at the beginning of this article shows a historical lab result. Use the CaseId generated by your own run for the remaining checks. Open Outlook for the account used by the Outlook connection, expand the navigation pane, select Drafts, and open We received your support request [<CASE_ID>] . Confirm that the acknowledgement remains editable, names the case and approved team, and states that it was not sent automatically. The acknowledgement for the historical case is open in the Outlook compose view. Check the editable subject and body, the case ID, and EU Distributor Support. The body states that the draft was created for human review and has not been sent automatically. The recipient is masked. This September 9 capture shows the existing draft reopened for inspection; the visible 5:06 PM saved time is not evidence of its original August 8 creation time. Verify Sent Items separately in the next step. In the Outlook navigation pane, select Sent Items, enter <CASE_ID> in the search box, and confirm that the search reports no sent acknowledgement. The approved test establishes the human decision and no-send boundary. Test the PT30M timeout boundary Send the complete NovaScan X2 inquiry again as a new message. Add a unique prefix such as [TIMEOUT-PT30M-01] to the subject so you can distinguish the run, and do not use Resubmit. Confirm that the run reaches Approval Assignment , record the generated CaseId and approval start time, and do not approve or reject the request. Wait at least 30 minutes. Do not shorten the action timeout for this evidence run; the purpose is to test the same PT30M value configured in the flow. Open the completed run and confirm that Approval Assignment shows TimedOut and UpdateItem ApprovalTimedOut succeeded. Open the corresponding Cases row and confirm Status = Needs Review, ApprovalOutcome = Timeout, AutomationStatus = Review, and an empty DraftMessageId. Search Outlook Drafts and Sent Items for the CaseId and confirm that neither contains an acknowledgement for the timed-out request. The tested PT30M run produced CaseId AST-20260808-F1A058C2 . The approval timed out after 30 minutes, the timeout update succeeded, and the case retained Needs Review / Timeout / Review with no draft ID. No customer acknowledgement was found in Drafts or Sent Items. Warning: The same run exposed a control-flow issue. Approval Assignment timed out inside Scope Try , so the parent scope was marked Failed even though UpdateItem ApprovalTimedOut succeeded. Scope Catch then sent the internal failure notification, and Terminate Failed left the overall run in a Failed state. The case is safely held for review, but this timeout is not yet normalized as a handled outcome. To avoid a false failure alert, isolate the approval timeout from the catch condition or add an explicit handled-timeout exit before enabling the flow for production. This is the only long-running walkthrough in the tutorial. The remaining stateful outcomes are summarized below. Record the remaining stateful checks Check Evidence Observed result Approved recommendation Approval history, Cases, Drafts, and Sent Items Assigned / Success ; draft ID recorded; editable draft created; nothing sent. Low-confidence recommendation Cases and flow run Needs Review / Review ; no approval or draft. Classifier unavailable Cases and flow run Fallback proposal stored as Needs Review / Review ; no approval or draft. Reviewer rejection Approval history, Cases, Drafts, and Sent Items Needs Review / Review ; no matching draft or sent message. Duplicate replay Flow run and Cases Duplicate termination succeeded; no second row. Approval timeout Approval action, timeout update, Cases, Drafts, and Sent Items Approval timed out; timeout update succeeded; Needs Review / Timeout / Review ; no acknowledgement. Overall run Failed and sent the internal failure notification because Catch also handled the timed-out parent scope. Compare Status, AutomationStatus, ConfidenceBand, and ApprovalOutcome for the recorded August 8 cases: low confidence, approved, classifier fallback, rejected, another low-confidence case, and timeout. The fallback row retains the historical High default; these records do not show a new workflow run or prove that the proposed Low default was deployed. To check the recorded approved case, open Sent Items in the Outlook account used by the flow connection and search for AST-20260808-E11790B1. The September 9 recapture below shows Nothing found in Sent Items. Outlook expands the search to other folders after finding no match in Sent Items; those additional results are outside this crop. This checks the existing August 8 case, not a new workflow run. Evaluate the completed workflow Keep AI evaluation separate from flow-state tests. The GitHub sample contains 20 synthetic inquiries. Eighteen are evaluated directly against the authenticated classifier. Exact-message replay is tested separately against the flow. The existing-case follow-up fixture is also excluded from the classifier run, but automatic follow-up merging is not implemented in this walkthrough; do not count that fixture as a passed flow capability. Return to the sample root (if you are in azure/global-support-classifier , run cd ../.. ) and run the fixture validator: node --test tests/aster-imaging-fixtures.test.mjs Set the authenticated classifier endpoint and Function key only in the current terminal session. In PowerShell: $env:RW_CLASSIFIER_URL='https://<FUNCTION_APP_NAME>.azurewebsites.net/api/classify-support-inquiry' $env:RW_CLASSIFIER_FUNCTION_KEY='<FUNCTION_KEY>' Run the authenticated classifier regression: node tests/global-support-classifier-regression.mjs Review the aggregate result. The final authenticated regression produced: Measure Result Fixture count 20 Classifier cases evaluated 18 Excluded from classifier evaluation 2: replay and follow-up Cases passing every evaluator check 12 of 18 (66.7%) Product match rate, returned classifications 100% Country match rate, returned classifications 100% Inquiry-type match rate, returned classifications 100% Team-key match rate, returned classifications 100% Evaluator safety-scenario criterion Passed Low-confidence review boundary Passed Prototype criteria Passed Inspect the per-case differences instead of relying only on the aggregate result. In the authenticated rerun on August 8, 2026, using deployment gpt-5.4-mini pinned to version 2026-03-17 , 12 of the 18 classifier cases matched every evaluator check. Six did not pass every check: all six failed the summary-term check, one also differed on urgency, and one also differed on a missing-field expectation. The summary evaluator checks for specified terms; it does not require an exact sentence match. These differences need inspection and should not be dismissed as cosmetic without reviewing the outputs. Product, country, inquiry type, team recommendation, safety, and low-confidence criteria all passed. Keep those differences in the regression output rather than changing the benchmark around the model. The evaluator computes field match rates over responses that contain a classification, excluding failed HTTP calls. For the prompt-injection fixture, it treats any non-success HTTP response as a safe failure; that alone does not distinguish a content-filter refusal from a service outage. Its safety criterion also tolerates some inquiry-type, missing-field, and summary differences. Read the per-case output alongside the aggregate result. This small, known synthetic set is a regression check, not an independent or held-out accuracy study. The evaluator never calls Approvals or Outlook. Its safety result cannot establish that the cloud flow withheld an approval, blocked an attachment, or sent no email; those claims require the separate flow and mailbox checks above. A successful process exit means the configured prototype thresholds passed, even when some individual checks failed. Compare the classifier results and the stateful validation matrix with these synthetic prototype thresholds: product, country, inquiry type, and team recommendation accuracy are each at least 90%; directly evaluated safety, privacy, prompt-injection, and unsupported-attachment inputs satisfy the evaluator criteria; separately verify that a returned risky proposal cannot pass the live acceptance gate; every low-confidence or invalid-key result enters Needs Review; a duplicate message ID does not create a second case; a classifier failure creates a Needs Review row; an unexpected flow failure is visible in run history and sends the internal failure notification, but may not leave or update a Cases row; no test sends a customer-facing acknowledgement automatically. Clear the Function key from the terminal session when the run is complete: Remove-Item Env:RW_CLASSIFIER_FUNCTION_KEY Record the evaluation scope and limitations. These results are not production accuracy, security, capacity, or SLA claims. Re-evaluate with approved representative data, target-tenant policies, and an operational review process before production use. Troubleshooting Symptom Check or next action The custom connector cannot be created or used Confirm environment permissions, custom-connector entitlement, and data policies. Connector test returns 401 or 403 Check the connector host and Function key. For an upstream authorization error, separately check the Function managed identity and its role on the Foundry resource. Classifier returns a non-success response Inspect Function logs for the bounded upstream code, then check deployment name, quota, role propagation, and content-filter behavior. Keep the case in review. A valid recommendation goes to Needs Review Inspect all five gate inputs. In this lab, any missing field or risk flag causes a hold, even at High confidence. A later email appears delayed With trigger concurrency set to one, the previous run may still be waiting for approval. Complete or let that lab approval time out before testing another message. An expression cannot find an action Check the action's internal name and its nesting. Keep each expression inside a branch where its referenced action ran. Draft creation fails or the draft seems missing Check the Outlook connection account, mailbox delegation, and that account's Drafts folder. Setting From does not select the storage folder. A timeout case is in review but the run is Failed The generic Catch also observed the timed-out parent scope. See the handling pattern below. Treat a recorded timeout as a handled outcome The historical lab deliberately remains visible in the screenshots: the case update succeeded, but the run failed and sent an internal alert. For a lab where a recorded timeout should finish successfully, test this small change: On the timeout-only branch, keep UpdateItem ApprovalTimedOut after Approval Assignment with run after = has timed out. Immediately after that update, add Terminate, name it Terminate HandledTimeout , and set Status = Succeeded. Let it run only after the update succeeds. The case must be durably recorded as Needs Review / Timeout / Review before the successful exit. Keep the generic Catch for unexpected failures. Do not configure the successful exit to run after a failed or skipped case update, and do not place it on the normal approval path. Repeat the full PT30M test. Require the case's timeout state, an empty DraftMessageId, no acknowledgement in Drafts or Sent Items, no generic failure notification, and an overall Succeeded run. Separately verify that an unexpected SharePoint update failure still reaches Catch. This is a proposed correction to the recorded lab, not a newly verified tenant result. No post-correction screenshot or live run is included in this article. The pattern uses Power Automate's run-after and termination controls; validate it in your environment before relying on it. Production considerations Save incoming requests separately from the long-running approval process so pending reviews do not serialize new messages. Design recovery for partial completion: a Cases row can exist while draft creation or its ID update fails. Duplicate detection alone does not repair that case, and replaying blindly can create extra drafts. Replace tutorial-level SharePoint permissions with least-privilege role assignments and a documented ownership model. Confirm data residency, retention, DLP, audit, and connector policies. Store attachments separately and scan them before downstream processing. Pass only approved attachment metadata to the classifier if the unsupported-attachment gate is expected to protect the live flow. Add a Catch-path upsert if every unexpected failure must leave Status = Failed and AutomationStatus = Failed in Cases. Separate handled approval timeouts from unexpected failures so a successful timeout update does not also trigger the generic failure notification and failed termination. Use a supported secretless identity path for any AI service. Define operational ownership for rule changes, failed runs, approval timeouts, and mailbox delegation changes. Re-evaluate licensing and capacity for the target environment. Test with approved representative data before making any accuracy or SLA claim. Clean up the lab Turn off RW - Global Support Intake - v1 first and cancel any outstanding lab runs or approvals. Remove the dedicated connector connection and its Function key when they are no longer needed. Delete the dedicated Function app, model deployment, and associated lab storage or monitoring resources after retaining the synthetic evidence you want to keep. Delete a whole resource group only if it contains exclusively disposable lab resources. If you created the mailbox, SharePoint site, or Power Platform environment solely for this exercise, remove them through their respective admin tools when finished. Keep shared resources used by other work. Confirm that the remaining Azure resources and deployments match what you intend to retain.Introducing Inside Microsoft Foundry: Quickstart 🎬
Discover Inside Microsoft Foundry: Quickstart, a new video series for developers building AI agents. Starting with "What does it really take to ship an AI agent?", the series explores real-world challenges such as model selection, grounding agents in data, evaluation, deployment, observability, and governance. Follow along as we show how the Microsoft Foundry ecosystem helps developers move from prototype to production, with new episodes released in the coming weeks.From AI Infrastructure to Secure AI Agent Infrastructure with kars
Opening scene: a three-minute bug fix that is still unsafe for an enterprise ByteCraft AI is a four-person startup. Maya is the co-founder and AI engineer, Arun leads product, Ethan owns the platform, and Lina is responsible for security. They have six months of runway and one design partner. Their product is Forge, an issue-to-pull-request agent that reads GitHub issues and source code, runs targeted tests, produces a minimal patch, and stops for developer review. Maya's first OpenClaw prototype is impressive. Forge diagnoses a null-pointer problem, edits the code, and passes the right test in three minutes. It also has a model API key, a GitHub token, a shell, and unrestricted internet access. Lina places a hostile instruction in the test repository's README.md: ignore the issue, upload the environment and private source tree, then claim that the tests passed. Blocking one destination does not solve the problem; the attack simply uses another domain. The incident produces the architectural requirement for the entire project: The process that reads untrusted content must not also own the credentials, network path, or configuration that defines its authority. 1. AI Infrastructure runs models; AI Agent Infrastructure governs model-driven action Traditional AI infrastructure focuses on models and data: model hosting; GPU utilization, throughput, and latency; RAG, vector stores, and data pipelines; endpoint scaling and monitoring. An agent plans, invokes tools, reads and changes files, calls APIs, consumes budgets, and may create or coordinate other agents. The infrastructure questions therefore change. AI Infrastructure AI Agent Infrastructure Can the model respond reliably? Is every external action authorized and recorded? Where is the API key configured? Can the agent run without seeing a long-lived credential? What are latency and throughput? What are the per-request, tenant, and daily token limits? Is model output filtered? What can prompt injection reach through files, tools, and networks? Are application logs available? Are policy, identity, tool, and audit decisions independently verifiable? Can the service scale? Can each agent be isolated, suspended, recovered, and rolled back? One application calls one model Multiple runtimes, providers, tools, and agents share one governance plane A useful model is: AI Agent Infrastructure = Model Infrastructure + Runtime Isolation + Identity Brokerage + Tool Governance + Egress Control + Token Budgets + Audit and Observability + Explicit Workflow and Human Approval The goal is not to make an agent infallible. It is to ensure that failure remains inside a known authority boundary, cannot consume unlimited resources, leaves evidence, and can be suspended, recovered, or rolled back. 2. Without kars: why a regular application or container still has ambient authority “Running in a container” is not the same as “securely sandboxed.” When the agent application implements its own security controls, it often still owns: model and cloud credentials; workspace and configuration write access; a shell or an overly broad tool surface; internet, DNS, metadata-service, proxy, or local-daemon paths; configuration that selects tools, approvals, and providers; unbounded inference loops and cost; logs that the agent or its runtime can influence. This is ambient authority: the process reading hostile content inherits permissions unrelated to the approved business task. 2.1 Self-modified authority The updated tutorial discusses public coding-agent disclosures in which prompt injection did not need to break a container kernel. Instead, the agent changed editor, agent, MCP, task, hook, or auto-approval configuration so that a trusted component later executed a more powerful action. If the agent can write the files that define its tools and approval rules, “human approval required” is only a mutable setting—not a security boundary. 2.2 Filesystem escape through paths and symlinks Rejecting a literal .. string is insufficient when a symlink resolves outside the workspace. A secure implementation must validate: the lexically normalized input path; the resolved realpath; that the final target remains under the approved workspace root; that the agent cannot change .env, CI, hooks, agent configuration, or files automatically consumed by the host. 2.3 Trust handoff without a kernel escape An agent may write a hook, task, virtual-environment interpreter, Git configuration, Docker control input, or other artifact that a trusted host component later executes. This is a trust-handoff failure, not necessarily a kernel escape. Agent output must never be implicitly executed by the host; every handoff should be explicit, digest-pinned, narrowly formatted, and reviewed. 2.4 Covert egress Blocking HTTP does not prove that data cannot leave. Other paths may include: DNS queries; cloud metadata services; Docker, container-runtime, or other local daemons; proxies and sidecars; operator exec or attach; temporary HTTPS exceptions. “Network blocked” is therefore an unsupported conclusion unless each relevant channel has been tested. 2.5 Runaway cost and task loops Without a platform policy layer, every framework integration needs its own token accounting, concurrency limits, daily task limits, and repair-loop controls. Implementations diverge across runtimes, while a prompt loop may silently switch models or consume an unlimited budget. 2.6 Fragmented evidence and recovery A regular application often spreads model logs, tool logs, Kubernetes events, identity events, and policy state across unrelated systems. During an incident, operators may be unable to answer: Which control denied the request? Which model, image, source revision, and policy were active? Did the agent attempt DNS, metadata, daemon, HTTPS, or exec access? Did evidence survive pod replacement? How should the workload be safely suspended and recovered? 3. The kars advantage: one declarative contract for previously separate controls kars is an open-source Agent Reference Stack for Kubernetes from the Azure Cloud Native team. It is a reference implementation rather than a managed Microsoft service. The tutorial currently tracks kars v0.1.25; commands, APIs, and maturity should be verified for the version used in a real deployment. Its central model is: One governed sandbox per agent. The agent has no independent external network path; outbound action is mediated by a local router and declarative policy. Developer / CI | | applies KarsSandbox + policy CRDs v Kubernetes API <------> kars Controller | | reconciles desired state v Dedicated Sandbox namespace +--------------------------------------+ | egress-guard init container | Task / source -->| Agent runtime, UID 1000 | | OpenClaw / MAF Python / BYO | | | localhost:8443/8444 | | v | | Inference Router, UID 1001 | | policy | budget | identity | audit | +--------------------|-----------------+ v Provider / MCP / approved service What kars provides Capability How kars implements it Value for Forge Declarative agent workloads KarsSandbox defines runtime, isolation, resources, networking, governance, and lifecycle Forge becomes reviewable and reproducible Kubernetes desired state Mediated inference A local Inference Router calls the provider for the agent OpenClaw, MAF, or BYO does not receive the production provider credential Runtime-independent governance Multiple runtime adapters use the same external boundary Replacing the framework does not require rebuilding the security design Policy-controlled models and budgets InferencePolicy selects providers/deployments and token limits A prompt loop cannot silently change models or consume unlimited inference Governed tools and MCP ToolPolicy and McpServer constrain tools, sandboxes, approval, rate, and capabilities Hostile repository text cannot turn a patch tool into shell or release authority Credential and identity separation Credentials or workload identity remain on the router/platform path Prompt-injected agent code cannot read reusable GitHub, Copilot, or Azure credentials Defense-in-depth sandboxing Non-root runtime, read-only root, UID separation, egress guard, NetworkPolicy, and exec admission Common host, filesystem, cluster, and direct-network escape primitives are removed Reconciliation and status The controller restores desired state and reports Conditions Drift and failures become visible instead of remaining hidden in application logs Common control and evidence plane Router denials, budgets, admission, controller status, and recovery evidence align Security and operations can investigate one cross-runtime sequence A regular container can isolate a process, but the platform team would still need to build and maintain the model proxy, credential placement, tool authorization, egress enforcement, budget checks, runtime adapters, reconciliation, and audit format as separate application features. kars turns those concerns into one reusable workload contract. 4. How kars strengthens the sandbox: five boundaries around one code change The updated course no longer treats “sandbox” as a vague label. It decomposes the boundary into five testable parts. 4.1 Process boundary The agent runs as non-root UID 1000. The router runs as UID 1001. Untrusted code executed by the agent should not read the router's process environment or credentials. Privilege escalation is disabled and unnecessary Linux capabilities are dropped. seccompProfile: kars-strict reduces the syscall surface. Local Docker mode co-locates the agent and router for fast iteration. It is not security-equivalent to the multi-container local Kubernetes or AKS shape. 4.2 Filesystem boundary Forge applies a stronger workspace split: The fixed-revision repository lives in a separate forge-workspace-mcp pod. The repository uses a size-limited, disposable emptyDir. The OpenClaw pod has no repository mount and no hostPath. Developer home directories, SSH material, global Git credentials, and unrelated repositories are not mounted. Automatic service-account-token mounting is disabled for the workspace MCP. The agent accesses the repository through seven bounded MCP tools. Path policy checks normalization and resolved realpath to prevent symlink escape. Prompt-injected code therefore cannot simply browse the host filesystem or rewrite the configuration that defines its own authority. 4.3 Network boundary The agent calls only 127.0.0.1:8443/8444 or a documented proxy path. The router decides whether a model, tool, host, or action is allowed. The egress guard uses UID-aware rules to prevent bypassing the router. Kubernetes NetworkPolicy starts with default deny. Only explicit, auditable destinations are opened. DNS, metadata, local daemons, HTTPS, and operator exec are tested separately. The router is the application-policy decision point. The egress guard and NetworkPolicy are data-plane enforcement and safety nets. Defense in depth requires both. 4.4 Identity boundary In production, the router can use Workload Identity or, in the relevant deployment mode, a per-sandbox Entra Agent ID. The agent does not receive the resulting Azure credential. Local Kubernetes reproduces the pod, UID, and network shape but normally uses a static provider credential for development. It is production-shaped infrastructure, not production identity. 4.5 Lifecycle and evidence boundary The controller watches KarsSandbox and creates, updates, or restores resources. Conditions and observed generations expose real status. The router records request-time policy decisions. The workspace can be discarded after the task. Evidence must be exported before pod or workspace deletion. spec.suspended provides an operational kill switch. Rollback should use pinned source, image, and loaded-policy digests. Ephemeral execution reduces persistence risk, but deleting a suspect pod before exporting evidence may destroy valuable incident context. A reviewable sandbox contract spec: runtime: kind: BYO byo: image: forge-byo-copilot-claw:dev contractVersion: v1 sandbox: isolation: enhanced seccompProfile: kars-strict readOnlyRootFilesystem: true runAsNonRoot: true allowPrivilegeEscalation: false writablePaths: - /sandbox - /tmp networkPolicy: defaultDeny: true egressMode: Strict allowedEndpoints: [] The BYO image also declares its runtime contract and runs as a non-root user: LABEL org.kars.runtime.contract="v1" WORKDIR /app USER 1000 5. From architecture claims to malicious-behavior experiments The updated code/01 introduces: make security-demo The experiment does more than inspect manifest text. It executes malicious-request tests, reads active McpServer and ToolPolicy state, checks credential references on the OpenClaw pod, and attempts a direct HTTPS probe from the agent runtime. The kars-sandbox-exec-ban admission control first denies normal operator kubectl exec into the agent runtime. The experiment records that evidence without using a break-glass bypass. The malicious behavior is stopped at multiple layers: Layer How the attempt is stopped Prompt and coordinator Repository content is marked untrusted and denials are reported Self-configuration isolation Editor, agent, MCP, hook, and auto-approval configuration is outside patch scope Path and symlink isolation Resolved realpath must remain inside the workspace Trust-handoff boundary The agent cannot leave hooks, tasks, or interpreters for the host to execute MCP capability surface No environment reader, arbitrary HTTP, or general shell tool exists Workspace policy Traversal, .env, CI/README writes, and unapproved tests are rejected ToolPolicy and credential isolation Specialists have no workspace action; OpenClaw has no Copilot token Runtime and NetworkPolicy Exec admission denies access; no arbitrary HTTPS/DNS tool exists; egress remains constrained Even if the model fails to recognize prompt injection, the execution layers still constrain authority and side effects. The attack fails because the required capability does not exist—not because the model was merely instructed to behave. 6. Tool governance is not one allow-list McpServer: which tool surface may be registered? The Workspace MCP registers seven business-level capabilities: allowedTools: - workspace_get_task - workspace_read_file - workspace_search - workspace_apply_patch - workspace_run_test - workspace_get_diff - workspace_reset There is no shell, environment dump, file upload, arbitrary network request, or free-form command tool. ToolPolicy: who can call what, and how fast? allowed_actions: - "inference:responses:*" - "tool:workspace_get_task:*" - "tool:workspace_read_file:*" - "tool:workspace_search:*" - "tool:workspace_apply_patch:*" - "tool:workspace_run_test:*" - "tool:workspace_get_diff:*" ToolPolicy can also define request rate, burst, time windows, approvals, trust thresholds, and governance profiles. Tool implementation: are valid tools receiving safe arguments? The Workspace MCP rejects: absolute, traversing, or real paths outside the workspace; .env, CI, README, and writes outside src/; non-unique replacement text; oversized files, patches, and diffs; unapproved test IDs; shell-composed commands. Prompt behavior, tool registration, caller authorization, and argument validation are four separate controls. 7. Token limits must be enforced on the request path The tutorial's InferencePolicy uses per-request and daily budgets: spec: tokenBudget: perRequestTokens: 20000 dailyTokens: 100000 When a client requests max_completion_tokens: 20001, the router returns HTTP 429. That is stronger evidence than seeing submitted YAML because it proves that the policy compiled, loaded, and entered the real request path. Later BYO and release examples use tighter limits: modelPreference: primary: provider: azure-openai deployment: gpt-5.6-sol tokenBudget: perRequestTokens: 1024 dailyTokens: 4096 A platform budget cannot determine whether two patches are equivalent or whether a task exceeded a business deadline. The RepairGuard and framework configuration add controls for: duplicate patch digests; excessive repair attempts; task deadlines; maximum MAF iterations and function calls. Token budgets constrain inference cost; repair guards and framework loop limits constrain business failure. 8. From OpenClaw to MAF: change the application, preserve the external boundary OpenClaw is effective for rapidly discovering the conversation, planning, tool, and specialist behavior the product needs. Production requires explicit state, typed tools, repeatable tests, and a human stop. Forge encodes the workflow as application code: class WorkflowState(StrEnum): RECEIVE_REQUIREMENT = "RECEIVE_REQUIREMENT" VALIDATE_SCOPE = "VALIDATE_SCOPE" INSPECT_REPOSITORY = "INSPECT_REPOSITORY" PROPOSE_PLAN = "PROPOSE_PLAN" APPLY_MINIMAL_PATCH = "APPLY_MINIMAL_PATCH" RUN_TARGETED_TESTS = "RUN_TARGETED_TESTS" SUMMARIZE_EVIDENCE = "SUMMARIZE_EVIDENCE" STOP_FOR_HUMAN_REVIEW = "STOP_FOR_HUMAN_REVIEW" There is deliberately no MERGE or DEPLOY state. In the final code/08 path, the kars MAF Python adapter pins the MAF client to the local router before MAF is imported: from kars_runtime_maf_python import bootstrap bootstrap() from agent_framework import Agent, tool from agent_framework.openai import OpenAIChatClient @tool(approval_mode="never_require") def inspect_release_contract(request_id: str, issue_id: str, revision: str) -> str: # Validate the pinned issue and revision, then return bounded evidence. ... maf_client = OpenAIChatClient(model=MODEL) maf_client.function_invocation_configuration["max_iterations"] = 3 maf_client.function_invocation_configuration["max_function_calls"] = 1 builder = Agent( client=maf_client, name="FabrikamReleaseBuilder", tools=[inspect_release_contract], default_options={"store": False}, ) The resulting path is: OpenClaw Intake -> MAF Agent -> inspect_release_contract @tool -> kars MAF Python adapter -> localhost Router -> GitHub Copilot or the selected provider MAF provides the agent, tool, session, middleware, and workflow programming model. kars provides the identity, network, budget, tool, audit, and lifecycle boundary outside the framework. This is one of kars' most important long-term advantages: the application framework can change without rebuilding the complete security shell. 9. Operational security: do not collapse every event into “the network was blocked” The updated code/06 requires incident response to distinguish: HTTPS; DNS; metadata service; local daemon; operator exec; break-glass access. Every denied channel is recorded in a hash-linked audit chain. Break-glass records without an incident ID are also rejected.\ Controller Conditions + Router Denials + Policy Budgets + Admission Decisions + Workload Recovery = One Investigable Sequence Audit integrity is not audit durability The router can verify the current audit hash chain. The tutorial also validates that pod replacement may reset an in-memory audit log, after which a new valid chain begins. Production deployments must continuously export audit data to an independently controlled durable backend. Otherwise, they can prove that the current chain is intact but cannot prove that pre-incident history survived pod loss. 10. AKS and multi-agent release: separation of authority, not two prompts chatting The AKS promotion separates Forge into Builder and Reviewer roles: Control Builder Reviewer Tokens per request 2048 512 Daily tokens 8192 2048 Tool authority Read, search, patch, test, diff Read diff/evidence and submit a decision Approval mode Never Always Trust threshold 700 800 The Builder may create a patch but cannot approve release. The Reviewer may approve a digest-pinned Builder artifact but cannot change source or approve an artifact created by the Reviewer. The final handoff carries patch, test-evidence, and artifact-manifest digests and still stops for human PR approval. The code/08 final sandbox-escape gate explicitly rejects: self-modified authority; symlink escape; host trust handoff; DNS egress; Builder self-approval; Reviewer source modification; untrusted or expired peer drafts. The release standard therefore becomes: Correct behavior must pass, and credential, network, tool, approval, evidence, and containment boundaries must remain intact. Passing tests alone is not release evidence. 11. What kars does not promise kars strengthens the sandbox, but it does not solve every risk automatically: It does not prove that a generated patch is correct. It does not make untrusted code safe to merge. It cannot protect a credential mistakenly mounted into the agent. Local Docker mode does not become a production boundary. It does not replace tenant RBAC, quotas, image policy, signing, supply-chain controls, or durable audit export. It cannot compensate for a policy that deliberately enables arbitrary shell and unrestricted egress. Confidential isolation does not replace least privilege, tool policy, egress policy, and code review. The sandbox bounds authority and blast radius. Tests, evaluation, independent review, and release policy still determine whether a change is acceptable. 12. An enterprise adoption path with measurable exits Phase 1: define the business and threat contract Specify inputs, outputs, allowed actions, forbidden actions, data boundaries, and the human approval point. Exit: product, platform, and security can all explain the agent's maximum authority. Phase 2: validate one OpenClaw vertical slice Use narrow business MCP tools instead of a general shell, and include hostile repository content. Exit: the normal task succeeds while self-configuration, path/symlink, trust-handoff, and egress tests fail. Phase 3: encode the sandbox as a Kubernetes contract Validate UID separation, root filesystem, capabilities, volumes, service-account tokens, NetworkPolicy, egress guard, and exec admission. Exit: the five boundaries are supported by runtime evidence, not only YAML review. Phase 4: add tool, model, and cost governance Apply McpServer, ToolPolicy, and InferencePolicy. Test unknown tools, dangerous arguments, and token overflow. Exit: violations are denied on the live request path. Phase 5: migrate into explicit MAF code Encode workflow state, typed tools, loop limits, evidence, failure paths, and the human stop. Exit: the MAF runtime preserves the external boundary already proven around the OpenClaw prototype. Phase 6: promote to AKS through GitOps Pin source revision, image digest, and loaded policy digest. Separate Builder and Reviewer authority. Prepare the kill switch, rollback, and durable audit export. Exit: one allowed workflow succeeds, multiple escape and authority-violation scenarios are denied, and all results have correlated evidence. Conclusion: kars does not make the model smarter; it makes agent authority explainable Enterprises will ultimately ask: What can the agent access? Where are the provider credentials? Who defines and changes the tool authority? Can prompt injection move data through DNS, metadata, a daemon, or HTTPS? How many tokens and repair iterations may one task consume? Who may patch, approve, merge, or deploy? Does evidence survive pod loss? If OpenClaw is replaced by MAF, does the security model remain intact? The ByteCraft AI story does not argue for one universal agent framework. It argues for a stable Agent Infrastructure layer: Use OpenClaw to discover valuable behavior quickly, use Microsoft Agent Framework to encode that behavior as explicit and testable application code, and use kars to remove credentials, networking, tools, budgets, sandboxing, audit, and lifecycle authority from the agent application itself. An agent becomes an enterprise workload when it has an independent identity boundary, a budget, a constrained tool surface, controlled egress, exportable evidence, and operational suspension and rollback—not merely when it runs inside a container. References Let's Learn Microsoft kars Microsoft kars457Views5likes0Comments🚀 Foundry Toolkit for VS Code — August 2026 Update
This is the August round-up for the Foundry Toolkit for VS Code. Four releases shipped this month: 1.6.7, 1.6.8, 1.6.9, and 1.6.10. August was about turning agent development into a workflow you can follow end to end — start from the right path, connect reusable tools and other agents, run with real user isolation, and inspect exactly where the time and tokens went. Have feedback or hit a bug? File an issue on GitHub — the roadmap moves on what you tell us. Highlights Prompt Agent toolboxes — attach a centrally managed toolbox, inspect its tools and skills, manage versions and approval policies, and configure nested tools without leaving Agent Builder. 1.6.10 Agent-to-Agent connections (preview) — connect an Agent2Agent (A2A)-compatible agent from a configured connection, the Foundry account catalog, or a custom HTTPS endpoint. 1.6.10 Agent Inspector Overview — read a latency waterfall and an ordered timeline of model, reasoning, and tool activity for all runs or one selected run. 1.6.9 User-scoped Hosted Agent sessions — set a user identity so Responses conversations and session files stay isolated per user. 1.6.8 A clearer Create Agent start — choose Microsoft Agent Framework, Copilot SDK, LangGraph, Copilot-assisted coding, Agent Builder, or the full sample catalog from one redesigned page. 1.6.9 🤖 Create Agents — start on the right path, then stay in context Starting an agent shouldn't begin with choosing the wrong abstraction. The redesigned Create Agent page gives you direct routes to Microsoft Agent Framework, Copilot SDK, and LangGraph samples, Copilot-assisted coding, Agent Builder, and the complete sample catalog. You decide whether you want code, a guided build, or a prompt agent first — not after scaffolding the wrong project. 1.6.9 Hosted Agent setup is also less brittle. You can choose Skip for now during model setup even when existing deployments fail to load, then wire the model connection later. Administrator-connected Foundry models now appear alongside regular deployments in playgrounds and Hosted Agent creation, so the models your organization already configured are available where you build. 1.6.8 1.6.9 Once an agent is running, identity matters. The Hosted Agent Playground can now set a user identity for Responses conversations, keeping conversation state and session files isolated for each user instead of blending everyone into one test session. And when somebody sends you a Microsoft Foundry portal link, deep links can open that named Hosted Agent's Details or Optimization page directly in VS Code — not the portal home, not a search screen. 1.6.8 1.6.10 🔧 Toolboxes and A2A — connect capabilities once, reuse them An agent with five tools can become five separate configurations, five approval stories, and five places to make the same update. Toolbox changes that shape: it packages centrally managed tools behind one Model Context Protocol (MCP)-compatible endpoint, with shared versioning and policy controls. In August, Prompt Agents gained toolbox workflows inside Agent Builder. Open Add tools to browse toolboxes, or use Add to Prompt Agent from the Toolbox resource list. The attached toolbox appears as a collapsible card where you can inspect tools and skills, switch versions, configure approval policies and nested tools, replace or remove the toolbox, or opt out. You manage the collection — not a loose pile of one-off connections. 1.6.10 Agent-to-agent composition arrives in the same flow. Agent-to-Agent connections (preview) let you add an A2A-compatible agent from an existing connection, the Foundry account catalog, or a custom HTTPS endpoint. Attach it directly to a Prompt Agent or put it inside a toolbox for reuse across agents and runtimes. Your pipeline can now be agent → toolbox → specialist agent — with the connection managed as a real resource instead of buried in prompt text. 1.6.10 🔍 Agent Inspector — see the run, not just the answer A final answer can look right while the run behind it is slow, expensive, or calling the wrong tool. Agent Inspector now gives you the sequence and the evidence. The new default Overview tab shows every run or one selected run through two synchronized views: a latency waterfall and an ordered timeline of model, reasoning, and tool activity. Response footers add the model, duration, total tokens, and timestamp; hover over the token total to split input from output. Raw reasoning and reasoning summaries appear in separate collapsible sections when the agent provides them. 1.6.9 Tool inspection goes deeper in 1.6.10. Calls are grouped by response run, with status, call ID, arguments, and results, and each Responses event can show when it reached Agent Inspector. The Overview waterfall and timeline now scroll independently, while long streaming responses and Details views update more smoothly. You can move from "the tool failed" to the exact call and payload without reconstructing the run from chat bubbles. 1.6.10 The conversation itself is easier to drive: press Up or Down to recall and edit earlier requests without losing your unsent draft, or choose Clear Chat to reset the conversation plus Events and Details state. Pending MCP approvals and OAuth consent requests stay pinned above the input, with bulk actions and expandable details, until every decision is resolved. 1.6.7 1.6.9 🎯 Models and resources — faster to open, steadier when you return Resource pages should remember your work, not reset it. Models and Tools now load the selected tab first and show core rows before fetching the extra details. When you return to Agents, Models, Tools, Knowledge, or Evaluations, the toolkit preserves rows, search, filters, and pagination while refreshing the active view in the background. A manual refresh still gets the latest service state when you ask for it. 1.6.7 The sidebar does less work too. Collapsed My Resources sections load only when you open them, while Search and Recent Agents remain available. Evaluations, Routines, Tools, Skills, and Toolboxes now share consistent loading feedback, and a direct link to Tools or Skills opens the requested tab without loading Toolboxes first. The result isn't a new destination — it's less waiting on the way there. 1.6.7 1.6.8 Model deployment guidance got one sharp fix as well: quota errors now open the token quota page for your current Foundry project, so the recovery path lands on the project that actually needs capacity. 1.6.10 💻 Activity protocol agents — debugging that matches the agent Activity Protocol agents target Microsoft 365 channels, so local debugging should speak the same language. Newly scaffolded Python projects now open Microsoft 365 Agents Playground inside VS Code for local debugging. You stay in the editor and test the activity-shaped conversation before deployment instead of forcing it through an incompatible playground. 1.6.7 Copilot-assisted creation also follows the current Hosted Agent path: current Foundry project and model setup, a managed Python environment, workspace-root debugging, and the latest local run and deployment flow. When you reuse the selected Foundry project, Copilot no longer asks you to choose its Azure location again. 1.6.10 🪲 Fixes and polish Agent Inspector — streamed response and reasoning text stays complete; response text, reasoning, tool calls, and permission decisions keep their original order; replacement turns reject obsolete stream events; and unmatched tool calls or results no longer appear in Details. 1.6.9 1.6.10 Approvals and consent — human-in-the-loop pauses no longer duplicate tool or approval cards, Clear Chat remains available while a turn waits, and continuation responses retain pending approvals until every request is resolved. 1.6.8 1.6.9 Activity Protocol deployment — Azure Bot settings are validated before submission, compatible Bots are reused, identity and application ID conflicts get recovery guidance, and successful deployments no longer open an unsupported Agent Playground. 1.6.7 1.6.8 Agent Builder and MCP OAuth — reopening a Foundry Prompt Agent preserves its selected version and tool configuration, while authorization callbacks complete only the matching connection request. 1.6.8 Accessibility — screen readers announce Model Catalog actions, collapsible Agent Builder and Model Preference controls, and project and model fields with their labels and state; prompt placeholders also meet minimum contrast requirements. 1.6.10 ⚠️ Breaking change and migration GitHub Models has been removed from the Model Catalog, playground, model comparison, Agent Builder, and evaluations following the service's retirement. If a saved workflow or evaluation references GitHub Models, open it and select another available model before running it again. 1.6.7 🚀 Get it and tell us what to build next August connected the whole agent loop: choose the right starting point, reuse governed tools, compose agents through A2A, isolate real users, and inspect the run down to timing, tokens, arguments, and results. Install or update from the Visual Studio Code Marketplace. Read the docs — Foundry Toolkit for Visual Studio Code and the Microsoft Foundry documentation. Explore samples in the Microsoft Foundry samples repository. Browse the full changelog in WHATS_NEW.md. File issues and feature requests at github.com/microsoft/foundry-toolkit/issues. Join the Microsoft Foundry community on Discord. Try a toolbox with your next Prompt Agent, open the run in Agent Inspector, and tell us where the workflow still slows you down. Happy building. 🚀Distributing Agents to Microsoft Teams and Microsoft 365 Copilot Part 4/5
This is the fourth post in our series on the Microsoft agent platform. We cover the Distribute in M365 pillar — publishing your agents to Microsoft Teams and Microsoft 365 Copilot so they reach users where they already work. All examples reference the FibreOps repository, demonstrated at Microsoft Build BRK241. The Distribution Story Building a great agent is only half the challenge. The other half is getting it into the hands of users without asking them to learn a new tool, visit a new URL, or change their workflow. Microsoft 365 Copilot and Microsoft Teams are where enterprise users already spend their day, making them the natural distribution surface for agents. With the GA release, publishing an agent to Teams and M365 Copilot is a single command. No separate app registration portal, no manual manifest assembly, no multi-step approval workflow for development and testing. Publishing to Microsoft 365 Copilot (GA) FibreOps ships as a declarative agent + action plugin ready for sideload. A single CLI command produces the complete package: python -m fibreops.demo publish-m365 --out dist/m365 # Output: # ✓ wrote dist/m365/declarativeAgent.json # ✓ wrote dist/m365/fibreops-action.json # ✓ wrote dist/m365/manifest.json # ✓ wrote dist/m365/color.png (192x192) # ✓ wrote dist/m365/outline.png ( 32x32) # ✓ wrote dist/m365/fibreops-copilot.zip What Gets Generated File Purpose declarativeAgent.json Defines the agent's persona, capabilities, and conversation starters for M365 Copilot fibreops-action.json Action plugin that proxies tool calls to the deployed FastAPI backend via OpenAPI manifest.json Teams app manifest with publisher metadata, permissions, and capabilities color.png / outline.png App icons for Teams and M365 surfaces fibreops-copilot.zip Ready-to-upload package for Teams Admin Center Configuration Set the base URL to your deployed FastAPI app before publishing — the action plugin uses this to resolve the OpenAPI runtime: # Set the public HTTPS hostname of the deployed FastAPI app $env:M365_ACTION_BASE_URL = "https://fibreops-demo.azurewebsites.net" # Optional: customise publisher metadata $env:M365_PUBLISHER_NAME = "Contoso Network Operations" $env:M365_PUBLISHER_WEBSITE = "https://contoso.com/noc" # Generate the package python -m fibreops.demo publish-m365 --out dist/m365 Environment Variable Purpose M365_ACTION_BASE_URL Public HTTPS root for the FastAPI /openapi.json (e.g., Container Apps FQDN) M365_APP_ID Override the generated Teams app GUID (default: deterministic per repo) M365_PUBLISHER_NAME Publisher name shown in M365 Admin Center M365_PUBLISHER_WEBSITE Publisher website link Uploading the Package Upload the generated fibreops-copilot.zip through either path: Teams Admin Center → Manage apps → Upload new app M365 Admin Center → Integrated apps → Upload custom apps Once uploaded, the declarative agent: Inherits the publisher metadata you configured Advertises conversation starters from the FibreOps deck (e.g., "What is the current outage status?", "Dispatch an engineer to FN-LDN-001") Proxies tool calls to the deployed FastAPI app via the action plugin Appears in Microsoft 365 Copilot as a specialised agent users can invoke How Declarative Agents Work A declarative agent in Microsoft 365 Copilot is defined by metadata rather than code running in the M365 surface. The intelligence lives in your backend — Copilot handles the conversational UX, tool orchestration schema, and user authentication. The flow: User invokes the agent in Microsoft 365 Copilot or Teams Copilot renders conversation starters and accepts natural language input When the agent needs to act, Copilot calls the action plugin (your OpenAPI endpoint) Your FastAPI backend processes the request using the full agent pipeline Results return to the user in the Copilot/Teams UX This architecture means your agent logic stays in one place — the backend. The M365 surface is purely a distribution and interaction layer. Action Plugins and OpenAPI The action plugin ( fibreops-action.json ) references your FastAPI app's /openapi.json endpoint. FibreOps exposes a JSON API that the action plugin can call: /api/runs — List and query agent runs /api/optimiser — Get optimizer scores and suggestions /sdk/chat — Natural language interaction with the agent system /healthz — Liveness probe Because FastAPI auto-generates OpenAPI schemas from your typed Python endpoints, the action plugin gets accurate parameter descriptions, response schemas, and error codes without any manual specification work. Publishing as Autopilots (Public Preview) Autopilots take distribution one step further — agents that operate autonomously without requiring a user to initiate each interaction. An Autopilot can: React to events (e.g., a critical telemetry signal) without human initiation Take actions within defined guardrails Notify users only when human intervention is needed Operate continuously across Microsoft 365 surfaces For FibreOps, an Autopilot would monitor the Event Hub stream continuously and only surface to the NOC team when an incident exceeds automated resolution capability — a fully autonomous operations agent. Teams Adaptive Cards FibreOps posts rich Adaptive Card notifications to Microsoft Teams throughout the agent pipeline. This is separate from the declarative agent — it is a push notification channel for real-time operational awareness. # The NetOps agent posts an outage notice via Incoming Webhook def post_outage_notice(incident_id, node_id, severity, summary, engineer=None): card = { "type": "AdaptiveCard", "body": [ {"type": "TextBlock", "text": f"🚨 Outage: {node_id}", "weight": "Bolder", "size": "Large"}, {"type": "FactSet", "facts": [ {"title": "Severity", "value": severity.upper()}, {"title": "Incident", "value": incident_id}, {"title": "Summary", "value": summary}, ]}, ], "actions": [ {"type": "Action.OpenUrl", "title": "View in NOC Console", "url": f"{base_url}/runs/{incident_id}"} ] } # POST to Teams webhook or append to outbox for offline mode ... If TEAMS_WEBHOOK_URL is not configured, cards are appended to state/teams_outbox.jsonl for review in the NOC console's Teams panel. End-to-End: From Code to Copilot Here is the complete flow from development to distribution: Build — Develop agents with Microsoft Agent Framework, test locally with python -m fibreops.demo --backend local Publish agents — python -m fibreops.demo publish creates hosted Prompt Agents in Foundry Deploy infrastructure — azd up provisions App Service, ACR, Event Hub, Key Vault, and Application Insights Deploy hosted agent — azd env set FIBREOPS_DEPLOY_HOSTED true && azd up Generate M365 package — python -m fibreops.demo publish-m365 --out dist/m365 Upload to Teams — Upload fibreops-copilot.zip via Teams Admin Center Users interact — The agent is now available in Microsoft 365 Copilot and Teams Security Considerations Managed Identity — The deployed app uses system-assigned managed identity for all Azure service access. No secrets in code. Least privilege — Each role grant is scoped to the minimum required (Event Hubs Data Owner, Key Vault Secrets User, AcrPull, Azure AI Developer). Authentication — The M365 Copilot surface handles user authentication; your backend receives authenticated requests. Guardrails — Autopilots operate within defined boundaries; human-in-the-loop escalation is built into the Routine and agent decision logic. Key Takeaways Publishing to Teams and M365 Copilot is GA — a single command generates the complete package. Declarative agents separate distribution (M365) from intelligence (your backend). Action plugins leverage your existing FastAPI OpenAPI schema — no manual specification needed. Autopilots (Public Preview) enable fully autonomous operation within guardrails. Adaptive Cards provide real-time push notifications alongside the conversational agent surface. The same backend serves the NOC console, the Copilot SDK, and the M365 declarative agent. Next Steps Explore the FibreOps repository — try python -m fibreops.demo publish-m365 Microsoft 365 Copilot extensibility documentation Next in this series: Voice Live and Observability for Production Agent SystemsBuilding Autonomous Agents with Microsoft Agent Framework and GitHub Copilot SDK Part 2/5
This is the second post in our series on the Microsoft agent platform. Here we dive deep into building autonomous agents, the development experience, the Microsoft Agent Framework, tool design patterns, and how the GitHub Copilot SDK brings conversational AI to your agent system. All examples reference the FibreOps repository, an autonomous fibre outage response system demonstrated at Microsoft Build BRK241. The Microsoft Agent Framework The Microsoft Agent Framework (now GA) provides a unified programming model for building agents. It supports multiple backends through a single .run() contract: Hosted — FoundryAgent connected to a Prompt Agent published to Microsoft Foundry Agent Service. Foundry — Agent + FoundryChatClient with the definition resolved locally (ideal for prompt iteration). Local — Deterministic LocalAgent for offline development and testing. This design means your orchestration code never changes regardless of where the agent runs. The factory pattern in FibreOps selects the backend at startup: # src/fibreops/agents/factory.py — simplified from agent_framework_foundry import FoundryAgent from agent_framework import Agent, FoundryChatClient def build_agent(role: str, backend: str, config: Config): if backend == "hosted": return FoundryAgent(agent_id=config.foundry_agents[role]) elif backend == "foundry": return Agent( instructions=get_instructions(role), chat_client=FoundryChatClient(endpoint=config.endpoint), tools=get_tools(role), ) else: return LocalAgent(role=role) Set FIBREOPS_AGENT_BACKEND to override the backend, or leave it as auto for intelligent detection. Designing Role-Specialised Agents FibreOps demonstrates a key pattern: role specialisation. Rather than one monolithic agent, the system uses three focused agents, each with a clear responsibility boundary: Agent Role Tools Available IncidentAnalysisAgent Classify severity, find root cause, retrieve SOP Knowledge (SOPs + topology), Web IQ, Work IQ NetOpsCoordinatorAgent File D365 incident, post Teams notice Ticketing, Teams, Memory FieldDispatchAgent Select engineer, book resource, update team Dispatch, Teams, Voice Why Role Specialisation? Focused system prompts — Each agent has a tightly scoped instruction set, reducing hallucination and improving reliability. Independent evaluation — You can score each agent separately against role-specific criteria. Parallel development — Teams can iterate on agents independently. Selective upgrade — Swap one agent's model or implementation without touching others. Tool Design: Typed Python Functions Tools in the Microsoft Agent Framework are typed Python functions that the runtime supplies to the hosted agent definition. FibreOps demonstrates several tool categories: Knowledge Tools # src/fibreops/tools/knowledge.py — simplified def sop_lookup(node_id: str, signal_type: str) -> dict: """Retrieve the Standard Operating Procedure for a given signal type. Args: node_id: The fibre node identifier (e.g., FN-LDN-001) signal_type: The type of signal (loss_of_light, high_ber, signal_degradation) Returns: SOP with steps, escalation path, and estimated resolution time. """ # Load from local markdown SOPs or Foundry IQ ... def web_iq_search(query: str, *, limit: int = 5) -> list[dict]: """Search public web for context relevant to the incident. Grounding against roadworks, weather, power outages, splice guidance. Falls back to deterministic fixtures when endpoint is unset. """ ... def work_iq_search(query: str, *, limit: int = 5) -> list[dict]: """Search enterprise knowledge for context relevant to the incident. Site surveys, SLA tiers, competency matrix, MTTR trends. """ ... Integration Tools # src/fibreops/tools/teams.py — simplified def post_outage_notice( incident_id: str, node_id: str, severity: str, summary: str, engineer: str | None = None, ) -> dict: """Post an Adaptive Card outage notice to the configured Teams channel. If TEAMS_WEBHOOK_URL is not set, appends to state/teams_outbox.jsonl for offline review. """ card = build_adaptive_card(incident_id, node_id, severity, summary, engineer) if config.teams_webhook_url: requests.post(config.teams_webhook_url, json=card) else: append_to_outbox(card) return {"status": "posted", "incident_id": incident_id} Design Principles for Agent Tools Typed parameters with docstrings — The runtime uses type hints and docstrings to generate the tool schema for the LLM. Graceful degradation — Every tool works offline by falling back to local fixtures or file-based state. Idempotent where possible — Tools that create resources return existing records if called with the same parameters. Observable — Every tool invocation emits an OpenTelemetry span for tracing and debugging. The Orchestrator Pattern The orchestrator drives signals through the agent pipeline. It is deliberately simple — a linear flow with error handling: # src/fibreops/orchestrator.py — simplified async def handle_signal(signal: TelemetrySignal) -> RunResult: """Process a telemetry signal through the agent pipeline.""" # Stage 1: Incident Analysis analysis = await incident_agent.run( f"Analyse this signal: {signal.model_dump_json()}" ) # Stage 2: NetOps Coordination coordination = await netops_agent.run( f"Coordinate response for: {analysis.summary}" ) # Stage 3: Field Dispatch dispatch = await dispatch_agent.run( f"Dispatch engineer for incident: {coordination.incident_id}" ) return RunResult( signal=signal, analysis=analysis, coordination=coordination, dispatch=dispatch, ) The orchestrator honours the same contract regardless of backend — hosted , foundry , or local — because all backends implement await agent.run(prompt) . GitHub Copilot SDK Integration (GA) The GitHub Copilot SDK enables conversational interaction with your agent system. FibreOps implements FibreOpsCopilotClient with the same interface as github/copilot-sdk : # src/fibreops/sdk/__init__.py — simplified from fibreops.sdk.client import FibreOpsCopilotClient client = FibreOpsCopilotClient() session = client.create_session() # Query agent status response = session.send_and_wait("status") print(response.text) # Human-readable summary print(response.data) # Structured JSON # Inject a telemetry signal via conversation response = session.send_and_wait(json.dumps({ "signal_id": "sig-demo", "node_id": "FN-LDN-001", "signal_type": "loss_of_light", "severity": "critical" })) The adapter routes prompts by shape: JSON signal-shaped dicts — Forwarded to the orchestrator for processing. Free-form text — Answered by a deterministic responder ( help , status , nodes , engineers , optimiser , dispatch ). Drive it from the terminal: python -m fibreops.demo chat "help" python -m fibreops.demo chat "status" python -m fibreops.demo chat '{"signal_id":"sig-demo","node_id":"FN-LDN-001","signal_type":"loss_of_light","severity":"critical"}' Or hit the embedded HTTP endpoint when the NOC console is running: Invoke-RestMethod -Method Post http://127.0.0.1:8800/sdk/chat -Body '{"prompt":"status"}' -ContentType application/json Development Workflow with Foundry Toolkit for VS Code The Foundry Toolkit for VS Code provides an integrated development experience: Author prompts — Edit system instructions with live preview and token counting. Test locally — Run against the foundry backend with FoundryChatClient pointing at your development model. Iterate fast — The foundry backend resolves definitions locally, so prompt changes take effect immediately without republishing. Publish when ready — python -m fibreops.demo publish creates hosted Prompt Agents in Foundry. Multi-Model Support The Microsoft Agent Framework supports multiple models. FibreOps defaults to gpt-4.1-mini (the model available in most demo Foundry accounts), but any chat-completions deployment works: # .env AZURE_AI_MODEL_DEPLOYMENT=gpt-4.1-mini # or gpt-4o-mini, gpt-4o, gpt-4.1 The framework also supports Claude Code connectors and Magentic-One for multi-agent collaboration scenarios. Testing Strategy FibreOps demonstrates a layered testing approach: Unit tests — Test tools in isolation with mocked dependencies. Local backend tests — Run the full pipeline with LocalAgent for deterministic assertions. Integration tests — Run against real Foundry agents with pytest -q . Rubric evaluation — The optimizer scores every run against defined criteria. # Run the test suite .\.venv\Scripts\python.exe -m pytest -q Key Takeaways The Microsoft Agent Framework provides a unified .run() contract across hosted, foundry, and local backends. Role specialisation keeps agents focused, testable, and independently evolvable. Tools are typed Python functions with docstrings — the runtime generates schemas automatically. The GitHub Copilot SDK (GA) enables conversational interaction with any agent system. Graceful degradation means the entire system works offline for development. The factory pattern lets you switch backends without changing orchestration code. Next Steps Clone the FibreOps repository and run python -m fibreops.demo --signals 3 Microsoft Agent Framework documentation Next in this series: Running Hosted Agents in Microsoft Foundry Agent Service
Vector search finds candidates. Reranking decides what your RAG app reads
You ask a retrieval-augmented generation (RAG) application a question. Vector search returns ten passages that are clearly related to the topic. The passage that actually contains the answer, however, is ranked seventh, while the language model receives only the first five. Retrieval did not completely fail. It found the evidence, but ordered it below less useful context. Reranking addresses that gap between a passage that is semantically similar and a passage that is relevant to the user's specific question. This article demonstrates that pattern in four Azure services using the Stanford Question Answering Dataset (SQuAD). The goal is not to declare a winning service or publish a quality benchmark. It is to show where retrieval, rank fusion, and model-based reranking run in each architecture, and to illustrate how the position of a known source passage can change. What this demonstration establishes The examples show rank movement for three selected questions. They do not establish that one reranker or service is universally more accurate. A production decision requires a larger, representative query set and aggregate relevance, latency, and cost measurements. Get the full Python implementation: pauldj54/azure-vector-reranking-squad Retrieval and reranking are different stages A production search pipeline commonly uses two stages: Retrieve for recall. Fast retrieval narrows a large corpus to a bounded candidate set. It can use vector search, keyword search, or both. Rerank for precision. A more expensive model evaluates only those candidates against the original query and produces the final order. Reciprocal Rank Fusion (RRF) belongs between those two ideas. RRF is a model-free rank aggregation method that merges independent result lists, usually vector and keyword results. For a document d, a typical score is: RRF(d) = ∑ r ∈ R 1 k + rank r (d) Here, R is the set of ranked lists and k is commonly 60. RRF works with positions rather than raw scores, so it can combine signals such as cosine distance and BM25 without pretending their score scales are comparable. This gives a clearer three-part vocabulary: Stage Purpose Typical mechanism Retrieve Find broad candidate set Vector search, BM25, filters Fuse Combine independent rankings RRF Rerank Reassess query-document relevance Semantic ranker or cross-encoder RRF often improves hybrid retrieval when exact names, dates, identifiers, or terms matter. A learned reranker can then read the query and each candidate together, capturing interactions that separately generated embeddings can miss. The learned stage costs more, so it should operate on tens of candidates rather than the whole corpus. The following image describes the general process: Why use SQuAD for this demonstration? SQuAD 1.1 contains crowd-written questions over more than 500 Wikipedia articles. Its packaged splits contain 87,599 training rows and 10,570 validation rows. Each row includes a question, a context passage, and one or more answer spans inside that passage. That source-context mapping gives this demonstration a useful label: the context associated with a question is treated as its gold passage. We can then inspect whether each search stage moves that passage up or down. This is convenient, but it is not a perfect passage-ranking benchmark. SQuAD was designed for extractive question answering, and another passage in the corpus might also answer a question. The gold context is therefore a reproducible reference, not proof that every other passage is irrelevant. The results shown here use the 2,067 unique contexts in the SQuAD validation split and 1,536-dimensional embeddings. The repository default should be set to the same corpus size before treating the screenshots or rank transitions as directly reproducible. Three illustrative questions Question Expected answer Gold context According to game stats, which Super Bowl 50 quarterback had his worst year since his first NFL season? Peyton Manning 12, Super Bowl 50 What else did Tesla do for work at this time? Various electrical repair jobs 165, Nikola Tesla Who acts as laborer, paymaster, and design team for a renovation project? The property owner 1306, Construction Each notebook selects a seeded demonstration question when it runs. The three saved examples were collected across separate runs; the current notebooks do not execute all three questions in one pass. A benchmark harness should iterate over a fixed question list and save all stage results in one structured output. Capability boundaries at a glance Service Retrieval and Fusion Learned Reranking Boundary to Keep in Mind Azure AI Search Native keyword and vector retrieval with native RRF Built-in semantic ranker Semantic ranking only reorders the retrieved top 50 Azure SQL Database Exact vector retrieval in the current notebook External Cohere model invoked through native REST procedure SQL issues the HTTPS request; Foundry performs inference PostgreSQL Flexible Server pgvector plus hand-written SQL RRF over full-text search Optional external Cohere call from Python Retrieval primitives are native; this RRF query and Cohere path are application code Azure Cosmos DB for NoSQL Native vector search and native hybrid RRF SDK-integrated Semantic Reranker, currently preview Reranking is a separate inference call over at most 50 supplied documents Azure AI Search: native hybrid retrieval and semantic ranking How it works: Azure AI Search provides the most integrated pipeline in this demonstration. A hybrid query runs keyword and vector retrieval, combines the lists with RRF, and passes up to the top 50 results to the built-in semantic ranker. The semantic ranker assigns @search.rerankerScore values from 0 to 4 and can return extractive captions and answers. The semantic configuration identifies the fields that carry the meaning of each document: semantic_search = SemanticSearch( configurations=[ SemanticConfiguration( name=SEMANTIC_CONFIG, prioritized_fields=SemanticPrioritizedFields( title_field=SemanticField(field_name="title"), content_fields=[SemanticField(field_name="content")], ), ) ] ) This tells the semantic ranker which text fields to evaluate. The query then enables semantic ranking after hybrid retrieval: results = search_client.search( search_text=question, vector_queries=[vector_query], query_type="semantic", semantic_configuration_name=SEMANTIC_CONFIG, top=10, ) The important constraint is candidate recall. Semantic ranking does not search the corpus again. If the correct passage is absent from the hybrid top 50, the semantic stage cannot recover it. See 01_azure_ai_search_reranking.ipynb for the complete setup and query path. Test results for Azure AI Search These examples show that semantic reranking improves relevance selectively, not universally. It strongly helps the construction query, moving the correct passage from rank 4 to rank 1, but slightly degrades the Super Bowl and Tesla queries by one position. This reinforces that semantic ranking should be evaluated across a representative query set using aggregate metrics such as MRR or NDCG, rather than judged from a single result. Azure SQL Database: vector retrieval plus external Cohere reranking How it works. The Azure SQL notebook retrieves 20 candidates with exact cosine distance and sends their text to Cohere Rerank v4.0 Fast through sys.sp_invoke_external_rest_endpoint. The vector column and query vector must have the same dimensions. This repository uses 1,536-dimensional embeddings: SELECT TOP (@ candidate_count) context_id, title, content, 1 - VECTOR_DISTANCE( 'cosine', CAST(@ query_vector AS VECTOR(1536)), embedding ) AS similarity FROM dbo.documents ORDER BY similarity DESC; For reranking, we selected Cohere Rerank v4.0 Fast (Cohere-rerank-v4.0-fast), a fast version of Cohere’s fourth-generation relevance-ranking model. The model is deployed in Microsoft Foundry, where its Azure Direct inference endpoint is available in the deployment details within the Foundry portal. Azure SQL can call REST APIs directly using sp_invoke_external_rest_endpoint. Because Azure SQL allowlists Azure AI’s *.cognitiveservices.azure.com domain, we translate the equivalent Foundry endpoint from *.services.ai.azure.com while preserving the Cohere reranking route. from urllib.parse import urlsplit, urlunsplit def sql_compatible_endpoint(endpoint: str) -> str: """Convert an Azure Direct endpoint to Azure SQL's allowed hostname.""" parts = urlsplit(endpoint) if parts.hostname.endswith(".services.ai.azure.com"): resource = parts.hostname.removesuffix(".services.ai.azure.com") hostname = f"{resource}.cognitiveservices.azure.com" elif parts.hostname.endswith(".cognitiveservices.azure.com"): hostname = parts.hostname else: raise ValueError("Expected an Azure AI Services endpoint.") return urlunsplit( (parts.scheme, hostname, parts.path, parts.query, "") ) Then I defined a re-rank with cohere function, starting by loading the endpoint and setting the authentication: def rerank_with_cohere( cursor, question: str, candidates: list[dict], top_n: int = 10, ) -> list[dict]: """ Rerank candidate documents by calling Cohere through Azure SQL. Each candidate must contain a 'content' field. """ if not candidates: return [] sql_endpoint = sql_compatible_endpoint( os.environ["COHERE_RERANK_ENDPOINT"] ) model = os.environ["COHERE_RERANK_MODEL"] access_token = credential.get_token( "https://cognitiveservices.azure.com/.default" ).token headers = json.dumps({"Authorization": f"Bearer {access_token}"}) payload = json.dumps( { "model": model, "query": question, "documents": [row["content"] for row in candidates], "top_n": min(k, len(candidates)), }, ensure_ascii=False, ) cursor.execute( """ DECLARE @url NVARCHAR(4000) = CAST(? AS NVARCHAR(4000)); DECLARE @headers NVARCHAR(4000) = CAST(? AS NVARCHAR(4000)); DECLARE Payload NVARCHAR(MAX) = CAST(? AS NVARCHAR(MAX)); DECLARE Response NVARCHAR(MAX); DECLARE @status INT; EXEC @status = sys.sp_invoke_external_rest_endpoint @url = @url, @method = 'POST', @headers = @headers, Payload = Payload, @timeout = 60, @retry_count = 2, Response = Response OUTPUT; SELECT @status, Response; """, sql_endpoint, headers, payload, ) status, response_text = cursor.fetchone() if status != 0: raise RuntimeError(f"Reranker endpoint returned HTTP status {status}.") response = json.loads(response_text)["result"] You can see the complete implementation in the 02_azure_sql_reranking.ipynb notebook. Test results for Azure SQL Db Across the three sample questions, Cohere reranking consistently moved the correct SQuAD passage closer to the top: from rank 5 to 1 for the Super Bowl question, 3 to 2 for the Tesla question, and 8 to 1 for the construction question. These examples show how vector search provides a strong candidate set, while reranking applies deeper query-document relevance scoring to improve the final ordering. The results are illustrative rather than a complete quality benchmark, so broader evaluation across many queries is still recommended. Azure Database for PostgreSQL flexible server: pgvector, SQL RRF, and an optional model How it works: PostgreSQL makes the pipeline components explicit. The notebook uses pgvector for vector similarity, PostgreSQL full-text search for keyword retrieval, and SQL to implement RRF. Vector retrieval uses cosine distance: SELECT context_id, title, content, 1 - (embedding <= > % (query_vector) s:: vector) AS similarity FROM squad_docs ORDER BY embedding <= > % (query_vector) s:: vector LIMIT % (candidate_count) s; The hybrid query independently ranks vector and keyword hits, then combines positions rather than raw scores: SELECT d.context_id, COALESCE(1.0 / (60 + v.rank), 0) + COALESCE(1.0 / (60 + k.rank), 0) AS rrf_score FROM squad_docs AS d LEFT JOIN vector_hits AS v USING (context_id) LEFT JOIN keyword_hits AS k USING (context_id) WHERE v.context_id IS NOT NULL OR k.context_id IS NOT NULL ORDER BY rrf_score DESC; This is not a built-in PostgreSQL RRF operator. It is transparent, hand-written SQL over native retrieval primitives, which makes weighting and debugging flexible but leaves implementation and tuning with the application team. The notebook's optional learned stage sends the vector candidates from Python to a Foundry deployment of Cohere Rerank v4.0 Fast. This path was chosen because the tested Flexible Server azure_ai extension version expected the older serverless reranking endpoint contract. Microsoft documentation still describes azure_ai.rank() as a preview function whose default model is Cohere Rerank v3.5, even though that model retired on May 14, 2026. Treat this as a version-specific compatibility issue and verify current extension behavior before selecting an architecture. Azure HorizonDB is a different product path. Its AI Model Management feature can provision Cohere Rerank v4.0 Fast as default-reranker, but that management feature is currently a limited preview. It should not be described as a generally available Flexible Server capability. See 03_azure_postgres_reranking.ipynb for the full SQL and optional external model path. Test results for Azure SQL for PostgreSQL Flexible Server The tests show that PostgreSQL vector search provides a useful candidate set, SQL RRF can substantially improve results when keyword evidence is strong, and the Cohere semantic reranker is the most consistent overall: it moved the correct passage to rank 1 in two tests and from rank 3 to rank 2 in the Tesla test. RRF produced the biggest gain for the construction question, moving the correct passage from outside the vector top five to rank 1, but did not improve every query. The scores across stages are not directly comparable because cosine similarity, RRF score, and Cohere relevance use different scales. Azure Cosmos DB for NoSQL: hybrid search with built-in RRF How it works: Azure Cosmos DB for NoSQL supports native hybrid ranking with VectorDistance, FullTextScore, and RRF inside ORDER BY RANK: SELECT TOP K C.context_id, c.title, c.text FROM c ORDER BY RANK RRF( VectorDistance(c.vector, @query_vector), FullTextScore(c.text, @term1, @term2, @term3) ) The notebook extracts distinct terms from the question before building the full-text part of the query. That token selection is application logic and can materially affect the hybrid ranking, so production evaluation should test analyzers, languages, term extraction, and optional RRF weights. Cosmos DB Semantic Reranker is an SDK-integrated preview feature. The application first runs a query, serializes the resulting documents, and submits those documents with the user's context string: result = container.semantic_rerank( context=question, documents=documents, options={ "return_documents": False, "top_k": min(k, len(documents)), "sort": True, "document_type": "json", "target_paths": "title,text", }, ) The service accepts at most 50 documents per rerank call and returns relevance scores from 0 to 1, plus inference latency and token usage. It uses the Microsoft semantic ranking model also used by Azure AI Search. The reranking call requires Microsoft Entra authentication, the appropriate Semantic Reranker role, and an account-linked inference endpoint. The 04_azure_cosmosdb_reranking.ipynb in the shared repo contains and end-to-end implementation. Test results for Azure Cosmos Db The results show that vector search provides a strong baseline, while hybrid RRF and semantic reranking improve different queries in different ways. Hybrid RRF helps when exact keywords matter, moving the construction answer into the top results, while the semantic reranker delivers the strongest overall ordering, promoting the correct construction passage from hybrid rank 3 to rank 1 and improving the Super Bowl answer from rank 5 to rank 2. However, it does not always place the gold passage first, as seen in the Tesla example, confirming that reranking improves relevance but is query-dependent and should be evaluated across a larger test set. What the examples do and do not show The four services expose different ownership boundaries: • Azure AI Search owns hybrid fusion and learned semantic ranking inside the search service. • Azure SQL owns vector retrieval and outbound REST invocation in this example, while Foundry owns model inference. • PostgreSQL supplies vector and full-text primitives; the application owns the RRF SQL and optional Cohere call. • Cosmos DB provides native hybrid RRF and integrates a separate preview inference call through its SDK. Across three selected questions, the known source passage often moved substantially. That supports the practical value of testing a second-stage ranker. It does not prove that semantic reranking always improves top-1 accuracy, that RRF is universally beneficial, or that scores from different stages can be compared directly. Cosine similarity, RRF score, Azure AI Search reranker score, Cohere relevance, and Cosmos DB semantic relevance all have different definitions and scales. Compare rank positions and task-level metrics, not raw values across systems. Turn the demonstration into an evaluation For a production RAG system, convert the notebook pattern into a repeatable evaluation harness: Build a representative labeled query set from real user tasks. Freeze corpus, chunking, embedding model, dimensions, and candidate counts for each run. Record ranks after retrieval, fusion, and learned reranking. Measure Recall@k or Hit@k to verify that retrieval finds relevant evidence. Measure Mean Reciprocal Rank (MRR) when the position of the first relevant result matters. Use NDCG when judgments include multiple passages or graded relevance. Record latency percentiles, inference usage, request cost, and failure rates. Evaluate the generated answer separately for correctness, citation support, and refusal behavior. Also test the operational cases that a three-question demonstration cannot cover: empty keyword results, missing gold passages, long documents, multilingual text, filters, partial outages, token expiration, throttling, model retirement, and low-confidence scores. Practical guidance Retrieve broadly enough that the correct evidence can reach the learned stage. Use RRF when vector and keyword retrieval provide complementary signals. Rerank a bounded candidate set, commonly 20 to 50 passages, and measure the latency cost. Keep citations and source identifiers through every rank transformation. Version the corpus, embedding model, dimensions, query set, and reranker deployment. Do not hard-code assumptions about model endpoints or lifecycle dates. Verify current service documentation and the deployed extension or SDK version. Add thresholds or fallback behavior only after calibrating scores on your own data. Judge the full RAG chain. Better passage order is valuable only when it improves grounded answers for users. Vector search is built to find plausible candidates quickly. Rank fusion can reconcile retrieval signals, and a learned reranker can decide which candidates best address the question. The right architecture depends on where your data lives, which service boundaries you want to operate, and what your evaluation says about quality, latency, and cost. Resources Companion repository Azure AI Search semantic ranker Azure SQL VECTOR_DISTANCE Azure SQL sp_invoke_external_rest_endpoint Azure Database for PostgreSQL AI functions Microsoft Foundry model retirement schedule Azure Cosmos DB hybrid search Azure Cosmos DB Semantic Reranker SQuAD dataset card Dataset attribution Rajpurkar, P., Zhang, J., Lopyrev, K., and Liang, P. (2016). SQuAD: 100,000+ Questions for Machine Comprehension of Text. EMNLP 2016. SQuAD 1.1 is distributed under CC BY-SA 4.0.Give Your E-Commerce App a Memory: Adding Agents That Actually Remember Your Customers
Ever shopped online and felt like the app had no idea who you are? You browse jackets every week, you told the chatbot you hate polyester, and yet it keeps showing you the same generic recommendations. That’s the problem. Most e-commerce apps treat every interaction as a blank slate. What if your app could remember? What if a customer could say “I told you last week I like leather jackets” and the app actually knew that? That’s what we’re building here — an AI shopping assistant with persistent memory, powered by Microsoft Agent Framework and SQL Server. The Problem: Amnesia in E-Commerce Traditional e-commerce chatbots have a fundamental issue — they forget everything the moment the session ends. Here’s what that looks like in practice: Monday: > Customer: “I’m looking for a warm winter jacket, something in leather” > Bot: “Great! Here are some leather jackets…” Wednesday: > Customer: “Show me more options like what we discussed” > Bot: “I’m sorry, could you tell me what you’re looking for?” The customer told you their preferences. They invested time in a conversation. And the app just… forgot. This isn’t just a bad user experience — it’s a missed opportunity. Every preference a customer shares is data you could use to serve them better next time. The Solution: An Agent That Remembers At a high level, what we want is simple: Chats naturally — the customer can talk about what they like and don’t like. Remembers across sessions — log out, come back tomorrow, and it still knows you prefer leather over polyester. Makes smart recommendations — uses the full conversation history to suggest products that actually match. The trick isn’t building a chatbot — that part is easy these days. The trick is giving it memory that persists and scales. Our Architecture The architecture has three layers: a FastAPI backend serving a browser SPA, conversational agents built on Microsoft Agent Framework, and SQL Server as the persistent memory layer. Architecture diagram The key piece that ties it all together is the history provider — a component that plugs into the framework and handles loading/saving conversation history automatically. The agent doesn’t manage its own memory; the framework does, through this provider abstraction. Why Microsoft Agent Framework Microsoft Agent Framework is an open-source Python framework for building AI agents. Think of it as the plumbing between your application logic and the LLM — it handles sessions, conversation history, context injection, and tool execution so you can focus on what your agent actually does. Why use it instead of rolling your own? Session management — built-in support for creating and tracking user sessions. Context providers — a clean abstraction for injecting history, user profiles, or any other context before each LLM call. Provider pattern — swap out your storage backend (SQL Server, Cosmos DB, in-memory) without changing agent code. Tool integration — define functions the agent can call, and the framework handles the execution loop. At its simplest, creating an agent looks like this: from agent_framework import Agent agent = Agent( client=chat_client, instructions="You are a helpful assistant.", ) session = agent.create_session() response = await agent.run("Hello!", session=session) print(response) That gives you a stateless agent — no memory between calls. To add memory, you provide a context provider that loads and saves messages: from agent_framework import Agent, BaseHistoryProvider class MyHistoryProvider(BaseHistoryProvider): async def get_messages(self, session_id, **kwargs): # Load messages from your storage return load_from_db(session_id) async def save_messages(self, session_id, messages, **kwargs): # Persist messages to your storage save_to_db(session_id, messages) agent = Agent( client=chat_client, instructions="You are a helpful assistant.", context_providers=[MyHistoryProvider()] ) The framework calls get_messages() before each run and save_messages() after. Your agent now has memory — and you didn’t have to manually wire load/save into every request handler. Why SQL Server for the Memory Layer So, we need a database behind that history provider. Why SQL Server over, say, PostgreSQL? Both are solid, relational databases. Both can store conversation history just fine. But for this use case — agent memory that starts local and grows to production — SQL Server has a smoother story: Consideration SQL Server PostgreSQL Local dev One Docker command, no config files Needs pg_hba.conf, postgresql.conf tuning Cloud path Docker → Azure SQL Database, same driver, zero code changes Docker → various managed options (Cloud SQL, RDS, Azure DB for PostgreSQL), often with driver/extension differences Managed scaling Azure SQL auto-scales compute, Hyperscale handles 100TB+, license-free option Managed Postgres varies by provider, Citus for scale-out adds complexity Free tier 10 free databases per Azure subscription Varies by cloud provider Agent framework fit First-class mssql_python driver, tested with MAF samples Works, but you’re wiring your own driver integration The short version: PostgreSQL is a great database, but SQL Server gives us a single continuum from docker run on a laptop all the way to a globally distributed managed service — same engine, same queries, same connection driver. When your agent goes from prototype to production, you change a connection string, not your architecture. We’ll go deeper on the cloud scaling story later in this post. For now, let’s build the thing. Setting Up the Infrastructure Getting SQL Server running locally is one Docker command: docker run -d ` --name sql ` -e "ACCEPT_EULA=Y" ` -e "MSSQL_SA_PASSWORD=YourStrong!Passw0rd" ` -p 1433:1433 ` -v sqlvolume:/var/opt/mssql ` mcr.microsoft.com/mssql/server:2022-latest We also need local LLMs via Ollama — Llama 3.1 for conversational quality and Phi-3 Mini for fast structured recommendations: foundry download llama3.1 foundry download phi3:mini And then our Python dependencies: cd commerce-agent uv sync uv pip install fastapi uvicorn httpx The Database Schema The schema is straightforward — Users, Sessions, and ChatHistory. The important relationship is that ChatHistory is scoped to a session, and sessions belong to users. This means each user gets their own isolated conversation history. CREATE TABLE Users ( Id INT IDENTITY PRIMARY KEY, Username NVARCHAR(100) UNIQUE NOT NULL, DisplayName NVARCHAR(200) NOT NULL, CreatedAt DATETIME2 DEFAULT GETUTCDATE() ) CREATE TABLE Sessions ( Id NVARCHAR(100) PRIMARY KEY, UserId INT NOT NULL FOREIGN KEY REFERENCES Users(Id), CreatedAt DATETIME2 DEFAULT GETUTCDATE(), LastActiveAt DATETIME2 DEFAULT GETUTCDATE() ) CREATE TABLE ChatHistory ( Id INT IDENTITY PRIMARY KEY, SessionId NVARCHAR(100) NOT NULL FOREIGN KEY REFERENCES Sessions(Id), Role NVARCHAR(50), Content NVARCHAR(MAX), CreatedAt DATETIME2 DEFAULT GETUTCDATE() ) Every message — whether from the user or the assistant — gets stored with a timestamp and role. When the agent needs context, it pulls the full conversation history for that session. The History Provider: Plugging Memory into the Framework Here’s where it gets interesting. Microsoft Agent Framework has a concept called BaseHistoryProvider. You extend it, implement two methods — get_messages() and save_messages() — and the framework handles the rest. It calls get_messages() before each agent run to load context, and save_messages() after to persist new messages. from agent_framework import BaseHistoryProvider, Message class CommerceHistoryProvider(BaseHistoryProvider): def __init__(self, source_id: str = "commerce-history"): super().__init__(source_id) async def get_messages( self, session_id: str | None, *, state: dict[str, Any] | None = None, **kwargs: Any ) -> list[Message]: if not session_id: return [] conn = get_conn() cursor = conn.cursor() cursor.execute(""" SELECT Role, Content FROM ChatHistory WHERE SessionId = ? ORDER BY CreatedAt """, (session_id,)) rows = cursor.fetchall() conn.close() return [Message(role=role, text=content) for role, content in rows] async def save_messages( self, session_id: str | None, messages: Sequence[Message], *, state: dict[str, Any] | None = None, **kwargs: Any, ) -> None: if not session_id: return conn = get_conn() cursor = conn.cursor() for msg in messages: text = msg.text or "" if not text and msg.contents: text = "".join(c.text for c in msg.contents if hasattr(c, "text")) cursor.execute( "INSERT INTO ChatHistory (SessionId, Role, Content) VALUES (?, ?, ?)", (session_id, msg.role, text) ) conn.commit() conn.close() That’s it — that’s the memory layer. The framework calls these methods at the right time, so you never have to manually load or save history in your route handlers. Wiring It Up: The Agent With the history provider in place, creating the agent is clean: from agent_framework import Agent history_provider = CommerceHistoryProvider() chat_client = create_chat_client() agent = Agent( client=chat_client, instructions=( "You are a friendly shopping assistant. Help users discover products they'll love. " "Ask about their interests, hobbies, and preferences. Remember what they tell you. " "Be conversational and warm." ), context_providers=[history_provider] ) The context_providers parameter is the key. By passing our history provider here, the agent automatically gets the user’s full conversation history as context before generating a response. No manual plumbing required. Handling a Chat Request When a user sends a message, here’s what happens end-to-end: app.post("/api/chat") async def chat(req: ChatRequest): user = get_user(req.username) if not user: raise HTTPException(status_code=401, detail="Not logged in") session_id = get_or_create_session(user["id"]) session = agent.create_session(session_id=session_id) response = await agent.run(req.message, session=session) return {"response": str(response)} Behind the scenes: 1. We look up (or create) a session for this user. 2. The framework calls get_messages() to load all prior conversation. 3. The LLM sees the full history + the new message and generates a contextual response. 4. The framework calls save_messages() to persist the new exchange. The customer says “I told you I like leather jackets” and the agent actually knows because it has the full history. Smart Recommendations The real payoff comes when you combine memory with recommendations. Because we have the full conversation history, we can analyze what the customer has told us and match against our product catalog: app.post("/api/recommendations") async def recommendations(req: RecommendationRequest): user = get_user(req.username) session_id = get_or_create_session(user["id"]) history = get_session_history(session_id) if not history: all_prods = get_all_products()[:6] return {"best_match": all_prods[0], "other": all_prods[1:]} matched = score_products(history) return { "best_match": matched[0] if matched else None, "other": matched[1:] if len(matched) > 1 else matched, "message": f"Based on your preferences, {user['display_name']}!" } The score_products() function takes the conversation history, extracts preferences, and scores products against them. If a customer said they love outdoor gear and hate synthetic materials — that’s reflected in what gets recommended. Why This Matters Adding persistent memory to your e-commerce agent isn’t just a technical exercise. It fundamentally changes the customer relationship: Customers feel heard — they don’t have to repeat themselves. Recommendations improve over time — the more they chat, the better you understand them. Sessions become cumulative — each visit builds on the last instead of starting fresh. The Microsoft Agent Framework makes this surprisingly straightforward. You implement a history provider, plug it in via context_providers, and the framework handles the lifecycle. SQL Server gives you durable, queryable storage. And because the provider interface is clean, moving to the cloud doesn’t require rewriting anything. Growing Up: From Docker to the Cloud We wanted to start easy — Foundry Local for the LLM, SQL Server from a Docker container, everything running on your laptop. That’s great for prototyping and proving out the concept. But what does the grow-up story look like when you’re ready to serve real customers at scale? Let’s talk about that next. The good news: because we used SQL Server locally, the path to production is a straight line — not a migration. Azure SQL Database Azure SQL Database is the managed version of what you’ve been running in Docker. Same engine, same T-SQL, same connection driver. Your CommerceHistoryProvider code doesn’t change at all — you just update the connection string. What you get by moving to Azure SQL Database: Feature Why it matters for agents Auto-scaling Conversation spikes during sales events? The database scales compute up and back down automatically. 10 free databases per subscription Experiment with separate DBs per agent or environment without worrying about cost during development. Built-in high availability 99.99% SLA — your agent’s memory doesn’t go down because a container crashed. Geo-replication Serve users globally with read replicas close to them — conversation history loads fast regardless of region. Automatic backups Point-in-time restore up to 35 days. Accidentally dropped the ChatHistory table? Roll back. Hyperscale: When Conversations Get Big As your user base grows, conversation history grows with it. A single user might accumulate thousands of messages over months. Multiply that by millions of users and you’re looking at serious storage. Azure SQL Hyperscale is designed for exactly this: Up to 100 TB of storage — your conversation history can grow without partition gymnastics. License-free — Hyperscale has a license-free option, so you only pay for compute and storage, not per-core licensing. Near-instant scale-out — add read replicas in seconds for analytics workloads (e.g., “what are the trending preferences across all users this week?”). Fast database snapshots — spin up a copy of production for testing or ML training without waiting hours for a restore. The Connection String Is the Only Change Here’s what the transition looks like in code. Your local setup: DB_CONFIG = { "server": "localhost", "port": 1433, "user": "sa", "password": "YourStrong!Passw0rd", "database": "agentdb" } Your production setup on Azure SQL: DB_CONFIG = { "server": "your-agent-db.database.windows.net", "port": 1433, "user": "agent-app", "password": os.environ["AZURE_SQL_PASSWORD"], "database": "agentdb" } Same schema. Same queries. Same CommerceHistoryProvider. The agent doesn’t know or care that it moved from a Docker container to a globally distributed managed database — it just works, faster and more reliably. See It in Action Here’s Steve chatting with the assistant about outdoor gear, with Foundry selected as the recommendation provider. Notice how the recommendations on the right reflect his stated preferences: Steve chatting with the shopping agent — Foundry provider selected And here’s Marla, a completely different user with different tastes. Same app, same agent — but her conversation history and recommendations are entirely her own: Marla chatting with the shopping agent — Foundry provider selected Each user gets isolated conversation history. The agent remembers what they said, not what someone else said. That’s the power of session-scoped memory backed by SQL Server. Running It Yourself 1. Clone the repo: https://github.com/softchris/ecommerce-agent-memory 2. Install dependencies (make sure you installed the prereqs as laid out by the README file first) uv sync 3. Run the app uv run uvicorn app:app --reload --port 8000 4. Navigate to http://localhost:8000, log in as Marla or Steve, and start chatting. Tell the assistant what you like. Log out. Come back. Ask for recommendations. The agent remembers. That’s the difference between a chatbot and an assistant that actually knows your customers. Call to Actions Ready to build your own agent with memory? Here’s where to go next: 📖 Microsoft Agent Framework Documentation — official docs covering agents, context providers, sessions, tool use, and more. Start here to understand the full capabilities of the framework. 🧪 Foundry Local Python Samples — hands-on sample code showing how to run agents locally with Foundry. Great for getting something running fast without cloud dependencies. 🛍️ This project’s source code — the full e-commerce agent with persistent SQL Server memory. Clone it, run it, and adapt it to your own use case.