ai
37 TopicsLevel up your Python + AI skills with our complete series
We've just wrapped up our live series on Python + AI, a comprehensive nine-part journey diving deep into how to use generative AI models from Python. The series introduced multiple types of models, including LLMs, embedding models, and vision models. We dug into popular techniques like RAG, tool calling, and structured outputs. We assessed AI quality and safety using automated evaluations and red-teaming. Finally, we developed AI agents using popular Python agents frameworks and explored the new Model Context Protocol (MCP). To help you apply what you've learned, all of our code examples work with GitHub Models, a service that provides free models to every GitHub account holder for experimentation and education. Even if you missed the live series, you can still access all the material using the links below! If you're an instructor, feel free to use the slides and code examples in your own classes. If you're a Spanish speaker, check out the Spanish version of the series. Python + AI: Large Language Models 📺 Watch recording In this session, we explore Large Language Models (LLMs), the models that power ChatGPT and GitHub Copilot. We use Python to interact with LLMs using popular packages like the OpenAI SDK and LangChain. We experiment with prompt engineering and few-shot examples to improve outputs. We also demonstrate how to build a full-stack app powered by LLMs and explain the importance of concurrency and streaming for user-facing AI apps. Slides for this session Code repository with examples: python-openai-demos Python + AI: Vector embeddings 📺 Watch recording In our second session, we dive into a different type of model: the vector embedding model. A vector embedding is a way to encode text or images as an array of floating-point numbers. Vector embeddings enable similarity search across many types of content. In this session, we explore different vector embedding models, such as the OpenAI text-embedding-3 series, through both visualizations and Python code. We compare distance metrics, use quantization to reduce vector size, and experiment with multimodal embedding models. Slides for this session Code repository with examples: vector-embedding-demos Python + AI: Retrieval Augmented Generation 📺 Watch recording In our third session, we explore one of the most popular techniques used with LLMs: Retrieval Augmented Generation. RAG is an approach that provides context to the LLM, enabling it to deliver well-grounded answers for a particular domain. The RAG approach works with many types of data sources, including CSVs, webpages, documents, and databases. In this session, we walk through RAG flows in Python, starting with a simple flow and culminating in a full-stack RAG application based on Azure AI Search. Slides for this session Code repository with examples: python-openai-demos Python + AI: Vision models 📺 Watch recording Our fourth session is all about vision models! Vision models are LLMs that can accept both text and images, such as GPT-4o and GPT-4o mini. You can use these models for image captioning, data extraction, question answering, classification, and more! We use Python to send images to vision models, build a basic chat-with-images app, and create a multimodal search engine. Slides for this session Code repository with examples: openai-chat-vision-quickstart Python + AI: Structured outputs 📺 Watch recording In our fifth session, we discover how to get LLMs to output structured responses that adhere to a schema. In Python, all you need to do is define a Pydantic BaseModel to get validated output that perfectly meets your needs. We focus on the structured outputs mode available in OpenAI models, but you can use similar techniques with other model providers. Our examples demonstrate the many ways you can use structured responses, such as entity extraction, classification, and agentic workflows. Slides for this session Code repository with examples: python-openai-demos Python + AI: Quality and safety 📺 Watch recording This session covers a crucial topic: how to use AI safely and how to evaluate the quality of AI outputs. There are multiple mitigation layers when working with LLMs: the model itself, a safety system on top, the prompting and context, and the application user experience. We focus on Azure tools that make it easier to deploy safe AI systems into production. We demonstrate how to configure the Azure AI Content Safety system when working with Azure AI models and how to handle errors in Python code. Then we use the Azure AI Evaluation SDK to evaluate the safety and quality of output from your LLM. Slides for this session Code repository with examples: ai-quality-safety-demos Python + AI: Tool calling 📺 Watch recording In the final part of the series, we focus on the technologies needed to build AI agents, starting with the foundation: tool calling (also known as function calling). We define tool call specifications using both JSON schema and Python function definitions, then send these definitions to the LLM. We demonstrate how to properly handle tool call responses from LLMs, enable parallel tool calling, and iterate over multiple tool calls. Understanding tool calling is absolutely essential before diving into agents, so don't skip over this foundational session. Slides for this session Code repository with examples: python-openai-demos Python + AI: Agents 📺 Watch recording In the penultimate session, we build AI agents! We use Python AI agent frameworks such as the new agent-framework from Microsoft and the popular LangGraph framework. Our agents start simple and then increase in complexity, demonstrating different architectures such as multiple tools, supervisor patterns, graphs, and human-in-the-loop workflows. Slides for this session Code repository with examples: python-ai-agent-frameworks-demos Python + AI: Model Context Protocol 📺 Watch recording In the final session, we dive into the hottest technology of 2025: MCP (Model Context Protocol). This open protocol makes it easy to extend AI agents and chatbots with custom functionality, making them more powerful and flexible. We demonstrate how to use the Python FastMCP SDK to build an MCP server running locally and consume that server from chatbots like GitHub Copilot. Then we build our own MCP client to consume the server. Finally, we discover how easy it is to connect AI agent frameworks like LangGraph and Microsoft agent-framework to MCP servers. With great power comes great responsibility, so we briefly discuss the security risks that come with MCP, both as a user and as a developer. Slides for this session Code repository with examples: python-mcp-demo12KViews6likes0CommentsPrivyDoc: Building a Zero-Data-Leak AI with Foundry Local & Microsoft's Agent Framework
Tired of choosing between powerful AI insights and sacrificing your data's privacy? PrivyDoc offers a groundbreaking solution. In this article, Microsoft MVP in AI, Shivam Goyal, introduces his innovative project that brings robust AI document analysis directly to your local machine, ensuring zero data ever leaves your device. Discover how PrivyDoc leverages two cutting-edge Microsoft technologies: Foundry Local: The secret sauce for 100% on-device AI processing, allowing advanced models to run securely without cloud dependency. Microsoft Agent Framework: The intelligent orchestrator that builds a sophisticated multi-agent pipeline, handling everything from text extraction and entity recognition to summarization and sentiment analysis. Learn about PrivyDoc's intuitive web UI, its multi-format support, and crucial features that make it perfect for sensitive industries like legal, healthcare, and finance. Say goodbye to privacy concerns and hello to AI-powered document intelligence without compromise.655Views3likes0CommentsHow to use any Python AI agent framework with free GitHub Models
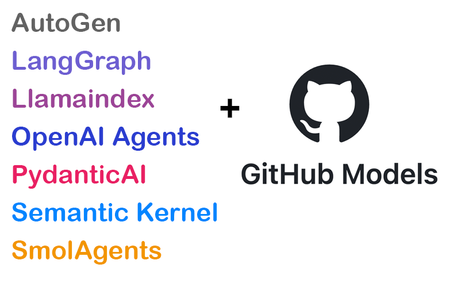
I ❤️ when companies offer free tiers for developer services, since it gives everyone a way to learn new technologies without breaking the bank. Free tiers are especially important for students and people between jobs, when the desire to learn is high but the available cash is low. That's why I'm such a fan of GitHub Models: free, high-quality generative AI models available to anyone with a GitHub account. The available models include the latest OpenAI LLMs (like o3-mini), LLMs from the research community (like Phi and Llama), LLMs from other popular providers (like Mistral and Jamba), multimodal models (like gpt-4o and llama-vision-instruct) and even a few embedding models (from OpenAI and Cohere). With access to such a range of models, you can prototype complex multi-model workflows to improve your productivity or heck, just make something fun for yourself. 🤗 To use GitHub Models, you can start off in no-code mode: open the playground for a model, send a few requests, tweak the parameters, and check out the answers. When you're ready to write code, select "Use this model". A screen will pop up where you can select a programming language (Python/JavaScript/C#/Java/REST) and select an SDK (which varies depending on model). Then you'll get instructions and code for that model, language, and SDK. But here's what's really cool about GitHub Models: you can use them with all the popular Python AI frameworks, even if the framework has no specific integration with GitHub Models. How is that possible? The vast majority of Python AI frameworks support the OpenAI Chat Completions API, since that API became a defacto standard supported by many LLM API providers besides OpenAI itself. GitHub Models also provide OpenAI-compatible endpoints for chat completion models. Therefore, any Python AI framework that supports OpenAI-like models can be used with GitHub Models as well. 🎉 To prove it, I've made a new repository with examples from eight different Python AI agent packages, all working with GitHub Models: python-ai-agent-frameworks-demos. There are examples for AutoGen, LangGraph, Llamaindex, OpenAI Agents SDK, OpenAI standard SDK, PydanticAI, Semantic Kernel, and SmolAgents. You can open that repository in GitHub Codespaces, install the packages, and get the examples running immediately. Now let's walk through the API connection code for GitHub Models for each framework. Even if I missed your favorite framework, I hope my tips here will help you connect any framework to GitHub Models. OpenAI I'll start with openai , the package that started it all! import openai client = openai.OpenAI( api_key=os.environ["GITHUB_TOKEN"], base_url="https://models.inference.ai.azure.com") The code above demonstrates the two key parameters we'll need to configure for all frameworks: api_key : When using OpenAI.com, you pass your OpenAI API key here. When using GitHub Models, you pass in a Personal Access Token (PAT). If you open the repository (or any repository) in GitHub Codespaces, a PAT is already stored in the GITHUB_TOKEN environment variable. However, if you're working locally with GitHub Models, you'll need to generate a PAT yourself and store it. PATs expire after a while, so you need to generate new PATs every so often. base_url : This parameter tells the OpenAI client to send all requests to "https://models.inference.ai.azure.com" instead of the OpenAI.com API servers. That's the domain that hosts the OpenAI-compatible endpoint for GitHub Models, so you'll always pass that domain as the base URL. If we're working with the new openai-agents SDK, we use very similar code, but we must use the AsyncOpenAI client from openai instead. Lately, Python AI packages are defaulting to async, because it's so much better for performance. import agents import openai client = openai.AsyncOpenAI( base_url="https://models.inference.ai.azure.com", api_key=os.environ["GITHUB_TOKEN"]) model = agents.OpenAIChatCompletionsModel( model="gpt-4o", openai_client=client) spanish_agent = agents.Agent( name="Spanish agent", instructions="You only speak Spanish.", model=model) PydanticAI Now let's look at all of the packages that make it really easy for us, by allowing us to directly bring in an instance of either OpenAI or AsyncOpenAI . For PydanticAI, we configure an AsyncOpenAI client, then construct an OpenAIModel object from PydanticAI, and pass that model to the agent: import openai import pydantic_ai import pydantic_ai.models.openai client = openai.AsyncOpenAI( api_key=os.environ["GITHUB_TOKEN"], base_url="https://models.inference.ai.azure.com") model = pydantic_ai.models.openai.OpenAIModel( "gpt-4o", provider=OpenAIProvider(openai_client=client)) spanish_agent = pydantic_ai.Agent( model, system_prompt="You only speak Spanish.") Semantic Kernel For Semantic Kernel, the code is very similar. We configure an AsyncOpenAI client, then construct an OpenAIChatCompletion object from Semantic Kernel, and add that object to the kernel. import openai import semantic_kernel.connectors.ai.open_ai import semantic_kernel.agents chat_client = openai.AsyncOpenAI( api_key=os.environ["GITHUB_TOKEN"], base_url="https://models.inference.ai.azure.com") chat = semantic_kernel.connectors.ai.open_ai.OpenAIChatCompletion( ai_model_id="gpt-4o", async_client=chat_client) kernel.add_service(chat) spanish_agent = semantic_kernel.agents.ChatCompletionAgent( kernel=kernel, name="Spanish agent" instructions="You only speak Spanish") AutoGen Next, we'll check out a few frameworks that have their own wrapper of the OpenAI clients, so we won't be using any classes from openai directly. For AutoGen, we configure both the OpenAI parameters and the model name in the same object, then pass that to each agent: import autogen_ext.models.openai import autogen_agentchat.agents client = autogen_ext.models.openai.OpenAIChatCompletionClient( model="gpt-4o", api_key=os.environ["GITHUB_TOKEN"], base_url="https://models.inference.ai.azure.com") spanish_agent = autogen_agentchat.agents.AssistantAgent( "spanish_agent", model_client=client, system_message="You only speak Spanish") LangGraph For LangGraph, we configure a very similar object, which even has the same parameter names: import langchain_openai import langgraph.graph model = langchain_openai.ChatOpenAI( model="gpt-4o", api_key=os.environ["GITHUB_TOKEN"], base_url="https://models.inference.ai.azure.com", ) def call_model(state): messages = state["messages"] response = model.invoke(messages) return {"messages": [response]} workflow = langgraph.graph.StateGraph(MessagesState) workflow.add_node("agent", call_model) SmolAgents Once again, for SmolAgents, we configure a similar object, though with slightly different parameter names: import smolagents model = smolagents.OpenAIServerModel( model_id="gpt-4o", api_key=os.environ["GITHUB_TOKEN"], api_base="https://models.inference.ai.azure.com") agent = smolagents.CodeAgent(model=model) Llamaindex I saved Llamaindex for last, as it is the most different. The llama-index package has a different constructor for OpenAI.com versus OpenAI-like servers, so I opted to use that OpenAILike constructor instead. However, I also needed an embeddings model for my example, and the package doesn't have an OpenAIEmbeddingsLike constructor, so I used the standard OpenAIEmbedding constructor. import llama_index.embeddings.openai import llama_index.llms.openai_like import llama_index.core.agent.workflow Settings.llm = llama_index.llms.openai_like.OpenAILike( model="gpt-4o", api_key=os.environ["GITHUB_TOKEN"], api_base="https://models.inference.ai.azure.com", is_chat_model=True) Settings.embed_model = llama_index.embeddings.openai.OpenAIEmbedding( model="text-embedding-3-small", api_key=os.environ["GITHUB_TOKEN"], api_base="https://models.inference.ai.azure.com") agent = llama_index.core.agent.workflow.ReActAgent( tools=query_engine_tools, llm=Settings.llm) Choose your models wisely! In all of the examples above, I specified the gpt-4o model. The gpt-4o model is a great choice for agents because it supports function calling, and many agent frameworks only work (or work best) with models that natively support function calling. Fortunately, GitHub Models includes multiple models that support function calling, at least in my basic experiments: gpt-4o gpt-4o-mini o3-mini AI21-Jamba-1.5-Large AI21-Jamba-1.5-Mini Codestral-2501 Cohere-command-r Ministral-3B Mistral-Large-2411 Mistral-Nemo Mistral-small You might find that some models work better than others, especially if you're using agents with multiple tools. With GitHub Models, it's very easy to experiment and see for yourself, by simply changing the model name and re-running the code. Join the AI Agents Hackathon We are currently running a free virtual hackathon from April 8th - 30th, to challenge developers to create agentic applications using Microsoft technologies. You could build an agent entirely using GitHub Models and submit it to the hackathon for a chance to win amazing prizes! You can also join our 30+ streams about building AI agents, including a stream all about prototyping with GitHub Models. Learn more and register at https://aka.ms/agentshack3.1KViews3likes0CommentsCombating Digitally Altered Images: Deepfake Detection
In today's digital age, the rise of deepfake technology poses significant threats to credibility, privacy, and security. This article delves into our Deepfake Detection Project, a robust solution designed to combat the misuse of AI-generated content.1.7KViews3likes0CommentsAI Agents: Building Trustworthy Agents- Part 6
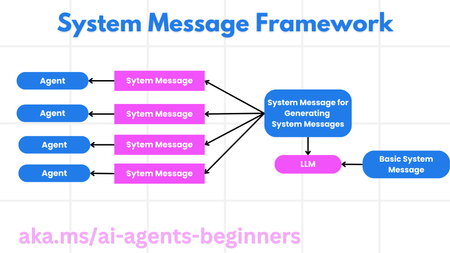
This blog post, Part 6 in a series on AI agents, focuses on building trustworthy AI agents. It emphasizes the importance of safety and security in agent design and deployment. The post details a system message framework for creating robust and scalable prompts, outlining a four-step process from meta prompt to iterative refinement. It then explores various threats to AI agents, including task manipulation, unauthorized access, resource overloading, knowledge base poisoning, and cascading errors, providing mitigation strategies for each. The post also highlights the human-in-the-loop approach for enhanced trust and control, providing a code example using AutoGen. Finally, it links to further resources on responsible AI, model evaluation, and risk assessment, along with the previous posts in the series.1KViews3likes0CommentsFix Broken Migrations with AI Powered Debugging in VS Code Using GitHub Copilot
Data is at the heart of every application. But evolving your schema is risky business. One broken migration, and your dev or prod environment can go down. We've all experienced it: mismatched columns, orphaned constraints, missing fields, or that dreaded "table already exists" error. But what if debugging migrations didn’t have to be painful? What if you could simply describe the error or broken state, and AI could fix your migration in seconds? In this blog, you’ll learn how to: Use GitHub Copilot to describe and fix broken migrations with natural language Catch schema issues like incorrect foreign keys before they block your workflow Validate and deploy your database changes using GibsonAI CLI Broken migrations are nothing new. Whether you're working on a side project or part of a large team, it’s all too easy to introduce schema issues that can block deployments or corrupt local environments. Traditionally, fixing them means scanning SQL files, reading error logs, and manually tracking down what went wrong. But what if you could skip all that? What if you could simply describe the issue in plain English and AI would fix it for you? That’s exactly what GitHub Copilot let you do, right from within VS Code. What You Need: Visual Studio Code Installed Account in GitHub Sign up with GitHub Copilot GibsonAI CLI installed and logged in Let’s Break (and Fix) a Migration: Here’s a common mistake. Say you create two tables: users and posts. CREATE TABLE users ( id UUID PRIMARY KEY, name TEXT, email TEXT UNIQUE ); CREATE TABLE posts ( id UUID PRIMARY KEY, title TEXT, user_id UUID REFERENCES user(id) ); The problem? The posts table refers to a table called user, but you named it users. This one-word mistake breaks the migration. If you've worked with relational databases, you’ve probably run into this exact thing. Just Ask a GitHub Copilot: Instead of troubleshooting manually, open Copilot Chat and ask: “My migration fails because posts.user_id references a missing user table. Can you fix the foreign key?” Copilot understands what you're asking. It reads the context and suggests the fix: CREATE TABLE posts ( id UUID PRIMARY KEY, title TEXT, user_id UUID REFERENCES users(id) ); It even explains what changed, so you learn along the way. Wait — how does Copilot know what I mean? GitHub Copilot is smart enough to understand your code, your errors, and even what you’re asking in plain English. It doesn’t directly connect to GibsonAI. You’ll use the GibsonAI CLI for that, but Copilot helps you figure things out and fix your code faster. Validating with GibsonAI Once Copilot gives you the fixed migration, it’s time to test it. Run: gibson validate This checks your migration and schema consistency. When you're ready to apply it, just run: gibson deploy GibsonAI handles the rest so no broken chains, no surprises. Why This Works Manual debugging of migrations is frustrating and error prone. GibsonAI with GitHub Copilot: Eliminates guesswork in debugging You don’t need to Google every error Reduces time to fix production schema issues You stay in one tool: VS Code You learn while debugging Whether you're a student learning SQL or a developer on a fast moving team, this setup helps you recover faster and ship safer. Fixing migrations used to be all trial and error, digging through files and hoping nothing broke. It was time-consuming and stressful. Now with GitHub Copilot and GibsonAI, fixing issues is fast and simple. Copilot helps you write and correct migrations. GibsonAI lets you validate and deploy with confidence. So next time your migration fails, don’t panic. Just describe the issue to GitHub Copilot, run a quick check with GibsonAI, and get back to building. Ready to try it yourself? Sign up atgibsonai.com Want to Go Further? If you’re ready to explore more powerful workflows with GibsonAI, here are two great next steps: GibsonAI MCP Server – Enable Copilot Agent Mode to integrate schema intelligence directly into your dev environment. Automatic PR Creation for Schema Changes – The in-depth guide on how to automate pull requests for database updates using GibsonAI. Want to Know More About GitHub Copilot? Explore these resources to get the most out of Copilot: Get Started with GitHub Copilot Introduction to prompt engineering with GitHub Copilot GitHub Copilot Agent Mode GitHub Copilot Customization Use GitHub Copilot Agent Mode to create a Copilot Chat application in 5 minutes Deploy Your First App Using GitHub Copilot for Azure: A Beginner’s Guide That's it, folks! But the best part? You can become part of a thriving community of learners and builders by joining the Microsoft Student Ambassadors Community. Connect with like minded individuals, explore hands-on projects, and stay updated with the latest in cloud and AI. 💬 Join the community on Discord here and explore more benefits on the Microsoft Learn Student Hub.474Views2likes2Comments
CampusSphere: Building the Future of Campus AI with Microsoft's Agentic Framework
Project Overview We are a team of Imperial College Students committed to improving campus life through innovative multi-agent solutions. CampusSphere leverages Microsoft Azure AI capabilities to automate core university campus services. We created an end-to-end solution that allows both students and staff to access a multi-agent framework for room/gym booking, attendance tracking, calendar management, IoT monitoring and more. 🔭 Our Initial Vision: Reimagining Campus Technology When our team at Imperial College London embarked on the CampusSphere project as part of Microsoft's Agentic Campus initiative, we had one clear ambition: to create an intelligent campus ecosystem that would fundamentally change how students, faculty, and staff interact with university services. The inspiration came from a simple observation—despite living in an age of advanced AI, campus technology remained frustratingly fragmented. Students juggled multiple portals for course registration, room booking, dining services, and academic support. Faculty members navigated separate systems for teaching, research, and administrative tasks. The result? Countless hours wasted on mundane navigation tasks that could be better spent on learning, teaching, and innovation. Our vision was ambitious: create a single, intelligent interface that could understand natural language, anticipate user needs, and seamlessly integrate with existing campus infrastructure. We didn't just want to build another campus app—we wanted to demonstrate how Microsoft's agentic AI technologies could create a truly intelligent campus companion. 🧠 Enter CampusSphere CampusSphere is an intelligent campus assistant made up of multiple AI agents, each with a specific domain of expertise — all communicating seamlessly through a centralized architecture. Think of it as a digital concierge for campus life, where your calendar, attendance, IoT data, and facility bookings are coordinated by specialized GPT-powered agents. Here’s what we built: TriageAgent – the brain of the system, using Retrieval-Augmented Generation (RAG) to understand user intent CalendarAgent – handles scheduling, bookings, and reminders AttendanceAgent – tracks check-ins automatically IoTAgent – monitors real-time sensor data from classrooms and labs GymAgent – manages access and reservations for sports facilities 30+ MCP Tools – perform SQL queries, scrape web data, and connect with external APIs All of this is built on Microsoft Azure AI, Semantic Kernel, and Model Context Protocol (MCP) — making it scalable, secure, and lightning fast. 🖥️ The Tech Stack Our Azure-powered architecture showcases a modular and scalable approach to real-time data processing and intelligent agent coordination. The frontend is built using React with a Vite development server, providing a fast and responsive user interface. When users submit a prompt, it travels to a Flask backend server acting as the Triage agent, which intelligently delegates tasks to a FastAPI agent service. This FastAPI service asynchronously communicates with individual agents and handles responses efficiently. Complex queries are routed to MCP Tools, which interact with the CosmosDB-powered Campus Database. Simultaneously, real-time synthetic IoT data is pushed into the database via Azure Function Apps and Azure IoT Hub. Authentication is securely managed: users log in through the frontend, receive a token from the database API server, and use it for authorized access to MCP services, with permissions enforced based on user roles using our custom MCP server implementation. This robust architecture enables seamless integration, real-time data flow, and secure multi-agent collaboration across Azure services. Our system leverages a multi-agent architecture designed to intelligently coordinate task execution across specialized services. At the core is the TriageAgent, which uses Retrieval-Augmented Generation (RAG) to interpret user prompts, enrich them with relevant context, and determine the optimal response path. Based on the nature of the request, it may handle the response directly, seek clarification, or delegate tasks to specific agents via FastAPI. Each specialized agent has a clearly defined role: AttendanceAgent: Interfaces with CosmosDB-backed FastAPI endpoints to check student attendance, using filters like event name, student ID, or date. IoTAgent: Monitors room conditions (e.g., temperature, CO₂ levels) and flags anomalies using real-time data from Azure IoT Hub, processed via FastAPI. CalendarAgent: Handles scheduling, availability checks, and event creation by querying or updating CosmosDB through FastAPI. Future integration with Microsoft Graph API is planned for direct calendar syncing. Gym Slot Agent: Checks available times for gym sessions using dedicated MCP tools. The triage agent serves as the orchestrator, breaking down complex requests (like "Book a gym session") into subtasks. It consults relevant agents (e.g., calendar and gym slot agents), merges results, and then confirms the final action with the user. This distributed and asynchronous workflow reduces backend load and enhances both responsiveness and reliability of the system. 🔮 What’s Next? Integrating CampusSphere with live systems via Microsoft OAuth is crucial for enhancing its capabilities. This integration will grant the agent authenticated access to a wider range of student data, moving beyond synthetic datasets. This expanded access to real-world information will enable deeply personalized advice, such as tailored course selection, scholarship recommendations, event suggestions, and deadline reminders, transforming CampusSphere into a sophisticated, proactive personal assistant. 🤝Meet the Team Behind CampusSphere Our success stemmed from a diverse team of innovators who brought together expertise from multiple domains: Benny Liu - https://www.linkedin.com/in/zong-benny-liu-393a4621b/ Lucas Ng - https://www.linkedin.com/in/lucas-ng-11b317203/ Lu Ju - https://www.linkedin.com/in/lu-ju/ Bruno Duaso - https://www.linkedin.com/in/bruno-duaso-jimeno-744464262/ Martim Coutinho - https://www.linkedin.com/in/martim-pereira-coutinho-116308233/ Krischad Pourpongpan - https://www.linkedin.com/in/krischadpua/ Yixu Pan - https://www.linkedin.com/in/yixu-pan/ Our collaborative approach enabled us to create a sophisticated agentic AI system that demonstrates the powerful potential of Microsoft's AI technologies in educational environments. 🧑💻 Project Repository: GitHub - Imperial-Microsoft-Agentic-Campus/CampusSphere Contribute to Imperial-Microsoft-Agentic-Campus/CampusSphere development by creating an account on GitHub. github.com Have questions about implementing similar solutions at your institution? Connect with our team members on LinkedIn—we're always excited to share knowledge and collaborate on innovative campus technology projects. 📚Get Started with Microsoft's AI Tools Ready to explore the technologies that made CampusSphere possible? Here are essential resources: Microsoft Semantic Kernel: The core framework for building AI agent orchestration systems. Learn how to create, coordinate, and manage multiple AI agents working together seamlessly. AI Agents for Beginners: A comprehensive guide to understanding and building AI agents from the ground up. Perfect for getting started with agentic AI development. Model Context Protocol (MCP): Learn about the protocol that enables secure connections between AI models and external tools and services—essential for building integrated AI systems. Windows AI Toolkit: Microsoft's toolkit for developing AI applications on Windows, providing local AI model development capabilities and deployment tools. Azure Container Apps: Understand how to deploy and scale containerized AI applications in the cloud, perfect for hosting multi-agent systems. Azure Cosmos DB Security: Essential security practices for managing data in AI applications, covering encryption, access control, and compliance.787Views2likes0CommentsLearn How to Build Smarter AI Agents with Microsoft’s MCP Resources Hub
If you've been curious about how to build your own AI agents that can talk to APIs, connect with tools like databases, or even follow documentation you're in the right place. Microsoft has created something called MCP, which stands for Model‑Context‑Protocol. And to help you learn it step by step, they’ve made an amazing MCP Resources Hub on GitHub. In this blog, I’ll Walk you through what MCP is, why it matters, and how to use this hub to get started, even if you're new to AI development. What is MCP (Model‑Context‑Protocol)? Think of MCP like a communication bridge between your AI model and the outside world. Normally, when we chat with AI (like ChatGPT), it only knows what’s in its training data. But with MCP, you can give your AI real-time context from: APIs Documents Databases Websites This makes your AI agent smarter and more useful just like a real developer who looks up things online, checks documentation, and queries databases. What’s Inside the MCP Resources Hub? The MCP Resources Hub is a collection of everything you need to learn MCP: Videos Blogs Code examples Here are some beginner-friendly videos that explain MCP: Title What You'll Learn VS Code Agent Mode Just Changed Everything See how VS Code and MCP build an app with AI connecting to a database and following docs. The Future of AI in VS Code Learn how MCP makes GitHub Copilot smarter with real-time tools. Build MCP Servers using Azure Functions Host your own MCP servers using Azure in C#, .NET, or TypeScript. Use APIs as Tools with MCP See how to use APIs as tools inside your AI agent. Blazor Chat App with MCP + Aspire Create a chat app powered by MCP in .NET Aspire Tip: Start with the VS Code videos if you’re just beginning. Blogs Deep Dives and How-To Guides Microsoft has also written blogs that explain MCP concepts in detail. Some of the best ones include: Build AI agent tools using remote MCP with Azure Functions: Learn how to deploy MCP servers remotely using Azure. Create an MCP Server with Azure AI Agent Service : Enables Developers to create an agent with Azure AI Agent Service and uses the model context protocol (MCP) for consumption of the agents in compatible clients (VS Code, Cursor, Claude Desktop). Vibe coding with GitHub Copilot: Agent mode and MCP support: MCP allows you to equip agent mode with the context and capabilities it needs to help you, like a USB port for intelligence. When you enter a chat prompt in agent mode within VS Code, the model can use different tools to handle tasks like understanding database schema or querying the web. Enhancing AI Integrations with MCP and Azure API Management Enhance AI integrations using MCP and Azure API Management Understanding and Mitigating Security Risks in MCP Implementations Overview of security risks and mitigation strategies for MCP implementations Protecting Against Indirect Injection Attacks in MCP Strategies to prevent indirect injection attacks in MCP implementations Microsoft Copilot Studio MCP Announcement of the Microsoft Copilot Studio MCP lab Getting started with MCP for Beginners 9 part course on MCP Client and Servers Code Repositories Try it Yourself Want to build something with MCP? Microsoft has shared open-source sample code in Python, .NET, and TypeScript: Repo Name Language Description Azure-Samples/remote-mcp-apim-functions-python Python Recommended for Secure remote hosting Sample Python Azure Functions demonstrating remote MCP integration with Azure API Management Azure-Samples/remote-mcp-functions-python Python Sample Python Azure Functions demonstrating remote MCP integration Azure-Samples/remote-mcp-functions-dotnet C# Sample .NET Azure Functions demonstrating remote MCP integration Azure-Samples/remote-mcp-functions-typescript TypeScript Sample TypeScript Azure Functions demonstrating remote MCP integration Microsoft Copilot Studio MCP TypeScript Microsoft Copilot Studio MCP lab You can clone the repo, open it in VS Code, and follow the instructions to run your own MCP server. Using MCP with the AI Toolkit in Visual Studio Code To make your MCP journey even easier, Microsoft provides the AI Toolkit for Visual Studio Code. This toolkit includes: A built-in model catalog Tools to help you deploy and run models locally Seamless integration with MCP agent tools You can install the AI Toolkit extension from the Visual Studio Code Marketplace. Once installed, it helps you: Discover and select models quickly Connect those models to MCP agents Develop and test AI workflows locally before deploying to the cloud You can explore the full documentation here: Overview of the AI Toolkit for Visual Studio Code – Microsoft Learn This is perfect for developers who want to test things on their own system without needing a cloud setup right away. Why Should You Care About MCP? Because MCP: Makes your AI tools more powerful by giving them real-time knowledge Works with GitHub Copilot, Azure, and VS Code tools you may already use Is open-source and beginner-friendly with lots of tutorials and sample code It’s the future of AI development connecting models to the real world. Final Thoughts If you're learning AI or building software agents, don’t miss this valuable MCP Resources Hub. It’s like a starter kit for building smart, connected agents with Microsoft tools. Try one video or repo today. Experiment. Learn by doing and start your journey with the MCP for Beginners curricula.3.9KViews2likes2Comments
Agentic Mentor: A Specification-Driven, Multi-Agent Learning Tool
Project Overview Rather than relying on the model to know when the student understands, we built a pipeline where progress itself is gated: a student cannot move forward until they can demonstrate they understood what was just built. And rather than depending on commercial, token-billed APIs to make this teaching possible, the system is designed to run on locally hosted or free-tier models, keeping it accessible to students and institutions alike. As our contribution to Microsoft, we've handed over the full public repository behind Agentic Mentor. Given how central token-based services have become to software development, we see real potential for this approach in initiatives like GitHub Education, where affordable, agentic tools for students matter. In this post, we'll walk through what motivated the project, how Agentic Mentor works under the hood, and what we learned putting it to the test on a real piece of university coursework. The Project Journey This project was completed over three months. The first few weeks were spent on background research and requirements elicitation. We reviewed the literature on AI-assisted learning, specification-driven development and prompt ambiguity, elicited functional and non-functional requirements from our client supervisor at Microsoft, Lee Stott, and our academic supervisors, and broke the work into components we could build and test independently. This told us what was realistically achievable in the time we had, and which features were core to the tool rather than desirable extras. Implementation was coordinated through GitHub, with the team meeting daily to keep parallel work in sync and weekly meetings with both our supervisors and our client to report progress and check we were still building the right thing. We worked this way because the shape of the tool was still settling once implementation began, and that frequency of contact meant a wrong assumption surfaced in days rather than weeks. The most consequential decision of the project came out of those conversations. Agentic Mentor had been proposed as an assessment tool, but the AI does not write the assessment brief, so it cannot be relied on to read it as the academic intended, and grading on top of that reading would carry the model's misunderstanding into a student's mark. We pivoted to a learning tool, and the design of the pipeline followed from there. The final month went on completing both interfaces and evaluating the system, first against SpecBench as a correctness check, then against a real master's-level coursework. Two problems surfaced. Our GPU infrastructure went offline, so we moved to free-tier cloud models and scheduled runs around quota resets. And one of the questions the system generated turned out to be subtly wrong, and we had read it and accepted it without question, which is the automation bias we had spent the project writing about. Technical Details Agentic Mentor is built as a multi-agent, specification-driven pipeline. It has four agents; Research, Ingestion, Mentoring, and Viva. Each agent was implemented using the Microsoft Agent Framework. We chose to give each phase its own dedicated agent so that every stage could be equipped with the specific tools its task required, rather than relying on one general-purpose agent to handle the whole assignment. The agents run linearly, with each one writing its output to disk and the orchestrator passing the resulting file paths to the next stage. This design lets a session pause and resume. An overview of Agentic Mentor's architecture is seen in the figure below. Research Agent. This stage grounds the pipeline in external context. It uses GitHub and arXiv MCP servers to gather relevant literature and existing implementations. MCP gave the agent a uniform interface to both sources, meaning further ones could be added later simply by connecting another server, without reworking the agent itself. Ingestion Agent. Built around GitHub SpecKit, an open-source toolkit for spec-driven development, this agent converts the assignment brief and research context into structured specification files. Rather than letting the model resolve ambiguities in the brief on its own, SpecKit's clarification step surfaces unclear points directly to the student, who must answer before the pipeline continues. This choice keeps the student engaged in design decisions rather than letting the model make them silently. Mentoring Agent. This is where the student and the model actually build the project together, phase by phase, with the agent writing code and explaining its reasoning as it goes. Progress is gated: the student cannot move to the next phase until every task is complete, and a short multiple-choice checkpoint has been passed. The checkpoint tests understanding of what was just built rather than simply advancing on request. Viva Agent. Once implementation is complete, this agent interviews the student. Answers are checked against key points prepared in advance, with feedback given after each response and a full transcript saved for later review. How Microsoft's tools shaped the project. The Microsoft Agent Framework was the backbone that made the multi-agent design practical: it let us build four functionally distinct agents that could each carry their own tools and responsibilities while still communicating cleanly through a shared orchestration layer. Together with GitHub SpecKit's structured approach to specification-driven development, these tools gave Agentic Mentor a technical foundation that would have been considerably harder to assemble from scratch, and were central to making the pipeline's phase-gated, specification-first design actually work in practice rather than remaining a concept on paper. Demo This demo video shows an end-to-end demonstration of the VS Code extension of Agentic Mentor. Results and outcomes We evaluated Agentic Mentor in two phases: a benchmark check for basic correctness, followed by a real master's-level coursework that better matched the system's intended use. Phase 1: Code Correctness We used SpecBench to evaluate Agentic Mentor’s code correctness. SpecBench is a benchmark of 30 systems-level programming tasks with pre-existing test suites. We ran six of them using a locally served Qwen3.6-27B model. Our results show that tasks with common structural logic scored well, such as json_parser achieving a 97.7% pass rate. However, more complex tasks performed worse. On crypto_primitives, hallucinations prevented a testable solution being produced at all. This result reflects the limits of a small local model such as Qwen3.6-27B. However, the success of some tasks show that smaller local models have promise. Phase 2: Student Understanding The second phase evaluated the system against a real academic assignment on Test-Driven Development, which the team had previously completed without Agentic Mentor. Claude Sonnet 5 was used to reduce hallucinations and improve reasoning. We combined our own assessment as students with an interview with Jens Krinke, the module leader who set and assessed the coursework. From our perspective, we found that Agentic Mentor made a large, loosely specified project easier to approach, and the questions at each stage required active recall which helped us understand the assignment better. It improved on our original attempt by constructing a synthetic repository with known test–production pairs as concrete acceptance criteria, linking test and production files by co-occurrence in commit history rather than naming conventions, and producing unit test coverage within a properly separated project structure. The assessment of its understanding was less favourable. Jens rated its comprehension as comparable to a typical student's, but no better: it treated commit history as capable of confirming the presence of TDD, when it can only reveal the degree of its absence, and it missed an implicit hint regarding commit size. Lessons Learned Building Agentic Mentor taught our team a great deal about coding agents, local models, and the practical challenges of applying AI in education. These lessons shaped both the tool itself and how we think about deploying AI in learning contexts. Knowing where the tool fits. One of our clearest takeaways was that Agentic Mentor works best on well-specified, undergraduate-level assignments rather than open-ended, research-style coursework. Our evaluation on SpecBench's json_parser task, where the tool achieved a 97.7% pass rate, showed just how effective it can be on concrete, well-bounded problems. Our Test-Driven Development case study showed the same tool struggling once the task demanded interpreting ambiguous or partially hidden objectives. Even so, our own experience using the tool showed genuine improvements in our learning outcomes and even surfaced implementation ideas we hadn't considered ourselves, which reinforced our belief in the promise of agentic learning tools when applied to the right kind of problem. Navigating the local model trade-off. Our extensive experimentation with locally hosted models taught us that there is a trade-off between accessibility and quality. Local models performed well on smaller, simpler tasks, but as task complexity grew, code correctness declined and hallucinations became more frequent. This was a valuable lesson in engineering trade-offs: a fully local, cost-free deployment is achievable in principle, but a genuinely effective one currently depends on access to larger, cloud-hosted models. Rethinking what the tool should be for. Perhaps our biggest shift in thinking came from an idea we abandoned. We originally envisioned Agentic Mentor as an assessment tool, capable of evaluating a student's understanding for official grading. Working through the implementation made clear why that vision doesn't hold up: an AI system that didn't generate the assessment brief itself cannot be guaranteed to interpret an educator's intent correctly. This is a limitation of natural language interpretation that is well documented in the literature we reviewed. Recognizing this early enough to change course was itself a valuable exercise in engineering judgment, and it led us to reposition Agentic Mentor as a learning tool focused on helping students engage with agentic AI, rather than an assessment tool that asks AI to make judgments it isn't equipped to make reliably. Implications for Educators Our experience building and evaluating Agentic Mentor highlighted three critical takeaways for educators looking to integrate AI into their classrooms. Watch out for automation bias. Our academic evaluation revealed that the AI agents occasionally held technical misconceptions, which raised up the risk of automation bias; one of the biggest risks in AI-assisted education. When an AI speaks with absolute confidence, it’s incredibly easy to believe it. If students trust the model's outputs without sufficient questioning, they bypass the critical thinking the coursework was meant to provoke. Educational AI needs built-in friction to force the AI to highlight its own uncertainties and encourage students to question the output. Be careful using AI as an Assessment tool. The discovery of the AI’s technical misconceptions also suggests caution using AI for grading or formal assessment. Because the model can misunderstand core concepts the exact same way a student might, it cannot reliably evaluate student comprehension. This also led us to pivot Agentic Mentor strictly to a learning tool. AI is an excellent tool for supporting student learning through phased tasks, but it is not currently reliable enough to act as an autonomous judge of a student's underlying understanding. Agentic Development is reshaping software engineering. As agentic development reshapes software engineering, educators must shift their focus from teaching students how to write code manually, to teaching them how to prompt coding agents. This includes using practices such as specification-driven development, which reduces AI errors in code by preventing ambiguities in natural language prompts. Future Development The limitations we encountered while building Agentic Mentor point to two clear directions for further development. Both would make the system a more reliable learning tool for students. Validation agent Agentic Mentor currently interprets a project with the same gaps and misconceptions a typical student might bring to it. Because the system presents its output with confidence, those gaps can be passed on unchallenged. We propose extending the pipeline with a validation agent. This component would be dedicated to interrogating the questions and conclusions the system produces. Its purpose would be to introduce a deliberate layer of hesitation, surfacing assumptions explicitly rather than allowing them to reach the student as established fact. The intended outcome is a reduction in automation bias, encouraging students to engage critically with the system's output rather than accepting it uncritically. Integration with academic platforms As long as the system's understanding of an assignment is constrained in the same ways a student's is, it cannot be relied upon to identify a task's critical elements. A future version could accept explicit input from educators, specifying those critical elements in advance along with guidance on how students should be directed through them. This would require Agentic Mentor to move beyond a standalone local tool and integrate with the institution's existing education platform. Such integration would give educators direct control over the system's behaviour, making it both more trustworthy and more productive as a learning aid. Conclusion Agentic Mentor was built to help students learn from their coding coursework rather than simply complete it, embedding the learning process into the structure of the system instead of relying on vibe coding. We found that a model cannot be trusted to be consistently correct. Running on smaller local models trades capability for accessibility. And measuring student understanding is difficult without a large user study. Agentic Mentor nonetheless represents a step towards integrating AI-assisted development into education while preserving student understanding. With adequate guardrails against automation bias, it can serve as an accessible tool that adapts the learning process to the changes AI has brought to software development. Call to Action The challenge of "one-click" AI code generation in education is here to stay, but with Agentic Mentor, we aim to keep students actively engaged in problem-solving rather than bypassing it. We invite you to explore our work and help us build the future of AI in education. Explore the Code: Visit the Agentic Mentor GitHub Repository Run It Your Way: Execute the orchestrator via the CLI (see the main README), or use our custom GUI by running the VS Code Extension (located in the agentic-mentor-extension folder). Tools: Our pipeline is built on the Microsoft Agent Framework for multi-agent routing and GitHub SpecKit to enforce strict Specification-Driven Development. Team Our team involved in developing this project included 6 members. All of us are Masters students at UCL, studying either Software Systems Engineering or Artificial Intelligence and Data Engineering. Mark Connor – Team Leader – Software Engineer GitHub URL: https://github.com/markjconnor LinkedIn URL: http://www.linkedin.com/in/mark-connor2003 Alexander Filippov – Software Engineer GitHub URL: https://github.com/ucabavf LinkedIn URL: https://www.linkedin.com/in/alexander-f-003a5721b Weeraya Hew – Software Engineer GitHub URL: https://github.com/tingwry LinkedIn URL: https://www.linkedin.com/in/weeraya-hew-924a19261 Tanishka Jaikrishnia – Software Engineer GitHub URL: https://github.com/tanishkajaikrishnia LinkedIn URL: https://www.linkedin.com/in/tanishka-jaikrishnia-96b652274/ Pranav Kannan – Software Engineer GitHub URL: https://github.com/pranavk295 LinkedIn URL: https://www.linkedin.com/in/pranav-kannan-0b2a11221 Gabriel Mardakhaev – Software Engineer GitHub URL: https://github.com/gabmardakhaev LinkedIn URL: https://www.linkedin.com/in/gabriel-mardakhaev Special Thanks to Contributors We want to express our deepest gratitude to the following contributors, whose ongoing support and dedication led to the success of this project. Lee Stott, Principal Cloud Advocate Microsoft He Ye, Academic Supervisor, UCL Jens Krinke, Senior Lecturer and Academic Supervisor, UCL 2KViews1like1Comment
Build AI RAG Apps with LangChain, Azure DocumentDB and Microsoft Foundry: Step-by-Step Guide
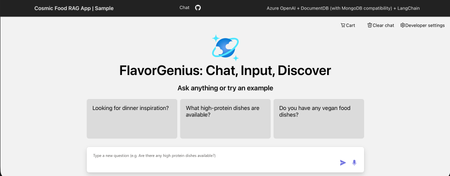
Scenario Imagine you are building your company’s RAG chat application using Microsoft Foundry - Azure OpenAI and orchestrating the flow with LangChain. The chat experience works, but now it needs to be grounded in your company’s data. You generate embeddings and want to store and query them without adding another database or complex sync pipeline. Instead of stitching services together, you use Azure DocumentDB (with MongoDB compatibility) with built-in vector search to store your JSON data and embeddings in one place. You deploy the app to Azure App Service and quickly compare vector search alone versus a full RAG pipeline, sharing it with your team for testing. What will you learn? In this blog, you'll learn to: Create an Azure DocumentDB (with MongoDB compatibility) resource. Create an embeddings and a chat deployment in Microsoft Foundry Azure OpenAI portal. Create an Azure App Service website with continuous deployment from GitHub. Configure Azure App Service application settings to enable communication between Azure resources. Configure GitHub workflow to work successfully. What is the main objective? Build AI Powered RAG Application using LangChain, Microsoft Foundry Azure OpenAI, and Azure DocumentDB (with MongoDB compatibility): Step-by-Step Guide Prerequisites An Azure subscription. If you don’t already have one, you can sign up for an Azure free account. For students, you can use the free Azure for Students offer which doesn’t require a credit card only your school email. A GitHub account. Summary of the steps: Step 1: Create an Azure DocumentDB (with MongoDB compatibility) resource Step 2: Create a Microsoft Foundry - Azure OpenAI resource and Deploy chat and embedding Models Step 3: Create an Azure App Service and Deploy the RAG Chat Application Step 1: Create an Azure DocumentDB (with MongoDB compatibility) resource In this step, you'll: Open the Azure Portal. Create an Azure DocumentDB (with MongoDB compatibility) resource. Open the Azure Portal 1. Visit the Azure Portal https://portal.azure.com in your browser and sign in. Now you are inside the Azure portal! Create a new Azure DocumentDB (with MongoDB compatibility) resource In this step, you create an Azure DocumentDB (with MongoDB compatibility) resource to store your data, vector embedding, and perform vector search. 1. Type documentdb in the search bar at the top of the portal page and select Azure DocumentDB (with MongoDB compatibility) from the available options. 2. Select Create from the toolbar to start provisioning your new cluster. 3. Add the following information to create a resource: What Value Subscription Use your preferred subscription. It's advised to use the same subscription across all the resources that communicate with each other on Azure. Resource group Select Create new to create a new resource group. Enter a unique name for the resource group. Cluster name Enter a globally unique name. Location Select a region close to you for the best response time. For example, Select UK South. MongoDB version Select the latest available version of MongoDB 4. Select Configure to configure your cluster tier. 5. Add the following information to configure the cluster tier. You can scale it up later: What Value Cluster tier Select M25 tier, 2 (Burstable) vCores. Storage Select 32 GiB. 6. Select Save. 7. Enter the cluster Admin Username and Password and store them in a secure location. 8. Select Next to configure the networking settings. 9. Select Allow Public Access from Azure services and resources within the Azure to this cluster. 10. Select Add current IP address to the firewall rules to allow local access to the cluster. 11. Select Review + create. 12. Confirm your configuration settings and select Create to start provisioning the resource. Note: The cluster creation can take up to 10 minutes. It's recommended to move on with the rest of the steps and get back to it later. Step 2: Create a Microsoft Foundry - Azure OpenAI resource and Deploy chat and embedding Models In this step, you'll: Create a Microsoft Foundry Azure OpenAI resource. Create chat and embedding model deployments. Create an Azure OpenAI resource In this step, you create an Azure OpenAI Service resource that enables you to interact with different large language models (LLMs). 1. Type openai in the search bar at the top of the portal page and select Azure OpenAI from the available options. 2. Select Create from the toolbar then select Azure OpenAI to provision a new Azure OpenAI resource. 3. Add the following information to create a resource: What Value Subscription Use the same subscription you used to apply for Azure OpenAI access. Resource group Use the resource group you created in the previous step. Region Select a region close to you for the best response time. For example, Select UK South. Name Enter a globally unique name. Pricing tier Select S0. Currently, this is the only available pricing tier. 4. Now that the basic information is added, select Next to confirm your details and proceed to the next page. 5. Select Next to confirm your network details. 6. Select Next to confirm your tag details. 7. Confirm your configuration settings and select Create to start provisioning the resource. Wait for the deployment to finish. 8. After the deployment finishes, select Go to resource to inspect your created resource. Here, you can manage your resource and find important information like the endpoint URL and API keys. Create chat and embedding model deployments In this step, you create an Azure OpenAI embedding model deployment and a chat model deployment. Creating a deployment on your previously provisioned resource allows you to generate text embeddings (i.e. numerical representation for text) and have a natural language conversation with your data. 1. Select Go to Foundry portal from the toolbar to open the studio. 2. Select Deployments from the Shared resources left side menu to go to the deployments tab. 3. Select + Deploy model from the toolbar then select Deploy base model from the options. A Deploy model window opens. 4. Type gpt-4o-mini to search for the model then select it then select Use model. 5. Select Continue with existing setup to proceed to next step. 6. Refresh page and repeat previous steps to select the model then select Confirm. 7. Review selected options then select Deploy. 8. Select + Deploy model from the toolbar then select Deploy base model from the options. A Deploy model window opens. 9. Type text-embedding-3-small to search for the model then select it then select Confirm. 10. Review selected options then select Deploy. Step 3: Create an Azure App Service and Deploy the RAG Chat Application In this step, you'll: Fork the sample repository on GitHub. Create an Azure App Service resource with a deployment from GitHub. Modify Azure App Service Application settings in the Azure portal. Configure the workflow to deploy your application from GitHub. Test the website before and after adding the data. Fork the Sample Repository on GitHub In this step, you create a copy from the source code on your GitHub account to be able to edit it and use it later. 1. Visit the sample github.com/Azure-Samples/Cosmic-Food-RAG-app in your browser and sign in. 2. Select Fork from the top of the sample page. 3. Select an owner for the fork then, select Create fork. Create an Azure App Service resource with a deployment from GitHub In this step, you create an Azure App service resource and connect it with your GitHub account to deploy a Python application. 1. Type app service in the search bar at the top of the portal page and select App Services from the available options. 2. Select Create Web App from the toolbar to start provisioning a new web application. 3. Add the following information to fill in the basic configuration of the application: What Value Subscription Use the same subscription you used to apply for Azure OpenAI access. Resource group Use the same resource group you created before. Name Enter a unique name for your website. For example, cosmic-food-rag. Publish? Select Code. This option specifies whether your deployment consists of code or a container. Runtime stack Select Python 3.12. Operating System Select Linux. Region Select UK South. This is the region where the rest of the resources you created reside. 4. Add the following information to create the app service plan. You can scale it up later: What Value Linux Plan Select a pre-existing plan or create a new plan. Pricing Plan Select Basic B1. 5. Select Deployment from the toolbar to move to the deployment configuration tab. 6. Add the following information to enable continuous deployment from GitHub: What Value Continuous deployment Select Enable. GitHub account Select your GitHub account. Organization Select your organization. If you are using your personal account then select it. Repository Select Cosmic-Food-RAG-app. Branch Select main. 7. Select Review + create. 8. Confirm your configuration settings and select Create to start provisioning the resource. Wait for the deployment to finish. 9. After the deployment finishes, select Go to resource to inspect your created resource. Here, you can manage your resource and find important information like the application settings and logs. Modify Azure App service Application settings in the Azure portal In this step, you configure the Application settings to make the website able to communicate with other cloud resources. 1. In the Web App resource, select Environment variables from the left side menu. 2. Select + Add to add new environment variables to the function configuration. 3. Add the following names and values one by one and select Ok. Make sure to add your own values. These application settings are for the Azure OpenAI resources that you created: What Value OPENAI_API_VERSION 2024-10-21 AZURE_OPENAI_CHAT_DEPLOYMENT_NAME gpt-4o-mini AZURE_OPENAI_CHAT_MODEL_NAME gpt-4o-mini AZURE_OPENAI_EMBEDDINGS_DEPLOYMENT_NAME text-embedding-3-small AZURE_OPENAI_EMBEDDINGS_MODEL_NAME text-embedding-3-small AZURE_OPENAI_EMBEDDINGS_DIMENSIONS 1536 AZURE_OPENAI_DEPLOYMENT_NAME <azureOpenAiResourceName> AZURE_OPENAI_ENDPOINT https://<azureOpenAiResourceName>.openai.azure.com/ AZURE_OPENAI_API_KEY <azureOpenAiResourceKey> You can get the Azure OpenAI key from the Azure OpenAI resource page. Select Keys and Endpoint from the Resource Management section and copy any of the available keys. These application settings are for Azure DocumentDB (with MongoDB compatibility): AZURE_COSMOS_USERNAME <documentUsername> AZURE_COSMOS_PASSWORD <documentPassword> AZURE_COSMOS_CONNECTION_STRING mongodb+srv://<user>:<password>@<clusterName>.global.mongocluster.cosmos.azure.com/?tls=true&authMechanism=SCRAM-SHA-256&retrywrites=false&maxIdleTimeMS=120000 You can get the DocumentDB connection string from the Azure DocumentDB (with MongoDB compatibility) resource page. Select Connection strings and copy the connection string. Make sure to replace the user and password with the ones you created. These application settings are new and are used for resources that will be created when the application starts you can use any value for them: AZURE_COSMOS_DATABASE_NAME <documentDatabaseName> ex. CosmicDB AZURE_COSMOS_COLLECTION_NAME <documentContainerName> ex. CosmicFoodCollection AZURE_COSMOS_INDEX_NAME <documentIndexName> ex. CosmicIndex 4. Select Apply to save your newly added environment variables. 5. Select Configuration then Stack settings to edit the application startup command. 6. Type entrypoint.sh in the startup command field then select Apply. Configure the Workflow to deploy your application from GitHub In this step, you modify the GitHub deployment workflow to point to the folder that contains the application. 1. Visit your forked repository on GitHub and notice the failing workflow. 2. Open the workflow file .github/workflows/main_cosmic-food-rag.yml. 3. Open the file and select the pen icon to edit it. 4. Modify line 41 from . to src/. 5. Remove the optional Local Build Section since the application already has tests that cover this part. 6. Add this section to Install Node 22 and build the static frontend. 7. Select Commit changes, and review your commit message and description. Select Commit changes. The final workflow file should look like this: # Docs for the Azure Web Apps Deploy action: https://github.com/Azure/webapps-deploy # More GitHub Actions for Azure: https://github.com/Azure/actions # More info on Python, GitHub Actions, and Azure App Service: https://aka.ms/python-webapps-actions name: Build and deploy Python app to Azure Web App - cosmic-food-rag on: push: branches: - main workflow_dispatch: jobs: build: runs-on: ubuntu-latest permissions: contents: read #This is required for actions/checkout steps: - uses: actions/checkout@v4 - name: Set up Node 22 uses: actions/setup-node@v6 with: node-version: 22 - name: Install Node Packages & Build Static Site run: cd frontend && npm install && npm run build # By default, when you enable GitHub CI/CD integration through the Azure portal, the platform automatically sets the SCM_DO_BUILD_DURING_DEPLOYMENT application setting to true. This triggers the use of Oryx, a build engine that handles application compilation and dependency installation (e.g., pip install) directly on the platform during deployment. Hence, we exclude the antenv virtual environment directory from the deployment artifact to reduce the payload size. - name: Upload artifact for deployment jobs uses: actions/upload-artifact@v4 with: name: python-app path: | src/ !antenv/ # 🚫 Opting Out of Oryx Build # If you prefer to disable the Oryx build process during deployment, follow these steps: # 1. Remove the SCM_DO_BUILD_DURING_DEPLOYMENT app setting from your Azure App Service Environment variables. # 2. Refer to sample workflows for alternative deployment strategies: https://github.com/Azure/actions-workflow-samples/tree/master/AppService deploy: runs-on: ubuntu-latest needs: build permissions: id-token: write #This is required for requesting the JWT contents: read #This is required for actions/checkout steps: - name: Download artifact from build job uses: actions/download-artifact@v4 with: name: python-app - name: Login to Azure uses: azure/login@v2 with: client-id: ${{ secrets.AZUREAPPSERVICE_CLIENTID_5672547ED09F46D59DD431ACF5A29F28 }} tenant-id: ${{ secrets.AZUREAPPSERVICE_TENANTID_0059913572C8467882D3999D0E0DD5B8 }} subscription-id: ${{ secrets.AZUREAPPSERVICE_SUBSCRIPTIONID_7C42E3352C5D47F084CB0CD14F549D27 }} - name: 'Deploy to Azure Web App' uses: azure/webapps-deploy@v3 id: deploy-to-webapp with: app-name: 'cosmic-food-rag' slot-name: 'Production' 8. Select Actions to review the workflow run status. Test the website before and After adding the data In this step, you test the application before adding the data, add the data, and test again. 1. Select the workflow name to open it and get the website URL. 2. Select any of the suggested messages or type your own and it should respond with No results found. 3. Navigate to your Azure App Service resource page and select SSH then select Go to open a new SSH page. 4. In the SSH terminal, run these commands: uv sync --active uv run --active ./scripts/add_data.py --file="./data/food_items.json" 5. Navigate back to the live website and type in the chat message Do you have any vegan food dishes? and it should respond with the correct answer now. Congratulations!! You successfully built the full application. Clean Up Once you finish experimenting on Microsoft Azure you might want to delete the resources to not consume any more money from your subscription. You can delete the resource group and it will delete everything inside it or delete the resources one by one that's totally up to you. Conclusion Congratulations! You've learned how to create an Azure DocumentDB (with MongoDB compatibility) cluster, how to create a Microsoft Foundry - Azure OpenAI resource, how to deploy an embedding model and a chat model from the Foundry portal, how to create an Azure App Service and configure continuous deployment with GitHub, and how to modify application settings to enable the communication across Azure resources. By using these technologies, you can build a RAG chat application with the option to perform vector search too over your own data and provide grounded (relevant) responses. Next steps Documentation Azure OpenAI in Microsoft Foundry models Understand embeddings in Azure OpenAI in Microsoft Foundry Models (classic) Azure DocumentDB (with MongoDB compatibility) documentation Integrated vector store in Azure DocumentDB LangChain Python documentation Training Content Develop generative AI apps in Azure Found this useful? Share it with others and follow me to get updates on: Twitter (twitter.com/john00isaac) LinkedIn (linkedin.com/in/john0isaac) Feel free to share your comments and/or inquiries in the comment section below.. See you in future demos!591Views1like1Comment