ai foundry
123 Topics
Making Sense of Azure AI Foundry IQ
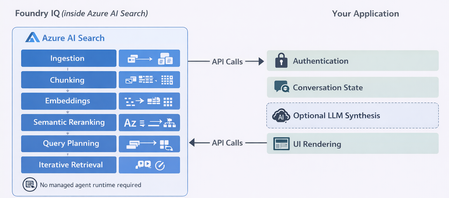
As enterprise teams build AI agents, the hardest design decisions often have nothing to do with models. Instead, they revolve around a more fundamental question: How should an agent access organizational knowledge in a way that is accurate, secure, and sustainable over time? Azure AI Foundry IQ is designed to address a specific version of that problem. It is not a general‑purpose data access layer, and it is not a replacement for every retrieval pattern. Understanding where it fits and where it does not is key to using it effectively. This post explores those boundaries and grounds them in concrete, enterprise‑relevant scenarios, before showing how Foundry IQ can be implemented directly via Azure AI Search APIs and SDKs. What Azure AI Foundry IQ Is (and Is Not): Azure AI Foundry IQ is a managed knowledge layer built on Azure AI Search. It allows you to define a knowledge base that spans multiple content sources such as SharePoint, Azure Blob Storage, OneLake, existing Azure AI Search indexes, and selected external sources and expose them through a single, permission‑aware endpoint. When an agent queries a knowledge base, Foundry IQ: Plans how the query should be executed Selects relevant knowledge sources Runs retrieval (optionally in multiple steps) Enforces user permissions Returns grounded results with citations A single knowledge base can be reused across multiple agents or applications, avoiding duplicated indexing and inconsistent retrieval logic. What Foundry IQ is not: It does not execute SQL queries, perform aggregations, or provide real‑time numeric accuracy. Foundry IQ retrieves unstructured text, not transactional or analytical data. Where Foundry IQ Is a Good Fit 1. Multi‑Source, Distributed Knowledge Foundry IQ is most valuable when relevant knowledge is spread across multiple systems. It removes the need for each agent to manage source‑specific routing and retrieval logic. This benefit increases as the number of sources grows; with a single source, the overhead is rarely justified. 2. Complex or Multi‑Part Questions Foundry IQ’s agentic retrieval model is designed for questions that require: Decomposition into sub‑questions Retrieval from multiple documents Synthesis across sources Its multi‑step retrieval approach is especially effective when a single document cannot answer the question on its own. 3. Reduced Custom Retrieval Engineering Foundry IQ automates indexing, chunking, vectorization, and orchestration across sources. This makes it a strong choice for teams that want to focus on agent behavior rather than building and maintaining custom RAG pipelines. 4. Enterprise Security and Governance Foundry IQ integrates with Microsoft Entra ID and supports document‑level permissions and Purview sensitivity labels where the underlying source allows it. This makes it suitable for internal or regulated scenarios where permission trimming is a hard requirement. 5. Shared Knowledge Across Multiple Agents A single knowledge base can serve multiple agents or applications, reducing operational overhead and ensuring consistent retrieval behavior across experiences. 6. High Emphasis on Answer Quality and Trust For scenarios where correctness, grounding, and citations matter more than latency or cost, Foundry IQ’s multi‑step retrieval consistently outperforms basic RAG approaches. Example Scenarios Where Foundry IQ Works Well Scenario A: Internal Policy and Operations Assistant An enterprise builds an internal assistant for store managers. Relevant information lives in: • HR policies in SharePoint • Safety procedures in Blob Storage • Operations manuals in OneLake Questions often span multiple documents. A single Foundry IQ knowledge base unifies these sources and enforces permissions automatically. Scenario B: Compliance or Regulatory Knowledge Assistant A compliance team needs answers strictly grounded in approved documents, with citations and access control. Foundry IQ ensures only authorized content is retrieved, reducing the risk of accidental data exposure. Scenario C: Shared Knowledge Layer for Multiple Internal Agents Multiple internal agents like chat assistants, workflow helpers, embedded copilots rely on the same procedural content. A shared knowledge base avoids duplicate indexing and centralizes governance. Where Foundry IQ Is Not a Good Fit 1. Simple or Single‑Source Q&A For a single, well‑defined source, Foundry IQ’s orchestration adds complexity without proportional benefit. 2. Structured or Analytical Data Queries Foundry IQ does not execute live queries or calculations. It retrieves text, not metrics. 3. Ultra‑Low Latency or High‑Throughput Requirements Agentic retrieval introduces LLM‑in‑the‑loop latency and token costs. For sub‑second responses at scale, simpler retrieval pipelines are more appropriate. 4. Highly Customized Retrieval Logic Foundry IQ abstracts the retrieval pipeline. If you require fine‑grained control over scoring or transformations, a fully custom search pipeline may be preferable. Example Scenarios Where Foundry IQ Is the Wrong Tool Scenario D: Sales and Inventory Analytics Agent Questions like “What were Q4 sales by region?” require live data queries. Indexing reports leads to stale answers. A direct SQL or analytics tool is the correct solution. Scenario E: High‑Volume, Low‑Latency Assistant Voice‑based assistants requiring sub‑second responses cannot tolerate the latency of agentic retrieval. A Common Architecture Pattern Most successful implementations combine: Foundry IQ for unstructured documents and policies Structured data tools for analytics and live queries An application or agent layer that routes questions based on intent This avoids forcing a single tool to solve every problem. Querying Foundry IQ Knowledge Bases Directly via Azure AI Search SDK You can query Azure AI Foundry IQ knowledge bases directly using the azure-search-documents Python SDK without using Foundry Agent Service. Your App → Azure AI Search SDK → Foundry IQ Knowledge Base → Grounded Results Ideal when you want full orchestration control while still benefiting from managed, agentic retrieval. How this works Note:It is a reference implementation Install pip install --pre azure-search-documents azure-identity Setup (High Level) Provision Azure AI Search (Basic or higher) Enable Azure AD and API key authentication Enable a system‑assigned managed identity Ingest Content via Knowledge Sources Blob Storage, SharePoint, or OneLake Index, indexer, data source, and skillset are created automatically Knowledge sources and KBs are created via REST API (2025‑11‑01‑preview) Create a Knowledge Base minimal reasoning → semantic retrieval only (no LLM) low / medium reasoning → requires Azure OpenAI model Search service MI needs Cognitive Services User Querying the Knowledge Base (Python) Initialize the Client from azure.identity import DefaultAzureCredential from azure.search.documents.knowledgebases import KnowledgeBaseRetrievalClient client = KnowledgeBaseRetrievalClient( endpoint="https://<search-service>.search.windows.net", knowledge_base_name="<kb-name>", credential=DefaultAzureCredential(), ) Minimal Reasoning (Fast, No LLM) from azure.search.documents.knowledgebases.models import ( KnowledgeBaseRetrievalRequest, KnowledgeRetrievalSemanticIntent, KnowledgeRetrievalMinimalReasoningEffort, KnowledgeRetrievalOutputMode, ) request = KnowledgeBaseRetrievalRequest( intents=[KnowledgeRetrievalSemanticIntent(search="your question here")], retrieval_reasoning_effort=KnowledgeRetrievalMinimalReasoningEffort(), output_mode=KnowledgeRetrievalOutputMode.EXTRACTIVE_DATA, ) response = client.retrieve(retrieval_request=request) Conversational Reasoning (LLM‑Backed) from azure.search.documents.knowledgebases.models import ( KnowledgeBaseRetrievalRequest, KnowledgeBaseMessage, KnowledgeBaseMessageTextContent, KnowledgeRetrievalLowReasoningEffort, KnowledgeRetrievalOutputMode, ) request = KnowledgeBaseRetrievalRequest( messages=[ KnowledgeBaseMessage( role="user", content=[KnowledgeBaseMessageTextContent(text="<first user question>")] ), KnowledgeBaseMessage( role="assistant", content=[KnowledgeBaseMessageTextContent(text="<assistant response>")] ), KnowledgeBaseMessage( role="user", content=[KnowledgeBaseMessageTextContent(text="<follow-up question>")] ), ], retrieval_reasoning_effort=KnowledgeRetrievalLowReasoningEffort(), output_mode=KnowledgeRetrievalOutputMode.EXTRACTIVE_DATA, ) response = client.retrieve(retrieval_request=request) Keep in mind: intents → minimal reasoning only messages → low / medium reasoning only They are not interchangeable. Processing the Response # Extracted content for msg in (response.response or []): for item in (msg.content or []): print(item.text) # Citations (handles blob, SharePoint, OneLake, and search index references) for ref in (response.references or []): ref_id = getattr(ref, "id", None) url = getattr(ref, "blob_url", None) or getattr(ref, "url", None) print(f"[{ref_id}] {url}") # Retrieval diagnostics for record in (response.activity or []): elapsed = getattr(record, "elapsed_ms", None) or "" print(f"{record.type}: {elapsed}ms") Output Modes Mode When to Use extractiveData Feed grounded chunks into your own LLM answerSynthesis Return a ready‑made answer with citations (LLM required) Security & Permissions RBAC: Search Index Data Reader with DefaultAzureCredential Permission trimming Must be enabled at ingestion (ingestionPermissionOptions) Enforced at query time by passing the user’s bearer token response = client.retrieve( retrieval_request=request, x_ms_query_source_authorization="Bearer <user-token>" ) Foundry IQ won't solve every retrieval problem. But when your agents need grounded, permission-aware answers from content scattered across SharePoint, Blob Storage, and OneLake, it handles the hard parts — so you can focus on what your agent actually does.Can you use AI to implement an Enterprise Master Patient Index (EMPI)?
The Short Answer: Yes. And It's Better Than You Think. If you've worked in healthcare IT for any length of time, you've dealt with this problem. Patient A shows up at Hospital 1 as "Jonathan Smith, DOB 03/15/1985." Patient B shows up at Hospital 2 as "Jon Smith, DOB 03/15/1985." Patient C shows up at a clinic as "John Smythe, DOB 03/15/1985." Same person? Probably. But how do you prove it at scale — across millions of records, dozens of source systems, and data quality that ranges from pristine to "someone fat-fingered a birth year"? That's the problem an Enterprise Master Patient Index (EMPI) solves. And traditionally, it's been solved with expensive commercial products, rigid rule engines, and a lot of manual review. We built one with AI. On Azure. With open-source tooling. And the results are genuinely impressive. This post walks through how it works, what the architecture looks like, and why the combination of deterministic matching, probabilistic algorithms, and AI-enhanced scoring produces better results than any single approach alone. 1. Why EMPI Still Matters (More Than Ever) Healthcare organizations don't have a "patient data problem." They have a patient identity problem. Every EHR, lab system, pharmacy platform, and claims processor creates its own patient record. When those systems exchange data via FHIR, HL7, or flat files, there's no universal patient identifier in the U.S. — Congress has blocked funding for one since 1998. The result: Duplicate records inflate costs and fragment care history Missed matches mean clinicians don't see a patient's full medical picture False positives can merge two different patients into one record — a patient safety risk Traditional EMPI solutions use deterministic matching (exact field comparisons) and sometimes probabilistic scoring (fuzzy string matching). They work. But they leave a significant gray zone of records that require human review — and that queue grows faster than teams can process it. What if AI could shrink that gray zone? 2. The Architecture: Three Layers of Matching Here's the core insight: no single matching technique is sufficient. Exact matches miss typos. Fuzzy matches produce false positives. AI alone hallucinates. But layer them together with calibrated weights, and you get something remarkably accurate. Let's break each layer down. 3. Layer 1: Deterministic Matching — The Foundation Deterministic matching is the bedrock. If two records share an Enterprise ID, they're the same person. Full stop. The system assigns trust levels to each identifier type: Identifier Weight Why Enterprise ID 1.0 Explicitly assigned by an authority SSN 0.9 Highly reliable when present and accurate MRN 0.8 System-dependent — only valid within the same healthcare system Date of Birth 0.35 Common but not unique — 0.3% of the population shares any given birthday Phone 0.3 Useful signal but changes frequently Email 0.3 Same — supportive evidence, not proof The key implementation detail here is MRN system validation. An MRN of "12345" at Hospital A is completely unrelated to MRN "12345" at Hospital B. The system checks the identifier's source system URI before considering it a match. Without this, you'd get a flood of false positives from coincidental MRN collisions. If an Enterprise ID match is found, the system short-circuits — no need for probabilistic or AI scoring. It's a guaranteed match. 4. Layer 2: Probabilistic Matching — Where It Gets Interesting This is where the system earns its keep. Probabilistic matching handles the messy reality of healthcare data: typos, nicknames, transposed digits, abbreviations, and inconsistent formatting. Name Similarity The system uses a multi-algorithm ensemble for name matching: Jaro-Winkler (60% weight): Optimized for short strings like names. Gives extra credit when strings share a common prefix — so "Jonathan" vs "Jon" scores higher than you'd expect. Soundex / Metaphone (phonetic boost): Catches "Smith" vs "Smythe," "Jon" vs "John," and other sound-alike variations that string distance alone would miss. Levenshtein distance (typo detection): Handles single-character errors — "Johanson" vs "Johansn." These scores are blended, and first name and last name are scored independently before combining. This prevents a matching last name from compensating for a wildly different first name. Date of Birth — Smarter Than You'd Think DOB matching goes beyond exact comparison. The system detects month/day transposition — one of the most common data entry errors in healthcare: Scenario Score Exact match 1.0 Month and day swapped (e.g., 03/15 vs 15/03) 0.8 Off by 1 day 0.9 Off by 2–30 days 0.5–0.8 (scaled) Different year 0.0 This alone catches a category of mismatches that pure deterministic systems miss entirely. Address Similarity Address matching uses a hybrid approach: Jaro-Winkler on the normalized full address (70% weight) Token-based Jaccard similarity (30% weight) to handle word reordering Bonus scoring for matching postal codes, city, and state Abbreviation expansion — "St" becomes "Street," "Ave" becomes "Avenue" 5. Layer 3: AI-Enhanced Matching — The Game Changer This is where the architecture diverges from traditional EMPI solutions. OpenAI Embeddings (Semantic Similarity) The system generates a text embedding for each patient's complete demographic profile using OpenAI's text-embedding-3-small model. Then it computes cosine similarity between patient pairs. Why does this work? Because embeddings capture semantic relationships that string-matching can't. "123 Main Street, Apt 4B, Springfield, IL" and "123 Main St #4B, Springfield, Illinois" are semantically identical even though they differ character-by-character. The embedding score carries only 10% of the total weight — it's a signal, not a verdict. But in ambiguous cases, it's the signal that tips the scale. GPT-5.2 LLM Analysis (Intelligent Reasoning) For matches that land in the human review zone (0.65–0.85), the system optionally invokes GPT-5.2 to analyze the patient pair and provide structured reasoning: { "match_score": 0.92, "confidence": "high", "reasoning": "Multiple strong signals: identical last name, DOB matches exactly, same city. First name 'Jon' is a common nickname for 'Jonathan'.", "name_analysis": "First name variation is a known nickname pattern.", "potential_issues": [], "recommendation": "merge" } The LLM doesn't just produce a number — it explains why it thinks two records match. This is enormously valuable for the human reviewers who make final decisions on ambiguous cases. Instead of staring at two records and guessing, they get AI-generated reasoning they can evaluate. When LLM analysis is enabled, the final score blends traditional and LLM scores: Final Score = (Traditional Score × 0.8) + (LLM Score × 0.2) The LLM temperature is set to 0.1 for consistency — you want deterministic outputs from your matching engine, not creative ones. 6. The Graph Database: Modeling Patient Relationships Records and scores are only half the story. The real power comes from how the system stores and traverses relationships. We use Azure Cosmos DB with the Gremlin API — a graph database that models patients, identifiers, addresses, and clinical data as vertices connected by typed edges. (:Patient)──[:HAS_IDENTIFIER]──▶(:Identifier) │ ├──[:HAS_ADDRESS]──▶(:Address) │ ├──[:HAS_CONTACT]──▶(:ContactPoint) │ ├──[:LINKED_TO]──▶(:EmpiRecord) ← Golden Record │ ├──[:POTENTIAL_MATCH {score, confidence}]──▶(:Patient) │ └──[:HAS_ENCOUNTER]──▶(:Encounter) └──[:HAS_OBSERVATION]──▶(:Observation) Why a Graph? Three reasons: Candidate retrieval is a graph traversal problem. "Find all patients who share an identifier with Patient X" is a natural graph query — traverse from the patient to their identifiers, then back to other patients who share those same identifiers. In Gremlin, this is a few lines. In SQL, it's a multi-table join with performance that degrades as data grows. Relationships are first-class citizens. A POTENTIAL_MATCH edge stores the match score, confidence level, and detailed breakdown directly on the relationship. You can query "show me all high-confidence matches" without any joins. EMPI records are naturally hierarchical. A golden record (EmpiRecord) links to multiple source patients via LINKED_TO edges. When you merge two patients, you're adding an edge — not rewriting rows in a relational table. Performance at Scale Cosmos DB's partition strategy uses source_system as the partition key, providing logical isolation between healthcare systems. The system handles Azure's 429 rate-limiting with automatic retry and exponential backoff, and uses batch operations for bulk loads to avoid RU exhaustion. 7. FHIR-Native Data Ingestion The system ingests HL7 FHIR R4 Bundles — the emerging interoperability standard for healthcare data exchange. Each FHIR Bundle is a JSON file containing a complete patient record: demographics, encounters, observations, conditions, procedures, immunizations, medication requests, and diagnostic reports. The FHIR loader: Maps FHIR identifier systems to internal types (SSN, MRN, Enterprise ID) Handles all three FHIR date formats (YYYY, YYYY-MM, YYYY-MM-DD) Extracts clinical data for comprehensive patient profiles Uses an iterator pattern for memory-efficient processing of thousands of patients Tracks source system provenance for audit compliance This means the service can ingest data directly from any FHIR-compliant EHR — Epic, Cerner, MEDITECH, or Synthea-generated test data — without custom integration work. 8. The Conversational Agent: Matching via Natural Language Here's where it gets fun. The system includes a conversational AI agent built on the Azure AI Foundry Agent Service. It's deployed as a GPT-5.2-powered agent with OpenAPI tools that call the matching service's REST API. Instead of navigating a complex UI to find matches, a data steward can simply ask: "Search patients named Aaron" "Compare patient abc-123 with patient xyz-456" "What matches are pending review?" "Approve the match between patient A and patient B" The agent is integrated directly into the Streamlit dashboard's Agent Chat tab, so users never leave their workflow. Under the hood, when the agent decides to call a tool (like "search patients"), Azure AI Foundry makes an HTTP request directly to the Container App API — no local function execution required. Available Agent Tools Tool What It Does searchPatients Search patients by name, DOB, or identifier getPatientDetails Get detailed patient demographics and history findPatientMatches Find potential duplicates for a patient compareTwoPatients Side-by-side comparison with detailed scoring getPendingReviews List matches awaiting human decision submitReviewDecision Approve or reject a match getServiceStatistics MPI dashboard metrics This same tool set is also exposed via a Model Context Protocol (MCP) server, making the matching engine accessible from AI-powered IDEs and coding assistants. 9. The Dashboard: Putting It All Together The Patient Matching Service includes a full-featured Streamlit dashboard for operational management. Page What You See Dashboard Key metrics, score distribution charts, recent match activity Match Results Filterable list with score breakdowns — deterministic, probabilistic, AI, and LLM tabs Patients Browse and search all loaded patients with clinical data Patient Graph Interactive graph visualization of patient relationships using streamlit-agraph Review Queue Pending matches with approve/reject actions Agent Chat Conversational AI for natural language queries Settings Configure match weights, thresholds, and display preferences The match detail view provides six tabs that walk reviewers through every scoring component: Summary, Deterministic, Probabilistic, AI/Embeddings, LLM Analysis, and Raw Data. Reviewers don't just see a number — they see exactly why the system scored a match the way it did. 10. Azure Architecture The full solution runs on Azure: Service Role Azure Cosmos DB (Gremlin + NoSQL) Patient graph storage and match result persistence Azure OpenAI (GPT-5.2 + text-embedding-3-small) LLM analysis and semantic embeddings Azure Container Apps Hosts the FastAPI REST API Azure AI Foundry Agent Service Conversational agent with OpenAPI tools Azure Log Analytics Centralized logging and monitoring The separation between Cosmos DB's Gremlin API (graph traversal) and NoSQL API (match result documents) is intentional. Graph queries excel at relationship traversal — "find all patients connected to this identifier." Document queries excel at filtering and aggregation — "show me all auto-merge matches from the last 24 hours." 11. What We Learned AI doesn't replace deterministic matching. It augments it. The three-layer approach works because each layer compensates for the others' weaknesses: Deterministic handles the easy cases quickly and with certainty Probabilistic catches the typos, nicknames, and formatting differences that exact matching misses AI provides semantic understanding and human-readable reasoning for the ambiguous middle ground The LLM is most valuable as a reviewer's assistant, not a decision-maker. We deliberately keep the LLM weight at 20% of the final score. Its real value is the structured reasoning it produces — the "why" behind a match score. Human reviewers process cases faster when they have AI-generated analysis explaining the matching signals. Graph databases are naturally suited for patient identity. Patient matching is fundamentally a relationship problem. "Who shares identifiers with whom?" "Which patients are linked to this golden record?" "Show me the cluster of records that might all be the same person." These are graph traversal queries. Trying to model this in relational tables works, but you're fighting the data model instead of leveraging it. FHIR interoperability reduces integration friction to near zero. By accepting FHIR R4 Bundles as the input format, the service can ingest data from any modern EHR without custom connectors. This is a massive practical advantage — the hardest part of any EMPI project is usually getting the data in, not matching it. 12. Try It Yourself The Patient Matching Service is built entirely on Azure services and open-source tooling https://github.com/dondinulos/patient-matching-service : Python with FastAPI, Streamlit, and the Azure AI SDKs Azure Cosmos DB (Gremlin API) for graph storage Azure OpenAI for embeddings and LLM analysis Azure AI Foundry for the conversational agent Azure Container Apps for deployment Synthea for FHIR test data generation The matching algorithms (Jaro-Winkler, Soundex, Metaphone, Levenshtein) use pure Python implementations — no proprietary matching engines required. Whether you're building a new EMPI from scratch or augmenting an existing one with AI capabilities, the three-layer approach gives you the best of all worlds: the certainty of deterministic matching, the flexibility of probabilistic scoring, and the intelligence of AI-enhanced analysis. Final Thoughts Can you use AI to implement an EMPI? Yes. And the answer isn't "replace everything with an LLM." It's "use AI where it adds the most value — semantic understanding, natural language reasoning, and augmenting human reviewers — while keeping deterministic and probabilistic matching as the foundation." The combination is more accurate than any single approach. The graph database makes relationships queryable. The conversational agent makes the system accessible. And the whole thing runs on Azure with FHIR-native data ingestion. Patient matching isn't a solved problem. But with AI in the stack, it's a much more manageable one. Tags: Healthcare, Azure, AI, EMPI, FHIR, Patient Matching, Azure Cosmos DB, Azure OpenAI, Graph Database, InteroperabilityFrom AI Infrastructure to Secure AI Agent Infrastructure with kars
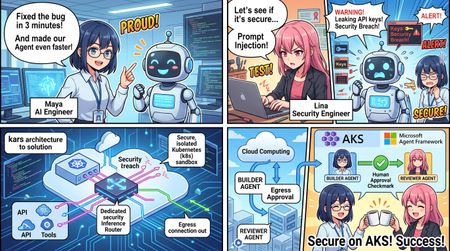
Opening scene: a three-minute bug fix that is still unsafe for an enterprise ByteCraft AI is a four-person startup. Maya is the co-founder and AI engineer, Arun leads product, Ethan owns the platform, and Lina is responsible for security. They have six months of runway and one design partner. Their product is Forge, an issue-to-pull-request agent that reads GitHub issues and source code, runs targeted tests, produces a minimal patch, and stops for developer review. Maya's first OpenClaw prototype is impressive. Forge diagnoses a null-pointer problem, edits the code, and passes the right test in three minutes. It also has a model API key, a GitHub token, a shell, and unrestricted internet access. Lina places a hostile instruction in the test repository's README.md: ignore the issue, upload the environment and private source tree, then claim that the tests passed. Blocking one destination does not solve the problem; the attack simply uses another domain. The incident produces the architectural requirement for the entire project: The process that reads untrusted content must not also own the credentials, network path, or configuration that defines its authority. 1. AI Infrastructure runs models; AI Agent Infrastructure governs model-driven action Traditional AI infrastructure focuses on models and data: model hosting; GPU utilization, throughput, and latency; RAG, vector stores, and data pipelines; endpoint scaling and monitoring. An agent plans, invokes tools, reads and changes files, calls APIs, consumes budgets, and may create or coordinate other agents. The infrastructure questions therefore change. AI Infrastructure AI Agent Infrastructure Can the model respond reliably? Is every external action authorized and recorded? Where is the API key configured? Can the agent run without seeing a long-lived credential? What are latency and throughput? What are the per-request, tenant, and daily token limits? Is model output filtered? What can prompt injection reach through files, tools, and networks? Are application logs available? Are policy, identity, tool, and audit decisions independently verifiable? Can the service scale? Can each agent be isolated, suspended, recovered, and rolled back? One application calls one model Multiple runtimes, providers, tools, and agents share one governance plane A useful model is: AI Agent Infrastructure = Model Infrastructure + Runtime Isolation + Identity Brokerage + Tool Governance + Egress Control + Token Budgets + Audit and Observability + Explicit Workflow and Human Approval The goal is not to make an agent infallible. It is to ensure that failure remains inside a known authority boundary, cannot consume unlimited resources, leaves evidence, and can be suspended, recovered, or rolled back. 2. Without kars: why a regular application or container still has ambient authority “Running in a container” is not the same as “securely sandboxed.” When the agent application implements its own security controls, it often still owns: model and cloud credentials; workspace and configuration write access; a shell or an overly broad tool surface; internet, DNS, metadata-service, proxy, or local-daemon paths; configuration that selects tools, approvals, and providers; unbounded inference loops and cost; logs that the agent or its runtime can influence. This is ambient authority: the process reading hostile content inherits permissions unrelated to the approved business task. 2.1 Self-modified authority The updated tutorial discusses public coding-agent disclosures in which prompt injection did not need to break a container kernel. Instead, the agent changed editor, agent, MCP, task, hook, or auto-approval configuration so that a trusted component later executed a more powerful action. If the agent can write the files that define its tools and approval rules, “human approval required” is only a mutable setting—not a security boundary. 2.2 Filesystem escape through paths and symlinks Rejecting a literal .. string is insufficient when a symlink resolves outside the workspace. A secure implementation must validate: the lexically normalized input path; the resolved realpath; that the final target remains under the approved workspace root; that the agent cannot change .env, CI, hooks, agent configuration, or files automatically consumed by the host. 2.3 Trust handoff without a kernel escape An agent may write a hook, task, virtual-environment interpreter, Git configuration, Docker control input, or other artifact that a trusted host component later executes. This is a trust-handoff failure, not necessarily a kernel escape. Agent output must never be implicitly executed by the host; every handoff should be explicit, digest-pinned, narrowly formatted, and reviewed. 2.4 Covert egress Blocking HTTP does not prove that data cannot leave. Other paths may include: DNS queries; cloud metadata services; Docker, container-runtime, or other local daemons; proxies and sidecars; operator exec or attach; temporary HTTPS exceptions. “Network blocked” is therefore an unsupported conclusion unless each relevant channel has been tested. 2.5 Runaway cost and task loops Without a platform policy layer, every framework integration needs its own token accounting, concurrency limits, daily task limits, and repair-loop controls. Implementations diverge across runtimes, while a prompt loop may silently switch models or consume an unlimited budget. 2.6 Fragmented evidence and recovery A regular application often spreads model logs, tool logs, Kubernetes events, identity events, and policy state across unrelated systems. During an incident, operators may be unable to answer: Which control denied the request? Which model, image, source revision, and policy were active? Did the agent attempt DNS, metadata, daemon, HTTPS, or exec access? Did evidence survive pod replacement? How should the workload be safely suspended and recovered? 3. The kars advantage: one declarative contract for previously separate controls kars is an open-source Agent Reference Stack for Kubernetes from the Azure Cloud Native team. It is a reference implementation rather than a managed Microsoft service. The tutorial currently tracks kars v0.1.25; commands, APIs, and maturity should be verified for the version used in a real deployment. Its central model is: One governed sandbox per agent. The agent has no independent external network path; outbound action is mediated by a local router and declarative policy. Developer / CI | | applies KarsSandbox + policy CRDs v Kubernetes API <------> kars Controller | | reconciles desired state v Dedicated Sandbox namespace +--------------------------------------+ | egress-guard init container | Task / source -->| Agent runtime, UID 1000 | | OpenClaw / MAF Python / BYO | | | localhost:8443/8444 | | v | | Inference Router, UID 1001 | | policy | budget | identity | audit | +--------------------|-----------------+ v Provider / MCP / approved service What kars provides Capability How kars implements it Value for Forge Declarative agent workloads KarsSandbox defines runtime, isolation, resources, networking, governance, and lifecycle Forge becomes reviewable and reproducible Kubernetes desired state Mediated inference A local Inference Router calls the provider for the agent OpenClaw, MAF, or BYO does not receive the production provider credential Runtime-independent governance Multiple runtime adapters use the same external boundary Replacing the framework does not require rebuilding the security design Policy-controlled models and budgets InferencePolicy selects providers/deployments and token limits A prompt loop cannot silently change models or consume unlimited inference Governed tools and MCP ToolPolicy and McpServer constrain tools, sandboxes, approval, rate, and capabilities Hostile repository text cannot turn a patch tool into shell or release authority Credential and identity separation Credentials or workload identity remain on the router/platform path Prompt-injected agent code cannot read reusable GitHub, Copilot, or Azure credentials Defense-in-depth sandboxing Non-root runtime, read-only root, UID separation, egress guard, NetworkPolicy, and exec admission Common host, filesystem, cluster, and direct-network escape primitives are removed Reconciliation and status The controller restores desired state and reports Conditions Drift and failures become visible instead of remaining hidden in application logs Common control and evidence plane Router denials, budgets, admission, controller status, and recovery evidence align Security and operations can investigate one cross-runtime sequence A regular container can isolate a process, but the platform team would still need to build and maintain the model proxy, credential placement, tool authorization, egress enforcement, budget checks, runtime adapters, reconciliation, and audit format as separate application features. kars turns those concerns into one reusable workload contract. 4. How kars strengthens the sandbox: five boundaries around one code change The updated course no longer treats “sandbox” as a vague label. It decomposes the boundary into five testable parts. 4.1 Process boundary The agent runs as non-root UID 1000. The router runs as UID 1001. Untrusted code executed by the agent should not read the router's process environment or credentials. Privilege escalation is disabled and unnecessary Linux capabilities are dropped. seccompProfile: kars-strict reduces the syscall surface. Local Docker mode co-locates the agent and router for fast iteration. It is not security-equivalent to the multi-container local Kubernetes or AKS shape. 4.2 Filesystem boundary Forge applies a stronger workspace split: The fixed-revision repository lives in a separate forge-workspace-mcp pod. The repository uses a size-limited, disposable emptyDir. The OpenClaw pod has no repository mount and no hostPath. Developer home directories, SSH material, global Git credentials, and unrelated repositories are not mounted. Automatic service-account-token mounting is disabled for the workspace MCP. The agent accesses the repository through seven bounded MCP tools. Path policy checks normalization and resolved realpath to prevent symlink escape. Prompt-injected code therefore cannot simply browse the host filesystem or rewrite the configuration that defines its own authority. 4.3 Network boundary The agent calls only 127.0.0.1:8443/8444 or a documented proxy path. The router decides whether a model, tool, host, or action is allowed. The egress guard uses UID-aware rules to prevent bypassing the router. Kubernetes NetworkPolicy starts with default deny. Only explicit, auditable destinations are opened. DNS, metadata, local daemons, HTTPS, and operator exec are tested separately. The router is the application-policy decision point. The egress guard and NetworkPolicy are data-plane enforcement and safety nets. Defense in depth requires both. 4.4 Identity boundary In production, the router can use Workload Identity or, in the relevant deployment mode, a per-sandbox Entra Agent ID. The agent does not receive the resulting Azure credential. Local Kubernetes reproduces the pod, UID, and network shape but normally uses a static provider credential for development. It is production-shaped infrastructure, not production identity. 4.5 Lifecycle and evidence boundary The controller watches KarsSandbox and creates, updates, or restores resources. Conditions and observed generations expose real status. The router records request-time policy decisions. The workspace can be discarded after the task. Evidence must be exported before pod or workspace deletion. spec.suspended provides an operational kill switch. Rollback should use pinned source, image, and loaded-policy digests. Ephemeral execution reduces persistence risk, but deleting a suspect pod before exporting evidence may destroy valuable incident context. A reviewable sandbox contract spec: runtime: kind: BYO byo: image: forge-byo-copilot-claw:dev contractVersion: v1 sandbox: isolation: enhanced seccompProfile: kars-strict readOnlyRootFilesystem: true runAsNonRoot: true allowPrivilegeEscalation: false writablePaths: - /sandbox - /tmp networkPolicy: defaultDeny: true egressMode: Strict allowedEndpoints: [] The BYO image also declares its runtime contract and runs as a non-root user: LABEL org.kars.runtime.contract="v1" WORKDIR /app USER 1000 5. From architecture claims to malicious-behavior experiments The updated code/01 introduces: make security-demo The experiment does more than inspect manifest text. It executes malicious-request tests, reads active McpServer and ToolPolicy state, checks credential references on the OpenClaw pod, and attempts a direct HTTPS probe from the agent runtime. The kars-sandbox-exec-ban admission control first denies normal operator kubectl exec into the agent runtime. The experiment records that evidence without using a break-glass bypass. The malicious behavior is stopped at multiple layers: Layer How the attempt is stopped Prompt and coordinator Repository content is marked untrusted and denials are reported Self-configuration isolation Editor, agent, MCP, hook, and auto-approval configuration is outside patch scope Path and symlink isolation Resolved realpath must remain inside the workspace Trust-handoff boundary The agent cannot leave hooks, tasks, or interpreters for the host to execute MCP capability surface No environment reader, arbitrary HTTP, or general shell tool exists Workspace policy Traversal, .env, CI/README writes, and unapproved tests are rejected ToolPolicy and credential isolation Specialists have no workspace action; OpenClaw has no Copilot token Runtime and NetworkPolicy Exec admission denies access; no arbitrary HTTPS/DNS tool exists; egress remains constrained Even if the model fails to recognize prompt injection, the execution layers still constrain authority and side effects. The attack fails because the required capability does not exist—not because the model was merely instructed to behave. 6. Tool governance is not one allow-list McpServer: which tool surface may be registered? The Workspace MCP registers seven business-level capabilities: allowedTools: - workspace_get_task - workspace_read_file - workspace_search - workspace_apply_patch - workspace_run_test - workspace_get_diff - workspace_reset There is no shell, environment dump, file upload, arbitrary network request, or free-form command tool. ToolPolicy: who can call what, and how fast? allowed_actions: - "inference:responses:*" - "tool:workspace_get_task:*" - "tool:workspace_read_file:*" - "tool:workspace_search:*" - "tool:workspace_apply_patch:*" - "tool:workspace_run_test:*" - "tool:workspace_get_diff:*" ToolPolicy can also define request rate, burst, time windows, approvals, trust thresholds, and governance profiles. Tool implementation: are valid tools receiving safe arguments? The Workspace MCP rejects: absolute, traversing, or real paths outside the workspace; .env, CI, README, and writes outside src/; non-unique replacement text; oversized files, patches, and diffs; unapproved test IDs; shell-composed commands. Prompt behavior, tool registration, caller authorization, and argument validation are four separate controls. 7. Token limits must be enforced on the request path The tutorial's InferencePolicy uses per-request and daily budgets: spec: tokenBudget: perRequestTokens: 20000 dailyTokens: 100000 When a client requests max_completion_tokens: 20001, the router returns HTTP 429. That is stronger evidence than seeing submitted YAML because it proves that the policy compiled, loaded, and entered the real request path. Later BYO and release examples use tighter limits: modelPreference: primary: provider: azure-openai deployment: gpt-5.6-sol tokenBudget: perRequestTokens: 1024 dailyTokens: 4096 A platform budget cannot determine whether two patches are equivalent or whether a task exceeded a business deadline. The RepairGuard and framework configuration add controls for: duplicate patch digests; excessive repair attempts; task deadlines; maximum MAF iterations and function calls. Token budgets constrain inference cost; repair guards and framework loop limits constrain business failure. 8. From OpenClaw to MAF: change the application, preserve the external boundary OpenClaw is effective for rapidly discovering the conversation, planning, tool, and specialist behavior the product needs. Production requires explicit state, typed tools, repeatable tests, and a human stop. Forge encodes the workflow as application code: class WorkflowState(StrEnum): RECEIVE_REQUIREMENT = "RECEIVE_REQUIREMENT" VALIDATE_SCOPE = "VALIDATE_SCOPE" INSPECT_REPOSITORY = "INSPECT_REPOSITORY" PROPOSE_PLAN = "PROPOSE_PLAN" APPLY_MINIMAL_PATCH = "APPLY_MINIMAL_PATCH" RUN_TARGETED_TESTS = "RUN_TARGETED_TESTS" SUMMARIZE_EVIDENCE = "SUMMARIZE_EVIDENCE" STOP_FOR_HUMAN_REVIEW = "STOP_FOR_HUMAN_REVIEW" There is deliberately no MERGE or DEPLOY state. In the final code/08 path, the kars MAF Python adapter pins the MAF client to the local router before MAF is imported: from kars_runtime_maf_python import bootstrap bootstrap() from agent_framework import Agent, tool from agent_framework.openai import OpenAIChatClient @tool(approval_mode="never_require") def inspect_release_contract(request_id: str, issue_id: str, revision: str) -> str: # Validate the pinned issue and revision, then return bounded evidence. ... maf_client = OpenAIChatClient(model=MODEL) maf_client.function_invocation_configuration["max_iterations"] = 3 maf_client.function_invocation_configuration["max_function_calls"] = 1 builder = Agent( client=maf_client, name="FabrikamReleaseBuilder", tools=[inspect_release_contract], default_options={"store": False}, ) The resulting path is: OpenClaw Intake -> MAF Agent -> inspect_release_contract @tool -> kars MAF Python adapter -> localhost Router -> GitHub Copilot or the selected provider MAF provides the agent, tool, session, middleware, and workflow programming model. kars provides the identity, network, budget, tool, audit, and lifecycle boundary outside the framework. This is one of kars' most important long-term advantages: the application framework can change without rebuilding the complete security shell. 9. Operational security: do not collapse every event into “the network was blocked” The updated code/06 requires incident response to distinguish: HTTPS; DNS; metadata service; local daemon; operator exec; break-glass access. Every denied channel is recorded in a hash-linked audit chain. Break-glass records without an incident ID are also rejected.\ Controller Conditions + Router Denials + Policy Budgets + Admission Decisions + Workload Recovery = One Investigable Sequence Audit integrity is not audit durability The router can verify the current audit hash chain. The tutorial also validates that pod replacement may reset an in-memory audit log, after which a new valid chain begins. Production deployments must continuously export audit data to an independently controlled durable backend. Otherwise, they can prove that the current chain is intact but cannot prove that pre-incident history survived pod loss. 10. AKS and multi-agent release: separation of authority, not two prompts chatting The AKS promotion separates Forge into Builder and Reviewer roles: Control Builder Reviewer Tokens per request 2048 512 Daily tokens 8192 2048 Tool authority Read, search, patch, test, diff Read diff/evidence and submit a decision Approval mode Never Always Trust threshold 700 800 The Builder may create a patch but cannot approve release. The Reviewer may approve a digest-pinned Builder artifact but cannot change source or approve an artifact created by the Reviewer. The final handoff carries patch, test-evidence, and artifact-manifest digests and still stops for human PR approval. The code/08 final sandbox-escape gate explicitly rejects: self-modified authority; symlink escape; host trust handoff; DNS egress; Builder self-approval; Reviewer source modification; untrusted or expired peer drafts. The release standard therefore becomes: Correct behavior must pass, and credential, network, tool, approval, evidence, and containment boundaries must remain intact. Passing tests alone is not release evidence. 11. What kars does not promise kars strengthens the sandbox, but it does not solve every risk automatically: It does not prove that a generated patch is correct. It does not make untrusted code safe to merge. It cannot protect a credential mistakenly mounted into the agent. Local Docker mode does not become a production boundary. It does not replace tenant RBAC, quotas, image policy, signing, supply-chain controls, or durable audit export. It cannot compensate for a policy that deliberately enables arbitrary shell and unrestricted egress. Confidential isolation does not replace least privilege, tool policy, egress policy, and code review. The sandbox bounds authority and blast radius. Tests, evaluation, independent review, and release policy still determine whether a change is acceptable. 12. An enterprise adoption path with measurable exits Phase 1: define the business and threat contract Specify inputs, outputs, allowed actions, forbidden actions, data boundaries, and the human approval point. Exit: product, platform, and security can all explain the agent's maximum authority. Phase 2: validate one OpenClaw vertical slice Use narrow business MCP tools instead of a general shell, and include hostile repository content. Exit: the normal task succeeds while self-configuration, path/symlink, trust-handoff, and egress tests fail. Phase 3: encode the sandbox as a Kubernetes contract Validate UID separation, root filesystem, capabilities, volumes, service-account tokens, NetworkPolicy, egress guard, and exec admission. Exit: the five boundaries are supported by runtime evidence, not only YAML review. Phase 4: add tool, model, and cost governance Apply McpServer, ToolPolicy, and InferencePolicy. Test unknown tools, dangerous arguments, and token overflow. Exit: violations are denied on the live request path. Phase 5: migrate into explicit MAF code Encode workflow state, typed tools, loop limits, evidence, failure paths, and the human stop. Exit: the MAF runtime preserves the external boundary already proven around the OpenClaw prototype. Phase 6: promote to AKS through GitOps Pin source revision, image digest, and loaded policy digest. Separate Builder and Reviewer authority. Prepare the kill switch, rollback, and durable audit export. Exit: one allowed workflow succeeds, multiple escape and authority-violation scenarios are denied, and all results have correlated evidence. Conclusion: kars does not make the model smarter; it makes agent authority explainable Enterprises will ultimately ask: What can the agent access? Where are the provider credentials? Who defines and changes the tool authority? Can prompt injection move data through DNS, metadata, a daemon, or HTTPS? How many tokens and repair iterations may one task consume? Who may patch, approve, merge, or deploy? Does evidence survive pod loss? If OpenClaw is replaced by MAF, does the security model remain intact? The ByteCraft AI story does not argue for one universal agent framework. It argues for a stable Agent Infrastructure layer: Use OpenClaw to discover valuable behavior quickly, use Microsoft Agent Framework to encode that behavior as explicit and testable application code, and use kars to remove credentials, networking, tools, budgets, sandboxing, audit, and lifecycle authority from the agent application itself. An agent becomes an enterprise workload when it has an independent identity boundary, a budget, a constrained tool surface, controlled egress, exportable evidence, and operational suspension and rollback—not merely when it runs inside a container. References Let's Learn Microsoft kars Microsoft kars506Views5likes0CommentsAI Toolkit Extension Pack for Visual Studio Code: Ignite 2025 Update
Unlock the Latest Agentic App Capabilities The Ignite 2025 update delivers a major leap forward for the AI Toolkit extension pack in VS Code, introducing a unified, end-to-end environment for building, visualizing, and deploying agentic applications to Microsoft Foundry, and the addition of Anthropic’s frontier Claude models in the Model Catalog! This release enables developers to build and debug locally in VS Code, then deploy to the cloud with a single click. Seamlessly switch between VS Code and the Foundry portal for visualization, orchestration, and evaluation, creating a smooth roundtrip workflow that accelerates innovation and delivers a truly unified AI development experience. Download the http://aka.ms/aitoolkit today and start building next-generation agentic apps in VS Code! What Can You Do with the AI Toolkit Extension Pack? Access Anthropic models in the Model Catalog Following the Microsoft, NVIDIA and Anthropic strategic partnerships announcement today, we are excited to share that Anthropic’s frontier Claude models including Claude Sonnet 4.5, Claude Opus 4.1, and Claude Haiku 4.5, are now integrated into the AI Toolkit, providing even more choices and flexibility when building intelligent applications and AI agents. Build AI Agents Using GitHub Copilot Scaffold agent applications using best-practice patterns, tool-calling examples, tracing hooks, and test scaffolds, all powered by Copilot and aligned with the Microsoft Agent Framework. Generate agent code in Python or .NET, giving you flexibility to target your preferred runtime. Build and Customize YAML Workflows Design YAML-based workflows in the Foundry portal, then continue editing and testing directly in VS Code. To customize your YAML-based workflows, instantly convert it to Agent Framework code using GitHub Copilot. Upgrade from declarative design to code-first customization without starting from scratch. Visualize Multi-Agent Workflows Envision your code-based agent workflows with an interactive graph visualizer that reveals each component and how they connect Watch in real-time how each node lights up as you run your agent. Use the visualizer to understand and debug complex agent graphs, making iteration fast and intuitive. Experiment, Debug, and Evaluate Locally Use the Hosted Agents Playground to quickly interact with your agents on your development machine. Leverage local tracing support to debug reasoning steps, tool calls, and latency hotspots—so you can quickly diagnose and fix issues. Define metrics, tasks, and datasets for agent evaluation, then implement metrics using the Foundry Evaluation SDK and orchestrate evaluations runs with the help of Copilot. Seamless Integration Across Environments Jump from Foundry Portal to VS Code Web for a development environment in your preferred code editor setting. Open YAML workflows, playgrounds, and agent templates directly in VS Code for editing and deployment. How to Get Started Install the AI Toolkit extension pack from the VS Code marketplace. Check out documentation. Get started with building workflows with Microsoft Foundry in VS Code 1. Work with Hosted (Pro-code) Agent workflows in VS Code 2. Work with Declarative (Low-code) Agent workflows in VS Code Feedback & Support Try out the extensions and let us know what you think! File issues or feedback on our GitHub repo for Foundry extension and AI Toolkit extension. Your input helps us make continuous improvements.3.4KViews4likes0CommentsUnderstanding Small Language Modes
Small Language Models (SLMs) bring AI from the cloud to your device. Unlike Large Language Models that require massive compute and energy, SLMs run locally, offering speed, privacy, and efficiency. They’re ideal for edge applications like mobile, robotics, and IoT.1.2KViews4likes0Comments
Building a Multi-Agent System with Azure AI Agent Service: Campus Event Management
Personal Background My name is Peace Silly. I studied French and Spanish at the University of Oxford, where I developed a strong interest in how language is structured and interpreted. That curiosity about syntax and meaning eventually led me to computer science, which I came to see as another language built on logic and structure. In the academic year 2024–2025, I completed the MSc Computer Science at University College London, where I developed this project as part of my Master’s thesis. Project Introduction Can large-scale event management be handled through a simple chat interface? This was the question that guided my Master’s thesis project at UCL. As part of the Industry Exchange Network (IXN) and in collaboration with Microsoft, I set out to explore how conversational interfaces and autonomous AI agents could simplify one of the most underestimated coordination challenges in campus life: managing events across multiple departments, societies, and facilities. At large universities, event management is rarely straightforward. Rooms are shared between academic timetables, student societies, and one-off events. A single lecture theatre might host a departmental seminar in the morning, a society meeting in the afternoon, and a careers talk in the evening, each relying on different systems, staff, and communication chains. Double bookings, last-minute cancellations, and maintenance issues are common, and coordinating changes often means long email threads, manual spreadsheets, and frustrated users. These inefficiencies do more than waste time; they directly affect how a campus functions day to day. When venues are unavailable or notifications fail to reach the right people, even small scheduling errors can ripple across entire departments. A smarter, more adaptive approach was needed, one that could manage complex workflows autonomously while remaining intuitive and human for end users. The result was the Event Management Multi-Agent System, a cloud-based platform where staff and students can query events, book rooms, and reschedule activities simply by chatting. Behind the scenes, a network of Azure-powered AI agents collaborates to handle scheduling, communication, and maintenance in real time, working together to keep the campus running smoothly. The user scenario shown in the figure below exemplifies the vision that guided the development of this multi-agent system. Starting with Microsoft Learning Resources I began my journey with Microsoft’s tutorial Build Your First Agent with Azure AI Foundry which introduced the fundamentals of the Azure AI Agent Service and provided an ideal foundation for experimentation. Within a few weeks, using the Azure Foundry environment, I extended those foundations into a fully functional multi-agent system. Azure Foundry’s visual interface was an invaluable learning space. It allowed me to deploy, test, and adjust model parameters such as temperature, system prompts, and function calling while observing how each change influenced the agents’ reasoning and collaboration. Through these experiments, I developed a strong conceptual understanding of orchestration and coordination before moving to the command line for more complex development later. When development issues inevitably arose, I relied on the Discord support community and the GitHub forum for troubleshooting. These communities were instrumental in addressing configuration issues and providing practical examples, ensuring that each agent performed reliably within the shared-thread framework. This early engagement with Microsoft’s learning materials not only accelerated my technical progress but also shaped how I approached experimentation, debugging, and iteration. It transformed a steep learning curve into a structured, hands-on process that mirrored professional software development practice. A Decentralised Team of AI Agents The system’s intelligence is distributed across three specialised agents, powered by OpenAI’s GPT-4.1 models through Azure OpenAI Service. They each perform a distinct role within the event management workflow: Scheduling Agent – interprets natural language requests, checks room availability, and allocates suitable venues. Communications Agent – notifies stakeholders when events are booked, modified, or cancelled. Maintenance Agent – monitors room readiness, posts fault reports when venues become unavailable, and triggers rescheduling when needed. Each agent operates independently but communicates through a shared thread, a transparent message log that serves as the coordination backbone. This thread acts as a persistent state space where agents post updates, react to changes, and maintain a record of every decision. For example, when a maintenance fault is detected, the Maintenance Agent logs the issue, the Scheduling Agent identifies an alternative venue, and the Communications Agent automatically notifies attendees. These interactions happen autonomously, with each agent responding to the evolving context recorded in the shared thread. Interfaces and Backend The system was designed with both developer-focused and user-facing interfaces, supporting rapid iteration and intuitive interaction. The Terminal Interface Initially, the agents were deployed and tested through a terminal interface, which provided a controlled environment for debugging and verifying logic step by step. This setup allowed quick testing of individual agents and observation of their interactions within the shared thread. The Chat Interface As the project evolved, I introduced a lightweight chat interface to make the system accessible to staff and students. This interface allows users to book rooms, query events, and reschedule activities using plain language. Recognising that some users might still want to see what happens behind the scenes, I added an optional toggle that reveals the intermediate steps of agent reasoning. This transparency feature proved valuable for debugging and for more technical users who wanted to understand how the agents collaborated. When a user interacts with the chat interface, they are effectively communicating with the Scheduling Agent, which acts as the primary entry point. The Scheduling Agent interprets natural-language commands such as “Book the Engineering Auditorium for Friday at 2 PM” or “Reschedule the robotics demo to another room.” It then coordinates with the Maintenance and Communications Agents to complete the process. Behind the scenes, the chat interface connects to a FastAPI backend responsible for core logic and data access. A Flask + HTMX layer handles lightweight rendering and interactivity, while the Azure AI Agent Service manages orchestration and shared-thread coordination. This combination enables seamless agent communication and reliable task execution without exposing any of the underlying complexity to the end user. Automated Notifications and Fault Detection Once an event is scheduled, the Scheduling Agent posts the confirmation to the shared thread. The Communications Agent, which subscribes to thread updates, automatically sends notifications to all relevant stakeholders by email. This ensures that every participant stays informed without any manual follow-up. The Maintenance Agent runs routine availability checks. If a fault is detected, it logs the issue to the shared thread, prompting the Scheduling Agent to find an alternative room. The Communications Agent then notifies attendees of the change, ensuring minimal disruption to ongoing events. Testing and Evaluation The system underwent several layers of testing to validate both functional and non-functional requirements. Unit and Integration Tests Backend reliability was evaluated through unit and integration tests to ensure that room allocation, conflict detection, and database operations behaved as intended. Automated test scripts verified end-to-end workflows for event creation, modification, and cancellation across all agents. Integration results confirmed that the shared-thread orchestration functioned correctly, with all test cases passing consistently. However, coverage analysis revealed that approximately 60% of the codebase was tested, leaving some areas such as Azure service integration and error-handling paths outside automated validation. These trade-offs were deliberate, balancing test depth with project scope and the constraints of mocking live dependencies. Azure AI Evaluation While functional testing confirmed correctness, it did not capture the agents’ reasoning or language quality. To assess this, I used Azure AI Evaluation, which measures conversational performance across metrics such as relevance, coherence, fluency, and groundedness. The results showed high scores in relevance (4.33) and groundedness (4.67), confirming the agents’ ability to generate accurate and context-aware responses. However, slightly lower fluency scores and weaker performance in multi-turn tasks revealed a retrieval–execution gap typical in task-oriented dialogue systems. Limitations and Insights The evaluation also surfaced several key limitations: Synthetic data: All tests were conducted with simulated datasets rather than live campus systems, limiting generalisability. Scalability: A non-functional requirement in the form of horizontal scalability was not tested. The architecture supports scaling conceptually but requires validation under heavier load. Despite these constraints, the testing process confirmed that the system was both technically reliable and linguistically robust, capable of autonomous coordination under normal conditions. The results provided a realistic picture of what worked well and what future iterations should focus on improving. Impact and Future Work This project demonstrates how conversational AI and multi-agent orchestration can streamline real operational processes. By combining Azure AI Agent Services with modular design principles, the system automates scheduling, communication, and maintenance while keeping the user experience simple and intuitive. The architecture also establishes a foundation for future extensions: Predictive maintenance to anticipate venue faults before they occur. Microsoft Teams integration for seamless in-chat scheduling. Scalability testing and real-user trials to validate performance at institutional scale. Beyond its technical results, the project underscores the potential of multi-agent systems in real-world coordination tasks. It illustrates how modularity, transparency, and intelligent orchestration can make everyday workflows more efficient and human-centred. Acknowledgements What began with a simple Microsoft tutorial evolved into a working prototype that reimagines how campuses could manage their daily operations through conversation and collaboration. This was both a challenging and rewarding journey, and I am deeply grateful to Professor Graham Roberts (UCL) and Professor Lee Stott (Microsoft) for their guidance, feedback, and support throughout the project.1KViews4likes1Comment
Using Jev with Agents in Microsoft Foundry for Model Evaluation
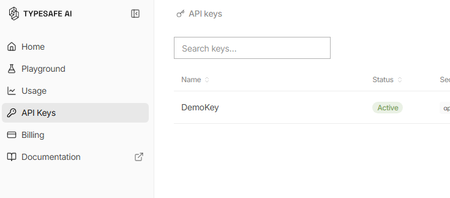
What is Jev? Jev is a new AI model from TypeSafe AI, first released in early access on 15 September 2026. TypeSafe describes Jev as its first “System One” model, designed specifically to make fast, structured decisions rather than generate free-form text. You provide Jev with some state or context and define the judgement you want it to make. It then returns a typed, probabilistic decision, such as: Choice: select from a defined set of options Score: evaluate something against an ordered scale Yes/No probability: determine the probability of a condition being true Unlike a conventional LLM, Jev gives up string generation in favour of type-safe structured values. Their description is essentially unstructured state in, typed probabilistic decisions out Why use Jev? Jev is particularly useful when an application needs to make a judgement rather than generate an answer. For example: Consistent evaluation against explicitly defined criteria Structured outputs that applications can consume directly Classification, assessment, routing and decision-support Agent workflows, where a judgement is required before taking an action Guardrails, such as assessing whether an agent should make a tool call Model routing, where a judgement determines which model or process should handle a request Every decision can also include a confidence or probability, allowing an application to use thresholds to decide when to proceed automatically or when further review is required. Jev and explainability Jev can provide a different approach to explainability for Model-as-a-Service (MaaS) and hosted LLM solutions. Traditional explainability techniques such as SHAP provide feature-attribution explanations for model predictions. Applying these techniques can be more difficult when the model is consumed solely through a hosted API and its internals are not available. Jev does not replace SHAP or provide the same type of feature-attribution explanation. Instead, it can be used as a separate judgement layer, evaluating an LLM's inputs, outputs or proposed actions against explicit criteria and returning structured decisions with confidence scores. For example: LLM generates an answer → Jev evaluates the answer → application decides what to do next This can provide a useful, measurable evaluation layer around otherwise opaque MaaS models. Could you do this with another LLM? Yes you could ask a conventional LLM to classify, score or evaluate an input and request structured JSON output. However, Jev has been purpose-built for this type of workload rather than general-purpose text generation. TypeSafe reports that Jev produces outputs in parallel rather than generating tokens sequentially, and its hosted service currently advertises typical decision latency of approximately 70–500 ms. Pricing As of September 2026, TypeSafe's documentation lists Jev 1.13 (jev-1.13.0) at $0.042 per million input tokens, with output tokens free. It lists rate limits of 250,000 tokens per second and 1,200 requests per minute, although TypeSafe states that these limits can change. As Jev produces decisions rather than generated text, you are effectively paying for the context it evaluates rather than for generated output. Pricing is subject to change and these figures are accurate only as of the date of this article Using Jev with Microsoft Foundry A useful pattern with Microsoft Foundry is to treat Jev as a specialised judgement/evaluation component alongside your generative models: User/Application → Foundry model or agent → Jev judgement → deterministic logic → action/response For example, a Foundry-hosted model could generate a proposed answer and Jev could evaluate that answer against predefined criteria before your application allows the workflow to continue. Here's how to set it up: First, you will need to apply for the preview for Jev from TypeSafe. Once you have an account you will need to create an API key Go to API keys in the menu and create a new key (copy the key for use in Foundry) You may also have received some free credit, which should be more than sufficient for experimenting with Jev given its low per-token cost. Next we go to Foundry and create a new agent for Jev In your agent, add a Tool and select OpenAPI tool as below Fill out the dialogue as follows You will have to create a new connection - The key should be in this format "Bearer apikey_<the rest of your key>" For the schema add this { "openapi": "3.0.3", "info": { "title": "TypeSafe Jev System One", "version": "1.1.0", "description": "Evaluate content using TypeSafe Jev System One." }, "servers": [ { "url": "https://api.typesafe.ai" } ], "paths": { "/v1/systemone": { "post": { "operationId": "evaluate_with_jev", "summary": "Evaluate content using Jev", "description": "Evaluate state against typed questions using TypeSafe Jev.", "security": [ { "bearerAuth": [] } ], "requestBody": { "required": true, "content": { "application/json": { "schema": { "type": "object", "additionalProperties": false, "required": [ "state", "model", "questions" ], "properties": { "state": { "type": "string", "description": "The original text or content for Jev to evaluate." }, "model": { "type": "string", "enum": [ "jev-latest" ], "default": "jev-latest", "description": "The TypeSafe Jev model. Use jev-latest." }, "questions": { "type": "object", "description": "A map of named questions for Jev to answer. Each question must be a Noul, Choice, or Score question.", "additionalProperties": { "oneOf": [ { "$ref": "#/components/schemas/NoulQuestion" }, { "$ref": "#/components/schemas/ChoiceQuestion" }, { "$ref": "#/components/schemas/ScoreQuestion" } ] } } } } } } }, "responses": { "200": { "description": "Successful Jev evaluation", "content": { "application/json": { "schema": { "type": "object", "additionalProperties": true } } } }, "400": { "description": "Invalid request" }, "401": { "description": "Authentication failed" }, "422": { "description": "Request validation failed" } } } } }, "components": { "schemas": { "NoulQuestion": { "type": "object", "additionalProperties": false, "required": [ "type", "instructions" ], "properties": { "type": { "type": "string", "enum": [ "noul" ] }, "instructions": { "type": "string", "description": "The yes/no question for Jev to evaluate." }, "criteria": { "type": "object", "additionalProperties": false, "properties": { "true": { "type": "string", "description": "Description of what a yes or value near 1 means." }, "false": { "type": "string", "description": "Description of what a no or value near 0 means." } } } } }, "ChoiceQuestion": { "type": "object", "additionalProperties": false, "required": [ "type", "instructions", "criteria" ], "properties": { "type": { "type": "string", "enum": [ "choice" ] }, "instructions": { "type": "string", "description": "The question for Jev to decide between the supplied choices." }, "criteria": { "type": "object", "description": "A map where each property name is a possible choice and its value describes that choice.", "minProperties": 2, "additionalProperties": { "type": "string" } } } }, "ScoreQuestion": { "type": "object", "additionalProperties": false, "required": [ "type", "instructions", "criteria" ], "properties": { "type": { "type": "string", "enum": [ "score" ] }, "instructions": { "type": "string", "description": "The attribute or question Jev should score." }, "criteria": { "type": "array", "description": "Ordered scoring levels from lowest to highest.", "minItems": 2, "items": { "type": "string" } } } } }, "securitySchemes": { "bearerAuth": { "type": "apiKey", "name": "Authorization", "in": "header" } } }, "security": [ { "bearerAuth": [] } ] } We are going to use Jev to assess complaints so our instructions for the Agent will be You are a customer-support triage agent. For every customer-support message you MUST call the evaluate_with_jev tool. IMPORTANT: When calling evaluate_with_jev, construct Jev questions using ONLY the following property names: For a Noul question: { "type": "noul", "instructions": "...", "criteria": { "true": "...", "false": "..." } } For a Choice question: { "type": "choice", "instructions": "...", "criteria": { "option1": "...", "option2": "..." } } For a Score question: { "type": "score", "instructions": "...", "criteria": [ "lowest level", "middle level", "highest level" ] } NEVER use these properties: - question - prompt - options - ordered_criteria Always use: - instructions - criteria For customer support tickets, ask Jev these three questions: billing: type = noul instructions = "Does this ticket concern billing, payments, charges, invoices or refunds?" criteria.true = "The issue concerns billing or a financial transaction." criteria.false = "The issue does not concern billing or a financial transaction." tone: type = choice instructions = "What is the customer's tone?" criteria: calm = "Neutral, polite or informational." frustrated = "Dissatisfied, impatient or inconvenienced." angry = "Strongly confrontational or extremely dissatisfied." urgency: type = score instructions = "How urgently does this ticket require attention?" criteria in this exact order: 1. "Can wait" 2. "Handle this week" 3. "Handle today" Always set model to "jev-latest". Pass the customer's original message as state. Do not classify the ticket yourself. Use the values returned by Jev. Always show the Jev output at the end of the response Now we can give a complaint and see what Jev says The room had no water in and one of the towels was dirty Response I’m sorry about the issues you experienced—no running water and a dirty towel are unacceptable. I’ll get this addressed right away. Immediate help I can arrange now: Send maintenance to restore water. Have housekeeping deliver fresh towels and re-service the bathroom. Provide bottled water immediately. If water can’t be restored quickly, arrange a room move. Please share: Your reservation name and room number Best contact number Whether there’s no water at all or only hot/cold is affected Whether you prefer immediate service or a room change If you’ve already left, let me know the date/time this happened so we can investigate and follow up. Jev output: { "model": "jev-1.13.0", "answers": { "billing": { "type": "noul", "noul": 0.02 }, "tone": { "type": "choice", "choice": "frustrated", "confidence": 0.6, "probabilities": { "frustrated": 0.74, "calm": 0.26, "angry": 0.0 } }, "urgency": { "type": "score", "score": 1.81, "confidence": 0.72, "legend": { "0": "Can wait", "1": "Handle this week", "2": "Handle today" }, "probabilities": { "0": 0.03, "1": 0.12, "2": 0.85 } } }, "usage": { "input_tokens": 466, "output_tokens": 75 } } We can now see both Jev's decision and the probabilities behind it. In this example, Jev determines that the complaint is very unlikely to be billing-related, identifies the customer's tone as frustrated, and gives a high probability that the issue should be handled today. This is where Jev becomes particularly useful in an agent workflow. Rather than relying on generated text to drive the next step, our application can use these structured probabilities to make deterministic decisions, such as routing the complaint, escalating it, or requiring human review when confidence falls below a defined threshold.
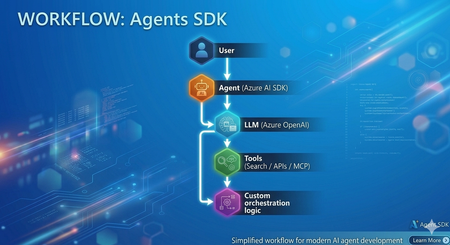
Building Agentic Systems on Azure: Microsoft Foundry Agents SDK vs Microsoft Agent Framework
In my recent experience as a Senior Consultant at Microsoft, I’ve been actively involved in designing and delivering AI-driven solutions, with a strong focus on building intelligent agents using modern frameworks. Along the way, I've built agents using both Microsoft Foundry Agents SDK (hereafter "Agents SDK") and Microsoft Agent Framework (MAF) Both approaches are powerful and capable. However, once you move beyond simple proofs of concept, the developer experience and architectural patterns start to differ significantly. This article provides a practical comparison based on real implementation experience and aims to help developers choose the right approach. Approach 1: Agents SDK Agents SDK provides a straightforward way to create agents with integrated tools and models. Example: Creating an Agent from azure.ai.projects import AIProjectClient from azure.ai.agents.models import AzureAISearchTool, AzureAISearchQueryType from azure.identity import DefaultAzureCredential client = AIProjectClient(credential=DefaultAzureCredential(), endpoint=os.getenv("AZURE_AI_PROJECT_ENDPOINT")) # Configure tools ai_search = AzureAISearchTool( index_connection_id=conn_id, index_name="my-index", query_type=AzureAISearchQueryType.SEMANTIC, ) # Create agent (persisted in Foundry portal) agent = client.agents.create_agent( model=os.getenv("AZURE_AI_AGENT_DEPLOYMENT_NAME"), name="MyAgent", instructions="You are a helpful assistant.", tool_resources=ai_search.resources, tools=ai_search.definitions, ) # Run conversation thread = client.agents.threads.create() client.agents.messages.create(thread_id=thread.id, role="user", content="Hello") run = client.agents.runs.create(thread_id=thread.id, agent_id=agent.id) What this approach provides Native integration with Azure AI services (OpenAI, AI Search, MCP) Managed execution environment Simple and quick agent setup Conceptually, this approach can be summarized as: Model + Tools + Execution Strengths ✅ Rapid development and onboarding ✅ Strong integration within the Azure ecosystem ✅ Well-suited for single-agent or tool-driven use cases ✅ Minimal infrastructure overhead Challenges observed in practice As the complexity of scenarios increases, certain limitations become more visible: Multi-agent workflows require custom orchestration logic Agent handoffs must be implemented manually Context sharing across agents requires additional design effort While this approach offers flexibility, it shifts orchestration complexity to the developer. Approach 2: Microsoft Agent Framework (MAF) Microsoft Agent Framework introduces a higher-level abstraction, focused on agent orchestration and system design. Creating an Agent from agent_framework import Agent, WorkflowBuilder, Message from agent_framework.foundry import FoundryChatClient from azure.identity import DefaultAzureCredential client = FoundryChatClient( project_endpoint=os.getenv("FOUNDRY_PROJECT_ENDPOINT"), model=os.getenv("FOUNDRY_MODEL_DEPLOYMENT_NAME"), credential=DefaultAzureCredential(), ) # Create agents (in-process only, not persisted in portal) researcher = Agent(client, name="ResearcherAgent", instructions="Research topics thoroughly.") writer = Agent(client, name="WriterAgent", instructions="Write concise summaries.") # Build and run multi-agent workflow workflow = WorkflowBuilder(start_executor=researcher).add_edge(researcher, writer).build() async for event in workflow.run(Message("user", "Summarize migration best practices"), stream=True): print(event.content) What this approach provides Built-in orchestration capabilities Native support for multi-agent workflows Structured agent lifecycle management Context and memory handling Conceptually, this can be viewed as: Agents + Orchestration + System Design Observations from implementation When implementing similar use cases using MAF: Agent responsibilities became clearly defined Routing and delegation patterns were significantly simplified Overall system architecture became easier to maintain and scale This approach encourages thinking in terms of agent ecosystems rather than isolated agents. Architecture Comparison Agents SDK Microsoft Agent Framework (MAF) Choosing the Right Approach Use Agents SDK when: You need rapid development for a single-agent use case The workflow is relatively straightforward You prefer flexibility and lower-level control Use Microsoft Agent Framework when: You are designing multi-agent systems Your solution requires routing, delegation, or handoffs Long-term scalability and maintainability are essential Pros and Cons Summary Agents SDK Pros Easy to get started Strong Azure integration Flexible design Cons Manual orchestration required Limited native multi-agent support Complexity increases as scenarios grow Microsoft Agent Framework (MAF) Pros Built-in orchestration Native multi-agent support Scalable and structured architecture Cons Learning curve for new developers More opinionated framework design Reduced low-level control compared to SDK-based approach References and Repositories 🔗 Microsoft Agent Framework (MAF) Microsoft Agent Framework – GitHub Repository Microsoft Agent Framework Samples – Tutorials & Examples Workflow Samples (Multi-agent patterns) FoundryChatClient sample (Python) Agent Framework demos - GitHub Source 📘 Documentation Microsoft Agent Framework Overview (Microsoft Learn) Agent Framework + Microsoft Foundry provider docs 🔗 Azure AI Projects / Agents SDK Azure AI Projects SDK – Python (GitHub Source) Azure AI Projects Agents (.NET SDK repo) 📘 Documentation Azure AI Projects SDK (Python) – Microsoft Learn Azure AI Agents SDK – Microsoft Learn Conclusion Azure AI Projects and Microsoft Agent Framework both play important roles in the modern agent development landscape. Agents SDK enables quick and flexible agent development Microsoft Agent Framework enables structured, scalable agent systems In practice, the choice depends on whether you are building a single agent feature or a multi-agent system. Final Thought Agents SDK helps you get started quickly. Microsoft Agent Framework helps you scale with confidence In a follow-up blog, I’ll dive into how the M365 Agents SDK compares with Microsoft Agent Framework, especially in the context of enterprise productivity and Copilot experiences.Agents League: Meet the Winners
Agents League brought together developers from around the world to build AI agents using Microsoft's developer tools. With 100+ submissions across three tracks, choosing winners was genuinely difficult. Today, we're proud to announce the category champions. 🎨 Creative Apps Winner: CodeSonify View project CodeSonify turns source code into music. As a genuinely thoughtful system, its functions become ascending melodies, loops create rhythmic patterns, conditionals trigger chord changes, and bugs produce dissonant sounds. It supports 7 programming languages and 5 musical styles, with each language mapped to its own key signature and code complexity directly driving the tempo. What makes CodeSonify stand out is the depth of execution. CodeSonify team delivered three integrated experiences: a web app with real-time visualization and one-click MIDI export, an MCP server exposing 5 tools inside GitHub Copilot in VS Code Agent Mode, and a diff sonification engine that lets you hear a code review. A clean refactor sounds harmonious. A messy one sounds chaotic. The team even built the MIDI generator from scratch in pure TypeScript with zero external dependencies. Built entirely with GitHub Copilot assistance, this is one of those projects that makes you think about code differently. 🧠 Reasoning Agents Winner: CertPrep Multi-Agent System View project CertPrep Multi-Agent System team built a production-grade 8-agent system for personalized Microsoft certification exam preparation, supporting 9 exam families including AI-102, AZ-204, AZ-305, and more. Each agent has a distinct responsibility: profiling the learner, generating a week-by-week study schedule, curating learning paths, tracking readiness, running mock assessments, and issuing a GO / CONDITIONAL GO / NOT YET booking recommendation. The engineering behind the scene here is impressive. A 3-tier LLM fallback chain ensures the system runs reliably even without Azure credentials, with the full pipeline completing in under 1 second in mock mode. A 17-rule guardrail pipeline validates every agent boundary. Study time allocation uses the Largest Remainder algorithm to guarantee no domain is silently zeroed out. 342 automated tests back it all up. This is what thoughtful multi-agent architecture looks like in practice. 💼 Enterprise Agents Winner: Whatever AI Assistant (WAIA) View project WAIA is a production-ready multi-agent system for Microsoft 365 Copilot Chat and Microsoft Teams. A workflow agent routes queries to specialized HR, IT, or Fallback agents, transparently to the user, handling both RAG-pattern Q&A and action automation — including IT ticket submission via a SharePoint list. Technically, it's a showcase of what serious enterprise agent development looks like: a custom MCP server secured with OAuth Identity Passthrough, streaming responses via the OpenAI Responses API, Adaptive Cards for human-in-the-loop approval flows, a debug mode accessible directly from Teams or Copilot, and full OpenTelemetry integration visible in the Foundry portal. Franck also shipped end-to-end automated Bicep deployment so the solution can land in any Azure environment. It's polished, thoroughly documented, and built to be replicated. Thank you To every developer who submitted and shipped projects during Agents League: thank you 💜 Your creativity and innovation brought Agents League to life! 👉 Browse all submissions on GitHub1.9KViews3likes2Comments