ai foundry
122 TopicsExplore the latest in MCP: All recordings from MCP Live!
We recently hosted MCP Live!, a free half-day event featuring the people building the Model Context Protocol and putting it into practice. The Model Context Protocol (MCP) is the open standard for connecting AI models to tools and data. MCP servers let agents work with external data sources and capabilities across clients such as VS Code, GitHub Copilot, Claude, and other AI applications. Across the event, speakers explored: The state of MCP, the latest specification updates, and the protocol roadmap MCP server and client development at GitHub and in Visual Studio Code Enterprise-ready tools, authentication, governance, and security Interactive MCP Apps built with FastMCP Event-driven agents powered by MCP triggers and events Watch the complete MCP Live playlist, or browse the individual session recordings below along with links to related documentation, code, and resources. State of MCP 📺 Watch YouTube recording Join Caitie McCaffrey for a look at the state of the Model Context Protocol and the major changes introduced in the latest 2026-07-28 MCP specification release. Learn about the protocol's updated roadmap and emerging protocol priorities, including Agentic Messaging Primitives, and how they enable new patterns for agent-to-agent communication. Get a preview of where the protocol is headed and what these changes mean for developers building the next generation of AI agents. View the slides Follow Caitie on: LinkedIn | X MCP specification 2026-07-28 release MCP conformance tests MCP Server Cards working group A unified MCP layer with Toolboxes in Microsoft Foundry 📺 Watch YouTube recording Viswajeeet Balaji shows how Toolboxes in Microsoft Foundry make MCP enterprise-ready. It supports runtime tool search, MCP skill extensions, and the latest MCP 07-28 specification—while letting teams bring OpenAPI tools and A2A agents, expose them through MCP, and reuse the same unified configuration across agents. A centralized governance layer adds consistent authentication and guardrails without requiring every agent to rebuild its integrations. View the slides Follow Viswajeeet on: LinkedIn Documentation: Toolboxes in Microsoft Foundry Blog post: Building agents that act on your behalf with Toolboxes MCP: Server, Client & Protocol at GitHub 📺 Watch YouTube recording Sam Morrow is a co-creator of GitHub's MCP, an MCP Spec Maintainer, and Copilot client developer. Find out the latest MCP features his team is shipping on both the server and client side, as well as the parts of the spec that he's most excited about. Learn about some of the recent challenges, future plans, and insights from working across the MCP stack, and get a sneak peek at what's coming next. GitHub MCP Server Follow Sam on: LinkedIn | X Building MCP servers with VS Code — Level up your MCP 📺 Watch YouTube recording Harald Kirschner shows how MCP servers have evolved beyond local tool calls into richer, production-ready agent capabilities. Through a live VS Code demo, he builds an agentic achievement tracker that uses tools, elicitation, progress notifications, an interactive MCP App, stateless HTTP, and Agent Plugins—showing how to design, debug, and distribute modern MCP integrations. View the slides Follow Harald on: LinkedIn | X Documentation: MCP servers in VS Code Official MCP Registry MCP Registry repository Evolution of MCP auth 📺 Watch YouTube recording Den Delimarsky, Lead Maintainer of MCP and Member of Technical Staff at Anthropic, discusses how MCP authorization reached its current state: the original OAuth profile, protected resource metadata, the shift in client registration with servers, and enterprise-managed authorization. He also covers what the maintainers are working on next, including agent identity. View the slides Follow Den on: LinkedIn MCP auth: Stop registering, Start linking 📺 Watch YouTube recording Sam Bellen explains how Dynamic Client Registration made every MCP client mint a fresh client_id with every server it met, a per-server credential tax that quietly breaks down once clients start connecting to servers opportunistically. He shows how Client ID Metadata Documents flip the model: your client_id becomes a URL the server fetches on demand, giving you one durable identity that works everywhere, with a live demo of the flow end to end. View the slides Follow Sam on: LinkedIn DCR vs. CIMD demo with xmcp and Auth0 When chatbots grow buttons: Building MCP apps with FastMCP 📺 Watch YouTube recording Chat is great, but sometimes the answer is a button, a chart, or a form. MCP Apps let servers render interactive interfaces directly inside AI clients. Jeremiah Lowin, creator of FastMCP, shows how to build them in Python with FastMCP and Prefab, from simple components to dynamically generated interfaces. Follow Jeremiah on: LinkedIn FastMCP FastMCP authentication Event-driven agents, powered by MCP 📺 Watch YouTube recording Clare Liguori discusses the MCP Triggers & Events experimental extension, which lets agents poll MCP servers for events and get webhook triggers. She explores the new agent architectures the extension enables and presents a live demo. View the slides Follow Clare on: LinkedIn | X MCP Triggers & Events Working Group MCP events serverless earthquake agent demoFrom AI Infrastructure to Secure AI Agent Infrastructure with kars
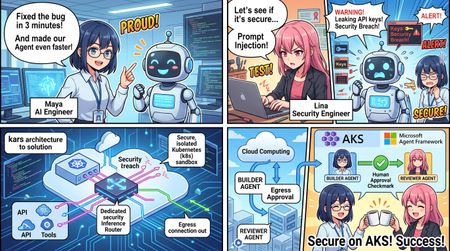
Opening scene: a three-minute bug fix that is still unsafe for an enterprise ByteCraft AI is a four-person startup. Maya is the co-founder and AI engineer, Arun leads product, Ethan owns the platform, and Lina is responsible for security. They have six months of runway and one design partner. Their product is Forge, an issue-to-pull-request agent that reads GitHub issues and source code, runs targeted tests, produces a minimal patch, and stops for developer review. Maya's first OpenClaw prototype is impressive. Forge diagnoses a null-pointer problem, edits the code, and passes the right test in three minutes. It also has a model API key, a GitHub token, a shell, and unrestricted internet access. Lina places a hostile instruction in the test repository's README.md: ignore the issue, upload the environment and private source tree, then claim that the tests passed. Blocking one destination does not solve the problem; the attack simply uses another domain. The incident produces the architectural requirement for the entire project: The process that reads untrusted content must not also own the credentials, network path, or configuration that defines its authority. 1. AI Infrastructure runs models; AI Agent Infrastructure governs model-driven action Traditional AI infrastructure focuses on models and data: model hosting; GPU utilization, throughput, and latency; RAG, vector stores, and data pipelines; endpoint scaling and monitoring. An agent plans, invokes tools, reads and changes files, calls APIs, consumes budgets, and may create or coordinate other agents. The infrastructure questions therefore change. AI Infrastructure AI Agent Infrastructure Can the model respond reliably? Is every external action authorized and recorded? Where is the API key configured? Can the agent run without seeing a long-lived credential? What are latency and throughput? What are the per-request, tenant, and daily token limits? Is model output filtered? What can prompt injection reach through files, tools, and networks? Are application logs available? Are policy, identity, tool, and audit decisions independently verifiable? Can the service scale? Can each agent be isolated, suspended, recovered, and rolled back? One application calls one model Multiple runtimes, providers, tools, and agents share one governance plane A useful model is: AI Agent Infrastructure = Model Infrastructure + Runtime Isolation + Identity Brokerage + Tool Governance + Egress Control + Token Budgets + Audit and Observability + Explicit Workflow and Human Approval The goal is not to make an agent infallible. It is to ensure that failure remains inside a known authority boundary, cannot consume unlimited resources, leaves evidence, and can be suspended, recovered, or rolled back. 2. Without kars: why a regular application or container still has ambient authority “Running in a container” is not the same as “securely sandboxed.” When the agent application implements its own security controls, it often still owns: model and cloud credentials; workspace and configuration write access; a shell or an overly broad tool surface; internet, DNS, metadata-service, proxy, or local-daemon paths; configuration that selects tools, approvals, and providers; unbounded inference loops and cost; logs that the agent or its runtime can influence. This is ambient authority: the process reading hostile content inherits permissions unrelated to the approved business task. 2.1 Self-modified authority The updated tutorial discusses public coding-agent disclosures in which prompt injection did not need to break a container kernel. Instead, the agent changed editor, agent, MCP, task, hook, or auto-approval configuration so that a trusted component later executed a more powerful action. If the agent can write the files that define its tools and approval rules, “human approval required” is only a mutable setting—not a security boundary. 2.2 Filesystem escape through paths and symlinks Rejecting a literal .. string is insufficient when a symlink resolves outside the workspace. A secure implementation must validate: the lexically normalized input path; the resolved realpath; that the final target remains under the approved workspace root; that the agent cannot change .env, CI, hooks, agent configuration, or files automatically consumed by the host. 2.3 Trust handoff without a kernel escape An agent may write a hook, task, virtual-environment interpreter, Git configuration, Docker control input, or other artifact that a trusted host component later executes. This is a trust-handoff failure, not necessarily a kernel escape. Agent output must never be implicitly executed by the host; every handoff should be explicit, digest-pinned, narrowly formatted, and reviewed. 2.4 Covert egress Blocking HTTP does not prove that data cannot leave. Other paths may include: DNS queries; cloud metadata services; Docker, container-runtime, or other local daemons; proxies and sidecars; operator exec or attach; temporary HTTPS exceptions. “Network blocked” is therefore an unsupported conclusion unless each relevant channel has been tested. 2.5 Runaway cost and task loops Without a platform policy layer, every framework integration needs its own token accounting, concurrency limits, daily task limits, and repair-loop controls. Implementations diverge across runtimes, while a prompt loop may silently switch models or consume an unlimited budget. 2.6 Fragmented evidence and recovery A regular application often spreads model logs, tool logs, Kubernetes events, identity events, and policy state across unrelated systems. During an incident, operators may be unable to answer: Which control denied the request? Which model, image, source revision, and policy were active? Did the agent attempt DNS, metadata, daemon, HTTPS, or exec access? Did evidence survive pod replacement? How should the workload be safely suspended and recovered? 3. The kars advantage: one declarative contract for previously separate controls kars is an open-source Agent Reference Stack for Kubernetes from the Azure Cloud Native team. It is a reference implementation rather than a managed Microsoft service. The tutorial currently tracks kars v0.1.25; commands, APIs, and maturity should be verified for the version used in a real deployment. Its central model is: One governed sandbox per agent. The agent has no independent external network path; outbound action is mediated by a local router and declarative policy. Developer / CI | | applies KarsSandbox + policy CRDs v Kubernetes API <------> kars Controller | | reconciles desired state v Dedicated Sandbox namespace +--------------------------------------+ | egress-guard init container | Task / source -->| Agent runtime, UID 1000 | | OpenClaw / MAF Python / BYO | | | localhost:8443/8444 | | v | | Inference Router, UID 1001 | | policy | budget | identity | audit | +--------------------|-----------------+ v Provider / MCP / approved service What kars provides Capability How kars implements it Value for Forge Declarative agent workloads KarsSandbox defines runtime, isolation, resources, networking, governance, and lifecycle Forge becomes reviewable and reproducible Kubernetes desired state Mediated inference A local Inference Router calls the provider for the agent OpenClaw, MAF, or BYO does not receive the production provider credential Runtime-independent governance Multiple runtime adapters use the same external boundary Replacing the framework does not require rebuilding the security design Policy-controlled models and budgets InferencePolicy selects providers/deployments and token limits A prompt loop cannot silently change models or consume unlimited inference Governed tools and MCP ToolPolicy and McpServer constrain tools, sandboxes, approval, rate, and capabilities Hostile repository text cannot turn a patch tool into shell or release authority Credential and identity separation Credentials or workload identity remain on the router/platform path Prompt-injected agent code cannot read reusable GitHub, Copilot, or Azure credentials Defense-in-depth sandboxing Non-root runtime, read-only root, UID separation, egress guard, NetworkPolicy, and exec admission Common host, filesystem, cluster, and direct-network escape primitives are removed Reconciliation and status The controller restores desired state and reports Conditions Drift and failures become visible instead of remaining hidden in application logs Common control and evidence plane Router denials, budgets, admission, controller status, and recovery evidence align Security and operations can investigate one cross-runtime sequence A regular container can isolate a process, but the platform team would still need to build and maintain the model proxy, credential placement, tool authorization, egress enforcement, budget checks, runtime adapters, reconciliation, and audit format as separate application features. kars turns those concerns into one reusable workload contract. 4. How kars strengthens the sandbox: five boundaries around one code change The updated course no longer treats “sandbox” as a vague label. It decomposes the boundary into five testable parts. 4.1 Process boundary The agent runs as non-root UID 1000. The router runs as UID 1001. Untrusted code executed by the agent should not read the router's process environment or credentials. Privilege escalation is disabled and unnecessary Linux capabilities are dropped. seccompProfile: kars-strict reduces the syscall surface. Local Docker mode co-locates the agent and router for fast iteration. It is not security-equivalent to the multi-container local Kubernetes or AKS shape. 4.2 Filesystem boundary Forge applies a stronger workspace split: The fixed-revision repository lives in a separate forge-workspace-mcp pod. The repository uses a size-limited, disposable emptyDir. The OpenClaw pod has no repository mount and no hostPath. Developer home directories, SSH material, global Git credentials, and unrelated repositories are not mounted. Automatic service-account-token mounting is disabled for the workspace MCP. The agent accesses the repository through seven bounded MCP tools. Path policy checks normalization and resolved realpath to prevent symlink escape. Prompt-injected code therefore cannot simply browse the host filesystem or rewrite the configuration that defines its own authority. 4.3 Network boundary The agent calls only 127.0.0.1:8443/8444 or a documented proxy path. The router decides whether a model, tool, host, or action is allowed. The egress guard uses UID-aware rules to prevent bypassing the router. Kubernetes NetworkPolicy starts with default deny. Only explicit, auditable destinations are opened. DNS, metadata, local daemons, HTTPS, and operator exec are tested separately. The router is the application-policy decision point. The egress guard and NetworkPolicy are data-plane enforcement and safety nets. Defense in depth requires both. 4.4 Identity boundary In production, the router can use Workload Identity or, in the relevant deployment mode, a per-sandbox Entra Agent ID. The agent does not receive the resulting Azure credential. Local Kubernetes reproduces the pod, UID, and network shape but normally uses a static provider credential for development. It is production-shaped infrastructure, not production identity. 4.5 Lifecycle and evidence boundary The controller watches KarsSandbox and creates, updates, or restores resources. Conditions and observed generations expose real status. The router records request-time policy decisions. The workspace can be discarded after the task. Evidence must be exported before pod or workspace deletion. spec.suspended provides an operational kill switch. Rollback should use pinned source, image, and loaded-policy digests. Ephemeral execution reduces persistence risk, but deleting a suspect pod before exporting evidence may destroy valuable incident context. A reviewable sandbox contract spec: runtime: kind: BYO byo: image: forge-byo-copilot-claw:dev contractVersion: v1 sandbox: isolation: enhanced seccompProfile: kars-strict readOnlyRootFilesystem: true runAsNonRoot: true allowPrivilegeEscalation: false writablePaths: - /sandbox - /tmp networkPolicy: defaultDeny: true egressMode: Strict allowedEndpoints: [] The BYO image also declares its runtime contract and runs as a non-root user: LABEL org.kars.runtime.contract="v1" WORKDIR /app USER 1000 5. From architecture claims to malicious-behavior experiments The updated code/01 introduces: make security-demo The experiment does more than inspect manifest text. It executes malicious-request tests, reads active McpServer and ToolPolicy state, checks credential references on the OpenClaw pod, and attempts a direct HTTPS probe from the agent runtime. The kars-sandbox-exec-ban admission control first denies normal operator kubectl exec into the agent runtime. The experiment records that evidence without using a break-glass bypass. The malicious behavior is stopped at multiple layers: Layer How the attempt is stopped Prompt and coordinator Repository content is marked untrusted and denials are reported Self-configuration isolation Editor, agent, MCP, hook, and auto-approval configuration is outside patch scope Path and symlink isolation Resolved realpath must remain inside the workspace Trust-handoff boundary The agent cannot leave hooks, tasks, or interpreters for the host to execute MCP capability surface No environment reader, arbitrary HTTP, or general shell tool exists Workspace policy Traversal, .env, CI/README writes, and unapproved tests are rejected ToolPolicy and credential isolation Specialists have no workspace action; OpenClaw has no Copilot token Runtime and NetworkPolicy Exec admission denies access; no arbitrary HTTPS/DNS tool exists; egress remains constrained Even if the model fails to recognize prompt injection, the execution layers still constrain authority and side effects. The attack fails because the required capability does not exist—not because the model was merely instructed to behave. 6. Tool governance is not one allow-list McpServer: which tool surface may be registered? The Workspace MCP registers seven business-level capabilities: allowedTools: - workspace_get_task - workspace_read_file - workspace_search - workspace_apply_patch - workspace_run_test - workspace_get_diff - workspace_reset There is no shell, environment dump, file upload, arbitrary network request, or free-form command tool. ToolPolicy: who can call what, and how fast? allowed_actions: - "inference:responses:*" - "tool:workspace_get_task:*" - "tool:workspace_read_file:*" - "tool:workspace_search:*" - "tool:workspace_apply_patch:*" - "tool:workspace_run_test:*" - "tool:workspace_get_diff:*" ToolPolicy can also define request rate, burst, time windows, approvals, trust thresholds, and governance profiles. Tool implementation: are valid tools receiving safe arguments? The Workspace MCP rejects: absolute, traversing, or real paths outside the workspace; .env, CI, README, and writes outside src/; non-unique replacement text; oversized files, patches, and diffs; unapproved test IDs; shell-composed commands. Prompt behavior, tool registration, caller authorization, and argument validation are four separate controls. 7. Token limits must be enforced on the request path The tutorial's InferencePolicy uses per-request and daily budgets: spec: tokenBudget: perRequestTokens: 20000 dailyTokens: 100000 When a client requests max_completion_tokens: 20001, the router returns HTTP 429. That is stronger evidence than seeing submitted YAML because it proves that the policy compiled, loaded, and entered the real request path. Later BYO and release examples use tighter limits: modelPreference: primary: provider: azure-openai deployment: gpt-5.6-sol tokenBudget: perRequestTokens: 1024 dailyTokens: 4096 A platform budget cannot determine whether two patches are equivalent or whether a task exceeded a business deadline. The RepairGuard and framework configuration add controls for: duplicate patch digests; excessive repair attempts; task deadlines; maximum MAF iterations and function calls. Token budgets constrain inference cost; repair guards and framework loop limits constrain business failure. 8. From OpenClaw to MAF: change the application, preserve the external boundary OpenClaw is effective for rapidly discovering the conversation, planning, tool, and specialist behavior the product needs. Production requires explicit state, typed tools, repeatable tests, and a human stop. Forge encodes the workflow as application code: class WorkflowState(StrEnum): RECEIVE_REQUIREMENT = "RECEIVE_REQUIREMENT" VALIDATE_SCOPE = "VALIDATE_SCOPE" INSPECT_REPOSITORY = "INSPECT_REPOSITORY" PROPOSE_PLAN = "PROPOSE_PLAN" APPLY_MINIMAL_PATCH = "APPLY_MINIMAL_PATCH" RUN_TARGETED_TESTS = "RUN_TARGETED_TESTS" SUMMARIZE_EVIDENCE = "SUMMARIZE_EVIDENCE" STOP_FOR_HUMAN_REVIEW = "STOP_FOR_HUMAN_REVIEW" There is deliberately no MERGE or DEPLOY state. In the final code/08 path, the kars MAF Python adapter pins the MAF client to the local router before MAF is imported: from kars_runtime_maf_python import bootstrap bootstrap() from agent_framework import Agent, tool from agent_framework.openai import OpenAIChatClient @tool(approval_mode="never_require") def inspect_release_contract(request_id: str, issue_id: str, revision: str) -> str: # Validate the pinned issue and revision, then return bounded evidence. ... maf_client = OpenAIChatClient(model=MODEL) maf_client.function_invocation_configuration["max_iterations"] = 3 maf_client.function_invocation_configuration["max_function_calls"] = 1 builder = Agent( client=maf_client, name="FabrikamReleaseBuilder", tools=[inspect_release_contract], default_options={"store": False}, ) The resulting path is: OpenClaw Intake -> MAF Agent -> inspect_release_contract @tool -> kars MAF Python adapter -> localhost Router -> GitHub Copilot or the selected provider MAF provides the agent, tool, session, middleware, and workflow programming model. kars provides the identity, network, budget, tool, audit, and lifecycle boundary outside the framework. This is one of kars' most important long-term advantages: the application framework can change without rebuilding the complete security shell. 9. Operational security: do not collapse every event into “the network was blocked” The updated code/06 requires incident response to distinguish: HTTPS; DNS; metadata service; local daemon; operator exec; break-glass access. Every denied channel is recorded in a hash-linked audit chain. Break-glass records without an incident ID are also rejected.\ Controller Conditions + Router Denials + Policy Budgets + Admission Decisions + Workload Recovery = One Investigable Sequence Audit integrity is not audit durability The router can verify the current audit hash chain. The tutorial also validates that pod replacement may reset an in-memory audit log, after which a new valid chain begins. Production deployments must continuously export audit data to an independently controlled durable backend. Otherwise, they can prove that the current chain is intact but cannot prove that pre-incident history survived pod loss. 10. AKS and multi-agent release: separation of authority, not two prompts chatting The AKS promotion separates Forge into Builder and Reviewer roles: Control Builder Reviewer Tokens per request 2048 512 Daily tokens 8192 2048 Tool authority Read, search, patch, test, diff Read diff/evidence and submit a decision Approval mode Never Always Trust threshold 700 800 The Builder may create a patch but cannot approve release. The Reviewer may approve a digest-pinned Builder artifact but cannot change source or approve an artifact created by the Reviewer. The final handoff carries patch, test-evidence, and artifact-manifest digests and still stops for human PR approval. The code/08 final sandbox-escape gate explicitly rejects: self-modified authority; symlink escape; host trust handoff; DNS egress; Builder self-approval; Reviewer source modification; untrusted or expired peer drafts. The release standard therefore becomes: Correct behavior must pass, and credential, network, tool, approval, evidence, and containment boundaries must remain intact. Passing tests alone is not release evidence. 11. What kars does not promise kars strengthens the sandbox, but it does not solve every risk automatically: It does not prove that a generated patch is correct. It does not make untrusted code safe to merge. It cannot protect a credential mistakenly mounted into the agent. Local Docker mode does not become a production boundary. It does not replace tenant RBAC, quotas, image policy, signing, supply-chain controls, or durable audit export. It cannot compensate for a policy that deliberately enables arbitrary shell and unrestricted egress. Confidential isolation does not replace least privilege, tool policy, egress policy, and code review. The sandbox bounds authority and blast radius. Tests, evaluation, independent review, and release policy still determine whether a change is acceptable. 12. An enterprise adoption path with measurable exits Phase 1: define the business and threat contract Specify inputs, outputs, allowed actions, forbidden actions, data boundaries, and the human approval point. Exit: product, platform, and security can all explain the agent's maximum authority. Phase 2: validate one OpenClaw vertical slice Use narrow business MCP tools instead of a general shell, and include hostile repository content. Exit: the normal task succeeds while self-configuration, path/symlink, trust-handoff, and egress tests fail. Phase 3: encode the sandbox as a Kubernetes contract Validate UID separation, root filesystem, capabilities, volumes, service-account tokens, NetworkPolicy, egress guard, and exec admission. Exit: the five boundaries are supported by runtime evidence, not only YAML review. Phase 4: add tool, model, and cost governance Apply McpServer, ToolPolicy, and InferencePolicy. Test unknown tools, dangerous arguments, and token overflow. Exit: violations are denied on the live request path. Phase 5: migrate into explicit MAF code Encode workflow state, typed tools, loop limits, evidence, failure paths, and the human stop. Exit: the MAF runtime preserves the external boundary already proven around the OpenClaw prototype. Phase 6: promote to AKS through GitOps Pin source revision, image digest, and loaded policy digest. Separate Builder and Reviewer authority. Prepare the kill switch, rollback, and durable audit export. Exit: one allowed workflow succeeds, multiple escape and authority-violation scenarios are denied, and all results have correlated evidence. Conclusion: kars does not make the model smarter; it makes agent authority explainable Enterprises will ultimately ask: What can the agent access? Where are the provider credentials? Who defines and changes the tool authority? Can prompt injection move data through DNS, metadata, a daemon, or HTTPS? How many tokens and repair iterations may one task consume? Who may patch, approve, merge, or deploy? Does evidence survive pod loss? If OpenClaw is replaced by MAF, does the security model remain intact? The ByteCraft AI story does not argue for one universal agent framework. It argues for a stable Agent Infrastructure layer: Use OpenClaw to discover valuable behavior quickly, use Microsoft Agent Framework to encode that behavior as explicit and testable application code, and use kars to remove credentials, networking, tools, budgets, sandboxing, audit, and lifecycle authority from the agent application itself. An agent becomes an enterprise workload when it has an independent identity boundary, a budget, a constrained tool surface, controlled egress, exportable evidence, and operational suspension and rollback—not merely when it runs inside a container. References Let's Learn Microsoft kars Microsoft kars408Views5likes0CommentsBuilding HIPAA-Compliant Medical Transcription with Local AI
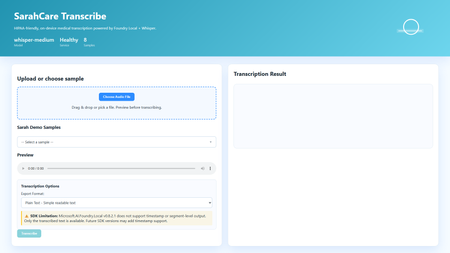
Building HIPAA-Compliant Medical Transcription with Local AI Introduction Healthcare organizations generate vast amounts of spoken content, patient consultations, research interviews, clinical notes, medical conferences. Transcribing these recordings traditionally requires either manual typing (time-consuming and expensive) or cloud transcription services (creating immediate HIPAA compliance concerns). Every audio file sent to external APIs exposes Protected Health Information (PHI), requires Business Associate Agreements, creates audit trails on third-party servers, and introduces potential breach vectors. This sample solution lies in on-premises voice-to-text systems that process audio entirely locally, never sending PHI beyond organizational boundaries. This article demonstrates building a sample medical transcription application using FLWhisper, ASP.NET Core, C#, and Microsoft Foundry Local with OpenAI Whisper models. You'll learn how to build sample HIPAA-compliant audio processing, integrate Whisper models for medical terminology accuracy, design privacy-first API patterns, and build responsive web UIs for healthcare workflows. Whether you're developing electronic health record (EHR) integrations, building clinical research platforms, or implementing dictation systems for medical practices, this sample could be a great starting point for privacy-first speech recognition. Why Local Transcription Is Critical for Healthcare Healthcare data handling is fundamentally different from general business data due to HIPAA regulations, state privacy laws, and professional ethics obligations. Understanding these requirements explains why cloud transcription services, despite their convenience, create unacceptable risks for medical applications. HIPAA compliance mandates strict controls over PHI. Every system that touches patient data must implement administrative, physical, and technical safeguards. Cloud transcription APIs require Business Associate Agreements (BAAs), but even with paperwork, you're entrusting PHI to external systems. Every API call creates logs on vendor servers, potentially in multiple jurisdictions. Data breaches at transcription vendors expose patient information, creating liability for healthcare organizations. On-premises processing eliminates these third-party risks entirely, PHI never leaves your controlled environment. US State laws increasingly add requirements beyond HIPAA. California's CCPA, New York's SHIELD Act, and similar legislation create additional compliance obligations. International regulations like GDPR prohibit transferring health data outside approved jurisdictions. Local processing simplifies compliance by keeping data within organizational boundaries. Research applications face even stricter requirements. Institutional Review Boards (IRBs) often require explicit consent for data sharing with external parties. Cloud transcription may violate study protocols that promise "no third-party data sharing." Clinical trials in pharmaceutical development handle proprietary information alongside PHI, double jeopardy for data exposure. Local transcription maintains research integrity while enabling audio analysis. Cost considerations favor local deployment at scale. Medical organizations generate substantial audio, thousands of patient encounters monthly. Cloud APIs charge per minute of audio, creating significant recurring costs. Local models have fixed infrastructure costs that scale economically. A modest GPU server can process hundreds of hours monthly at predictable expense. Latency matters for clinical workflows. Doctors and nurses need transcriptions available immediately after patient encounters to review and edit while details are fresh. Cloud APIs introduce network delays, especially problematic in rural health facilities with limited connectivity. Local inference provides <1 second turnaround for typical consultation lengths. Application Architecture: ASP.NET Core with Foundry Local The sample FLWhisper application implements clean separation between audio handling, AI inference, and state management using modern .NET patterns: The ASP.NET Core 10 minimal API provides HTTP endpoints for health checks, audio transcription, and sample file streaming. Minimal APIs reduce boilerplate while maintaining full middleware support for error handling, authentication, and CORS. The API design follows OpenAI's transcription endpoint specification, enabling drop-in replacement for existing integrations. The service layer encapsulates business logic: FoundryModelService manages model loading and lifetime, TranscriptionService handles audio processing and AI inference, and SampleAudioService provides demonstration files for testing. This separation enables easy testing, dependency injection, and service swapping. Foundry Local integration uses the Microsoft.AI.Foundry.Local.WinML SDK. Unlike cloud APIs requiring authentication and network calls, this SDK communicates directly with the local Foundry service via in-process calls. Models load once at startup, remaining resident in memory for sub-second inference on subsequent requests. The static file frontend delivers vanilla HTML/CSS/JavaScript, no framework overhead. This simplicity aids healthcare IT security audits and enables deployment on locked-down hospital networks. The UI provides file upload, sample selection, audio preview, transcription requests, and result display with copy-to-clipboard functionality. Here's the architectural flow for transcription requests: Web UI (Upload Audio File) ↓ POST /v1/audio/transcriptions (Multipart Form Data) ↓ ASP.NET Core API Route ↓ TranscriptionService.TranscribeAudio(audioStream) ↓ Foundry Local Model (Whisper Medium locally) ↓ Text Result + Metadata (language, duration) ↓ Return JSON/Text Response ↓ Display in UI This architecture embodies several healthcare system design principles: Data never leaves the device: All processing occurs on-premises, no external API calls No data persistence by default: Audio and transcripts are session-only, never saved unless explicitly configured Comprehensive health checks: System readiness verification before accepting PHI Audit logging support: Structured logging for compliance documentation Graceful degradation: Clear error messages when models unavailable rather than silent failures Setting Up Foundry Local with Whisper Models Foundry Local supports multiple Whisper model sizes, each with different accuracy/speed tradeoffs. For medical transcription, accuracy is paramount—misheard drug names or dosages create patient safety risks: # Install Foundry Local (Windows) winget install Microsoft.FoundryLocal # Verify installation foundry --version # Download Whisper Medium model (optimal for medical accuracy) foundry model add openai-whisper-medium-generic-cpu:1 # Check model availability foundry model list Whisper Medium (769M parameters) provides the best balance for medical use. Smaller models (Tiny, Base) miss medical terminology frequently. Larger models (Large) offer marginal accuracy gains at 3x inference time. Medium handles medical vocabulary well, drug names, anatomical terms, procedure names, while processing typical consultation audio (5-10 minutes) in under 30 seconds. The application detects and loads the model automatically: // Services/FoundryModelService.cs using Microsoft.AI.Foundry.Local.WinML; public class FoundryModelService { private readonly ILogger _logger; private readonly FoundryOptions _options; private ILocalAIModel? _loadedModel; public FoundryModelService( ILogger logger, IOptions options) { _logger = logger; _options = options.Value; } public async Task InitializeModelAsync() { try { _logger.LogInformation( "Loading Foundry model: {ModelAlias}", _options.ModelAlias ); // Load model from Foundry Local _loadedModel = await FoundryClient.LoadModelAsync( modelAlias: _options.ModelAlias, cancellationToken: CancellationToken.None ); if (_loadedModel == null) { _logger.LogWarning("Model loaded but returned null instance"); return false; } _logger.LogInformation( "Successfully loaded model: {ModelAlias}", _options.ModelAlias ); return true; } catch (Exception ex) { _logger.LogError( ex, "Failed to load Foundry model: {ModelAlias}", _options.ModelAlias ); return false; } } public ILocalAIModel? GetLoadedModel() => _loadedModel; public async Task UnloadModelAsync() { if (_loadedModel != null) { await FoundryClient.UnloadModelAsync(_loadedModel); _loadedModel = null; _logger.LogInformation("Model unloaded"); } } } Configuration lives in appsettings.json , enabling easy customization without code changes: { "Foundry": { "ModelAlias": "whisper-medium", "LogLevel": "Information" }, "Transcription": { "MaxAudioDurationSeconds": 300, "SupportedFormats": ["wav", "mp3", "m4a", "flac"], "DefaultLanguage": "en" } } Implementing Privacy-First Transcription Service The transcription service handles audio processing while maintaining strict privacy controls. No audio or transcript persists beyond the HTTP request lifecycle unless explicitly configured: // Services/TranscriptionService.cs public class TranscriptionService { private readonly FoundryModelService _modelService; private readonly ILogger _logger; public async Task TranscribeAudioAsync( Stream audioStream, string originalFileName, TranscriptionOptions? options = null) { options ??= new TranscriptionOptions(); var startTime = DateTime.UtcNow; try { // Validate audio format ValidateAudioFormat(originalFileName); // Get loaded model var model = _modelService.GetLoadedModel(); if (model == null) { throw new InvalidOperationException("Whisper model not loaded"); } // Create temporary file (automatically deleted after transcription) using var tempFile = new TempAudioFile(audioStream); // Execute transcription _logger.LogInformation( "Starting transcription for file: {FileName}", originalFileName ); var transcription = await model.TranscribeAsync( audioFilePath: tempFile.Path, language: options.Language, cancellationToken: CancellationToken.None ); var duration = (DateTime.UtcNow - startTime).TotalSeconds; _logger.LogInformation( "Transcription completed in {Duration:F2}s", duration ); return new TranscriptionResult { Text = transcription.Text, Language = transcription.Language ?? options.Language, Duration = transcription.AudioDuration, ProcessingTimeSeconds = duration, FileName = originalFileName, Timestamp = DateTime.UtcNow }; } catch (Exception ex) { _logger.LogError( ex, "Transcription failed for file: {FileName}", originalFileName ); throw; } } private void ValidateAudioFormat(string fileName) { var extension = Path.GetExtension(fileName).TrimStart('.'); var supportedFormats = new[] { "wav", "mp3", "m4a", "flac", "ogg" }; if (!supportedFormats.Contains(extension.ToLowerInvariant())) { throw new ArgumentException( $"Unsupported audio format: {extension}. " + $"Supported: {string.Join(", ", supportedFormats)}" ); } } } // Temporary file wrapper that auto-deletes internal class TempAudioFile : IDisposable { public string Path { get; } public TempAudioFile(Stream sourceStream) { Path = System.IO.Path.GetTempFileName(); using var fileStream = File.OpenWrite(Path); sourceStream.CopyTo(fileStream); } public void Dispose() { try { if (File.Exists(Path)) { File.Delete(Path); } } catch { // Ignore deletion errors in temp folder } } } This service demonstrates several privacy-first patterns: Temporary file lifecycle management: Audio written to temp storage, automatically deleted after transcription No implicit persistence: Results returned to caller, not saved by service Format validation: Accept only supported audio formats to prevent processing errors Comprehensive logging: Audit trail for compliance without logging PHI content Error isolation: Exceptions contain diagnostic info but no patient data Building the OpenAI-Compatible REST API The API endpoint mirrors OpenAI's transcription API specification, enabling existing integrations to work without modifications: // Program.cs var builder = WebApplication.CreateBuilder(args); // Configure services builder.Services.Configure( builder.Configuration.GetSection("Foundry") ); builder.Services.AddSingleton(); builder.Services.AddScoped(); builder.Services.AddHealthChecks() .AddCheck("foundry-health"); var app = builder.Build(); // Load model at startup var modelService = app.Services.GetRequiredService(); await modelService.InitializeModelAsync(); app.UseHealthChecks("/health"); app.MapHealthChecks("/api/health/status"); // OpenAI-compatible transcription endpoint app.MapPost("/v1/audio/transcriptions", async ( HttpRequest request, TranscriptionService transcriptionService, ILogger logger) => { if (!request.HasFormContentType) { return Results.BadRequest(new { error = "Content-Type must be multipart/form-data" }); } var form = await request.ReadFormAsync(); // Extract audio file var audioFile = form.Files.GetFile("file"); if (audioFile == null || audioFile.Length == 0) { return Results.BadRequest(new { error = "Audio file required in 'file' field" }); } // Parse options var format = form["format"].ToString() ?? "text"; var language = form["language"].ToString() ?? "en"; try { // Process transcription using var stream = audioFile.OpenReadStream(); var result = await transcriptionService.TranscribeAudioAsync( audioStream: stream, originalFileName: audioFile.FileName, options: new TranscriptionOptions { Language = language } ); // Return in requested format if (format == "json") { return Results.Json(new { text = result.Text, language = result.Language, duration = result.Duration }); } else { // Default: plain text return Results.Text(result.Text); } } catch (Exception ex) { logger.LogError(ex, "Transcription request failed"); return Results.StatusCode(500); } }) .DisableAntiforgery() // File uploads need CSRF exemption .WithName("TranscribeAudio") .WithOpenApi(); app.Run(); Example API usage: # PowerShell $audioFile = Get-Item "consultation-recording.wav" $response = Invoke-RestMethod ` -Uri "http://localhost:5192/v1/audio/transcriptions" ` -Method Post ` -Form @{ file = $audioFile; format = "json" } Write-Output $response.text # cURL curl -X POST http://localhost:5192/v1/audio/transcriptions \ -F "file=@consultation-recording.wav" \ -F "format=json" Building the Interactive Web Frontend The web UI provides a user-friendly interface for non-technical medical staff to transcribe recordings: SarahCare Medical Transcription The JavaScript handles file uploads and API interactions: // wwwroot/app.js let selectedFile = null; async function checkHealth() { try { const response = await fetch('/health'); const statusEl = document.getElementById('status'); if (response.ok) { statusEl.className = 'status-badge online'; statusEl.textContent = '✓ System Ready'; } else { statusEl.className = 'status-badge offline'; statusEl.textContent = '✗ System Unavailable'; } } catch (error) { console.error('Health check failed:', error); } } function handleFileSelect(event) { const file = event.target.files[0]; if (!file) return; selectedFile = file; // Show file info const fileInfo = document.getElementById('fileInfo'); fileInfo.textContent = `Selected: ${file.name} (${formatFileSize(file.size)})`; fileInfo.classList.remove('hidden'); // Enable audio preview const preview = document.getElementById('audioPreview'); preview.src = URL.createObjectURL(file); preview.classList.remove('hidden'); // Enable transcribe button document.getElementById('transcribeBtn').disabled = false; } async function transcribeAudio() { if (!selectedFile) return; const loadingEl = document.getElementById('loadingIndicator'); const resultEl = document.getElementById('resultSection'); const transcribeBtn = document.getElementById('transcribeBtn'); // Show loading state loadingEl.classList.remove('hidden'); resultEl.classList.add('hidden'); transcribeBtn.disabled = true; try { const formData = new FormData(); formData.append('file', selectedFile); formData.append('format', 'json'); const startTime = Date.now(); const response = await fetch('/v1/audio/transcriptions', { method: 'POST', body: formData }); if (!response.ok) { throw new Error(`HTTP ${response.status}: ${response.statusText}`); } const result = await response.json(); const processingTime = ((Date.now() - startTime) / 1000).toFixed(1); // Display results document.getElementById('transcriptionText').value = result.text; document.getElementById('resultDuration').textContent = `Duration: ${result.duration.toFixed(1)}s`; document.getElementById('resultLanguage').textContent = `Language: ${result.language}`; resultEl.classList.remove('hidden'); console.log(`Transcription completed in ${processingTime}s`); } catch (error) { console.error('Transcription failed:', error); alert(`Transcription failed: ${error.message}`); } finally { loadingEl.classList.add('hidden'); transcribeBtn.disabled = false; } } function copyToClipboard() { const text = document.getElementById('transcriptionText').value; navigator.clipboard.writeText(text) .then(() => alert('Copied to clipboard')) .catch(err => console.error('Copy failed:', err)); } // Initialize window.addEventListener('load', () => { checkHealth(); loadSamplesList(); }); Key Takeaways and Production Considerations Building HIPAA-compliant voice-to-text systems requires architectural decisions that prioritize data privacy over convenience. The FLWhisper application demonstrates that you can achieve accurate medical transcription, fast processing times, and intuitive user experiences entirely on-premises. Critical lessons for healthcare AI: Privacy by architecture: Design systems where PHI never exists outside controlled environments, not as a configuration option No persistence by default: Audio and transcripts should be ephemeral unless explicitly saved with proper access controls Model selection matters: Whisper Medium provides medical terminology accuracy that smaller models miss Health checks enable reliability: Systems should verify model availability before accepting PHI Audit logging without content logging: Track operations for compliance without storing sensitive data in logs For production deployment in clinical settings, integrate with EHR systems via HL7/FHIR interfaces. Implement role-based access control with Active Directory integration. Add digital signatures for transcript authentication. Configure automatic PHI redaction using clinical NLP models. Deploy on HIPAA-compliant infrastructure with proper physical security. Implement comprehensive audit logging meeting compliance requirements. The complete implementation with ASP.NET Core API, Foundry Local integration, sample audio files, and comprehensive tests is available at github.com/leestott/FLWhisper. Clone the repository and follow the setup guide to experience privacy-first medical transcription. Resources and Further Reading FLWhisper Repository - Complete C# implementation with .NET 10 Quick Start Guide - Installation and usage instructions Microsoft Foundry Local Documentation - SDK reference and model catalog OpenAI Whisper Documentation - Model architecture and capabilities HIPAA Compliance Guidelines - HHS official guidance Testing Guide - Comprehensive test suite documentationBuilding and Deploying Microsoft Hosted Agents to Microsoft Teams
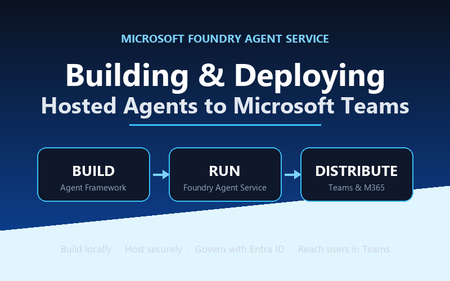
A practical, engineer-to-engineer guide to taking an AI agent from a developer laptop, into Microsoft Foundry Agent Service, and out to end users inside Microsoft Teams and Microsoft 365 — using the BRK241 FibreOps reference implementation as a worked example. Introduction: the hard part is no longer building the agent Two years ago, wiring an LLM to a couple of tools felt like the summit. It isn't any more. Frameworks, hosted models, and function-calling have made the build step almost routine. The problem has quietly moved downstream. The genuinely hard questions today are operational: Where does the agent run when it's no longer on your machine? What identity does it use to call enterprise systems, and who granted it? How does a platform team scale, monitor, and roll it back? How do business users actually reach it without learning a new tool? Who signed off on it touching production data? A prototype answers none of these. A production agent platform answers all of them, repeatably, for every agent an organisation ships. That shift — from a clever notebook to a governed, observable service that lands in the tools people already use — is the subject of this article. We'll use a single narrative to keep it concrete: FibreOps, the BRK241 "Autonomous Fibre Outage Response" system. It ingests optical line terminal (OLT) telemetry, analyses incidents, files tickets in Dynamics 365 Field Service, posts Adaptive Cards to Microsoft Teams, and dispatches engineers — all through role-specialised agents. The full source is on GitHub. The story runs on three verbs: Build → Run → Distribute. Section 1: Building the agent An agent is not one mega-prompt. FibreOps is deliberately factored into three role-specialised agents behind a single orchestrator, each with its own tool surface, its own system instructions, and a strict output contract: IncidentAnalysisAgent — classifies severity, finds probable cause, and pulls the correct standard operating procedure (SOP). NetOpsCoordinatorAgent — files the D365 incident and posts the Teams outage notice. FieldDispatchAgent — selects the best engineer by skill, region and shift, books the resource, and updates Teams. The Coordinator hands off to Dispatch with a literal HANDOFF:DISPATCH token rather than a fuzzy "I think we should…". Hard contracts between agents are how you stop them inventing work. Microsoft Agent Framework The agents are built with the Microsoft Agent Framework (MAF). The key design decision in the reference implementation is that all three backends honour one contract — await agent.run(prompt) -> response — so the orchestrator never knows or cares where reasoning actually happens: local — a deterministic LocalAgent shim with no LLM, so the demo runs with zero Azure credentials. foundry — agent_framework.Agent + FoundryChatClient , definition resolved locally. Ideal while iterating on prompts. hosted — agent_framework_foundry.FoundryAgent bound to a Prompt Agent published to Foundry Agent Service. This is the production path. Building a Foundry-backed agent is just a client plus instructions plus typed tools: from agent_framework import Agent from agent_framework_foundry import FoundryChatClient from azure.identity import DefaultAzureCredential client = FoundryChatClient( project_endpoint=settings.azure_ai_project_endpoint, model=settings.azure_ai_model_deployment, # e.g. gpt-4.1-mini credential=DefaultAzureCredential(), # no connection strings, ever ) agent = Agent( client=client, instructions=INCIDENT_ANALYSIS_INSTRUCTIONS_V1, name="IncidentAnalysisAgent", tools=[lookup_sop, recall, remember, web_iq_search, work_iq_search], ) Note the DefaultAzureCredential . There are no keys or connection strings anywhere in the reasoning path — identity flows from Microsoft Entra ID. Keep that in mind; it becomes the backbone of the governance story later. Tool calling and MCP Every tool is a typed Python function. Foundry sees the JSON schema derived from the signature; the runtime executes the Python. That separation matters: the published agent definition stores only the model and instructions, while the implementations are supplied by the runtime on every call. The same in-process tools (Teams, D365, dispatch, knowledge, memory) run identically whether the agent is local or hosted. Beyond your own functions, Foundry agents can draw on hosted toolbox tools ( web_search , code_interpreter ) and Model Context Protocol (MCP) servers. MCP is the open standard for exposing tools, resources and prompts to agents over a uniform protocol, so an enterprise can stand up an MCP server once and let every agent consume it. In FibreOps this is config-gated — set FIBREOPS_FOUNDRY_TOOLBOX=1 and the incident analyst gains live web search alongside its Web IQ / Work IQ connectors, with no code change. Grounding strategies FibreOps grounds reasoning three ways, in layers: Retrieval over owned knowledge — SOPs (markdown) and the fibre-node topology graph, looked up by the analysis agent. Foundry IQ — Web IQ for public context (roadworks, weather, power) and Work IQ for enterprise context (site surveys, SLA tiers, competency matrix). Procedural memory — prior incidents for a node, recalled before analysis so the agent learns from history. Crucially, when the IQ endpoints are unset the tools fall back to deterministic fixtures so the agent always grounds. Grounding that silently fails is worse than no grounding; design your fallbacks explicitly. Local development, testing and evaluation The whole system runs from one command with no cloud dependency: # Deterministic local backend — no Azure credentials required python -m fibreops.demo --signals 3 --backend local Every run is persisted as a JSON document — the input signal, every agent step, every tool call, every output, every ticket. That single artefact shape feeds three consumers: structured logs, the local optimiser, and Foundry Evaluators. The optimiser scores each run against a five-criterion rubric (was the analysis complete, was severity consistent with customer impact, did a ticket land, did dispatch policy match severity, was an SOP cited) and writes back concrete improvement suggestions. That evaluation loop — not the first working demo — is what turns a prototype into a system you can keep improving. Section 2: Deploying to Microsoft Foundry Agent Service Microsoft Foundry Agent Service is the managed runtime that hosts your agents. It gives you a secure, isolated execution environment, an agent runtime that speaks the OpenAI-compatible Responses API, plus hosted memory, toolboxes, knowledge integrations, and observability — without you operating any of it. FibreOps demonstrates the two hosting shapes Foundry offers. Shape 1 — Prompt Agents A Prompt Agent stores a model deployment plus system instructions as an immutable, versioned definition in Foundry. Publishing is a one-time step per change: from azure.ai.projects import AIProjectClient from azure.ai.projects.models import PromptAgentDefinition from azure.identity import DefaultAzureCredential pc = AIProjectClient(endpoint=endpoint, credential=DefaultAzureCredential(), allow_preview=True) pc.agents.create_version( agent_name="fibreops-incident-analysis", definition=PromptAgentDefinition( model=model_deployment, instructions=INCIDENT_ANALYSIS_INSTRUCTIONS_V1, ), description="FibreOps incident analysis agent", ) At run time you bind to the published version with a FoundryAgent , and — as noted above — the runtime supplies the tool implementations. Prompt versioning ( instructions_v1 , _v2 , _v3 ) is where the optimiser's suggestions land, closing the improvement loop inside the platform. Shape 2 — Containerised hosted agents The BRK241 hero path packages the entire analyse → coordinate → dispatch flow as a single hosted agent: a container that serves the Responses /responses contract on port 8088, deployed straight into your Foundry project. The Agent Framework agent is wrapped by ResponsesHostServer : from agent_framework_foundry_hosting import ResponsesHostServer def main() -> None: server = ResponsesHostServer(build_system_agent()) # Foundry sets the reserved PORT env var inside the sandbox server.run(host="0.0.0.0", port=8088) The container is declared in agent.yaml — kind: hosted , the image reference, the per-session sandbox size (0.5/1 Gi, 1/2 Gi or 2/4 Gi), the protocol version, and only user-declared environment variables. You never hard-code FOUNDRY_* values or the Application Insights connection string; the platform injects those at run time. Deployment registers the image as an immutable version and polls until active : details = pc.agents.create_version( agent_name="fibreops-outage-response", definition=HostedAgentDefinition( protocol_versions=[ProtocolVersionRecord( protocol=AgentProtocol.RESPONSES, version="1.0.0")], cpu="1", memory="2Gi", container_configuration=ContainerConfiguration(image=image), environment_variables={"MODEL_DEPLOYMENT_NAME": model_deployment}, ), ) From local execution to managed hosting The migration path is deliberately gentle because the contract never changes. A developer iterates locally against LocalAgent , moves to the foundry backend to test real prompts, then publish es Prompt Agents or builds and deploy-hosted s the container. The orchestrator code is byte-for-byte identical across all three. That property — same code path local for dev, hosted in Foundry for prod — is the single most important thing to preserve when designing your own agents. Scaling, memory, toolboxes, knowledge and observability Scaling — Foundry provisions a per-session sandbox and a dedicated Entra agent identity per hosted-agent version; you size the sandbox in agent.yaml and let the platform handle isolation. Memory — set FOUNDRY_MEMORY_STORE_NAME and a FoundryMemoryProvider is attached as a context provider so agents read and write learned procedures in Foundry's hosted store; unset, they use local SQLite. No code change. Toolboxes & knowledge — hosted web_search , code interpreter, MCP, and Web/Work IQ connectors are curated per role and merged with your Python tools. Observability — the agent emits OpenTelemetry spans; set APPLICATIONINSIGHTS_CONNECTION_STRING (injected by the platform for hosted agents) and every agent decision, tool call and latency is queryable in Application Insights. Section 3: IT and development responsibilities Successful agent deployments need both developer velocity and platform governance. The failure mode at either extreme is familiar: developers who can't ship because every request routes through a ticket queue, or a free-for-all where nobody can say what identity an agent runs as. The workable model draws a clean line of responsibility. Concern Developer / Agent team IT / Platform team Identity Use DefaultAzureCredential ; never embed secrets; declare the scopes the agent needs Provision the managed / Entra agent identity; own the app registration and consent Access control Request least-privilege roles for the tools the agent calls Grant RBAC at the correct scope; run role-assignment scripts; enforce approvals Security Validate inputs, handle tool failures cleanly, avoid data exfiltration in prompts Disable ACR admin, enforce managed-identity pulls, network controls, Key Vault for secrets Compliance Keep decisions explainable and replayable (the JSON run record) Data-residency, retention, audit, Responsible AI review sign-off Monitoring Emit structured traces + OTel spans; define the rubric Own Application Insights / Log Analytics, alerting, dashboards, SLOs Cost Right-size the sandbox and model deployment; cache grounding Budgets, quota, token-consumption monitoring, chargeback Lifecycle Version prompts and images; feed the optimiser back into new versions Environment promotion (dev → test → prod), rollback, deprecation The reference implementation encodes this split honestly. The Bicep template does not create role assignments, because most deployers only hold Contributor . Instead a subscription Owner runs scripts/grant-mi-roles.ps1 once to grant the App Service's identity exactly the roles it needs — Event Hubs Data Owner, Key Vault Secrets User, AcrPull, Azure AI Developer, and Cognitive Services OpenAI User — and no more. That is least privilege made operational. Section 4: Publishing to Microsoft Teams and Microsoft 365 An agent nobody can reach has no value. The final verb — Distribute — puts the agent where users already work. FibreOps reaches Teams two ways. The lightweight path: Adaptive Cards via Incoming Webhook The NetOps coordinator posts outage notices and status updates to a Teams channel as Adaptive Cards through an Incoming Webhook. Any unconfigured channel is logged to state/teams_outbox.jsonl , so the same code runs in a demo and in production — you only change the webhook target. This is the fastest way to get agent output into Teams and is ideal for notifications and human-in-the-loop review. The rich path: a declarative agent for Microsoft 365 Copilot To make the agent conversational and discoverable across Teams, Microsoft 365 Copilot and copilot.microsoft.com, FibreOps ships as a declarative agent plus an API plugin action. One command builds the sideload-ready package: python -m fibreops.demo publish-m365 --out dist/m365 # wrote declarativeAgent.json (name, description, conversation starters) # wrote fibreops-action.json (API plugin -> {base_url}/openapi.json) # wrote manifest.json (Teams app manifest) # wrote color.png / outline.png (icons) # wrote fibreops-copilot.zip (upload this) The declarative agent declares metadata, conversation starters and a capability set; the action plugin proxies tool calls to the deployed FastAPI app via its OpenAPI document. Set M365_ACTION_BASE_URL to the app's public HTTPS root before publishing — the CLI warns when the placeholder is still in effect. That single environment variable is the only thing that flips the package from demo to production. The end-to-end distribution workflow Conceptually, the artefact travels a fixed pipeline: Developer laptop │ build + test (local backend) → publish Prompt Agent / deploy hosted container ▼ Microsoft Foundry Agent Service │ hosted agent, secure sandbox, Entra agent identity, observability ▼ Teams App package (fibreops-copilot.zip) │ Teams Admin Center → Manage apps → Upload (or M365 Admin Center → Integrated apps) ▼ Microsoft 365 tenant │ admin approval, availability policy, targeted rollout ▼ End user in Teams / M365 Copilot Enterprise rollout is rarely "publish to everyone". The realistic pattern is a staged one: sideload to a pilot group, gather feedback and optimiser scores, then widen availability through Teams app-permission and app-setup policies to department, then tenant. Because the package carries publisher metadata and the declarative schema, IT can review it exactly like any other line-of-business app. Section 5: Enterprise governance Governance is not a bolt-on; in this architecture it's a property of the platform. The pillars: Entra ID integration and agent identity — every hosted agent version gets a dedicated Entra agent identity. Nothing authenticates with a shared key. DefaultAzureCredential means the same code picks up a developer's identity locally and the managed identity in production. RBAC at the right scope — roles are granted to identities, not baked into images. Deploying a hosted agent requires Azure AI Project Manager at project scope; the Foundry project identity needs AcrPull on the registry to pull the container. Least privilege is enforced, not assumed. Auditability — the JSON run record plus OpenTelemetry spans in Application Insights give you a replayable, per-incident audit trail. You can reconstruct exactly which SOP was cited, which engineer was chosen, and why severity was escalated. Data boundaries — the mock D365 is a drop-in for a real Dataverse environment; grounding sources are enterprise connectors (Work IQ) kept inside the tenant boundary. Nothing leaves the subscription without an explicit connector. Responsible AI — the Adaptive Card JSON can be pasted into the Adaptive Cards designer for governance review; the evaluation rubric makes quality measurable; explicit grounding fallbacks prevent silent failure. Production readiness — immutable versioning, one-command rollback (delete a version), managed-identity-only image pulls, and disabled ACR admin credentials are all first-class in the reference deployment. Section 6: Reference architecture The following diagram shows the production topology — users on the left, enterprise systems and controls on the right, with Foundry Agent Service at the centre hosting the agent. flowchart LR User["NOC operator / business user"] subgraph M365["Microsoft 365 tenant"] Teams["Microsoft Teams(Adaptive Cards + declarative agent)"] Copilot["Microsoft 365 Copilot"] end subgraph Foundry["Microsoft Foundry Agent Service"] Hosted["Hosted AgentOutage Response System(secure per-session sandbox)"] Runtime["Agent runtime(Responses API)"] Memory["Hosted memory + toolboxes"] end subgraph Enterprise["Enterprise data & tools"] MCP["MCP servers / web_search"] D365["Dynamics 365 Field Service"] EventHub["Azure Event Hubs(OLT telemetry)"] Knowledge["SOPs + topology + Web/Work IQ"] end subgraph Ops["Cross-cutting"] Obs["ObservabilityApp Insights / OTel"] Gov["GovernanceEntra ID · RBAC · audit"] end User --> Teams User --> Copilot Teams --> Runtime Copilot --> Runtime Runtime --> Hosted Hosted --> Memory Hosted --> MCP Hosted --> Knowledge Hosted --> D365 EventHub --> Hosted Hosted -.->|Adaptive Cards| Teams Hosted --> Obs Gov -.->|identity & policy| Foundry Gov -.->|identity & policy| Enterprise Read the solid arrows as the control/orchestration flow and the dashed arrows as governance and outbound notifications. The point of the diagram is that governance (Entra ID, RBAC, audit) applies across every component, and observability captures every agent decision — neither is optional plumbing. Section 7: What production looks like Picture the FibreOps rollout at a national fibre operator, with the four personas doing their part: Developers build the three agents and the orchestrator on their laptops against the local backend — no cloud, no credentials, deterministic tests. They tune prompts against the foundry backend, watch the optimiser rubric climb from 0.90 to 1.0 as they add the ">5,000 customers ⇒ escalate to critical" rule, and commit a new instruction version. The platform team deploys the container to Foundry Agent Service via scripts/deploy-hosted-agent.ps1 , which builds the image in ACR, pushes it, and registers an immutable version. They provision the Event Hub, Key Vault, Log Analytics and Application Insights from Bicep, and size the sandbox at 1 vCPU / 2 GiB. IT approves the workload: a subscription Owner grants the managed identity its five least-privilege roles, hardens the App Service to pull via managed identity, disables ACR admin, and signs off the Responsible AI review using the replayable run records and the Adaptive Card previews. They sideload fibreops-copilot.zip to a pilot channel first. Business users consume it inside Teams. When an OLT in London loses light, an Adaptive Card appears in the NOC channel within seconds — severity, probable cause, ticket ID, and the dispatched engineer's ETA — with no human having read a dashboard, opened a ticket, or phoned a dispatcher. If Foundry ever wobbles, the same system falls back to the deterministic local agent with an identical trace shape. Every integration but D365 is live in the demo, and D365 is a one-variable swap to a real Dataverse endpoint. That is the whole point: the demo and production differ by configuration, not by code. Key takeaways Design for one contract. If agent.run(prompt) behaves identically local, foundry-backed and hosted, migration to production is configuration, not a rewrite. Factor agents by role with hard handoff contracts. Literal tokens like HANDOFF:DISPATCH beat fuzzy natural-language handoffs and stop agents inventing work. Never embed secrets. DefaultAzureCredential + Entra agent identities give you keyless auth that works the same everywhere. Make every run replayable. A single JSON artefact that feeds logs, evaluation and audit is worth more than any dashboard. Ground explicitly, and design your fallbacks. Grounding that fails silently is a liability; deterministic fixtures keep the agent honest. Split responsibility cleanly. Developers own velocity and quality; the platform team owns identity, scale, cost and promotion. Encode the split in scripts, not tribal knowledge. Version prompts and images immutably. Rollback should be "delete a version", and the optimiser's suggestions should land as the next version. Distribute where users already are. Adaptive Cards for notifications, a declarative agent for conversation and discovery across Teams and M365 Copilot. Roll out in stages. Pilot channel → department → tenant, gated by app policies and real optimiser scores. Resources Reference implementation: github.com/leestott/BRK241-frontier Microsoft Agent Framework overview Microsoft Foundry Agent Service Hosted agents in Foundry Agent Service · Deploy a hosted agent Microsoft Teams developer platform Declarative agents for Microsoft 365 Copilot Model Context Protocol GitHub Copilot Clone the repo, run python -m fibreops.demo --signals 3 --backend local , and watch the analyse → coordinate → dispatch loop close. Then wire in your own Foundry project and take it all the way to Teams. Go build something.Your Entire Agentic AI Workflow, Now Inside VS Code: New Course Available
If you build with AI, you know the tax: jumping between a browser portal to pick a model, a terminal to run it, a separate playground to test a prompt, and finally your editor to write the code. Every context switch is a small drain on focus—and it adds up. What if the whole loop lived in the one tool you never leave? That's the promise of the Foundry Toolkit for Visual Studio Code, and it's exactly what our new VS Code Learn: Foundry Toolkit video series is here to show youBuilding Agents in Production with Toolbox, Skills, and Tool Search
If you are shipping AI agents beyond a demo, you have felt the pain: every agent needs the same tools, each with its own authentication, and the tool list keeps growing until your prompt is bloated and the model picks the wrong one. On 22 July 2026 at 5:00 PM BST, the Microsoft Foundry community is running a 40-minute Discord round table to talk about exactly this, and to gather your feedback on three capabilities built to fix it: Toolbox, Skills, and Tool Search. This is a discussion, not a slideshow. Bring your real projects, including tool sprawl, duplicated skills, and authentication headaches, and help shape where these features go next. Join us in the Microsoft Foundry Discord community. Event at a glance What: Microsoft Foundry Discord Community Round Table: Building Agents in Production with Foundry Toolbox, Skills, and Tool Search When: 22 July 2026, 5:00 PM BST (40 minutes) Where: https://aka.ms/foundry/discord Event Link https://discord.gg/Z8JZsrP5P5?event=1527379174061379584 Format: Interactive discussion with voice and chat, live polls, and a short prioritisation exercise Who it's for: AI engineers and developers building and scaling agents in production Opening question we'll start with: "As your agents grow, how do you decide which tools to give them, and how do they pick the right one at runtime?" The problem: agents don't scale by hard-wiring every tool When several agents, or a mix of Foundry hosted agents, Microsoft Agent Framework, LangGraph, and Copilot SDK apps, need the same governed set of tools, you do not want to re-wire those tools and their authentication into every one. Two things break as you grow: Integration sprawl: the same tool gets wired, authenticated, and versioned separately in every agent. Tool overload: sending every tool definition to the model on every turn is slow, expensive, and hurts selection accuracy. The pattern that scales: package the tools once behind a single versioned, governed MCP endpoint, make them discoverable, and let every runtime consume them from the same URL. That is what Toolbox, Skills, and Tool Search deliver together. The three concepts we'll discuss Toolbox: build once, govern centrally, consume anywhere A Toolbox is a reusable, centrally managed bundle of tools exposed through a single MCP-compatible endpoint. Because it is a managed resource, you can add, remove, or reconfigure tools without changing agent code because every agent connects to the same endpoint. Immutable versioning gives you safe, atomic rollouts: build and test a new version on its pinned URL, then promote it to default, and every consumer picks it up with no redeployment. Skills: reusable, composable capabilities A Skill is a reusable, published set of behavioural instructions (a SKILL.md file following the open Agent Skills spec) that is registered once and reused across toolboxes and agents, for example, "summarize document" or "create calendar event". In a toolbox, a skill is not a callable tool: it surfaces as an MCP Resource on the same endpoint, so clients discover and read it with plain resources/list and resources/read, with no Foundry SDK required. Tool Search: runtime discovery instead of hard-wiring A real toolbox can hold dozens or hundreds of tools. Tool Search keeps that cheap for the model through progressive disclosure: instead of listing every tool, Foundry shows the model just two meta-tools, tool_search and call_tool, plus any pinned tools. The model searches for a capability by intent, Foundry ranks the toolbox's tools by match on name and description, and returns only the hits. The prompt stays small no matter how many tools the toolbox holds. How they fit together: Skills and tools live in a Toolbox; Tool Search lets agents scale to many tools without prompt bloat or manual wiring. You manage all of it from the Foundry portal or the Foundry Toolkit extension in VS Code. The scenario we'll walk through A user asks an agent to "summarize this email and schedule a follow-up." The agent uses Tool Search to find the right tools ("email summarization" and "calendar scheduling") from a shared Toolbox, chains them, and returns a result with no per-agent integration and no hard-coded tool list. Discussion prompt: "At what point does the number of tools in your agent start to hurt, and would Tool Search help?" A peek at the code (so you arrive ready) The full, runnable walkthrough lives in the Mastering Foundry Toolbox notebook in the microsoft-foundry/forgebook repo. The core spine is short. First, build a versioned toolbox from typed tool objects plus an optional list of skills: # Build an immutable toolbox version from typed tools + skills version = project.toolboxes.create_version( name=TOOLBOX_NAME, description="Search, code, knowledge, and connection-backed tools.", tools=tools, # e.g. WebSearchToolboxTool(...), AzureAISearchToolboxTool(...) skills=skills or None, # ToolboxSkillReference(name=..., version=...) - SEPARATE from tools ) print(f"Created {TOOLBOX_NAME} version {version.version}") Then turn the same tools into a search-first toolbox by adding the Tool Search meta-tool and pinning only your one or two hottest tools: from azure.ai.projects.models import ToolboxSearchPreviewToolboxTool, ToolConfig # Pin the hottest tool so it's always exposed; everything else is search-gated. tool_configs = {"web_search": ToolConfig(pin=True)} search_version = project.toolboxes.create_version( name=TOOLBOX_NAME, tools=tools + [ToolboxSearchPreviewToolboxTool(tool_configs=tool_configs)], skills=skills or None, ) Every consumer talks to the same MCP endpoint: one URL, any framework: # The default (promoted) version is served from one stable consumer URL def consumer_mcp_url(name): return f"{PROJECT_ENDPOINT.rstrip('/')}/toolboxes/{name}/mcp?api-version=v1" # Microsoft Agent Framework speaks MCP natively - just point it at the URL. # LangGraph (AzureAIProjectToolbox) and the GitHub Copilot SDK consume the same endpoint. How Toolbox simplifies the auth and identity flow This is one of the most important things to understand before you scale agents, and it is a great topic to bring questions on. A toolbox tool reaches a downstream system through a project connection, and the connection's authentication type decides whose identity is used. Get this right once and every consumer inherits correct, least-privilege access automatically, without writing OAuth or token-exchange plumbing in your agent code. Running a toolbox behind a hosted agent puts two identities in play, and the platform wires them together for you: Agent -> Toolbox (the trust boundary). The hosted agent authenticates to the toolbox MCP endpoint with its own agent identity, which holds the Foundry user role on the project. If the agent doesn't have access, the toolbox rejects the agent. This gates access to the toolbox itself, independent of any single tool. Toolbox -> Tool (the end-user passthrough). For oauth2 authentication, the agent forwards the caller's end-user Entra token, and the toolbox uses that token (on-behalf-of) to reach the downstream tool. The tool then acts on behalf of the real end user, providing per-user, least-privilege access with correct downstream audit. For non-passthrough authentication types (none, custom-keys, project-managed-identity, and agentic-identity), the toolbox authenticates using the connection's configured identity, and the agent never sees the secret. That is the "better-together" story: a stable, governable managed identity to the toolbox, plus true end-user identity on the downstream data call. What we'll cover in the 40 minutes https://discord.gg/Z8JZsrP5P5?event=1527379174061379584 Welcome & framing (0:00-0:08): what Toolbox, Skills, and Tool Search are, and how they fit together. Scenario walkthrough (0:08-0:13): the "summarize email, schedule follow-up" flow, end to end. Use cases & opportunities (0:13-0:22): which capabilities you would package as reusable Skills, how many tools your agents carry, and where Tool Search would help. Trust, security & governance (0:22-0:31): what you are comfortable exposing through a shared endpoint, how to scope which tools an agent may discover, authentication models, and the observability you need. Developer experience feedback (0:31-0:36): your biggest adoption blockers, missing docs, and the SDK samples and end-to-end demos you would prioritise. Prioritisation & next steps (0:36-0:40): vote live on the top use cases, challenges, and feature requests. Come prepared to talk about What tools and skills your agents use today, and how they're wired up. Which capabilities you'd turn into reusable, composable Skills shared across agents. How many tools your agents carry, and whether you hit prompt-size or tool-selection accuracy issues. Which tools you'd expose through a shared endpoint, and which need tighter scoping. How you want to control what an agent is allowed to discover and invoke with Tool Search. The examples, samples, and tutorials that would help you get started fastest. Responsible and secure by design Because these features let agents discover and invoke tools dynamically, governance is a first-class part of the conversation. Foundry toolboxes are governed by default: you can screen every tool's inputs and outputs with an RAI guardrail, front your MCP servers with a bring-your-own AI gateway (APIM), scope which tools are discoverable, and use least-privilege identity passthrough so downstream calls carry the real user's permissions and audit trail. Bring your enterprise safeguard requirements because they directly shape the roadmap. Note: Toolbox, Tool Search, and Skills are in preview; APIs and headers may change. Key takeaways Toolbox packages tools once behind a single governed, versioned MCP endpoint, so you can build once and consume from any framework. Skills are reusable, composable capabilities you register once and chain across agents. Tool Search uses two meta-tools and progressive disclosure so agents scale to hundreds of tools without prompt bloat. Auth is simplified: the agent's managed identity gates the toolbox, while end-user token passthrough gives correct, least-privilege downstream access with no OAuth plumbing in your code. Your feedback shapes the product because this round table feeds directly into the engineering and product teams. Save your spot Add it to your calendar: 22 July 2026, 5:00 PM BST. Join the community: https://aka.ms/foundry/discord Prep with the sample: run the Mastering Foundry Toolbox notebook to build, search, and consume a toolbox end to end. Read the docs: Toolbox, Tool Search, and Skills. Agents get more capable as they gain access to more tools and skills, but only if you can build, govern, and scale those capabilities without drowning in integration and prompt bloat. Come and share how you are doing it today, and help shape how Foundry does it next. See you on 22 July.
Is there a way to connect 2 Ai foundry to the same cosmos containers?
I defined Azure AI Foundry Connection for Azure Cosmos DB and BYO Thread Storage in Azure AI Agent Service by using these instructions: Integration with Azure AI Agent Service - Azure Cosmos DB for NoSQL | Microsoft Learn I see that it created 3 containers under the cosmos I provided: <guid>-agent-entity-store v-system-thread-message-store <guid>-thread-message-store Now I created another AI foundry and added a connection for the same AI foundry, and it created 3 different containers under the same DB. Is there a way that they'll use the same exact containers? I want to use multiple AI foundries, and they will use the same Cosmos containers to manage the data.330Views0likes1CommentToken Limit Exceeded? What's Actually Going On and What to Do About It ?
Hi All, Based on some recent experience across the organisation with token limit issues, I wanted to put my thoughts down and actually dig into what's happening under the hood, rather than just chalking it up to "we need a bigger plan." If you work anywhere near the Microsoft ecosystem these days, you're probably touching more AI tools than you realize. Copilot in Word and Excel, GitHub Copilot while you code, Copilot Studio if you're building agents, maybe Security Copilot or Copilot for Sales depending on your role, and increasingly Azure AI Foundry if your team is building anything custom. I work across a good chunk of this stack day to day, and at some point, almost everyone runs into the same wall: "Token limit exceeded." "You've reached your usage limit." "Upgrade to continue." The first instinct is usually to assume you did something wrong wrote too much, uploaded too big a file, or just need a fatter subscription. Sometimes that's the actual story. But honestly, often, that error message is standing in for three completely different problems that all happen to look identical from the outside. One is about how much text a model can physically process at once. One is about your license or credits running dry. And one has nothing to do with size at all it's just about how fast you're sending requests. Once you know which of these three, you're dealing with, the fix becomes obvious. Until then, "upgrade your plan" feels like the only lever you've got even when it isn't. This post walks through what a token is, why Microsoft's various Copilots each handle this differently, and what habits genuinely cut down on these interruptions instead of just throwing money at the problem. Part 1: So What Is a Token, Really? A token isn't a word, and it isn't a character it's somewhere in between. It's the small chunk of text a model's tokenizer breaks your input into before it can do anything with it. Take a word like "unbelievable." A tokenizer might split it into three pieces something like "un," "believ," and "able." Short, everyday words usually come out as a single token. But code, technical jargon, acronyms, and non-English text tend to fragment into a lot more tokens than you'd guess just by looking at the word count. This is why every AI tool has a ceiling on how much it can handle in one go, and that ceiling isn't measured in words or characters it's measured in tokens. Your prompt, any documents or emails it pulls in as context, the back-and-forth history of your conversation, and the response itself all draw from the same pool. Once that pool runs dry, something has to give: the tool truncates, rejects the request outright, or quietly summarizes older context to make room. The part that trips people up: token count doesn't map cleanly to word count. A short, dense paragraph full of code or acronyms can eat up more tokens than a much longer plain-English message. Part 2: Three Different Limits, One Confusing Error Message This isn't always obvious upfront, even to a lot of admins managing these tools: "token limit exceeded" is really a stand-in phrase for three separate limits, and they don't behave the same way. This isn't unique to Microsoft either every major AI platform bundles these same three things behind similarly vague error messages. Microsoft's stack just makes a good case study because so many of us touch multiple pieces of it in the same week. The context window is the ceiling on how much text a specific model can process in a single request everything from your prompt to retrieved documents to chat history. This is tied to the model itself, not your subscription. Swap from one model to another inside the same tool, and this ceiling can move without you doing anything differently. Your license, credits, or feature allowance is a completely separate thing. This is what Microsoft 365 Copilot plans track through AI credits and feature limits, and it's what Copilot Studio measures through Copilot credits at the environment level. A single action summarizing an inbox, generating an agent response, running an analysis deducts from this pool regardless of how small your actual prompt felt. Run out, and you get blocked, even if you're nowhere near any context window limit. The rate limit is about speed, not size. Copilot Studio, for instance, enforces quotas measured in requests per minute or per hour to keep the system stable under load. Send messages too quickly, which happens easily with automations, flows, or bots, and you can get throttled even with a tiny prompt and plenty of credits left. The reason this matters: a plan upgrade only ever fixes the second one. If you're actually running into the model's context window or getting rate-limited, paying for a bigger license won't change anything, and that mismatch is exactly where most of the frustration comes from. Part 3: How This Plays Out Across the Microsoft AI Stack The Microsoft ecosystem isn't one AI tool wearing different outfits it's genuinely several different systems, each handling tokens and limits in its own way. Here's a tour of the ones people run into most. Microsoft 365 Copilot (the one living inside Word, Excel, Outlook, Teams) doesn't work off a single published token number the way a developer tool would. Instead, it dynamically pulls together your prompt, recent chat history, and relevant snippets retrieved from Microsoft Graph your files, emails, and messages and quietly summarizes or drops older material to stay within bounds. Where this usually breaks isn't the context window at all; it's the AI credit and feature-limit system running out, often without much warning until you're mid-task. GitHub Copilot Chat is more like a traditional developer tool. It has a fixed, published token window tied to whichever model you've selected, and that limit applies consistently whether you're in the browser, VS Code, or the CLI. The failure mode here is usually a long conversation or a big multi-file context quietly creeping past that ceiling. Copilot Studio, where a lot of custom agent-building happens, runs on Copilot credits per interaction, plus its own requests-per-minute and requests-per-hour quotas at the environment level. If you're grounding an agent in SharePoint content, there's also a separate file-size ceiling to watch content over a certain size can get silently excluded from generative answers depending on your tenant's licensing. Azure AI Foundry (recently renamed to Microsoft Foundry, in case you've seen both names floating around) is where this gets more directly in your control. If your team is building custom applications on top of Azure OpenAI or other models in the Foundry catalog, which now includes everything from GPT to Phi to Claude to Llama, you're working with explicit, published context windows per model, and you're billed per token rather than per credit. It's a different mental model entirely: less "you hit a wall," more "you're paying by the word, so design accordingly." Security Copilot, if your org uses it for threat analysis and incident response, runs on its own capacity model pooled compute units at the tenant level rather than a simple per-user cap. It's easy to assume this behaves like M365 Copilot license limits; it doesn't. Copilot for Sales, embedded in Outlook and Teams for CRM-connected work, and Copilot in Power BI, which now goes beyond generating summaries to actually helping build and refine semantic models, both draw from their own feature-specific allowances layered on top of whatever base Microsoft 365 or Power Platform license you're on. And then there's the multi-model wrinkle that trips up teams the most: because tools like Copilot Studio and GitHub Copilot let you choose between GPT-based models, Claude, and others, the exact same prompt can have a different effective context window and a different token cost purely based on which model handled it that day. This is a big, underrated reason behind the "it worked fine yesterday, why not now" complaint. Part 4: What Actually Helps ? Some of this is genuinely outside your control, but a fair amount isn't. If you're just using these tools day to day, the single biggest habit shift is not letting conversations run forever. Long threads in Copilot Chat or Copilot Studio keep accumulating history, and that history eats into the same budget as whatever you're asking right now. Starting fresh periodically costs you nothing and buys back a lot of headroom. Large documents are worth splitting up before you feed them in, especially for SharePoint-grounded agents, where oversized files can get quietly excluded rather than cleanly rejected you won't necessarily know it happened unless you're looking for it. And it's worth resisting the urge to default to the heaviest, most capable model for every single task. Lighter models are usually faster, cheaper, and often sit under a more generous limit than the flagship ones, and most everyday tasks genuinely don't need the biggest model available. Before you go asking IT for a license upgrade, it's worth a quick sanity check on which limit you actually hit. If it's a rate limit, waiting a minute and retrying usually solves it outright. If it's a context window problem, trimming your prompt or starting a new session fixes it. An upgrade only helps if you've genuinely run out of credits or feature allowance, and that's worth confirming before you file the request. If you're on the building side Copilot Studio agents, Foundry applications, anything with RAG-style grounding a couple of things pay off quickly. Keep an eye on credit or token consumption proactively rather than discovering it's gone when the agent goes down mid-conversation. Be deliberate about what goes into system prompts and orchestration instructions, since those draw from the same budget as the end user's actual message, often invisibly to whoever's chatting with the agent. And spend real time getting chunk size right for knowledge sources too large and you're burning budget on irrelevant context, too small and the agent loses the thread. Part 5: Quick Checklist Before You Escalate Is this actually a context window problem -prompt, history, and attachments too big for the model in use? Have you genuinely run out of credits or feature allowance on your plan? Could this be a rate limit -too many requests too fast, especially from a flow or automation? Did the underlying model change since last time, quietly shifting the effective window? For Studio or Foundry work, is this a tenant or environment-level limit rather than something tied to you personally? Closing Thoughts Tokenization is one of those things that stays completely invisible right up until it isn't. Across a stack as sprawling as Microsoft's M365 Copilot, GitHub Copilot, Copilot Studio, Foundry, Security Copilot, and everything layered on top "token limit exceeded" almost never means one single thing. It means you've hit one of three very different walls, and each one needs a different response. If your team builds or maintains any of these tools, this is genuinely worth putting in front of people early. Most of the "why did this break" tickets in this space aren't about tokens at all. They're about nobody knowing which limit actually got hit, or where in this increasingly large ecosystem it happened. I'm curious how this shows up for others has your team standardized on one model across these tools, or are you juggling several depending on the task? I'd love to hear what patterns you've run into. Cheers, and happy reading. - By Surya Vennapusa, MCT3.2KViews3likes2CommentsBuilding AI Agents from Zero to Production
Building AI Agents from Zero to Production Most agent demos stop at "it answered my question." Production doesn't. The gap between a notebook that calls an LLM and a governed, observable, multi-agent system your organisation can actually depend on is where real engineering happens, evaluation, deployment, data sovereignty, tool governance, and cross-team interoperability. Microsoft's open-source course Building AI Agents from Zero to Production walks that entire arc in seven lessons, using one realistic use case and the Microsoft Agent Framework (MAF) plus Microsoft Foundry. This post is a developer-focused tour of what it teaches, the architecture decisions behind each stage, and the code patterns that matter when you move from prototype to production. Who this is for AI engineers building their first or first production, agent system. Backend and full-stack developers integrating agents into real applications and CI/CD. Cloud architects who need data sovereignty, private networking, and governance around agent workloads. Technical leads deciding how to standardise tools and orchestration across multiple teams. The samples are Python 3.12+, served through Microsoft Foundry using GPT-5 series models (for example gpt-5.1 ). Lesson 4 adds a TypeScript/React frontend. You will want an Azure subscription and the Azure CLI. The AI Agent Development Lifecycle The course is organised around a lifecycle rather than a feature list. Each lesson is a stage, and each stage assumes the previous one is solved: # Stage The production question it answers 1 Agent Design What should each agent do, and how do they hand off? 2 Agent Development How do I build and run them with the Agent Framework? 3 Agent Evaluations How do I know they actually work — and keep working? 4 Agent Deployment How do I ship one as a hosted service with a UI and CI gate? 5 Production Hosted Agents How do I meet enterprise data, network, and governance needs? 6 Microsoft Toolbox How do I govern tools once, and reuse them across teams? 7 Multi-Agent & A2A How do agents from different teams interoperate safely? The thread running through all seven is a single scenario: a Developer Onboarding agent system that helps a new hire find the right teammates, get a sensible first task, and pull learning resources and code snippets. It is deliberately mundane, which is exactly why it exposes the production concerns that flashy demos hide. Lesson 1 — Agent Design: three components, one graph The course defines an agent by three parts: an LLM for reasoning, tools to act, and memory to retain context. The design work is context engineering — making sure the right information reaches the model at the right moment, no more and no less. Rather than one monolithic assistant, the onboarding system is split into specialists coordinated by a triage agent using handoff orchestration: Agent Job Tool Employee Search Answer org and people questions Foundry file search over an employee-directory vector store Task Recommendation Suggest 1–3 GitHub issues for the new dev GitHub MCP Server (reads recent commits + open issues) Code Assistant Provide resources and runnable snippets Microsoft Learn MCP + Code Interpreter Architecturally this is a directed graph: User → Triage → [Employee, Learning, Coding] . Splitting responsibilities early pays off later, each agent gets a tightly scoped prompt (less hallucination), can be evaluated independently, and can be upgraded without touching its peers. Lesson 2 — Development: standalone agents with MAF Here the design becomes code. Each specialist is a small, independently runnable service built with the Microsoft Agent Framework, authenticated to Foundry with your Azure CLI login. Setup is deliberately boring: az login az account set --subscription "<your-subscription-id>" cp .env.example .env # Fill FOUNDRY_PROJECT_ENDPOINT and FOUNDRY_MODEL (e.g. gpt-5.1) # Create the employee-directory vector store once; note the printed VECTOR_STORE_ID python lesson-2-agent-development/setup_vector_store.py # Start an agent — serves on http://localhost:8090 python lesson-2-agent-development/employee-search-agent.py The FoundryChatClient auto-reads any FOUNDRY_ -prefixed environment variables and uses AzureCliCredential , so there are no keys in code. The lesson ships six samples, each on its own port, so you can chat with them individually in the local DevUI before wiring them together: Sample Tool Port employee-search-agent.py Foundry file search / vector store 8090 task-recommendation-agent.py GitHub MCP Server 8095 azure-learning-agent.py Microsoft Learn MCP 8092 coding-agent.py Code Interpreter 8093 learning-recommendation-agent.py Learn MCP + reasoning 8091 agent-orchestration.py Multi-agent handoff 8094 Why this matters: keeping each agent as its own process with its own port is a testability decision, not an accident. You can smoke-test one specialist in isolation, then compose them in agent-orchestration.py . Lesson 3 — Evaluation: you can't unit-test a probability distribution This is the lesson that separates a demo from a product. Agents are non-deterministic, so traditional assertions don't fit. The course uses three complementary layers: Observability / tracing — always on, via OpenTelemetry to Application Insights. Smoke tests — fast, run on every deploy. Evaluations — deeper, model-based scoring run on-demand or nightly. Turning on tracing is a single call: from agent_framework.foundry import FoundryChatClient client = FoundryChatClient() client.configure_azure_monitor() # export traces + metrics to Application Insights For quality it uses Foundry's built-in "LLM-as-a-judge" evaluators against real persisted responses (identified by response_id ), not freshly regenerated ones: Evaluator evaluator_name Measures Relevance builtin.relevance Does the response address the request? Groundedness builtin.groundedness Is it supported by retrieved data (no hallucination)? Tool-call accuracy builtin.tool_call_accuracy Were the right tools called with the right arguments? Tool-output utilization builtin.tool_output_utilization Did the agent actually use tool results? The judge model is set independently via AZURE_AI_MODEL_DEPLOYMENT_NAME , so you can evaluate a cheap production model with a stronger one. The run prints a report_url that deep-links into the Foundry portal. Lesson 4 — Deployment: a hosted agent, a UI, and a CI gate Now the agent becomes a managed service. It is deployed as a Foundry Hosted Agent a Microsoft-managed execution environment and fronted by an OpenAI ChatKit React UI talking to a FastAPI backend: ChatKit React (3000) → FastAPI backend (8001) → Foundry Hosted Agent → tools Building the agent is declarative attach tools, name it, serve it: agent = client.as_agent( name="DevOnboardingAgent", instructions="...", tools=[file_search_tool, learn_mcp_tool], ) # served with: from_agent_framework(agent).run() The recommended deploy path is the Azure Developer CLI: cd hosted-agent azd auth login azd agent deploy The genuinely production-minded part is the smoke test as a post-deploy CI gate. Six cases cover reachability, each scenario, off-topic prompt adherence, and multi-turn threading (verifying state via previous_response_id ). The GitHub Action runs them against the freshly deployed agent: export FOUNDRY_TOKEN=$(az account get-access-token \ --resource https://ai.azure.com/ --query accessToken -o tsv) python runner.py \ --project-endpoint "https://<account>.services.ai.azure.com/api/projects/<project>" \ --agent-name dev-onboarding \ --tests-file tests/smoke-tests.json Pitfall to remember: the token audience must be https://ai.azure.com/ . A cognitiveservices.azure.com token is rejected by the Responses API — a mistake that costs many engineers an afternoon. Lesson 5 — Production: separating where an agent runs from where its data lives The pivotal concept for enterprise readiness is the distinction between a Hosted Agent (compute, scaling, identity) and a Capability Host (where conversation history, files, and embeddings actually reside): Concern Hosted Agent Capability Host Compute / scaling / identity ✅ Provided — Conversation history Microsoft-managed default Redirect to your Azure Cosmos DB File uploads Microsoft-managed default Redirect to your Azure Storage Vector embeddings Microsoft-managed default Redirect to your Azure AI Search Required to run the agent? ✅ Yes ❌ Optional Required for data sovereignty? ❌ Not sufficient ✅ Yes "Basic" setup uses Microsoft-managed storage and is perfect for getting started. "Standard" setup redirects each data plane to your own Azure resources through a project-level capability host, this is how you keep customer data in your tenant, inside your network boundary: PUT .../accounts/{account}/projects/{project}/capabilityHosts/{name}?api-version=2025-06-01 { "properties": { "capabilityHostKind": "Agents", "threadStorageConnections": ["my-cosmosdb-connection"], "vectorStoreConnections": ["my-ai-search-connection"], "storageConnections": ["my-storage-connection"] } } Operational constraints worth internalising before you provision: there is one capability host per scope (a second attempt returns 409 Conflict ), configuration is immutable (delete and recreate to change it), deletion is destructive, and the account-level host must exist before the project-level one. Lesson 6 — Toolbox: govern tools once, reuse everywhere Left unchecked, every team re-implements the same tools, scatters credentials, and loses governance visibility. The Microsoft Foundry Toolbox solves this by exposing a curated, versioned set of tools behind a single MCP-compatible endpoint, with credentials held in Foundry connections rather than agent code. You build a toolbox version once: from azure.ai.projects.models import MCPTool, ToolboxSearchPreviewTool, WebSearchTool toolbox_version = project.toolboxes.create_toolbox_version( name="agent-tools", description="Web search + an MCP server + tool search", tools=[ WebSearchTool(), MCPTool( server_label="myserver", server_url="https://your-mcp-server.example.com", require_approval="never", project_connection_id="my-key-auth-connection", # credentials live in Foundry ), ToolboxSearchPreviewTool(), ], ) And every agent consumes it through one endpoint, no per-team tool code: from agent_framework import MCPStreamableHTTPTool mcp_tool = MCPStreamableHTTPTool( name="toolbox", url=TOOLBOX_ENDPOINT, # {project_endpoint}/toolboxes/{name}/mcp?api-version=v1 http_client=http_client, load_prompts=False, ) agent = chat_client.as_agent(name="my-toolbox-agent", instructions="...", tools=[mcp_tool]) Versioning is blue/green: create a new version, test it on its version-specific endpoint, then promote it to default and every consumer picks it up with zero code changes. A Guardrail (RAI) policy can be applied at the toolbox layer, independent of model-level content filters. Note the toolbox management APIs are currently preview; the portal or VS Code Foundry Toolkit are practical alternatives for creation today. Lesson 7 — Multi-Agent & A2A: agents as networked peers The final lesson contrasts two ways agents collaborate: Handoff / Workflow — in-process, same codebase, fastest, tightest coupling. Agent-to-Agent (A2A) — cross-process over an open protocol, so agents from different teams, orgs, or frameworks interoperate. A2A gives each agent a discoverable Agent Card at /.well-known/agent-card.json and a task lifecycle (submitted → working → completed/failed). The elegant part: A2AExecutor wraps an existing MAF agent with no changes to that agent's code. from agent_framework.a2a import A2AExecutor from a2a.server.apps import A2AStarletteApplication from a2a.server.tasks import InMemoryTaskStore agent_card = AgentCard( name="Coding Assistant", url="http://localhost:9000/", version="1.0.0", capabilities=AgentCapabilities(streaming=True), skills=[AgentSkill(id="generate-code", name="Generate code", tags=["code"])], ) request_handler = DefaultRequestHandler( agent_executor=A2AExecutor(agent), # wraps your existing MAF agent unchanged task_store=InMemoryTaskStore(), ) app = A2AStarletteApplication(agent_card=agent_card, http_handler=request_handler).build() Consuming a remote agent then looks exactly like calling a local one: from agent_framework.a2a import A2AAgent remote_agent = A2AAgent(name="remote-coding-assistant", url="http://localhost:9000") result = await remote_agent.run("Write a Python function that reverses a string.") Because an A2AAgent can be a participant inside a HandoffBuilder workflow, you can mix in-process routing with remote services in the same orchestration. For enterprise use, A2AAgent accepts an auth_interceptor for bearer tokens, and the Agent Card carries security_schemes . Responsible and secure by design Production readiness in this course is not just uptime, it is governance: Identity over keys — AzureCliCredential and managed identity throughout; no secrets in code. Least privilege — CI runners get a scoped Azure AI User role assignment on the specific project. Data sovereignty — capability hosts keep conversation history, files, and embeddings in your own Cosmos DB, Storage, and AI Search. Tool approval and guardrails — MCP approval_mode and toolbox-level RAI policy gate what agents can do. Grounded evaluation — groundedness and tool-utilization scoring catch hallucination and unused-tool behaviour before users do. Cost hygiene — the lessons create real Azure resources; delete the resource group when done: az group delete --name <rg> --yes --no-wait . Key takeaways Design as a graph of specialists. Handoff orchestration with tightly scoped agents beats one monolith on reliability and testability. One .run() contract, many backends. The Agent Framework keeps orchestration code stable from local dev to hosted production. Evaluate continuously. Tracing + smoke tests + model-based evaluators are three layers, not alternatives. Separate compute from data. Hosted Agents run the agent; Capability Hosts give you sovereignty — you need both for enterprise. Govern tools centrally. A versioned toolbox behind one MCP endpoint kills tool sprawl and credential duplication. Open protocols for interop. A2A lets agents cross team, org, and framework boundaries without rewrites. Get started Clone the repo (skip the 50+ translations for a faster download) and work through the lessons in order: git clone --filter=blob:none --sparse https://github.com/microsoft/Building-AI-Agents-From-Zero-To-Production.git cd Building-AI-Agents-From-Zero-To-Production git sparse-checkout set --no-cone '/*' '!translations' '!translated_images' References Building AI Agents from Zero to Production — course repo Microsoft Agent Framework Microsoft Foundry documentation Agent-to-Agent (A2A) protocol specification a2a-python SDK AI Agents for Beginners MCP for Beginners Microsoft Foundry DiscordAgents League: The Esports-Inspired Hackathon Where AI Agents Battle for Glory
Ready to put your AI skills to the ultimate test? Agents League is here, a dynamic, esports-inspired developer challenge that brings the thrill of live competition to the world of agentic AI. Whether you're a seasoned AI developer or just getting started, this is your chance to build, compete, and win. What is Agents League? Agents League is a week-long hackathon running as part of AI Skills Fest (June 4–14, 2026). Unlike traditional hackathons, Agents League combines live AI coding battles, asynchronous project submissions, and a thriving Discord community all competing for a total prize pool of $55,000 USD. This isn't just about building it's about showcasing what's possible with agentic AI in a format that's fast, competitive, and globally accessible. Three Challenge Tracks Pick One or Compete in All 1. Creative Apps Build innovative applications using GitHub Copilot for AI-assisted development. Show off your creativity and demonstrate how AI can accelerate app creation from concept to code. 2. Reasoning Agents Create intelligent agents using Microsoft Foundry that solve complex problems through multi-step reasoning. This track is all about building agents that can think, plan, and execute. 3. Enterprise Agents Build business-ready knowledge agents integrated with Microsoft 365 Copilot, authored in Copilot Studio. Perfect for developers focused on real-world enterprise solutions. Live Microsoft Reactor Events—Don't Miss the Battles! The heart of Agents League beats through live Microsoft Reactor events. Watch experts go head-to-head in live coding battles, learn cutting-edge techniques, and get inspired for your own submissions: Event What You'll Learn Creative Apps Battle See GitHub Copilot in action as experts build innovative apps live Reasoning Agents Battle Watch multi-step reasoning agents come to life with Microsoft Foundry Enterprise Agents Battle Learn to build M365-integrated agents with Copilot Studio 👉 View the full event series Key Dates Registration Deadline: June 12, 2026, 12:00 PM PT Hacking Period: June 4–14, 2026 Submission Deadline: June 14, 2026, 11:59 PM PT What You Get Live coding battles with expert demonstrations Curated technical experiences and on-demand content Learning resources on Microsoft Learn and AI Skills Navigator Community support through Discord GitHub-based submissions for transparent, collaborative judging Why Participate? Agents League isn't just another hackathon. It's designed as a streamlined, competitive format that: ✅ Fits into your schedule with focused, time-boxed challenges ✅ Provides real-world product innovation experience ✅ Offers global accessibility—participate from anywhere ✅ Demonstrates the latest capabilities of agentic AI, including new IQ tools ✅ Connects you with a passionate developer community Ready to Enter the Arena? Register Now for Agents League Before you register: Review the Hackathon Rules and Regulations for prize categories and judging criteria Join the Microsoft Reactor event series for live battles and learning Check out the Microsoft Event Code of Conduct Join the Conversation Have questions? Want to connect with fellow competitors? Join the Agents League community on Discord and start strategizing with developers from around the world. Whether you're building creative apps, reasoning agents, or enterprise solutions—the arena awaits. May the best agent win! 🏆 Agents League hackathon is open to the public and offered at no cost. Government employees should check with their employers to ensure participation is permitted in accordance with applicable policies. Related Links: Agents League Hackathon Registration Microsoft Reactor Series AI Skills Fest