ai agents
208 TopicsGPT-6.1 Terra now generally available in Microsoft Foundry: build agents that see and act
AI agents that read dense charts, navigate desktop apps, and process scanned documents are only as capable as the model behind them. OpenAI’s GPT-6.1 Terra, now generally available in Microsoft Foundry, delivers significant gains in visual reasoning and computer-use speed, so the apps and agents you build can see more and act faster. AI projects often slow down on identity, networking, governance, data handling, evaluation, and compliance. Microsoft Foundry brings these fundamentals together in Azure, so you can take GPT-6.1 Terra from prototype to production with speed and trust. What's new in GPT-6.1 Terra GPT-6.1 Terra is a quick, efficient model built for day-to-day professional tasks, with four core strengths: Stronger vision. Improved visual reasoning helps the model pick out the details that matter in product photos, technical drawings, floor plans, and application screens. Faster, more precise computer use. The model pairs what it sees with quick, accurate actions across browsers, desktop software, and apps, so agents can go from reviewing information to finishing the task. Clear writing. Summarizes what it finds in plain, approachable language and drafts natural-sounding emails and proposals for everyday work. GPT-6.1 Terra also provides: Large context window. Up to 1M input tokens. Multimodal input. Accepts text and images. Developer controls. Tune reasoning effort, including a none setting for latency-sensitive calls, and adjust verbosity to match response length to the task. Interim updates. When your orchestration layer supports it, the model can send interim messages to the user while it continues working toward a final response, keeping long-running tasks responsive. Where GPT-6.1 Terra fits GPT-6.1 Terra is built for work that starts with visual analysis and ends with action inside software: Forms, email, and proposals. Complete forms and draft emails and proposals as part of routine administrative work. Design and technical visuals. Review campaign assets for cropping and text placement and turn issues into a clear list of fixes or read technical drawings and update floor plans in the right tools. Visual analysis to action. Review what appears in images or on application screens and use those insights to drive the next step in a software workflow. Retail catalog upkeep. Match supplier product images to existing catalog entries, spot gaps in product details, and update listings in the browser. Video workflows. Find a specific moment in a video and make edits through video applications. GPT-6.1 Terra complements GPT-6 Astra. Astra reasons through open-ended, multi-step work and plans the job. Terra handles the high-volume visual and screen-based tasks inside it, at a lower price point. Built into the Foundry platform GPT-6.1 Terra works with the Foundry APIs and tools you already use. It’s available through the Responses API with no new SDK requirements or schema changes. From day one, GPT-6.1 Terra is available through Foundry Models in Global Standard deployments across all supported regions, and in Data Zone Standard deployments in US, EU and APAC. You can adopt the latest frontier model where you’ve already built and scaled your applications, without trading off performance for data residency. Watch the demo with Naomi Moneypenny for a platform-wide walkthrough of model selection, evaluation on your own data, and approaches to cost optimization. GPT-6.1 Terra Pricing (USD/1M tokens) Model Deployment Context Length Pricing (USD $/million tokens) Input Cached Input Cached Writes Output GPT-6.1 Terra Global Standard Short context $1.00 $0.05 $1.25 $5.00 Long context $2.00 $0.10 $2.50 $7.50 Data Zone Standard (US) Short context $1.10 $0.055 $1.375 $5.50 Long context $2.20 $0.11 $2.75 $8.25 Data Zone Standard (EU) Short context $1.20 $0.06 $1.50 $6.00 Long context $2.40 $0.12 $3.00 $9.00 Data Zone Standard (APAC) Short context $1.20 $0.06 $1.50 $6.00 Long context $2.40 $0.12 $3.00 $9.00 Learn more pricing details in here. Put GPT-6.1 Terra to work on your next AI app Deploy GPT-6.1 Terra in Microsoft Foundry today to build apps and agents that read complex visuals and act on screen faster. Some steps in your app need a fast, structured answer instead of generated text, such as classifying content or routing a request. For those, use the Decisions API. Last week, we announced the general availability of OpenAI’s Decisions API with GPT-6 Luna in Microsoft Foundry. Terra handles the visual and on-screen work, and the Decisions API makes the quick call on what happens next. Whichever you start with, you get development, evaluation, and governance on one platform, so you can move from prototype to production with confidence.1.9KViews0likes1Comment
You don't have access to talk to this bot, contact the owner. copilot studio
I created a copilot studio agent and then embedded it inside a code app. It works fine but i am facing the below error. You don't have access to talk to this bot, contact the owner. copilot studio I have provided Microsoft based authentication and am an owner so will have access to the bot. Yet facing the above issue. Is there something i am missing950Views0likes4CommentsWhen the Answer Isn’t in the Document: Metadata-Aware Agentic RAG with Foundry IQ
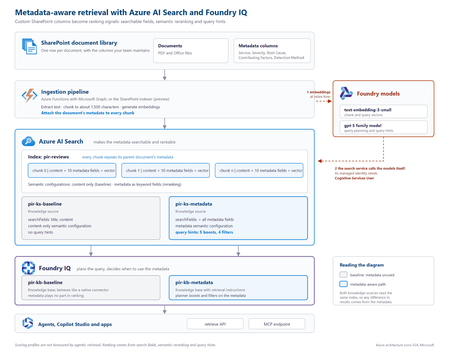
The problem SharePoint libraries often contain years of carefully curated metadata, including root cause, severity, business unit, document type, owner and classification. If that metadata never reaches the retrieval pipeline, however, a RAG system cannot use it. This creates a common blind spot: the information that explains what a document is about may exist in its metadata rather than its text. Consider an incident review containing this statement: “Investigation found that a DNS record was repointed during a migration while the old target was still serving writes.” The associated Root Cause Category is Configuration change, but those words do not appear in the document. Another review might mention that a configuration change was suspected and ruled out. Text-only retrieval can therefore favour the wrong document. In the sample dataset used for this project, none of the 19 reviews classified as configuration-change incidents contained the word “configuration”, while six reviews with other root causes did. Metadata does not improve every search. It helps when the information that determines what a document is lives outside the document text. Why tuning alone cannot fix it With a native SharePoint knowledge source, document text is extracted, chunked and embedded, while standard properties are retained. Custom SharePoint columns are not part of that ingestion path. Fields such as Root Cause Category, Contributing Factors, Detection Method and Severity therefore never become structured fields available to retrieval. If the metadata is absent from the index, search tuning cannot make it count. Flattening all metadata into a single text string is also problematic: Notification Service | Sev2 | Configuration change | Missing runbook This preserves the words but loses their meaning. A root cause, severity and contributing factor represent different concepts and should remain separate fields. Bring a custom Azure AI Search index The approach is to create and control a custom Azure AI Search index, then expose it to Foundry IQ as a searchIndex knowledge source. This combines metadata control with agentic query planning and a governed retrieval surface. Approach Metadata control Agentic planning Native SharePoint knowledge source No Yes Custom index queried directly Yes No Custom index as a knowledge source Yes Yes Architecture The key design principle is simple: every chunk carries its parent document's metadata. Figure 1. Metadata-aware retrieval architecture with Azure AI Search and Foundry IQ. The ingestion pipeline extracts a document, creates chunks, attaches document-level metadata to every chunk, generates embeddings and writes the records to Azure AI Search. Foundry IQ then uses the index as a knowledge source. Azure AI Search holds the metadata. Foundry IQ decides when to use it. Figure 2. Detailed implementation view, including the baseline and metadata-aware retrieval paths. At query time, the search service calls the configured models for vectorisation and query planning. Where key authentication is disabled, the search service's managed identity needs the required access. In the tested implementation, the Cognitive Services User role resolved HTTP 401 responses from retrieve requests. Put metadata on every chunk A chunk can only be retrieved and ranked using information available on that chunk. Each metadata property should therefore remain in its own field: { "id": "doc1035-000", "parentId": "doc1035", "title": "Notification Service: failed sign-ins", "content": "<extracted review text>", "rootCauseCategory": "Configuration change", "contributingFactors": "Missing runbook; Change outside window", "detectionMethod": "Customer report", "severity": "Sev2" } A separate metadata index does not solve the same problem because a match against metadata in one index cannot raise the ranking of a content chunk in another. What influences retrieval Four areas matter in this design: Search fields: searchFields determine which fields generated subqueries search. Semantic configuration: prioritised fields give the semantic reranker access to important metadata. Query hints: hints help the planner connect natural-language requests to known metadata values. Filters: a baseFilter or request-level filterAddOn can enforce constraints. Boost hints influence ranking without excluding documents. Filter hints can narrow the result set when the planner determines that a filter is appropriate. "queryHints": { "boosts": [{ "kind": "fieldValue", "field": "rootCauseCategory", "fieldValues": ["Configuration change", "Capacity", "Software defect", "Dependency failure", "Certificate expiry"], "boost": 3.0, "boostInstructions": "Boost when the user describes what caused an incident." }] } Hints are best effort. Hard requirements should use a base filter or document-level access control rather than relying on the planner to select a hint. The tested configuration used the 2026-08-01-preview API. Current documentation should be checked for supported models, limits and behaviour before implementation. Why can't vector search or semantic ranking solve this? This is probably the most obvious question: if embeddings understand meaning, and semantic ranking understands context, why do we need metadata at all? The answer is that vector search and semantic ranking solve a different problem. This approach complements them rather than replacing them. Vector search finds similarity, not recorded facts In a typical RAG pipeline, document chunks are converted into embeddings, numerical representations of their meaning. The user's question is embedded as well, and vector search finds chunks that are close to it in vector space. For example, a passage saying: “The gateway routing rule was updated shortly before the incident.” might rank highly for: “Find incidents caused by configuration changes.” That's useful. But it doesn't necessarily mean Configuration change was the confirmed root cause. The passage could describe an investigation path, a contributing factor, or even something that was later ruled out. Vector similarity is essentially asking: “Does this content mean something similar to what the user is asking about?” Metadata lets us ask a different question: “What was this incident actually classified as?” If the incident review already contains a curated rootCauseCategory = Configuration change field, we should not require an embedding model to rediscover that fact from the prose every time somebody searches. What about semantic ranking? Semantic ranking helps, but at a different stage. In Azure AI Search, semantic ranker applies secondary ranking to an initial result set, using language understanding to promote results that are more semantically relevant to the query. That can help distinguish between: a configuration change that caused an incident a configuration change that was merely investigated a configuration change that was explicitly ruled out But semantic ranking still works with the information supplied to the retrieval pipeline. It cannot make use of a classification stored in a separate metadata field if that field was never supplied to retrieval or ranking in the first place. The difference becomes clearer with a real query Consider: “Show me configuration change incidents that customers reported.” A content-first approach primarily asks: “Does this passage sound relevant to configuration changes and customer reports?” A metadata-aware approach can additionally ask: “Is the recorded root cause Configuration change , and is the recorded detection method Customer report ?” Those signals can influence retrieval in different ways: Boost: favour incidents with those metadata values while still allowing other relevant results. Filter: restrict the candidate set when those classifications represent hard constraints. Retrieval layer Typical content-first RAG Metadata-aware approach Vector search Finds chunks with similar meaning using content embeddings Keeps content embeddings for narrative similarity Searchable fields Primarily searches document content and other configured fields Makes classifications such as root cause and detection method explicit searchable or filterable fields Semantic ranking Reranks the supplied candidate content for relevance Can also benefit from curated text fields when those fields are included and prioritised in the semantic configuration Query planning Translates the question into retrieval over content, optionally with application-defined filters Uses the metadata taxonomy to generate field-specific boosts or filters where appropriate There is an important nuance here: traditional RAG can absolutely use metadata filters and hybrid search. So the contribution here isn't a new embedding algorithm, nor is metadata an alternative to vector search. It is about making structured knowledge a first-class retrieval signal, and wiring that information into candidate retrieval, ranking and Foundry IQ's agentic query planning rather than asking the system to infer every classification from document text. And importantly, in the comparison below, both approaches use the same Azure AI Search index. So the comparison isn't: vector search vs. metadata. It's: content-first retrieval vs. retrieval that can also use the structured information the organisation already knows. Measuring the impact Two knowledge bases were created over the same Azure AI Search index. The baseline searched title and content. The metadata-aware configuration used the same content plus structured metadata, semantic configuration and query hints. Ten questions were run through both configurations. Correctness was determined directly from the metadata attached to returned reviews, rather than by asking an LLM whether a result appeared relevant. For the question “What can be learned from outages caused by configuration changes?”, the planner generated: rootCauseCategory eq 'Configuration change' Matching reports in top 5 Score Baseline 0 Metadata-aware 3 Best possible 5 Across ten questions and four runs using gpt-5.4-mini for query planning, the baseline returned 26 matching reviews in the top five. The metadata-aware configuration returned 39 to 41, against a best possible score of 50. The gains appeared where metadata carried the missing meaning: Configuration changes: 0 → 3 Configuration changes reported by customers: 0 → 3 Capacity in production: 1 → 5 Alert fatigue: 3 → 5 Queries whose important terms already appeared in the document text scored 5/5 in both configurations. The result is therefore more specific than “metadata improves search”: metadata closes a retrieval gap when document text does not fully describe what the document represents. A failure mode worth handling Because query planning uses an LLM, the planner can occasionally generate a filter that the search index rejects. Two invalid examples observed during testing were: severity eq Sev1 changeRelated eq true The first omitted quotes around a string. The second treated an Edm.String field containing Yes and No as a Boolean. The latter caused the retrieve request to fail with HTTP 502. The fix was to make the schema and allowed values explicit: This is a text field, not a Boolean. The only valid values are 'Yes' and 'No'. Never compare the field with true or false. Application code should also handle retrieval failures rather than assuming every generated filter will be valid. Production considerations A custom index provides control, but the solution now owns ingestion. Options include the SharePoint indexer with custom columns, an Azure Function using Microsoft Graph, or an existing pipeline built with Logic Apps, Azure Data Factory or Microsoft Fabric. A custom Azure AI Search index does not automatically inherit the SharePoint permissions model. Where users have different document permissions, ACLs must be carried into ingestion and retrieval. Query hints should also be regenerated when taxonomy values change. Key takeaways Confirm that the required metadata reaches the index. Keep metadata structured rather than flattening it into one text field. Attach parent-document metadata to every chunk. Use search fields, semantic configuration, query hints and filters deliberately. Describe field types and valid values clearly in filter instructions. Evaluate against a baseline using objective correctness rules. Metadata-aware retrieval is not about making every search better. It gives the retrieval system access to context that does not exist in the document text. Try the proof of concept The complete proof of concept, synthetic dataset, index scripts, knowledge-base configurations and A/B evaluation harness are available in the GitHub - shikha-msft/foundryiq-metadata-agentic-rag. References Create a search index knowledge source Create a knowledge base Query a knowledge base via API or MCP What is Foundry IQ?451Views0likes0Comments
Agent Credit Limits and Alerts - Copilot Studio
Hi everyone, We're evaluating the use of Agent Credit Limits and alert notifications in the Power Platform Admin Center as a way to control unexpected Copilot Credit consumption. Recently, we had an agent consume 668k Copilot Credits in just 3 days, which raised concerns about how quickly usage can grow before administrators become aware of it. My questions are: How frequently is Copilot Credit consumption evaluated against an agent's credit limit? Are alert notifications generated in near real-time, or are they dependent on the same reporting pipeline used by the consumption reports? If an agent reaches its configured credit limit, is it automatically turned off or blocked from further consumption? Given that consumption reports often appear to refresh hours later (or even the next day), can alerts also be delayed? If there is a reporting delay, is there a risk that an agent could significantly exceed the intended limit before administrators receive a notification? What is the recommended approach for preventing large unexpected consumption spikes in production? Has anyone successfully implemented a governance model that provides more immediate protection against runaway usage, or are the current credit limits and alerts primarily intended for retrospective monitoring? Thanks in advance for any guidance.338Views0likes4Comments
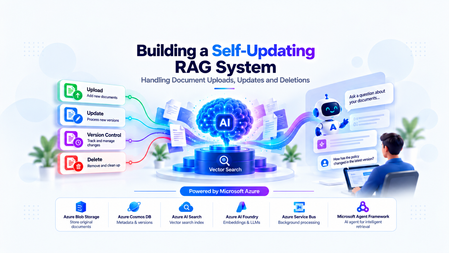
Building a Self-Updating RAG System: Handling Document Uploads, Updates and Deletions
The Hidden Challenge of Production RAG Imagine your organization has deployed an AI assistant to answer questions about employee policies. An employee asks, “How many days of annual leave am I entitled to?” The assistant responds confidently: “15 days.” There is just one problem. The company updated its policy last week. Employees are now entitled to 20 days. The updated PDF was uploaded successfully. The storage service is healthy. The search index is responding. The language model is generating answers without errors. Yet the answer is wrong. This is a different kind of production failure. Nothing appears to be broken at the infrastructure level. The failure lies in the relationship between the source document and the information the AI retrieves. Retrieval-Augmented Generation (RAG) systems depend on external knowledge to ground their responses. But that knowledge is not static. Policies change, contracts get revised, product documentation evolves, and outdated documents are removed. When the underlying documents change, the associated chunks, embeddings, metadata, and search-index entries must be managed accordingly. Otherwise, the system can continue generating plausible answers from information that is no longer valid. Building a RAG pipeline is a retrieval problem. Keeping it correct as data changes is a data lifecycle engineering problem. In this article, we will design a self-updating RAG system that handles document creation, updates, and deletion while addressing asynchronous processing, version consistency, failed jobs, and stale retrieval results. The goal is not simply to index documents automatically. It is to make sure that the right version of the right document is available to the right user when a query is executed. Understand the Problem Before Designing the Architecture A basic RAG pipeline is relatively straightforward: Load a document. Extract its text. Split the text into smaller chunks. Generate an embedding for each chunk. Store the chunks and embeddings in a searchable index. Retrieve relevant chunks when a user asks a question. Pass the retrieved context to a language model to generate an answer. This works well when the document collection is relatively static. The difficulty begins when the source data changes after indexing. Consider three common scenarios. Scenario A: A document is uploaded A new policy is added to the knowledge base. The system must process it and make its content searchable. Until indexing finishes, the document may not be available to the chatbot. Scenario B: A document is updated The original policy allows 15 days of annual leave. A revised policy allows 20 days. If the new version is indexed without correctly deactivating the old version, both versions may appear in search results. The language model may then select the wrong passage or combine conflicting information. Scenario C: A document is deleted An administrator removes a document from the application. However, deleting the original PDF from storage does not automatically delete the corresponding records from Azure AI Search. The content may remain searchable until its indexed chunks are removed. Azure AI Search document deletion itself can also take time to be reflected in index statistics. Microsoft Learn: Delete documents in Azure AI Search These scenarios reveal an important design principle: The source document, its metadata, the background processing jobs, and the search index must be treated as parts of one logical lifecycle—even though they are separate systems. We need a design that can handle failures between these systems without exposing outdated or unauthorized content. Design the System Around Clear Responsibilities Rather than making the upload API responsible for every operation, we can separate the system into a document management path, an asynchronous processing path, and a query path. The Proposed Architecture The design uses the following components: Component Responsibility Azure Blob Storage Stores the original document files Azure Cosmos DB Maintains document metadata, versions, and lifecycle state Azure Service Bus Queues ingestion and deletion jobs Background worker Extracts text, creates chunks, generates embeddings, and updates the index Microsoft Foundry Provides the models used for embedding generation and response generation Azure AI Search Stores searchable document chunks, metadata, and vectors FastAPI Exposes document management and chat APIs Microsoft Agent Framework Supports agentic query workflows when multi-step reasoning or tool use is required The background worker can be implemented as a separate Python service or another suitable compute component. It does not have to be part of the FastAPI process. Why separate these responsibilities? Suppose a user uploads a 100-page contract. The application may need to extract text, split thousands of characters into chunks, generate embeddings, and send multiple indexing requests. Performing all of that synchronously inside the upload request increases latency and makes the API vulnerable to timeouts. Instead, FastAPI accepts the request, persists the document and its metadata, and arranges for the work to be processed asynchronously. The worker performs the expensive operations independently. This allows ingestion to scale separately from query traffic and makes retries easier to manage. The query path remains separate: it retrieves eligible, relevant chunks and uses them to ground the model's response. Establish a source of truth Azure Cosmos DB should hold the authoritative lifecycle metadata in this design. Azure AI Search is the retrieval index, not the authority on whether a document is currently active. For example, a document record might look like this: { "id": "policy-123", "documentId": "policy-123", "currentVersion": 2, "indexedVersion": 1, "status": "PROCESSING", "blobPath": "policies/leave-policy.pdf" } Here, version 2 is the desired version, but version 1 is still the last successfully indexed version. The application must not assume that the latest upload has already become searchable simply because the metadata record has been updated. This distinction between the desired version and the indexed version is central to reliable lifecycle management. Implementing Document Uploads A reliable upload operation involves more than storing a file and sending a message to a queue. It must establish a durable record of the document, identify the version being processed, and ensure that background processing can be retried safely. Step 1: Accept and persist the document When a client uploads a document, FastAPI validates the request, checks the user's permissions, and stores the original file in Azure Blob Storage. The application then creates or updates the document metadata in Cosmos DB. At this stage, the document can be marked as PROCESSING until the ingestion pipeline completes. Step 2: Schedule background processing The system creates an ingestion job containing enough information for the worker to locate the source and determine exactly which version to process. For example: { "operationId": "op-789", "operation": "INGEST", "documentId": "policy-123", "documentVersion": 2, "blobPath": "policies/leave-policy-v2.pdf" } The worker should process the specified version rather than blindly reading whatever file happens to exist at a mutable storage path. For systems that overwrite the same blob path, use blob versioning, an immutable version-specific path, or another mechanism that ensures the worker reads the intended content. Step 3: Extract, chunk, and embed The worker downloads the appropriate document and extracts its text. The extracted text is divided into chunks. Each chunk should carry identifiers that connect it to its parent document and version. For example: { "id": "policy-123-v2-chunk-001", "documentId": "policy-123", "documentVersion": 2, "chunkNumber": 1, "content": "Employees are entitled to 20 days of annual leave." } The worker generates an embedding for each chunk and writes the chunk, its metadata, and its vector to Azure AI Search. The exact index schema depends on the retrieval strategy, embedding dimensions, filtering requirements, and whether hybrid search is used. Step 4: Mark the version as indexed After the worker confirms that all required indexing operations succeeded, it updates the document metadata to record the indexed version and processing status. For example: { "id": "policy-123", "currentVersion": 2, "indexedVersion": 2, "status": "ACTIVE" } This update must be conditional on the document still being at version 2. If a newer version has already been uploaded, the older job must not mark itself as the current version. Why idempotency matters Distributed systems can deliver the same job more than once. A worker may finish indexing but fail before acknowledging the queue message. The message can then be delivered again. If every attempt creates new chunk IDs, duplicate content may accumulate in the index. A practical solution is to derive chunk IDs deterministically from the document ID, version, and chunk identifier. Reprocessing the same version then targets the same index records instead of creating a new set each time. This does not eliminate every failure mode, but it makes repeated indexing much safer. Azure Service Bus supports duplicate detection for eligible tiers, but queue-level duplicate detection is not a substitute for idempotent worker logic. Microsoft Learn: Duplicate detection Updating Documents Without Serving Stale Content Document updates are the most interesting part of the lifecycle because they introduce a consistency problem. Imagine the current leave policy is version 1, allowing 15 days. An administrator uploads version 2, allowing 20 days. The worker starts processing version 2, but embedding generation takes time. Meanwhile, users continue querying the application. What should those users see? There are two common strategies. The right choice depends on whether the system prioritizes availability or strict freshness. Strategy A: Make the new version active after indexing succeeds In this approach, the existing active version remains available while the new version is processed. The workflow is: Create version 2 and mark it as processing. Extract text and generate embeddings for version 2. Index all required version 2 chunks. Verify indexing success. Atomically update the authoritative metadata to make version 2 active. Clean up version 1's indexed chunks asynchronously. This minimizes the time during which the document is unavailable. However, it means that version 1 can remain available while version 2 is being processed. That may be acceptable for some knowledge bases but inappropriate for policies that must become effective immediately. Strategy B: Disable the old version as soon as an update is accepted For high-sensitivity documents, the application can immediately mark the old version as ineligible for retrieval. It then processes the new version and activates it only after successful indexing. The trade-off is that the document may temporarily have no eligible version. The application should return a clear message or use an approved fallback rather than silently serving obsolete information. Prevent old jobs from overwriting new versions Consider this sequence: Version 2 starts processing. Version 3 is uploaded before version 2 finishes. Version 3 finishes indexing first. Version 2 finishes later and attempts to update the metadata. Without version checks, the late version 2 job could incorrectly reactivate stale content. The worker must therefore use conditional updates or optimistic concurrency checks against the authoritative document version. A job may complete its indexing work, but it must not activate its version unless it is still eligible to do so. Handle the lack of a cross-service transaction Cosmos DB and Azure AI Search do not participate in a single distributed transaction in this architecture. A metadata update can succeed while an indexing request fails. An indexing request can succeed while the subsequent metadata update fails. The system should account for these partial failures using: Explicit lifecycle states. Conditional version updates. Retryable and idempotent operations. Periodic reconciliation between metadata and indexed records. The important engineering principle is to make incomplete operations detectable and recoverable, rather than assuming every multi-step workflow succeeds atomically. Deleting Documents Safely Deletion requires special treatment because removing a document from the source does not automatically remove its indexed content. More importantly, waiting for physical index cleanup before preventing retrieval creates a window in which content that should no longer be available may still be returned. Step 1: Make the document ineligible for retrieval When an authorized deletion request arrives, the application updates the authoritative metadata to indicate that the document is being deleted or has been logically deleted. The retrieval path must check that status before using retrieved content. For sensitive documents, this check must happen before the content is added to the LLM context. Merely hiding a document in the user interface is insufficient. Step 2: Schedule physical cleanup The application enqueues a deletion job that identifies the document and all indexed records associated with it. The worker queries or otherwise identifies the corresponding chunk keys and deletes those records from Azure AI Search. The deletion operation should be idempotent. Retrying a deletion for an already-removed chunk should not cause the workflow to fail unnecessarily. Step 3: Verify cleanup The worker checks whether the targeted records have been removed and records the cleanup result. If an operation fails, the job should be retried according to a defined policy. Jobs that continue failing should be sent to a dead-letter queue for investigation and controlled recovery. Azure AI Search supports deleting indexed documents by their document keys. Its documentation also describes how to verify deletion and why index statistics may not update immediately. Microsoft Learn: Delete documents A simplified FastAPI deletion endpoint The following example illustrates the API boundary. The helper functions represent application-specific implementations. from fastapi import FastAPI, HTTPException app = FastAPI() @app.delete("/documents/{document_id}") async def delete_document(document_id: str): document = await get_document_metadata(document_id) if document is None: raise HTTPException( status_code=404, detail="Document not found" ) # Must enforce authorization and use a # concurrency-safe lifecycle transition. await mark_document_deleting(document_id) # The job must be published reliably. await enqueue_deletion_job( document_id=document_id, document_version=document["currentVersion"] ) return { "documentId": document_id, "status": "DELETING" } This is an illustrative example, not a complete production implementation. In particular, the metadata transition and message publication must be coordinated reliably. One approach is the transactional outbox pattern: write the lifecycle change and an outbox event in the same Cosmos DB transactional batch when the data model and partitioning allow it, then publish the event asynchronously. The publisher can retry without losing the intent to schedule cleanup. Deletion must also account for in-flight queries Suppose a query retrieves a document's chunks just before the deletion request is processed. The query might still hold those chunks in memory even after the document is marked deleted. For stricter deletion guarantees, the application needs a defined policy for in-flight requests, cache invalidation, and authorization checks immediately before content is sent to the model. If the requirement is that no response may contain content after a deletion takes effect, that guarantee must explicitly cover requests already in progress. Physical cleanup and retrieval eligibility are separate responsibilities. Both matter. Coordinate Lifecycle Changes Reliably Once ingestion and deletion run asynchronously, the queue becomes part of the system's correctness model. A production worker should not assume that each message is delivered exactly once or that messages for a particular document always finish in order. Design for at-least-once processing A practical worker lifecycle is: Receive a message using a lock-based delivery mode. Validate the document ID, version, and operation. Check whether the operation is still eligible to run. Perform idempotent indexing or deletion. Update lifecycle metadata conditionally. Acknowledge the message only after successful processing. If the worker fails before acknowledging the message, the message may be delivered again. That is expected behavior and should be handled by the design. Add retry and dead-letter policies Not all failures should be treated equally. Transient network errors or throttling may succeed after a delay. Invalid documents, unsupported file formats, and persistent schema mismatches may require manual investigation. The system should use bounded retries with appropriate backoff, record meaningful failure details, and route repeatedly failing messages to a dead-letter queue. Use reconciliation as a safety net Even with retries, the system needs a way to detect inconsistencies that escaped the normal workflow. A reconciliation job can compare authoritative metadata against indexed document versions and lifecycle states. It can identify cases such as: A document marked active whose current version is not fully indexed. Chunks belonging to an obsolete version. Search records for a logically deleted document. An operation that remained in a processing state beyond its expected duration. Reconciliation should repair only states it can safely determine. It should not reactivate a version simply because its chunks exist in the index. For applications using Azure Cosmos DB change feed, document metadata changes can also drive incremental background processing. The change feed captures inserts and updates in its standard latest-version mode; capturing deletions requires selecting and configuring an appropriate supported mode or using explicit lifecycle events. Microsoft Learn: Cosmos DB change feed Where Microsoft Agent Framework Fits A common mistake is to assume that every part of an agentic RAG application should be implemented as an AI agent. Document uploads, version transitions, embedding generation, and index deletion are predictable operations with explicit success and failure conditions. These are generally best implemented with conventional application logic and background workers. Microsoft Agent Framework becomes useful when the query itself requires multi-step reasoning, tool selection, or orchestration. For example, a user might ask: “Compare the current leave policy with the previous version and explain the changes that affect employees.” An agent could use approved tools to retrieve the current policy and the permitted historical version, compare the relevant passages, and generate an evidence-based explanation. The application must still control which documents and versions are eligible for retrieval. The agent should not independently decide whether a deleted document is authorized for use. This distinction is important: deterministic workflows protect data integrity; agentic workflows help solve tasks that benefit from reasoning and tool use. Microsoft Agent Framework provides both agent and workflow capabilities, allowing developers to choose an appropriate orchestration model for the task. Microsoft Agent Framework documentation Production Readiness: What Should We Measure? A pipeline that successfully indexes a document once is not necessarily production-ready. The system needs observable lifecycle states and measurable recovery behavior. Area What to validate Ingestion Can a failed upload or indexing job be retried safely? Idempotency Does processing the same document version twice create duplicate records? Version consistency Can a delayed job reactivate an older version? Deletion Can logically deleted content enter the LLM context? Authorization Are tenant and document-level permissions enforced during retrieval? Recovery Can reconciliation detect and repair partial failures? Observability Can operators identify stuck jobs, indexing failures, and cleanup delays? Performance How long does it take for an accepted update to become searchable? Useful operational metrics include ingestion success rate, queue age, indexing latency, retry counts, dead-letter queue depth, time spent in each lifecycle state, and deletion cleanup latency. Also test race conditions deliberately. Upload a new version while an earlier job is still running. Delete a document while a query is in flight. Simulate an indexing failure after metadata has been updated. Restart a worker after it has indexed content but before it acknowledges the message. These tests expose the problems that a happy-path demonstration will not reveal. Bringing It All Together Keeping a RAG system accurate is not simply a matter of re-running embeddings whenever a file changes. It requires a deliberate lifecycle design that connects source documents, versioned metadata, asynchronous processing, search-index operations, and retrieval-time authorization. Azure Blob Storage can preserve the source documents, Cosmos DB can track authoritative lifecycle state, Service Bus can distribute background work, and Azure AI Search can provide retrieval. Microsoft Foundry supplies the models, while Microsoft Agent Framework can support the parts of the application that genuinely benefit from agentic orchestration. The architecture becomes reliable when it assumes that failures will happen: messages may be repeated, jobs may finish out of order, index operations may partially succeed, and cleanup may take time. Version checks, idempotent operations, explicit lifecycle states, reliable event publication, and reconciliation turn those failure modes into manageable engineering problems. The objective is not merely to keep the index populated. It is to ensure that every answer is grounded in information that is current, eligible, and authorized for the user who asked the question. Further Reading Azure AI Search: Delete documents Azure Cosmos DB: Change feed Azure Service Bus: Duplicate detection Microsoft Agent Framework I'd be interested to hear from engineers building production RAG systems: how do you coordinate document updates and deletions across your source of truth and search index?450Views4likes2CommentsIntroducing the customer conversation harness in Microsoft Copilot Studio
By Omar Aftab, Vice President, Conversational AI The way customers interact with brands is fundamentally changing. More and more interactions are driven by conversational AI, and customers increasingly expect every interaction to be deeply personalized and contextual. With millions of people interacting with sophisticated AI systems every day, consumers are no longer willing to put up with legacy IVRs, restrictive menus, and loss of context. Engaging with customers has been central to Microsoft Copilot Studio from the very start. Copilot Studio customers have created thousands of agents that engage with their customers, whether those customers are chatting on a website, speaking with a voice agent on the phone, or using an AI agent embedded in an app or kiosk. Today we’re announcing the public preview of our new customer conversation harness in Copilot Studio. This is a purpose-built harness and builder specifically designed to create powerful conversational agents for customer engagement. It supports the full arc of a customer interaction in a modern world: connecting to customers across channels, understanding what they need, drawing on the right knowledge and tools, interacting with human representatives as needed, and providing a swift resolution – whether the customer is speaking or typing. To enable this, the harness introduces a set of core new conversational capabilities. These range from teams of agents that work together, more seamless interactions between generative skills and deterministic topics, powerful omnichannel conversations across chat and voice, to better human-agent interactions. The harness also enables integration with third-party contact centers through our new Microsoft Contact Center Intelligence product that we also announced today. Build intelligent conversational agents that work together At the center of the new harness is the new conversational agent builder. Makers can now build state-of-the-art experiences for voice and chat within a single agent. Every agent is omnichannel out of the box and has the skills you’d expect any versatile customer-facing representative to have. They speak conversationally. They understand multiple languages. They are channel-aware. You can move between digital and voice channels without losing context, and the agents maintain memory across them. Connect a team of specialized agents to business knowledge and tools The customer conversation harness makes it easy to orchestrate multiple agents to work together as a team of specialists. Each sub-agent can have its own knowledge and its own tools to hand its own specialized tasks. At GA, each agent will also be able use its own model. This means makers can choose which model is best suited to the kinds of jobs and intents each specialist agent handles. Some tasks call for deep reasoning, while others benefit from models optimized for cost and latency. The harness is designed to orchestrate and combine these agents seamlessly into one customer engagement system. What's more: Microsoft Foundry extensibility is built in. You can create a custom agent with code in Foundry and add it to the team of agents with just a few clicks. The harness handles the complexity and does the heavy lifting, allowing you to build on your existing assets or more easily leverage pro-code capabilities. Finally, Microsoft IQ, which helps ground AI experiences in your organization's work context and business data, is also backed into the harness and available to each agent. With Work IQ, agents can draw on information from the Microsoft 365 apps your team uses every day. For example, an agent helping resolve a billing dispute could reference a refund policy stored in SharePoint and also reference an exception that was agreed to in a Teams thread. The agent accesses this information with its own identity, respecting existing enterprise data access and security policies. Agents can also connect to Foundry IQ for large-scale knowledge sources, such as product manuals, warranty terms, and documents indexed in Azure AI Search; Fabric IQ for reasoning over business data; and more. Combine generative skills with topics Each agent in the team handles multiple jobs - whether it's recommending a credit card, looking up a balance, or taking a payment. And just like when giving a task to an employee, you can provide general instructions for some tasks, and provide specific turn-by-turn directions for others. In the new harness, each agent skill can either be fully generative - you simply provide a prompt and let the model use its own judgment (e.g. “Go and gather the credit card information from the user”) - or fully deterministic, using a topic (commonly used, for example, in IVRs or voice trees where exact, step-by-step instructions are desired). This flexibility is key for large customer engagement systems and has been a recurring customer ask. In the past, an agent could do one or the other. Now, each agent in your team can seamlessly handle a mix of both, depending on the job to be done. Deliver natural experiences across voice and chat Because the harness is natively omnichannel, voice is a first-class experience for both makers and customers. You can choose among speech models and configure rich voice capabilities. These include voice fonts for more natural and customized interactions, speech instructions to guide the agent’s tone and speaking style, DTMF behavior, speech sensitivity settings, and more. When you're ready to publish, you can even acquire phone numbers and deploy your agent to them, making the agent accessible to customers over the phone. And you can test and evaluate all of this right within the experience. Make customer verification easier with voice biometrics Authentication can be one of the most frustrating parts of a customer service call. Traditional verification methods, from security questions to one-time passcodes, can add time and friction before customers can even explain why they're calling. Verifying a customer's identity is essential, but it shouldn't get in the way of a great service experience. The new harness, together with Contact Center Intelligence, supports enterprise grade state-of-the-art voice biometrics that help authenticate customers in real time. Rather than ask a rigid set of questions to validate identity, customers can continue to speak about why they’re calling in while the system validates the caller's identity with a unique voiceprint designed to meet the precision level required by the organization. This also means that if a call drops and the customer calls back, the conversation can seamlessly resume. Connect customer conversations to the enterprise Conversational agents and human representatives work best when they can collaborate to resolve customer needs, and the customer conversation harness in Copilot Studio provides built-in handoff capabilities for different kinds of escalation paths to live representatives. Partner with your human agents in Teams Out of the box, the new harness has better support for partnering with your internal employees in Teams. You can escalate incoming calls to a Teams queue, and very soon directly to Teams chats. Think of a scenario: Oh, that’s an invoice coding issue, it should go to…Sally in accounting. And you can send that call to Sally with just a few clicks, right from within the UX. Or connect to your existing contact center When a full-fledged contact center is needed, connecting to one is simple. The new harness is designed to integrate seamlessly with our new Microsoft Contact Center Intelligence product and is also accessible within it. You can connect to your existing contact center, modernize your existing IVR systems and chat bots, partner with your existing human agents, configure advanced biometrics, score your calls, get insights on how your human-AI partnerships are working, and more - while retaining your existing telephony, routing, and queues. All with a few simple clicks. Govern agents with Microsoft Agent 365 Finally, like all Copilot Studio agents, these conversational agents are fully part of Microsoft’s Agent 365 governance story. Every agent built on the customer conversation harness will show up in Agent 365 upon creation. Admins should immediately see the details of the agent, including owner, channels, Entra agent ID, knowledge, tools, permissions, usage, etc. Centralized governance helps admins apply and update existing policies comprehensively across the enterprise. And, like the rest of Copilot Studio, the customer conversation harness uses Copilot Credits with usage-based billing, so it's easy to get started. Get started with the customer conversation harness With the new customer conversation harness in Copilot Studio, we're helping organizations build more natural, intelligent, and effective customer experiences - wherever they engage with customers. Many of these capabilities are available now in public preview, with more rolling out over the coming weeks. Together with the launch of our new Contact Center Intelligence offering, this is the first step in a journey to transform how everyone on the planet interacts with a brand. Head over to Copilot Studio, click "more ways to build" to try out our new customer conversation harness, and start changing how you engage with your customers today. For more information as you get started, explore the resources below: Learn how to build with the customer conversation harness Read about Microsoft Contact Center Intelligence4.9KViews4likes1Comment
STAR: A Simple Way to Choose the Right Microsoft Copilot Studio Architecture
STAR: A Simple Way to Choose the Right Microsoft Copilot Studio Architecture One of the biggest challenges when building AI agents isn't creating the agent itself. It's choosing the right architecture for what you want the agent to accomplish. Should you use the Standard harness? The GitHub Copilot harness? Extend Microsoft 365 Copilot Chat? Build an application around your agent? Or create a voice-driven experience? These options serve different purposes. Choosing the wrong starting point can introduce unnecessary complexity and rework. I use a simple mnemonic called STAR to organize four important architectural considerations when designing solutions with Microsoft Copilot Studio. STAR stands for: S: Standard harness T: Task-oriented automation with the GitHub Copilot harness A: Application experiences R: Real-time voice experiences STAR is my own decision-making mnemonic, not an official Microsoft framework. Let's explore each option. S: STANDARD HARNESS When predictability matters The Standard harness is a useful starting point for agents that follow defined topics, instructions, conditions, and conversational paths. Consider an internal knowledge agent that answers questions using approved enterprise information and follows predefined workflows for specific tasks. The Standard harness lets you structure the conversation and control behavior through the components you configure. Consider this approach when: The process follows predictable steps. You need structured conversations and defined paths. The agent relies on established topics, prompts, and knowledge. You want to control the experience through explicit configuration. The principle is simple: when the process is predictable, a structured architecture can be the right choice. Official documentation: https://learn.microsoft.com/en-us/microsoft-copilot-studio/harnesses-overview 2.T: TASK-ORIENTED AUTOMATION WITH THE GITHUB COPILOT HARNESS When the agent needs to reason, plan, and execute Some tasks cannot be described as a simple sequence of predefined conversation paths. An agent might need to inspect multiple files, gather information from different sources, invoke several tools, evaluate intermediate results, and adjust its approach as the task progresses. The GitHub Copilot harness in Microsoft Copilot Studio is designed for this kind of reasoning-heavy execution. Despite its name, this is a Copilot Studio agent runtime, not the GitHub Copilot coding assistant. Depending on the configured capabilities, an agent can use tools, knowledge sources, MCP servers, connected agents, skills, and memory to accomplish a task. For example, an agent could analyze business documents, extract relevant information, prepare a structured summary, and generate an output file. Consider this approach when: The task involves multiple reasoning steps. The agent needs to work across several tools or information sources. File creation, editing, or analysis is important. The execution path may change based on intermediate results. You want to automate a complex business process. The key distinction is adaptive, multi-step execution rather than relying exclusively on predefined conversational paths. Official documentation: https://learn.microsoft.com/en-us/microsoft-copilot-studio/harnesses-overview 3.A: APPLICATION EXPERIENCES When a conversation is not enough Sometimes, the requirement is not simply to build an agent that answers questions. You need an application experience around the agent. This could include interactive components, structured data, custom layouts, dashboards, forms, and controls that let users work with information visually. Microsoft Copilot Studio Apps provide an application-oriented approach to creating experiences around agents and their capabilities. Depending on the requirements, developers may also use technologies such as SharePoint Framework (SPFx) to build custom components and integrate agent capabilities into SharePoint experiences. Imagine an AI-powered project workspace where users can ask questions, review generated insights, interact with structured information, and use custom interface components. The agent provides reasoning and conversational interaction, while the application provides the surrounding user experience. Consider an application-oriented architecture when: Users need more than a chat interface. The solution requires custom interactive components. Structured information needs to be presented visually. The experience must integrate with an existing application or SharePoint environment. You need greater control over the surrounding interface. The important question is whether users need a conversation or an application powered by an agent. Official documentation: https://learn.microsoft.com/en-us/microsoft-copilot-studio/apps-experience/apps-overview 4.R: REAL-TIME VOICE EXPERIENCES When interaction happens through speech Some agent experiences begin with spoken conversation rather than a typed prompt. Voice introduces additional architectural considerations, including speech processing, turn-taking, response timing, and conversational context. Microsoft Copilot Studio supports voice experiences, with available capabilities depending on the selected configuration and deployment channel. When designing a voice-driven solution, consider the entire interaction rather than simply converting text responses into speech. For example, an agent might need to understand spoken instructions, retrieve relevant information, perform a task, and communicate the result naturally. Consider a voice-oriented architecture when: Spoken interaction is a core requirement. Users need hands-free interaction. The solution depends on natural conversational turn-taking. Speech and conversation management are central to the experience. Voice is an interaction and deployment consideration rather than a direct equivalent of the Standard or GitHub Copilot harness. Confirm which capabilities are supported for your intended scenario. Official documentation: https://learn.microsoft.com/en-us/microsoft-copilot-studio/ WHAT ABOUT THE COPILOT CHAT HARNESS? STAR organizes four architectural considerations, but another important option is the Copilot Chat harness. This harness is designed to extend Microsoft 365 Copilot Chat with organizational knowledge so employees can obtain grounded answers within their existing Microsoft 365 experience. For example, an organization might want employees to retrieve information from approved internal knowledge without building an entirely separate application. In that case, extending Microsoft 365 Copilot Chat may be a better fit than creating a standalone agent experience. Consider it when the primary objective is to bring organizational knowledge into Microsoft 365 Copilot Chat. Official documentation: https://learn.microsoft.com/en-us/microsoft-copilot-studio/harnesses-overview QUICK DECISION GUIDE Structured conversations and predictable paths: Consider the Standard harness. Complex, multi-step tasks involving reasoning and tools: Consider the GitHub Copilot harness. Extending Microsoft 365 Copilot Chat with organizational knowledge: Consider the Copilot Chat harness. Custom application experiences and interactive components: Consider Copilot Studio Apps or a suitable custom application. Custom SharePoint interface components: Consider SharePoint Framework (SPFx), where appropriate. Speech-driven interaction: Consider a supported Copilot Studio voice experience. These options do not all belong to the same architectural layer. The Standard, GitHub Copilot, and Copilot Chat harnesses are runtime options. Applications and SPFx shape the user experience. Voice describes an interaction channel and its associated capabilities. A solution may combine multiple options when the selected technologies support the intended architecture. ARCHITECTURE BEFORE IMPLEMENTATION When planning an AI solution, it is tempting to start with whichever feature looks most impressive. A better approach is to begin with the work the solution must perform. Ask four questions. First, how predictable is the task? If the process follows established rules and paths, start by evaluating the Standard harness. Second, how much reasoning and adaptation does it require? If the agent must work through a complex objective involving multiple tools and intermediate decisions, evaluate the GitHub Copilot harness. Third, what experience do users actually need? If they need interactive components, structured information, or a custom application, consider the application layer separately from the agent runtime. Fourth, how will users interact with the solution? Determine whether the experience belongs in Microsoft 365 Copilot Chat, a custom application, a supported voice channel, or another appropriate deployment surface. These questions help establish the architecture before investing time in implementation. FINAL THOUGHTS Microsoft Copilot Studio offers different approaches to building agents and delivering experiences. The challenge is knowing which combination makes sense. My STAR mnemonic provides a simple starting point. S: Standard for structured execution. T: Task-oriented automation for complex, multi-step work. A: Applications for richer user experiences. R: Real-time voice for speech-driven interaction. The Copilot Chat harness is another option when the goal is to extend Microsoft 365 Copilot Chat with organizational knowledge. STAR is not about choosing the most advanced technology every time. It is about choosing an architecture that matches the task, the users, and the experience you want to build. How do you decide between a structured agent, a multi-step workflow, and a custom application experience when designing your next Copilot Studio solution? ABOUT ME! Sapan Patel AI Agent Developer | Microsoft Copilot Studio | Cowork | Power Platform | Azure AI38Views0likes0CommentsUnderstand the Copilot Studio app-building harness
The first important distinction is that building an app is different from building a conversational agent. An app provides an interactive user interface. An agent reasons about a request and may use tools to accomplish a task. A workflow executes defined business logic. You can combine all three in a business solution. Component Responsibility Example Copilot Studio Apps User interface and application experience An employee service dashboard GitHub Copilot harness AI-powered building and orchestration runtime Planning multi-step tasks and generating app components Agent Reasoning and task execution Investigating a service request Workflow Repeatable business process Routing an approved request Data layer Stores and retrieves business information Requests, users, approvals, and status Connectors and APIs Integrates enterprise systems SharePoint, Microsoft Graph, or ServiceNow The GitHub Copilot harness in Copilot Studio is not the same thing as using the GitHub Copilot service. It is a Copilot Studio runtime for advanced reasoning and orchestration. Microsoft's documentation states that the normal Copilot Studio security, privacy, compliance, and data residency commitments continue to apply. 2. Before building: define the application properly One of the biggest mistakes is asking the builder to create an app with a vague prompt. For example: Weak prompt "Build an employee management app." This leaves too many decisions to the AI. It might generate an attractive interface but miss important business requirements. Instead, define these eight elements before generating the application. Element What to specify Business problem What problem does the application solve? Target users Who will use it? User journeys What tasks must users complete? Data model What entities, fields, and relationships are needed? UI requirements What screens, components, filters, and interactions are required? Business rules What validations and conditions must be enforced? Integrations What APIs, data sources, and systems are involved? Security Who can view, create, edit, approve, or delete records? Also define the acceptance criteria before generation. For example: Users can search requests by ID, owner, status, and date. Selecting a request opens its detailed view. Users can update permitted fields. Invalid status transitions are rejected. Loading, empty, and error states are handled. Changes are persisted to the intended data source. My recommendation: Write the requirements first, then build the app. Don't use repeated prompts to discover the business requirements while simultaneously generating the UI. 3. Step-by-step guide to building an app Step 1: Open the app-building experience Open copilot studio Step 2: Start with a complete application specification Let's use an example: an Enterprise AI Operations Dashboard. The app will help employees and administrators monitor AI automation requests, investigate failures, track processing time, and manage remediation. Start with a structured prompt. Master app-generation prompt You can adapt this prompt for your first build. Build a professional enterprise application called Enterprise AI Operations Dashboard. BUSINESS OBJECTIVE Create a centralized interface for monitoring AI automation requests, execution outcomes, failures, processing time, and remediation activities. TARGET USERS Operations analysts who monitor executions. Administrators who investigate failures. Managers who review operational performance. APPLICATION STRUCTURE Create the following pages: Overview Dashboard Total executions Successful executions Failed executions Success rate Average processing time Execution trend over time Recent failures Status distribution Execution Explorer Search by execution ID Filter by status, application, owner, and date Sort by execution time and duration Paginated or appropriately limited results Select an execution to open its details Execution Details Execution ID Application name Initiated by Start time and end time Duration Status Error summary Diagnostic information, when available Remediation history Remediation Center Display unresolved failures Allow authorized users to assign an owner Add investigation notes Update remediation status Record timestamps for changes Settings Configurable filters and display preferences Clear explanation of administrative permissions No destructive administrative actions without confirmation DATA MODEL Create a logical data model containing: Execution: ExecutionId ApplicationName InitiatedBy StartTime EndTime DurationSeconds Status ErrorSummary Environment RemediationStatus Remediation: RemediationId ExecutionId AssignedTo Notes Status CreatedAt UpdatedAt Define a relationship between Execution and Remediation. If a persistent data source is not configured, use clearly identified sample data. Do not present sample data as live production data. UI AND DESIGN Use a clean, modern enterprise dashboard with: Clear visual hierarchy Readable typography Consistent spacing Responsive layouts Accessible contrast Reusable UI components Summary cards Appropriate charts Searchable and filterable tables Clear loading, empty, success, and error states FUNCTIONAL REQUIREMENTS Search and filters must work. Dashboard metrics must be calculated from the underlying dataset. Selecting a row must display the corresponding execution details. Form inputs must be validated. Status changes must update the intended data source. Display clear error messages when operations fail. Prevent duplicate submissions where appropriate. Confirm potentially destructive actions. Preserve filters when navigating between related screens where feasible. SECURITY Respect the signed-in user's permissions. Do not expose secrets, access tokens, or sensitive diagnostic information. Do not rely on hiding a UI button as the only authorization control. Enforce authorization at the data source or API. Do not create external integrations without explicitly identifying their requirements. IMPLEMENTATION PROCESS First, summarize the proposed architecture, data entities, pages, and assumptions. Ask clarifying questions if a critical requirement is ambiguous. Then generate the first functional version of the application. After generation, test the primary user journeys and identify incomplete functionality. Clearly distinguish implemented features, simulated features, and integrations that still require configuration. This is a starting specification, not a guarantee that every requested capability will be generated correctly. Inspect the resulting application and verify its actual behavior. Step 3: Review the generated application Once the app preview appears, don't immediately ask for more features. First, inspect the application against the specification. Check: Does the navigation work? Are the pages connected logically? Do the tables display consistent data? Do the filters actually change the results? Are dashboard metrics calculated correctly? Does selecting a record open the correct details? Do forms validate required fields? Does saving actually persist the changes? Are the displayed integrations real or simulated? This distinction is essential: a functional-looking interface is not proof of a working backend. Microsoft's app-building experience provides an interactive preview and lets you refine the app through conversation. It also exposes the underlying code for inspection. 4. Technical prompting techniques for better apps This is where you can significantly improve the quality of generated applications. Technique 1: Build in controlled iterations Avoid asking the builder to implement every feature, integration, chart, and workflow in one enormous request. Use a sequence of targeted changes. Iteration 1: Application foundation "Review the generated application and identify missing requirements. Fix the navigation structure, page layout, data model, and core interactions before adding new features." Iteration 2: Data integrity "Review the application data model. Ensure each execution has a unique identifier, remediation records reference valid executions, and dashboard metrics are calculated from the underlying records. Identify any assumptions that require confirmation." Iteration 3: UI quality "Improve the visual hierarchy, spacing, typography, responsive behavior, table readability, and empty states. Preserve existing functionality and data relationships." Iteration 4: Functional behavior "Test search, filtering, sorting, record selection, form validation, and save operations. Fix broken interactions. Do not replace functional data operations with hardcoded sample results." Iteration 5: Error handling "Add appropriate handling for failed API requests, unavailable data, validation errors, empty results, and repeated submissions. Provide useful user-facing messages without exposing secrets or internal stack traces." Iteration 6: Final verification "Compare the application against the original requirements. List each requirement as implemented, partially implemented, or not implemented. Identify any feature that uses mock data or still needs external configuration." This approach makes failures easier to isolate and reduces the risk of breaking working functionality during a large rewrite. Technique 2: Specify behavior, not just appearance A prompt such as: "Add a modern search bar." defines appearance, not behavior. A better instruction is: "Add a search field above the execution table. Search across ExecutionId and ApplicationName. Apply the search when the user submits or after a short debounce. Combine the search with existing status and date filters. Show an empty state when no records match. Provide a clear-search action and preserve the selected sort order." The second instruction describes expected behavior, interaction, and edge cases. Technique 3: Define invariants An invariant is a condition that must remain true throughout the application. Examples: Every remediation record must reference an existing execution. Execution IDs must be unique. Failed executions must not be marked successful merely because a remediation note was added. A user cannot approve their own request if the business policy prohibits it. Dashboard metrics must use the same filtering rules as the displayed data. Failed writes must not display a false success notification. Add important invariants to the application specification and ask the builder to preserve them during modifications. Technique 4: Request minimal changes When fixing a specific problem, avoid asking the builder to regenerate the entire application. Instead, use an instruction such as: "Fix the execution table's date filter. Preserve the existing navigation, data model, styling, and other filters. Change only the logic needed to make the date filter work. Verify that it works independently and in combination with the status filter." This helps reduce unintended changes and makes troubleshooting easier. Technique 5: Ask for evidence of completion Don't accept a statement that a feature is complete without testing it. Ask: "Identify the implementation for this requirement, test the relevant user journey in the preview, and report any remaining limitation. If the functionality depends on an unconfigured API or connector, identify that dependency explicitly." Where the preview does not allow a test to be performed, request a clear statement of what remains unverified. 5. Underlying code: what to inspect Copilot Studio's app authoring experience includes a way to switch between the interactive preview and the underlying code. Use that capability to inspect the implementation rather than treating the generated UI as a black box. A. Component structure Look for whether the application separates responsibilities into logical components, such as: Navigation Dashboard cards Charts Data tables Search and filter controls Detail views Forms Notifications Loading and error states A large application that puts everything into one component can become difficult to maintain. Prompt: "Review the application structure and identify opportunities to separate repeated UI patterns into reusable components. Refactor only where the current authoring environment supports it, and preserve the existing behavior." B. State management Check how the app manages: Selected records Active filters Search terms Form values Loading states API errors Unsaved changes For example, changing the status filter should not unexpectedly clear the search term or cause the selected record to display stale data. Prompt: "Review state management for the search, filter, table, and detail views. Prevent stale selections, inconsistent filters, and UI updates that occur before a save operation succeeds." C. Data access Identify whether each data source is: Hardcoded sample data Local application state A configured connector A REST API A persistent business data source For production applications, ensure the data access layer has clear responsibilities and that failures are handled consistently. Prompt: "Identify every data source used by the application. Classify each as sample data, local state, or a live integration. Do not imply that data is persisted if it exists only in memory." D. Security Inspect the implementation for: Sensitive values embedded in client-side code Authorization implemented only through UI visibility Excessive data exposure Missing validation Unrestricted destructive operations Unclear handling of user identity Never place API secrets or privileged credentials in browser-accessible code. For sensitive operations, authorization must be enforced by the relevant backend or data source, not just by the interface. Important: Access to the app and access to its underlying data are separate concerns. Microsoft's documentation explains that apps use the signed-in user's identity when connecting to organizational data, and sharing an app does not automatically grant access to data the recipient otherwise cannot access. 6. Connecting the app to enterprise systems For a Microsoft enterprise scenario, you might need to connect the app to SharePoint, Dataverse, Microsoft Graph, Power Automate, or an internal API. The appropriate integration depends on the operation and the capabilities supported by the app-building environment. Requirement Possible integration Technical consideration Store business records Dataverse Define tables, relationships, permissions, and validation Read or update SharePoint items SharePoint connector or API Respect site and item permissions Retrieve Microsoft 365 information Microsoft Graph Configure authentication, consent, and least-privilege permissions Execute deterministic business logic Power Automate or an appropriate workflow Handle failures, retries, and duplicate requests Integrate a custom enterprise system REST API or supported connector Define authentication, schemas, and error contracts Use agent reasoning Copilot Studio agent Restrict tools and define clear instructions These are architecture options, not a claim that every integration is automatically configured by the app builder. Recommended architecture For an enterprise application, consider the following logical design: User ↓ Copilot Studio app and UI ↓ Approved application actions ↓ Connector, workflow, or API ↓ Business data source Where reasoning is required, the app can also invoke an appropriately configured agent. Keep responsibilities separate: UI: Collect input and display results. Business logic: Enforce validation and business rules. Agent: Handle tasks that benefit from reasoning. Workflow: Execute predictable, repeatable steps. Data source: Persist records and enforce applicable access controls. For example, an AI-generated remediation recommendation can be presented in the UI, but changing a production system should require an authorized action and the appropriate validation. 7. App testing: use a structured checklist Before publishing, test the main user journeys, not just the visual design. Test category Example test Functional Can the user create, view, and update a record? Validation Does the app reject a missing required field? Data integrity Does a remediation reference the correct execution? Filtering Do search and status filters work together? Error handling What happens when the API returns an error? Persistence Does the update remain after refreshing or reopening the app? Authorization Can an unauthorized user perform a restricted action? Accessibility Are controls labelled and keyboard-accessible? Responsive design Does the layout remain usable at narrower widths? Performance Does the interface remain responsive with realistic data volumes? Security Are secrets excluded from client-side code? Data integrity under failure Does a failed write avoid displaying a false success message? For each critical requirement, define an expected result and test it. For an application that modifies business data, also test repeated submissions, concurrent updates, and partial failures where applicable. 8. Optimize Copilot Credits and iteration time App creation, previewing, testing, and refinement can consume Copilot Credits. Microsoft documents usage-based billing for the app-building experience. These practices can help reduce unnecessary iterations. Write a complete specification first. Resolve critical questions about users, data, and business behavior before generation. Generate a minimum viable application. Start with the core pages and one complete user journey. Fix related problems together. Instead of making five separate requests for spacing, typography, card alignment, and table readability, group those visual changes into one clearly scoped request. Avoid unnecessary full rewrites. Ask for a targeted fix and explicitly preserve unrelated functionality. Separate requirements from optional enhancements. Finish the core user journey before adding animations, elaborate charts, and secondary features. Reuse a master specification. Keep the requirements, data model, and acceptance criteria in a reusable document so you don't need to reconstruct them for every iteration. Verify before requesting another change. Test the current result first. Otherwise, you may spend credits fixing an issue that no longer exists or introduce a new issue while fixing an old one. These are practical optimization strategies, not a guarantee of a particular percentage reduction in credit consumption. 9. Publishing and sharing the application Once the app has passed its tests: Review the final UI and application behavior. Confirm that sample data is clearly distinguished from live data. Verify configured connections and permissions. Test the intended user experience. Use the available publish action to publish the app. Share it with the intended users or groups. Verify access with an appropriately authorized test account. Document known limitations and outstanding integrations. The preview status matters. Microsoft explicitly notes that Apps in Copilot Studio is a preview feature, which may have restricted functionality and is not intended for production use. Therefore, don't assume that a successful preview or publishing action alone makes the application suitable for production. Confirm the current feature terms, organizational approval, and production-readiness requirements before deploying it for business-critical use. My final recommendation For your work with Copilot Studio, Power Platform, Cowork, MCP integrations, and enterprise automation, I would develop a reusable App Builder Playbook with five parts: A requirements template. A master app-generation prompt. A reusable set of UI and data-model refinement prompts. A testing and security checklist. A credit-optimization and publishing checklist. That gives you a repeatable engineering process instead of relying on trial-and-error prompting for every new app. The most important principle is this: use natural language to accelerate implementation, but use engineering discipline to verify the result.82Views1like0Comments