agentic ai
33 TopicsEnterprise Deployment Architecture for Agentic AI: ChatGPT-Style UI on IIS over Agents & MCP Servers
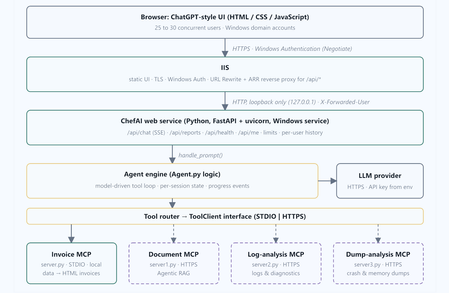
Research Disclaimer: This article is a technical research paper intended solely for educational, research, and illustrative purposes. It reflects the author’s personal technical perspectives. All concepts, architectural designs, diagrams, and implementation approaches are provided “AS IS” for technical exploration and review, not as production-ready development guidance. Organizations considering implementing these approaches should consult their internal software development standards, enterprise architecture teams, corporate security policies, and governance requirements. Any production implementation must undergo appropriate end-to-end architectural, security, privacy, compliance, and responsible AI or ethics reviews, along with necessary testing and organizational approvals before deployment. Abstract. Large language model agents that call tools through the Model Context Protocol (MCP) are usually shown from a console or a developer IDE. Enterprise users expect something different. They want a familiar chat interface, single sign-on and steady behavior when many people use the system at once. This paper gives architectural guidance for a ChatGPT-style web interface, hosted in Microsoft Internet Information Services (IIS) with Windows Authentication, that fronts an MCP-based agent for 25 to 30 concurrent users. The work is broken into nine steps: the engine boundary, state isolation, a streaming API, the chat UI, a Windows service host, IIS reverse-proxy configuration, security, testing and deployment. The paper explains why a long-running Python service behind IIS beats launching Python for every request, and why no Kerberos delegation (the double hop) is needed. It also describes a small transport-neutral tool-client layer, so the same agent can call a local STDIO MCP server and several remote MCP servers over HTTPS without any change to the user interface. The reference scenario is ChefAI, a fictitious restaurant-operations assistant that needs real-time answers, invoice generation, and log and crash-dump analysis for technical troubleshooting. Its STDIO server generates invoices. Three HTTP servers handle document retrieval through an Agentic RAG system, log analysis and dump analysis. The agent logic itself is treated as a black box. The paper closes with a threat model, a capacity argument and an evaluation methodology. Keywords: Model Context Protocol, agent user interface, IIS, Windows Authentication, reverse proxy, Server-Sent Events, agentic RAG, concurrency control, tool routing 1. Introduction Tool-using language model agents have become practical because protocols such as the Model Context Protocol (MCP) standardize how an agent discovers and calls external capabilities [1]. A typical agent loop sends a user request and the list of available tools to a model, receives a tool choice, runs the tool, and feeds the result back until the model can answer. The loop is easy to demonstrate in a terminal. Putting it in front of a team is harder, because the interface, identity, concurrency, streaming and deployment all become real concerns. This paper addresses that gap for a common enterprise setting: Windows infrastructure, an intranet, Active Directory identities and IIS as the standard web host. It is written as a reference architecture. It describes the components, what each one is responsible for, the trust boundaries between them and the order in which to build them. A fictitious reference application, ChefAI (Section 1.2), keeps the discussion concrete. End users reach the application through a browser chat window with their Windows identity, while the agent behind the scenes talks to one local MCP server over STDIO and to several remote MCP servers over HTTPS. 1.1 Contributions A nine-step design for a ChatGPT-style web interface that fronts an MCP agent and is hosted on IIS with Windows Authentication (Sections 4 and 5). A concurrency design sized for 25 to 30 simultaneous users, with explicit queues, per-user limits, timeouts and cleanup (Sections 5.2, 5.5 and 10). A transport-neutral tool-client layer made of an interface, a server registry and a router, which keeps the UI independent of how tools are reached (Section 6). A reference fleet of four MCP servers with different capabilities and data sensitivities, including an Agentic RAG document server, used to reason about routing and security (Section 7). An analysis of identity flow showing that no Kerberos delegation is needed, a threat model and an evaluation methodology (Sections 8 to 10). 1.2 The ChefAI reference application What ChefAI is. ChefAI is a fictitious restaurant-operations application used throughout this paper as the reference scenario. It is an AI assistant for a restaurant business. Staff need real-time answers during service, invoices generated from purchasing data, and help with technical troubleshooting when systems such as point-of-sale terminals, kitchen displays or online-ordering services misbehave. Staff describe what they need in plain language in a browser. The assistant decides which capability to use and answers with figures, documents, diagnostics or a generated report. How it is structured. The application is split into an agent and four MCP servers. Agent.py is the agent. It receives a request, consults a language model and calls tools exposed by MCP servers. The first server, server.py , is a local STDIO server and acts as the invoice generator. It reads purchasing data and produces HTML invoices and reports. The other three servers are remote HTTP(S) servers ( server1.py , server2.py and server3.py ), not STDIO, and the agent calls them to get information and to support technical issues. They are a document processor that answers questions by retrieving data and documents from an Agentic RAG system, a log analyzer and a dump analyzer. Table 0 summarizes the scenario. Capability Example request from staff Served by Transport Real-time spend answers “What did we spend on tomatoes last year?” Invoice server ( server.py ) STDIO, local Invoice generation “Generate the year-to-date invoice.” Invoice server ( server.py ) STDIO, local Knowledge and documents “What is our return policy for dairy deliveries?” “How do we descale the combi oven?” Document processor with Agentic RAG ( server1.py ) HTTPS, remote Log analysis “Why did the point-of-sale terminals time out on Friday evening?” Log analyzer ( server2.py ) HTTPS, remote Dump analysis “The kitchen display crashed. What does this dump show?” Dump analyzer ( server3.py ) HTTPS, remote Table 0. The ChefAI reference scenario: capabilities, the server that provides each, and its transport. The scenario deliberately mixes a business need (spend, invoices, policies) with an operational need (logs, dumps and runbooks). One interface therefore has to route between servers with very different data and risk profiles. The restaurant details, hostnames and example questions are illustrative and do not describe a real business. 1.3 Scope The focus is the user-interface tier and its hosting. The agent internals are out of scope except for the configuration the UI depends on, namely how the agent is invoked and how it reaches tools. The tool names, capacity figures and timeouts in this paper are illustrative design values. They show how to reason about a deployment and should be checked against the real workload (Section 10). 2. Background 2.1 The Model Context Protocol and its transports MCP defines how a client discovers a server’s tools, resources and prompts and calls them using JSON- RPC messages [1]. Two standard transports matter here. STDIO launches the server as a child process and exchanges messages over standard input and output. It is simple and local and needs no network port, but it ties the server’s lifetime to the client process. Streamable HTTP exposes the server at a URL. That allows servers on other machines, shared by several clients and protected by TLS and HTTP authentication. The official SDKs let the same tool code be exposed over either transport, so a server can move from one to the other without rewriting its tools. 2.2 Server-Sent Events for progress Agent requests can last tens of seconds because they chain model calls and tool calls. Server-Sent Events (SSE) let the server push a one-way stream of text events over an ordinary HTTP response [2]. This suits a chat interface that wants to show “queued”, “analyzing logs” and “building invoice” before the final answer. SSE also passes through reverse proxies more easily than WebSockets, as long as buffering is turned off. 2.3 IIS, ARR and Windows Authentication IIS can authenticate users with the Negotiate provider, which uses Kerberos where available and falls back to NTLM [3]. With the URL Rewrite and Application Request Routing (ARR) extensions, IIS can act as a reverse proxy. It forwards selected paths to a back-end service and can copy server variables such as LOGON_USER into request headers [4]. 2.4 The double-hop problem A “double hop” happens when a server has to use the caller’s Windows identity to reach a second server on the caller’s behalf. That requires Kerberos delegation. Section 8 shows why this design avoids it. 3. Requirements and Constraints Category Requirement Interface ChatGPT-style chat in a browser, real-time progress, a stop button, report cards with preview, and no CDN so it works offline on an intranet. Identity Windows Authentication in IIS. The application knows the user’s name and never handles user passwords. Concurrency 25 to 30 simultaneous users without cross-user data leakage, orphaned processes or unbounded resource use. Tools A local STDIO MCP server and several remote HTTPS MCP servers. The UI must not change when servers are added or moved. Security LLM keys never in files, logs or the browser. Loopback-only back end, output escaping, restrictive report serving and allow-listed remote servers. Operations Runs as a Windows service with restart on failure, structured logs and idempotent deployment scripts. Constraints System Python without virtual environments, standard-library HTTP for model calls, IIS as the only public listener and no Kerberos delegation. 4. System Architecture Figure 1 shows the end-to-end architecture. Users reach IIS over HTTPS and authenticate with Windows credentials. IIS serves the static single-page interface and reverse-proxies /api/* over loopback to a Python web service. The service owns the agent engine, which plans with a language model and calls tools through a router. The router reaches the local invoice server over STDIO and the remote servers over HTTPS. Figure 1. End-to-end architecture. Solid boxes and arrows are local components and the local STDIO server. Dashed boxes and arrows are remote MCP servers reached over HTTPS. Adding a server only touches the service and the tool layer. The browser and IIS tiers stay the same. 4.1 Request lifecycle Figure 2 follows a single prompt. The browser posts to /api/chat . IIS authenticates the user, overwrites the identity header and proxies the call. The service queues and admits the request, then streams status events while the engine consults the model and calls tools. The loop repeats, up to a fixed number of tool calls, until the model reports completion or, for report requests, an HTML file exists. The final answer and report links go out as the last events. Figure 2. Request lifecycle for one prompt. Messages 3 and 12 are Server-Sent Events returned through IIS on the original HTTP response. The browser never talks to the engine, the model or any MCP server directly. 4.2 Why a web service sits between the browser and the agent, and why the browser cannot call MCP servers directly The browser cannot call the agent directly, for reasons of feasibility and of fitness. On feasibility, clientside JavaScript can only issue HTTP requests and cannot start or import a Python program. IIS, as a static-file and ASP.NET host, has no in-process Python runtime. An agent is also a script and not a network endpoint, so something has to listen for requests and invoke it. On fitness, an agent request is long-lived, stateful and costly. It chains model and tool calls for tens of seconds, spawns MCP child processes that must be cleaned up on timeout or disconnect, keeps per-conversation state and has to stream progress. It therefore needs a persistent process that can enforce admission control (per-user gates, a bounded queue, semaphores and timeouts), isolate sessions, emit Server-Sent Events and hold the model key and service credentials in a service account, not in the client or the IIS application pool. Launching Python for every request would add seconds of start-up cost and make streaming, cancellation and cleanup fragile. Letting IIS supervise the process, for example through FastCGI or HttpPlatformHandler, changes who restarts it but not the need for it. The browser also cannot call the MCP servers directly. A STDIO server has no network listener at all. A Streamable HTTP server does carry MCP’s JSON-RPC over HTTP, so transport is not the real obstacle. The real obstacle is that an MCP server exposes typed tools and does not understand natural language, so some component must decide which tool to call with which arguments and iterate on the results. That component is the modeldriven agent loop, and it needs the LLM key. Direct access would also place server tokens or client certificates in every browser and expose the sensitive log and dump servers to every desktop. It would bypass central rate limiting, audit, allow-listing and redaction, remove the agent’s defence against prompt injection in tool results, and force the interface to carry discovery, routing and namespacing logic for every server, so adding a server would change the UI. Putting the service in between reduces the browser’s contract to a single HTTP endpoint, /api/chat , and keeps MCP, model credentials and trust decisions on the server side. 5. User-Interface-Centered Design in Nine Steps The design is organized as nine steps (Figure 3). Steps 1 and 2 define the boundary to the agent, Steps 3 and 4 deliver the API and the interface, Steps 5 and 6 host it, Step 7 secures it, Step 8 tests it and Step 9 documents and deploys it. Figure 3. The nine-step roadmap. Amber is the agent boundary, green is the API and interface, grey is hosting, red is security, and purple is verification and delivery. 5.1 Step 1: Define an engine boundary the UI can call An agent is often first written as a console program that mixes the planning loop with prompts and printing. The first step separates them. The agent exposes one asynchronous function, handle_prompt(prompt, history, progress_callback) , that returns {answer, html_files, tool_trace, error} and reports progress through a callback instead of printing. It never reads from or writes to a console. A single prompt box replaces any menu of modes, and the model decides from the live tool list whether the request needs a generated file or only an answer. Recent conversation turns, six by default, are passed as context so that follow-ups such as “now compare it to 2026” work. Only aggregates and provenance go back to the model, and raw rows stay on the server. This boundary is the only contract between the interface tier and the agent. 5.2 Step 2: Remove shared mutable state Agents and tool servers often keep module-level state, such as loaded data and cached query results. With 25 to 30 concurrent users, that state becomes a correctness and privacy hazard. The design therefore does three things. It loads and parses reference data once into an immutable shared dataset, reloaded only when the source file’s size or modification time changes and guarded by a lock. It keeps query results in a per-session store, so each query identifier belongs to exactly one session. And it gives each request an isolated tool connection, or a bounded pool of server processes with per-request session identifiers. Shared outputs are written atomically (a temporary file, then a rename) so a reader never sees a half-written file. 5.3 Step 3: Provide a streaming API The service exposes four endpoints (Table 1). The chat endpoint returns a Server-Sent Event stream. Conversation history is kept per user and conversation with a time-to-live and a cap, and no other user can read it. Endpoint Behavior POST /api/chat Body {prompt, conversation id} . The prompt is validated and capped at 2000 characters. Streams status , tool , result , done and error events (Appendix A). GET /api/reports/{name} Serves generated HTML from one folder only. Filenames are allow-listed and the resolved path must stay inside the folder. Sends a restrictive Content-Security-Policy and nosniff . Reports are scoped per user, plus shared built-in reports. GET /api/health Status, provider, model, data-loaded flag, queue depth and running count. Never keys or paths outside the project. GET /api/me Authenticated display name taken from the trusted header. Table 1. API surface of the web service. 5.4 Step 4: Build the ChatGPT-style interface The interface is plain HTML, CSS and vanilla JavaScript. There is no framework and no CDN, so it works on an isolated intranet and adds no supply-chain exposure. Figure 4 shows the layout. The sidebar lists this browser’s recent conversations from localStorage . The main pane shows user and assistant bubbles, a live status line fed by the event stream, and report cards that open in a new tab or preview in a sandboxed iframe with scripts disabled. The composer grows with its content, sends on Enter, inserts a newline on Shift+Enter, shows a character counter and is disabled while that user has a request running. A Stop button aborts the stream, which in turn cancels the server-side run. Example prompts fill an empty chat. Figure 4. Wireframe of the chat interface. (1) Conversation sidebar, (2) message bubbles, (3) live status line from the event stream, (4) report card with Open and Preview, (5) composer with Send and Stop, (6) data-egress notice. All model and server text is inserted as escaped text. Minimal formatting (line breaks, bold, simple tables) is added by the interface itself and never by interpreting model output as HTML. Errors are visible and actionable. Network loss, 401 and 403, 409 (a request is already running), 429 (system busy, with a retry hint) and timeouts each show a message and a Retry button. Figure 5. Typical event sequence for an invoice request. The browser adds each event to the status line as it arrives and renders the final answer and report cards when the closing done event comes in. 5.5 Step 5: Host the service The Python application runs under a Windows service wrapper (for example NSSM or WinSW), bound to 127.0.0.1 on a fixed port, with automatic restart and a dedicated low-privilege account. It reads the provider name, the model override, the data path and the limits from environment variables, and it reads the LLM key from the service environment only. The account gets read access to the project and data, and write access only to the report output and log folders. Capacity is protected by explicit limits (Figure 6). There is a per-user gate (one running request and a rate limit), a bounded queue that reports “queued, position N” through the stream and returns HTTP 429 when full, a semaphore on concurrent agent runs (default 8) and a separate semaphore on concurrent model calls (default 6). Every request has a wall-clock timeout (default 120 s). On timeout, cancellation or browser disconnect, the request’s child processes are terminated and its slots released, so no orphaned processes remain. Blocking work such as file and network I/O runs off the event loop, so one slow call cannot stall other users. Figure 6. Admission control and cleanup. A request has to pass the per-user gate and the queue before it gets an agent slot, and model calls are throttled separately. 5.6 Step 6: Configure IIS IIS is configured as a thin front end. The site’s application pool uses “No Managed Code” because IIS only serves static files and proxies. URL Rewrite forwards /api/* to the loopback service and, in the same rule, sets an X-Forwarded-User header from the authenticated LOGON_USER value, overwriting anything the client sent. The ARR proxy is enabled with a timeout longer than the engine’s request timeout, and response buffering and dynamic compression are turned off so the event stream is delivered live. Request size is capped, risky file extensions ( .py , .csv , .env , .log , .md ) are denied and an HTTPS binding is required. Windows Authentication is enabled and Anonymous is disabled. Those sections are locked at server level by default, so they are set through appcmd at the application-host scope. Appendix C lists the key settings. 5.7 Step 7: Secure the system Section 8 covers the security controls in detail. In short, identity comes only from IIS and the service accepts connections from loopback only. The model key is read from the service environment and scrubbed from every error and log. All text is escaped in the browser. Reports are served with a restrictive policy from one folder. Tools are read-only against the data and write only to report folders. Users are told that aggregated figures are sent to the external model provider. 5.8 Step 8: Test Tests use a mocked model, so no paid calls are made and results are repeatable (Section 10.1). They cover the API contract, path traversal, cross-user isolation, malformed model output and missing keys. They also run a simulated 30-user mixed workload, check cleanup on timeout and disconnect, scan responses and logs to confirm the key never appears, and exercise the tool router with fake clients. 5.9 Step 9: Document and deploy Two idempotent PowerShell scripts install the service and configure IIS. The README documents installation, service commands, key rotation and troubleshooting. Idempotence matters because configuration drift is a frequent cause of failure in reverse-proxy deployments, and a script that can be safely rerun repairs drift instead of adding to it. 6. The Agent Boundary and a Transport-Neutral Tool Layer The agent is treated as a black box that takes a prompt and history and returns an answer, files and a trace. Only one part of its configuration matters to the interface design, and that is how it reaches tools. A deployment may reach a tool server as a local STDIO child process or as a remote HTTPS endpoint, and may move a server from one to the other. Neither choice should change the browser, IIS or the API contract. Three small abstractions achieve this (Figure 7). ToolClient interface. Three asynchronous operations: list_tools() , which returns name, description and input schema, call_tool(name, arguments) , which returns a result object, and close() . An STDIO client, an in-process fallback and a Streamable HTTP client all implement it. Server registry. A list of entries, each with a name, transport, command or URL, the name of the environment variable holding its credential, a timeout and an enabled flag. A deployment can start with a single entry, such as the local invoice server over STDIO, and grow by loading more entries from a configuration file. Tool router. It combines the tools of every enabled client into one live list for the model and sends each call to the client that owns the tool. Once more than one server is registered, it namespaces tool names ( server__tool ) so collisions cannot happen. A slow or unreachable server is skipped with a status event and does not fail the whole request. Application-specific behavior, such as the data summary sent to the model, query identifiers and the rule that report requests must produce an HTML file, lives in an adapter and not in the generic loop. That way, servers that know nothing about invoices can still be used. Figure 7. The transport-neutral tool layer. A remote server is added with a registry entry. One HTTP client implementation serves all remote servers, and no code above the router changes. 6.1 Registry example The following shows the shape of the registry for the four ChefAI servers. Credentials are referenced by environment-variable name, and the secrets themselves never appear in the file. Here docs , logs and dumps correspond to server1.py , server2.py and server3.py . With several servers registered, the model sees namespaced tools such as invoices__generate_invoice or logs__search_logs . Each extra server makes the tool list sent with every model call longer, so a practical deployment should filter or pre-route the list by request intent. Section 11 returns to this. 7. The ChefAI MCP Server Fleet The ChefAI scenario (Section 1.2) uses four servers with deliberately different capabilities (Table 2). Tool names are illustrative, and an implementation may name and group tools differently. Server Transport Capability and example tools Data sensitivity Operational notes Invoice generator server.py STDIO, local Queries purchasing data by period, item and vendor, and generates HTML invoices and reports with totals computed in code. Tools: query expenses ,generate invoice ,generate report , chef summary . Business- confidential totals and vendor names. One child process per request. Read- only on data, writes only to report folders. Document processor (Agentic RAG) server1.py HTTPS, remote Answers questions by retrieving data and documents (supplier contracts, return policies, menus, allergen sheets, equipment manuals, runbooks) from an Agentic RAG system and returning an answer with citations. Tools: search documents , get document, answer with citations . Mixed. Some documents are confidential (contracts, pricing), so it needs document-level access control. Read-only. Always returns source references. Has a retrieval budget and timeout, and shows index freshness. Log analyzer server2.py HTTPS, remote Searches and summarizes application and device logs from point-of-sale, kitchen-display and ordering systems: error counts by time bucket, top messages, correlation by request id. Tools: search logs ,summarize errors ,time histogram . May contain user identifiers, IP addresses or secrets, so it needs redaction. Read-only. Limits result size and redacts on the server side. Dump analyzer server3.py HTTPS, remote Triages crash or memory dumps from restaurant systems:exception summary, faulting module, thread stacks. Tools: list dumps , analyze dump , stack summary. Dumps can contain memory contents,including credentials. The most sensitive server. Long-running, so it needs a larger timeout. Strict access control. Returns summaries only, never raw dumps, to the model. Table 2. The four MCP servers in the ChefAI scenario. 7.1 Agentic RAG in the document processor Retrieval-augmented generation (RAG) grounds a model’s answer in retrieved documents instead of the model’s own memory. An agentic RAG system goes further. It plans the retrieval, may rewrite the query, searches several collections, reads the most promising documents, checks whether the evidence is enough and iterates before answering. In ChefAI this behavior lives inside the document server, behind a small tool surface. The main agent sees one tool, such as answer_with_citations , and does not need to know how the retrieval works. This has three consequences for the design. The document server must return citations so the interface can show sources. Its latency is usually higher than a simple lookup and is bounded by its own timeout and retrieval budget. And retrieved text is untrusted input that can carry injected instructions (threat T2 in Section 8). 7.2 Cross-server tasks The value of a multi-server fleet is that the servers can work together. Take a request such as “The kitchen display froze during Friday dinner service. What happened and what should we do?” It could need the log analyzer for an error histogram around the incident, the dump analyzer for the crash cause and the document processor for the vendor’s runbook and escalation policy. A request such as “Generate the year-to-date invoice and check our dairy return policy” combines the invoice generator with the document processor. The router makes these tools look like one catalogue. Per-server timeouts and failure isolation mean that if the dump server is down, the other tools still answer. Combining servers also raises a data-flow question, because results from one server become inputs to another through the model. Every result passes through the engine, so the engine is the right place to apply size limits, redaction rules and per-server allow-lists. 8. Windows Authentication, Trust Boundaries and Threats 8.1 Identity flow and the absence of a double hop The browser authenticates to IIS using Negotiate (Kerberos or NTLM). IIS knows the user’s account, copies it into X-Forwarded-User and forwards the request over loopback. From that point the application uses only the name, for scoping history, report access, rate limits and logs. The user’s Windows token is never impersonated or forwarded. Resources are reached with service-level credentials: the data file with the service account, the model with an API key, and remote MCP servers with a bearer token or client certificate (Figure 8). No downstream system needs to act as the user, so Kerberos constrained delegation is unnecessary. Figure 8. Identity and credential flow. The user identity is used only for scoping, and every downstream resource is reached with a service-level credential. When delegation would be needed. Delegation, or token forwarding, becomes necessary only if a downstream system must authorize the end user itself. Examples are a per-user permissioned file share, a SQL Server using Windows authentication as the user, or a remote MCP server (such as the document processor) that must apply the caller’s own document entitlements. Those cases would need Kerberos constrained delegation or an OAuthstyle token exchange, and they are outside this design. 8.2 Trust boundaries Figure 9 marks four zones and the threats that cross them. The key rule is that the Python service trusts the identity header only because it listens on loopback and IIS overwrites the header on every proxied request. Figure 9. Trust zones and threat markers T1 to T6 (Table 3). Arrows show the direction of requests. ID Threat Mitigation in this design T1 Spoofed identity header or direct access to the service port IIS overwrites the header on every proxied request. The service binds to 127.0.0.1 and rejects non-loopback callers, and the port is not opened in the firewall. T2 Prompt injection through tool results, retrieved documents or logs (for example text that says “ignore your instructions”) Tool results and retrieved text are treated as untrusted data. Tools are read- only. Tool calls are allow-listed and capped, arguments are validated against schemas, and results are size-limited and redacted before they reach the model. T3 Pointing the agent at arbitrary URLs (server-side request forgery) Remote servers come only from the registry. HTTPS is required, hosts are allow-listed and the model cannot supply URLs. T4 Sensitive data leaving the network through the model provider Only aggregates, provenance and short cited excerpts are sent, never raw rows. Log and dump summaries are redacted. The UI shows a notice and the provider is chosen by policy. T5 Cross-user leakage (history, query results, reports, documents) Per-session stores keyed by user and conversation. Query identifiers are owned by one session, reports are scoped, and the retrieval system applies document-level access control. Tests try cross-access on purpose. T6 Path traversal or exposure of secrets in files served by IIS or the service Report filenames are allow-listed and the resolved path is checked. IIS denies .py , .csv , .env , .log and .md . Keys live only in the service environment and are scrubbed from errors and logs. Table 3. Threat model. The model key is stored in the service’s environment, which administrators can read from the registry. Sites that need stronger protection should use a machine-level secret store read at start-up. 9. IIS Hosting and Deployment Figure 10 shows the physical deployment. Only port 443 is exposed to clients. The Python service listens on loopback and needs no inbound firewall rule. Outbound traffic is limited to the model provider and the approved remote MCP hosts. Figure 10. Deployment topology and firewall posture. 9.1 Provisioning sequence Install IIS with static content, request filtering and Windows Authentication. Install URL Rewrite and ARR. Enable the ARR proxy, set its timeout above the engine timeout, set the response buffer limit to zero and allow the HTTP_X_FORWARDED_USER server variable. Create the application pool (No Managed Code) and the site pointing at the UI folder, then add the HTTPS binding with an internal CA or test certificate. Disable Anonymous and enable Windows Authentication at the application-host scope. Add the rewrite rule, request limits, security headers and file-type deny list to the site configuration. Create the service account, grant the narrowest file permissions, install the service wrapper, set the environment variables and start the service. Verify the result: the service is running, the health endpoint answers on loopback, sign-in from a client is silent, a streamed answer arrives, a report card appears, access to data and source files is blocked, and two simultaneous users get independent results. 9.2 Common failure modes Symptom Typical cause 502.3 on /api Service stopped, wrong port, or ARR proxy not enabled. 500.50 from URL Rewrite The identity server variable is not in the allowed list. Repeated sign-in prompts Authentication sections not set at application-host scope, browser zone settings, or a missing service principal name for the site name. Progress arrives only at the end Response buffering or dynamic compression on the proxied route. Timeouts near two minutes Proxy timeout shorter than the engine timeout. Leftover Python processes Cleanup path not triggered on timeout or disconnect. 10. Evaluation Methodology and Capacity Reasoning 10.1 Evaluation plan An implementation of this architecture should be evaluated against the criteria in Table 4 before it is released to users. A mocked model keeps functional tests repeatable and free of provider cost. Latency and quality are then measured with the real provider. Question Method Metric or pass criterion Correctness of the API Mocked model, test client and deterministic scenarios. All contract and error-path tests pass, and totals equal direct data queries. Isolation 30 simulated users with mixed queries and reports, plus deliberate cross-access attempts. Zero cross-user data, zero unhandled exceptions and zero orphaned processes. Concurrency limits Ramp from 1 to 30 users, saturate agent slots and fill the queue. Running agents never exceed the configured cap, overflow returns 429, and the system recovers after the burst. Real-time responsiveness Mocked model with a fixed delay, then the real provider, with a browser trace through IIS. Median and 95th-percentile end-to-end time, time to first event, first event before the first tool completes, and no buffering. Cleanup Timeout and abrupt disconnect tests. Child processes terminated, slots released and no handle growth after repeated runs. Secret hygiene Automated scan of responses, logs and error text. The key never appears. Router Two to four fake clients, one slow and one failing. Correct routing and namespacing, and the request still succeeds when one client fails. Retrieval quality (document server) A question set with known source documents. Share of answers with correct citations, and refusal when evidence is missing. Table 4. Recommended evaluation plan. 10.2 A capacity argument Little’s law relates the average number of requests in service N to the arrival rate λ and the average time in the system W: N = λ × W [7]. Suppose, as an assumption, that each of 30 users submits one request per minute on average (λ = 0.5 requests per second). If the mean service time is 15 s, then on average N = 7.5 requests are in service at once. That fits the default of eight agent slots with little queueing. If the mean time is 30 s, then N = 15, the slots saturate and queueing delay grows, so either the cap or the speed of each run has to change. The model call is the biggest part of a run, and an Agentic RAG lookup adds its own multi-step latency. Provider latency and the number of tool calls per request therefore set the capacity you need. These figures illustrate the method, and each deployment should substitute its own measured arrival rate and service time. Memory per STDIO child process also grows with N, so it must be measured before choosing between one child per request and a pool. 11. Limitations and Future Work Reference architecture. ChefAI is a fictitious scenario and the figures in this paper are design values, not benchmark results. Capacity, latency and memory must be measured for each real deployment. Single-process assumption. Per-user limits, history and the shared data cache live in memory. Scaling to several worker processes needs a shared store, such as a database or cache, or sticky routing. Tool-list growth. More servers mean larger prompts and more mistakes in tool selection. Pre- routing by intent, per-user tool entitlements and lazy tool loading are natural extensions. Per-user authorization downstream. The design uses service credentials. If remote servers, notably the document processor, must enforce each user’s own rights, token exchange or delegation will be required. Model-provider dependence. Answers depend on an external provider’s availability, cost and data policy. An on-premises model would change the data-egress analysis. Human factors. The paper does not prescribe a usability study. Candidate measures include task completion, perceived trust in numbers and citations, and how clear the status line is. Secret storage. A service environment variable is fine for a pilot. A managed secret store is better for production. 12. Conclusion Putting an MCP agent behind a familiar chat interface is mostly an engineering problem at the edges. The questions are how the request enters, who the user is, how long-running work is streamed, how concurrent users are kept apart and how new tool servers are added without disturbing the rest. The architecture in this paper keeps IIS thin, with static content, TLS, Windows Authentication and a reverse proxy. It puts the agent behind a loopback Python service with explicit admission control, and it separates the interface from the way tools are reached by using a small transport-neutral tool layer. User identity is used only for scoping and every downstream resource is reached with a service credential, so no Kerberos delegation is needed. For the fictitious ChefAI restaurant, this gives staff real-time answers, invoices, document-grounded guidance and log and dump diagnostics from one chat window. The recommended path is to build the nine steps in order, validate the result with the evaluation plan, and add remote MCP servers one at a time through registry entries. References Model Context Protocol. “Model Context Protocol specification.” modelcontextprotocol.io (accessed October 2026). WHATWG. “HTML Living Standard: Server-sent events.” html.spec.whatwg.org (accessed October 2026). Jaganathan, K., Zhu, L., and Brezak, J. “SPNEGO-based Kerberos and NTLM HTTP Authentication in Microsoft Windows,” RFC 4559, IETF, June 2006. Microsoft. “URL Rewrite” and “Application Request Routing” documentation for IIS, learn.microsoft.com and iis.net (accessed October 2026). Fielding, R., Nottingham, M., and Reschke, J. “HTTP Semantics,” RFC 9110, IETF, 2022. OWASP Foundation. “OWASP Top 10 for Large Language Model Applications.” owasp.org (accessed October 2026). Little, J. D. C. “A Proof for the Queuing Formula: L = λW.” Operations Research 9(3), 1961. Appendix A. Event stream schema Each SSE message has an event name and a JSON data field. The schema is the only contract between the browser and the engine. Appendix B. Environment variables Variable Purpose LLM_PROVIDER, LLM_MODEL Model provider and optional model override. LLM_API_KEY Provider key. Service environment only, never logged or returned. CHEFAI_CSV_PATH Location of the purchasing data file used by the invoice server. CHEFAI_REQUIRE_USER 1 rejects requests without the identity header (production). 0 uses a single anonymous user (development). CHEFAI_MAX_AGENTS Concurrent agent runs (default 8). CHEFAI_REQUEST_TIMEOUT Per-request wall-clock limit in seconds (default 120). MCP_*_TOKEN Per-server credentials for remote MCP servers, referenced by name in the registry. Appendix C. Key IIS settings These settings are indicative. Module versions and server policies vary, so validate them in a non-production environment before rolling out.390Views3likes0CommentsThe Context Advantage
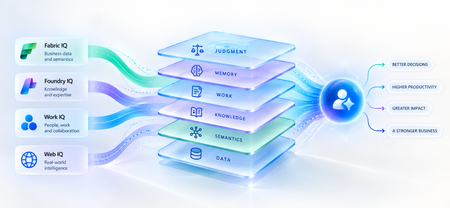
A strange thing happens when enterprises upgrade their AI models. The model gets smarter. The benchmarks improve. The demos become more impressive. And sometimes, the business outcome barely moves. The agent still asks questions the organization answered months ago. It recommends something policy doesn't allow. It treats a strategic customer like any other customer. It proposes an architecture your engineering team rejected six months ago. The problem isn't necessarily intelligence. It is ignorance of the business. That distinction matters because the world's most capable models are becoming available to almost everyone. Your competitors can increasingly access the same frontier intelligence you can. What they cannot access is your customer history, operating knowledge, organizational memory or understanding of how decisions actually get made. Models are becoming shared. Context remains proprietary. And that may be where the next enterprise AI advantage is built. Intelligence Without Context is Surprisingly Ordinary Consider a simple enterprise question: Can we offer this customer a larger discount? A powerful model can reason about discounts. But answering that question properly may require the customer's lifetime value, current contract, payment history, margins and approval thresholds and perhaps a conversation yesterday in which the account executive learned that a competitor had entered the deal. The model isn't missing intelligence. It is missing context. Humans rarely make important decisions from one piece of information. We combine data, experience, relationships, history and situational awareness almost unconsciously. Agents need a version of the same capability. That is why enterprise AI is moving from an era dominated by prompt engineering toward one increasingly shaped by context engineering. Satya Nadella recently described the emerging market simply as “a world of context engineering.” Prompt engineering asks: What should I tell the model? Context engineering asks the larger question: What does the model need to understand before it can act well? That difference becomes critical as AI moves from answering questions to performing work. The Enterprise Context Stack In discussions about enterprise agents, “context” can easily become shorthand for giving a model access to more data. That definition is too narrow. I think about enterprise context as a stack: DATA → SEMANTICS → KNOWLEDGE → WORK → MEMORY → JUDGMENT Data tells the agent what happened: orders, transactions, inventory, claims and customer records. Semantics tells it what that data means to the business: what constitutes a strategic customer, how margin is calculated, which assets belong to which production line. Knowledge tells it what the organization knows: policies, contracts, procedures, research and accumulated expertise. Work tells it what is happening now: who is involved, what has been discussed and which commitments already exist. Memory tells it what happened before: previous interactions, decisions, exceptions and outcomes. And judgment helps determine what should happen next. Memory deserves particular attention because it is context agents can accumulate through experience. Microsoft Foundry now distinguishes between session, user and procedural memory - moving agents beyond remembering a conversation toward remembering preferences and learning how work gets done across repeated interactions. Sometimes the cheapest way to make an agent meaningfully better may not be a bigger model. It may be a better memory. Not every agent needs every layer. But the more consequential its responsibility, the richer, and more carefully governed, its context usually needs to become. This is where context stops being a retrieval problem and starts becoming an enterprise architecture problem. Context Is Becoming Infrastructure This shift is now visible well beyond any one technology platform. Gartner increasingly describes a context layer as an architectural foundation for agentic AI - bringing together semantics, operational state, provenance and other enterprise signals so agents can act reliably. Anthropic, approaching the problem from AI engineering, argues that context should be treated as a finite resource that must be carefully curated rather than simply expanded. Microsoft's recent direction is particularly interesting through this lens. Work IQ, Fabric IQ, Foundry IQ and Web IQ increasingly form a shared intelligence layer across Microsoft's stack. Work IQ provides context about how work happens. Fabric IQ brings business semantics and relationships. Foundry IQ provides reusable enterprise knowledge and agentic retrieval. Web IQ extends that understanding with fresh external intelligence. The architectural implication matters more than the product names. Instead of every new agent rebuilding connectors, retrieval logic, semantic definitions and permissions, context becomes reusable infrastructure from which many agents can reason. Microsoft captured the shift particularly well: As agents become the new application model, context becomes critical infrastructure. Your Data Estate Is Not Automatically Your AI Moat For years, organizations have been told their data is a competitive advantage. Sometimes it is. But possessing data and making that data useful to an agent are very different things. Most enterprises don't suffer from a shortage of information. They suffer from an abundance of it -scattered across databases, documents, emails, meetings, applications and people's heads. The advantage doesn't come from connecting an agent to all of it. It comes from turning information into usable context: preserving business meaning, understanding relationships, distinguishing authoritative knowledge from convenient information, respecting permissions and retrieving what matters when a decision is being made. The enterprise with the most data may not build the best AI. The enterprise that makes its context most usable might. The Context Budget There is a trap on the other side too. If context improves AI, the natural instinct is to give the agent as much as possible. That is the wrong objective. Context consumes attention and compute. Irrelevant information creates noise. Stale information can mislead. Conflicting context can degrade reasoning rather than improve it. The objective should therefore not be maximum context. It should be minimum sufficient context the smallest trusted, relevant and permission-aware set of information required to produce the right outcome. In Beyond Tokens, I introduced the idea of an Intelligence Budget: How much intelligence does this outcome deserve? Enterprise agents increasingly need a companion concept. The Context Budget. How much context does this decision deserve? A scheduling agent may need calendars and preferences. A pricing agent may need customer economics, margins, commitments and approval policies. A clinical agent requires an entirely different level of completeness, provenance and governance. Every unnecessary token of context is cost. Every missing piece of necessary context is risk. Which gives us a useful way to think about enterprise agents: Right Intelligence × Right Context → Right Outcome Spend more intelligence where the outcome warrants it. Provide more context where the decision requires it. Do neither indiscriminately. What An Agent May Know Matters Too! There is another dimension to the Context Budget: permissions. Enterprise context belongs to someone. A system that retrieves the right answer but ignores whether the agent is entitled to see it isn't intelligent. It is a security problem. Enterprise context must therefore remain identity-aware and permission-aware as it moves from source systems into agent reasoning. This becomes especially important as agents gain persistent identities and greater autonomy. What an agent may know is as much a part of its job description as what it may do. Autonomy defines the boundary of action. Context defines the boundary of understanding. From RAG Projects To Context Architecture The first generation of enterprise GenAI often started with RAG: connect documents to a model and retrieve relevant passages. That was an important step. But an agentic enterprise cannot become a collection of hundreds of independent RAG pipelines, each separately rediscovering the organization's customers, products, policies, terminology and permissions. That risks creating another generation of technology fragmentation. The opportunity is to move from agent-specific retrieval toward reusable enterprise context. What knowledge should agents inherit? Which business entities should have common definitions? Which sources are authoritative? Which memories should persist—and which should be forgotten? And perhaps the hardest question: Who owns enterprise context? Today, responsibility is scattered across data teams, application teams, knowledge management, security, business functions and increasingly AI teams. In an agentic enterprise, context may need to be managed as a product, not everyone's side project. The Moat Is Not The Model Imagine two competing organizations using exactly the same frontier model. One connects it to fragmented documents and a handful of applications. The other has strong data foundations, shared business semantics, governed knowledge, connected workflows and organizational memory. They have access to the same AI. They do not have the same intelligence system. The second organization's agents understand customers more deeply, interpret signals more accurately and act with greater awareness of how the organization actually works. And that advantage compounds. Every workflow creates more context. Every interaction adds organizational memory. Every decision creates another signal from which future agents can reason. Models depreciate the moment a better one ships. Context appreciates every day you operate. That may be the most important strategic shift of all. Anyone can rent intelligence. No one can rent your context. Intelligence Is Becoming Abundant. Understanding Isn't. The first wave of enterprise AI taught us how powerful models could be. The next may teach us that models were only one part of the equation. An agent needs intelligence to reason. But it needs context to understand your business. As frontier intelligence becomes more accessible, enterprises may discover that their most defensible AI asset was never the model. It was everything the organization had learned before the model arrived: its data, semantics, knowledge, relationships, history, workflows and judgment. The organizations that turn those assets into trusted, reusable context will give every agent they build an advantage from day one. So perhaps the strategic question is no longer simply: Which model should we use? It is: What does our organization know that our competitors don't and can our AI actually use it? Because in a world where everyone can access intelligence, context may be what makes that intelligence uniquely yours. References Microsoft — FY2026 Q2 Earnings Conference Call Microsoft — FY2026 Q4 Earnings Conference Call Microsoft Learn — What is Foundry IQ? Microsoft Foundry — Foundry IQ: Build Smarter Agents Faster with Unified Knowledge and Serverless Retrieval Microsoft Foundry — What's New in Microsoft Foundry | Build 2026 Gartner — Context Engineering Is the New Prompt Engineering Gartner — Market Overview for AI Context Platforms Gartner — The 3 Core Components of the Context Layer for AI Agents297Views0likes2CommentsTransforming Enterprise Documents into AI Knowledge with Agentic RAG
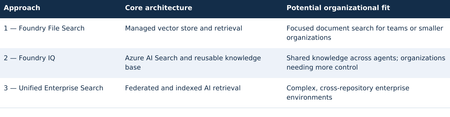
TECHNICAL RESEARCH PAPER Research Disclaimer: This article is a technical research paper intended solely for educational, research, and illustrative purposes. It reflects the author’s personal technical perspectives. All concepts, architectural designs, diagrams, and implementation approaches are provided “AS IS” for technical exploration and review, not as production-ready development guidance. Organizations considering implementing these approaches should consult their internal software development standards, enterprise architecture teams, corporate security policies, and governance requirements. Any production implementation must undergo appropriate end-to-end architectural, security, privacy, compliance, and responsible AI or ethics reviews, along with necessary testing and organizational approvals before deployment. Abstract. This research paper explores three independent approaches to transforming enterprise documents and knowledge repositories into AI-powered search experiences using Agentic Retrieval-Augmented Generation (RAG), Microsoft Foundry, and ASP.NET Core. Organizations can evaluate and adopt any one approach independently according to their business requirements, organizational size, document volume, technical complexity, available resources, and security considerations. Approach 1 — Microsoft Foundry File Search: A streamlined option with managed ingestion, vector storage, retrieval, and an optional ASP.NET Core/Blazor conversational web interface. It may be a sufficient standalone solution for focused document-search needs. Approach 2 — Microsoft Foundry IQ: A knowledge-centric option built around Azure AI Search and reusable knowledge bases, suitable for applications that need more configurable retrieval or shared knowledge across authorized agents. It does not require Approach 1 to be implemented first. Approach 3 — Unified Enterprise Agentic Search: A broader design combining federated and indexed retrieval across approved enterprise repositories, for organizations with extensive integration, authorization, governance, and cross-source search requirements. These are alternatives, not mandatory sequential stages. Approaches 1 and 2 may each be complete solutions. Organizations considering Approach 3 may optionally pilot Approach 1 or 2 to assess retrieval quality, citations, user experience, and operational readiness, but neither pilot is a prerequisite. The examples are research illustrations, not production-ready implementation instructions. 1. Three independent architectural approaches Select an approach based on organizational needs rather than following a required progression: Optional evaluation path: An enterprise exploring Approach 3 can run a focused File Search or Foundry IQ POC first. A small organization may stop at Approach 1 or 2 if its requirements are met. 2. Three independent implementations 3. How documents become AI-searchable For indexed sources, the broad workflow is similar across managed File Search and Foundry IQ-backed Azure AI Search, although ingestion details, formats, and service capabilities differ. Federated retrieval may query existing repositories without creating new embeddings. Indexed document processing and agent retrieval workflow The original document is not replaced by vectors alone: searchable text and source references are retained. Scanned PDFs and images may need OCR or multimodal processing. 3.1 Example: what happens to one PDF? Source: IIS-AppPool-Troubleshooting.pdf. Example passage: “If an IIS application pool repeatedly terminates, examine WAS events and investigate rapid-fail protection.” Illustrative document chunk, vector, and metadata A query such as “Why does my IIS application pool keep crashing?” may retrieve the relevant passage through semantic similarity. The agent uses the readable retrieved content to explain the issue and cite its source. Architecture note: This paper targets the new Microsoft Foundry Agent Service (Responses API-based), not classic Foundry agents or legacy Assistants API implementations. 4. Approach 1 — Microsoft Foundry File Search 4.1 Objective Explore a potentially standalone AI-powered search solution over 20 approved technical documents with limited ingestion configuration. Evaluate one Foundry File Search-enabled agent through the built-in Playground and/or a custom conversational web application. 4.2 Architecture flow Approach 1 — Microsoft Foundry File Search architecture 4.3 What is a managed vector store? A managed vector store exposes searchable passages, embeddings, and metadata while abstracting ingestion and retrieval. In standard Foundry Agent Service setup, files can remain in customer-managed Azure Storage and Azure AI Search can back the vector store; basic setup uses Microsoft-managed resources. Where supported, multiple agents in the same project can reference the same vector store ID through File Search tool configuration, subject to API and permission boundaries. 4.4 User experience options Option 1: Use the Foundry Agent Playground to ask questions, inspect citations, and evaluate multi-document synthesis. Option 2: Build an ASP.NET Core/Blazor portal using supported APIs/SDKs with multi-turn chat, streaming where supported, clickable citations, error handling, and Microsoft Entra ID sign-in. Keep privileged credentials on the server. 4.5 Illustrative implementation and deliverables • Prepare 20 approved documents and a fixed question set. • Configure a compatible Foundry project, model, agent, and File Search tool. • Upload files; verify managed processing and retrieval quality. • Test in the Playground; optionally implement and test the Blazor portal. • Evaluate answer grounding, citations, latency, ingestion behavior, and costs. Possible standalone deliverable: File Search agent, managed vector store, working selected interface(s), and an evaluation report. The custom portal is optional; Approach 2 is not required. 5. Approach 2 — Microsoft Foundry IQ 5.1 Objective Evaluate a reusable knowledge-base architecture with Azure AI Search-backed retrieval. This is an independent option: it can be built directly without first implementing Foundry File Search. For a comparative research exercise, the same 20 documents and questions may be reused. 5.2 Architecture flow Approach 2 — Microsoft Foundry IQ architecture 5.3 What is an Azure AI Search index? An Azure AI Search index is a structured, searchable collection of content extracted from enterprise data sources, including documents, websites, and other supported repositories. It stores searchable text, vector embeddings, metadata, and source references, enabling keyword, vector, hybrid, and semantic search to retrieve relevant information efficiently. During ingestion, documents can be processed, divided into smaller chunks, and converted into vector embeddings that represent their semantic meaning. When a user submits a natural-language question, Azure AI Search can combine keyword matching with vector similarity and semantic ranking to identify relevant passages, which an AI agent can use to generate grounded responses with citations to the original sources. 5.4 What Foundry IQ adds? Microsoft Foundry IQ builds on Azure AI Search by providing reusable knowledge bases and agentic retrieval capabilities across supported enterprise data sources. Multiple authorized AI agents can access the same knowledge base without duplicating document ingestion, while agentic retrieval can intelligently plan and execute searches to identify relevant information. Supported remote SharePoint knowledge sources can also be queried through the Copilot Retrieval API without creating a separate local vector index. This capability may require eligible Microsoft 365 Copilot licensing for end users, with access governed by source-specific permissions. For indexed content, document-level security trimming depends on supported knowledge-source capabilities and properly configured access control lists (ACLs) or security filters. 5.5 User experience and optional comparison A Foundry IQ solution may use the Agent Playground and/or its own ASP.NET Core/Blazor application. If an organization is comparing Approaches 1 and 2, it can optionally reuse a common web UI and provide an agent selector. Reusing Approach 1 is not a dependency. 5.6 Illustrative implementation and deliverables • Provision compatible Azure AI Search and Foundry resources. • Create the knowledge base and supported knowledge source; validate ingestion. • Connect a Foundry agent; evaluate retrieval and citations in the Playground. • Optionally build or reuse a Blazor interface for the same agent. • Measure relevance, knowledge reuse, latency, costs, and operational complexity. Direct-file ingestion may depend on preview, region, or API availability; Azure Blob ingestion may be needed. Possible standalone deliverable: reusable knowledge base, index, connected agent, selected interface(s), and evaluation report. 6. Foundry File Search versus Foundry IQ Section 6 — Foundry File Search versus Foundry IQ Key takeaway: Both File Search and Foundry IQ can support keyword, vector, and semantic relevance, with hybrid retrieval where supported. File Search emphasizes managed processing and search behavior; Foundry IQ provides reusable knowledge bases and more configurable Azure AI Search-backed sources. The distinction is control, source integration, and operations—not whether embeddings or semantic relevance exist. Both may be standalone solutions. 7. Approach 3 — Unified Enterprise Agentic Search 7.1 Objective Explore a comprehensive architecture for organizations requiring search across multiple repositories, with both federated and indexed retrieval, grounded answers, citations, and permission-aware access. This approach can be evaluated directly; smaller POCs are optional validation exercises, not prerequisites. 7.2 Unified enterprise architecture flow Section 7 — Unified Enterprise Agentic Search architecture 7.3 Option A — Federated enterprise search Query approved repositories through source APIs/connectors while retaining documents in place. Delegated access and source-native ACLs must be enforced for each connector. Remote SharePoint retrieval through Copilot Retrieval can require Microsoft 365 Copilot licenses for end users; source-specific permission behavior must be validated. Other repositories may require custom connectors or indexing. 7.4 Option B — Indexed enterprise AI search Index approved extracted text, vectors, metadata, and source references in Azure AI Search. Foundry IQ can provide reusable knowledge retrieval. OCR and complex layout extraction are not guaranteed by default File Search or every Foundry IQ knowledge source: test each format and add Azure AI Search OCR/Document Intelligence layout skills or other processing where needed. Derived indexed content requires explicit authorization and security trimming. 7.5 Combined example For “Find documentation explaining HTTP 503 errors in IIS and compare it with internal troubleshooting procedures,” the agent could retrieve current SharePoint guidance through Option A and indexed engineering articles through Option B, synthesize findings, and cite original sources. 8. A Unified UI for All Three Approaches: ASP.NET Core / Blazor Conversational Portal Section 8 — Unified ASP.NET Core/Blazor conversational portal for all three approaches The shared Blazor UI and ASP.NET Core backend can route requests to any of the three independent approaches. Approach 3 additionally coordinates federated and indexed retrieval; all paths return grounded answers and source citations. The retrieval router shown in the diagram is custom ASP.NET Core application/BFF logic, not a standalone Microsoft product. It selects the configured File Search, Foundry IQ, or federated/indexed enterprise path and normalizes citations. The architecture targets the new Microsoft Foundry Agent Service (Responses API-based). 9. Security and governance Section 9 — Security and governance Use approved noncustomer documents for initial research. Validate source permissions and prevent restricted content disclosure. Azure AI Search does not automatically preserve original repository ACLs when content is copied into an index. Indexed security trimming requires appropriate ACL fields and identity-aware filters or supported permission integration; not every knowledge source provides user-level trimming out of the box. Customer data requires organizational approvals. 10. Independent POC evaluation and success criteria Evaluate only the approach or approaches an organization is considering. A side-by-side comparison is optional, not a required sequence. If comparing File Search and Foundry IQ, use identical documents, questions, models, and prompts where possible. Section 10 — Independent POC evaluation and success criteria Illustrative acceptance target: at least 90% correct retrieval on a curated test set, valid citations for grounded responses, and reliable operation through the selected interface(s). These are proposed research criteria, not platform guarantees. Approach 3 additionally requires source-permission, cross-repository, and governance validation. 11. Independent estimates and potential deliverables Section 11 — Independent estimates and potential deliverables These are independent, illustrative POC estimates, not a cumulative rollout schedule. The Approach 2 estimate assumes compatible resources and an existing interface or Playground-only evaluation; building a new custom application can add effort. Approach 3 needs a separately scoped plan for connectors, access control, compliance reviews, testing, deployment, and operational readiness. 12. Research findings and needs-based architectural direction Approach 1: Consider Foundry File Search where a manageable document collection and simpler managed retrieval meet the organization’s requirements. Approach 2: Consider Foundry IQ where reusable knowledge, multiple agents, or greater search configurability are important. Approach 3: Consider unified enterprise retrieval where many systems, security boundaries, and content types must be integrated. No approach is universally preferred, and organization size alone is not a definitive selection criterion. A smaller organization may need advanced governance, while a large enterprise team may only need a focused File Search solution. Optional POCs using Approach 1 or 2 can inform an Approach 3 decision without becoming mandatory prerequisites. Envisioned outcome: A needs-appropriate, citation-grounded enterprise knowledge search experience built with Microsoft technologies, subject to technical validation, organizational security and privacy review, and responsible AI governance. The architectures remain independent research options rather than an endorsed implementation sequence. 13. Implementation notes and service lifecycle Current agent runtime: Target the current Microsoft Foundry Agent Service, not classic agents. Classic agents are deprecated and scheduled for retirement on March 31, 2027. Agentic retrieval: Foundry IQ query planning uses a supported model at low/medium reasoning effort. Minimal effort skips LLM query planning; model and API support must be checked. Availability and previews: Verify regional support, RBAC, API version, and GA-versus-preview status for File Search, Foundry IQ knowledge sources, and portal features before implementation. POC schedule: The illustrative estimates assume ready resources and a working Playground or reusable UI; region, permissions, and unsupported document formats can extend delivery. Technical validation: Microsoft Learn — Foundry File Search; Foundry IQ FAQ; Agentic Retrieval; Foundry Agent Service (classic) migration; Azure AI Search OCR and Document Layout skills.349Views0likes0CommentsWhen Intent Becomes the Interface: Why Applications Are No Longer the Starting Point
For decades, enterprise software has asked people to learn how applications work. Which screen to open. Which fields to complete. Which workflow to trigger. Which report to generate. And which application to visit next. Here is a situation I keep meeting. A sales executive is preparing a renewal proposal. Customer relationships live in CRM. Contract terms sit in SharePoint. Support issues are tracked elsewhere. Revenue data comes from finance. Relevant conversations are scattered across Outlook and Teams. The executive knows what needs to be accomplished. The software requires them to figure out how. But something interesting is happening. We are beginning to separate the intent to accomplish work from the applications traditionally required to perform it. Microsoft's developments across Copilot, Cowork, Code, Copilot Studio and Microsoft IQ suggest that this could become a defining shift in enterprise software. The question is no longer simply how to make applications more intelligent. What if enterprise software started with the work, rather than the application? Enterprise Software Was Built Around Navigation Traditional enterprise applications organize business capabilities into reliable systems. ERP manages transactions. CRM manages customer relationships. HR platforms manage employee processes. These systems aren't going away. Their data models, transaction controls and business rules remain essential. But their user experiences were designed for a world where software needed explicit instructions at almost every step. People became the integration layer. We retrieved information from one system, interpreted it, entered it into another, initiated approvals and followed up when something stalled. APIs and automation improved individual steps. Generative AI introduced conversational interfaces. But the underlying model often remained unchanged. People still needed to know which application to use and how to move the result into the next step. Now the architecture itself is beginning to change. Microsoft Is Bringing Three Capabilities Together One of Microsoft's more consequential recent developments is the convergence of applications, workflows and agents in Copilot Studio. These are fundamentally different capabilities. Applications provide structured experiences for people to view information, make decisions and act. Workflows provide predictable execution for repeatable processes, business rules and integrations. Agents bring reasoning and adaptation when the next step cannot always be predetermined. Not every business process needs an agent. Not every decision should be probabilistic. And not every interaction belongs in a chat window. A purchase approval may require deterministic policy enforcement. Evaluating an unusual supplier proposal may benefit from AI reasoning. A material exception may require human judgment through a purpose-built application. Microsoft Copilot Studio is bringing these capabilities into a more unified development experience, supported by agent orchestration, workflow execution, reusable skills and connected tools. And the audience for this convergence is already enormous: Microsoft noted on a recent earnings call that more than 80% of the Fortune 500 already have active agents built with its low-code tools. This suggests a useful architectural principle: Use reasoning where the path is uncertain. Use workflows where the rules are known. Use applications where human interaction adds value. I have started calling this the Composition Rule. The breakthrough isn't replacing one with another. It is combining them deliberately. From Application-Led to Intent-Led Work Return to our sales executive preparing a renewal proposal. Instead of visiting multiple systems, the executive could begin with a request: Prepare the renewal proposal. Incorporate the latest commercial terms, outstanding support issues and account commitments. Flag anything requiring approval. The system must interpret the request, retrieve authoritative information, apply business rules, assemble the deliverable and recognize where human judgment is necessary. Different Microsoft capabilities can contribute to that experience. Microsoft 365 Copilot Cowork enables delegation of complex, multi-step work across connected productivity experiences. Work IQ provides context from Microsoft 365 collaboration. Fabric IQ contributes business semantics and relationships across enterprise data. Foundry IQ supports reusable enterprise knowledge and retrieval. Together, they form the context layer I explored in The Context Advantage and intent-led work is where that investment begins to pay out. Dynamics 365 and Power Platform connect intelligence to operational records, business processes and actions. Copilot Studio enables agents to use tools and workflows, while applications can provide structured experiences for human review. These are complementary building blocks, not necessarily one automatically integrated execution path. Bringing them together requires deliberate solution architecture, connectors, permissions and orchestration. The executive receives a proposal, supporting evidence and decisions requiring attention. The underlying systems remain important. But navigating them is no longer necessarily the executive's responsibility. In traditional enterprise architecture, applications organize capabilities and users navigate between them. In an intent-led architecture, the desired outcome becomes the organizing principle. Applications, workflows, agents and enterprise services are composed around that intent. The application remains important. But it is no longer necessarily the primary unit of the user experience. When Software Can Be Assembled Another development deserves attention. Microsoft's Copilot Code and Copilot Studio capabilities are making it easier to create software experiences from natural-language requirements. Copilot Managed Runtime provides Microsoft-hosted infrastructure for running and governing supported applications. These capabilities are at different stages of availability, but their direction is significant. Traditionally, an enterprise application begins with a development project: requirements, design, engineering, testing, deployment and maintenance. That remains essential for complex, mission-critical systems. But not every business need justifies a conventional development cycle. A procurement manager may need a focused interface for comparing supplier proposals. A finance team may need a temporary application for reviewing reconciliation exceptions. Increasingly, some experiences can be generated, connected to governed data and shared with colleagues. The distance between recognizing a business need and creating a useful software experience may shrink dramatically. But faster creation also raises important questions. Who owns the generated application? How is it tested? Which identities and permissions does it use? How is it maintained or retired? Microsoft Copilot Managed Runtime, currently in preview, addresses part of this challenge through managed hosting, Microsoft Entra authentication and application governance capabilities. The ability to generate software is becoming easier. The ability to operate that software responsibly remains an engineering discipline. Software creation may become democratized. Software accountability cannot become optional. Reasoning Is Not Execution There is one distinction I find myself drawing on whiteboards more often than any other as AI moves deeper into enterprise processes. Large language models are useful when tasks require interpretation, synthesis and adaptation. But enterprises also depend on predictability. An invoice approval threshold shouldn't change because a model reasons differently. A financial transaction must preserve the integrity of the system recording it. Consider an insurance claim. An agent interprets submitted documentation and identifies missing information. A workflow applies established eligibility rules and routes the claim. A human reviewer examines complex exceptions through an application presenting the relevant evidence. The model contributes interpretation. The workflow contributes repeatability. The application supports human judgment. And the system of record preserves the authoritative transaction. This requires business capabilities to be accessible beyond application screens. APIs, Model Context Protocol (MCP) tools, Power Platform connectors and reusable services become building blocks through which intelligent workflows can operate across systems. Microsoft Copilot Studio supports this direction through workflow triggers, agent handoffs, connected tools and evaluation capabilities. Microsoft Foundry provides complementary capabilities for agent development, evaluation, tracing and operational monitoring. The quality of the experience increasingly depends on how well these capabilities can be composed - not simply on how intelligent the underlying model is. For enterprise architects, this introduces a more useful question than where to deploy another agent: Which parts of this process should be intelligent, which must be deterministic and which require human judgment? That is the Composition Rule at work. A New Architecture, Not Another Generation of Sprawl The counterargument comes up in almost every architecture conversation I am part of. If every employee can generate applications and every department can assemble workflows, enterprises could recreate decades of software fragmentation at unprecedented speed. A hundred individually useful applications don't necessarily create a coherent enterprise architecture. The answer isn't to prevent experimentation. It is to establish reusable foundations. Common identity through Microsoft Entra. Trusted business semantics through Fabric IQ. Approved connectors and MCP tools. Shared engineering standards. Managed execution environments. Clear ownership and lifecycle controls. Microsoft Agent 365 adds an enterprise control plane for discovering, securing and governing agents across supported environments. These capabilities address different parts of the challenge. They do not eliminate the need for enterprise architecture. The more accessible software creation becomes, the more important shared foundations become. Otherwise, we risk making software easier to build while making the enterprise harder to operate. When the Business Need Comes First I don't expect enterprise applications to disappear. Organizations will continue to need ERP, CRM, finance, HR and industry-specific platforms. Systems of record remain indispensable. But the relationship between people and applications is beginning to evolve. Today, enterprise users learn which application performs which function. Tomorrow, more experiences may begin with a desired result, with intelligence coordinating underlying capabilities and presenting the appropriate interface when needed. Sometimes that interface will be a conversation. Sometimes a generated application. Sometimes a familiar enterprise screen. And sometimes a workflow will complete a defined step without another interaction. Microsoft's convergence of Copilot, Copilot Studio, Microsoft IQ, Power Platform and managed execution infrastructure makes this architectural possibility increasingly tangible. We may be moving from a world where people navigate software to accomplish work toward one where software is assembled around the work people need to accomplish. That won't happen overnight. It requires strong architecture, trusted data, explicit execution boundaries and deliberate engineering choices. But it raises a question worth asking before the next enterprise software investment: Are we designing another application people must learn to operate or a capability that understands the work they are trying to accomplish? References Microsoft Copilot Studio Blog: “Build apps, workflows, and agents together” The Official Microsoft Blog: “Introducing the new Copilot with Home, Code and Autopilot” (September 25, 2026) Microsoft Copilot Studio Blog: “Microsoft Copilot Managed Runtime: Enterprise code execution for Microsoft 365” Microsoft 365 Blog: “Powering Frontier Transformation with Copilot and agents” (Copilot Cowork) Microsoft IQ Microsoft Agent 365 Microsoft FY26 Q2 earnings conference call — more than 80% of the Fortune 500 with active agents built using Microsoft's low-code tools Ashok Karania Articles on Microsoft Tech Community — “The Context Advantage”; “When AI Stops Waiting for Instructions”; “Beyond Tokens: Rethinking AI Economics with Microsoft Foundry” Image Credit: OpenAI203Views1like0CommentsLand Your Offer - Anatomy of Revenue Generating Partner Offer - Part 2 - Copilot Envisioning
In Part 1 we dissected Copilot in 30 — a $0 trial offer for SMB customers. This time the customer is larger, the engagement is funded rather than free, and the anatomy of revenue changes with it. It also lands when Microsoft just introduced the new Copilot — Home, Code and Autopilot, running on usage-based billing and governed through FinOps for AI — which makes a structured envisioning engagement the front door to a much bigger conversation. Most organisations with 300 or more seats already believe Copilot and agents matter. What they lack is a clear picture of where AI will pay off, what it will take to get ready, and how they'll prove it before committing budget. The Frontier Accelerate for Copilot: Envisioning & POC engagement gives you a pre-sales, partner-led answer to all three — funded by Microsoft and sized from a 10-hour readiness sprint to a 280-hour enterprise programme. Package it as a Microsoft Marketplace offer and you have a repeatable front door to every Copilot, Agent 365 and Microsoft 365 E7 opportunity in your territory. Start Here: Why Publishing on Microsoft Marketplace Matters Microsoft Marketplace is Microsoft's partner-focused business platform, designed to help you reach more customers and simplify how you sell. A published offer gives your practice a permanent, discoverable storefront in the place customers and Microsoft sellers already look for Copilot expertise. More importantly, an offer turns your expertise into something repeatable. Define the engagement once — phases, activities, deliverables, sizing — and run it across every qualified customer instead of scoping from scratch. Professional service and managed service offer types are available in Partner Center, so one listing can carry the envisioning engagement, the POC and the ongoing services that follow. The Enterprise Opportunity: Interest Is High, Direction Is Missing The customers for this offer are organisations with at least 300 Office 365 / Microsoft 365 seats — mid-market through to the largest enterprises. They are the customers with the most to gain from Copilot and agents, and the most complexity to work through first: security and governance, tenant and access dependencies, adoption and change, and a credible way to measure value. That gap between ambition and a plan is where partners win. Microsoft is investing in the full Copilot journey in FY27, from envisioning and proof of concept through deployment and adoption — and the envisioning stage is where you shape the roadmap, the scope and the commercial conversation before anyone else does. Why Copilot and Agents Are the Right Place to Start Microsoft 365 Copilot puts AI inside the apps people already use every day — Outlook, Teams, Word, Excel and PowerPoint — so value arrives without a platform change. For larger organisations, that is only the first layer: Agent 365, custom agents built with Copilot Studio, and Microsoft 365 E7 extend Copilot from personal productivity into role-based and process-level automation. The new Copilot adds a third layer. Cowork takes delegated work and returns a finished result; Code lets knowledge workers build apps, dashboards and automations in natural language, hosted on Copilot Managed Runtime; and Autopilot is a persistent agent with its own identity that keeps work moving without a prompt. All three run on usage-based billing rather than the per-user subscription, which means every customer now has to decide which users and which scenarios justify consumption spend — and how to govern it with FinOps for AI. Each layer brings its own questions — which personas, which scenarios, what governance, what consumption model, which capabilities are worth paying for by the task — and each question is an envisioning conversation a partner is best placed to lead. Meet the Offer: Envisioning & POC, Sized to the Customer The Frontier Accelerate for Copilot: Envisioning & POC engagement is a pre-sales, partner-led engagement that identifies personas and use cases and builds a business case for Microsoft 365 Copilot, Agent 365, Microsoft 365 E7 and/or agents — with an optional proof of concept. The essentials: Who qualifies: Customers with a minimum of 300 Office 365 / Microsoft 365 seats; larger tiers unlock at 500, 1,000, 1,500, 3,000 / 5,000 and 10,000+ seats How it's sized: Six tiers — XXS (10 hrs), XS (20 hrs), S (40 hrs), M (100 hrs), L/XL (150 hrs) and XXL (280 hrs) — with hours scaling with the seats in scope What it covers: Five phases — Assess, Inspire, Design, POC and Executive Summary — with a working POC and measured results from the S tier upward What Microsoft provides: A delivery guide, pre-engagement planning resources and Microsoft Commercial Incentives (MCI) funding tied to proof of execution What the customer gets: Readiness findings, a business case and value plan including usage-based billing and Copilot Credits, technical requirements and a remediation plan, an adoption roadmap, a working POC and an executive readout Microsoft funds the engagement. You own the scope, the relationship and everything that follows. Your Role: From Trusted Assessor to Transformation Partner An envisioning engagement is not a workshop; it is a guided decision. Your job is to move the customer from curiosity to a signed proposal, with evidence at every step. Assess — identify high-value scenarios, choose the right assessments, define what success looks like and deliver readiness findings the customer can act on. Inspire — show what Copilot and agents can do across roles; make security, governance, adoption and reporting concrete rather than abstract concerns. Design — turn findings into a business case and value plan (including usage-based billing), a remediation plan, technical requirements, an adoption roadmap and clear POC criteria with risks, owners and dates. Prove — scope the POC users and products, prepare the environment, build the agent or solution, train the users and measure results including Copilot Credits consumed. Summarise — deliver the executive readout on seat growth and consumption, then convert: trial to paid licences, commercial proposal and signature, and a named wave 2 expansion plan. Every phase produces something the customer keeps — and every deliverable positions you as the partner who should build what comes next. Inside the Offer: Activities and Hours by Engagement Size Below is the full activity plan behind the offer, with hours for each of the six engagement sizes. Use it to size your own offer plans and statements of work. ID Phase Activity XXS XS S M L/XL XXL — Pre-req Customer eligibility (min. O365/M365 seats) 300+ 500+ 1,000+ 1,500+ 3,000+ / 5,000+ 10,000+ A1 Assess Identify high-value scenarios 0.5 1 1.75 3.75 5.5 10.5 A2 Assess Select assessment(s) 0.5 0.5 1 2.25 3.5 6.25 A3 Assess Define success 0.5 0.75 1.5 3 4.5 8.5 A4 Assess Deliver readiness assessment(s) 1 1.75 2.75 6 9 16.75 I1 Inspire Product overviews & demos across Copilot and agent capabilities 1 1.5 2 4.5 6.75 12.5 I2 Inspire Security/governance overview, incl. tenant and access dependencies 0.5 1 1.5 3 4.5 8.5 I3 Inspire Adoption/change overview 0.5 0.75 1 2.25 3.5 6.25 I4 Inspire Reporting/analytics overview 0.5 0.75 1 2.25 3.5 6.25 I5 Inspire Stories & Scenario Library 0.5 1 1.5 3 4.25 8.5 D1 Design Business case/value plan, incl. usage-based billing (UBB) 1 1.75 2.75 6.25 9.5 17.5 D2 Design Remediation plan 0.5 1 1.75 3.75 5.5 10.5 D3 Design Technical/functional requirements 0.75 1.5 2.25 5 7.5 14 D4 Design Adoption roadmap 0.5 1 1.75 3.75 5.5 10.5 D5 Design POC success criteria & environment prep 0.5 1 1.75 3.75 5.5 10.5 D6 Design Recommendations/risks/owners/dates, incl. validation and next-step owners 0.25 0.75 0.75 2.5 4 7 P1 POC Scope/users/products/features 0 0.25 1 3.5 5.25 9.75 P2 POC Confirm requirements/design 0 0.25 1 3.5 5.25 9.75 P3 POC IT access & environment prep 0 0.25 1.75 5.25 8 14.75 P4 POC Trial licenses 0 0.25 1 3.5 5.25 9.75 P5 POC Build POC agent(s)/solution(s); confirm Copilot Credits consumption 0 0.5 3.75 12.25 18.5 34.25 P6 POC Train POC users 0 0.25 1 3.5 5.25 9.75 P7 POC Measure/evaluate results, incl. usage and Copilot Credits consumed 0 0.25 1.5 3.5 5 10 E1 Exec summary Executive readout: seat growth and consumption implications 1 2 4 10 15 28 TOTAL Hours 10 20 40 100 150 280 Land Your Offer: What One Customer Is Worth The table below is the revenue anatomy of one Envisioning & POC engagement at each of the six sizes — and it shows that the funded engagement is only the first of three revenue streams. They stack on top of each other: MCI engagement incentive — Microsoft funds the envisioning and POC work itself, from $2K for a 10-hour XXS engagement to $100K for a 280-hour XXL programme, paid against proof of execution. CSP incentive on the licences that follow — earned on the Copilot revenue the business case unlocks, from the trial-to-paid conversion (T1) through the wave 2 expansion (X1), and growing as agent consumption and Copilot Credits scale. Managed services and follow-on professional services — the recurring engagement described in After the Readout, which is where the largest and most durable share of revenue lives. Item XXS XS S M L/XL XXL Minimum customer seats 300+ 500+ 1,000+ 1,500+ 3,000+ / 5,000+ 10,000+ Engagement hours 10 20 40 100 150 280 Post-delivery outcomes: Copilot rev (K) | Agent consumption (K) | Agent MAU 10 | 6 | 300 25 | 15 | 500 50 | 30 | 1,000 125 | 75 | 1,500 250/375 | 150/225 | 3,000/5,000 500 | 300 | 10,000 MCI engagement incentive (K) $2K $5K $10K $25K $50K / $75K $100K CSP incentive on Copilot revenue (K)† $1.95K $4.88K $9.75K $24.38K $48.75K / $73.13K $97.5K † CSP incentive shown at a blended 19.5% of the Copilot revenue outcome (direct bill 2.5 + 7 + 10; indirect reseller 7 + 12.5). Illustrative estimates from the offer plan — confirm current MCI payouts, CSP rates, eligibility and proof-of-execution requirements in the Microsoft Commercial Partner Incentives Guide. Now multiply. Everything above is the anatomy of a single customer. Landing the offer means running it across every qualifying customer in your territory — and you don't need to guess who they are. Partner Center's growth insights reporting, available through the AI Business Solutions & Security Insights (ASPX) dashboard, gives you account-level Copilot eligibility and seat whitespace, E7 opportunity, data security maturity, MCI eligibility and potential earnings for the customers you already manage. How the Offer Fits Together: From Sizing to Proof of Execution The offer runs left to right in three layers: Sizing & value — six engagement sizes from XXS (10 hrs) to XXL (280 hrs). Hours scale with the seats in scope, and value is tracked in the customer's own metrics. Five phases — Assess (A1–A4), Inspire (I1–I5), Design (D1–D6), POC (P1–P7) and Executive Summary (E1, T1, T2, X1). Each phase produces a concrete output the sponsor can see. Proof of execution — readiness and assessment findings; a business case and value plan including usage-based billing and Copilot Credits; technical requirements and a remediation plan; an adoption roadmap; a working POC with measured results; an executive readout covering next steps and consumption implications — and a named wave 2 expansion beyond the pilot team. The highlighted activities — security & governance (I2), adoption & change (I3), remediation plan (D2), technical requirements (D3), adoption roadmap (D4), IT access & environment (P3), build POC solution (P5), train POC users (P6), trial-to-paid conversion (T1), commercial proposal (T2) and the wave 2 expansion plan (X1) — are where the engagement stops being a project and becomes an ongoing relationship: managed services, ongoing optimisation and follow-on professional services after the engagement closes. After the Readout: Managed Services That Keep Delivering The executive readout is the start of the real engagement. Package these as standing services in your offer. Each one is sized in partner days so you can price it, and each one is tied to a result the customer's sponsor will recognise without a glossary: Managed service Partner activity — what you deliver and measure Customer business outcome — what it drives (illustrative targets, 1,500-seat customer) Deployment and remediation delivery • Effort: 5–10 days per wave • Activity: Close every item on the remediation plan and technical requirements (D2, D3) against dated owners, then licence and activate the wave's users by the roadmap date • Reported as: Items closed on time; seats activated; days from readout to go-live • Wave 1 live within 30 days of the readout, not 90 — two extra months of value on every seat • ≥95% of paid seats assigned and active; 75 idle seats would waste ≈$27K a year • Roll-out delivered within ±5% of the business-case budget Security and governance management • Effort: 2 days a month • Activity: Maintain the admin-settings baseline and data-protection controls, review agent permissions and access dependencies, approve plugins through the plugin registry and govern apps hosted on Copilot Managed Runtime, act on every Admin Settings Recommendation • Reported as: Recommended settings enabled; findings opened and closed; agents, plugins and apps with a named owner • Zero Copilot-related oversharing incidents; one enterprise data breach averages $4M+ • 100% of recommended settings on; findings closed within 30 days • Audit evidence produced in hours, not weeks — Data Security Maturity at Advanced-Healthy Adoption and change management • Effort: 3–4 days a month • Activity: Run the adoption roadmap (D4): coach champions, deliver role-based training, refresh scenarios, hold the monthly Copilot Analytics business review • Reported as: Active users as a share of assigned seats; people trained; low-activity users re-engaged • ≥80% of assigned seats active every month • 2–4 hours saved per user a week (≈3,000–6,000 hours across 1,500 seats) • ≈$0.5–1M a month of staff time released at $40/hour Agent and solution build-out • Effort: 5–15 days per agent or solution, then half a day a month to tune • Activity: Take each POC agent (P5) into production with Copilot Studio and Agent 365; release new Copilot Studio agents, Code-built apps and Autopilot agents from the scenario backlog, hosted on Copilot Managed Runtime • Reported as: Agents and apps live; active users per agent; tasks completed; Copilot Credits per completed task • 20–40% of tier-1 tickets or cases deflected per automated process • Cycle time cut 30–50% on each agent-run workflow; 200–500 hours removed a month per agent • Cost per completed task tracked and falling quarter on quarter FinOps for AI: consumption and licence management • Effort: 1-2 days a month • Activity: Track Copilot Credits and usage-based billing across Cowork, Code and Autopilot; set budgets, limits and model-family policies per user group; route credit requests through the customer's approval workflow; forecast spend and align seat additions, renewals and terms to each wave • Reported as: Reported as: Forecast versus actual variance; credits per active user; spend per business outcome; seats added; renewals completed on schedule • AI spend held within ±10% of forecast — no unplanned overage • Zero unused seats at renewal; 100% of renewals on schedule • Cost per outcome down 10–20% a year as usage matures Quarterly value reviews • Effort: 2 days a quarter • Activity: Refresh the business case (D1) with actuals, capture proof points in the customer's own words, agree and date the next named expansion wave with the executive sponsor • Reported as: Realised versus forecast value; proof points captured; next wave scheduled • ROI in dollars: ≈$125K a year of Copilot seats vs. $6M+ of time released • ≥3 quantified proof points in the sponsor's words each quarter • Each review dates the next wave: +100–300 seats or +1–2 agents a quarter Effort shown is indicative for an M-tier customer (1,500+ seats) and scales with seats and agents in scope, exactly as the engagement hours above do. Add the recurring rows together and one M-tier customer with three agents in production sustains roughly 9–10 partner days a month after the readout, before wave deployments and new agent or solution builds are counted. Every row pairs a number you can invoice against with a result the customer already cares about, which is what turns a recurring service into a renewable one and keeps you positioned as the customer's AI transformation partner as their ambitions grow. Each of these is a recurring, outcome-based service rather than a one-off project — and each keeps you positioned as the customer's AI transformation partner as their ambitions grow. Ready to Build Your Envisioning & POC Offer? Read the engagement terms in the Microsoft Commercial Partner Incentives Guide and download the delivery guide and pre-engagement planning resources. Confirm your eligibility for Microsoft Commercial Incentives engagements in Partner Center and align your delivery team on the five-phase model. Publish your offer in Partner Center as a professional service (Envisioning & POC) with a managed service follow-on (deployment, adoption and optimisation). Pick your first cohort — customers with 300+ Microsoft 365 seats and no clear Copilot or agent roadmap yet, then size each one to the right tier. Book the executive readout before Assess begins — so the conversion, proposal and wave 2 conversation is already on the calendar. The customers are already in your base. Publish the offer and open the conversation. Resources Frontier Accelerate for Copilot: Envisioning & POC | Microsoft Commercial Partner Incentives Guide Copilot Envisioning & POC — Delivery Guide Copilot Envisioning & POC — Pre-Engagement Planning The new Copilot is here: the opportunity for Microsoft partners429Views2likes0CommentsLand Your Offer - Anatomy of Revenue Generating Partner Offer - Part 1 - Copilot in 30
Copilot in 30: A Ready-Made Marketplace Offer to Grow Your SMB Practice Thirty days. Twenty-five users. One repeatable offer that turns AI curiosity into a long-term customer relationship. Small and medium businesses know AI matters. What they lack is a trusted guide and a low-risk way to start. Copilot in 30 gives you both: a $0, 25-user, 30-day Microsoft 365 Copilot Business trial from Microsoft, wrapped in a structured journey that only a partner can deliver. Package it as a Microsoft Marketplace offer and you have a scalable on-ramp to every SMB customer in your base — and to the managed services that follow. Start Here: Why Publishing on Microsoft Marketplace Matters Microsoft Marketplace is Microsoft's partner-focused business platform, designed to help you reach more customers and simplify how you sell. A published offer gives your practice a permanent, discoverable storefront in the place customers already look for Copilot help. More importantly, an offer turns your expertise into something repeatable. Instead of scoping every engagement from scratch, you define the journey once — activities, timeline, deliverables — and run it across dozens of customers. Professional service and managed service offer types are available in Partner Center, so the same offer can carry both the 30-day journey and what comes after it. The SMB Opportunity Hiding in Plain Sight SMB customer segment is still early in their AI journey. These are organisations with 300 or fewer users on Microsoft 365 Business Basic, Standard or Premium — typically without an in-house AI team. That combination is exactly where partners win: high demand, limited internal capacity, and a customer base large enough that a well-designed, repeatable offer scales far beyond what bespoke projects can. Why Copilot Is the Right First AI Step for SMBs Microsoft 365 Copilot Business is the cost-effective Copilot add-on built for SMB customers, delivering the same capabilities as Microsoft 365 Copilot inside the apps their people already use — Outlook, Teams, Word, Excel and PowerPoint. No platform overhaul, minimal training, immediate relevance. Copilot is also the on-ramp. Once a team works confidently with Copilot, the natural next steps are agents, automated workflows and Copilot Cowork — each one deepening the customer's dependence on the partner who guided them there. Meet Copilot in 30: 25 Users, 30 Days, $0 Copilot in 30 is a limited-time, CSP partner-led Microsoft 365 Copilot Business trial for SMB customers with fewer than 300 employees. The essentials: What the customer gets: 25 Microsoft 365 Copilot Business seats for 30 days at $0, transacted through CSP New Commerce (Product ID CFQ7TTC0MM8R · SKU 006Z) Who qualifies: Customers on Microsoft 365 Business Basic, Standard or Premium with no paid Microsoft 365 Copilot today — one trial per customer How long it runs: Available to transact until 31 December 2026 What happens at Day 30: The trial auto-converts to a paid subscription unless renewal settings are changed, with a 7-day cancellation window What Microsoft provides: A launch kit, campaign materials, setup guidance, the Copilot Success Planner and conversion guidance Microsoft supplies the licences and the assets. The offer — and the customer relationship — is yours. Your Role: The Guide Who Turns a Trial Into a Habit A trial alone rarely changes behaviour. A guided trial does. Your job across the 30 days is to make sure 25 people experience real value in real work, and that the sponsor can see it. Before Day 0 — pick the right customers, become "Customer Zero" by using Copilot in your own business, secure a named sponsor and Copilot admin, and build a 30-day success plan with agreed measures. Day 0 — transact the trial, set the paid renewal quantity and term, complete admin setup, assign all 25 licences and run the kick-off with starter prompts. Days 1–28 — lead a weekly scenario (Outlook, Teams, Apps, Agents), review Copilot Analytics, re-engage low-activity users and capture proof points in the customer's own words. Days 29–30 — run the outcome and ROI review, confirm the paid offer and open the expansion and consumption conversation. Every touchpoint is partner expertise the customer cannot get from a licence alone — and every one moves the decision at Day 30 from "should we?" to "how much more?" Inside the Offer: Activities, Timeline and Deliverables Below is the full activity plan behind the offer, ready to drop into your own offer description or statement of work. ID Stage Activity Trial day (of 30) Key deliverables — Pre-req Customer eligibility (Copilot Business trial) Before Day 0 Active M365 Business base licence; no paid M365 Copilot; one $0 trial per customer; CSP New Commerce transactable; offer open to 31 Dec 2026 I1 Identify Build the prioritised target list Pre-trial Tier A/B target list from ASPX and Cloud Ascent; 50–300 eligible seats I2 Identify Confirm eligibility and trial fit Pre-trial Eligibility check: M365 Business base licence, no paid Copilot, one trial I3 Identify Launch the acquisition campaign Pre-trial Campaign email sent; briefing delivered; responses triaged into pipeline I4 Identify Be Customer Zero: complete microskilling Pre-trial Microskilling complete; internal Copilot experience; team briefed P1 Plan Confirm sponsor and success measures Pre-trial Named sponsor and admin; 25 trial users; agreed success measures P2 Plan Build the 30-day success plan Pre-trial Personalised Success Planner output; weekly scenarios; admin and user views P3 Plan Confirm technical and compliance readiness Pre-trial Minimum requirements verified; data and compliance review; blocker log A1 Activate Transact the trial in CSP New Commerce Day 0 25-seat, 30-day, $0 trial ordered (CFQ7TTC0MM8R · SKU 006Z) A2 Activate Configure the paid renewal settings Day 0 Renewal quantity, term and billing set; Cowork usage-based billing if in scope A3 Activate Complete admin setup and assign licences Day 0 Recommended settings on; 25 licences assigned (starts the clock) A4 Activate Run the kick-off and share starter prompts Day 0 Kick-off email; starter prompts; four-week prompt series scheduled X1 Experience Week 1 · Outlook — catch up and communicate Days 1–7 Week 1 prompts landed; first-week activation rate reviewed X2 Experience Week 2 · Teams — meetings that run themselves Days 8–14 Copilot Analytics checkpoint; recaps adopted; low-activity users re-engaged X3 Experience Week 3 · Apps — create in minutes Days 15–21 App scenarios and proof points; week 3 training gate before day 30 X4 Experience Week 4 · Agents — unlock the next level Days 22–28 Role-built agents trialled; 30-day usage trends from the admin centre C1 Convert Outcome review, paid offer and expansion plan Days 29–30 ROI review; 50-seat offer confirmed in 7 days; wave 2 plan; consumption conversation opened Land Your Offer: What One Customer Is Worth The table below is the revenue anatomy of one Copilot in 30 engagement — and it shows that the money is not in the trial, but in what the trial sets up. Item Value Detail Offer duration 30 days Trial clock runs Days 1–30; identify, plan and Day 0 setup precede it Trial offer 25 seats M365 Copilot Business · 30 days · $0 · one per customer · to 31 Dec 2026 CSP incentive — 25 seats (K) $0.32K 5.0% direct bill (2.5% M365 CSP Core + 2.5% Strategic Product Accelerator Tier 1) on 25 M365 Copilot Business seats x $21/mo† ≈ $6.3K/yr; indirect reseller 2.5% ≈ $0.16K Conversion target 50 seats Lead with 50 paid seats at conversion; sets up the wave 2 expansion plan CSP incentive — 50 seats (K) $0.63K 5.0% direct bill (Core + SPA Tier 1) on 50 M365 Copilot Business seats x $21/mo† ≈ $12.6K/yr; indirect reseller 2.5% ≈ $0.32K Frontier Accelerate deployment funding (K) $2.5K Microsoft Commercial Incentives funding for the Copilot deployment engagement when the conversion lands with 50 paid seats†; funds the deployment and adoption work that leads into managed services † Illustrative estimates from the offer plan. Confirm current incentive rates, funding and eligibility in Partner Center. Three streams stack on top of each other: CSP incentive — earned on every paid Copilot Business seat from the moment the trial converts, and growing again when the customer expands from 25 to 50 seats. Frontier Accelerate deployment funding — $2,500 available when you lead the conversion with 50 paid seats, paying for the deployment work that makes the expansion stick. Managed services — the recurring engagement described in Day 31 and Beyond, which is where the largest and most durable share of revenue lives. Now multiply. Everything above is the anatomy of a single customer. Landing the offer means running it across every eligible customer in your base — and you don't need to guess who they are. Partner Center's growth insights reporting, available through the AI Business Solutions & Security Insights (ASPX) dashboard, gives you account-level Copilot eligibility, seat whitespace, free Copilot Chat usage and adoption signals for the customers you already manage. To turn that export into a ranked target list, my colleague Brian O'Shea has built a Copilot for 30 Power BI dashboard that sits over your ASPX data and scores each customer on a 0–100 priority scale from eligible seats, whitespace, free-to-paid potential and opportunity signals — so your first cohort is the ten customers most likely to convert, not the first ten who reply. How the Offer Fits Together: From Trial Inputs to Proof of Value The offer runs left to right in three layers: Trial inputs — 25 users, 30 days, $0 CSP trial SKU; an SMB with 50–300 eligible Microsoft 365 seats; no paid Copilot today; a Business Basic, Standard or Premium base; one trial per customer to 31 Dec 2026; a named sponsor and Copilot admin; auto-conversion to paid unless changed. Five stages — Identify (I1–I4), Plan (P1–P3), Activate (A1–A4), Experience (X1–X4) and Convert (C1, T1, T2, W2). Each stage produces a concrete output the sponsor can see. Proof of value — a prioritised list and campaign responses; agreed use cases and success measures; a provisioned trial with 25 licences assigned; weekly usage from the Microsoft 365 admin centre; adoption proof points in the customer's words; paid conversion confirmed in Partner Center — and a named wave 2 expansion beyond the first 25. The highlighted activities — admin setup (A3), Week 4 agents (X4), 25→50 paid seats (T1), Frontier Accelerate funding (T2) and the wave 2 expansion plan (W2) — are where the engagement stops being a project and starts becoming an ongoing relationship: managed services, agent build-out, Copilot Studio and Copilot Cowork follow-on once the trial converts. Day 31 and Beyond: Managed Services That Keep Delivering The end of the trial is the start of the real engagement. Package these as standing services in your offer: Copilot adoption management — monthly Copilot Analytics business reviews, prompt and scenario refreshes, champion programme and onboarding for each new wave of users Licence and expansion management — take the customer from 25 to 50 paid seats and on to wave 2, aligning renewals, terms and billing as the footprint grows Agent build-out — design, build and maintain role-based agents with Copilot Studio for sales, service, finance and operations scenarios surfaced in Week 4 Copilot Cowork enablement and governance — introduce consumption-based Cowork scenarios, set budgets and cost controls, and report on usage each month Security, compliance and readiness — keep data protection, permissions and governance in step with expanding AI use, including a path to Microsoft 365 Business Premium Quarterly value reviews — refresh success measures, capture new proof points and agree the next expansion plan with the sponsor Each of these is a recurring, outcome-based service rather than a one-off project — and each keeps you positioned as the customer's AI partner as their needs grow. Ready to Build Your Copilot in 30 Offer? Download the Copilot in 30 launch kit and Microsoft 365 Copilot Partner FAQ from the Microsoft AI Cloud Partner Program. Be Customer Zero — run Copilot and the microskilling series inside your own business first. Publish your offer in Partner Center as a professional service (the 30-day journey) with a managed service follow-on (Day 31 and beyond). Pick your first cohort — customers with 50–300 seats on a Microsoft 365 Business plan and no paid Copilot today. Transact your first trial through CSP New Commerce (Product ID CFQ7TTC0MM8R · SKU 006Z) and set the paid renewal on Day 0. Book the Day 30 review before Day 1 — so the conversion and expansion conversation is already on the calendar. The window closes on 31 December 2026. The customers are already in your base. Publish the offer and start the clock. Resources From AI curiosity to Copilot adoption in 30 days — Microsoft Partner Blog Copilot in 30 Launch Kit — partner GTM playbook, customer trial guide, invitation and weekly prompt emails, admin setup guidance Build Your 30-Day Copilot Success Plan Copilot Success Planner Walkthrough video Partner Skilling Hub | Microskilling for Copilot in 30 Power BI Dashboard that integrates with your ASPXi Partner Data · By Brian O'Shea Create compelling customer business cases847Views2likes1CommentWhen AI Stops Waiting for Instructions
Microsoft’s Autopilots mark a shift from AI that responds to prompts to persistent agents with identity, initiative and standing responsibilities. As AI begins to hold a “job,” the enterprise challenge moves beyond deploying agents to defining what they should own, how far their autonomy should extend, and where human accountability must remain.353Views2likes0CommentsBeyond Tokens: Rethinking AI Economics with Microsoft Foundry
Beyond Tokens: Rethinking AI Economics with Microsoft Foundry From the cost of intelligence to the value of outcomes Enterprise AI has an accounting problem. Executives expect agentic AI to return roughly 171% on investment, according to one widely cited survey. Yet McKinsey finds only about 39% of organizations can attribute any earnings impact to AI at all. Both numbers can be true at once — because the gap between them is not a technology gap. It is a measurement gap. For the first few years of generative AI, one number dominated the economics conversation: tokens. How many tokens did a model consume? What was the cost per million tokens? Could a smaller model perform the same task? Those questions mattered when enterprises were experimenting with AI. They are no longer enough as AI moves into production. An enterprise agent doesn't simply consume tokens. It reasons, retrieves context, invokes tools, calls APIs, verifies its work, retries unsuccessful actions and sometimes escalates exceptions to humans. The model call might cost pennies. The business outcome could cost considerably more. Which leads to an increasingly important question: What is the right economic unit for intelligence? From AI experimentation to economic accountability The first wave of enterprise AI was about possibility: Can AI do this? The next wave is about production, as AI becomes embedded in software engineering, customer service, finance, healthcare and supply chains. And production changes the question: Should AI do this and at what cost? Microsoft has moved decisively onto this ground. In August 2026, the Microsoft Foundry team launched its Economics of Agent Optimization series, arguing that "tokens have become the new unit of technology spend" and that AI should be run as a managed investment system. On the latest earnings call, Satya Nadella described Microsoft's objective as "advancing the frontier on the cost-to-outcome curve, ensuring every customer can turn tokens into business results." The discipline is going mainstream too: 98% of FinOps teams now manage AI spend, up from 31% two years ago. Microsoft's series is largely about the numerator of that curve - making every request, agent and dollar more efficient. This article is about the denominator: what an outcome is, what it truly costs, and what it is worth. The evolution of Microsoft Foundry reflects the same shift. At Build 2026, Microsoft expanded the conversation beyond building agents toward tracing behavior, evaluating quality, monitoring production performance, optimizing agents and connecting their operation to ROI. Think of the progression as: Trace → Evaluate → Monitor → Optimize → ROI This is more than a technology roadmap. It represents a shift from observing AI as technology to managing AI as an economic asset. Tokens became the unit of spend. They were never the unit of value. Consider two AI agents handling the same customer-service workflow. Agent A costs $0.08 per interaction. Agent B costs $0.20. Agent A appears cheaper. But suppose Agent A successfully resolves only 55% of cases, while Agent B resolves 90%. The remainder require retries, additional reasoning or human intervention. Which agent is actually cheaper? The inexpensive interaction may produce the expensive resolution. This illustrates a fundamental problem: We often measure AI where it is consumed rather than where value is created. Tokens are a unit of consumption. Businesses operate in outcomes. A customer-service leader cares about issues resolved. An engineering leader cares about high-quality software reaching production. A finance leader cares about reconciliations completed accurately. The economic denominator needs to move closer to the business. The AI Economic Ladder I think of this evolution as an AI Economic Ladder: Tokens → Interactions → Tasks → Outcomes → Value Each step moves measurement closer to what the enterprise actually cares about. At the token level: What intelligence did we consume? At the interaction level: What did each AI run cost? At the task level: What did it cost to complete the work? At the outcome level: What did a successful result cost? At the value level: Was the outcome worth creating? An AI system can become more efficient at every technical metric while creating little economic value. Conversely, an expensive AI workflow could be extraordinarily valuable if it prevents revenue leakage, reduces operational risk or accelerates a critical business process. The objective isn't cheaper AI. It is better economics. Not every completed task is a successful outcome There is another complication. If an agent completes a workflow, should we count it as a successful outcome? Not necessarily. A meaningful outcome needs three characteristics: Completed. Quality-gated. Attributable. It must reach its intended end state, meet an explicit standard for quality, accuracy, safety or business acceptability, and be attributable to the agent or workflow that produced it. That gives us a more meaningful measure: Cost per Successful Outcome = Fully Loaded AI Workflow Cost / Completed, Quality-Gated, Attributable Outcomes The denominator becomes real only when named in business language: cost per prior authorization resolved in healthcare, per pull request triaged and tested in engineering, per disputed invoice reconciled in finance operations. If you cannot name the outcome in a sentence the process owner recognizes, you are not ready to measure it. The quality gate matters. With AI, "the system ran successfully" and "the system produced a good outcome" are not the same thing. Microsoft Foundry's tracing and evaluation capabilities become economically important for precisely this reason. Evaluation isn't merely quality control. It helps determine what gets counted as value. What does an AI outcome really cost? The true economic footprint goes far beyond inference: Model + Reasoning + Grounding + Tools + Orchestration + Infrastructure + Retries + Evaluation + Governance + Human Intervention Human intervention is particularly easy to overlook. Every time someone must review, correct, approve or recover an AI-generated outcome, the economics change. The same applies to verification. An agent reaching an acceptable result in three steps has different economics from one requiring fifteen steps and multiple retries. And verification is not a rounding error — it is the bulk of the bill. McKinsey's 2026 analysis of production agentic workflows found roughly 60% of an agentic task's cost is tied to refining answers — checking, repairing, re-verifying — not generating the initial response. Most of what you pay for is not intelligence. It is assurance. This means quality and economics are connected. The quality bar you set influences the cost you pay. The challenge isn't simply minimizing consumption. It is finding the right balance between quality, cost, speed and risk. Cost per outcome is only half the equation Now imagine two agents. Both cost $5 per successful outcome. One saves an employee ten minutes of administrative work. The other prevents $500 in revenue leakage. Their cost efficiency is identical. Their economics clearly aren't. So we need to move another step up the ladder: from Cost per Outcome to Value per Outcome. The question isn't only how cheaply AI can complete the work. It is: How much economic value does this outcome create relative to the intelligence required to produce it? Now the CIO, CFO, CAIO and business leader have a common conversation. Give every outcome an Intelligence Budget Not every problem deserves the smartest model available. Classifying an email may require relatively little intelligence. Resolving a complicated customer complaint may justify more context and reasoning. Assessing the risks in a multimillion-dollar contract may justify sophisticated reasoning, multiple validations and human review. Every business outcome therefore has an economically rational amount of intelligence worth spending on it. Call it an Intelligence Budget. This changes the architecture question from which model should we standardize on, to: What combination of model, reasoning, context, tools and human judgment does this outcome deserve? This is where Microsoft Foundry's model router becomes interesting. Individual requests can be dynamically routed so simpler work doesn't consume the same model resources as complex reasoning. If the Intelligence Budget is the economic principle, intelligent routing is one way of operationalizing it. The future enterprise AI architecture won't be about one model doing everything. It will route intelligence according to the economics, quality and risk of the outcome. Making AI economics observable None of this works without visibility. An AI system can be technically healthy and economically unhealthy — responsive and error-free while repeatedly choosing inefficient reasoning paths, invoking unnecessary tools or producing outputs requiring expensive human correction. AI economics and AI observability are becoming inseparable. Microsoft Foundry increasingly connects these disciplines. Tracing shows what an agent did. Evaluation determines whether it met required criteria. Observability helps monitor production behavior. Agent optimizer can test improvements across prompts, skills and models. Microsoft's emerging ROI capabilities take the next step by connecting operating costs with measures such as task completion, time saved and cost efficiency. Attribution is the bridge to the finance conversation. Teams place Azure API Management in front of Foundry endpoints as an AI Gateway, stream token telemetry into Application Insights, and use Entra Agent ID to give every agent run a discrete identity that maps cost to its cost center. Microsoft Agent 365 extends the discipline tenant-wide — spending policies, budget caps and departmental chargeback across Microsoft and third-party agents. Together, they create something enterprises have historically lacked: A feedback loop between how intelligence is consumed and what that intelligence accomplishes. The paradox of cheaper intelligence There is another reason AI economics will become more important as models get cheaper. The Jevons paradox suggests that when technology makes a resource cheaper and more efficient, total consumption can actually increase. AI may experience the same effect. Cheaper intelligence enables more agents, more reasoning and more workflows that were previously uneconomic. So we could see cost per unit of intelligence fall while total intelligence consumed rises. Cheaper AI may therefore produce larger AI bills. That isn't necessarily bad — provided value grows faster than consumption. The objective isn't minimum AI consumption. It is maximum economic value from AI consumption. From workload economics to portfolio economics As AI scales, economics becomes a capital-allocation question. I see three levels. Workload Economics: Is this AI system running efficiently? Outcome Economics: Is it producing quality outcomes economically? Portfolio Economics: Where should we put our next AI dollar? That final question will become increasingly important. An enterprise with hundreds of AI initiatives shouldn't assume every one deserves continued investment. Some should scale. Some need optimization. Some should be redesigned or consolidated. And some should be stopped. The ability to experiment cheaply created the first explosion of enterprise AI. The discipline to allocate capital intelligently will determine what scales. Who owns AI economics? Once an agent becomes part of how work gets done, its economics cannot remain purely an IT metric. The business understands the value of the outcome. Technology understands the architecture and optimization levers. Finance brings economic discipline and comparability. That suggests a shared model: Business owns the outcome. Technology owns the optimization levers. Finance owns the economic discipline. AI economics ultimately isn't just a technology-cost conversation. It is a business-performance and capital-allocation conversation. From abundant intelligence to intelligent economics We are entering an era where intelligence is becoming an increasingly abundant, programmable and variable-cost resource. Microsoft Foundry and the broader Microsoft AI stack are making it easier to build, evaluate, observe, optimize and govern that intelligence. But abundant intelligence does not guarantee abundant value. Enterprises still need to decide where AI belongs, how much intelligence each problem deserves, what defines a successful outcome, when humans should remain involved and which AI investments deserve more capital. The winners won't necessarily use the cheapest models. They won't consume the fewest tokens. And they won't be the organizations that build the most agents. They will become exceptionally good at moving up the AI Economic Ladder: from consumption, to outcomes, to value. Because the next era of AI won't be won by organizations that buy intelligence most cheaply. It will be won by those that convert intelligence into value most efficiently. Where to start: the first 90 days Define the denominator for your top three agents — what counts as done, what quality gate applies, who signs off. Instrument attribution — Azure API Management as an AI Gateway, token telemetry to Application Insights, Entra Agent ID on every run. Wire evaluations into the cost pipeline so only quality-gated outcomes count. Set Intelligence Budgets — model router per request, agent optimizer against your evaluators, Agent 365 policies as circuit breakers. Stand up a joint monthly review — business, technology and finance on one dashboard: outcomes delivered, cost per outcome, value per outcome. Frequently asked questions What is Cost per Successful Outcome in enterprise AI? The fully loaded cost of an AI workload divided by outputs that were completed, quality-gated and attributable - for example, cost per prior authorization resolved or per pull request triaged. It turns token metrics into the unit economics of AI-performed work. What is an Intelligence Budget? The economically rational amount of intelligence - model capability, reasoning, context, tools and human review — worth spending on a given outcome, based on its value and risk. Model router in Microsoft Foundry is one way to operationalize it. Why do AI agents cost more than single model calls? One agent task can involve planning, tool calls, retries and verification - many model calls with compounding context. Research on production agentic workflows attributes roughly 60% of task cost to refining and verifying answers, not generating the first response. Will falling model prices make AI cost management unnecessary? No. By the Jevons paradox, cheaper intelligence expands consumption, so total AI spend typically rises as unit prices fall. The discipline that matters is maximizing value per unit of intelligence. Who should own AI economics? A shared model: the business owns the outcome and its value, technology owns the optimization levers, and finance owns the economic discipline and review cadence. #MicrosoftFoundry #Agent365 #AzureAI #FinOps #AgenticAI #AIAgents #Azure #MicrosoftCostManagement #AIEconomics #Tokens References Microsoft Azure Blog: "The Economics of Agent Optimization: From pilots to measurable returns" (August 12, 2026) Microsoft FY26 Q4 earnings call (Satya Nadella, July 2026) McKinsey — "Cost versus value: managing agentic AI system performance" (July 2026) FinOps Foundation — State of FinOps 2026; Microsoft Learn — Model router for Microsoft Foundry; Agent optimizer; Foundry Control Plane cost optimization1KViews1like2CommentsAdding a Fallback Model to Hermes with Microsoft Foundry
So the plan was simple. Leave the Bedrock configuration untouched, then wire Microsoft Foundry in behind it as a fallback, so Hermes always has somewhere else to go when the primary provider is not responding. A few other reasons pushed me towards Foundry in particular: Redundancy that does not need me. If Bedrock is throttled or out of quota, I want Hermes to fail over on its own rather than waiting for me to notice. A catalogue I already pay for. Foundry puts the latest GPT models next to open-weight and partner models in one place, so I can pick a model that suits the task instead of settling for whatever a single provider happens to offer. Enterprise controls out of the box. Region pinning, private networking, content filters and per-deployment quota all sit in the same portal, which makes the setup far easier to defend to a security reviewer. Learning the mechanics before I need them. Working out how Hermes handles a provider chain is much nicer on a quiet Tuesday than during a live outage. Here is the short version, if you are deciding whether to read on. Time: about thirty minutes if nothing goes wrong. Cost: pay-as-you-go tokens only, and none at all while the fallback sits idle. Result: an assistant that keeps answering when your primary provider stops. Before you start, you will need three things: a machine with Hermes already installed and a working primary provider configured, an Azure subscription with access to Microsoft Foundry in a region you can actually deploy into, and enough quota in that region to create a deployment. One thing that made this easy to justify: Foundry deployments bill per token on the standard pay-as-you-go tier. A fallback provider that never gets invoked costs nothing beyond the requests it actually serves, so the insurance is close to free until the day you need it. Chat surface (CLI, messaging) → Hermes Gateway → Primary Amazon Bedrock → Fallback Microsoft Foundry Figure 1: Where the fallback sits. Every request goes through the Hermes gateway to the primary provider; only when that provider is unavailable does the chain continue to Microsoft Foundry. Part 1: Deploying a Model on Microsoft Foundry The first half of this job happens entirely inside the Microsoft Foundry portal and has nothing to do with Hermes yet. All you are really doing here is making sure your Azure subscription can serve a model, and that you hold an endpoint and key Hermes can authenticate with later. 1. Deploy model in Foundry → 2. Copy endpoint + key → 3. hermes fallback add → 4. Authenticate → 5. Select models, test Figure 2: The whole setup in five moves. The first two happen in the Microsoft Foundry portal (orange); the rest happen on the Hermes machine (blue). Go to Microsoft Foundry > Build > Models > Deploy > Deploy a base model. You can deploy a fine-tuned model instead if you already have one, which works just as well with Hermes. Check the region shown at the top of the portal before you commit, because both model availability and deployment quota differ from one region to the next. Then deploy the model you have selected: In this case I deployed gpt-5.6-sol, which is the model Hermes will fall back to. The choice was deliberate rather than exciting. My primary model on Bedrock is a general-purpose chat model, and a fallback is only useful if the answers it gives feel like a continuation of the same conversation rather than a different assistant wearing the same name. The gpt-5.6-sol deployment matches that behaviour closely, it was available in the region I wanted to pin, and the quota I was granted comfortably covers a day of normal use. If a fallback surprises you the first time it fires, it is the wrong fallback. Once the deployment finishes, open it and take note of two values: the target endpoint URI and the API key. Copy both somewhere safe now, because you will be pasting them into Hermes in the next part. If your organisation rotates keys on a schedule, use a key with the longest life you are allowed, since a fallback secured with a credential that expires quietly stops being a fallback. What to copy Where it lives in the portal Where Hermes asks for it Target endpoint URI Deployment > Endpoint > Target URI "Endpoint" prompt in hermes fallback add API key Deployment > Endpoint > Key "API key" prompt, or choose Entra ID instead Deployment name Deployment > Details > Name Shown in the model list Hermes returns Region Top of the portal, next to the resource Must match the region you deployed into Figure 3: Everything Hermes will ask for, and where to find each value before you leave the portal. Part 2: Adding Foundry to Hermes as a Fallback With the Foundry side sorted, everything from here happens in the Hermes CLI. One thing worth knowing before you start: this is the fallback command, not the primary model command, so your existing Bedrock configuration is left completely alone. Nothing in this section can break what is already working, which makes it a good one to try on a live setup. Run the Hermes fallback command: When Hermes asks which provider to add, choose Azure Foundry. The picker still carries the old name; it is the same service that the portal now calls Microsoft Foundry. Paste the target endpoint URI from your deployment, then authenticate with the API key you copied earlier. Hermes also offers Microsoft Entra ID at this prompt, which is the better option if your organisation would rather not have a static key sitting on the machine. If authentication fails here, check the endpoint before you start suspecting the key. In my experience the endpoint is wrong far more often than the credential is, usually because the deployment name at the end of the URI does not match the deployment you actually created. Once authentication succeeds, Hermes lists the deployments your Foundry resource exposes and asks which ones you want to use. You can select more than one, and the order is not cosmetic: Hermes walks down the chain from top to bottom whenever the provider above is unavailable. Treat that list as a priority order, not a shopping basket. What happens to the primary What Hermes does What you see in the chat Responds normally Routes every request to the primary and never touches the chain Nothing. The fallback stays idle Throttled or out of quota Retries the next provider down the chain on the same request A reply, served by the fallback model Endpoint unreachable Keeps failing over on each new request until the primary recovers Slightly different tone and latency, but a working assistant Every provider fails Returns the error rather than hanging An error worth chasing with hermes status Figure 4: The chain in practice. The fallback only earns its keep in the middle two rows, which is exactly why it is easy to forget you configured it. Part 3: Promoting Foundry to the Primary Model At this stage Foundry is sitting in the back seat as a backup. I wanted to reverse the arrangement and make Foundry the primary while Bedrock slides down into the fallback slot, partly because I preferred keeping day-to-day traffic inside my Azure subscription, and partly because I wanted proof the chain works in both directions. Before promotion After promotion Primary: Amazon Bedrock → Primary: Microsoft Foundry Fallback: Microsoft Foundry → Fallback: Amazon Bedrock Figure 5: The promotion, in effect. Nothing is added or removed; the two providers simply trade places in the chain. There is no dedicated "promote" command in Hermes, so the manual route is a short sequence of steps rather than a single instruction: Select the fallback provider/model as the new primary: hermes model Remove the now-duplicate model from the fallback chain: hermes fallback remove Optionally add the old primary model as a fallback: hermes fallback add Restart the messaging gateway: hermes gateway restart Verify the result: hermes status / hermes fallback list That sequence works, and it is good to know what is happening underneath. But since I already had a working provider configured, I would rather just ask Hermes to rearrange itself. This is the part I genuinely enjoy about the tool: the configuration is something you can talk to, not only something you type commands at. Prompt: Okay now please make the model I configured on Microsoft Foundry into the main model, and make the Bedrock one the fallback model! Hermes rewrites the provider chain on its own and confirms the swap once it is done, which is a great deal less error-prone than running the five commands by hand. Part 4: Testing the Switch Configuration you have not tested is just an assumption with extra steps, so the next thing is to confirm Hermes really is talking to Foundry. Type /model when running Hermes to bring up the model picker. You will be prompted to select a provider first. Pick the Microsoft Foundry entry, then choose the specific deployment from the list underneath it. The active model should switch straight away. Send it a plain "Hello" to check that the deployment actually responds, rather than just looking correct in the menu. Appearing in a dropdown and serving a request are two very different things. A second test is worth the thirty seconds it costs: run hermes status to confirm which provider is live, then hermes fallback list to confirm the chain is ordered the way you intended. The picker tells you what you selected; those two commands tell you what Hermes will actually do at three in the morning. Part 5: The Obstacle, and What It Actually Taught Me Every walkthrough has the part the author quietly leaves out. Here is mine: the wrinkle was not the model, it was capacity. My first attempt deployed into the region closest to me out of habit, and the portal turned it down because there was no capacity left for that model at the tier I asked for. The model was clearly listed in the catalogue; being listed and being deployable in your region, on your subscription, at your quota, are three separate questions. Redeploying in a different region fixed it in a couple of minutes, but it meant the endpoint URI changed, which in turn meant the value I had already pasted into Hermes was stale. Re-running hermes fallback add against the new endpoint sorted it out. The lesson is cheap enough to hand over for free: check quota and regional capacity for your specific subscription before you design a walkthrough, a demo or a production fallback around one deployment. In the Foundry portal, Management then Quota shows exactly what you have been granted per region and per model family, which is the only list that matters. Symptom Likely cause Fix Deployment rejected in the portal No capacity for that model at the tier you asked for, in that region Deploy in another region, or drop to a smaller tier Hermes rejects the credential Endpoint URI does not match the deployment you created Re-copy the target URI from the deployment, not the resource Provider authenticates but lists nothing Key belongs to a different Foundry resource Check you are in the right resource, then re-run hermes fallback add Fallback never fires Chain ordered the wrong way round hermes fallback list, then reorder Figure 6: The four things that went wrong, or nearly did, and what fixed each one. There is a silver lining worth stating plainly. Because the fallback chain was already in place, a deployment that refused to come up did not take the assistant down with it. That is precisely the scenario this whole exercise was meant to cover, and it turned up on day one without me having to simulate it. Command Cheat Sheet Everything used in this walkthrough, collected in one place: hermes fallback add: attach a provider to the fallback chain hermes fallback remove: drop a provider from the chain hermes fallback list: show the chain in priority order hermes model: set the primary model hermes gateway restart: restart the messaging gateway after a change hermes status: confirm which provider is currently live /model: switch models from inside a running session Conclusion Adding Microsoft Foundry as a fallback behind my existing Bedrock setup took an afternoon, and most of that was spent recovering from a regional capacity limit I should have checked first. The work itself is small: deploy a model, copy the endpoint and key, run hermes fallback add, authenticate, pick your deployments. The payoff is that Hermes no longer depends on one provider staying healthy. Three things are worth carrying away from this: Check quota, not just the catalogue. The Foundry catalogue shows what Microsoft offers. It does not show what your subscription and region can actually deploy today. Confirm that first, before you build anything on top of a specific deployment. Order your fallback chain deliberately. Hermes works down the list from top to bottom, so the sequence you choose during setup is the failover policy you are going to live with. Put the model you actually trust at the top. Treat the endpoint as part of the credential. Redeploying in a new region changes the endpoint URI, and a fallback pointed at an endpoint that no longer exists is not a fallback. Re-run the setup whenever the deployment moves. The switch from Bedrock primary to Foundry primary also proved the chain runs in both directions, which is the real point. Provider redundancy is only useful if you have watched it work. Next on my list is deliberately breaking the primary provider to confirm the failover triggers on its own, without me typing a single command. If you run this against a different model, region or provider pairing, I would genuinely like to know how it went, particularly if your quota experience was better than mine. Drop it in the comments.411Views0likes0CommentsSimplify AKS observability with Azure Native New Relic Service
An Azure Native path to New Relic Intelligent Observability for AKS AKS environments are dynamic by design. Applications can span clusters, namespaces, nodes, pods, and containers, while workloads scale and change continuously. Obtaining consistent visibility often requires platform teams to deploy and maintain monitoring components separately on every cluster. Azure Native New Relic Service simplifies this process by integrating New Relic onboarding and management into Azure. Customers can already use the service to: Create a new New Relic account or link an existing account from Azure. Configure the forwarding of Azure platform metrics and logs to New Relic. View the monitoring status of Azure resources. Consolidate procurement and eligible New Relic charges through Azure Marketplace. Monitor multiple Azure subscriptions through a single New Relic resource. With AKS extension support, customers can now extend this native management experience to their Kubernetes clusters. Install the New Relic integration from the Azure portal The new experience follows the same simple model used by Azure Native integrations for other compute resources. From an Azure Native New Relic Service resource, customers can navigate to New Relic account config > Azure Kubernetes Services, select an eligible AKS cluster, and choose Install Extension. Azure then deploys the New Relic Kubernetes integration by using the AKS cluster extensions framework. After deployment completes, the portal displays the installation status for the cluster. Customers can return to the same experience to review the status or select Uninstall Extension when monitoring is no longer required. AKS cluster extensions provide an Azure Resource Manager-based approach for installing and managing services on AKS. This gives customers a consistent Azure control plane experience for deployment and lifecycle operations instead of requiring a separate, manual Helm installation for each cluster. Gain deeper visibility into Kubernetes workloads The extension deploys the New Relic Kubernetes integration to the selected AKS cluster. The integration provides visibility across Kubernetes infrastructure and workloads, including cluster, node, namespace, deployment, pod, and container health and performance. Depending on the enabled New Relic configuration, customers can also bring together Kubernetes events, logs, and Prometheus-formatted metrics with application and Azure platform telemetry in New Relic. This helps application, platform, and site reliability engineering teams investigate issues across the stack without stitching together disconnected views. Teams can use New Relic to: Understand resource consumption and health across clusters, nodes, pods, and containers. Identify unhealthy workloads, container restarts, and capacity constraints. Correlate Kubernetes infrastructure signals with application performance data. Explore Kubernetes entities and relationships through New Relic's cluster experience. Create dashboards, alerts, and operational workflows using telemetry from Azure and AKS. The result is a more direct path from detecting an issue to understanding its impact on applications and users. Reduce operational toil with unified telemetry For organizations operating multiple AKS clusters, consistency is as important as visibility. Manual installation can lead to configuration drift, missed clusters, and additional work whenever monitoring components need to be changed. The Azure Native New Relic Service experience helps address these challenges by providing: Simplified onboarding: Install the integration from the Azure portal without building a separate deployment workflow. Centralized visibility: Review AKS extension status alongside other Azure resources connected to New Relic. Azure governance alignment: Use Azure Resource Manager and Azure role-based access control as part of the management experience. Lifecycle management: Install or remove the extension through a consistent Azure workflow. Unified, full-stack observability: Connect AKS telemetry with application, infrastructure, log, and Azure platform data in New Relic. This experience is particularly useful for platform teams that want to make observability available as a standardized service while allowing development teams to use New Relic for troubleshooting and performance optimization. Get started To begin monitoring AKS with Azure Native New Relic Service: Either browse to the Marketplace offer listing or in the Azure portal, create an Azure Native New Relic Service resource. Go to New Relic account config > Azure Kubernetes Services. Select the AKS cluster that you want to monitor. Select Install Extension and then confirm the installation. After the status changes to Installed, open New Relic to explore your Kubernetes data and configure the dashboards and alerts appropriate for your environment. If you face any technical challenges do raise a support ticket and share your feedback.352Views0likes0Comments