.net
23 TopicsBuilding HIPAA-Compliant Medical Transcription with Local AI
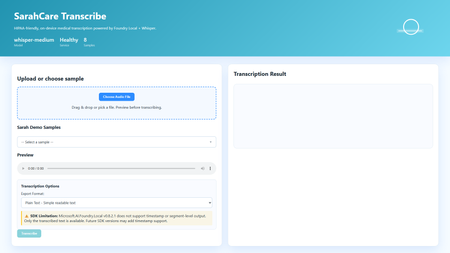
Building HIPAA-Compliant Medical Transcription with Local AI Introduction Healthcare organizations generate vast amounts of spoken content, patient consultations, research interviews, clinical notes, medical conferences. Transcribing these recordings traditionally requires either manual typing (time-consuming and expensive) or cloud transcription services (creating immediate HIPAA compliance concerns). Every audio file sent to external APIs exposes Protected Health Information (PHI), requires Business Associate Agreements, creates audit trails on third-party servers, and introduces potential breach vectors. This sample solution lies in on-premises voice-to-text systems that process audio entirely locally, never sending PHI beyond organizational boundaries. This article demonstrates building a sample medical transcription application using FLWhisper, ASP.NET Core, C#, and Microsoft Foundry Local with OpenAI Whisper models. You'll learn how to build sample HIPAA-compliant audio processing, integrate Whisper models for medical terminology accuracy, design privacy-first API patterns, and build responsive web UIs for healthcare workflows. Whether you're developing electronic health record (EHR) integrations, building clinical research platforms, or implementing dictation systems for medical practices, this sample could be a great starting point for privacy-first speech recognition. Why Local Transcription Is Critical for Healthcare Healthcare data handling is fundamentally different from general business data due to HIPAA regulations, state privacy laws, and professional ethics obligations. Understanding these requirements explains why cloud transcription services, despite their convenience, create unacceptable risks for medical applications. HIPAA compliance mandates strict controls over PHI. Every system that touches patient data must implement administrative, physical, and technical safeguards. Cloud transcription APIs require Business Associate Agreements (BAAs), but even with paperwork, you're entrusting PHI to external systems. Every API call creates logs on vendor servers, potentially in multiple jurisdictions. Data breaches at transcription vendors expose patient information, creating liability for healthcare organizations. On-premises processing eliminates these third-party risks entirely, PHI never leaves your controlled environment. US State laws increasingly add requirements beyond HIPAA. California's CCPA, New York's SHIELD Act, and similar legislation create additional compliance obligations. International regulations like GDPR prohibit transferring health data outside approved jurisdictions. Local processing simplifies compliance by keeping data within organizational boundaries. Research applications face even stricter requirements. Institutional Review Boards (IRBs) often require explicit consent for data sharing with external parties. Cloud transcription may violate study protocols that promise "no third-party data sharing." Clinical trials in pharmaceutical development handle proprietary information alongside PHI, double jeopardy for data exposure. Local transcription maintains research integrity while enabling audio analysis. Cost considerations favor local deployment at scale. Medical organizations generate substantial audio, thousands of patient encounters monthly. Cloud APIs charge per minute of audio, creating significant recurring costs. Local models have fixed infrastructure costs that scale economically. A modest GPU server can process hundreds of hours monthly at predictable expense. Latency matters for clinical workflows. Doctors and nurses need transcriptions available immediately after patient encounters to review and edit while details are fresh. Cloud APIs introduce network delays, especially problematic in rural health facilities with limited connectivity. Local inference provides <1 second turnaround for typical consultation lengths. Application Architecture: ASP.NET Core with Foundry Local The sample FLWhisper application implements clean separation between audio handling, AI inference, and state management using modern .NET patterns: The ASP.NET Core 10 minimal API provides HTTP endpoints for health checks, audio transcription, and sample file streaming. Minimal APIs reduce boilerplate while maintaining full middleware support for error handling, authentication, and CORS. The API design follows OpenAI's transcription endpoint specification, enabling drop-in replacement for existing integrations. The service layer encapsulates business logic: FoundryModelService manages model loading and lifetime, TranscriptionService handles audio processing and AI inference, and SampleAudioService provides demonstration files for testing. This separation enables easy testing, dependency injection, and service swapping. Foundry Local integration uses the Microsoft.AI.Foundry.Local.WinML SDK. Unlike cloud APIs requiring authentication and network calls, this SDK communicates directly with the local Foundry service via in-process calls. Models load once at startup, remaining resident in memory for sub-second inference on subsequent requests. The static file frontend delivers vanilla HTML/CSS/JavaScript, no framework overhead. This simplicity aids healthcare IT security audits and enables deployment on locked-down hospital networks. The UI provides file upload, sample selection, audio preview, transcription requests, and result display with copy-to-clipboard functionality. Here's the architectural flow for transcription requests: Web UI (Upload Audio File) ↓ POST /v1/audio/transcriptions (Multipart Form Data) ↓ ASP.NET Core API Route ↓ TranscriptionService.TranscribeAudio(audioStream) ↓ Foundry Local Model (Whisper Medium locally) ↓ Text Result + Metadata (language, duration) ↓ Return JSON/Text Response ↓ Display in UI This architecture embodies several healthcare system design principles: Data never leaves the device: All processing occurs on-premises, no external API calls No data persistence by default: Audio and transcripts are session-only, never saved unless explicitly configured Comprehensive health checks: System readiness verification before accepting PHI Audit logging support: Structured logging for compliance documentation Graceful degradation: Clear error messages when models unavailable rather than silent failures Setting Up Foundry Local with Whisper Models Foundry Local supports multiple Whisper model sizes, each with different accuracy/speed tradeoffs. For medical transcription, accuracy is paramount—misheard drug names or dosages create patient safety risks: # Install Foundry Local (Windows) winget install Microsoft.FoundryLocal # Verify installation foundry --version # Download Whisper Medium model (optimal for medical accuracy) foundry model add openai-whisper-medium-generic-cpu:1 # Check model availability foundry model list Whisper Medium (769M parameters) provides the best balance for medical use. Smaller models (Tiny, Base) miss medical terminology frequently. Larger models (Large) offer marginal accuracy gains at 3x inference time. Medium handles medical vocabulary well, drug names, anatomical terms, procedure names, while processing typical consultation audio (5-10 minutes) in under 30 seconds. The application detects and loads the model automatically: // Services/FoundryModelService.cs using Microsoft.AI.Foundry.Local.WinML; public class FoundryModelService { private readonly ILogger _logger; private readonly FoundryOptions _options; private ILocalAIModel? _loadedModel; public FoundryModelService( ILogger logger, IOptions options) { _logger = logger; _options = options.Value; } public async Task InitializeModelAsync() { try { _logger.LogInformation( "Loading Foundry model: {ModelAlias}", _options.ModelAlias ); // Load model from Foundry Local _loadedModel = await FoundryClient.LoadModelAsync( modelAlias: _options.ModelAlias, cancellationToken: CancellationToken.None ); if (_loadedModel == null) { _logger.LogWarning("Model loaded but returned null instance"); return false; } _logger.LogInformation( "Successfully loaded model: {ModelAlias}", _options.ModelAlias ); return true; } catch (Exception ex) { _logger.LogError( ex, "Failed to load Foundry model: {ModelAlias}", _options.ModelAlias ); return false; } } public ILocalAIModel? GetLoadedModel() => _loadedModel; public async Task UnloadModelAsync() { if (_loadedModel != null) { await FoundryClient.UnloadModelAsync(_loadedModel); _loadedModel = null; _logger.LogInformation("Model unloaded"); } } } Configuration lives in appsettings.json , enabling easy customization without code changes: { "Foundry": { "ModelAlias": "whisper-medium", "LogLevel": "Information" }, "Transcription": { "MaxAudioDurationSeconds": 300, "SupportedFormats": ["wav", "mp3", "m4a", "flac"], "DefaultLanguage": "en" } } Implementing Privacy-First Transcription Service The transcription service handles audio processing while maintaining strict privacy controls. No audio or transcript persists beyond the HTTP request lifecycle unless explicitly configured: // Services/TranscriptionService.cs public class TranscriptionService { private readonly FoundryModelService _modelService; private readonly ILogger _logger; public async Task TranscribeAudioAsync( Stream audioStream, string originalFileName, TranscriptionOptions? options = null) { options ??= new TranscriptionOptions(); var startTime = DateTime.UtcNow; try { // Validate audio format ValidateAudioFormat(originalFileName); // Get loaded model var model = _modelService.GetLoadedModel(); if (model == null) { throw new InvalidOperationException("Whisper model not loaded"); } // Create temporary file (automatically deleted after transcription) using var tempFile = new TempAudioFile(audioStream); // Execute transcription _logger.LogInformation( "Starting transcription for file: {FileName}", originalFileName ); var transcription = await model.TranscribeAsync( audioFilePath: tempFile.Path, language: options.Language, cancellationToken: CancellationToken.None ); var duration = (DateTime.UtcNow - startTime).TotalSeconds; _logger.LogInformation( "Transcription completed in {Duration:F2}s", duration ); return new TranscriptionResult { Text = transcription.Text, Language = transcription.Language ?? options.Language, Duration = transcription.AudioDuration, ProcessingTimeSeconds = duration, FileName = originalFileName, Timestamp = DateTime.UtcNow }; } catch (Exception ex) { _logger.LogError( ex, "Transcription failed for file: {FileName}", originalFileName ); throw; } } private void ValidateAudioFormat(string fileName) { var extension = Path.GetExtension(fileName).TrimStart('.'); var supportedFormats = new[] { "wav", "mp3", "m4a", "flac", "ogg" }; if (!supportedFormats.Contains(extension.ToLowerInvariant())) { throw new ArgumentException( $"Unsupported audio format: {extension}. " + $"Supported: {string.Join(", ", supportedFormats)}" ); } } } // Temporary file wrapper that auto-deletes internal class TempAudioFile : IDisposable { public string Path { get; } public TempAudioFile(Stream sourceStream) { Path = System.IO.Path.GetTempFileName(); using var fileStream = File.OpenWrite(Path); sourceStream.CopyTo(fileStream); } public void Dispose() { try { if (File.Exists(Path)) { File.Delete(Path); } } catch { // Ignore deletion errors in temp folder } } } This service demonstrates several privacy-first patterns: Temporary file lifecycle management: Audio written to temp storage, automatically deleted after transcription No implicit persistence: Results returned to caller, not saved by service Format validation: Accept only supported audio formats to prevent processing errors Comprehensive logging: Audit trail for compliance without logging PHI content Error isolation: Exceptions contain diagnostic info but no patient data Building the OpenAI-Compatible REST API The API endpoint mirrors OpenAI's transcription API specification, enabling existing integrations to work without modifications: // Program.cs var builder = WebApplication.CreateBuilder(args); // Configure services builder.Services.Configure( builder.Configuration.GetSection("Foundry") ); builder.Services.AddSingleton(); builder.Services.AddScoped(); builder.Services.AddHealthChecks() .AddCheck("foundry-health"); var app = builder.Build(); // Load model at startup var modelService = app.Services.GetRequiredService(); await modelService.InitializeModelAsync(); app.UseHealthChecks("/health"); app.MapHealthChecks("/api/health/status"); // OpenAI-compatible transcription endpoint app.MapPost("/v1/audio/transcriptions", async ( HttpRequest request, TranscriptionService transcriptionService, ILogger logger) => { if (!request.HasFormContentType) { return Results.BadRequest(new { error = "Content-Type must be multipart/form-data" }); } var form = await request.ReadFormAsync(); // Extract audio file var audioFile = form.Files.GetFile("file"); if (audioFile == null || audioFile.Length == 0) { return Results.BadRequest(new { error = "Audio file required in 'file' field" }); } // Parse options var format = form["format"].ToString() ?? "text"; var language = form["language"].ToString() ?? "en"; try { // Process transcription using var stream = audioFile.OpenReadStream(); var result = await transcriptionService.TranscribeAudioAsync( audioStream: stream, originalFileName: audioFile.FileName, options: new TranscriptionOptions { Language = language } ); // Return in requested format if (format == "json") { return Results.Json(new { text = result.Text, language = result.Language, duration = result.Duration }); } else { // Default: plain text return Results.Text(result.Text); } } catch (Exception ex) { logger.LogError(ex, "Transcription request failed"); return Results.StatusCode(500); } }) .DisableAntiforgery() // File uploads need CSRF exemption .WithName("TranscribeAudio") .WithOpenApi(); app.Run(); Example API usage: # PowerShell $audioFile = Get-Item "consultation-recording.wav" $response = Invoke-RestMethod ` -Uri "http://localhost:5192/v1/audio/transcriptions" ` -Method Post ` -Form @{ file = $audioFile; format = "json" } Write-Output $response.text # cURL curl -X POST http://localhost:5192/v1/audio/transcriptions \ -F "file=@consultation-recording.wav" \ -F "format=json" Building the Interactive Web Frontend The web UI provides a user-friendly interface for non-technical medical staff to transcribe recordings: SarahCare Medical Transcription The JavaScript handles file uploads and API interactions: // wwwroot/app.js let selectedFile = null; async function checkHealth() { try { const response = await fetch('/health'); const statusEl = document.getElementById('status'); if (response.ok) { statusEl.className = 'status-badge online'; statusEl.textContent = '✓ System Ready'; } else { statusEl.className = 'status-badge offline'; statusEl.textContent = '✗ System Unavailable'; } } catch (error) { console.error('Health check failed:', error); } } function handleFileSelect(event) { const file = event.target.files[0]; if (!file) return; selectedFile = file; // Show file info const fileInfo = document.getElementById('fileInfo'); fileInfo.textContent = `Selected: ${file.name} (${formatFileSize(file.size)})`; fileInfo.classList.remove('hidden'); // Enable audio preview const preview = document.getElementById('audioPreview'); preview.src = URL.createObjectURL(file); preview.classList.remove('hidden'); // Enable transcribe button document.getElementById('transcribeBtn').disabled = false; } async function transcribeAudio() { if (!selectedFile) return; const loadingEl = document.getElementById('loadingIndicator'); const resultEl = document.getElementById('resultSection'); const transcribeBtn = document.getElementById('transcribeBtn'); // Show loading state loadingEl.classList.remove('hidden'); resultEl.classList.add('hidden'); transcribeBtn.disabled = true; try { const formData = new FormData(); formData.append('file', selectedFile); formData.append('format', 'json'); const startTime = Date.now(); const response = await fetch('/v1/audio/transcriptions', { method: 'POST', body: formData }); if (!response.ok) { throw new Error(`HTTP ${response.status}: ${response.statusText}`); } const result = await response.json(); const processingTime = ((Date.now() - startTime) / 1000).toFixed(1); // Display results document.getElementById('transcriptionText').value = result.text; document.getElementById('resultDuration').textContent = `Duration: ${result.duration.toFixed(1)}s`; document.getElementById('resultLanguage').textContent = `Language: ${result.language}`; resultEl.classList.remove('hidden'); console.log(`Transcription completed in ${processingTime}s`); } catch (error) { console.error('Transcription failed:', error); alert(`Transcription failed: ${error.message}`); } finally { loadingEl.classList.add('hidden'); transcribeBtn.disabled = false; } } function copyToClipboard() { const text = document.getElementById('transcriptionText').value; navigator.clipboard.writeText(text) .then(() => alert('Copied to clipboard')) .catch(err => console.error('Copy failed:', err)); } // Initialize window.addEventListener('load', () => { checkHealth(); loadSamplesList(); }); Key Takeaways and Production Considerations Building HIPAA-compliant voice-to-text systems requires architectural decisions that prioritize data privacy over convenience. The FLWhisper application demonstrates that you can achieve accurate medical transcription, fast processing times, and intuitive user experiences entirely on-premises. Critical lessons for healthcare AI: Privacy by architecture: Design systems where PHI never exists outside controlled environments, not as a configuration option No persistence by default: Audio and transcripts should be ephemeral unless explicitly saved with proper access controls Model selection matters: Whisper Medium provides medical terminology accuracy that smaller models miss Health checks enable reliability: Systems should verify model availability before accepting PHI Audit logging without content logging: Track operations for compliance without storing sensitive data in logs For production deployment in clinical settings, integrate with EHR systems via HL7/FHIR interfaces. Implement role-based access control with Active Directory integration. Add digital signatures for transcript authentication. Configure automatic PHI redaction using clinical NLP models. Deploy on HIPAA-compliant infrastructure with proper physical security. Implement comprehensive audit logging meeting compliance requirements. The complete implementation with ASP.NET Core API, Foundry Local integration, sample audio files, and comprehensive tests is available at github.com/leestott/FLWhisper. Clone the repository and follow the setup guide to experience privacy-first medical transcription. Resources and Further Reading FLWhisper Repository - Complete C# implementation with .NET 10 Quick Start Guide - Installation and usage instructions Microsoft Foundry Local Documentation - SDK reference and model catalog OpenAI Whisper Documentation - Model architecture and capabilities HIPAA Compliance Guidelines - HHS official guidance Testing Guide - Comprehensive test suite documentationAgents League: The Esports-Inspired Hackathon Where AI Agents Battle for Glory
Ready to put your AI skills to the ultimate test? Agents League is here, a dynamic, esports-inspired developer challenge that brings the thrill of live competition to the world of agentic AI. Whether you're a seasoned AI developer or just getting started, this is your chance to build, compete, and win. What is Agents League? Agents League is a week-long hackathon running as part of AI Skills Fest (June 4–14, 2026). Unlike traditional hackathons, Agents League combines live AI coding battles, asynchronous project submissions, and a thriving Discord community all competing for a total prize pool of $55,000 USD. This isn't just about building it's about showcasing what's possible with agentic AI in a format that's fast, competitive, and globally accessible. Three Challenge Tracks Pick One or Compete in All 1. Creative Apps Build innovative applications using GitHub Copilot for AI-assisted development. Show off your creativity and demonstrate how AI can accelerate app creation from concept to code. 2. Reasoning Agents Create intelligent agents using Microsoft Foundry that solve complex problems through multi-step reasoning. This track is all about building agents that can think, plan, and execute. 3. Enterprise Agents Build business-ready knowledge agents integrated with Microsoft 365 Copilot, authored in Copilot Studio. Perfect for developers focused on real-world enterprise solutions. Live Microsoft Reactor Events—Don't Miss the Battles! The heart of Agents League beats through live Microsoft Reactor events. Watch experts go head-to-head in live coding battles, learn cutting-edge techniques, and get inspired for your own submissions: Event What You'll Learn Creative Apps Battle See GitHub Copilot in action as experts build innovative apps live Reasoning Agents Battle Watch multi-step reasoning agents come to life with Microsoft Foundry Enterprise Agents Battle Learn to build M365-integrated agents with Copilot Studio 👉 View the full event series Key Dates Registration Deadline: June 12, 2026, 12:00 PM PT Hacking Period: June 4–14, 2026 Submission Deadline: June 14, 2026, 11:59 PM PT What You Get Live coding battles with expert demonstrations Curated technical experiences and on-demand content Learning resources on Microsoft Learn and AI Skills Navigator Community support through Discord GitHub-based submissions for transparent, collaborative judging Why Participate? Agents League isn't just another hackathon. It's designed as a streamlined, competitive format that: ✅ Fits into your schedule with focused, time-boxed challenges ✅ Provides real-world product innovation experience ✅ Offers global accessibility—participate from anywhere ✅ Demonstrates the latest capabilities of agentic AI, including new IQ tools ✅ Connects you with a passionate developer community Ready to Enter the Arena? Register Now for Agents League Before you register: Review the Hackathon Rules and Regulations for prize categories and judging criteria Join the Microsoft Reactor event series for live battles and learning Check out the Microsoft Event Code of Conduct Join the Conversation Have questions? Want to connect with fellow competitors? Join the Agents League community on Discord and start strategizing with developers from around the world. Whether you're building creative apps, reasoning agents, or enterprise solutions—the arena awaits. May the best agent win! 🏆 Agents League hackathon is open to the public and offered at no cost. Government employees should check with their employers to ensure participation is permitted in accordance with applicable policies. Related Links: Agents League Hackathon Registration Microsoft Reactor Series AI Skills FestMastering Query Fields in Azure AI Document Intelligence with C#
Introduction Azure AI Document Intelligence simplifies document data extraction, with features like query fields enabling targeted data retrieval. However, using these features with the C# SDK can be tricky. This guide highlights a real-world issue, provides a corrected implementation, and shares best practices for efficient usage. Use case scenario During the cause of Azure AI Document Intelligence software engineering code tasks or review, many developers encountered an error while trying to extract fields like "FullName," "CompanyName," and "JobTitle" using `AnalyzeDocumentAsync`: The error might be similar to Inner Error: The parameter urlSource or base64Source is required. This is a challenge referred to as parameter errors and SDK changes. Most problematic code are looks like below in C#: BinaryData data = BinaryData.FromBytes(Content); var queryFields = new List<string> { "FullName", "CompanyName", "JobTitle" }; var operation = await client.AnalyzeDocumentAsync( WaitUntil.Completed, modelId, data, "1-2", queryFields: queryFields, features: new List<DocumentAnalysisFeature> { DocumentAnalysisFeature.QueryFields } ); One of the reasons this failed was that the developer was using `Azure.AI.DocumentIntelligence v1.0.0`, where `base64Source` and `urlSource` must be handled internally. Because the older examples using `AnalyzeDocumentContent` no longer apply and leading to errors. Practical Solution Using AnalyzeDocumentOptions. Alternative Method using manual JSON Payload. Using AnalyzeDocumentOptions The correct method involves using AnalyzeDocumentOptions, which streamlines the request construction using the below steps: Prepare the document content: BinaryData data = BinaryData.FromBytes(Content); Create AnalyzeDocumentOptions: var analyzeOptions = new AnalyzeDocumentOptions(modelId, data) { Pages = "1-2", Features = { DocumentAnalysisFeature.QueryFields }, QueryFields = { "FullName", "CompanyName", "JobTitle" } }; - `modelId`: Your trained model’s ID. - `Pages`: Specify pages to analyze (e.g., "1-2"). - `Features`: Enable `QueryFields`. - `QueryFields`: Define which fields to extract. Run the analysis: Operation<AnalyzeResult> operation = await client.AnalyzeDocumentAsync( WaitUntil.Completed, analyzeOptions ); AnalyzeResult result = operation.Value; The reason this works: The SDK manages `base64Source` automatically. This approach matches the latest SDK standards. It results in cleaner, more maintainable code. Alternative method using manual JSON payload For advanced use cases where more control over the request is needed, you can manually create the JSON payload. For an example: var queriesPayload = new { queryFields = new[] { new { key = "FullName" }, new { key = "CompanyName" }, new { key = "JobTitle" } } }; string jsonPayload = JsonSerializer.Serialize(queriesPayload); BinaryData requestData = BinaryData.FromString(jsonPayload); var operation = await client.AnalyzeDocumentAsync( WaitUntil.Completed, modelId, requestData, "1-2", features: new List<DocumentAnalysisFeature> { DocumentAnalysisFeature.QueryFields } ); When to use the above: Custom request formats Non-standard data source integration Key points to remember Breaking changes exist between preview versions and v1.0.0 by checking the SDK version. Prefer `AnalyzeDocumentOptions` for simpler, error-free integration by using built-In classes. Ensure your content is wrapped in `BinaryData` or use a direct URL for correct document input: Conclusion Using AnalyzeDocumentOptions provides a cleaner and more reliable way to work with query fields in Azure AI Document Intelligence using C#. By aligning with the latest SDK approach, developers can simplify implementation, reduce common errors, and improve code maintainability. Keeping up with SDK enhancements and recommended practices ensures more accurate and efficient document data extraction. As Azure AI capabilities continue to evolve, adopting modern integration patterns will help you build scalable and future-ready document processing solutions with greater confidence. Reference Official AnalyzeDocumentAsync Documentation. Official Azure SDK documentation. Azure Document Intelligence C# SDK support add-on query field.705Views0likes0Comments
Performance Tuning Cold Starts, Scaling Delays, and Startup Latency in Azure Container Apps
Introduction There is a particular kind of frustration that comes not when your application fails to start, but when it starts too slowly. The container is running, the health probes pass, your monitoring shows green — and yet every few minutes a user somewhere in the world hits a request that takes 15 seconds to respond. Your support team starts getting tickets. Your SLA dashboard turns amber. This is the cold start problem, and it is one of the most widely discussed pain points with any serverless container platform. Azure Container Apps is no different. But what most engineers do not realize is that the cold start is only one part of the story. Scaling delays, inefficient image layers, wrong resource allocations, and misconfigured KEDA rules all compound to create latency spikes that feel indistinguishable from cold starts but have completely different root causes and fixes. In this part of the series, we break down each cause systematically and show you exactly how to address it. Understanding What "Cold Start" Actually Means in Container Apps Before we fix anything, it helps to understand what is actually happening during a cold start. When a new replica is created, Azure Container Apps needs to do several things in sequence before your application can serve a single request: The platform schedules the new replica on available infrastructure. The container runtime pulls the image layers that are not already cached on that node. The container starts and the process inside it begins executing. Your application framework initializes (the .NET DI container, Django's ORM layer, loaded ML models, etc.). The readiness probe passes, signaling that the replica can accept traffic. Every one of these steps takes time. The total duration is your cold start latency. When you have `minReplicas: 0`, this full cycle happens for every "first request after idle" scenario. With `minReplicas: 1`, steps 1 and 2 are already done, but steps 3–5 still happen whenever a new replica is created due to scaling out. Scenario 1: Requests Spike to 10+ Seconds After a Period of Inactivity What You See Everything looks fine during load testing, but the next morning after a quiet night, the first user to hit the app gets a timeout or a very slow response. You check your Application Insights or Log Analytics and you see exactly one request with a dramatically higher duration than all the others. Why This Happens You have `minReplicas` set to `0` (or it defaults to 0). When there are no replicas running and a new request arrives, the entire cold start sequence kicks off — and the request waits in the ingress queue the entire time. Depending on your image size and application initialization time, this can easily reach 15–30 seconds for a .NET application with a large DI graph, or even longer for a Python application that imports heavy libraries. The Fix Option A (Recommended for most workloads): Set `minReplicas` to 1. This ensures at least one replica is always warm and ready to handle requests. You will pay for that one replica's compute even during idle periods, but you eliminate the cold start for your users: az containerapp update --name my-dotnet-api --resource-group my-rg --min-replicas 1 --max-replicas 10 Or in your Container App YAML: scale: minReplicas: 1 maxReplicas: 10 rules: - name: http-scaling-rule http: metadata: concurrentRequests: "10" Option B: Reduce image size to speed up the pull. Every megabyte in your container image adds time to cold starts. A production .NET API should not be a 2 GB image. Use multi-stage builds to strip away the SDK, test tools, and development dependencies: # Stage 1: Build FROM mcr.microsoft.com/dotnet/sdk:8.0 AS build WORKDIR /src COPY ["MyApp.csproj", "."] RUN dotnet restore COPY . . RUN dotnet publish -c Release -o /app/publish --no-restore # Stage 2: Runtime only - much smaller FROM mcr.microsoft.com/dotnet/aspnet:8.0 AS final WORKDIR /app COPY --from=build /app/publish . # Run as non-root for security USER app EXPOSE 8080 ENTRYPOINT ["dotnet", "MyApp.dll"] For Django, the equivalent pattern is: FROM python:3.11-slim AS base # Install only production dependencies WORKDIR /app COPY requirements.txt . RUN pip install --no-cache-dir -r requirements.txt && find /usr/local -name "*.pyc" -delete && find /usr/local -name "__pycache__" -type d -exec rm -rf {} + 2>/dev/null || true COPY . . RUN SECRET_KEY=placeholder python manage.py collectstatic --noinput USER nobody EXPOSE 8000 CMD ["gunicorn", "myproject.wsgi:application", "--bind", "0.0.0.0:8000", "--workers", "2"] Option C: Use a startup probe to manage the readiness window. If your app genuinely needs 20–30 seconds to initialize (loading configuration, warming caches, establishing connection pools), configure a startup probe separately from your liveness probe. This gives the container time to start without the liveness probe killing it prematurely: probes: - type: Startup httpGet: path: /health port: 8080 initialDelaySeconds: 5 periodSeconds: 5 failureThreshold: 12 # 12 * 5s = 60 seconds total window - type: Liveness httpGet: path: /health port: 8080 periodSeconds: 10 failureThreshold: 3 - type: Readiness httpGet: path: /health/ready port: 8080 periodSeconds: 5 failureThreshold: 3 Scenario 2: New Replicas Lag Behind Traffic Spikes What You See Your application handles steady traffic just fine. Then a sudden burst arrives — a marketing email goes out, a scheduled batch job triggers API calls, or a downstream system fires webhooks — and for 30–60 seconds your error rate jumps and your latency spikes. After that window, everything recovers. The scaling logs show new replicas were created, but they came online too late. Why This Happens KEDA (the scaling engine behind Container Apps) works reactively. By default, HTTP-based scaling triggers new replicas when concurrent requests exceed the configured threshold. But there is an inherent delay between the moment traffic spikes, the moment KEDA detects it, and the moment a new replica is warm and serving traffic. This window is where your users experience the pain. Additionally, if your image pull takes a long time (large image, first pull on a new node), the new replica arrives even later. KEDA cannot compensate for slow image pulls. The Fix Step 1 — Tune your KEDA scaling rules to trigger earlier. Rather than waiting until you are already at capacity, configure scaling to trigger with a lower concurrency threshold. If your app can handle 20 concurrent requests comfortably, set the threshold to 10 so new replicas spin up before you are overwhelmed: scale: minReplicas: 1 maxReplicas: 20 rules: - name: http-rule http: metadata: concurrentRequests: "10" # Scale earlier, not at capacity For Azure Service Bus or Event Hubs-triggered scaling (common in job-style workloads), use a queue length threshold that gives you a buffer: scale: minReplicas: 0 maxReplicas: 30 rules: - name: servicebus-rule custom: type: azure-servicebus metadata: queueName: my-processing-queue namespace: my-servicebus-namespace messageCount: "5" # Scale when queue depth reaches 5, not 100 auth: - secretRef: servicebus-connection triggerParameter: connection Step 2 — Pre-warm your connection pools in .NET. One of the biggest contributors to new replica slowness is the time spent establishing database connections and other external connections. The first request that hits a new replica bears the cost of opening the connection pool. Configure your connection pool to warm up eagerly at startup: // In Program.cs, after building the app if (app.Environment.IsProduction()) { // Warm up the database connection pool before accepting traffic using var scope = app.Services.CreateScope(); var dbContext = scope.ServiceProvider.GetRequiredService<AppDbContext>(); await dbContext.Database.ExecuteSqlRawAsync("SELECT 1"); } await app.RunAsync(); Step 3 — Enable HTTP/2 keep-alive and connection reuse. In .NET applications running behind the Container Apps ingress, configure your HTTP client to use connection pooling properly: builder.Services.AddHttpClient("downstream-api", client => { client.BaseAddress = new Uri("https://my-downstream-service"); client.DefaultRequestVersion = new Version(2, 0); }) .ConfigurePrimaryHttpMessageHandler(() => new SocketsHttpHandler { PooledConnectionLifetime = TimeSpan.FromMinutes(5), PooledConnectionIdleTimeout = TimeSpan.FromMinutes(2), MaxConnectionsPerServer = 20 }); Scenario 3: Django Startup Is Slow Due to Import Time What You See Your Django application takes 8–12 seconds to start even on a warm node. You check the Gunicorn startup logs and see it spending most of that time in Python module imports before it ever processes a request. Why This Happens Python's import system is synchronous and single-threaded. When you import `django`, `rest_framework`, `pandas`, `numpy`, or any large library, Python reads and executes every module file in the dependency chain. A Django project with Django REST Framework, Celery, and a few third-party packages can easily spend 5–8 seconds just on imports. Multiply that by the number of Gunicorn workers (each is a separate process that imports everything independently) and startup time balloons. The Fix Step 1 — Profile import time to find the worst offenders. Add this to your Dockerfile's entrypoint or run it manually: # Run this in a container shell to see which imports take the longest python -X importtime -c "import django; django.setup()" 2>&1 | sort -k2 -rn | head -20 Step 2 — Use lazy imports for heavy dependencies that are not needed at startup. Instead of importing everything at the module level, defer imports to the functions that actually need them: # Instead of this at the top of your file: import pandas as pd import numpy as np # Do this — import only when the function is actually called: def process_data(data): import pandas as pd import numpy as np df = pd.DataFrame(data) return df.describe().to_dict() Step 3 — Reduce Gunicorn worker count for memory-constrained environments. Having too many workers means too many independent Python processes all importing everything at the same time. For Container Apps with 0.5–1 vCPU, 2 workers is usually the right starting point: CMD ["gunicorn", "myproject.wsgi:application", "--bind", "0.0.0.0:8000", "--workers", "2", "--worker-class", "gthread", "--threads", "4", "--timeout", "120", "--keep-alive", "5", "--log-level", "info"] Step 4 — Consider switching from Gunicorn to Uvicorn for async Django. If you are on Django 4.x with ASGI support, Uvicorn with async workers can handle significantly more concurrent requests per worker than synchronous Gunicorn workers: CMD ["uvicorn", "myproject.asgi:application", "--host", "0.0.0.0", "--port", "8000", "--workers", "2", "--log-level", "info"] Scenario 4: Resource Limits Are Causing Throttling and Slow Responses What You See Your application starts fine and handles light traffic well, but under moderate to heavy load — even well below your max replicas — individual requests become slow and CPU metrics show your replicas running near 100% utilization. You may also see the .NET GC (garbage collector) running very frequently, or Django showing slow database queries that are actually fast queries being delayed because the process has no CPU to run. Why This Happens Container Apps defaults to 0.25 vCPU and 0.5 Gi memory if you do not specify resource limits. For a production .NET API or a Django application serving real traffic, this is almost always too little. When a container hits its CPU limit, the container runtime throttles it — the process continues to run but gets less CPU time, making everything slower without any obvious error signal. The Fix Step 1 — Measure actual resource usage before guessing. Query Log Analytics for actual CPU and memory usage to establish a baseline: ContainerAppSystemLogs_CL | where ContainerAppName_s == "my-dotnet-api" | where TimeGenerated > ago(7d) | summarize AvgCpuUsage = avg(todouble(CpuUsageNanoCores_d)) / 1000000, MaxCpuUsage = max(todouble(CpuUsageNanoCores_d)) / 1000000, AvgMemoryMB = avg(todouble(MemoryWorkingSetBytes_d)) / 1048576, MaxMemoryMB = max(todouble(MemoryWorkingSetBytes_d)) / 1048576 by bin(TimeGenerated, 1h) | order by TimeGenerated desc Step 2 — Update resource allocations based on what you observed. az containerapp update --name my-dotnet-api --resource-group my-rg --cpu 0.5 --memory 1.0Gi Container Apps has specific valid CPU/memory combinations. The valid pairs are: `0.25 vCPU / 0.5 Gi`, `0.5 vCPU / 1.0 Gi`, `0.75 vCPU / 1.5 Gi`, `1.0 vCPU / 2.0 Gi`, and up to `4.0 vCPU / 8.0 Gi`. You cannot mix arbitrary values. Step 3 — Configure .NET GC for server workloads. By default, .NET uses the workstation GC mode which is tuned for interactive applications. For server containers, use server GC mode and configure the heap size appropriately: // In runtimeconfig.template.json or via environment variables { "configProperties": { "System.GC.Server": true, "System.GC.HeapHardLimit": 805306368, "System.GC.HighMemoryPercent": 75 } } Or as environment variables in your Container App: az containerapp update --name my-dotnet-api --resource-group my-rg --set-env-vars "DOTNET_GCConserveMemory=5" "DOTNET_GCHeapHardLimit=805306368" Measuring the Impact of Your Changes After making changes, use this Log Analytics query to track your startup times over the past 24 hours and confirm the improvements: ContainerAppConsoleLogs_CL | where ContainerAppName_s == "my-dotnet-api" | where Log_s contains "Application started" or Log_s contains "Now listening on" | project TimeGenerated, Log_s, ContainerName_s | order by TimeGenerated desc And check request duration percentiles in Application Insights: requests | where cloud_RoleName == "my-dotnet-api" | where timestamp > ago(24h) | summarize p50 = percentile(duration, 50), p90 = percentile(duration, 90), p99 = percentile(duration, 99), count = count() by bin(timestamp, 1h) | order by timestamp desc Summary: Your Performance Tuning Quick Reference Here is a quick decision guide based on what you are seeing: Symptom Most Likely Cause First Fix to Try First request after idle is very slow `minReplicas: 0` Set `minReplicas: 1` Spike period has errors, then recovers KEDA scaling too slow Lower concurrentRequests threshold New replicas start slowly Large image size Multi-stage Docker build High CPU at moderate traffic Under-allocated resources Increase CPU/memory allocation Django startup is slow Heavy Python imports Profile and defer imports .NET app slow under load Workstation GC mode Enable server GC References and Sample Resources Use these links to tune startup performance, scaling behavior, and runtime efficiency. Azure Container Apps docs (core) Scale applications in Azure Container Apps Workload profiles overview Health probes in Azure Container Apps Revisions in Azure Container Apps Monitoring and logging in Azure Container Apps Runtime and framework performance references Docker multi-stage builds .NET performance best practices for ASP.NET Core .NET runtime GC configuration Django performance optimization Uvicorn deployment guide Scaling engine references and samples KEDA concepts and documentation KEDA scaler samples Azure Samples: .NET on Azure Container Apps Azure Samples: Python on Azure Container Apps What's Next In Part 3, we go deeper into the most specialized and complex scenario in this series: troubleshooting AI workloads in Azure Container Apps. Loading large ML models, managing GPU and CPU resource constraints, and dealing with memory pressure from inference workloads all require techniques that go beyond standard web application troubleshooting. Part of the series: Troubleshooting Azure Container Apps in Production Next: Part 3 — Troubleshooting ML Model Loading, GPU Issues, and Memory Pressure in Azure Container AppsTroubleshooting Azure Container Apps and Jobs for .NET and Django Workloads
Introduction Deploying to Azure Container Apps feels like a huge step forward — you get serverless containers, automatic scaling, built-in ingress, and managed environments without managing Kubernetes directly. But when something goes wrong and your container refuses to start, or your Container App Job silently fails, it can feel like debugging inside a black box. This first part of our four-part series walks through the most common deployment and startup failures you will hit when running .NET and Django applications on Azure Container Apps and Container App Jobs. We cover what the real error looks like, why it is happening under the hood, and what you need to do to fix it — step by step. The Real-World Problem: "My Container App is stuck in a restart loop and I have no idea why" This is probably the most common thing engineers report when they first move workloads to Azure Container Apps. The deployment finishes successfully, the revision shows as active, but the app never becomes healthy. In the Azure portal it cycles between `Running` and `Degraded`, and in the logs you see cryptic exit codes or — even worse — nothing at all. The root causes almost always fall into one of these buckets: The container exits immediately because the process crashes on startup (misconfiguration, missing secrets, unhandled exceptions). The health probe fails because the app takes too long to start or is listening on the wrong port. A Container App Job never completes because it times out or the job process exits with a non-zero code. Let us walk through each of these in detail. Scenario 1: Your .NET Application Crashes at Startup What You See Your Container App revision goes into a restart loop. You check the Log Analytics workspace and see something like this: ContainerAppConsoleLogs_CL | where ContainerAppName_s == "my-dotnet-api" | where TimeGenerated > ago(30m) | project TimeGenerated, Log_s | order by TimeGenerated desc The output shows: Unhandled exception. System.InvalidOperationException: Unable to resolve service for type 'MyApp.Data.AppDbContext' at Microsoft.Extensions.DependencyInjection.ServiceProviderServiceExtensions.GetRequiredService ... Application is shutting down. Or even more commonly with Entity Framework Core: fail: Microsoft.EntityFrameworkCore.Database.Connection An error occurred using the connection to database 'mydb' on server 'myserver.database.windows.net'. System.Net.Sockets.SocketException: Connection refused Why This Happens When .NET 6+ applications start up, they run the entire `WebApplication.Build()` pipeline before accepting traffic. If any registered service — like a database context — cannot be constructed or if the connection string is missing or wrong, the application throws an unhandled exception and the process exits with a non-zero code. Container Apps detects this exit and restarts the container. This cycle repeats indefinitely. The most frequent trigger is missing or incorrectly named environment variables and secrets. In local development you rely on `appsettings.Development.json` or `user secrets`, but in Container Apps those files are not present unless you explicitly copy them into the image (which you should never do for secrets). Step-by-Step Fix Step 1 — Verify your secrets and environment variables are configured correctly. In the Azure portal, navigate to your Container App → Configuration → Secrets and Environment variables. Make sure every value your app reads from IConfiguration is defined here. From the CLI you can inspect and update them like this: # Add or update a secret reference az containerapp secret set --name my-dotnet-api --resource-group my-rg --secrets "connectionstring=Server=myserver.database.windows.net;..." # Reference that secret as an environment variable az containerapp update --name my-dotnet-api --resource-group my-rg --set-env-vars "ConnectionStrings__DefaultConnection=secretref:connectionstring" Step 2 — Make sure your .NET app reads configuration correctly. The naming convention that trips up almost everyone: Azure Container Apps uses double underscores (`__`) to represent the colon (`:`) separator in .NET configuration keys. So `ConnectionStrings:DefaultConnection` becomes `ConnectionStrings__DefaultConnection` as the environment variable name. // This reads from "ConnectionStrings__DefaultConnection" env var automatically builder.Services.AddDbContext<AppDbContext>(options => options.UseSqlServer(builder.Configuration.GetConnectionString("DefaultConnection"))); Step 3 — Add a startup health check that gives meaningful feedback. Configure a liveness probe with a generous initial delay to avoid a container being killed before it has had time to start: # In your Container App YAML configuration probes: - type: Liveness httpGet: path: /health port: 8080 initialDelaySeconds: 30 periodSeconds: 10 failureThreshold: 5 - type: Readiness httpGet: path: /health/ready port: 8080 initialDelaySeconds: 15 periodSeconds: 5 failureThreshold: 3 Add the corresponding health endpoint in your .NET app: // Program.cs builder.Services.AddHealthChecks() .AddSqlServer( builder.Configuration.GetConnectionString("DefaultConnection")!, name: "database", tags: new[] { "ready" }); app.MapHealthChecks("/health"); app.MapHealthChecks("/health/ready", new HealthCheckOptions { Predicate = check => check.Tags.Contains("ready") }); Step 4 — Pull the raw container logs using the CLI to see exactly what happened before the container exited: az containerapp logs show --name my-dotnet-api --resource-group my-rg --type console --tail 50 Scenario 2: Your Django Application Fails to Start What You See Your Django app deploys, the container starts, but within seconds it exits. In the logs you see one of these common errors: django.core.exceptions.ImproperlyConfigured: Set the SECRET_KEY environment variable Or: django.db.utils.OperationalError: could not connect to server: Connection refused Is the server running on host "localhost" (127.0.0.1) and accepting TCP/IP connections on port 5432? Or the static files problem that catches almost everyone: [Errno 2] No such file or directory: '/app/staticfiles' Why This Happens Django validates its configuration eagerly when the WSGI/ASGI server starts. If `SECRET_KEY` is not set, if `ALLOWED_HOSTS` does not include the container's hostname or the ingress FQDN, or if `DEBUG=True` is set in a configuration branch that requires a proper database, Django refuses to serve any requests. The static files error comes up because many teams forget to run `python manage.py collectstatic` as part of the container image build process. The `STATIC_ROOT` directory simply does not exist at runtime. Step-by-Step Fix Step 1 — Set required Django environment variables in your Container App. az containerapp secret set --name my-django-app --resource-group my-rg --secrets "django-secret-key=your-very-secret-key-here" "db-password=your-db-password" az containerapp update --name my-django-app --resource-group my-rg --set-env-vars "DJANGO_SECRET_KEY=secretref:django-secret-key" "DEBUG=False" "ALLOWED_HOSTS=my-django-app.happyfield-abc123.eastus.azurecontainerapps.io" "DATABASE_URL=secretref:db-password" Step 2 — Run `collectstatic` during Docker image build, not at runtime.* This is a very common mistake. Static files should be baked into the image, not generated when the container starts. Update your `Dockerfile`: FROM python:3.11-slim WORKDIR /app COPY requirements.txt . RUN pip install --no-cache-dir -r requirements.txt COPY . . # Collect static files at build time with a dummy SECRET_KEY RUN SECRET_KEY=build-time-placeholder python manage.py collectstatic --noinput EXPOSE 8000 CMD ["gunicorn", "myproject.wsgi:application", "--bind", "0.0.0.0:8000", "--workers", "2", "--timeout", "120"] Step 3 — Make sure Gunicorn is configured correctly for Container Apps. The most important thing to verify is that Gunicorn is binding to `0.0.0.0` and not `127.0.0.1`. Container Apps expects the application to listen on all interfaces so that the ingress layer can reach it. Also make sure the port matches what you defined in your Container App's ingress target port: # Set ingress to match Gunicorn's bind port az containerapp ingress update --name my-django-app --resource-group my-rg --target-port 8000 --type external Step 4 — Handle database migrations safely. Never run `python manage.py migrate` as part of your container startup command. If you have multiple replicas, all of them will try to run migrations simultaneously, which can corrupt your schema. Instead, use a Container App Job to run migrations as a pre-deployment step: # Create a one-time Container App Job to run migrations az containerapp job create --name django-migrate-job --resource-group my-rg --environment my-aca-env --trigger-type Manual --replica-timeout 300 --image myregistry.azurecr.io/my-django-app:latest --command "python" --args "manage.py" "migrate" --env-vars "DJANGO_SECRET_KEY=secretref:django-secret-key" "DATABASE_URL=secretref:db-password" # Execute the migration job before deploying the new revision az containerapp job start --name django-migrate-job --resource-group my-rg Scenario 3: Your Container App Job Fails Silently or Times Out What You See You trigger a Container App Job — maybe it is a nightly data processing job, a scheduled report generator, or a cleanup task — and in the Azure portal the execution shows as Failed with no helpful error message. Or it shows as Running for an unusually long time and then transitions to Failed with a timeout error. Why This Happens Container App Jobs have a `replicaTimeout` property. If your job process does not complete within that window, Azure Container Apps kills it and marks the execution as failed. This is different from Container Apps (services) where the container keeps running. Jobs are expected to run to completion and exit with code `0`. The silent failure happens when your job process exits with a non-zero exit code but does not write anything to `stdout` or `stderr`. Container Apps records the exit code but has no log content to show you. Step-by-Step Fix Step 1 — Make your job emit logs to stdout explicitly. Every print statement, every log line should go to `stdout` or `stderr`. In Python: import sys import logging logging.basicConfig( level=logging.INFO, format="%(asctime)s %(levelname)s %(message)s", handlers=[logging.StreamHandler(sys.stdout)] ) logger = logging.getLogger(__name__) def main(): logger.info("Job starting") try: # your job logic here process_data() logger.info("Job completed successfully") sys.exit(0) except Exception as e: logger.error(f"Job failed with error: {e}", exc_info=True) sys.exit(1) In .NET: // Use ILogger which writes to stdout by default in containers public class MyJob { private readonly ILogger<MyJob> _logger; public MyJob(ILogger<MyJob> logger) { _logger = logger; } public async Task RunAsync(CancellationToken cancellationToken) { _logger.LogInformation("Job starting at {Time}", DateTimeOffset.UtcNow); try { await ProcessDataAsync(cancellationToken); _logger.LogInformation("Job completed successfully"); } catch (Exception ex) { _logger.LogError(ex, "Job failed"); throw; // Let the process exit with non-zero code } } } Step 2 — Set an appropriate replica timeout and retry count. Be realistic about how long your job takes in production, then add a buffer: az containerapp job update --name my-processing-job --resource-group my-rg --replica-timeout 1800 # 30 minutes --replica-retry-limit 2 # Retry twice before marking as failed Step 3 — Check job execution history and logs. # List recent job executions and their status az containerapp job execution list --name my-processing-job --resource-group my-rg --output table # Get logs for a specific execution az containerapp job execution show --name my-processing-job --resource-group my-rg --job-execution-name my-processing-job-abc123 From Log Analytics: ContainerAppConsoleLogs_CL | where ContainerAppName_s == "my-processing-job" | where TimeGenerated > ago(24h) | project TimeGenerated, Log_s, ContainerName_s | order by TimeGenerated desc Summary: Your Startup Troubleshooting Checklist Before you dig into complex diagnostics, run through this checklist whenever a Container App or Job fails to start: Are all required environment variables and secrets defined and correctly referenced? Is the application listening on `0.0.0.0` and on the port that matches the ingress target port? Does the Dockerfile copy everything needed for the app to run (migrations, static files, etc.)? Are health probes configured with enough initial delay for the app to start? For jobs: is the replica timeout long enough, and does the process exit with code 0 on success? Is the container registry accessible from the Container Apps environment (managed identity or registry credentials configured)? Are the resource allocations (CPU and memory) sufficient for the application to start without OOM-killing? References and Sample Resources Use these resources for deeper implementation details and production-ready patterns. Azure Container Apps docs (core) Azure Container Apps overview Manage secrets in Azure Container Apps Manage environment variables in Azure Container Apps Health probes in Azure Container Apps Ingress in Azure Container Apps View logs in Azure Container Apps Azure Container Apps Jobs overview Azure Container Apps revisions .NET and Django references ASP.NET Core configuration fundamentals ASP.NET Core health checks Django deployment checklist Gunicorn settings Sample repositories Azure Samples: .NET on Azure Container Apps Azure Samples: Python on Azure Container Apps Azure Samples: TypeScript MCP container sample What's Next In Part 2 of this series, we move past startup failures and look at what happens after your app is running — the frustrating world of cold starts, scaling delays, and startup latency spikes that make your application feel slow under real production traffic. Part of the series: Troubleshooting Azure Container Apps in Production Next: Part 2 — From Slow to Snappy: Performance Tuning Cold Starts and Scaling Delays in Azure Container AppsMulti-Tenant Architecture: Real Challenges and an Azure Design Walkthrough
Azure Multi-Tenant Architecture (B2C Scenario) Let’s start with a reference design commonly used in Azure-based systems. A pretty standard setup looks something like this: Microsoft Entra External ID (Azure AD B2C) for authentication Azure API Management as the entry layer App Service or Functions for the compute layer Cosmos DB or SQL for storage Redis for caching Service Bus for async processing Application Insights for monitoring If you’ve worked on Azure systems, nothing here is surprising. On paper, this architecture is clean, scalable, and “multi-tenant ready”. But once traffic starts flowing and tenants behave differently, things start breaking in subtle ways. 1. Tenant Context Propagation Across Services A request doesn’t stay in one place. It moves across: API layer queues/topics background workers What I’ve seen happen multiple times: tenant ID is present in the API, but missing in async flows background jobs process data without knowing which tenant it belongs to logs become useless because you can’t tie actions back to a tenant The fix is simple in theory, but often missed in implementation: Every message should carry tenant context. No exceptions. If you rely on “it will be available somewhere”, it won’t be, especially in distributed systems. Ensure tenant context is explicitly carried everywhere: public class TenantMessage { public string TenantId { get; set; } public string Payload { get; set; } } Every message, event, and async operation should include tenant scope. 2. Data Isolation in Shared Databases Most teams start with a shared database model with tenant-based partitioning. It works well initially. Problems start creeping in later: someone forgets to add a tenant filter in a query a query suddenly scans across partitions one large tenant starts slowing down others A simple query like this becomes critical: var query = container.GetItemQueryIterator<Order>( new QueryDefinition("SELECT * FROM c WHERE c.tenantId = @tenantId") .WithParameter("@tenantId", tenantId) ); The tricky part is not writing it once, it’s making sure it’s applied everywhere, every time. 3. Authorization Beyond Tenant Boundaries At the beginning, access control is simple: “Users can access data from their own tenant.” But then requirements grow: admin access cross-tenant visibility reporting across firms or regions And this is where things usually get messy. Different services start implementing their own logic, and over time you end up with inconsistent behavior. A simple check: public bool CanAccess(string userTenant, string resourceTenant, bool isGlobalAdmin) { if (isGlobalAdmin) return true; return userTenant == resourceTenant; } becomes much harder to manage when duplicated across multiple services. One thing that helps a lot here is centralizing authorization logic early. 4. Caching as a Hidden Risk Caching is usually added later for performance. And that’s exactly why it becomes risky. I’ve seen scenarios where: cached data from one tenant is returned to another because the cache key didn’t include tenant information Fixing it is straightforward: public string BuildCacheKey(string tenantId, string key) { return $"{tenantId}:{key}"; } Cache keys must always include tenant boundaries 5. Resource Contention (Noisy Neighbor Problem) All tenants share resources: compute database throughput messaging What happens in practice: one high-load tenant impacts others latency becomes unpredictable system behavior differs per tenant You start adding controls like: if (RequestsPerTenant[tenantId] > 100) { return StatusCode(429); } And gradually move towards: throttling workload isolation prioritization This is less of a design problem and more of an operational reality. 6. Observability in Multi-Tenant Systems Logging works great, until you scale. Then suddenly: logs from all tenants are mixed debugging becomes slow it’s hard to answer basic questions like “which tenant failed?” A small change makes a huge difference: _logger.LogInformation( "Tenant={TenantId} Action=ProcessOrder OrderId={OrderId}", tenantId, orderId ); It sounds obvious, but it’s often inconsistent across services. 7. Backup and Restore Considerations Taking backups is easy. Restoring a single tenant isn’t. In most shared database setups: restore is done at database level which affects all tenants So if one tenant has a problem, recovery is not straightforward. This is one of those areas where decisions made early in design matter a lot later. Final Thoughts Designing a multi-tenant system is not just about choosing Azure services. The real challenges come from: how tenant context flows how isolation is enforced how systems behave under uneven load Most issues don’t show up on day one. They appear gradually as tenants grow, scale, and behave differently. References and Further Reading If you want to explore these concepts in more depth, here are some useful official resources: Microsoft Entra External ID (Azure AD B2C) Azure API Management Azure App Service Azure Cosmos DB and multitenant design Azure Service BusBuilding an Enterprise Knowledge Copilot with Foundry IQ and Agentic Retrieval on Azure AI
Every enterprise has the same problem: knowledge scattered across SharePoint, file shares, wikis, and email. This article walks through building a knowledge copilot that unifies that data behind a single conversational interface — using Microsoft's Foundry IQ knowledge bases and the agentic retrieval engine in Azure AI Search. The Problem: Fragmented Knowledge, Fragmented Answers Enterprise AI projects today share a common pain point. Each new agent or copilot that needs to answer questions from company data must rebuild its own retrieval pipeline from scratch — data connections, chunking logic, embeddings, routing, permissions — all duplicated project after project. The result is a tangle of fragmented, siloed pipelines that are expensive to maintain and inconsistent in quality. Consider a field technician troubleshooting equipment. The answer might span a vendor manual stored in OneLake, a company repair policy on SharePoint, and a public electrical standard on the web. Traditional single-index RAG cannot orchestrate across those sources in one pass. The technician waits, the issue escalates, and productivity drops. Foundry IQ, announced in public preview in November 2025, addresses this directly. It provides a unified knowledge layer for agents — a single endpoint that replaces per-project RAG pipelines with a reusable, topic-centric knowledge base that any number of agents can consume. What Is Foundry IQ? Foundry IQ introduces four capabilities built on top of Azure AI Search: Knowledge Bases — Reusable, topic-centric collections (e.g., "employee policies," "product documentation") available directly in the Foundry portal. Rather than wiring retrieval logic into every agent, you define a knowledge base once and ground multiple agents through a single API. Indexed and Federated Knowledge Sources — A knowledge base can draw from Azure Blob Storage, OneLake, SharePoint, Azure AI Search indexes, the web, and MCP servers (MCP in private preview). Developers do not need to manage different retrieval strategies per source; the knowledge base presents a unified endpoint. Agentic Retrieval Engine — A self-reflective query engine that uses AI to plan, search, and synthesize answers with configurable retrieval reasoning effort. Enterprise-Grade Security — Document-level access control and alignment with existing permissions models. Microsoft Purview sensitivity labels are respected through the indexing and retrieval pipeline, so classified content remains governed as it flows into knowledge bases. For indexed sources, Foundry IQ automatically manages the full indexing pipeline: content is ingested, chunked, vectorized, and prepared for hybrid retrieval. When Azure Content Understanding is enabled, complex documents gain layout-aware enrichment — tables, figures, and headers are extracted and structured without extra engineering work. How Agentic Retrieval Works Single-shot RAG — one query, one index, one pass — breaks down when questions are ambiguous, multi-hop, or span several data silos. Foundry IQ's agentic retrieval engine treats retrieval as a multi-step reasoning task rather than a keyword lookup: Plan — The engine analyzes the conversation and decomposes the query into focused sub-queries, deciding which knowledge sources to consult. Search — Sub-queries run concurrently against selected sources using keyword, vector, or hybrid techniques. Rank — Semantic reranking identifies the most relevant results. Reflect — If the information gathered is insufficient, the engine iterates — issuing follow-up queries autonomously. Synthesize — Results are unified into a natural-language answer with source references. Developers control this behaviour through a high-level retrieval reasoning effort setting. Lower effort suits fast, lightweight lookups; higher effort enables iterative search and richer planning across the entire data estate. Real-world impact: AT&T integrated Azure AI Search and retrieval-augmented generation into its multi-agent framework, reducing customer resolution times by 33 percent, cutting average handle time by nearly 10 percent, and scaling 71 AI solutions to 100,000 employees. Ontario Power Generation used agentic retrieval to sift through over 40 years of nuclear operating experience, enabling data-driven decision-making and helping new staff learn from decades of institutional knowledge. Architecture Overview Step-by-Step: Setting Up the Knowledge Copilot Provision Resources You need an Azure AI Search service (Basic tier or above), a Microsoft Foundry project, an embedding model deployment (e.g., text-embedding-3-large), and an LLM deployment (e.g., gpt-4.1) for query planning and answer generation. .NET 8 or later is required for the C# SDK. Create a Knowledge Base in Azure AI Search Using the Azure.Search.Documents preview SDK, define an index, a knowledge source pointing to your data, and a knowledge base with OutputMode set to AnswerSynthesis for natural-language answers with citations. The following C# snippet (adapted from the official Azure AI Search quickstart) shows the knowledge base creation: using Azure; using Azure.Identity; using Azure.Search.Documents.Indexes; var searchEndpoint = "https://<your-service>.search.windows.net"; var aoaiEndpoint = "https://<your-resource>.openai.azure.com/"; var indexClient = new SearchIndexClient( new Uri(searchEndpoint), new DefaultAzureCredential()); // Configure the LLM for query planning and answer synthesis var openAiParameters = new AzureOpenAIVectorizerParameters { ResourceUri = new Uri(aoaiEndpoint), DeploymentName = "gpt-4.1", ModelName = "gpt-4.1" }; var model = new KnowledgeBaseAzureOpenAIModel(openAiParameters); // Create the knowledge base with answer synthesis enabled var knowledgeBase = new KnowledgeBase("<knowledge-base-name>") { OutputMode = KnowledgeBaseOutputMode.AnswerSynthesis, AnswerInstructions = "Provide a concise answer based on the retrieved documents.", Models = { model } }; await indexClient.CreateOrUpdateKnowledgeBaseAsync(knowledgeBase); Connect an Agent to the Knowledge Base via MCP Each knowledge base exposes a Model Context Protocol (MCP) endpoint that MCP-compatible agents can call. The Foundry IQ-specific agent SDK currently offers full code samples for Python and REST API, but you can use the general-purpose MCP tooling in C# to achieve the same connection. The following pattern is drawn from the official Microsoft Learn documentation on MCP tools with Foundry Agents: using Azure.AI.Projects; using Azure.Identity; var endpoint = "https://<your-resource>.services.ai.azure.com/api/projects/<your-project>"; var model = "gpt-4.1-mini"; // Point the MCP tool at the knowledge base's MCP endpoint var mcpTool = new MCPToolDefinition( serverLabel: "enterprise_kb", serverUrl: "https://<search-service>.search.windows.net" + "/knowledgebases/<kb-name>/mcp?api-version=2025-11-01-preview"); mcpTool.AllowedTools.Add("knowledge_base_retrieve"); // Create the agent with the MCP tool attached var projectClient = new AIProjectClient(new Uri(endpoint), new DefaultAzureCredential()); var agentVersion = await projectClient.AgentAdministrationClient .CreateAgentVersionAsync( "enterprise-copilot", new ProjectsAgentVersionCreationOptions( new DeclarativeAgentDefinition(model) { Instructions = "You are a company knowledge assistant. " + "Always search the knowledge base before answering. " + "If the knowledge base has no answer, say so clearly.", Tools = { mcpTool } })); The agent instructions are critical — explicitly requiring the agent to use the knowledge base prevents it from answering purely from the LLM's training data. Query the Copilot Once the agent is published, your application layer simply sends user questions via the Azure AI Projects SDK or REST API. The agent autonomously invokes the knowledge base tool, retrieves grounded context, and returns an answer with citations referencing the original documents. Trade-offs and Considerations Dimension Detail Maturity Foundry IQ is in public preview — not recommended for production workloads without accepting preview SLA terms. Cost Agentic retrieval has two billing streams: token-based billing from Azure AI Search for retrieval, and billing from Azure OpenAI for query planning and answer synthesis. Latency vs. Quality Higher retrieval reasoning effort produces better answers but adds latency due to iterative search. For sub-second lookups, use minimal effort; for complex multi-hop questions, use medium. C# SDK Coverage The Foundry IQ–specific agent connection SDK currently supports Python and REST API. C# support is available for the underlying agentic retrieval queries and for general MCP tool integration. Security Document-level ACLs from SharePoint are enforced at query time. For per-user authorization in Foundry Agent Service, the current preview does not support per-request MCP headers — use the Azure OpenAI Responses API as an alternative. Key Takeaways Foundry IQ transforms enterprise RAG from a bespoke, per-project exercise into a managed, reusable knowledge layer. You define a knowledge base once, connect it to your data sources, and any number of agents or apps can consume it. The agentic retrieval engine handles query planning, multi-source search, semantic reranking, and iterative refinement — capabilities that previously required significant custom engineering. For .NET developers, the Azure AI Search C# SDK and the MCP tooling in the Agent Framework provide the building blocks to integrate this into your applications today. References: What is Foundry IQ? Create a knowledge base in Azure AI Search Foundry IQ: Unlocking ubiquitous knowledge for agents1.1KViews0likes0Comments
The Future of Agentic AI: Inside Microsoft Agent Framework 1.0
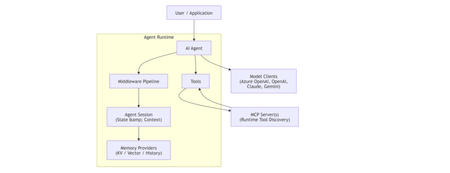
Agentic AI is rapidly moving beyond demos and chatbots toward long‑running, autonomous systems that reason, call tools, collaborate with other agents, and operate reliably in production. On April 3, 2026, Microsoft marked a major milestone with the General Availability (GA) release of Microsoft Agent Framework 1.0, a production‑ready, open‑source framework for building agents and multi‑agent workflows in.NET and Python. [techcommun...rosoft.com] In this post, we’ll deep‑dive into: What Microsoft Agent Framework actually is Its core architecture and design principles What’s new in version 1.0 How it differs from other agent frameworks When and how to use it—with real code examples What Is Microsoft Agent Framework? According to the official announcement, Microsoft Agent Framework is an open‑source SDK and runtime for building AI agents and multi‑agent workflows with strong enterprise foundations. Agent Framework provides two primary capability categories: 1. Agents Agents are long‑lived runtime components that: Use LLMs to interpret inputs Call tools and MCP servers Maintain session state Generate responses They are not just prompt wrappers, but stateful execution units. 2. Workflows Workflows are graph‑based orchestration engines that: Connect agents and functions Enforce execution order Support checkpointing and human‑in‑the‑loop scenarios This leads to a clean separation of responsibilities: Concern Handled By Reasoning & interpretation Agent Execution policy & control flow Workflow This separation is a foundational design decision. High‑Level Architecture From the official overview, Agent Framework is composed of several core building blocks: Model clients (chat completions & responses) Agent sessions (state & conversation management) Context providers (memory and retrieval) Middleware pipeline (interception, filtering, telemetry) MCP clients (tool discovery and invocation) Workflow engine (graph‑based orchestration) Conceptual Flow 🌟 What’s New in Version 1.0 Version 1.0 marks the transition from "Release Candidate" to "General Availability" (GA). Production-Ready Stability: Unlike the earlier experimental packages, 1.0 offers stable APIs, versioned releases, and a commitment to long-term support (LTS). A2A Protocol (Agent-to-Agent): A new structured messaging protocol that allows agents to communicate across different runtimes. For example, an agent built in Python can seamlessly coordinate with an agent running in a .NET environment. MCP (Model Context Protocol) Support: Full integration with the Model Context Protocol, enabling agents to dynamically discover and invoke external tools and data sources without manual integration code. Multi-Agent Orchestration Patterns: Stable implementations of complex patterns, including: Sequential: Linear handoffs between specialized agents. Group Chat: Collaborative reasoning where agents discuss and solve problems. Magentic-One: A sophisticated pattern for task-oriented reasoning and planning. Middleware Pipeline: The new middleware architecture lets you inject logic into the agent's execution loop without modifying the core prompts. This is essential for Responsible AI (RAI), allowing you to add content safety filters, logging, and compliance checks globally. DevUI Debugger: A browser-based local debugger that provides a real-time visual representation of agent message flows, tool calls, and state changes. Code Examples Creating a Simple Agent (C#) From Microsoft Learn : using Azure.AI.Projects; using Azure.Identity; using Microsoft.Agents.AI; AIAgent agent = new AIProjectClient( new Uri("https://your-foundry-service.services.ai.azure.com/api/projects/your-project"), new AzureCliCredential()) .AsAIAgent( model: "gpt-5.4-mini", instructions: "You are a friendly assistant. Keep your answers brief."); Console.WriteLine(await agent.RunAsync("What is the largest city in France?")); This shows: Provider‑agnostic model access Session‑aware agent execution Minimal setup for production agents Creating a Simple Agent (Python) from agent_framework.foundry import FoundryChatClient from azure.identity import AzureCliCredential client = FoundryChatClient( project_endpoint="https://your-foundry-service.services.ai.azure.com/api/projects/your-project", model="gpt-5.4-mini", credential=AzureCliCredential(), ) agent = client.as_agent( name="HelloAgent", instructions="You are a friendly assistant. Keep your answers brief.", ) result = await agent.run("What is the largest city in France?") print(result) The same agent abstraction applies across languages. When to Use Agents vs Workflows Microsoft provides clear guidance: Use an Agent when… Use a Workflow when… Task is open‑ended Steps are well‑defined Autonomous tool use is needed Execution order matters Single decision point Multiple agents/functions collaborate Key principle: If you can solve the task with deterministic code, do that instead of using an AI agent. 🔄 How It Differs from Other Frameworks Microsoft Agent Framework 1.0 distinguishes itself by focusing on "Enterprise Readiness" and "Interoperability." Feature Microsoft Agent Framework 1.0 Semantic Kernel / AutoGen LangChain / CrewAI Philosophy Unified, production-ready SDK. Research-focused or tool-specific. High-level, developer-friendly abstractions. Integration Deeply integrated with Microsoft Foundry and Azure. Varied; often requires more glue code. Generally cloud-agnostic. Interoperability Native A2A and MCP for cross-framework tasks. Limited to internal ecosystem. Uses proprietary connectors. Runtime Identical API parity for .NET and Python. Primarily Python-first (SK has C#). Primarily Python. Control Graph-based deterministic workflows. More non-deterministic/experimental. Mixture of role-based and agentic. 🛠️ Key Technical Components Agent Harness: The execution layer that provides agents with controlled access to the shell, file system, and messaging loops. Agent Skills: A portable, file-based or code-defined format for packaging domain expertise. Implementation Tip: If you are coming from Semantic Kernel, Microsoft provides migration assistants that analyze your existing code and generate step-by-step plans to upgrade to the new Agent Framework 1.0 standards. Microsoft Agent Framework Version 1.0 | Microsoft Agent Framework Agent Framework documentation 🎯 Summary Microsoft Agent Framework 1.0 is the "grown-up" version of AI orchestration. By standardizing the way agents talk to each other (A2A), discover tools (MCP), and process information (Middleware), Microsoft has provided a clear path for taking AI experiments into production. For more detailed guides, check out the official Microsoft Agent Framework DocumentationMicrosoft Agent Framework - .NET AI Community Standup
Dev Containers for .NET in VS Code: A Beginner‑Friendly Guide That Actually Works
What Dev Containers are really about At a high level, Dev Containers let you use a Docker container as your development environment inside VS Code. But the real idea is not “Docker for development”. The real idea is this: Move all environment complexity out of your laptop and into version‑controlled configuration. With Dev Containers: Your laptop becomes just a VS Code client Your tools, SDKs, runtimes, and dependencies live inside the container Your project defines its own development environment, not your machine This means: You can switch projects without breaking anything You can delete and recreate your environment safely New developers get the same setup without tribal knowledge Why Dev Containers are so useful for .NET projects .NET development often looks simple at first until it doesn’t. Common pain points: Different developers using different .NET SDK versions One project needs .NET 6, another needs .NET 8 Native dependencies work on one machine but not another CI runs on Linux but developers run on Windows Dev Containers solve this by: Locking the SDK version and OS used for development Running everything in a Linux container (close to CI/production) Keeping developer machines clean and stable Making onboarding almost instant: clone → reopen in container → run Once the .devcontainer folder is committed to the repo, the environment becomes part of the codebase, not a wiki page. How Dev Containers work in VS Code You don’t need deep Docker knowledge to use Dev Containers. Here’s the mental model that helped me: Your repository contains a .devcontainer folder Inside it, devcontainer.json describes the development environment VS Code reads that file and starts a container VS Code connects to the container and runs extensions inside it Your source code stays on your machine, but: the terminal runs inside the container the debugger runs inside the container the SDKs live inside the container If something breaks, you rebuild the container, not your laptop. When Dev Containers are a great choice (and when they’re not) Dev Containers are a great fit when: You work on multiple projects with different requirements Your team struggles with environment consistency You want Linux parity for CI and containerized deployments You value reproducibility over ad‑hoc local setup They may not be ideal when: You’re working on very small throwaway scripts You rely heavily on Windows‑only tooling You cannot use Docker at all in your environment For most professional .NET teams, the benefits far outweigh the cost. Docker on Windows: a choice you must make early When starting with Dev Containers on Windows, one of the first decisions you must make is how Docker runs on your machine. Both Docker Desktop and Docker Engine inside WSL work well with Dev Containers but they serve slightly different needs. Using Docker Desktop Docker Desktop is the easiest and most beginner‑friendly way to get started with Dev Containers. Pros Very quick setup with minimal configuration Comes with a graphical dashboard for containers, images, and logs Integrates smoothly with VS Code and WSL2 Easier to troubleshoot when you’re learning Cons Uses more system resources in the background Runs additional services even when you’re not actively developing May be restricted or licensed differently in some enterprise environments When to use Docker Desktop You are new to Docker or Dev Containers You want the simplest and fastest setup You value ease of use over fine‑grained control You are working on personal projects or in environments where Docker Desktop is allowed For most developers starting out with Dev Containers, Docker Desktop is the recommended entry point. Using Docker Engine inside WSL This approach installs Docker Engine directly inside a Linux distribution (like Ubuntu) running on WSL2, without Docker Desktop. Pros Lower resource usage compared to Docker Desktop Linux‑native behavior (closer to CI and production) No dependency on Docker Desktop Often preferred in enterprise or restricted environments Cons Requires manual installation and configuration Needs basic Linux and WSL knowledge No graphical UI everything is CLI‑based When to use Docker Engine in WSL Docker Desktop is not allowed or restricted You want a leaner, Linux‑first workflow You already work mostly inside WSL You want tighter control over your Docker setup This approach is ideal once you are comfortable with Docker and WSL. Note : Do not mix Docker Desktop and Docker Engine inside WSL.Pick one approach and stick with it. Running both at the same time often leads to Docker context confusion and Dev Containers failing in unpredictable ways, even when your configuration looks correct. A performance tip that makes a huge difference If you’re using Linux containers with WSL, store your code inside the WSL filesystem. Recommended: /home/<user>/projects/your-repo Avoid: /mnt/c/Users/<user>/your-repo Linux containers accessing Windows files are slower and cause file‑watching issues. Moving the repo into WSL made my Dev Containers feel almost native. First‑time setup: the simplest way to start If you’re trying Dev Containers for the first time, follow this exact order: Install Visual Studio Code Install the Dev Containers extension Install Docker Desktop (or Docker Engine in WSL) Clone your repo inside the WSL filesystem Open the folder in VS Code Run “Dev Containers: Reopen in Container” That’s it. VS Code handles the rest. Your first .NET Dev Container (hands‑on example) Tech Stack .NET 8 Web API PostgreSQL 16 Entity Framework Core + Npgsql VS Code Dev Containers Docker Compose Project Structure my-blog-api/ ├─ .devcontainer/ │ └─ devcontainer.json ├─ docker-compose.yml └─ src/ └─ BlogApi/ ├─ Program.cs ├─ BlogApi.csproj ├─ appsettings.json ├─ Models/ └─ Data/ Step 1: Create the Web API mkdir my-blog-api cd my-blog-api mkdir src && cd src dotnet new webapi -n BlogApi cd BlogApi Step 2: Add EF Core + PostgreSQL packages dotnet add package Npgsql.EntityFrameworkCore.PostgreSQL dotnet add package Microsoft.EntityFrameworkCore.Design Step 3: Docker Compose (API + PostgreSQL) Create docker-compose.yml at the repo root: version: "3.8" services: app: image: mcr.microsoft.com/devcontainers/dotnet:1-8.0 volumes: - .:/workspace:cached working_dir: /workspace command: sleep infinity ports: - "5000:5000" depends_on: - db db: image: postgres:16 environment: POSTGRES_USER: devuser POSTGRES_PASSWORD: devpwd POSTGRES_DB: devdb ports: - "5432:5432" volumes: - pgdata:/var/lib/postgresql/data pgadmin: image: dpage/pgadmin4 environment: PGADMIN_DEFAULT_EMAIL: admin@admin.com PGADMIN_DEFAULT_PASSWORD: admin ports: - "5050:80" depends_on: - db volumes: pgdata: Step 4: Dev Container configuration Create .devcontainer/devcontainer.json: { "name": "dotnet-postgres-devcontainer", "dockerComposeFile": "../docker-compose.yml", "service": "app", "workspaceFolder": "/workspace", "shutdownAction": "stopCompose", "customizations": { "vscode": { "extensions": [ "ms-dotnettools.csdevkit", "ms-dotnettools.csharp", "ms-azuretools.vscode-docker" ] } }, "postCreateCommand": "dotnet restore" } Open the folder in VS Code and run: Dev Containers: Reopen in Container Step 5: Connection string (container‑to‑container) Update appsettings.json: { "ConnectionStrings": { "DefaultConnection": "Host=db;Port=5432;Database=devdb;Username=devuser;Password=devpwd" }, "Logging": { "LogLevel": { "Default": "Information", "Microsoft.AspNetCore": "Warning" } }, "AllowedHosts": "*" } Host=db works because Docker Compose provides internal DNS between services. Step 6: EF Core Model & DbContext Post entity – Models/Post.cs namespace BlogApi.Models; public class Post { public int Id { get; set; } public string Title { get; set; } = string.Empty; public string Content { get; set; } = string.Empty; public DateTime CreatedUtc { get; set; } = DateTime.UtcNow; } DbContext – Data/BlogDbContext.cs using BlogApi.Models; using Microsoft.EntityFrameworkCore; namespace BlogApi.Data; public class BlogDbContext : DbContext { public BlogDbContext(DbContextOptions<BlogDbContext> options) : base(options) { } public DbSet<Post> Posts => Set<Post>(); } Step 7: Program.cs (Minimal CRUD) Replace Program.cs with: using BlogApi.Data; using BlogApi.Models; using Microsoft.EntityFrameworkCore; var builder = WebApplication.CreateBuilder(args); builder.Services.AddDbContext<BlogDbContext>(options => options.UseNpgsql(builder.Configuration.GetConnectionString("DefaultConnection"))); builder.Services.AddEndpointsApiExplorer(); builder.Services.AddSwaggerGen(); var app = builder.Build(); // Apply migrations on startup (dev-only convenience) using (var scope = app.Services.CreateScope()) { var db = scope.ServiceProvider.GetRequiredService<BlogDbContext>(); db.Database.Migrate(); } app.UseSwagger(); app.UseSwaggerUI(); app.MapGet("/posts", async (BlogDbContext db) => await db.Posts.OrderByDescending(p => p.CreatedUtc).ToListAsync()); app.MapPost("/posts", async (Post post, BlogDbContext db) => { db.Posts.Add(post); await db.SaveChangesAsync(); return Results.Created($"/posts/{post.Id}", post); }); app.MapPut("/posts/{id:int}", async (int id, Post input, BlogDbContext db) => { var post = await db.Posts.FindAsync(id); if (post is null) return Results.NotFound(); post.Title = input.Title; post.Content = input.Content; await db.SaveChangesAsync(); return Results.Ok(post); }); app.MapDelete("/posts/{id:int}", async (int id, BlogDbContext db) => { var post = await db.Posts.FindAsync(id); if (post is null) return Results.NotFound(); db.Posts.Remove(post); await db.SaveChangesAsync(); return Results.NoContent(); }); app.Run("http://0.0.0.0:5000"); Step 8: Run migrations (inside Dev Container) cd src/BlogApi dotnet tool install --global dotnet-ef export PATH="$PATH:/home/vscode/.dotnet/tools" dotnet ef migrations add InitialCreate dotnet ef database update Step 9: Run the API dotnet run 🔗 Open: Swagger → http://localhost:5000/swagger Posts API → http://localhost:5000/posts Common mistakes and quick fixes Mistake Symptom Fix Mixing Docker models Random failures Use only one Docker approach Code under /mnt/c Slow builds Move repo to WSL filesystem Docker not running Container won’t start Check docker info Pruning first Issues return Fix daemon/context first Common Challenges Faced Multiple Docker engines active simultaneously Docker Desktop and Docker Engine inside WSL were both present, causing conflicts. Unstable Docker CLI context Docker CLI intermittently pointed to different or broken Docker endpoints. Docker daemon appeared running but was unusable Docker commands failed with API errors despite the daemon seeming active. systemd dependency issues inside WSL Docker Engine depended on systemd, which was not consistently active after WSL restarts. Dev Containers failing during setup VS Code Dev Containers surfaced failures during feature installation and builds. Misleading Docker error messages Errors pointed to API or version issues, masking the real root cause. Cache cleanup ineffective Pruning images and containers did not resolve underlying daemon issues. Container observability confusion PostgreSQL and pgAdmin worked, but container health, volumes, and data locations were unclear. Solutions & Maintainable Settings Enforce a Single Docker Model. Use either Docker Desktop or native Docker Engine inside WSL .never both. docker version docker info Verify only one server is shown No references to dockerDesktopLinuxEngine when using native WSL Docker Explicitly Lock Docker CLI Context. Always verify and set Docker context before running Compose or Dev Containers. docker context ls docker context show docker context use default Context must point to the intended daemon (WSL or Desktop) Validate Docker Daemon Health Before Project Start.Confirm Docker is reachable before Dev Containers or Compose. docker info docker ps Must return without API / 500 / version errors Do not proceed if these fail Ensure systemd Is Enabled in WSL.Docker Engine inside WSL depends on systemd. cat /etc/wsl.conf Expected: [boot] systemd=true If not then apply changes.Restart WSL and re‑verify: wsl --shutdown systemctl status docker Start Docker Explicitly After WSL Restart.WSL restarts silently stop services. sudo systemctl start docker sudo systemctl enable docker Verify: docker ps Use Only WSL Native Filesystem for Projects.Keep project under /home/<user>/... Avoid /mnt/c/... paths. Path starts with /home/ Treat Dev Containers as a Consumer, Not the Fix. Fix Docker issues outside Dev Containers first. Pre‑check Commands docker compose config docker compose up -d Compose works before opening Dev Container Keep Dev Container Features Minimal on First Run Start with base image + required services only Add features after baseline stability docker images docker ps Verify Container Observability Explicitly.Confirm containers are healthy, ports mapped, volumes mounted. docker ps docker inspect <container_name> docker logs <container_name> Port check: ss -lntp | grep <port> Avoid Cache Cleanup as a First Fix. Do not rely on prune to fix daemon issues Only After Daemon Is Healthy docker system prune -f docker volume prune -f Establish a “Known‑Good” Baseline Checklist. Validate sequence before development starts Baseline Flow wsl --shutdown # reopen WSL sudo systemctl start docker docker context show docker info docker compose up -d code . # Only then open Reopen in Container If something breaks in between after running dev container we can stop and clean the containers and rebuild it again docker ps docker stop $(docker ps -q) docker rm -f $(docker ps -aq) docker ps Closing Thoughts Dev Containers shift local development from fragile, machine‑specific setups to reproducible, version‑controlled environments. With Dev Containers, Docker Compose, PostgreSQL, and pgAdmin, your entire .NET development stack lives inside containers.not on your laptop. SDKs, databases, and tools are isolated, consistent, and easy to rebuild. When something breaks, you rebuild containers.not machines. This approach removes onboarding friction, improves Linux parity with CI, and eliminates the classic “works on my machine” problem. Once Docker is stable, Dev Containers become one of the most reliable ways to build modern .NET applications. Key Takeaways Dev Containers treat the development environment as code .NET, PostgreSQL, and pgAdmin run fully isolated in containers pgAdmin provides clear visibility into database state and migrations Docker stability is a prerequisite.Dev Containers are not a Docker fix Onboarding becomes simple: clone → reopen in container → run Rebuild containers, not laptops2.9KViews0likes0CommentsStop Experimenting, Start Building: AI Apps & Agents Dev Days Has You Covered
The AI landscape has shifted. The question is no longer “Can we build AI applications?” it’s “Can we build AI applications that actually work in production?” Demos are easy. Reliable, scalable, resilient AI systems that handle real-world complexity? That’s where most teams struggle. If you’re an AI developer, software engineer, or solution architect who’s ready to move beyond prototypes and into production-grade AI, there’s a series built specifically for you. What Is AI Apps & Agents Dev Days? AI Apps & Agents Dev Days is a monthly technical series from Microsoft Reactor, delivered in partnership with Microsoft and NVIDIA. You can explore the full series at https://developer.microsoft.com/en-us/reactor/series/s-1590/ This isn’t a slide deck marathon. The series tagline says it best: “It’s not about slides, it’s about building.” Each session tackles real-world challenges, shares patterns that actually work, and digs into what’s next in AI-driven app and agent design. You bring your curiosity, your code, and your questions. You leave with something you can ship. The sessions are led by experienced engineers and advocates from both Microsoft and NVIDIA, people like Pamela Fox, Bruno Capuano, Anthony Shaw, Gwyneth Peña-Siguenza, and solutions architects from NVIDIA’s Cloud AI team. These aren’t theorists; they’re practitioners who build and ship the tools you use every day. What You’ll Learn The series covers the full spectrum of building AI applications and agent-based systems. Here are the key themes: Building AI Applications with Azure, GitHub, and Modern Tooling Sessions walk through how to wire up AI capabilities using Azure services, GitHub workflows, and the latest SDKs. The focus is always on code-first learning, you’ll see real implementations, not abstract architecture diagrams. Designing and Orchestrating AI Agents Agent development is one of the series’ strongest threads. Sessions cover how to build agents that orchestrate long-running workflows, persist state automatically, recover from failures, and pause for human-in-the-loop input, without losing progress. For example, the session “AI Agents That Don’t Break Under Pressure” demonstrates building durable, production-ready AI agents using the Microsoft Agent Framework, running on Azure Container Apps with NVIDIA serverless GPUs. Scaling LLM Inference and Deploying to Production Moving from a working prototype to a production deployment means grappling with inference performance, GPU infrastructure, and cost management. The series covers how to leverage NVIDIA GPU infrastructure alongside Azure services to scale inference effectively, including patterns for serverless GPU compute. Real-World Architecture Patterns Expect sessions on container-based deployments, distributed agent systems, and enterprise-grade architectures. You’ll learn how to use services like Azure Container Apps to host resilient AI workloads, how Foundry IQ fits into agent architectures as a trusted knowledge source, and how to make architectural decisions that balance performance, cost, and scalability. Why This Matters for Your Day Job There’s a critical gap between what most AI tutorials teach and what production systems actually require. This series bridges that gap: Production-ready patterns, not demos. Every session focuses on code and architecture you can take directly into your projects. You’ll learn patterns for state persistence, failure recovery, and durable execution — the things that break at 2 AM. Enterprise applicability. The scenarios covered — travel planning agents, multi-step workflows, GPU-accelerated inference — map directly to enterprise use cases. Whether you’re building internal tooling or customer-facing AI features, the patterns transfer. Honest trade-off discussions. The speakers don’t shy away from the hard questions: When do you need serverless GPUs versus dedicated compute? How do you handle agent failures gracefully? What does it actually cost to run these systems at scale? Watch On-Demand, Build at Your Own Pace Every session is available on-demand. You can watch, pause, and build along at your own pace, no need to rearrange your schedule. The full playlist is available at This is particularly valuable for technical content. Pause a session while you replicate the architecture in your own environment. Rewind when you need to catch a configuration detail. Build alongside the presenters rather than just watching passively. What You’ll Walk Away Wit After working through the series, you’ll have: Practical agent development skills — how to design, orchestrate, and deploy AI agents that handle real-world complexity, including state management, failure recovery, and human-in-the-loop patterns Production architecture patterns — battle-tested approaches for deploying AI workloads on Azure Container Apps, leveraging NVIDIA GPU infrastructure, and building resilient distributed systems Infrastructure decision-making confidence — a clearer understanding of when to use serverless GPUs, how to optimise inference costs, and how to choose the right compute strategy for your workload Working code and reference implementations — the sessions are built around live coding and sample applications (like the Travel Planner agent demo), giving you starting points you can adapt immediately A framework for continuous learning — with new sessions each month, you’ll stay current as the AI platform evolves and new capabilities emerge Start Building The AI applications that will matter most aren’t the ones with the flashiest demos — they’re the ones that work reliably, scale gracefully, and solve real problems. That’s exactly what this series helps you build. Whether you’re designing your first AI agent system or hardening an existing one for production, the AI Apps & Agents Dev Days sessions give you the patterns, tools, and practical knowledge to move forward with confidence. Explore the series at https://developer.microsoft.com/en-us/reactor/series/s-1590/ and start watching the on-demand sessions at the link above. The best time to level up your AI engineering skills was yesterday. The second-best time is right now and these sessions make it easy to start.