.net
462 TopicsAnnouncing General Availability of Managed Instance on Azure App Service
Today, we are thrilled to announce the General Availability (GA) of Managed Instance on Azure App Service. Following the tremendous response to our Public Preview announcement at Ignite 2025, we've spent the past nine months working closely with customers, partners, and the community to harden the platform, expand capabilities, and validate real-world enterprise migration scenarios. Managed Instance on Azure App Service is now ready for your production workloads, backed by a full enterprise SLA. The journey from Preview to GA Since November 2025, thousands of customers have used the public preview to move workloads that were previously "stuck" on-premises or on aging Windows Server VMs. The feedback has been unmistakable: Managed Instance on Azure App Service dramatically shortens the path to the cloud for legacy and complex .NET Framework applications often removing the need for code changes entirely. Enterprises across various sectors like financial services, healthcare, manufacturing, and the public sector migrated applications that depended on GAC assemblies, COM components, Windows Services, registry configuration, and mapped network drives apps that historically required expensive re-platforming or a full rewrite. With Managed Instance on Azure App Service, these workloads now run on a fully managed PaaS platform, side-by-side with modern cloud-native apps. What's new at GA Building on the preview foundation of configuration scripts, registry adapters, storage mounts, and RDP via Azure Bastion, GA brings several important additions: Production SLA (99.95%) – Full enterprise-grade availability commitment across all supported regions. Expanded regional availability – Available in at least 8 Azure regions worldwide at GA with continued expansion planned through the remainder of 2026. Deeper Premium v4 integration – Managed Instance now takes full advantage of the Premium v4 App Service Plan tier for enhanced performance, memory-optimized SKUs, and improved price-performance. Zone redundancy – Deploy Managed Instance workloads across Availability Zones for higher resiliency without additional configuration effort. Enhanced observability – First-class integration with Azure Monitor, Application Insights, and Log Analytics, including instance-level metrics for CPU, memory and disk. Improved configuration script experience – Faster startup times, richer diagnostics when scripts fail, versioning support for configuration bundles, and streamlined rollback. Managed Identity everywhere – All secrets, storage connections, and Key Vault references at GA use Managed Identity by default, eliminating stored credentials from your deployment pipelines. Azure Policy and Defender for Cloud coverage – Governance, compliance, and threat protection controls now apply to Managed Instance the same way they apply to standard App Service workloads. Bicep, Terraform, and ARM templates – Full IaC support with new resource providers and modules for repeatable, auditable deployments. GitHub Copilot Modernization - Deep Integration with GitHub Copilot modernization for Application assessment targeting Managed Instance on App Service https://learn.microsoft.com/en-us/dotnet/azure/migration/appmod/working-with-assessment Why customers are choosing Managed Instance on Azure App Service The core value proposition remains the same and it's stronger than ever at GA: 1. Lift-and-Improve legacy applications Migrate .NET Framework apps with hardcoded file paths, COM dependencies, GAC entries, or registry access with no major code rewrites. Install custom components directly on the managed instance using configuration scripts. 2. Re-platform hard-to-modernize apps Move applications with lost source code, legacy middleware (MSMQ, SMTP servers, third-party runtimes), or tight infrastructure coupling. Managed Instance removes the blockers that historically forced these apps to stay on VMs. 3. Hybrid and regulated workloads Integrate securely with on-premises resources using VNet integration and private endpoints. Enforce data residency, Bring Your Own Storage, and Managed Identity–backed access controls to meet finance, healthcare, and government compliance requirements. 4. Incremental modernization Start with "lift and Improve" then adopt PaaS features like DevOps automation, autoscaling, deployment slots, and centralized configuration at your own pace. Future-proof your portfolio without a big-bang transformation. What customers are saying During preview, we saw real numbers: Migration timelines cut from months to weeks for apps that would otherwise have required substantial refactoring. Zero code changes for a significant share of preview workloads that previously blocked App Service adoption. Reduced infrastructure footprint as customers consolidated Windows Server VMs onto managed App Service Plans with zone redundancy and autoscaling built in. We are grateful to every preview customer whose feedback shaped this release. Pricing and licensing Managed Instance on Azure App Service is billed as a capability on top of the Premium v4 App Service Plan. There is no separate Managed Instance surcharge at GA you pay for the underlying Premium v4 compute you consume. Existing App Service reservations, savings plans, and any other Azure Benefit all apply, helping you optimize the total cost of ownership as you migrate. Getting started Getting started is straightforward: Assess your workload using Azure Migrate's updated App Service assessment, which now flags candidates ideal for Managed Instance. Create a new Web App using the Managed Instance on Azure App Service option in the Azure Marketplace, or via Bicep, Terraform, or the Azure CLI. Package your dependencies into a configuration bundle (a zip file plus a PowerShell install script) and store it in Azure Storage. Grant access via Managed Identity. Configure registry values, storage mounts, and networking to match your on-premises environment. Deploy your application using the same App Service deployment mechanisms you already know—ZIP deploy, GitHub Actions, Azure DevOps, or Visual Studio publish. Operate with confidence use RDP over Azure Bastion for deep troubleshooting when you need it, and Azure Monitor for everything else. Resources 📘 Managed Instance on Azure App Service documentation 🎥 Technical Deep Dive session recording from Build 2026 🧭 GitHub Repo with sample configuration scripts, webapp and guidance for Managed Instance on App Service workloads Looking ahead GA is a milestone, not a finish line. On our roadmap we're already working on: Deeper integration with Azure Migrate's web app discovery and assessment capabilities to help identify web apps suitable for migration to Managed Instance on App Service Enhanced migration tooling with easier dependency detection and one-click configuration bundle generation. Expanded Rollout to Azure Regions across 2026 and beyond. Continuously Release new features and capabilities to make migrations easier and faster than ever before We can't wait to see what you build and what you migrate. Managed Instance on Azure App Service is here to make your modernization journey faster, simpler, and more secure than ever. Welcome to GA. 🚀 The Azure App Service Team2.5KViews1like0CommentsBuilding HIPAA-Compliant Medical Transcription with Local AI
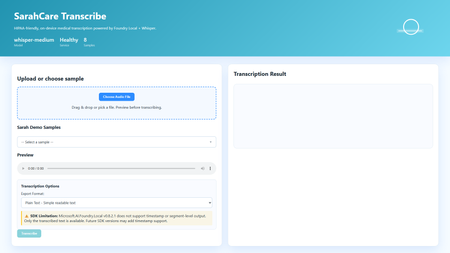
Building HIPAA-Compliant Medical Transcription with Local AI Introduction Healthcare organizations generate vast amounts of spoken content, patient consultations, research interviews, clinical notes, medical conferences. Transcribing these recordings traditionally requires either manual typing (time-consuming and expensive) or cloud transcription services (creating immediate HIPAA compliance concerns). Every audio file sent to external APIs exposes Protected Health Information (PHI), requires Business Associate Agreements, creates audit trails on third-party servers, and introduces potential breach vectors. This sample solution lies in on-premises voice-to-text systems that process audio entirely locally, never sending PHI beyond organizational boundaries. This article demonstrates building a sample medical transcription application using FLWhisper, ASP.NET Core, C#, and Microsoft Foundry Local with OpenAI Whisper models. You'll learn how to build sample HIPAA-compliant audio processing, integrate Whisper models for medical terminology accuracy, design privacy-first API patterns, and build responsive web UIs for healthcare workflows. Whether you're developing electronic health record (EHR) integrations, building clinical research platforms, or implementing dictation systems for medical practices, this sample could be a great starting point for privacy-first speech recognition. Why Local Transcription Is Critical for Healthcare Healthcare data handling is fundamentally different from general business data due to HIPAA regulations, state privacy laws, and professional ethics obligations. Understanding these requirements explains why cloud transcription services, despite their convenience, create unacceptable risks for medical applications. HIPAA compliance mandates strict controls over PHI. Every system that touches patient data must implement administrative, physical, and technical safeguards. Cloud transcription APIs require Business Associate Agreements (BAAs), but even with paperwork, you're entrusting PHI to external systems. Every API call creates logs on vendor servers, potentially in multiple jurisdictions. Data breaches at transcription vendors expose patient information, creating liability for healthcare organizations. On-premises processing eliminates these third-party risks entirely, PHI never leaves your controlled environment. US State laws increasingly add requirements beyond HIPAA. California's CCPA, New York's SHIELD Act, and similar legislation create additional compliance obligations. International regulations like GDPR prohibit transferring health data outside approved jurisdictions. Local processing simplifies compliance by keeping data within organizational boundaries. Research applications face even stricter requirements. Institutional Review Boards (IRBs) often require explicit consent for data sharing with external parties. Cloud transcription may violate study protocols that promise "no third-party data sharing." Clinical trials in pharmaceutical development handle proprietary information alongside PHI, double jeopardy for data exposure. Local transcription maintains research integrity while enabling audio analysis. Cost considerations favor local deployment at scale. Medical organizations generate substantial audio, thousands of patient encounters monthly. Cloud APIs charge per minute of audio, creating significant recurring costs. Local models have fixed infrastructure costs that scale economically. A modest GPU server can process hundreds of hours monthly at predictable expense. Latency matters for clinical workflows. Doctors and nurses need transcriptions available immediately after patient encounters to review and edit while details are fresh. Cloud APIs introduce network delays, especially problematic in rural health facilities with limited connectivity. Local inference provides <1 second turnaround for typical consultation lengths. Application Architecture: ASP.NET Core with Foundry Local The sample FLWhisper application implements clean separation between audio handling, AI inference, and state management using modern .NET patterns: The ASP.NET Core 10 minimal API provides HTTP endpoints for health checks, audio transcription, and sample file streaming. Minimal APIs reduce boilerplate while maintaining full middleware support for error handling, authentication, and CORS. The API design follows OpenAI's transcription endpoint specification, enabling drop-in replacement for existing integrations. The service layer encapsulates business logic: FoundryModelService manages model loading and lifetime, TranscriptionService handles audio processing and AI inference, and SampleAudioService provides demonstration files for testing. This separation enables easy testing, dependency injection, and service swapping. Foundry Local integration uses the Microsoft.AI.Foundry.Local.WinML SDK. Unlike cloud APIs requiring authentication and network calls, this SDK communicates directly with the local Foundry service via in-process calls. Models load once at startup, remaining resident in memory for sub-second inference on subsequent requests. The static file frontend delivers vanilla HTML/CSS/JavaScript, no framework overhead. This simplicity aids healthcare IT security audits and enables deployment on locked-down hospital networks. The UI provides file upload, sample selection, audio preview, transcription requests, and result display with copy-to-clipboard functionality. Here's the architectural flow for transcription requests: Web UI (Upload Audio File) ↓ POST /v1/audio/transcriptions (Multipart Form Data) ↓ ASP.NET Core API Route ↓ TranscriptionService.TranscribeAudio(audioStream) ↓ Foundry Local Model (Whisper Medium locally) ↓ Text Result + Metadata (language, duration) ↓ Return JSON/Text Response ↓ Display in UI This architecture embodies several healthcare system design principles: Data never leaves the device: All processing occurs on-premises, no external API calls No data persistence by default: Audio and transcripts are session-only, never saved unless explicitly configured Comprehensive health checks: System readiness verification before accepting PHI Audit logging support: Structured logging for compliance documentation Graceful degradation: Clear error messages when models unavailable rather than silent failures Setting Up Foundry Local with Whisper Models Foundry Local supports multiple Whisper model sizes, each with different accuracy/speed tradeoffs. For medical transcription, accuracy is paramount—misheard drug names or dosages create patient safety risks: # Install Foundry Local (Windows) winget install Microsoft.FoundryLocal # Verify installation foundry --version # Download Whisper Medium model (optimal for medical accuracy) foundry model add openai-whisper-medium-generic-cpu:1 # Check model availability foundry model list Whisper Medium (769M parameters) provides the best balance for medical use. Smaller models (Tiny, Base) miss medical terminology frequently. Larger models (Large) offer marginal accuracy gains at 3x inference time. Medium handles medical vocabulary well, drug names, anatomical terms, procedure names, while processing typical consultation audio (5-10 minutes) in under 30 seconds. The application detects and loads the model automatically: // Services/FoundryModelService.cs using Microsoft.AI.Foundry.Local.WinML; public class FoundryModelService { private readonly ILogger _logger; private readonly FoundryOptions _options; private ILocalAIModel? _loadedModel; public FoundryModelService( ILogger logger, IOptions options) { _logger = logger; _options = options.Value; } public async Task InitializeModelAsync() { try { _logger.LogInformation( "Loading Foundry model: {ModelAlias}", _options.ModelAlias ); // Load model from Foundry Local _loadedModel = await FoundryClient.LoadModelAsync( modelAlias: _options.ModelAlias, cancellationToken: CancellationToken.None ); if (_loadedModel == null) { _logger.LogWarning("Model loaded but returned null instance"); return false; } _logger.LogInformation( "Successfully loaded model: {ModelAlias}", _options.ModelAlias ); return true; } catch (Exception ex) { _logger.LogError( ex, "Failed to load Foundry model: {ModelAlias}", _options.ModelAlias ); return false; } } public ILocalAIModel? GetLoadedModel() => _loadedModel; public async Task UnloadModelAsync() { if (_loadedModel != null) { await FoundryClient.UnloadModelAsync(_loadedModel); _loadedModel = null; _logger.LogInformation("Model unloaded"); } } } Configuration lives in appsettings.json , enabling easy customization without code changes: { "Foundry": { "ModelAlias": "whisper-medium", "LogLevel": "Information" }, "Transcription": { "MaxAudioDurationSeconds": 300, "SupportedFormats": ["wav", "mp3", "m4a", "flac"], "DefaultLanguage": "en" } } Implementing Privacy-First Transcription Service The transcription service handles audio processing while maintaining strict privacy controls. No audio or transcript persists beyond the HTTP request lifecycle unless explicitly configured: // Services/TranscriptionService.cs public class TranscriptionService { private readonly FoundryModelService _modelService; private readonly ILogger _logger; public async Task TranscribeAudioAsync( Stream audioStream, string originalFileName, TranscriptionOptions? options = null) { options ??= new TranscriptionOptions(); var startTime = DateTime.UtcNow; try { // Validate audio format ValidateAudioFormat(originalFileName); // Get loaded model var model = _modelService.GetLoadedModel(); if (model == null) { throw new InvalidOperationException("Whisper model not loaded"); } // Create temporary file (automatically deleted after transcription) using var tempFile = new TempAudioFile(audioStream); // Execute transcription _logger.LogInformation( "Starting transcription for file: {FileName}", originalFileName ); var transcription = await model.TranscribeAsync( audioFilePath: tempFile.Path, language: options.Language, cancellationToken: CancellationToken.None ); var duration = (DateTime.UtcNow - startTime).TotalSeconds; _logger.LogInformation( "Transcription completed in {Duration:F2}s", duration ); return new TranscriptionResult { Text = transcription.Text, Language = transcription.Language ?? options.Language, Duration = transcription.AudioDuration, ProcessingTimeSeconds = duration, FileName = originalFileName, Timestamp = DateTime.UtcNow }; } catch (Exception ex) { _logger.LogError( ex, "Transcription failed for file: {FileName}", originalFileName ); throw; } } private void ValidateAudioFormat(string fileName) { var extension = Path.GetExtension(fileName).TrimStart('.'); var supportedFormats = new[] { "wav", "mp3", "m4a", "flac", "ogg" }; if (!supportedFormats.Contains(extension.ToLowerInvariant())) { throw new ArgumentException( $"Unsupported audio format: {extension}. " + $"Supported: {string.Join(", ", supportedFormats)}" ); } } } // Temporary file wrapper that auto-deletes internal class TempAudioFile : IDisposable { public string Path { get; } public TempAudioFile(Stream sourceStream) { Path = System.IO.Path.GetTempFileName(); using var fileStream = File.OpenWrite(Path); sourceStream.CopyTo(fileStream); } public void Dispose() { try { if (File.Exists(Path)) { File.Delete(Path); } } catch { // Ignore deletion errors in temp folder } } } This service demonstrates several privacy-first patterns: Temporary file lifecycle management: Audio written to temp storage, automatically deleted after transcription No implicit persistence: Results returned to caller, not saved by service Format validation: Accept only supported audio formats to prevent processing errors Comprehensive logging: Audit trail for compliance without logging PHI content Error isolation: Exceptions contain diagnostic info but no patient data Building the OpenAI-Compatible REST API The API endpoint mirrors OpenAI's transcription API specification, enabling existing integrations to work without modifications: // Program.cs var builder = WebApplication.CreateBuilder(args); // Configure services builder.Services.Configure( builder.Configuration.GetSection("Foundry") ); builder.Services.AddSingleton(); builder.Services.AddScoped(); builder.Services.AddHealthChecks() .AddCheck("foundry-health"); var app = builder.Build(); // Load model at startup var modelService = app.Services.GetRequiredService(); await modelService.InitializeModelAsync(); app.UseHealthChecks("/health"); app.MapHealthChecks("/api/health/status"); // OpenAI-compatible transcription endpoint app.MapPost("/v1/audio/transcriptions", async ( HttpRequest request, TranscriptionService transcriptionService, ILogger logger) => { if (!request.HasFormContentType) { return Results.BadRequest(new { error = "Content-Type must be multipart/form-data" }); } var form = await request.ReadFormAsync(); // Extract audio file var audioFile = form.Files.GetFile("file"); if (audioFile == null || audioFile.Length == 0) { return Results.BadRequest(new { error = "Audio file required in 'file' field" }); } // Parse options var format = form["format"].ToString() ?? "text"; var language = form["language"].ToString() ?? "en"; try { // Process transcription using var stream = audioFile.OpenReadStream(); var result = await transcriptionService.TranscribeAudioAsync( audioStream: stream, originalFileName: audioFile.FileName, options: new TranscriptionOptions { Language = language } ); // Return in requested format if (format == "json") { return Results.Json(new { text = result.Text, language = result.Language, duration = result.Duration }); } else { // Default: plain text return Results.Text(result.Text); } } catch (Exception ex) { logger.LogError(ex, "Transcription request failed"); return Results.StatusCode(500); } }) .DisableAntiforgery() // File uploads need CSRF exemption .WithName("TranscribeAudio") .WithOpenApi(); app.Run(); Example API usage: # PowerShell $audioFile = Get-Item "consultation-recording.wav" $response = Invoke-RestMethod ` -Uri "http://localhost:5192/v1/audio/transcriptions" ` -Method Post ` -Form @{ file = $audioFile; format = "json" } Write-Output $response.text # cURL curl -X POST http://localhost:5192/v1/audio/transcriptions \ -F "file=@consultation-recording.wav" \ -F "format=json" Building the Interactive Web Frontend The web UI provides a user-friendly interface for non-technical medical staff to transcribe recordings: SarahCare Medical Transcription The JavaScript handles file uploads and API interactions: // wwwroot/app.js let selectedFile = null; async function checkHealth() { try { const response = await fetch('/health'); const statusEl = document.getElementById('status'); if (response.ok) { statusEl.className = 'status-badge online'; statusEl.textContent = '✓ System Ready'; } else { statusEl.className = 'status-badge offline'; statusEl.textContent = '✗ System Unavailable'; } } catch (error) { console.error('Health check failed:', error); } } function handleFileSelect(event) { const file = event.target.files[0]; if (!file) return; selectedFile = file; // Show file info const fileInfo = document.getElementById('fileInfo'); fileInfo.textContent = `Selected: ${file.name} (${formatFileSize(file.size)})`; fileInfo.classList.remove('hidden'); // Enable audio preview const preview = document.getElementById('audioPreview'); preview.src = URL.createObjectURL(file); preview.classList.remove('hidden'); // Enable transcribe button document.getElementById('transcribeBtn').disabled = false; } async function transcribeAudio() { if (!selectedFile) return; const loadingEl = document.getElementById('loadingIndicator'); const resultEl = document.getElementById('resultSection'); const transcribeBtn = document.getElementById('transcribeBtn'); // Show loading state loadingEl.classList.remove('hidden'); resultEl.classList.add('hidden'); transcribeBtn.disabled = true; try { const formData = new FormData(); formData.append('file', selectedFile); formData.append('format', 'json'); const startTime = Date.now(); const response = await fetch('/v1/audio/transcriptions', { method: 'POST', body: formData }); if (!response.ok) { throw new Error(`HTTP ${response.status}: ${response.statusText}`); } const result = await response.json(); const processingTime = ((Date.now() - startTime) / 1000).toFixed(1); // Display results document.getElementById('transcriptionText').value = result.text; document.getElementById('resultDuration').textContent = `Duration: ${result.duration.toFixed(1)}s`; document.getElementById('resultLanguage').textContent = `Language: ${result.language}`; resultEl.classList.remove('hidden'); console.log(`Transcription completed in ${processingTime}s`); } catch (error) { console.error('Transcription failed:', error); alert(`Transcription failed: ${error.message}`); } finally { loadingEl.classList.add('hidden'); transcribeBtn.disabled = false; } } function copyToClipboard() { const text = document.getElementById('transcriptionText').value; navigator.clipboard.writeText(text) .then(() => alert('Copied to clipboard')) .catch(err => console.error('Copy failed:', err)); } // Initialize window.addEventListener('load', () => { checkHealth(); loadSamplesList(); }); Key Takeaways and Production Considerations Building HIPAA-compliant voice-to-text systems requires architectural decisions that prioritize data privacy over convenience. The FLWhisper application demonstrates that you can achieve accurate medical transcription, fast processing times, and intuitive user experiences entirely on-premises. Critical lessons for healthcare AI: Privacy by architecture: Design systems where PHI never exists outside controlled environments, not as a configuration option No persistence by default: Audio and transcripts should be ephemeral unless explicitly saved with proper access controls Model selection matters: Whisper Medium provides medical terminology accuracy that smaller models miss Health checks enable reliability: Systems should verify model availability before accepting PHI Audit logging without content logging: Track operations for compliance without storing sensitive data in logs For production deployment in clinical settings, integrate with EHR systems via HL7/FHIR interfaces. Implement role-based access control with Active Directory integration. Add digital signatures for transcript authentication. Configure automatic PHI redaction using clinical NLP models. Deploy on HIPAA-compliant infrastructure with proper physical security. Implement comprehensive audit logging meeting compliance requirements. The complete implementation with ASP.NET Core API, Foundry Local integration, sample audio files, and comprehensive tests is available at github.com/leestott/FLWhisper. Clone the repository and follow the setup guide to experience privacy-first medical transcription. Resources and Further Reading FLWhisper Repository - Complete C# implementation with .NET 10 Quick Start Guide - Installation and usage instructions Microsoft Foundry Local Documentation - SDK reference and model catalog OpenAI Whisper Documentation - Model architecture and capabilities HIPAA Compliance Guidelines - HHS official guidance Testing Guide - Comprehensive test suite documentation
MSB4184: The expression "[System.IO.Path]::GetDirectoryName('')" cannot be evaluate
Hi got this error now after I updated my VS IDE .... The path is not of a legal form. WinFormsSQLExamplePro C:\Program Files\dotnet\sdk\10.0.102\Sdks\Microsoft.NET.Sdk\targets\Microsoft.NET.Windows.targets <_WinRTRuntimeDllDirectory>$([System.IO.Path]::GetDirectoryName('%(_WinRTRuntimeDllReferencePath.FullPath)'))</_WinRTRuntimeDllDirectory> <_CsWinRTOrTargetingPackLibDirectory>$([System.IO.Path]::GetDirectoryName('$(_WinRTRuntimeDllDirectory)'))</_CsWinRTOrTargetingPackLibDirectory> Note the top most path entry contains a '%' character , whereas the 2nd path contains a '$' character... Not sure what is going on ... (happened after VS update)429Views0likes1Comment
Need help with ClickOnce deployment on .NET Framework 4.7.2 – "Unidentified program" warning
Hello, I have a WinForms application built on .NET Framework 4.7.2 that I'm publishing using ClickOnce from Visual Studio Community 2022 (official Microsoft version). Even after signing the application with a valid SHA256 V3 self-signed certificate, when I publish and try to install it via ClickOnce, I receive a warning saying the program is unidentified. Additionally, when I try to install the application on a machine that has antivirus software, the antivirus flags the program precisely because of the missing/certificate validation issue. How should I proceed? I'd like to know the correct way to publish with ClickOnce so that the application is fully recognized as valid by Windows, since I'm running into these antivirus validation problems. Thanks in advance for any guidance!219Views0likes1CommentAgents League: The Esports-Inspired Hackathon Where AI Agents Battle for Glory
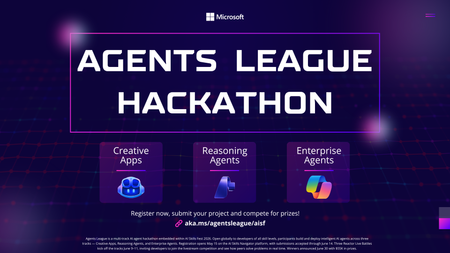
Ready to put your AI skills to the ultimate test? Agents League is here, a dynamic, esports-inspired developer challenge that brings the thrill of live competition to the world of agentic AI. Whether you're a seasoned AI developer or just getting started, this is your chance to build, compete, and win. What is Agents League? Agents League is a week-long hackathon running as part of AI Skills Fest (June 4–14, 2026). Unlike traditional hackathons, Agents League combines live AI coding battles, asynchronous project submissions, and a thriving Discord community all competing for a total prize pool of $55,000 USD. This isn't just about building it's about showcasing what's possible with agentic AI in a format that's fast, competitive, and globally accessible. Three Challenge Tracks Pick One or Compete in All 1. Creative Apps Build innovative applications using GitHub Copilot for AI-assisted development. Show off your creativity and demonstrate how AI can accelerate app creation from concept to code. 2. Reasoning Agents Create intelligent agents using Microsoft Foundry that solve complex problems through multi-step reasoning. This track is all about building agents that can think, plan, and execute. 3. Enterprise Agents Build business-ready knowledge agents integrated with Microsoft 365 Copilot, authored in Copilot Studio. Perfect for developers focused on real-world enterprise solutions. Live Microsoft Reactor Events—Don't Miss the Battles! The heart of Agents League beats through live Microsoft Reactor events. Watch experts go head-to-head in live coding battles, learn cutting-edge techniques, and get inspired for your own submissions: Event What You'll Learn Creative Apps Battle See GitHub Copilot in action as experts build innovative apps live Reasoning Agents Battle Watch multi-step reasoning agents come to life with Microsoft Foundry Enterprise Agents Battle Learn to build M365-integrated agents with Copilot Studio 👉 View the full event series Key Dates Registration Deadline: June 12, 2026, 12:00 PM PT Hacking Period: June 4–14, 2026 Submission Deadline: June 14, 2026, 11:59 PM PT What You Get Live coding battles with expert demonstrations Curated technical experiences and on-demand content Learning resources on Microsoft Learn and AI Skills Navigator Community support through Discord GitHub-based submissions for transparent, collaborative judging Why Participate? Agents League isn't just another hackathon. It's designed as a streamlined, competitive format that: ✅ Fits into your schedule with focused, time-boxed challenges ✅ Provides real-world product innovation experience ✅ Offers global accessibility—participate from anywhere ✅ Demonstrates the latest capabilities of agentic AI, including new IQ tools ✅ Connects you with a passionate developer community Ready to Enter the Arena? Register Now for Agents League Before you register: Review the Hackathon Rules and Regulations for prize categories and judging criteria Join the Microsoft Reactor event series for live battles and learning Check out the Microsoft Event Code of Conduct Join the Conversation Have questions? Want to connect with fellow competitors? Join the Agents League community on Discord and start strategizing with developers from around the world. Whether you're building creative apps, reasoning agents, or enterprise solutions—the arena awaits. May the best agent win! 🏆 Agents League hackathon is open to the public and offered at no cost. Government employees should check with their employers to ensure participation is permitted in accordance with applicable policies. Related Links: Agents League Hackathon Registration Microsoft Reactor Series AI Skills FestHow to build long-running MCP tools on Azure Functions
Recently, a customer building servers with the Azure Functions MCP extension reached out and asked: How do I handle tools that take longer than the client is willing to wait? This becomes especially relevant when tool calls move beyond simple request/response into multi-step workflows and long-running operations. At the same time, MCP is evolving to address exactly this. The Tasks extension is introduced in the 2026-07-28 release candidate, defining a standard way to model long-running work. In this post, we’ll walk through how to build long-running MCP tools on Azure Functions using Durable Functions , a framework for authoring stateful, long-running workflows as ordinary code, with checkpointing, scaling, and recovery handled automatically. MCP tools today Today, MCP tools are fundamentally request/response: the client issues a tools/call the server returns a result This works well for fast operations, but breaks down when: workflows take minutes execution depends on multiple steps latency is unpredictable In practice, clients enforce their own tool-call timeouts. These aren't standardized by the MCP spec and vary per client, but they're often in the ~30–60 second range. If a tool exceeds that window: In practice, clients often enforce short timeouts. If a tool exceeds that window: the client times out the agent observes a failed call the underlying work may still be running So the core issue is that you have synchronous tool calls don’t naturally model long-running work. The MCP Tasks extension The Tasks extension to address this. With the extension, a server can respond to a tools/call with an asynchronous task handle instead of a final result, and the client drives the lifecycle from there: tasks/get: poll the task's status tasks/update: submit input back to the server if the task reaches input_required tasks/cancel: cancel an in-flight task A task carries a status ("working", "input_required", "completed", "failed", or "cancelled") and on completion, the final result. Task creation is server-directed: the client advertises support by including the extension in its per-request capabilities, and the server decides per request whether to return a task. A server won't return a task to a client that hasn't advertised support. It's important to note that Tasks rely on ecosystem support. Clients must advertise the extension, and MCP SDKs must implement the task lifecycle, before servers can use it. So while Tasks is now a defined extension, broad client and SDK support is still in progress. Implement long-runng tasks with Durable Functions today Until the Tasks extension is broadly supported across clients, we need a pattern that works with existing request/response clients and supports long-running execution. The following samples show how, using Durable Functions: Python NET The long-running work in this sample mines a short chain of blocks. Each block requires solving a computational puzzle where the system keeps trying different inputs until it finds one that produces a result matching a specific pattern (for example, starting with a certain number of zeros). Because this involves lots of trial and error, it naturally takes time, making it a good example of a long-running workflow. The server in the sample exposes two tools: start_mining Starts a Durable Functions orchestration to mine the blocks Waits briefly (within a configurable budget) Returns result inline if completed within budget OR returns workflow_id if still running get_mining_result Takes the workflow_id Returns the current state, e.g. "completed", "running", "failed", or "not_found" To ensure that the agent calls the tools in the right order, workflow_id is a required parameter of get_mining_result, so the agent can't poll without starting a mining run first. Also, the "running" response carries a poll_after_seconds and a next instruction, ensuring the agent to poll again if work is not done rather than give up or assume completion. Even so, the poll path still relies on the agent correctly remembering, and not hallucinating, the workflow_id it was handed. If it garbles or invents an id, the poll lands on the wrong instance or none at all (which is why get_mining_result returns "not_found" rather than guessing). What changes with the Tasks extension Once the Tasks extension is fully implemented across clients and SDKs, the model becomes simpler and more reliable: the server returns a Task handle, the client manages the polling and lifecyle calls, and the SDK tracks execution state. This removes a key limitation of today’s solution, which requires the agent to remember and correctly pass identifiers like workflow_id. Call to action Try out the sample and let us know whether it addresses your MCP needs around long-running or workflow type tools!652Views0likes0CommentsBuild Multi-Agent AI Apps on Azure App Service with Microsoft Agent Framework 1.0
Part 1 of 3 — Multi-Agent AI on Azure App Service This is part 1 of a 3 part series on deploying and working with multi-agent AI on Azure App Service. Follow allong to learn how to deploy, manage, observe, and secure your agents on Azure App Service. A couple of months ago, we published a three-part series showing how to build multi-agent AI systems on Azure App Service using preview packages from the Microsoft Agent Framework (MAF) (formerly AutoGen / Semantic Kernel Agents). The series walked through async processing, the request-reply pattern, and client-side multi-agent orchestration — all running on App Service. Since then, Microsoft Agent Framework has reached 1.0 GA — unifying AutoGen and Semantic Kernel into a single, production-ready agent platform. This post is a fresh start with the GA bits. We'll rebuild our travel-planner sample on the stable API surface, call out the breaking changes from preview, and get you up and running fast. All of the code is in the companion repo: seligj95/app-service-multi-agent-maf-otel. What Changed in MAF 1.0 GA The 1.0 release is more than a version bump. Here's what moved: Unified platform. AutoGen and Semantic Kernel agent capabilities have converged into Microsoft.Agents.AI . One package, one API surface. Stable APIs with long-term support. The 1.0 contract is now locked for servicing. No more preview churn. Breaking change — Instructions on options removed. In preview, you set instructions through ChatClientAgentOptions.Instructions . In GA, pass them directly to the ChatClientAgent constructor. Breaking change — RunAsync parameter rename. The thread parameter is now session (type AgentSession ). If you were using named arguments, this is a compile error. Microsoft.Extensions.AI upgraded. The framework moved from the 9.x preview of Microsoft.Extensions.AI to the stable 10.4.1 release. OpenTelemetry integration built in. The builder pipeline now includes UseOpenTelemetry() out of the box — more on that in Blog 2. Our project references reflect the GA stack: <PackageReference Include="Microsoft.Agents.AI" Version="1.0.0" /> <PackageReference Include="Microsoft.Extensions.AI" Version="10.4.1" /> <PackageReference Include="Azure.AI.OpenAI" Version="2.1.0" /> Why Azure App Service for AI Agents? If you're building with Microsoft Agent Framework, you need somewhere to run your agents. You could reach for Kubernetes, containers, or serverless — but for most agent workloads, Azure App Service is the sweet spot. Here's why: No infrastructure management — App Service is fully managed. No clusters to configure, no container orchestration to learn. Deploy your .NET or Python agent code and it just runs. Always On — Agent workflows can take minutes. App Service's Always On feature (on Premium tiers) ensures your background workers never go cold, so agents are ready to process requests instantly. WebJobs for background processing — Long-running agent workflows don't belong in HTTP request handlers. App Service's built-in WebJob support gives you a dedicated background worker that shares the same deployment, configuration, and managed identity — no separate compute resource needed. Managed Identity everywhere — Zero secrets in your code. App Service's system-assigned managed identity authenticates to Azure OpenAI, Service Bus, Cosmos DB, and Application Insights automatically. No connection strings, no API keys, no rotation headaches. Built-in observability — Native integration with Application Insights and OpenTelemetry means you can see exactly what your agents are doing in production (more on this in Part 2). Enterprise-ready — VNet integration, deployment slots for safe rollouts, custom domains, auto-scaling rules, and built-in authentication. All the things you'll need when your agent POC becomes a production service. Cost-effective — A single P0v4 instance (~$75/month) hosts both your API and WebJob worker. Compare that to running separate container apps or a Kubernetes cluster for the same workload. The bottom line: App Service lets you focus on building your agents, not managing infrastructure. And since MAF supports both .NET and Python — both first-class citizens on App Service — you're covered regardless of your language preference. Architecture Overview The sample is a travel planner that coordinates six specialized agents to build a personalized trip itinerary. Users fill out a form (destination, dates, budget, interests), and the system returns a comprehensive travel plan complete with weather forecasts, currency advice, a day-by-day itinerary, and a budget breakdown. The Six Agents Currency Converter — calls the Frankfurter API for real-time exchange rates Weather Advisor — calls the National Weather Service API for forecasts and packing tips Local Knowledge Expert — cultural insights, customs, and hidden gems Itinerary Planner — day-by-day scheduling with timing and costs Budget Optimizer — allocates spend across categories and suggests savings Coordinator — assembles everything into a polished final plan Four-Phase Workflow Phase Agents Execution 1 — Parallel Gathering Currency, Weather, Local Knowledge Task.WhenAll 2 — Itinerary Itinerary Planner Sequential (uses Phase 1 context) 3 — Budget Budget Optimizer Sequential (uses Phase 2 output) 4 — Assembly Coordinator Final synthesis Infrastructure Azure App Service (P0v4) — hosts the API and a continuous WebJob for background processing Azure Service Bus — decouples the API from heavy AI work (async request-reply) Azure Cosmos DB — stores task state, results, and per-agent chat histories (24-hour TTL) Azure OpenAI (GPT-4o) — powers all agent LLM calls Application Insights + Log Analytics — monitoring and diagnostics ChatClientAgent Deep Dive At the core of every agent is ChatClientAgent from Microsoft.Agents.AI . It wraps an IChatClient (from Microsoft.Extensions.AI ) with instructions, a name, a description, and optionally a set of tools. This is client-side orchestration — you control the chat history, lifecycle, and execution order. No server-side Foundry agent resources are created. Here's the BaseAgent pattern used by all six agents in the sample: // BaseAgent.cs — constructor for agents with tools Agent = new ChatClientAgent( chatClient, instructions: Instructions, name: AgentName, description: Description, tools: chatOptions.Tools?.ToList()) .AsBuilder() .UseOpenTelemetry(sourceName: AgentName) .Build(); Notice the builder pipeline: .AsBuilder().UseOpenTelemetry(...).Build() . This opts every agent into the framework's built-in OpenTelemetry instrumentation with a single line. We'll explore what that telemetry looks like in Blog 2. Invoking an agent is equally straightforward: // BaseAgent.cs — InvokeAsync public async Task<ChatMessage> InvokeAsync( IList<ChatMessage> chatHistory, CancellationToken cancellationToken = default) { var response = await Agent.RunAsync( chatHistory, session: null, options: null, cancellationToken); return response.Messages.LastOrDefault() ?? new ChatMessage(ChatRole.Assistant, "No response generated."); } Key things to note: session: null — this is the renamed parameter (was thread in preview). We pass null because we manage chat history ourselves. The agent receives the full chatHistory list, so context accumulates across turns. Simple agents (Local Knowledge, Itinerary Planner, Budget Optimizer, Coordinator) use the tool-less constructor; agents that call external APIs (Currency, Weather) use the constructor that accepts ChatOptions with tools. Tool Integration Two of our agents — Weather Advisor and Currency Converter — call real external APIs through the MAF tool-calling pipeline. Tools are registered using AIFunctionFactory.Create() from Microsoft.Extensions.AI . Here's how the WeatherAdvisorAgent wires up its tool: // WeatherAdvisorAgent.cs private static ChatOptions CreateChatOptions( IWeatherService weatherService, ILogger logger) { var chatOptions = new ChatOptions { Tools = new List<AITool> { AIFunctionFactory.Create( GetWeatherForecastFunction(weatherService, logger)) } }; return chatOptions; } GetWeatherForecastFunction returns a Func<double, double, int, Task<string>> that the model can call with latitude, longitude, and number of days. Under the hood, it hits the National Weather Service API and returns a formatted forecast string. The Currency Converter follows the same pattern with the Frankfurter API. This is one of the nicest parts of the GA API: you write a plain C# method, wrap it with AIFunctionFactory.Create() , and the framework handles the JSON schema generation, function-call parsing, and response routing automatically. Multi-Phase Workflow Orchestration The TravelPlanningWorkflow class coordinates all six agents. The key insight is that the orchestration is just C# code — no YAML, no graph DSL, no special runtime. You decide when agents run, what context they receive, and how results flow between phases. // Phase 1: Parallel Information Gathering var gatheringTasks = new[] { GatherCurrencyInfoAsync(request, state, progress, cancellationToken), GatherWeatherInfoAsync(request, state, progress, cancellationToken), GatherLocalKnowledgeAsync(request, state, progress, cancellationToken) }; await Task.WhenAll(gatheringTasks); After Phase 1 completes, results are stored in a WorkflowState object — a simple dictionary-backed container that holds per-agent chat histories and contextual data: // WorkflowState.cs public Dictionary<string, object> Context { get; set; } = new(); public Dictionary<string, List<ChatMessage>> AgentChatHistories { get; set; } = new(); Phases 2–4 run sequentially, each pulling context from the previous phase. For example, the Itinerary Planner receives weather and local knowledge gathered in Phase 1: var localKnowledge = state.GetFromContext<string>("LocalKnowledge") ?? ""; var weatherAdvice = state.GetFromContext<string>("WeatherAdvice") ?? ""; var itineraryChatHistory = state.GetChatHistory("ItineraryPlanner"); itineraryChatHistory.Add(new ChatMessage(ChatRole.User, $"Create a detailed {days}-day itinerary for {request.Destination}..." + $"\n\nWEATHER INFORMATION:\n{weatherAdvice}" + $"\n\nLOCAL KNOWLEDGE & TIPS:\n{localKnowledge}")); var itineraryResponse = await _itineraryAgent.InvokeAsync( itineraryChatHistory, cancellationToken); This pattern — parallel fan-out followed by sequential context enrichment — is simple, testable, and easy to extend. Need a seventh agent? Add it to the appropriate phase and wire it into WorkflowState . Async Request-Reply Pattern A multi-agent workflow with six LLM calls (some with tool invocations) can easily run 30–60 seconds. That's well beyond typical HTTP timeout expectations and not a great user experience for a synchronous request. We use the Async Request-Reply pattern to handle this: The API receives the travel plan request and immediately queues a message to Service Bus. It stores an initial task record in Cosmos DB with status queued and returns a taskId to the client. A continuous WebJob (running as a separate process on the same App Service plan) picks up the message, executes the full multi-agent workflow, and writes the result back to Cosmos DB. The client polls the API for status updates until the task reaches completed . This pattern keeps the API responsive, makes the heavy work retriable (Service Bus handles retries and dead-lettering), and lets the WebJob run independently — you can restart it without affecting the API. We covered this pattern in detail in the previous series, so we won't repeat the plumbing here. Deploy with azd The repo is wired up with the Azure Developer CLI for one-command provisioning and deployment: git clone https://github.com/seligj95/app-service-multi-agent-maf-otel.git cd app-service-multi-agent-maf-otel azd auth login azd up azd up provisions the following resources via Bicep: Azure App Service (P0v4 Windows) with a continuous WebJob Azure Service Bus namespace and queue Azure Cosmos DB account, database, and containers Azure AI Services (Azure OpenAI with GPT-4o deployment) Application Insights and Log Analytics workspace Managed Identity with all necessary role assignments After deployment completes, azd outputs the App Service URL. Open it in your browser, fill in the travel form, and watch six agents collaborate on your trip plan in real time. What's Next We now have a production-ready multi-agent app running on App Service with the GA Microsoft Agent Framework. But how do you actually observe what these agents are doing? When six agents are making LLM calls, invoking tools, and passing context between phases — you need visibility into every step. In the next post, we'll dive deep into how we instrumented these agents with OpenTelemetry and the new Agents (Preview) view in Application Insights — giving you full visibility into agent runs, token usage, tool calls, and model performance. You already saw the .UseOpenTelemetry() call in the builder pipeline; Blog 2 shows what that telemetry looks like end to end and how to light up the new Agents experience in the Azure portal. Stay tuned! Resources Sample repo — app-service-multi-agent-maf-otel Microsoft Agent Framework 1.0 GA Announcement Microsoft Agent Framework Documentation Previous Series — Part 3: Client-Side Multi-Agent Orchestration on App Service Microsoft.Extensions.AI Documentation Azure App Service Documentation Blog 2: Monitor AI Agents on App Service with OpenTelemetry and the New Application Insights Agents View Blog 3: Govern AI Agents on App Service with the Microsoft Agent Governance Toolkit1.9KViews0likes0CommentsMastering Query Fields in Azure AI Document Intelligence with C#
Introduction Azure AI Document Intelligence simplifies document data extraction, with features like query fields enabling targeted data retrieval. However, using these features with the C# SDK can be tricky. This guide highlights a real-world issue, provides a corrected implementation, and shares best practices for efficient usage. Use case scenario During the cause of Azure AI Document Intelligence software engineering code tasks or review, many developers encountered an error while trying to extract fields like "FullName," "CompanyName," and "JobTitle" using `AnalyzeDocumentAsync`: The error might be similar to Inner Error: The parameter urlSource or base64Source is required. This is a challenge referred to as parameter errors and SDK changes. Most problematic code are looks like below in C#: BinaryData data = BinaryData.FromBytes(Content); var queryFields = new List<string> { "FullName", "CompanyName", "JobTitle" }; var operation = await client.AnalyzeDocumentAsync( WaitUntil.Completed, modelId, data, "1-2", queryFields: queryFields, features: new List<DocumentAnalysisFeature> { DocumentAnalysisFeature.QueryFields } ); One of the reasons this failed was that the developer was using `Azure.AI.DocumentIntelligence v1.0.0`, where `base64Source` and `urlSource` must be handled internally. Because the older examples using `AnalyzeDocumentContent` no longer apply and leading to errors. Practical Solution Using AnalyzeDocumentOptions. Alternative Method using manual JSON Payload. Using AnalyzeDocumentOptions The correct method involves using AnalyzeDocumentOptions, which streamlines the request construction using the below steps: Prepare the document content: BinaryData data = BinaryData.FromBytes(Content); Create AnalyzeDocumentOptions: var analyzeOptions = new AnalyzeDocumentOptions(modelId, data) { Pages = "1-2", Features = { DocumentAnalysisFeature.QueryFields }, QueryFields = { "FullName", "CompanyName", "JobTitle" } }; - `modelId`: Your trained model’s ID. - `Pages`: Specify pages to analyze (e.g., "1-2"). - `Features`: Enable `QueryFields`. - `QueryFields`: Define which fields to extract. Run the analysis: Operation<AnalyzeResult> operation = await client.AnalyzeDocumentAsync( WaitUntil.Completed, analyzeOptions ); AnalyzeResult result = operation.Value; The reason this works: The SDK manages `base64Source` automatically. This approach matches the latest SDK standards. It results in cleaner, more maintainable code. Alternative method using manual JSON payload For advanced use cases where more control over the request is needed, you can manually create the JSON payload. For an example: var queriesPayload = new { queryFields = new[] { new { key = "FullName" }, new { key = "CompanyName" }, new { key = "JobTitle" } } }; string jsonPayload = JsonSerializer.Serialize(queriesPayload); BinaryData requestData = BinaryData.FromString(jsonPayload); var operation = await client.AnalyzeDocumentAsync( WaitUntil.Completed, modelId, requestData, "1-2", features: new List<DocumentAnalysisFeature> { DocumentAnalysisFeature.QueryFields } ); When to use the above: Custom request formats Non-standard data source integration Key points to remember Breaking changes exist between preview versions and v1.0.0 by checking the SDK version. Prefer `AnalyzeDocumentOptions` for simpler, error-free integration by using built-In classes. Ensure your content is wrapped in `BinaryData` or use a direct URL for correct document input: Conclusion Using AnalyzeDocumentOptions provides a cleaner and more reliable way to work with query fields in Azure AI Document Intelligence using C#. By aligning with the latest SDK approach, developers can simplify implementation, reduce common errors, and improve code maintainability. Keeping up with SDK enhancements and recommended practices ensures more accurate and efficient document data extraction. As Azure AI capabilities continue to evolve, adopting modern integration patterns will help you build scalable and future-ready document processing solutions with greater confidence. Reference Official AnalyzeDocumentAsync Documentation. Official Azure SDK documentation. Azure Document Intelligence C# SDK support add-on query field.556Views0likes0Comments