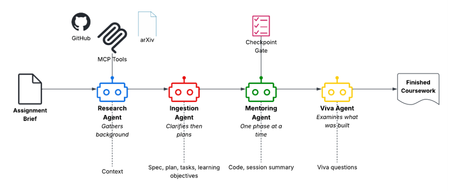
Really impressive work, Mark — the phase-gating approach (can't advance without passing a checkpoint) is a clever way to force genuine engagement rather than passive prompt-and-submit. Most "AI tutor" tools I've seen skip this entirely.
A few things stood out to me:
- The decision to pivot away from using it as an assessment tool once you realized the model can't reliably interpret an educator's intent — that's a mature call, and I think a lot of teams would've been tempted to push forward anyway just to hit a "grading AI" headline feature.
- The SpecBench results are a great honest data point 97.7% on json parser vs. complete failure on crypto_primitives really illustrates where local models like Qwen3.6-27B currently sit. Did you consider a hybrid approach (local model for simpler phases, cloud model only when complexity crosses a threshold) to balance cost and reliability, or did the phase-gated architecture make that harder to implement cleanly?
- The Viva Agent interviewing students against prepared key points is a nice touch curious how you're handling partial/creative answers that are technically correct but phrased very differently from your prepared answer key. Is that purely LLM-judged, or is there a rubric layer?
Great use of the Microsoft Agent Framework + SpecKit combo. Looking forward to seeing where the validation agent idea goes.