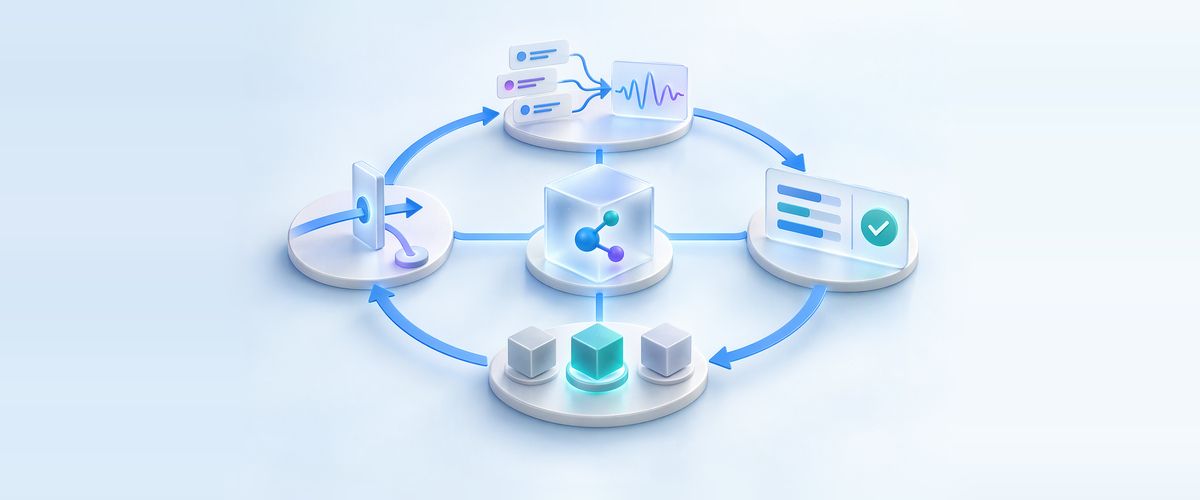
Connect production traces, Agent Optimizer, regression tests, and CI/CD to control how agent updates reach customers.
A production agent can lose accuracy or cost too much without a single code change. As live traffic grows, new user requests expose gaps in the agent instructions. At the same time, newer models can offer better quality or lower operating cost. Yet editing prompts by hand or swapping models in place risks breaking workflows that already work.
The diagram uses v1 and v2 for the active baseline and candidate; Microsoft Foundry assigns the actual version numbers.
Prerequisites and integration responsibilities
Before implementing this workflow, verify these platform resources and application components:
- Microsoft Foundry resources: Deploy a hosted agent with the Agent Optimizer SDK. Connect Application Insights, deploy approved models, and grant Microsoft Entra ID permissions.
- Application team responsibilities: Supply the sandboxed tool test harness, reviewed outcome labels (
ground_truth), the CI/CD release policy script, and session canary routing (version_indicator).
How the scheduled loop runs end to end
A scheduled GitHub Actions workflow or an Azure Monitor alert starts each cycle across Microsoft Foundry and GitHub Actions. On each run, the workflow reads recent continuous evaluation scores, Application Insights error metrics, and newly approved model deployments. When triage confirms an agent quality drop or a scheduled model evaluation, the workflow samples recent traces into a dataset for human label review. Next, Agent Optimizer searches across instructions, skills, tool descriptions, and models on your training and validation datasets. Your release automation applies the selected candidate and opens a pull request for engineer review. It then gates promotion on a held-out regression suite and updates .agent_configs/baseline/ after promotion.
1. Monitor live traffic with continuous evaluation
Safe promotion starts with measuring the active production configuration, which serves as the baseline for every comparison against a proposed candidate. On live traffic, Microsoft Foundry continuous evaluation scores execution traces to track how quality, tool use, latency, and cost change over time:
- Tool output versus reply (
groundedness). Checks whether the reply has support in the supplied context, flagging unsupported completion claims. - Instructions versus actions (
task_adherence). Checks whether the agent followed its system prompt rules during the conversation. - Query versus tool calls (
tool_call_accuracyandintent_resolution). Verifies that the agent selected the right tool and arguments for the user's request. - Safety and trace rules (
indirect_attackand span checks). Flags injected instructions while span checks detect tool errors and repeated write calls.
Triage alerts and set the optimization objective
When a quality alert fires, check Application Insights traces and Azure Monitor metrics first. Separate an agent configuration issue from other operational changes before running an optimizer job:
- Backend or tool outages. Rising tool timeouts or API errors call for infrastructure recovery before you tune the agent.
- Traffic-mix shifts. A surge in a new request type may require new tools, policy rules, or test coverage before optimization.
- Evaluator or rubric updates. A changed grader prompt or threshold shifts scores even when agent behavior is unchanged.
Confirm that a configuration change can address the issue, or start a run from a scheduled review or new model deployment. Define the objective up front:
| Optimization objective | Primary target | Mandatory requirements |
|---|---|---|
| Improve quality | Achieve a target score gain on failing task categories and meet the required quality floor | Preserve scores in existing categories, pass all critical safety and business checks, and stay within cost and latency limits |
| Reduce operating cost | Lower token and model cost across the agent workload | Meet the quality floor, stay within the allowed variation margin, pass all critical checks, and stay within latency limits |
2. Turn production traces into isolated, executable datasets
Once monitoring identifies what to improve, the next step is building the evaluation datasets for Agent Optimizer and CI/CD. Microsoft Foundry trace dataset generation (project_client.datasets.begin_create_generation_job) samples production traces from Application Insights into a versioned dataset registered in your project.
When you set max_samples, Microsoft Foundry uses MinHash sampling to filter out repetitive messages and select diverse conversations. Pinning agent_version samples behavior from one known release while redacting private content (redact_private_content=True) by default. In a tool-using workflow such as an order refund agent, flagged traces often expose three failure patterns:
- Unsafe retries after a tool timeout. The agent calls a write tool such as
submit_refund, and the call times out withoutcome_unknown. The agent repeats the write request before it checks the first request's status. The backend must also prevent duplicate transactions. - Premature completion claims on asynchronous work. The agent skips
get_refund_statusand reports a refund ascompletedwhile backend processing remainspending. - Prompt injection inside untrusted tool data. The agent obeys injected text inside a customer return note (
untrusted_return_note) and reports an unverified status.
Figure 1. The agent checks the refund status after a timed-out submission. The tool sequence shows how it handles an unknown outcome.
Bridge the gap from recorded traces to safe test execution
A generated trace dataset captures the conversation history from production. Turning those recorded interactions into safe, repeatable evaluation cases requires verified expected outcomes and a sandboxed test backend. Keep all evaluation runs isolated from live payment APIs and customer databases:
- Review expected outcomes (
ground_truth). Inspect each sampled trace and add the reviewed business outcome (status,order_id,refund_id, andreason) toground_truth. Preserve the original capturedresponseas the historical record. - Isolate tool execution in a test harness. Bind each evaluation case to controlled tool doubles and a resettable test database or ledger snapshot. Every evaluation run executes fresh tool calls against this sandbox.
- Keep optimizer data separate from the release regression suite. Split reviewed cases into training and validation datasets (
2a) for Agent Optimizer, and reserve a held-out regression suite (2b) for CI/CD release gating. Keep all requests from the same incident in one data split.
Figure 2. This example dataset uses synthetic interactions to illustrate the production trace workflow. Reviewers verify expected outcomes and pair each case with isolated test state.
3. Configure eval.yaml and evaluators against fixed requirements
With the datasets registered in Microsoft Foundry, define how each run is scored. Use eval.yaml to bind your baseline agent configuration, the training and validation datasets, evaluators, and approved model search space:
name: Refund agent configuration search
agent:
  name: refund-release-loop
  kind: hosted
  model: gpt-5.4-mini
  config: .agent_configs/baseline/metadata.yaml
dataset:
  name: refund-loop-training
  version: "1"
validation_dataset:
  name: refund-loop-validation
  version: "1"
evaluators:
  - builtin.task_adherence
  - name: refund-state
    version: "3"
options:
  eval_model: gpt-5.4-mini
  optimization_model: gpt-5.4
  max_candidates: 4
  optimization_config:
    model_search_space:
      - gpt-5.4-mini
      - gpt-5.4
Keep the held-out regression suite (refund-loop-release) in a separate CI/CD evaluation configuration so Agent Optimizer cannot access or overfit those cases during search.
Keep release criteria independent of candidate instructions
Prompt evaluators such as builtin.task_adherence help spot instruction drift, while Agent Optimizer rewrites instructions.md and SKILL.md to improve performance. Grade every candidate against fixed business requirements kept outside the editable agent configuration:
| Evaluator type | What it checks on each fresh sandboxed run | How it protects the release gate |
|---|---|---|
| Semantic and rubric evaluators | Grades the reply against fixed task-level criteria, mapped grounding context, and ground truth | Allows better phrasing or model changes while enforcing business rules and grounded claims |
| Custom code evaluator | Inspects the tool call sequence, structured JSON output, and resulting sandbox ledger state | Blocks duplicate write calls, skipped status checks, and mismatched transaction states |
To use builtin.groundedness on tool-supported claims, pass serialized tool outputs as grounding context and map that field in your evaluator inputs. Before testing, set your quality floor, target gain or cost savings, and allowed regression margin. Semantic evaluation permits harmless wording changes. The regression margin defines the largest acceptable quality loss. Assess sampling uncertainty separately.
Microsoft Foundry custom code evaluators inspect the candidate's tool events and sandbox state snapshot directly. The following illustrative check blocks duplicate refund submissions and status claims that disagree with the verification tool or ledger:
# Illustrative custom code evaluator logic
submissions = [e for e in events if e["tool"] == "submit_refund"]
if len(submissions) > 1:
    failures.append("repeated_submission")

verifications = [e["result"] for e in events if e["tool"] == "get_refund_status"]
claimed = output.get("status")
if claimed in {"completed", "pending", "failed"}:
    if not verifications or verifications[-1].get("status") != claimed:
        failures.append("unverified_claim")
    if not ledger or ledger[-1].get("status") != claimed:
        failures.append("claim_state_mismatch")
Because custom code evaluators run in an isolated environment without network access, the evaluation harness attaches the resulting sandbox state snapshot to each evaluation item.
4. Run Agent Optimizer on your evaluation dataset
Once eval.yaml is ready, run Agent Optimizer from your agent project root:
azd ai agent optimize
The command detects eval.yaml automatically. Agent Optimizer is in preview; see the optimization quickstart for supported flags and regions. During the job, it scores .agent_configs/baseline/, proposes up to max_candidates revisions from training tasks, and ranks candidates on validation_dataset:
| Optimization target | Baseline input | What Agent Optimizer changes |
|---|---|---|
| Instruction tuning | instructions.md | Rewrites the system prompt with explicit constraints, step ordering, and output format rules |
| Skill improvement | skills/<name>/SKILL.md | Refines domain skill descriptions, bodies, and activation criteria while keeping their purpose intact |
| Tool optimization | tools.json | Clarifies function and parameter descriptions without changing the executable tool schema |
| Model selection | model_search_space in eval.yaml | Tests candidate model deployments from the approved list in your Foundry project |
Load the selected instructions, skills, model, and tool descriptions at runtime with load_config(). Keep application logic, authorization, and tool contracts outside the optimization scope. For an illustrative submit_refund timeout, a candidate can update the refund skill and tool descriptions to check get_refund_status first. The configuration diff shows the intended changes, while evaluation provides evidence that the agent follows your business rules.
Figure 3. The comparison ranks four candidates on validation runs. The selected candidate refines the skill and tool descriptions.
5. Gate the candidate in GitHub Actions CI/CD
After you select a candidate in Agent Optimizer, apply its configuration to .agent_configs/ and open a pull request for review:
azd ai agent optimize apply --candidate <candidate-id>
In GitHub Actions, the workflow signs in to Azure with Microsoft Entra ID. It then runs a four-step release gate while live traffic stays on v1:
- Deploy the candidate version (
v2). Runazd deploy --no-promptto register the candidate container without changing the endpoint selector (v1). - Evaluate both pinned versions on the held-out suite (
2b). Run cloud evaluations onrefund-loop-releaseforv1andv2(orazd ai agent eval runper version). - Retrieve complete grades and resource metrics. Collect all evaluator scores, latency metrics, and model token counts from both completed runs.
- Enforce the release policy. Compare
v2againstv1using the objective from Step 1, and exit non-zero when the policy fails:
| Release check result | Outcome on the held-out regression suite | CI/CD gate action |
|---|---|---|
| Quality objective pass | Candidate clears the quality floor, meets the required quality gain after accounting for sampling uncertainty, passes all critical checks, and stays within resource limits | Pass the release gate and permit canary verification |
| Cost objective pass | Candidate reduces measured model spend (using model token pricing), clears the quality floor, stays within the allowed regression margin, and passes all critical checks | Pass the release gate and permit canary verification |
| Insufficient gain or savings | Candidate misses the target quality gain or measured cost reduction | Keep the baseline active |
| Regression or critical failure | Candidate drops below the quality floor or triggers repeated_submission, unverified_claim, or claim_state_mismatch | Fail the workflow and block release |
Separate evaluation job health from agent task performance. Every test case must return a complete evaluation record and all required evaluator scores; missing records or failed evaluator jobs always block release. Score recorded agent execution errors (such as a malformed response) as task failures. This lets a candidate repair a broken baseline case, such as an illustrative outcome_unknown timeout retry. Fixing one failure mode alone does not satisfy every release requirement. In Figure 4, the gate blocks promotion when the run shows category regressions, excess token usage, or incomplete baseline evidence.
Figure 4. GitHub Actions deploys the candidate version, blocks release when the held-out regression suite fails, and skips endpoint promotion.
6. Run a canary release, promote, and prepare the next cycle
Passing the held-out regression suite provides evidence that the candidate meets the requirements covered by those tests. Verify live traffic in four steps before full promotion:
- Smoke-test the deployed version. Send synthetic sessions with
version_indicatorset tov2to verify container startup, credentials, and tool connections. - Route canary sessions against a live control. Microsoft Foundry hosted endpoints send 100 percent of default traffic to
v1. Set your minimum sample count, observation window, and thresholds before starting. Route a slice of new sessions (5%, then25%) tov2viaversion_indicatoralongside matchingv1control traffic. - Wait for settled outcomes. Hold the canary stage until
v1andv2collect enough continuous evaluation scores, Azure Monitor metrics, and settled refund outcomes. - Promote, hold, or roll back:
| Canary and post-deployment evidence | Release action |
|---|---|
Candidate meets quality, latency, and settled outcome thresholds against live v1 control traffic during the canary window | Promote v2 by switching the Microsoft Foundry endpoint version selector to v2 for all new default sessions |
| Sample size is still below the minimum count or asynchronous transactions are still settling | Hold the current canary percentage and continue collecting evidence |
| Candidate quality falls below the required floor, exceeds the allowed regression margin against control, or triggers critical tool errors or Azure Monitor alerts | Roll back routing for new sessions to v1, stop or drain active v2 sessions, and reconcile affected records |
Plan for both session routing and backend state during a rollback. During a canary, clearing version_indicator sends new sessions to the default version (v1). After promotion, rolling back requires switching the Microsoft Foundry endpoint selector back to v1. Existing v2 sessions continue on v2 until you stop them explicitly (for example, with project_client.agents.stop_session) or let them drain. For transactions already submitted during the canary window, use backend idempotency keys and compensating reversals to keep customer records consistent.
Reset the baseline and refresh held-out cases for the next loop
After promoting v2 to 100 percent of default traffic, your release automation records its configuration in .agent_configs/baseline/ as the new comparison baseline. Keep v1 available until all in-flight v1 sessions finish.
To keep the held-out regression suite representative of current traffic, periodically add fresh reviewed production traces to both your training datasets and your release suite. This reduces the risk of repeated candidate selection gradually overfitting a single fixed test set.
Next steps: Implement continuous evaluation and CI/CD gating
Use these paths to set up the workflow in Microsoft Foundry:
- Enable continuous evaluation and trace datasets. Configure production monitoring on your deployed agent and convert production conversations into trace datasets.
- Create your evaluation suite and custom evaluators. Prepare
eval.yamland datasets for Agent Optimizer, add custom evaluators, and run cloud evaluations. - Optimize and automate CI/CD releases. Follow the Agent Optimizer overview, the optimization quickstart, and the hosted agent CI/CD guide to gate deployments in GitHub Actions.

 Microsoft