updates
589 Topics
Microsoft at OCP Global Summit 2026
At OCP Global Summit 2026, Microsoft will showcase how we’re advancing the infrastructure needed to scale AI, from silicon and systems to the datacenter. Come visit Microsoft at Booth C73 and hear from Microsoft leaders and experts through our keynote and sessions, panels, and workshops across the summit. Featured Sessions KEYNOTE Intelligence Infrastructure: Scaling AI for the Frontier Era October 13 · 9:15 AM - 9:35 AM · SJCC, Street Level, South Hall AI infrastructure depends on co-design across silicon, systems, software, and sites. This keynote examines how Microsoft brings those layers together to build scalable, reliable, and efficient infrastructure with security embedded throughout. It explores the path from technology development to a global fleet, how requirements change at scale, and how those lessons shape next-generation platforms. The session also considers sustainable scaling through closed-loop cooling and lower-carbon construction, the role of grid reliability and workforce development in host communities, and the challenges that call for ecosystem innovation. EXECUTIVE SESSION Powering the AI Era: Building Sustainable and Efficient Infrastructure at Cloud Scale October 12 · 2:30 PM - 2:50 PM · SJCC, Concourse Level, 210AE The explosive growth of generative AI is driving an unprecedented increase in demand for computing infrastructure. As AI workloads scale from training to widespread inference, every layer of the cloud stack is being challenged, from power grids and datacenters to servers, silicon, and software systems. Meeting this demand sustainably requires rethinking how computing infrastructure is designed, operated, and optimized. Microsoft Breakout Sessions, Panels, and Workshops Explore Microsoft daily sessions and hear from experts shaping the future of cloud and AI infrastructure. Tuesday, October 13 9:55 - 10:00 AM KEYNOTE Women in OCP (WOCP) - Community First, AI Forward Speakers: Sung Kim - BP Castrol, Shruti Sethi - Microsoft, Allison Boen - Alcatex and Shell Fluid, Anu Ramamurthy - Microchip Location: SJCC - Street Level - South Hall 1:15 - 1:35 PM PRESENTATION | OIF Workshop Enabling AI Scale-Up: Why Standards Matter and the Need for Industry Alignment Speakers: Fotini Karinou - Microsoft Location: SJCC - Lower Level - LL20BCD 1:45 - 2:00 PM PRESENTATION | Networking Switch Platform Architecture: A Unified Network Switch Platform Reference Design Speakers: Tao Ren - Meta, Ying Xie - Microsoft Location: SJCC - Concourse Level - 210AE 1:50 - 2:15 PM PANEL | AI Open Data Center Beyond the Build: Autonomous Robotics and the Future of Data Center Operations Speakers: Shashank Gupta - Fleet Data Centers, Eric Xu - Meta, Rob Lawson-Shanks - Molg, Evan Johnson - Microsoft; Moderator: Joel Chakkalakal - PHS West Location: SJCC - Concourse Level - 210CG 1:55 - 2:20 PM PRESENTATION | Manageability Workshop Redfish Aliasing Support and Redfish Streaming Telemetry Enhancements Speakers: Bill Scherer - HPE, Hari Ramachandran - Microsoft Corporation, Jeff Autor - Vertiv Location: SJCC - Lower Level - LL21BC 2:20 - 2:45 PM PANEL | AI Open Data Center Material Handling Automation for Next-Generation Datacenter Operations Speakers: Rachel Soukup - Google; Ben Wong - Meta; Amir Porter - Microsoft; Moderator: Evan Johnson - Microsoft Location: SJCC - Concourse Level - 210CG 2:20 - 2:45 PM PANEL | AI Computing Continuum Two Years of x86 Ecosystem Collaboration: Open Infrastructure, AI Readiness, and Developer Predictability Speakers: Jeff McVeigh - Intel, Stephen Watt - Red Hat, Andrew Wheeler - HPE, Martin Dixon - Google, Jon Lange - Microsoft; Moderator: Robert Hormuth - AMD Location: SJCC - Concourse Level - 211 2:35 - 2:45 PM PRESENTATION | IPEC Workshop IPEC Presentation Speakers: Yawei Yin - Microsoft Location: SJCC - Concourse Level - 230A 3:15 - 3:45 PM PANEL | AI Open Data Center Automation-Ready Infrastructure Design: From Light to Compute Speakers: Mike McKee-Hector - Microsoft, Dave Evans - Google, Ryan Olson - Meta; Moderator: Eric Xu - Meta Location: SJCC - Concourse Level - 210CG 3:50 - 4:05 PM PRESENTATION | Cooling Environments Building a Scalable Waste Heat Ecosystem: Datacenter Waste Heat, Offtakers, and Market Platforms Speakers: Maria Viitaniemi - Microsoft, Bharath Ramakrishnan - Microsoft Location: SJCC - Concourse Level - 220C 4:00 - 4:20 PM PRESENTATION | Manageability Workshop Using SPDM for PLDM Firmware Updates: Authorization Policy and Measurement Manifest Capabilities Speakers: Patrick Caporale - Lenovo, Brett Henning - Broadcom Inc., Scott Phuong - Microsoft Location: SJCC - Lower Level - LL21BC 4:10 - 4:45 PM PRESENTATION | Cooling Environments Heat Reuse Sub-Project Overview and Updates + Economics Tool Contribution Speakers: Aime Comella - DayOne; Jack Kolar - Dataquarium; Gemma Reeves - Alfa Laval; Bharath Ramakrishnan - Microsoft; Ahliana Byrd - Ascentra Innovations Location: SJCC - Concourse Level - 220C Wednesday, October 14 8:00 - 8:25 AM PANEL | AI Open DC: Power Distribution +/-400V / 800V On-Board Power Delivery Requirements Speakers: James Sun - Microsoft, Sachin Madhusoodhanan - Google, LJ (Jian) Lu - Google, Shengwen Xu - Meta; Moderator: Michelle Badal - Google Location: SJCC - Concourse Level - 210CG 8:15 - 9:10 AM PANEL | Systems Management OCP Hardware Fault Management Workstreams Status and Relationship Speakers: Theodros Yigzaw - NVIDIA; Vilas Sridharan - AMD; Janusz Jurski - Intel; Shubhada Pugaonkar - NVIDIA; Samer El-Haj-Mahmoud - Arm; Moderator: Drew Walton - Microsoft Location: Concourse Level - 211 8:15 - 8:35 AM PRESENTATION | SONiC Workshop SONiC Community Year in Review: Powering the Open Network for the AI Era Speakers: Yanzhao Zhang - Microsoft, Xin Liu - Microsoft Location: SJCC - Concourse Level - 230A 8:20 - 8:40 AM PRESENTATION | Storage Comprehensive Testing for OCP Datacenter NVMe SSD Specification Compliance Speakers: Timothy Sharp - Microsoft Corp, Nick Kriczky - Teledyne Lecroy, Rick Walsh - SANBlaze Location: SJCC - Concourse Level - 212 8:25 - 8:50 AM PANEL | Market Impact & Adoption PG25 at Scale: What We've Learned and Where We're Going Speakers: Keegan Yaroch - DOW Chemical, Paul Artman - AMD, Jacob Paugh - ChemTreat, Cam Turner - Microsoft; Moderator: Chris Campbell - Vertiv Location: SJCC - Lower Level - LL21DE 8:30 - 8:50 AM PRESENTATION | OCP Special Focus: Photonics Optical Scale-Up AI Systems: Architectures, Standards, and Resiliency Strategies Speakers: Fotini Karinou - Microsoft, Adrian Motamedi - Microsoft Location: SJCC - Concourse Level - 210AE 8:45 - 9:05 AM PRESENTATION | Cooling Environments Air vs. Liquid: Where Does Air Cooling Still Win for General Compute? Speakers: Jayesh Shah - Microsoft, Stewart Nguyen - Lenovo Location: SJCC - Concourse Level - 220C 9:30 - 9:45 AM SYMPOSIUM: POSTER AND PRESENTATION | FTS: Keynotes & Awards Poster Session Break Speakers: Samir Rajadnya - Microsoft, Oren Benisty - UniFabriX, Konstantin Tiutin - RIVVOR Inc., Timour Paltachev - Rivvor, Nazym Paltachev - rivvor, Sangsu Park - Samsung, Tushar Krishna - Georgia Institute of Technology, Seyyed Ali Ghorashi - Danovo Energy Solutions, Daniel Bauer - LoadCrest, Weipeng Zhang - LightXcelerate Inc, Manchen Hu - LightXcelerate, Xinyu Zhang - XPerf, Rakesh Sambaraju - Infraeo Inc., Xufu Ren - University of Cambridge, Yunqi Zhang - University of Cambridge, Shawn Yan - Vulcadi Inc, David Gyulnazaryan - Impleon, ROGER BASU - Coreshell Technologies, Inc, Fanny Oukhemanou - Syensqo, Taner Dosluoglu - weeteq, Patrick McCluskey - University of Maryland at College Park, Ibaad Gandikota - University of Maryland, Sang woo Ham - Lawrence Berkeley National Laboratory, Sam Abdel-Rahman - Infineon Technologies, Shuyu Zhang - UC Berkeley Location: SJCC - Lower Level - LL20BCD 9:45 - 10:00 AM PRESENTATION | Server Scaling Hyperscale Cloud Networking from 400G to 800G: System Integration Lessons and Implications for OCP Platforms Speakers: Lucy Yu - MSFT, Faye Yang - Microsoft Location: SJCC - Lower Level - LL21BC 9:50 - 10:10 AM PRESENTATION | SONiC Workshop SONiC BMC for Unified Management and Next-Generation Liquid-Cooled Networks Speakers: Judy Joseph - Microsoft, Roger Liao - Nexthop Systems Inc. Location: SJCC - Concourse Level - 230A 10:05 - 10:20 AM PRESENTATION | OCP Special Focus: Photonics System-Level Evaluation of XPO for High-Density Optical Interconnects in AI Infrastructure Speakers: Daniel Mohaghegh - Microsoft, Sunil Priyadarshi - Arista Networks Location: SJCC - Concourse Level - 210AE 10:05 - 10:25 AM PRESENTATION | Market Impact & Adoption Upgrading OCP S.A.F.E. and S.O.L.I.D. for the AI age Speakers: Zahra Lak - Microsoft, Jeff Andersen - Google Location: SJCC - Lower Level - LL21DE 10:10 - 10:30 AM PRESENTATION | Systems Management System-Level Manageability for GPU Platforms — Progress in the OCP System GPU Management Workstream Speakers: John Leung - Intel, Hari Ramachandran - Microsoft Corporation Location: SJCC - Concourse Level - 211 10:40 - 11:00 AM PRESENTATION | SONiC Workshop Democratizing DPU High Availability with a SONiC-Driven DASH HA Control Plane Speakers: Changrong Wu - Microsoft, Sudharsan Dhamal Gopalarathnam - NVIDIA Location: SJCC - Concourse Level - 230A 10:50 - 11:10 AM PRESENTATION | Server Accelerating High-Power Server Design Through Board-Level Electro-Thermal Co-Simulation of VRMs and PDNs Speakers: Steven Chien - Wiwynn Corporation, Zi Ping Wu - Microsoft Location: SJCC - Lower Level - LL21BC 11:30 AM - 1:00 PM PANEL | Meals & Breaks Women in AI Luncheon presented by Women in OCP (WOCP) - Sponsored by Lenovo & NVIDIA Speakers: Casey Moran - Lenovo, Cathie Deal - IREN, Shruti Koparkar - NVIDIA, Shruti Sethi - Microsoft; Moderator: Allison Boen - Alcatex and Shell Fluid Location: San Jose Marriott - Level 2 - Salon III & IV 11:45 AM - 12:00 PM Expo Hall Sessions | SONiC Open, Trusted, and Secure SONiC at Scale presented by Cisco Speakers: Will Eatherton - Cisco; Dina Papagiannaki - Microsoft Location: SJCC – Concourse Level – Expo Hall Theater 12:30 - 12:50 PM PRESENTATION | SONiC Workshop Beyond the T2 PIN: Pizza-Box Disaggregation for Next-Gen Regional Hubs Speakers: Kamini Santhanagopalan - Broadcom, Rita Hui - Microsoft Location: SJCC - Concourse Level - 230A 12:55 - 1:15 PM PRESENTATION | Systems Management Runtime SBOMs: Extending DMTF Redfish to Connect Build-Time and Live Software State Speakers: Harsh Bhuwania - Microsoft, Prashant Dewan - Microsoft Location: SJCC - Concourse Level - 211 1:20 - 1:40 PM PRESENTATION | SONiC Workshop 6–12x Route Programming Acceleration in SONiC: A Collaborative Profiling and Optimization Journey Speakers: Deepak Singhal - Microsoft, Amol Rawal - Nokia Location: SJCC - Concourse Level - 230A 1:20 - 1:50 PM PRESENTATION | Systems Management GPU & CPU Diagnostics and RAS Standardization Advances for Hyperscale Infrastructure Speakers: Rama Bhimanadhuni - Microsoft, Taniya Siddiqua - Advanced Micro Devices, Inc. Location: SJCC - Concourse Level - 211 1:35 - 1:55 PM PRESENTATION | AI Open DC: Power Distribution Designing Safe 800 VDC Systems: Protection, Fault Management, and Operations Speakers: Mike Tu - NVIDIA, Xianyong Feng - Microsoft Location: SJCC - Concourse Level - 210CG 3:15 - 3:35 PM PRESENTATION | Systems Management From Lab to Fleet: A Secure, Unified Debug Framework for Cloud Systems Speakers: Suresh Duthiraru - Microsoft, Rolf Kuehnis - Lauterbach Inc. Location: SJCC - Concourse Level - 211 3:15 - 3:55 PM PANEL | Storage OCP Storage Specifications Update and What Customers Care About Speakers: David Black - Dell Technologies, Timothy Sharp - Microsoft Corp., Chris Sabol - Google, Jeff Wolford - HPE, Vineet Parekh - Meta; Moderator: Ross Stenfort - SanDisk Location: SJCC - Concourse Level - 212 3:40 - 4:00 PM PRESENTATION | SONiC Workshop Extending Community SONiC for Advanced Optics Telemetry Aligned with OCP Standards Speakers: Rajan Pai - Credo, Prince George - Microsoft Location: SJCC - Concourse Level - 230A 3:54 - 5:00 PM SYMPOSIUM: PRESENTATION ONLY | FTI Workshop: Short Reach Optical Interconnects Scale-up optical reliability and GPU/system resiliency to optical link flaps Speakers: Eduard Roytman - Microsoft, Lenin Patra - Marvell, Ashwin Gumaste - NVIDIA, Greg Link - Microsoft, Jeffrey Hutchins - Ranovus Location: SJCC - Lower Level - LL21BC 4:00 - 4:20 PM PRESENTATION | Storage Adopting high-capacity HDDs, navigating throughput and IOPS Limits using SAS/NVME interfaces for the AI Cloud Speakers: Hariharan Kumar - Microsoft, Balaji Natrajan - Microsoft Location: SJCC - Concourse Level - 212 4:10 - 4:30 PM PRESENTATION | Systems Management Operating OpenBMC at Hyperscale: What Works, What Breaks, and What Needs to Change Speakers: Thirupathaiah Annapureddy - Microsoft, Hari Ramachandran - Microsoft Corporation Location: SJCC - Concourse Level - 211 4:30 - 4:50 PM PRESENTATION | SONiC Workshop FIPS 140-3 Support in SONiC Speakers: Kenneth Cheung - Arista Networks, Qi Luo - Microsoft Location: SJCC - Concourse Level - 230A 4:30 - 5:00 PM PANEL | AI Clusters Scale-across Networking: Panel discussion on routing and transport equipment implications Speakers: Jeff Rahn - Meta, Yawei Yin - Microsoft, Xiguang - Henry Wu - Broadcom, Tad Hofmeister - Google; Moderator: Vijay Vusirikala - Arista Networks Location: SJCC - Concourse Level - 220B 4:35 - 5:00 PM PRESENTATION | Systems Management From Scale to Security: Evolving GPU Management Standards in 2026 Speakers: Krishna Sugumaran - AMD, Sujoy Sen - Google, Akkiah (Choudary) Maddukuri - Microsoft, Qian Wang - NVIDIA, Balaji Vembu - Meta Location: SJCC - Concourse Level - 211 Thursday, October 15 8:00 - 8:20 AM PRESENTATION | AI Clusters MX v1.1: Advancing Open Standards for Low-Precision AI with MicroXcaling formats Speakers: Partha Maji - Microsoft Location: SJCC - Concourse Level - 220B 8:00 - 8:25 AM PANEL | Sustainability Updates from an exciting year with the OCP Sustainability Project, DCF Sustainability Project & Roadmap ahead Speakers: Alexander Rakow - Schneider Electric, Sung Kim - BP Castrol, Shruti Sethi - Microsoft, Priya Chhiba - Google Location: SJCC - Lower Level - LL21DE 8:20 - 8:40 AM PRESENTATION | Security Integrated HSM: Bringing Silicon-Level Key Security to the Server Tray Speakers: Craig Barner - Marvell, Vishal Soni - Microsoft, Mohan Kumar - Oracle Cloud Infrastructure Location: SJCC - Concourse Level - 212 8:45 - 9:05 AM PRESENTATION | Test & Validation AI-Native Hardware Validation: Building a Local-Context Agentic Test and Debug Platform Speakers: Wenxi Yan - Microsoft Location: SJCC - Lower Level - LL20BCD 8:50 - 9:05 AM PRESENTATION | Sustainability Performance-Normalized Embodied Rack Carbon Intensity for Next-Generation Hardware Speakers: Kali Frost - Microsoft Location: SJCC - Lower Level - LL21DE 9:10 - 9:30 AM PRESENTATION | Networking ESUN: Open Ethernet for the AI Scale-Up Era Speakers: Pratik Marolia - Microsoft, Manoj Wadekar - Meta Location: SJCC - Concourse Level - 210AE 9:10 - 9:30 AM PRESENTATION | Test & Validation From Spec to Sign-off - How Microsoft is transforming the platform validation workflow leveraging AI-powered, agent-driven solutions. Speakers: Rahul Shah - Microsoft, Vikram Vemulapalli - Microsoft Location: SJCC - Lower Level - LL20BCD 9:10 - 9:30 AM PRESENTATION | Rack & Power Scaling Hyperscale Power Delivery: Managing Aggregated and Cascaded Power Shelf Architectures for High-Density GPU Systems Speakers: Praveen Kumar Velpuri - Microsoft, Yang Hsiung - Microsoft Location: SJCC - Concourse Level - 230A 9:45 - 10:20 AM PANEL | Server: Composable Memory Systems Addressing Memory Wall challenge for AI and General Compute platforms (CMS Sub-Project Technical Update) Speakers: Anjaneya "Reddy" Chagam - Microsoft Corporation, Grant Mackey - XCENA, Mohamad El-Batal - Seagate, Samir Rajadnya - Microsoft Location: SJCC - Lower Level - LL21BC 9:45 - 10:10 AM PANEL | AI Clusters USB to Rule Them All: One Manageability Interface for AI Platforms Speakers: MARIUSZ ORIOL - NVIDIA, Bharat Pillili - Microsoft, Samer El-Haj-Mahmoud - Arm, Mohan Kumar - Oracle Cloud Infrastructure, Supreeth Venkatesh - AMD; Moderator: Kasper Wszolek - NVIDIA Location: SJCC - Concourse Level - 220B 10:45 - 11:30 AM PANEL | Cooling: Cold Plate Pushing the Single-Phase Cold Plate Limit: Design Practice, Field Learnings, and the Runway Before Two-Phase Scales Speakers: Weihua Tang - Google, REMCO VAN ERP - Corintis, Oscar Farias Moguel - Microsoft, Yin Hang - Meta; Moderator: Joel Chakkalakal - Guardian Data- LLC Location: SJCC - Concourse Level - 220C 10:50 - 11:05 AM PRESENTATION | Networking Scaling AI Beyond the Cloud Boundary: High-Capacity Interconnects Between Hyperscalers and GPUaaS NeoClouds Speakers: Krithika Moorthy - Cisco, Anish Narsian - Microsoft Location: SJCC - Concourse Level - 210AE 10:50 - 11:05 AM PRESENTATION | Security Upgrading OCP S.A.F.E. and S.O.L.I.D. for the AI age Speakers: Zahra Lak - Microsoft, Jeff Andersen - Google Location: SJCC - Concourse Level - 212 11:00 - 11:25 AM PRESENTATION | Test & Validation Product Intercept learnings and Compliance measurement for Diagnostics Standardization Speakers: Rajat Madhusudan - Microsoft, Jennifer Lee - Intel Location: SJCC - Lower Level - LL20BCD 11:15 - 11:30 AM PRESENTATION | Sustainability Enabling Scalable Waste Heat Recovery: Operational Realities, Design Principles, and Value from the Datacenter Perspective Speakers: Emily Matys - Microsoft Location: SJCC - Lower Level - LL21DE 12:30 - 12:45 PM PRESENTATION | Security Baremetal Security Architecture Speakers: Bharat Pillili - Microsoft, Darpana Munjal Loodu - Microsoft Location: SJCC - Concourse Level - 212 12:30 - 12:50 PM PRESENTATION | Rack & Power Mitigating AI Training Power Oscillations: Utility Requirements and In-Rack Power Filtering Speakers: Bo Wen - Microsoft, Xianyong Feng - Microsoft Location: SJCC - Concourse Level - 230A 1:15 - 1:30 PM PRESENTATION | Sustainability From Silicon to System: Embedding Power Efficiency as a Core Design Principle for Scalable AI and Compute Infrastructure Speakers: Devang Soparkar - Microsoft, Nilanjan Palit - Intel Location: SJCC - Lower Level - LL21DE 1:45 - 2:00 PM PRESENTATION | Open Platform Firmware (OPF) Dynamic Platform Abstraction for BMC Firmware via Host-Delivered Libraries Speakers: Sarathy Jayakumar - AMD, Rama Bhimanadhuni - Microsoft Location: SJCC - Lower Level - LL20BCD 1:55 - 2:10 PM PRESENTATION | Sustainability Closing the Loop: Structural Steel Reuse in Hyperscale Datacenter Construction — A Scalable Blueprint from Microsoft's Newport Imperial Park Datacenter (CWL01) Speakers: John O’Sullivan - Microsoft, Anjali Bhagat - Microsoft Location: SJCC - Lower Level - LL21DE 1:55 - 2:10 PM PRESENTATION | Security Package-Aware Integrity: From Source-Agnostic Publication to Full-System Attestation Speakers: Felipe Zimmerle da Nobrega Costa - KonaSense, Dhananjay Phadke - Microsoft Location: SJCC - Concourse Level - 212 2:15 - 2:30 PM PRESENTATION | Networking MRC: A Purpose-Built RDMA Transport for AI Training Networks Speakers: Abdul Kabbani - Microsoft, Wael Noureddine - Microsoft Location: SJCC - Concourse Level - 210AE 2:45 - 3:00 PM PRESENTATION | Security BMC-Mediated Platform Composite Attestation via Redfish Speakers: Xiling Sun - Microsoft, Roksana Golizadeh Mojarad - Microsoft Location: SJCC - Concourse Level - 212 2:45 - 3:10 PM PANEL | Sustainability Product Category Rule-style Specification for Life Cycle Assessment on Datacenter ICT-Equipment: Collaborative Progress & Draft publication Speakers: Lisa Rivalin - Meta, Stephan Benecke - Google, Ines Sousa - Microsoft, Vincenzo Ferrero - Amazon; Moderator: Chris Eckstein - Fraunhofer Location: SJCC - Lower Level - LL21DE 2:45 - 3:15 PM PANEL | Open Platform Firmware (OPF) Scaling Memory Safe Security Across Firmware Stack Speakers: Giri Mudusuru - Microsoft, Tim Lewis - Insyde Software, Bertrand Achard - Google, Raj Kapoor - AMD, Oleg Ilyasov - American Megatrends (AMI); Moderator: Murugasamy Nachimuthu - Oracle Location: SJCC - Lower Level - LL20BCD 2:45 - 3:05 PM PRESENTATION | AI Open Data Center The Future of Fuel Cells in Datacenters - High Temperature Fuel Cells. Speakers: Afshin Majd - Microsoft, Priya Chhiba - Google, Alberto Ravagni - Net Zero Innovation Hub Location: SJCC - Concourse Level - 210CG 3:05 - 3:20 PM PRESENTATION | Security Caliptra Subsystem 2.2: USB 2.0 and OCP Streaming Boot Speakers: Caleb Whitehead - Microsoft, Bart Vertenten - NXP Semiconductors Location: SJCC - Concourse Level - 212 3:25 - 3:40 PM PRESENTATION | Security Architectural Masking for PQC: Adam’s Bridge 3.0 Leveraging NTT Linearity Speakers: Mojtaba Bisheh-Niasar - Microsoft, Kiran Upadhyayula - Microsoft Location: SJCC - Concourse Level - 212 3:35 - 4:00 PM PANEL | Sustainability Increasing Rigor in Data Center Carbon Disclosure Speakers: Andrea Desimone - Schneider Electric, Lalit Joshi - Microsoft, Malcolm Hegeman - Google, Miranda Gardiner - iMasons Climate Accord; Moderator: Nalintip Suwannakarn - Meta Location: SJCC - Lower Level - LL21DE 3:45 - 4:00 PM PRESENTATION | Security Beyond Static Identity: Enabling Secure Certificate Refresh in Silicon Roots of Trust Speakers: Emre Karabulut - Microsoft, VISHAL MHATRE - Microsoft Location: SJCC - Concourse Level - 212 Offsite Microsoft Workshops 8:00 AM - 3:00 PM WORKSHOP RAS Workshop (at capacity) Hyperscalers, silicon vendors, and ecosystem partners will collaborate on RAS, Debug, Diagnostics, and Manageability initiatives, focused on aligning current requirements, sharing implementations and tools, and discussing the future direction of key specifications and workstreams. Location: MTV Campus 8:30 AM - 2:00 PM; 2:00 - 5:00 PM WORKSHOP Caliptra and BoF Workshops (at capacity) Members of the open-source silicon security community will collaborate on hardware root of trust technologies and secure silicon initiatives through discussions on ongoing technical work, ecosystem collaboration, implementation experiences, roadmap planning, community engagement, and related open-source security efforts Location: MTV Campus163Views0likes0CommentsRun an Ollaya decision model on Azure Container Apps
Many AI calls are not really conversations. A support message needs an intent. A workflow needs a route. A policy check needs a yes or no. An agent needs to select its next action from a known list. These are bounded decisions, but they are often sent to a general-purpose LLM. The LLM reads the request, generates an answer token by token, and then the application validates and parses the response. That is useful when the task needs reasoning or language generation. It is more machinery than necessary when the only valid answer is one of 60 labels. On September 15, 2026, TypeSafe released Jev, its first public System One Model, in early access. Jev has helped bring attention to models built specifically for decisions: structured state goes in, and typed choices with probabilities come out. Ollaya approaches the same problem from a self-hosted direction. It is a model runtime that can serve open decision models, including the winnow:e4b model used here. Jev and Ollaya are not connected products. Jev is a hosted model from TypeSafe; Ollaya provides a way to run decision models in infrastructure you control. They are related by the kind of work they target. What decision models are good at A decision model scores predefined options rather than generating open-ended text: Decision model Traditional LLM Selects from allowed choices Generates text Returns a probability for each decision Usually returns one generated answer Has a bounded, typed output Needs schema constraints and validation Supports confidence thresholds Often needs a separate confidence strategy Fits classification, routing, scoring, policy, and prioritization Fits generation, summarization, coding, and open-ended reasoning That narrower interface creates several practical benefits: Predictable outputs: the application receives an allowed value rather than text that must be repaired or parsed. Lower decision latency: there is no autoregressive output sequence to generate. Token savings: a decision can be returned without generating output tokens. Useful uncertainty: calibrated probabilities let the application act, reject, or escalate. Smaller infrastructure: a specialized model can fit on hardware that would be modest for a general LLM. Decision models are not replacements for every LLM call. They make sense when the possible outcomes are known before the request arrives. An LLM remains the better tool when the output itself is language, code, or open-ended reasoning. Why Azure Container Apps serverless GPU Azure Container Apps serverless GPUs make self-hosted inference feel much closer to consuming a managed API. You bring the container and model; Azure manages the underlying GPU infrastructure. The Consumption GPU profile provides: NVIDIA T4 or A100 GPUs without managing GPU nodes or a Kubernetes cluster. Automatic scaling with the option to scale to zero. Per-second GPU billing while replicas are running. Container Apps networking, identity, ingress, logging, and revision management. A private inference path where the model and request data stay inside your Azure environment. That last point matters for data-sensitive decisions. In the Ollaya-only configuration, text is sent to an internal Ollaya endpoint rather than an external model API. The model, API, persistent cache, and operational controls remain in the application's Azure environment. Serverless does not remove the need to think about cold starts. A model still needs to be loaded into VRAM. For low or sporadic traffic, scaling to zero can avoid idle GPU cost. For latency-sensitive traffic, a warm minimum replica avoids making a user wait for the model to load. Azure Files can retain the model layers across revisions so a new deployment does not download the full model again. The T4 is also an important part of this experiment. It is not the largest GPU available, but the goal is not to run the largest model. The goal is to match the hardware to a model designed for the task. A focused decision model on a T4 can compete with a hosted API when the workload is a bounded classification rather than text generation. The experiment I deployed winnow:e4b through Ollaya on an Azure Container Apps Consumption-GPU-NC8as-T4 workload profile. An authenticated API exposed the classifier while Ollaya remained on internal-only ingress. A second path sent the same requests to GPT-5.4 Nano through Azure OpenAI using managed identity. The evaluation used the complete 2,974-record test partition from Amazon MASSIVE 1.1. It contains 18 scenarios and 60 intents. Both providers received the same records, labels, and descriptions. The benchmark measured latency at concurrency 1 and throughput at concurrency 8. Providers and modes ran sequentially so one measurement did not load the service used by another. This was not a direct benchmark of Jev; it tested the same decision-model pattern with an open model that could run inside the Azure environment. What the results showed The benchmark ran on September 30, 2026. Provider Successful Intent accuracy Macro-F1 p50 p95 Winnow on T4 2,974 / 2,974 75.59% 76.40% 946 ms 960 ms GPT-5.4 Nano 2,974 / 2,974 79.12% 78.07% 1,369 ms 2,489 ms Nano led intent accuracy by 3.53 percentage points. Winnow was 30.9% faster at p50 and 61.4% faster at p95. This is the useful T4 result: a smaller GPU running the right specialized model matched and beat the hosted endpoint on response latency, though not on accuracy. At concurrency 8, Nano delivered 1.367 requests per second compared with Winnow's 1.120. Nano also had 25 requests fail after eight retries because the deployment exceeded its token-rate limit. Winnow completed all 2,974 requests, but its single loaded runner serialized work and increased queue time. The token comparison shows what the decision-only path removes: Provider, both benchmark passes Input tokens Cached input tokens Output tokens Winnow on T4 9,252,872 0 0 GPT-5.4 Nano 8,501,200 7,564,800 122,759 Winnow returned every decision without generating output tokens. Nano generated 122,759 output tokens across the latency and throughput passes. The rows do not represent equivalent billing models: Winnow consumes self-hosted GPU time, while Nano is metered by hosted token usage. The comparison isolates the generated tokens that a bounded decision did not need. Winnow also returned calibrated probabilities. At a 0.90 threshold, it accepted 53.73% of the records and was correct on 94.43% of those accepted decisions. An application could handle that high-confidence group locally and send only the uncertain remainder to an LLM or human reviewer. In brief A decision model is useful when software needs a bounded answer rather than generated language. In this experiment, Winnow on a serverless T4 traded some accuracy for lower latency, zero generated output tokens, private inference, and an explicit confidence signal. The practical design is often a combination: use the decision model for fast, high-confidence choices and reserve LLM calls for uncertain or open-ended work. Try it with the template The Azure Developer CLI template packages the Container Apps environment, T4 workload profile, authenticated API, internal Ollaya service, persistent model cache, GPU readiness checks, and benchmark. It supports two deployment modes: Mode What it deploys ollaya-only Private Winnow inference on a serverless T4 plus the authenticated API full The Ollaya deployment, GPT-5.4 Nano, and the comparison benchmark Read the deployment guide Inspect every benchmark prediction and retry Review the shared MASSIVE taxonomy410Views0likes0CommentsScaling distributed AI infrastructure with Azure’s ExpressRoute and AI Points of Presence (AI PoPs)
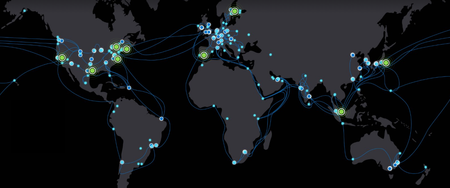
Rethinking connectivity for distributed AI infrastructure AI is changing more than the applications organizations build. It is reshaping where the infrastructure powering those applications is deployed. For years, cloud computing has been anchored by hyperscale regions that combine compute, storage, networking, security, and operations at massive scale. That model remains foundational to Microsoft Azure. At the same time, rapid AI growth is creating a more distributed infrastructure landscape. GPU capacity is increasingly being deployed across regions, providers, facilities, and operating environments wherever the right mix of power, space, cooling, and specialized infrastructure is available. That shift creates a practical challenge: how do organizations bring new GPU capacity online quickly while still giving AI workloads the Azure services, governance, security, and operational consistency they require? Microsoft’s approach: extending Azure to distributed AI infrastructure Microsoft is taking a platform approach to distributed AI infrastructure. For customers, Azure ExpressRoute offers the private connectivity experience for connecting remote sites and infrastructure to Azure. Behind that experience, AI PoPs provide Microsoft with a standardized infrastructure architecture for integrating distributed third-party GPU capacity into the Azure network and operating environment. Rather than building a unique network and operational integration for every external GPU deployment, Microsoft can use AI PoPs to onboard and aggregate GPU capacity wherever the GPUs may be, while customers continue to connect through familiar Azure networking products such as ExpressRoute. Azure ExpressRoute provides the private connectivity foundation for these customer-managed environments, enabling external GPU infrastructure to connect privately with Azure without traversing the public internet. Combined with the AI PoP architecture, this creates a repeatable model for integrating distributed GPU capacity with Azure, giving customers greater flexibility in where compute comes from while maintaining Azure as the platform connecting their AI environment. Based on current Microsoft deployment and provisioning data, Azure’s AI PoP operating model is already connecting and provisioning hundreds of thousands of GPUs across North America, Europe, and Asia Pacific, giving select preview customers a consistent Azure experience for using distributed AI infrastructure. The aim is simple: bring AI capacity to market faster, wherever it is located, while expanding the range of GPU providers and deployment locations. Customers receive a more consistent Azure experience regardless of where that capacity is located. Figure 1. Global deployment of Microsoft’s AI PoP infrastructure Microsoft is expanding AI PoPs to more than 10 planned sites across North America, Europe, and Asia over the next 12 months. Connecting distributed GPUs for faster connectivity and simpler operations for our customers AI workloads depend on more than chips. They need data, orchestration, identity, monitoring, security, and reliable high-bandwidth connectivity. ExpressRoute provides customers with private, high-bandwidth connectivity to Azure. Behind the scenes, AI PoP infrastructure helps Microsoft integrate and operate distributed third-party GPUs at scale. Together, this architecture can help customers: Connect privately to Azure: Use Azure ExpressRoute for private connectivity from remote sites and distributed infrastructure to Azure. Access distributed GPU capacity: Take advantage of GPU capacity across an expanding ecosystem of infrastructure providers without requiring customers to consume AI PoPs as a separate service. Use familiar Azure services: Connect workloads with Azure storage, orchestration, AI services, security, and operational tooling. Maintain a consistent Azure experience: Use established Azure networking and cloud services even as the physical GPU infrastructure becomes more distributed. For customers, this means less bespoke connectivity work and more focus on putting AI capacity to use. AI PoPs is part of the Microsoft infrastructure that enables Azure to integrate third-party GPU capacity into this experience, with ExpressRoute as a customer-facing service. For infrastructure providers, it creates a clearer path for integrating specialized GPU environments with the Microsoft Cloud. One Azure operating model, wherever AI capacity runs As GPU capacity becomes more distributed, customers should not have to adopt a new connectivity model for every provider or location. Azure ExpressRoute provides the customer connectivity experience, while AI PoPs give Microsoft a repeatable infrastructure architecture for integrating third-party GPU capacity into the Azure network and operating environment. That distinction matters as AI infrastructure spreads across regions and providers. Customers need flexibility in where capacity comes from, along with a reliable way to operate that capacity as part of a broader cloud environment. Microsoft is extending this model across regions to support Azure-connected AI capacity. The key principles behind the model are shown below (Figures 2–4). Figure 2. Example of aggregating capacity across multiple locations A single AI PoP can connect multiple GPU facilities and providers. Instead of treating each deployment as a unique project, new capacity can be onboarded through an established framework. This simplifies expansion, enables Microsoft to bring new capacity online faster, and makes it easier to scale as demand grows. Figure 3. Private connectivity to Azure services through Azure ExpressRoute and AI PoPs GPU capacity alone does not create an AI platform. Training and inference environments also depend on data, applications, orchestration, security, monitoring, and AI services. When GPU infrastructure sits outside Azure, the network becomes the critical bridge between compute and the Azure services it depends on. For customer-managed deployments, Azure ExpressRoute provides private connectivity between external infrastructure and Azure without sending traffic over the public internet. AI PoPs build on this connectivity model to provide a consistent approach for integrating distributed GPU environments with Azure services. Figure 4. AI PoPs deliver a consistent operating model Whether capacity is supplied by Microsoft, partners, or customers, AI PoPs are designed to provide a consistent connectivity and management experience. Standardization simplifies deployment, improves repeatability, and reduces the redesign required when introducing new providers or locations. Together, these design principles can reduce onboarding time, expand infrastructure choice, and provide a consistent Azure-connected experience. Looking ahead Demand for AI infrastructure continues to accelerate. Microsoft’s focus is not only on adding capacity, but also on making capacity available wherever it exists through a secure, reliable, and operationally consistent cloud platform. The next phase will focus on onboarding additional GPU providers, strengthening automation, and expanding Microsoft's ability to integrate distributed AI infrastructure with Azure. As AI PoP infrastructure scales behind Azure, customers can continue to use established Azure products such as ExpressRoute to privately connect remote sites and workloads, while gaining access to a broader ecosystem of distributed GPU capacity. As AI infrastructure becomes increasingly distributed, the ability to onboard capacity quickly, operate consistently across environments, and deliver a seamless Azure experience will become a meaningful differentiator. AI PoPs are one way Microsoft is helping shape that future.1.1KViews1like0CommentsMeet the Hosted Skills Canvas: Build, Run, and Debug in GitHub Copilot
Build, run, and debug event-driven AI apps right inside GitHub Copilot. The new Azure Functions Hosted Skills canvas brings instructions, triggers, and live results into one workspace—so you can spend less time switching tools and more time building. 506Views1like0Comments
Connect Azure Functions to more services with managed connectors
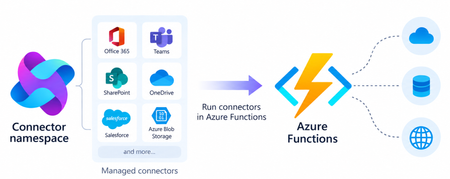
Azure Functions can already connect to many Azure services through triggers and bindings. With managed connectors, your functions can access about 1,700 connectors across services such as Microsoft 365, Microsoft Teams, Dataverse, SharePoint, OneDrive, and third-party systems. Connector triggers deliver events from these services to your function, while typed connector clients let your code take actions against them. You get this broader integration surface without writing the webhook registration code or managing the OAuth tokens required to connect to each service. Focus on your function's business logic and let Azure Connector Namespace handles the connection. Azure Functions integration with Connector Namespace is currently in public preview. It supports .NET isolated, Python, and Node.js. Review the managed connectors overview for current language, hosting plan, and regional availability. To demonstrate how connector triggers and actions work together, this article follows a .NET sample that automates RFP intake across SharePoint, Azure Content Understanding, and Teams. From an uploaded RFP to Teams notification Consider an organization that receives requests for proposals (RFPs) in a shared SharePoint document library. Someone must read each document, identify the requested capabilities, determine which subject-matter experts should respond, and notify the right team. The automated RFP intake sample turns that process into an event-driven workflow: A customer uploads an RFP to a SharePoint document library. A SharePoint connector trigger invokes an Azure Function when the file is created. The function uses a typed SharePoint connector client to retrieve the file contents. Azure Content Understanding extracts the document’s text and layout. The function applies deterministic rules to identify the customer, required capabilities, and recommended subject-matter experts. The function uses a typed Teams connector client to post the results as an Adaptive Card in a channel. Connector Namespace manages the SharePoint and Teams connections. The function controls file processing, document analysis, routing rules, error handling, and notification content How the sample works The .NET sample demonstrates both parts of the connector programming model: a connector trigger receives an event from SharePoint, and typed connector clients provided by the Connector SDKs to perform actions against SharePoint and Teams. The function starts when the SharePoint When a file is created trigger detects a new RFP. It declares the trigger using the ConnectorTrigger attribute and receives a typed payload containing the file’s properties: [Function("OnNewFile")] public async Task OnNewFile( [ConnectorTrigger] SharePointOnlineOnNewFileItemsTriggerPayload payload, CancellationToken cancellationToken) { // Process the newly uploaded file. } Because the trigger provides file properties rather than its contents, the function uses a typed SharePoint client to retrieve the document: byte[] response = await _sharePoint.GetFileContentAsync( Uri.EscapeDataString(siteAddress), fileIdentifier, cancellationToken: cancellationToken); byte[] document = SharePointFileContent.Decode(response); The SharePoint and Teams clients are registered through dependency injection. Each client uses the runtime URL of its Connector Namespace connection and authenticates with DefaultAzureCredential: services.AddSingleton( new SharePointOnlineClient( new Uri(sharePointRuntimeUrl), credential)); services.AddSingleton( new TeamsClient( new Uri(teamsRuntimeUrl), credential)); The function sends the document to Content Understanding’s prebuilt-layout analyzer, which extracts its text and structure. It then applies deterministic C# rules to identify the customer and required capabilities and map those capabilities to predefined subject-matter expert roles. Finally, the function creates an Adaptive Card containing the results and posts it to the configured Teams channel with the typed Teams client: await _teams.PostCardToConversationAsync( postAs, postIn, request, cancellationToken); Connector Namespace handles the SharePoint and Teams connections, while the function controls the document analysis, routing logic, error handling, and notification content. Try the sample The RFP intake sample includes the function code, Bicep infrastructure, Azure Developer CLI configuration, and supporting scripts. Its README explains how to test the workflow locally and deploy it to Azure. Common connector patterns Managed connectors are useful when a function must react to events or perform operations in external systems. Common patterns include: Event to action: React to an event in one service and take an action in another. Event to enrich to action: Retrieve additional information related to an event before acting. Event to document analysis to action: Extract text and structure from a document, apply application rules, and send the result through another connector. Event to AI to action: Analyze event data with an AI service and write the result back through a connector. Extend an existing function app: Add connector-based integrations alongside HTTP, timer, queue, Service Bus, Event Grid, or Durable Functions workloads. The RFP sample combines several of these patterns. A SharePoint event starts the workflow, a SharePoint action retrieves the document, Content Understanding extracts its contents, application code enriches the result, and a Teams action sends the notification. Closing thoughts Managed connectors extend the external systems that can trigger your functions and the services your function code can act on. This brings services such as SharePoint, Teams, Microsoft 365, and many third-party systems into the Azure Functions programming model without requiring you to build the underlying webhook and OAuth infrastructure. Choose Azure Functions with managed connectors when you want this broader integration surface in a code-first application and need custom branching, application libraries and SDKs, other Functions bindings, document or AI processing, or application-specific logic between the trigger and action. If the workload primarily orchestrates connector operations, involves little custom code, and would benefit from a visual designer, Azure Logic Apps is usually the simpler choice. Resources Documentations Overview of managed connectors in Azure Functions Azure Functions connector samples Azure Connector Namespace overview Content Understanding prebuilt-layout analyzer Connector SDK GitHub repos .NET SDK Python SDK Node.js SDK321Views0likes0Comments
Catalyst: Frontier stories of AI Infrastructure innovation
In the Catalyst series, we explore the transformative power of AI by showcasing visionary companies driving scientific and industry breakthroughs powered by Azure and NVIDIA. This video series spotlights how innovation ignites action and how today’s visionaries are shaping tomorrow with the power of AI and cloud innovation. Building resilience against extreme weather Tomorrow.io turns space-based data into AI-driven forecasting powered by Azure and NVIDIA at a global scale. Its high-performance AI models deliver real-time weather intelligence that helps governments and enterprises anticipate disruption, optimize operations, and act faster in the face of severe events. Expanding access in preventative healthcare Powered by Microsoft Azure and NVIDIA, Helfie uses multimodal AI to transform smartphone selfies into intelligent health screening at scale. By combining advanced models with real-time inference, it delivers rapid biometric insights that help identify risks earlier and expand access to remote and underserved communities. How AI is mapping the tree of life Powered by Azure and NVIDIA to build the world’s largest biological databases, Basecamp Research is decoding the complexity of biology to accelerate scientific breakthroughs. Building the next frontier of data Powered by Microsoft Azure and NVIDIA, Global Objects is digitizing the real world by creating high-fidelity digital twins of over 5 million physical items. These photorealistic 3D models are transforming immersive content creation across Hollywood, gaming, robotics, and cultural preservation. Changing how doctors diagnose diseases with AI Powered by Microsoft Azure and NVIDIA, Pangaea Data is closing care gaps by identifying untreated and under-treated patients across rare and hard-to-diagnose diseases faster, earlier, and more accurately. Learn more The Catalyst series explores how organizations are using AI infrastructure to tackle some of their most complex technical and business challenges, from accelerating scientific discovery to advancing autonomous systems and transforming core industries. Learn more about Catalyst. Learn more about Azure AI infrastructure.220Views2likes0Comments
Central pki
Has anyone implemented a centralised PKI where the Root CA is stored in Azure Key Vault and workloads can automatically obtain the Root CA when they are deployed, as well as receive updated versions when the Root CA needs to be rotated or renewed? I’m looking to implement a centralised PKI for an Azure hub-and-spoke architecture, where workloads across the spokes can automatically obtain and trust the Root CA. The workloads could include VMs, AKS, containers, App Services and Azure Functions. I’m aware that Azure Machine Configuration can be used to deploy certificates to VMs, but this is specific to VMs. What is the recommended approach for distributing the Root CA to the other Azure workload types using a consistent and automated mechanism? Ideally, I’d like the solution to be fully automated, so that new workloads receive the current Root CA during deployment and existing workloads automatically receive updated versions whenever the Root CA is rotated or renewed. I will be deploying the root ca in a key vault via terraform a project for the root ca only to update whenever is needed and then each resources to be able to get the latest root ca. Has anyone implemented something similar, or could you provide guidance on the recommended architecture and distribution mechanism?137Views0likes1Comment
ExpressRoute Gateway Microsoft initiated migration
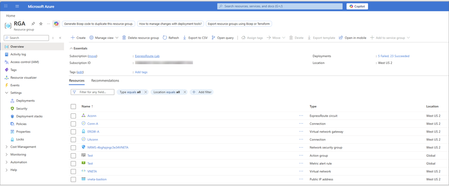
Objective The backend migration process is an automated upgrade performed by Microsoft to ensure your ExpressRoute gateways use the Standard IP SKU. This migration enhances gateway reliability and availability while maintaining service continuity. You receive notifications about scheduled maintenance windows and have options to control the migration timeline. For guidance on upgrading Basic SKU public IP addresses for other networking services, see Upgrading Basic to Standard SKU. Important: As of September 30, 2025, Basic SKU public IPs are retired. For more information, see the official announcement. You can initiate the ExpressRoute gateway migration yourself at a time that best suits your business needs, before the Microsoft team performs the migration on your behalf. This gives you control over the migration timing. Please use the ExpressRoute Gateway Migration Tool to migrate your gateway Public IP to Standard SKU. This tool provides a guided workflow in the Azure portal and PowerShell, enabling a smooth migration with minimal service disruption. Backend migration overview The backend migration is scheduled during your preferred maintenance window. During this time, the Microsoft team performs the migration with minimal disruption. You don’t need to take any actions. The process includes the following steps: Deploy new gateway: Azure provisions a second virtual network gateway in the same GatewaySubnet alongside your existing gateway. Microsoft automatically assigns a new Standard SKU public IP address to this gateway. Transfer configuration: The process copies all existing configurations (connections, settings, routes) from the old gateway. Both gateways run in parallel during the transition to minimize downtime. You may experience brief connectivity interruptions may occur. Clean up resources: After migration completes successfully and passes validation, Azure removes the old gateway and its associated connections. The new gateway includes a tag CreatedBy: GatewayMigrationByService to indicate it was created through the automated backend migration Important: To ensure a smooth backend migration, avoid making non-critical changes to your gateway resources or connected circuits during the migration process. If modifications are absolutely required, you can choose (after the Migrate stage complete) to either commit or abort the migration and make your changes. Backend process details This section provides an overview of the Azure portal experience during backend migration for an existing ExpressRoute gateway. It explains what to expect at each stage and what you see in the Azure portal as the migration progresses. To reduce risk and ensure service continuity, the process performs validation checks before and after every phase. The backend migration follows four key stages: Validate: Checks that your gateway and connected resources meet all migration requirements for the Basic to Standard public IP migration. Prepare: Deploys the new gateway with Standard IP SKU alongside your existing gateway. Migrate: Cuts over traffic from the old gateway to the new gateway with a Standard public IP. Commit or abort: Finalizes the public IP SKU migration by removing the old gateway or reverts to the old gateway if needed. These stages mirror the Gateway migration tool process, ensuring consistency across both migration approaches. The Azure resource group RGA serves as a logical container that displays all associated resources as the process updates, creates, or removes them. Before the migration begins, RGA contains the following resources: This image uses an example ExpressRoute gateway named ERGW-A with two connections (Conn-A and LAconn) in the resource group RGA. Portal walkthrough Before the backend migration starts, a banner appears in the Overview blade of the ExpressRoute gateway. It notifies you that the gateway uses the deprecated Basic IP SKU and will undergo backend migration between March 7, 2026, and April 30, 2026: Validate stage Once you start the migration, the banner in your gateway’s Overview page updates to indicate that migration is currently in progress. In this initial stage, all resources are checked to ensure they are in a Passed state. If any prerequisites aren't met, validation fails and the Azure team doesn't proceed with the migration to avoid traffic disruptions. No resources are created or modified in this stage. After the validation phase completes successfully, a notification appears indicating that validation passed and the migration can proceed to the Prepare stage. Prepare stage In this stage, the backend process provisions a new virtual network gateway in the same region and SKU type as the existing gateway. Azure automatically assigns a new public IP address and re-establishes all connections. This preparation step typically takes up to 45 minutes. To indicate that the new gateway is created by migration, the backend mechanism appends _migrate to the original gateway name. During this phase, the existing gateway is locked to prevent configuration changes, but you retain the option to abort the migration, which deletes the newly created gateway and its connections. After the Prepare stage starts, a notification appears showing that new resources are being deployed to the resource group: Deployment status In the resource group RGA, under Settings → Deployments, you can view the status of all newly deployed resources as part of the backend migration process. In the resource group RGA under the Activity Log blade, you can see events related to the Prepare stage. These events are initiated by GatewayRP, which indicates they are part of the backend process: Deployment verification After the Prepare stage completes, you can verify the deployment details in the resource group RGA under Settings > Deployments. This section lists all components created as part of the backend migration workflow. The new gateway ERGW-A_migrate is deployed successfully along with its corresponding connections: Conn-A_migrate and LAconn_migrate. Gateway tag The newly created gateway ERGW-A_migrate includes the tag CreatedBy: GatewayMigrationByService, which indicates it was provisioned by the backend migration process. Migrate stage After the Prepare stage finishes, the backend process starts the Migrate stage. During this stage, the process switches traffic from the existing gateway ERGW-A to the new gateway ERGW-A_migrate. Gateway ERGW-A_migrate: Old gateway (ERGW-A) handles traffic: After the backend team initiates the traffic migration, the process switches traffic from the old gateway to the new gateway. This step can take up to 15 minutes and might cause brief connectivity interruptions. New gateway (ERGW-A_migrate) handles traffic: Commit stage After migration, the Azure team monitors connectivity for 15 days to ensure everything is functioning as expected. The banner automatically updates to indicate completion of migration: During this validation period, you can’t modify resources associated with both the old and new gateways. To resume normal CRUD operations without waiting 15 days, you have two options: Commit: Finalize the migration and unlock resources. Abort: Revert to the old gateway, which deletes the new gateway and its connections. To initiate Commit before the 15-day window ends, type yes and select Commit in the portal. When the commit is initiated from the backend, you will see “Committing migration. The operation may take some time to complete.” The old gateway and its connections are deleted. The event shows as initiated by GatewayRP in the activity logs. After old connections are deleted, the old gateway gets deleted. Finally, the resource group RGA contains only resources only related to the migrated gateway ERGW-A_migrate: The ExpressRoute Gateway migration from Basic to Standard Public IP SKU is now complete. Frequently asked questions How long will Microsoft team wait before committing to the new gateway? The Microsoft team waits around 15 days after migration to allow you time to validate connectivity and ensure all requirements are met. You can commit at any time during this 15-day period. What is the traffic impact during migration? Is there packet loss or routing disruption? Traffic is rerouted seamlessly during migration. Under normal conditions, no packet loss or routing disruption is expected. Brief connectivity interruptions (typically less than 1 minute) might occur during the traffic cutover phase. Can we make any changes to ExpressRoute Gateway deployment during the migration? Avoid making non-critical changes to the deployment (gateway resources, connected circuits, etc.). If modifications are absolutely required, you have the option (after the Migrate stage) to either commit or abort the migration.3.4KViews1like3CommentsExpanding access to specialized GPU infrastructure through Dapple and Azure
Enterprise AI has entered a new phase. For much of the past decade, the challenge was building enough compute for machine learning. Today, organizations need platforms for foundation model training, fine-tuning, large-scale inference, agentic systems, and enterprise AI. As these workloads grow in scale and sophistication, the infrastructure supporting them is undergoing a fundamental transformation. The defining characteristic of modern AI infrastructure is no longer compute alone. It is topology. Training state-of-the-art AI models requires coordinated communication across hundreds or thousands of accelerators. Performance increasingly depends on how GPUs are interconnected, how data moves across the network fabric, and how efficiently distributed systems synchronize at scale—making network architecture as critical as compute performance. This shift is driving purpose-built AI infrastructure built around tightly coupled GPU fabrics, accelerated networking back-end interconnects, specialized storage architectures, and operational models that treat physical topology as a first-class concern. The challenge is turning this infrastructure into AI production without creating a separate operational domain or adding complexity for platform teams, application developers, and infrastructure operators. A new approach to scaling purpose-built AI infrastructure Microsoft is expanding access to purpose-built GPU capacity through infrastructure partners, including Dapple. Customers can use this specialized infrastructure within the Azure environment they already rely on to operate and govern their workloads. Through our collaboration, Dapple’s dedicated, topology-aware GPU infrastructure (Dapple Private AI Cloud | Microsoft Marketplace) is integrated into an Azure-native operating model that preserves Azure governance, security, and operational consistency. This model for purpose-built AI infrastructure can benefit any organization running compute-intensive AI workloads, including large-scale pre-training, fine-tuning, and distributed inference. Why purpose-built AI infrastructure matters AI workloads place demands on infrastructure that differ fundamentally from traditional enterprise applications. Conventional cloud architectures support a broad range of workloads across diverse infrastructure pools. Large-scale AI training environments, by contrast, depend on highly deterministic infrastructure characteristics, including GPU proximity, network topology, bandwidth consistency, and low-latency communication across thousands of accelerators. As model sizes continue to grow, the efficiency of the underlying GPU fabric becomes a critical determinant of training performance, infrastructure utilization, and overall time-to-results. For this reason, many AI deployments are increasingly built around purpose-designed GPU clusters featuring: Fixed infrastructure topology Dedicated InfiniBand fabrics High-bandwidth, low-latency communication paths Topology-optimized storage architectures Rack-scale and cluster-scale operational boundaries These systems are designed as integrated AI platforms rather than collections of independent compute nodes. Purpose-built GPU infrastructure is organized around validated cluster blocks: groups of compute, network, and related resources managed as a single topology, readiness, and maintenance boundary within InfiniBand fabric domains. Kubernetes nodes remain workload-scheduling objects, while cluster blocks represent the infrastructure unit on which distributed-job performance and availability depend. Figure 1 highlights an important distinction between traditional cloud infrastructure and modern AI systems. In conventional environments, compute resources are often treated as interchangeable units. Distributed AI workloads operate differently. GPU placement, rack boundaries, InfiniBand connectivity, and cluster block relationships can directly influence training throughput, communication efficiency, and overall job completion time. Physical topology therefore becomes a first-class operational consideration. The scheduler must account not only for resource availability, but also for how GPUs, racks, fabric domains, and cluster blocks relate to one another. Extending Azure beyond traditional cloud boundaries Addressing this challenge requires more than connecting specialized AI infrastructure to Azure. Purpose-built infrastructure must operate as a natural extension of the Azure environment, with the governance, security, and operational experience customers already use. This is where Azure and enterprise AI clouds such as Dapple are taking a different approach. Rather than treating large-scale GPU clusters as isolated infrastructure islands, the architecture extends the Azure operational model into dedicated AI environments. Customers can continue using familiar Azure governance frameworks, security models, and operational tools while leveraging infrastructure specifically optimized for large-scale AI workloads. The result is an architecture that combines two complementary capabilities: Purpose-built AI infrastructure optimized for topology-aware GPU workloads An Azure-native operational experience that preserves governance, security, and lifecycle consistency This model enables organizations to focus on AI innovation without creating a separate operational domain for their most demanding AI infrastructure. The role of Azure Kubernetes Service as the operational control plane As AI infrastructure evolves, the role of Kubernetes is evolving alongside it. Kubernetes has become the dominant platform for orchestrating cloud-native applications, AI services, and distributed workloads. Increasingly, it is also becoming the operational abstraction layer that enables organizations to manage heterogeneous infrastructure through a consistent interface. Azure Kubernetes Service (AKS) plays a critical role in this evolution. In the Azure and Dapple architecture, AKS serves as the primary operational control plane for AI workloads running on purpose-built GPU infrastructure. The physical infrastructure remains optimized around the realities of large-scale AI systems, including GPU topology, InfiniBand fabrics, hardware maintenance domains, and infrastructure lifecycle management. At the same time, platform teams continue to interact through familiar Kubernetes constructs for workload deployment, scheduling policies, governance, and lifecycle management. Organizations gain access to infrastructure designed specifically for modern AI workloads while preserving the operational consistency of a Kubernetes-based platform. In practice, enterprises rarely operate a single orchestrator. Kubernetes provides the common substrate, but the layers above it differ by team: batch schedulers for large training runs, workflow engines for data and fine-tuning pipelines, and internal control planes built around a specific operating model. Many organizations run several of these concurrently. For this reason, orchestration is best treated as a customer-owned concern. The infrastructure layer remains responsible for presenting consistent topology, readiness, and lifecycle semantics to whichever orchestrators an organization already operates. Extending Kubernetes into topology-aware infrastructure While Kubernetes excels at abstracting infrastructure, large-scale AI systems frequently require orchestration platforms that understand physical topology, maintenance boundaries, network fabrics, and hardware relationships. Simply exposing GPUs to a scheduler is no longer sufficient. Infrastructure operations must account for cluster blocks, fabric domains, rack boundaries, node recovery workflows, and physical lifecycle management activities that do not naturally exist within traditional Kubernetes environments. To bridge this challenge, Azure and Dapple are collaborating on an architecture that extends Kubernetes operations into topology-aware AI infrastructure while maintaining a clear separation between workload intent and infrastructure intent. Within this model, AKS remains the authoritative control plane for Kubernetes operations. Platform teams continue to leverage: Kubernetes APIs GitOps workflows Policy management Application lifecycle operations Multi-cluster governance AI workload orchestration At the infrastructure layer, Dapple maintains awareness of: Cluster-block composition GPU fabric topology Network-domain relationships Hardware lifecycle operations Infrastructure maintenance events Recovery and repave workflows The Dapple Operator serves as the integration layer between these domains. Rather than exposing infrastructure complexity directly to platform teams, the operator translates Azure-native operational intent into topology-aware infrastructure actions while synchronizing infrastructure state back into the Kubernetes environment. When hardware maintenance, node replacement, cluster recovery, or lifecycle events occur, the operator coordinates state transitions across both layers, helping ensure that infrastructure operations and workload operations remain aligned. FlexNode connects external workers to AKS, while the Dapple Operator synchronizes cluster block identity, topology, fabric health, maintenance intent, and rejoin evidence with the underlying Dapple infrastructure. This architecture reflects an important design principle: AKS remains responsible for workload intent, while Dapple remains responsible for infrastructure intent. The result is a unified operational model that preserves the architectural characteristics of purpose-built AI infrastructure while enabling Azure-native operations. Learn more Dapple Private AI Cloud | Microsoft Marketplace Dapple | The Enterprise OS Cloud780Views2likes0Comments