updates
36 Topics
Microsoft at OCP Global Summit 2026
At OCP Global Summit 2026, Microsoft will showcase how we’re advancing the infrastructure needed to scale AI, from silicon and systems to the datacenter. Visit Microsoft at booth C73 At Booth C73, get a closer look at Cobalt 200 and Maia silicon, advanced cooling, sustainability demonstrations, and security technologies, and hear from Microsoft leaders and experts through our keynote and sessions, panels, and workshops across the summit. Purpose-built silicon • Cobalt 200 • Maia 200 • Maia 300 • Azure Boost Cooling • 3rd Gen Azure Heat Exchange Unit Sustainability • DC Waste Heat Recovery • Circularity Server Reuse Security • Caliptra 2.2 and Platform Attestation • Baremetal Architecture Hardware Partitioning • Integrated HSM Fleet reliability • OCP RAS API demo • Debug and diagnostics Featured Sessions KEYNOTE Intelligence Infrastructure: Scaling AI for the Frontier Era October 13 · 9:15 AM - 9:35 AM · SJCC, Street Level, South Hall AI infrastructure depends on co-design across silicon, systems, software, and sites. This keynote examines how Microsoft brings those layers together to build scalable, reliable, and efficient infrastructure with security embedded throughout. It explores the path from technology development to a global fleet, how requirements change at scale, and how those lessons shape next-generation platforms. The session also considers sustainable scaling through closed-loop cooling and lower-carbon construction, the role of grid reliability and workforce development in host communities, and the challenges that call for ecosystem innovation. EXECUTIVE SESSION Powering the AI Era: Building Sustainable and Efficient Infrastructure at Cloud Scale October 12 · 2:30 PM - 2:50 PM · SJCC, Concourse Level, 210AE The explosive growth of generative AI is driving an unprecedented increase in demand for computing infrastructure. As AI workloads scale from training to widespread inference, every layer of the cloud stack is being challenged, from power grids and datacenters to servers, silicon, and software systems. Meeting this demand sustainably requires rethinking how computing infrastructure is designed, operated, and optimized. Microsoft Breakout Sessions, Panels, and Workshops Explore Microsoft daily sessions and hear from experts shaping the future of cloud and AI infrastructure. Tuesday, October 13 9:55 - 10:00 AM KEYNOTE Women in OCP (WOCP) - Community First, AI Forward Speakers: Sung Kim - BP Castrol, Shruti Sethi - Microsoft, Allison Boen - Alcatex and Shell Fluid, Anu Ramamurthy - Microchip Location: SJCC - Street Level - South Hall 1:15 - 1:35 PM PRESENTATION | OIF Workshop Enabling AI Scale-Up: Why Standards Matter and the Need for Industry Alignment Speakers: Fotini Karinou - Microsoft Location: SJCC - Lower Level - LL20BCD 1:45 - 2:00 PM PRESENTATION | Networking Switch Platform Architecture: A Unified Network Switch Platform Reference Design Speakers: Tao Ren - Meta, Ying Xie - Microsoft Location: SJCC - Concourse Level - 210AE 1:50 - 2:15 PM PANEL | AI Open Data Center Beyond the Build: Autonomous Robotics and the Future of Data Center Operations Speakers: Shashank Gupta - Fleet Data Centers, Eric Xu - Meta, Rob Lawson-Shanks - Molg, Evan Johnson - Microsoft; Moderator: Joel Chakkalakal - PHS West Location: SJCC - Concourse Level - 210CG 1:55 - 2:20 PM PRESENTATION | Manageability Workshop Redfish Aliasing Support and Redfish Streaming Telemetry Enhancements Speakers: Bill Scherer - HPE, Hari Ramachandran - Microsoft Corporation, Jeff Autor - Vertiv Location: SJCC - Lower Level - LL21BC 2:20 - 2:45 PM PANEL | AI Open Data Center Material Handling Automation for Next-Generation Datacenter Operations Speakers: Rachel Soukup - Google; Ben Wong - Meta; Amir Porter - Microsoft; Moderator: Evan Johnson - Microsoft Location: SJCC - Concourse Level - 210CG 2:20 - 2:45 PM PANEL | AI Computing Continuum Two Years of x86 Ecosystem Collaboration: Open Infrastructure, AI Readiness, and Developer Predictability Speakers: Jeff McVeigh - Intel, Stephen Watt - Red Hat, Andrew Wheeler - HPE, Martin Dixon - Google, Jon Lange - Microsoft; Moderator: Robert Hormuth - AMD Location: SJCC - Concourse Level - 211 2:35 - 2:45 PM PRESENTATION | IPEC Workshop IPEC Presentation Speakers: Yawei Yin - Microsoft Location: SJCC - Concourse Level - 230A 3:15 - 3:45 PM PANEL | AI Open Data Center Automation-Ready Infrastructure Design: From Light to Compute Speakers: Mike McKee-Hector - Microsoft, Dave Evans - Google, Ryan Olson - Meta; Moderator: Eric Xu - Meta Location: SJCC - Concourse Level - 210CG 3:50 - 4:05 PM PRESENTATION | Cooling Environments Building a Scalable Waste Heat Ecosystem: Datacenter Waste Heat, Offtakers, and Market Platforms Speakers: Maria Viitaniemi - Microsoft, Bharath Ramakrishnan - Microsoft Location: SJCC - Concourse Level - 220C 4:00 - 4:20 PM PRESENTATION | Manageability Workshop Using SPDM for PLDM Firmware Updates: Authorization Policy and Measurement Manifest Capabilities Speakers: Patrick Caporale - Lenovo, Brett Henning - Broadcom Inc., Scott Phuong - Microsoft Location: SJCC - Lower Level - LL21BC 4:10 - 4:45 PM PRESENTATION | Cooling Environments Heat Reuse Sub-Project Overview and Updates + Economics Tool Contribution Speakers: Aime Comella - DayOne; Jack Kolar - Dataquarium; Gemma Reeves - Alfa Laval; Bharath Ramakrishnan - Microsoft; Ahliana Byrd - Ascentra Innovations Location: SJCC - Concourse Level - 220C Wednesday, October 14 8:00 - 8:25 AM PANEL | AI Open DC: Power Distribution +/-400V / 800V On-Board Power Delivery Requirements Speakers: James Sun - Microsoft, Sachin Madhusoodhanan - Google, LJ (Jian) Lu - Google, Shengwen Xu - Meta; Moderator: Michelle Badal - Google Location: SJCC - Concourse Level - 210CG 8:15 - 9:10 AM PANEL | Systems Management OCP Hardware Fault Management Workstreams Status and Relationship Speakers: Theodros Yigzaw - NVIDIA; Vilas Sridharan - AMD; Janusz Jurski - Intel; Shubhada Pugaonkar - NVIDIA; Samer El-Haj-Mahmoud - Arm; Moderator: Drew Walton - Microsoft Location: Concourse Level - 211 8:15 - 8:35 AM PRESENTATION | SONiC Workshop SONiC Community Year in Review: Powering the Open Network for the AI Era Speakers: Yanzhao Zhang - Microsoft, Xin Liu - Microsoft Location: SJCC - Concourse Level - 230A 8:20 - 8:40 AM PRESENTATION | Storage Comprehensive Testing for OCP Datacenter NVMe SSD Specification Compliance Speakers: Timothy Sharp - Microsoft Corp, Nick Kriczky - Teledyne Lecroy, Rick Walsh - SANBlaze Location: SJCC - Concourse Level - 212 8:25 - 8:50 AM PANEL | Market Impact & Adoption PG25 at Scale: What We've Learned and Where We're Going Speakers: Keegan Yaroch - DOW Chemical, Paul Artman - AMD, Jacob Paugh - ChemTreat, Cam Turner - Microsoft; Moderator: Chris Campbell - Vertiv Location: SJCC - Lower Level - LL21DE 8:30 - 8:50 AM PRESENTATION | OCP Special Focus: Photonics Optical Scale-Up AI Systems: Architectures, Standards, and Resiliency Strategies Speakers: Fotini Karinou - Microsoft, Adrian Motamedi - Microsoft Location: SJCC - Concourse Level - 210AE 8:45 - 9:05 AM PRESENTATION | Cooling Environments Air vs. Liquid: Where Does Air Cooling Still Win for General Compute? Speakers: Jayesh Shah - Microsoft, Stewart Nguyen - Lenovo Location: SJCC - Concourse Level - 220C 9:30 - 9:45 AM SYMPOSIUM: POSTER AND PRESENTATION | FTS: Keynotes & Awards Poster Session Break Speakers: Samir Rajadnya - Microsoft, Oren Benisty - UniFabriX, Konstantin Tiutin - RIVVOR Inc., Timour Paltachev - Rivvor, Nazym Paltachev - rivvor, Sangsu Park - Samsung, Tushar Krishna - Georgia Institute of Technology, Seyyed Ali Ghorashi - Danovo Energy Solutions, Daniel Bauer - LoadCrest, Weipeng Zhang - LightXcelerate Inc, Manchen Hu - LightXcelerate, Xinyu Zhang - XPerf, Rakesh Sambaraju - Infraeo Inc., Xufu Ren - University of Cambridge, Yunqi Zhang - University of Cambridge, Shawn Yan - Vulcadi Inc, David Gyulnazaryan - Impleon, ROGER BASU - Coreshell Technologies, Inc, Fanny Oukhemanou - Syensqo, Taner Dosluoglu - weeteq, Patrick McCluskey - University of Maryland at College Park, Ibaad Gandikota - University of Maryland, Sang woo Ham - Lawrence Berkeley National Laboratory, Sam Abdel-Rahman - Infineon Technologies, Shuyu Zhang - UC Berkeley Location: SJCC - Lower Level - LL20BCD 9:45 - 10:00 AM PRESENTATION | Server Scaling Hyperscale Cloud Networking from 400G to 800G: System Integration Lessons and Implications for OCP Platforms Speakers: Lucy Yu - MSFT, Faye Yang - Microsoft Location: SJCC - Lower Level - LL21BC 9:50 - 10:10 AM PRESENTATION | SONiC Workshop SONiC BMC for Unified Management and Next-Generation Liquid-Cooled Networks Speakers: Judy Joseph - Microsoft, Roger Liao - Nexthop Systems Inc. Location: SJCC - Concourse Level - 230A 10:05 - 10:20 AM PRESENTATION | OCP Special Focus: Photonics System-Level Evaluation of XPO for High-Density Optical Interconnects in AI Infrastructure Speakers: Daniel Mohaghegh - Microsoft, Sunil Priyadarshi - Arista Networks Location: SJCC - Concourse Level - 210AE 10:05 - 10:25 AM PRESENTATION | Market Impact & Adoption Upgrading OCP S.A.F.E. and S.O.L.I.D. for the AI age Speakers: Zahra Lak - Microsoft, Jeff Andersen - Google Location: SJCC - Lower Level - LL21DE 10:10 - 10:30 AM PRESENTATION | Systems Management System-Level Manageability for GPU Platforms — Progress in the OCP System GPU Management Workstream Speakers: John Leung - Intel, Hari Ramachandran - Microsoft Corporation Location: SJCC - Concourse Level - 211 10:40 - 11:00 AM PRESENTATION | SONiC Workshop Democratizing DPU High Availability with a SONiC-Driven DASH HA Control Plane Speakers: Changrong Wu - Microsoft, Sudharsan Dhamal Gopalarathnam - NVIDIA Location: SJCC - Concourse Level - 230A 10:50 - 11:10 AM PRESENTATION | Server Accelerating High-Power Server Design Through Board-Level Electro-Thermal Co-Simulation of VRMs and PDNs Speakers: Steven Chien - Wiwynn Corporation, Zi Ping Wu - Microsoft Location: SJCC - Lower Level - LL21BC 11:30 AM - 1:00 PM PANEL | Meals & Breaks Women in AI Luncheon presented by Women in OCP (WOCP) - Sponsored by Lenovo & NVIDIA Speakers: Casey Moran - Lenovo, Cathie Deal - IREN, Shruti Koparkar - NVIDIA, Shruti Sethi - Microsoft; Moderator: Allison Boen - Alcatex and Shell Fluid Location: San Jose Marriott - Level 2 - Salon III & IV 11:45 AM - 12:00 PM Expo Hall Sessions | SONiC Open, Trusted, and Secure SONiC at Scale presented by Cisco Speakers: Will Eatherton - Cisco; Dina Papagiannaki - Microsoft Location: SJCC – Concourse Level – Expo Hall Theater 12:30 - 12:50 PM PRESENTATION | SONiC Workshop Beyond the T2 PIN: Pizza-Box Disaggregation for Next-Gen Regional Hubs Speakers: Kamini Santhanagopalan - Broadcom, Rita Hui - Microsoft Location: SJCC - Concourse Level - 230A 12:55 - 1:15 PM PRESENTATION | Systems Management Runtime SBOMs: Extending DMTF Redfish to Connect Build-Time and Live Software State Speakers: Harsh Bhuwania - Microsoft, Prashant Dewan - Microsoft Location: SJCC - Concourse Level - 211 1:20 - 1:40 PM PRESENTATION | SONiC Workshop 6–12x Route Programming Acceleration in SONiC: A Collaborative Profiling and Optimization Journey Speakers: Deepak Singhal - Microsoft, Amol Rawal - Nokia Location: SJCC - Concourse Level - 230A 1:20 - 1:50 PM PRESENTATION | Systems Management GPU & CPU Diagnostics and RAS Standardization Advances for Hyperscale Infrastructure Speakers: Rama Bhimanadhuni - Microsoft, Taniya Siddiqua - Advanced Micro Devices, Inc. Location: SJCC - Concourse Level - 211 1:35 - 1:55 PM PRESENTATION | AI Open DC: Power Distribution Designing Safe 800 VDC Systems: Protection, Fault Management, and Operations Speakers: Mike Tu - NVIDIA, Xianyong Feng - Microsoft Location: SJCC - Concourse Level - 210CG 3:15 - 3:35 PM PRESENTATION | Systems Management From Lab to Fleet: A Secure, Unified Debug Framework for Cloud Systems Speakers: Suresh Duthiraru - Microsoft, Rolf Kuehnis - Lauterbach Inc. Location: SJCC - Concourse Level - 211 3:15 - 3:55 PM PANEL | Storage OCP Storage Specifications Update and What Customers Care About Speakers: David Black - Dell Technologies, Timothy Sharp - Microsoft Corp., Chris Sabol - Google, Jeff Wolford - HPE, Vineet Parekh - Meta; Moderator: Ross Stenfort - SanDisk Location: SJCC - Concourse Level - 212 3:40 - 4:00 PM PRESENTATION | SONiC Workshop Extending Community SONiC for Advanced Optics Telemetry Aligned with OCP Standards Speakers: Rajan Pai - Credo, Prince George - Microsoft Location: SJCC - Concourse Level - 230A 3:54 - 5:00 PM SYMPOSIUM: PRESENTATION ONLY | FTI Workshop: Short Reach Optical Interconnects Scale-up optical reliability and GPU/system resiliency to optical link flaps Speakers: Eduard Roytman - Microsoft, Lenin Patra - Marvell, Ashwin Gumaste - NVIDIA, Greg Link - Microsoft, Jeffrey Hutchins - Ranovus Location: SJCC - Lower Level - LL21BC 4:00 - 4:20 PM PRESENTATION | Storage Adopting high-capacity HDDs, navigating throughput and IOPS Limits using SAS/NVME interfaces for the AI Cloud Speakers: Hariharan Kumar - Microsoft, Balaji Natrajan - Microsoft Location: SJCC - Concourse Level - 212 4:10 - 4:30 PM PRESENTATION | Systems Management Operating OpenBMC at Hyperscale: What Works, What Breaks, and What Needs to Change Speakers: Thirupathaiah Annapureddy - Microsoft, Hari Ramachandran - Microsoft Corporation Location: SJCC - Concourse Level - 211 4:30 - 4:50 PM PRESENTATION | SONiC Workshop FIPS 140-3 Support in SONiC Speakers: Kenneth Cheung - Arista Networks, Qi Luo - Microsoft Location: SJCC - Concourse Level - 230A 4:30 - 5:00 PM PANEL | AI Clusters Scale-across Networking: Panel discussion on routing and transport equipment implications Speakers: Jeff Rahn - Meta, Yawei Yin - Microsoft, Xiguang - Henry Wu - Broadcom, Tad Hofmeister - Google; Moderator: Vijay Vusirikala - Arista Networks Location: SJCC - Concourse Level - 220B 4:35 - 5:00 PM PRESENTATION | Systems Management From Scale to Security: Evolving GPU Management Standards in 2026 Speakers: Krishna Sugumaran - AMD, Sujoy Sen - Google, Akkiah (Choudary) Maddukuri - Microsoft, Qian Wang - NVIDIA, Balaji Vembu - Meta Location: SJCC - Concourse Level - 211 Thursday, October 15 8:00 - 8:20 AM PRESENTATION | AI Clusters MX v1.1: Advancing Open Standards for Low-Precision AI with MicroXcaling formats Speakers: Partha Maji - Microsoft Location: SJCC - Concourse Level - 220B 8:00 - 8:25 AM PANEL | Sustainability Updates from an exciting year with the OCP Sustainability Project, DCF Sustainability Project & Roadmap ahead Speakers: Alexander Rakow - Schneider Electric, Sung Kim - BP Castrol, Shruti Sethi - Microsoft, Priya Chhiba - Google Location: SJCC - Lower Level - LL21DE 8:20 - 8:40 AM PRESENTATION | Security Integrated HSM: Bringing Silicon-Level Key Security to the Server Tray Speakers: Craig Barner - Marvell, Vishal Soni - Microsoft, Mohan Kumar - Oracle Cloud Infrastructure Location: SJCC - Concourse Level - 212 8:45 - 9:05 AM PRESENTATION | Test & Validation AI-Native Hardware Validation: Building a Local-Context Agentic Test and Debug Platform Speakers: Wenxi Yan - Microsoft Location: SJCC - Lower Level - LL20BCD 8:50 - 9:05 AM PRESENTATION | Sustainability Performance-Normalized Embodied Rack Carbon Intensity for Next-Generation Hardware Speakers: Kali Frost - Microsoft Location: SJCC - Lower Level - LL21DE 9:10 - 9:30 AM PRESENTATION | Networking ESUN: Open Ethernet for the AI Scale-Up Era Speakers: Pratik Marolia - Microsoft, Manoj Wadekar - Meta Location: SJCC - Concourse Level - 210AE 9:10 - 9:30 AM PRESENTATION | Test & Validation From Spec to Sign-off - How Microsoft is transforming the platform validation workflow leveraging AI-powered, agent-driven solutions. Speakers: Rahul Shah - Microsoft, Vikram Vemulapalli - Microsoft Location: SJCC - Lower Level - LL20BCD 9:10 - 9:30 AM PRESENTATION | Rack & Power Scaling Hyperscale Power Delivery: Managing Aggregated and Cascaded Power Shelf Architectures for High-Density GPU Systems Speakers: Praveen Kumar Velpuri - Microsoft, Yang Hsiung - Microsoft Location: SJCC - Concourse Level - 230A 9:45 - 10:20 AM PANEL | Server: Composable Memory Systems Addressing Memory Wall challenge for AI and General Compute platforms (CMS Sub-Project Technical Update) Speakers: Anjaneya "Reddy" Chagam - Microsoft Corporation, Grant Mackey - XCENA, Mohamad El-Batal - Seagate, Samir Rajadnya - Microsoft Location: SJCC - Lower Level - LL21BC 9:45 - 10:10 AM PANEL | AI Clusters USB to Rule Them All: One Manageability Interface for AI Platforms Speakers: MARIUSZ ORIOL - NVIDIA, Bharat Pillili - Microsoft, Samer El-Haj-Mahmoud - Arm, Mohan Kumar - Oracle Cloud Infrastructure, Supreeth Venkatesh - AMD; Moderator: Kasper Wszolek - NVIDIA Location: SJCC - Concourse Level - 220B 10:45 - 11:30 AM PANEL | Cooling: Cold Plate Pushing the Single-Phase Cold Plate Limit: Design Practice, Field Learnings, and the Runway Before Two-Phase Scales Speakers: Weihua Tang - Google, REMCO VAN ERP - Corintis, Oscar Farias Moguel - Microsoft, Yin Hang - Meta; Moderator: Joel Chakkalakal - Guardian Data- LLC Location: SJCC - Concourse Level - 220C 10:50 - 11:05 AM PRESENTATION | Networking Scaling AI Beyond the Cloud Boundary: High-Capacity Interconnects Between Hyperscalers and GPUaaS NeoClouds Speakers: Krithika Moorthy - Cisco, Anish Narsian - Microsoft Location: SJCC - Concourse Level - 210AE 10:50 - 11:05 AM PRESENTATION | Security Upgrading OCP S.A.F.E. and S.O.L.I.D. for the AI age Speakers: Zahra Lak - Microsoft, Jeff Andersen - Google Location: SJCC - Concourse Level - 212 11:00 - 11:25 AM PRESENTATION | Test & Validation Product Intercept learnings and Compliance measurement for Diagnostics Standardization Speakers: Rajat Madhusudan - Microsoft, Jennifer Lee - Intel Location: SJCC - Lower Level - LL20BCD 11:15 - 11:30 AM PRESENTATION | Sustainability Enabling Scalable Waste Heat Recovery: Operational Realities, Design Principles, and Value from the Datacenter Perspective Speakers: Emily Matys - Microsoft Location: SJCC - Lower Level - LL21DE 12:30 - 12:45 PM PRESENTATION | Security Baremetal Security Architecture Speakers: Bharat Pillili - Microsoft, Darpana Munjal Loodu - Microsoft Location: SJCC - Concourse Level - 212 12:30 - 12:50 PM PRESENTATION | Rack & Power Mitigating AI Training Power Oscillations: Utility Requirements and In-Rack Power Filtering Speakers: Bo Wen - Microsoft, Xianyong Feng - Microsoft Location: SJCC - Concourse Level - 230A 1:15 - 1:30 PM PRESENTATION | Sustainability From Silicon to System: Embedding Power Efficiency as a Core Design Principle for Scalable AI and Compute Infrastructure Speakers: Devang Soparkar - Microsoft, Nilanjan Palit - Intel Location: SJCC - Lower Level - LL21DE 1:45 - 2:00 PM PRESENTATION | Open Platform Firmware (OPF) Dynamic Platform Abstraction for BMC Firmware via Host-Delivered Libraries Speakers: Sarathy Jayakumar - AMD, Rama Bhimanadhuni - Microsoft Location: SJCC - Lower Level - LL20BCD 1:55 - 2:10 PM PRESENTATION | Sustainability Closing the Loop: Structural Steel Reuse in Hyperscale Datacenter Construction — A Scalable Blueprint from Microsoft's Newport Imperial Park Datacenter (CWL01) Speakers: John O’Sullivan - Microsoft, Anjali Bhagat - Microsoft Location: SJCC - Lower Level - LL21DE 1:55 - 2:10 PM PRESENTATION | Security Package-Aware Integrity: From Source-Agnostic Publication to Full-System Attestation Speakers: Felipe Zimmerle da Nobrega Costa - KonaSense, Dhananjay Phadke - Microsoft Location: SJCC - Concourse Level - 212 2:15 - 2:30 PM PRESENTATION | Networking MRC: A Purpose-Built RDMA Transport for AI Training Networks Speakers: Abdul Kabbani - Microsoft, Wael Noureddine - Microsoft Location: SJCC - Concourse Level - 210AE 2:45 - 3:00 PM PRESENTATION | Security BMC-Mediated Platform Composite Attestation via Redfish Speakers: Xiling Sun - Microsoft, Roksana Golizadeh Mojarad - Microsoft Location: SJCC - Concourse Level - 212 2:45 - 3:10 PM PANEL | Sustainability Product Category Rule-style Specification for Life Cycle Assessment on Datacenter ICT-Equipment: Collaborative Progress & Draft publication Speakers: Lisa Rivalin - Meta, Stephan Benecke - Google, Ines Sousa - Microsoft, Vincenzo Ferrero - Amazon; Moderator: Chris Eckstein - Fraunhofer Location: SJCC - Lower Level - LL21DE 2:45 - 3:15 PM PANEL | Open Platform Firmware (OPF) Scaling Memory Safe Security Across Firmware Stack Speakers: Giri Mudusuru - Microsoft, Tim Lewis - Insyde Software, Bertrand Achard - Google, Raj Kapoor - AMD, Oleg Ilyasov - American Megatrends (AMI); Moderator: Murugasamy Nachimuthu - Oracle Location: SJCC - Lower Level - LL20BCD 2:45 - 3:05 PM PRESENTATION | AI Open Data Center The Future of Fuel Cells in Datacenters - High Temperature Fuel Cells. Speakers: Afshin Majd - Microsoft, Priya Chhiba - Google, Alberto Ravagni - Net Zero Innovation Hub Location: SJCC - Concourse Level - 210CG 3:05 - 3:20 PM PRESENTATION | Security Caliptra Subsystem 2.2: USB 2.0 and OCP Streaming Boot Speakers: Caleb Whitehead - Microsoft, Bart Vertenten - NXP Semiconductors Location: SJCC - Concourse Level - 212 3:25 - 3:40 PM PRESENTATION | Security Architectural Masking for PQC: Adam’s Bridge 3.0 Leveraging NTT Linearity Speakers: Mojtaba Bisheh-Niasar - Microsoft, Kiran Upadhyayula - Microsoft Location: SJCC - Concourse Level - 212 3:35 - 4:00 PM PANEL | Sustainability Increasing Rigor in Data Center Carbon Disclosure Speakers: Andrea Desimone - Schneider Electric, Lalit Joshi - Microsoft, Malcolm Hegeman - Google, Miranda Gardiner - iMasons Climate Accord; Moderator: Nalintip Suwannakarn - Meta Location: SJCC - Lower Level - LL21DE 3:45 - 4:00 PM PRESENTATION | Security Beyond Static Identity: Enabling Secure Certificate Refresh in Silicon Roots of Trust Speakers: Emre Karabulut - Microsoft, VISHAL MHATRE - Microsoft Location: SJCC - Concourse Level - 212 Offsite Microsoft Workshops 8:00 AM - 3:00 PM WORKSHOP RAS Workshop (at capacity) Hyperscalers, silicon vendors, and ecosystem partners will collaborate on RAS, Debug, Diagnostics, and Manageability initiatives, focused on aligning current requirements, sharing implementations and tools, and discussing the future direction of key specifications and workstreams. Location: MTV Campus 8:30 AM - 2:00 PM; 2:00 - 5:00 PM WORKSHOP Caliptra and BoF Workshops (at capacity) Members of the open-source silicon security community will collaborate on hardware root of trust technologies and secure silicon initiatives through discussions on ongoing technical work, ecosystem collaboration, implementation experiences, roadmap planning, community engagement, and related open-source security efforts Location: MTV Campus Learn more Infrastructure for the frontier era: Scaling intelligence through open industry collaboration Advancing hardware security with open-source Integrated HSM technology Powering Azure Infrastructure from Grid to Chip Advancing AI fleet reliability through industry collaboration Networking for the AI Era: Building for Scale, Efficiency, and Openness1.7KViews0likes0CommentsScaling distributed AI infrastructure with Azure’s ExpressRoute and AI Points of Presence (AI PoPs)
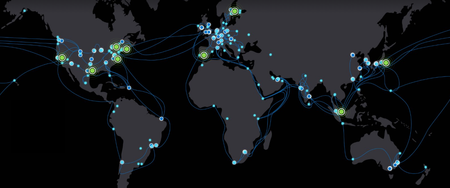
Rethinking connectivity for distributed AI infrastructure AI is changing more than the applications organizations build. It is reshaping where the infrastructure powering those applications is deployed. For years, cloud computing has been anchored by hyperscale regions that combine compute, storage, networking, security, and operations at massive scale. That model remains foundational to Microsoft Azure. At the same time, rapid AI growth is creating a more distributed infrastructure landscape. GPU capacity is increasingly being deployed across regions, providers, facilities, and operating environments wherever the right mix of power, space, cooling, and specialized infrastructure is available. That shift creates a practical challenge: how do organizations bring new GPU capacity online quickly while still giving AI workloads the Azure services, governance, security, and operational consistency they require? Microsoft’s approach: extending Azure to distributed AI infrastructure Microsoft is taking a platform approach to distributed AI infrastructure. For customers, Azure ExpressRoute offers the private connectivity experience for connecting remote sites and infrastructure to Azure. Behind that experience, AI PoPs provide Microsoft with a standardized infrastructure architecture for integrating distributed third-party GPU capacity into the Azure network and operating environment. Rather than building a unique network and operational integration for every external GPU deployment, Microsoft can use AI PoPs to onboard and aggregate GPU capacity wherever the GPUs may be, while customers continue to connect through familiar Azure networking products such as ExpressRoute. Azure ExpressRoute provides the private connectivity foundation for these customer-managed environments, enabling external GPU infrastructure to connect privately with Azure without traversing the public internet. Combined with the AI PoP architecture, this creates a repeatable model for integrating distributed GPU capacity with Azure, giving customers greater flexibility in where compute comes from while maintaining Azure as the platform connecting their AI environment. Based on current Microsoft deployment and provisioning data, Azure’s AI PoP operating model is already connecting and provisioning hundreds of thousands of GPUs across North America, Europe, and Asia Pacific, giving select preview customers a consistent Azure experience for using distributed AI infrastructure. The aim is simple: bring AI capacity to market faster, wherever it is located, while expanding the range of GPU providers and deployment locations. Customers receive a more consistent Azure experience regardless of where that capacity is located. Figure 1. Global deployment of Microsoft’s AI PoP infrastructure Microsoft is expanding AI PoPs to more than 10 planned sites across North America, Europe, and Asia over the next 12 months. Connecting distributed GPUs for faster connectivity and simpler operations for our customers AI workloads depend on more than chips. They need data, orchestration, identity, monitoring, security, and reliable high-bandwidth connectivity. ExpressRoute provides customers with private, high-bandwidth connectivity to Azure. Behind the scenes, AI PoP infrastructure helps Microsoft integrate and operate distributed third-party GPUs at scale. Together, this architecture can help customers: Connect privately to Azure: Use Azure ExpressRoute for private connectivity from remote sites and distributed infrastructure to Azure. Access distributed GPU capacity: Take advantage of GPU capacity across an expanding ecosystem of infrastructure providers without requiring customers to consume AI PoPs as a separate service. Use familiar Azure services: Connect workloads with Azure storage, orchestration, AI services, security, and operational tooling. Maintain a consistent Azure experience: Use established Azure networking and cloud services even as the physical GPU infrastructure becomes more distributed. For customers, this means less bespoke connectivity work and more focus on putting AI capacity to use. AI PoPs is part of the Microsoft infrastructure that enables Azure to integrate third-party GPU capacity into this experience, with ExpressRoute as a customer-facing service. For infrastructure providers, it creates a clearer path for integrating specialized GPU environments with the Microsoft Cloud. One Azure operating model, wherever AI capacity runs As GPU capacity becomes more distributed, customers should not have to adopt a new connectivity model for every provider or location. Azure ExpressRoute provides the customer connectivity experience, while AI PoPs give Microsoft a repeatable infrastructure architecture for integrating third-party GPU capacity into the Azure network and operating environment. That distinction matters as AI infrastructure spreads across regions and providers. Customers need flexibility in where capacity comes from, along with a reliable way to operate that capacity as part of a broader cloud environment. Microsoft is extending this model across regions to support Azure-connected AI capacity. The key principles behind the model are shown below (Figures 2–4). Figure 2. Example of aggregating capacity across multiple locations A single AI PoP can connect multiple GPU facilities and providers. Instead of treating each deployment as a unique project, new capacity can be onboarded through an established framework. This simplifies expansion, enables Microsoft to bring new capacity online faster, and makes it easier to scale as demand grows. Figure 3. Private connectivity to Azure services through Azure ExpressRoute and AI PoPs GPU capacity alone does not create an AI platform. Training and inference environments also depend on data, applications, orchestration, security, monitoring, and AI services. When GPU infrastructure sits outside Azure, the network becomes the critical bridge between compute and the Azure services it depends on. For customer-managed deployments, Azure ExpressRoute provides private connectivity between external infrastructure and Azure without sending traffic over the public internet. AI PoPs build on this connectivity model to provide a consistent approach for integrating distributed GPU environments with Azure services. Figure 4. AI PoPs deliver a consistent operating model Whether capacity is supplied by Microsoft, partners, or customers, AI PoPs are designed to provide a consistent connectivity and management experience. Standardization simplifies deployment, improves repeatability, and reduces the redesign required when introducing new providers or locations. Together, these design principles can reduce onboarding time, expand infrastructure choice, and provide a consistent Azure-connected experience. Looking ahead Demand for AI infrastructure continues to accelerate. Microsoft’s focus is not only on adding capacity, but also on making capacity available wherever it exists through a secure, reliable, and operationally consistent cloud platform. The next phase will focus on onboarding additional GPU providers, strengthening automation, and expanding Microsoft's ability to integrate distributed AI infrastructure with Azure. As AI PoP infrastructure scales behind Azure, customers can continue to use established Azure products such as ExpressRoute to privately connect remote sites and workloads, while gaining access to a broader ecosystem of distributed GPU capacity. As AI infrastructure becomes increasingly distributed, the ability to onboard capacity quickly, operate consistently across environments, and deliver a seamless Azure experience will become a meaningful differentiator. AI PoPs are one way Microsoft is helping shape that future.1.9KViews2likes0Comments
Catalyst: Frontier stories of AI Infrastructure innovation
In the Catalyst series, we explore the transformative power of AI by showcasing visionary companies driving scientific and industry breakthroughs powered by Azure and NVIDIA. This video series spotlights how innovation ignites action and how today’s visionaries are shaping tomorrow with the power of AI and cloud innovation. Building resilience against extreme weather Tomorrow.io turns space-based data into AI-driven forecasting powered by Azure and NVIDIA at a global scale. Its high-performance AI models deliver real-time weather intelligence that helps governments and enterprises anticipate disruption, optimize operations, and act faster in the face of severe events. Expanding access in preventative healthcare Powered by Microsoft Azure and NVIDIA, Helfie uses multimodal AI to transform smartphone selfies into intelligent health screening at scale. By combining advanced models with real-time inference, it delivers rapid biometric insights that help identify risks earlier and expand access to remote and underserved communities. How AI is mapping the tree of life Powered by Azure and NVIDIA to build the world’s largest biological databases, Basecamp Research is decoding the complexity of biology to accelerate scientific breakthroughs. Building the next frontier of data Powered by Microsoft Azure and NVIDIA, Global Objects is digitizing the real world by creating high-fidelity digital twins of over 5 million physical items. These photorealistic 3D models are transforming immersive content creation across Hollywood, gaming, robotics, and cultural preservation. Changing how doctors diagnose diseases with AI Powered by Microsoft Azure and NVIDIA, Pangaea Data is closing care gaps by identifying untreated and under-treated patients across rare and hard-to-diagnose diseases faster, earlier, and more accurately. Learn more The Catalyst series explores how organizations are using AI infrastructure to tackle some of their most complex technical and business challenges, from accelerating scientific discovery to advancing autonomous systems and transforming core industries. Learn more about Catalyst. Learn more about Azure AI infrastructure.273Views2likes0CommentsExpanding access to specialized GPU infrastructure through Dapple and Azure
Enterprise AI has entered a new phase. For much of the past decade, the challenge was building enough compute for machine learning. Today, organizations need platforms for foundation model training, fine-tuning, large-scale inference, agentic systems, and enterprise AI. As these workloads grow in scale and sophistication, the infrastructure supporting them is undergoing a fundamental transformation. The defining characteristic of modern AI infrastructure is no longer compute alone. It is topology. Training state-of-the-art AI models requires coordinated communication across hundreds or thousands of accelerators. Performance increasingly depends on how GPUs are interconnected, how data moves across the network fabric, and how efficiently distributed systems synchronize at scale—making network architecture as critical as compute performance. This shift is driving purpose-built AI infrastructure built around tightly coupled GPU fabrics, accelerated networking back-end interconnects, specialized storage architectures, and operational models that treat physical topology as a first-class concern. The challenge is turning this infrastructure into AI production without creating a separate operational domain or adding complexity for platform teams, application developers, and infrastructure operators. A new approach to scaling purpose-built AI infrastructure Microsoft is expanding access to purpose-built GPU capacity through infrastructure partners, including Dapple. Customers can use this specialized infrastructure within the Azure environment they already rely on to operate and govern their workloads. Through our collaboration, Dapple’s dedicated, topology-aware GPU infrastructure (Dapple Private AI Cloud | Microsoft Marketplace) is integrated into an Azure-native operating model that preserves Azure governance, security, and operational consistency. This model for purpose-built AI infrastructure can benefit any organization running compute-intensive AI workloads, including large-scale pre-training, fine-tuning, and distributed inference. Why purpose-built AI infrastructure matters AI workloads place demands on infrastructure that differ fundamentally from traditional enterprise applications. Conventional cloud architectures support a broad range of workloads across diverse infrastructure pools. Large-scale AI training environments, by contrast, depend on highly deterministic infrastructure characteristics, including GPU proximity, network topology, bandwidth consistency, and low-latency communication across thousands of accelerators. As model sizes continue to grow, the efficiency of the underlying GPU fabric becomes a critical determinant of training performance, infrastructure utilization, and overall time-to-results. For this reason, many AI deployments are increasingly built around purpose-designed GPU clusters featuring: Fixed infrastructure topology Dedicated InfiniBand fabrics High-bandwidth, low-latency communication paths Topology-optimized storage architectures Rack-scale and cluster-scale operational boundaries These systems are designed as integrated AI platforms rather than collections of independent compute nodes. Purpose-built GPU infrastructure is organized around validated cluster blocks: groups of compute, network, and related resources managed as a single topology, readiness, and maintenance boundary within InfiniBand fabric domains. Kubernetes nodes remain workload-scheduling objects, while cluster blocks represent the infrastructure unit on which distributed-job performance and availability depend. Figure 1 highlights an important distinction between traditional cloud infrastructure and modern AI systems. In conventional environments, compute resources are often treated as interchangeable units. Distributed AI workloads operate differently. GPU placement, rack boundaries, InfiniBand connectivity, and cluster block relationships can directly influence training throughput, communication efficiency, and overall job completion time. Physical topology therefore becomes a first-class operational consideration. The scheduler must account not only for resource availability, but also for how GPUs, racks, fabric domains, and cluster blocks relate to one another. Extending Azure beyond traditional cloud boundaries Addressing this challenge requires more than connecting specialized AI infrastructure to Azure. Purpose-built infrastructure must operate as a natural extension of the Azure environment, with the governance, security, and operational experience customers already use. This is where Azure and enterprise AI clouds such as Dapple are taking a different approach. Rather than treating large-scale GPU clusters as isolated infrastructure islands, the architecture extends the Azure operational model into dedicated AI environments. Customers can continue using familiar Azure governance frameworks, security models, and operational tools while leveraging infrastructure specifically optimized for large-scale AI workloads. The result is an architecture that combines two complementary capabilities: Purpose-built AI infrastructure optimized for topology-aware GPU workloads An Azure-native operational experience that preserves governance, security, and lifecycle consistency This model enables organizations to focus on AI innovation without creating a separate operational domain for their most demanding AI infrastructure. The role of Azure Kubernetes Service as the operational control plane As AI infrastructure evolves, the role of Kubernetes is evolving alongside it. Kubernetes has become the dominant platform for orchestrating cloud-native applications, AI services, and distributed workloads. Increasingly, it is also becoming the operational abstraction layer that enables organizations to manage heterogeneous infrastructure through a consistent interface. Azure Kubernetes Service (AKS) plays a critical role in this evolution. In the Azure and Dapple architecture, AKS serves as the primary operational control plane for AI workloads running on purpose-built GPU infrastructure. The physical infrastructure remains optimized around the realities of large-scale AI systems, including GPU topology, InfiniBand fabrics, hardware maintenance domains, and infrastructure lifecycle management. At the same time, platform teams continue to interact through familiar Kubernetes constructs for workload deployment, scheduling policies, governance, and lifecycle management. Organizations gain access to infrastructure designed specifically for modern AI workloads while preserving the operational consistency of a Kubernetes-based platform. In practice, enterprises rarely operate a single orchestrator. Kubernetes provides the common substrate, but the layers above it differ by team: batch schedulers for large training runs, workflow engines for data and fine-tuning pipelines, and internal control planes built around a specific operating model. Many organizations run several of these concurrently. For this reason, orchestration is best treated as a customer-owned concern. The infrastructure layer remains responsible for presenting consistent topology, readiness, and lifecycle semantics to whichever orchestrators an organization already operates. Extending Kubernetes into topology-aware infrastructure While Kubernetes excels at abstracting infrastructure, large-scale AI systems frequently require orchestration platforms that understand physical topology, maintenance boundaries, network fabrics, and hardware relationships. Simply exposing GPUs to a scheduler is no longer sufficient. Infrastructure operations must account for cluster blocks, fabric domains, rack boundaries, node recovery workflows, and physical lifecycle management activities that do not naturally exist within traditional Kubernetes environments. To bridge this challenge, Azure and Dapple are collaborating on an architecture that extends Kubernetes operations into topology-aware AI infrastructure while maintaining a clear separation between workload intent and infrastructure intent. Within this model, AKS remains the authoritative control plane for Kubernetes operations. Platform teams continue to leverage: Kubernetes APIs GitOps workflows Policy management Application lifecycle operations Multi-cluster governance AI workload orchestration At the infrastructure layer, Dapple maintains awareness of: Cluster-block composition GPU fabric topology Network-domain relationships Hardware lifecycle operations Infrastructure maintenance events Recovery and repave workflows The Dapple Operator serves as the integration layer between these domains. Rather than exposing infrastructure complexity directly to platform teams, the operator translates Azure-native operational intent into topology-aware infrastructure actions while synchronizing infrastructure state back into the Kubernetes environment. When hardware maintenance, node replacement, cluster recovery, or lifecycle events occur, the operator coordinates state transitions across both layers, helping ensure that infrastructure operations and workload operations remain aligned. FlexNode connects external workers to AKS, while the Dapple Operator synchronizes cluster block identity, topology, fabric health, maintenance intent, and rejoin evidence with the underlying Dapple infrastructure. This architecture reflects an important design principle: AKS remains responsible for workload intent, while Dapple remains responsible for infrastructure intent. The result is a unified operational model that preserves the architectural characteristics of purpose-built AI infrastructure while enabling Azure-native operations. Learn more Dapple Private AI Cloud | Microsoft Marketplace Dapple | The Enterprise OS Cloud1KViews2likes0CommentsBuild Your AI Agent in 5 Minutes with AI Toolkit for VS Code
What if building an AI agent was as easy as filling out a form? No frameworks to install. No boilerplate to copy-paste from GitHub. No YAML to debug at midnight. Just VS Code, one extension, and an idea. AI Toolkit for VS Code turns agent development into something anyone can do — whether you're a seasoned developer who wants full code control, or someone who's never touched an AI framework and just wants to see something work. Let's build an agent. Then let's explore what else this toolkit can do. Getting Set Up You need two things: VS Code — download and install if you haven't already AI Toolkit extension — open VS Code, go to Extensions (Ctrl+Shift+X), search "AI Toolkit", and install it That's it. No terminal commands. No dependencies to wrangle. When AI Toolkit installs, it brings everything it needs — including the Microsoft Foundry integration and GitHub Copilot skills for agent development. Once installed, you'll see a new AI Toolkit icon in the left sidebar. Click it. That's your home base for everything we're about to do. Build an Agent — No Code Required Open the Command Palette (Ctrl+Shift+P) and type "Create Agent". You'll see a clean panel with two options side by side: Design an Agent Without Code — visual builder, perfect for getting started Create in Code — full project scaffolding, for when you want complete control Click "Design an Agent Without Code." Agent Builder opens up. Now fill in three things: Give it a name Something descriptive. For this example: "Azure Advisor" Pick a model Click the model dropdown. You'll see a list of available models — GPT-4.1, Claude Opus 4.6, and others. Foundry models appear at the top as recommended options. Pick one. Here's a nice detail: you don't need to know whether your model uses the Chat Completions API or the Responses API. AI Toolkit detects this automatically and handles the switch behind the scenes. Write your instructions This is where you tell the agent who it is and how to behave. Think of it as a personality brief: Hit Run That's it. Click Run and start chatting with your agent in the built-in playground. Want More Control? Build in Code The no-code path is great for prototyping and prompt engineering. But when you need custom tools, business logic, or multi-agent workflows — switch to code. From the Create Agent View, choose "Create in Code with Full Control." You get two options: Scaffold from a template Pick a pre-built project structure — single agent, multi-agent, or LangGraph workflow. AI Toolkit generates a complete project with proper folder structure, configuration files, and starter code. Open it, customize it, run it. Generate with GitHub Copilot Describe your agent in plain English in Copilot Chat: "Create a customer support agent that can look up order status, process returns, and escalate to a human when the customer is upset." Copilot generates a full project — agent logic, tool definitions, system prompts, and evaluation tests. It uses the microsoft-foundry skill, the same open-source skill powering GitHub Copilot for Azure. AI Toolkit installs and keeps this skill updated automatically — you never configure it. The output is structured and production-ready. Real folder structure. Real separation of concerns. Not a single-file script. Either way, you get a project you can version-control, test, and deploy. Cool Features You Should Know About Building the agent is just the beginning. Here's where AI Toolkit gets genuinely impressive. 🔧 Add Real Tools with MCP Your agent can do more than just talk. Click Add Tool in Agent Builder to connect MCP (Model Context Protocol) servers — these give your agent real capabilities: Search the web Query a database Read files Call external APIs Interact with any service that has an MCP server You control how much freedom your agent gets. Set tool approval to Auto (tool runs immediately) or Manual (you approve each call). Perfect for when you trust a read-only search tool but want oversight on anything that takes action. You can also delete MCP servers directly from the Tool Catalog when you no longer need them — no config file editing required. 🧠 Prompt Optimizer Not sure if your instructions are good enough? Click the Improve button in Agent Builder. The Foundry Prompt Optimizer analyzes your prompt and rewrites it to be clearer, more structured, and more effective. It's like having a prompt engineering expert review your work — except it takes seconds. 🕸️ Agent Inspector When your agent runs, open Agent Inspector to see what's happening under the hood. It visualizes the entire workflow in real time — which tools are called, in what order, and how the agent makes decisions. 💬 Conversations View Agent Builder includes a Conversations tab where you can review the full history of interactions with your agent. Scroll through past conversations, compare how your agent handled different scenarios, and spot patterns in where it succeeds or struggles. 📁 Everything in One Sidebar AI Toolkit puts everything in a single My Resources panel: Recent Agents — one-click access to agents you've been working on Local Resources — your local models, agents, and tools Foundry Resources — remote agents and models (if connected) Why AI Toolkit? There are other ways to build agents. What makes this different? Everything is in VS Code. You don't context-switch between a web UI, a CLI, and an IDE. Discovery, building, testing, debugging, and deployment all happen in one place. No-code and code-first aren't separate products. They're two views of the same agent. Start in Agent Builder, click View Code, and you have a full project. Or go the other way — build in code and test in the visual playground. Copilot is deeply integrated. Not as a chatbot bolted on the side — as an actual development tool that understands agent architecture and generates production-quality scaffolding. Wrapping Up: 📥 Install: AI Toolkit on the VS Code Marketplace 📖 Learn: AI Toolkit Documentation Open VS Code. Ctrl+Shift+P. Type "Create Agent." Five minutes from now, you'll have an agent running. 🚀5.5KViews7likes3CommentsAnnouncing Microsoft Azure Network Adapter (MANA) support for Existing VM SKUs
As a leader in cloud infrastructure, Microsoft ensures that Azure’s IaaS customers always have access to the latest hardware. Our goal is to consistently deliver technology to support business critical workloads with world class efficiency, reliability, and security. Customers benefit from cutting-edge performance enhancements and features, helping them to future proof their workloads while maintaining business continuity. Azure will be a deploying new hardware generation to support capacity demands for existing VM Size Families. The hardware is optimized for these VM sizes, utilizing Intel’s Emerald Rapid CPU, native NVMe SSD support for higher storage bandwidth and lower latency, and Microsoft Azure Network Adapter (MANA). Deployment timelines will be communicated via Service Health Advisory updates. The intent is to provide the benefits of new server hardware to customers of existing VM SKUs as they work towards migrating to newer SKUs. The deployments will be based on capacity needs and won’t be restricted by region. Once the hardware is available in a region, VMs can be deployed to it as needed. Workloads on operating systems which fully support MANA will benefit from sub-second Network Interface Card (NIC) firmware upgrades, higher throughput, lower latency, increased Security and Azure Boost-enabled data path accelerations. If your workload doesn't support MANA today, you'll still be able to access Azure’s network on MANA enabled SKUs, but performance will be comparable to previous generation (non-MANA) hardware. Check out the Azure Boost Overview and the Microsoft Azure Network Adapter (MANA) overview for more detailed information and OS compatibility. To determine whether your VMs are impacted and what actions (if any) you should take, start with MANA support for existing VM SKUs. This article provides additional information about which VM Sizes are eligible to be deployed on the new MANA-enabled hardware, what actions (if any) you should take, and how to determine if the workload has been deployed on MANA-enabled hardware.20KViews10likes8CommentsKubernetes Center: Security & LTS/Out-of-Support Version Insights Now Available
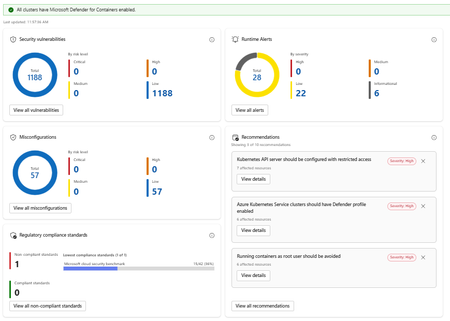
What's New Security Insights: The new Security page in Kubernetes Center gives you an immediate, all clusters or Kubernetes Fleet Manager-wide view of your security posture without leaving the portal. At the summary level you can see: Security vulnerabilities broken down by risk level Runtime alerts categorized by severity Non-compliant regulatory standards, with visibility into which benchmarks your clusters are falling short on Drilling deeper into the security detail view exposes four distinct panels: Security Vulnerabilities show a total count of vulnerabilities across all clusters, broken down by risk tier. Runtime Alerts surfaces live alerts from Defender for Containers categorized by High, Medium, Low, and Informational severity. You can see at a glance whether any active threats require immediate attention, and drill into the full alert list with one click. Misconfigurations show a count of configuration issues detected across your clusters, again broken down by risk level. Regulatory Compliance Standards lets you see which compliance standards your clusters are enrolled in, which are passing, and which are failing. The view surfaces the lowest-performing standard with its pass rate, so you know exactly where to focus remediation effort. Recommendations are shown alongside these panels, providing actionable and prioritized guidance. Each recommendation shows affected resource counts and links directly to remediation details. Note: Security insights require Microsoft Defender for Containers to be enabled. Kubernetes Center will confirm at a glance whether all your clusters have it enabled. Cluster Version Support Status: Stay Ahead of End-of-Support Running an out-of-support Kubernetes version is one of the most common and preventable sources of risk in production environments. The new Cluster Version Support Status panel in Kubernetes Center gives you a clear picture of where every cluster stands. The view breaks your clusters down into four states: Status What it means In support Running a supported Kubernetes version. No action needed. Expiring soon Version support is ending soon. Plan your upgrade. Out of support (LTS eligible) Out of support but eligible for Long Term Support. An easy path to extend coverage. Out of support No longer supported and not LTS eligible. Upgrade required. You can filter the view by cluster tier (Premium, Standard, or Free) to understand exposure by tier and prioritize accordingly. For clusters that are out of support but LTS eligible, a single Enable LTS for Eligible Clusters button lets you act immediately without navigating away. Kubernetes Center brings this into a single, always-on view so platform teams can: Catch version drift before it becomes an incident Spot misconfiguration patterns across clusters, not just within one Act on recommendations without switching tools Report on compliance posture without manual aggregation Try It Out These features are available now in Kubernetes Center in the Azure portal. → Open Security -Kubernetes Center in the Azure portal We'd love to hear what you think. Try the new security and version views with your clusters and share your feedback directly through the portal using the feedback button. FAQ Do I need Microsoft Defender for Containers enabled to use the security features? Yes. Security vulnerabilities, runtime alerts, and misconfiguration data are powered by MS Defender for Containers. Kubernetes Center will show you if any clusters don't have it enabled so you can quickly close that gap. Does this work across all my subscriptions and clusters? Kubernetes Center aggregates data across all AKS clusters you have access to. Make sure you have the appropriate RBAC permissions across the subscriptions you want visibility into. What is LTS and should I enable it for eligible clusters? Long Term Support (LTS) extends the supported lifecycle of a Kubernetes version beyond its standard window. It's available for clusters on eligible versions running the Premium tier. If you have clusters showing "Out of support, LTS eligible," enabling LTS is the fastest way to restore support coverage while you plan a full version upgrade. Is there a cost to use Kubernetes Center? Kubernetes Center itself is part of the Azure portal experience and there is no additional charge. Note that Microsoft Defender for Containers, which powers the security features, is a paid add-on. See the Defender for Containers pricing page for details. Where can I learn more about the Kubernetes version lifecycle? See the AKS Kubernetes version support policy documentation for full details on version support windows, LTS eligibility, and upgrade guidance.704Views1like0CommentsBuilding Secure AI Platforms in Banking Using Azure Enterprise Architecture
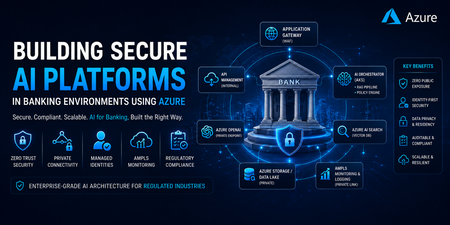
1. Introduction: AI in Banking Is Not Just a Model Problem Modern banking institutions are no longer asking “Can we use AI?” The real question is: “Can we use AI without violating regulatory, security, and data residency constraints?” Unlike public AI applications, banking systems must ensure: No public internet exposure Strict identity-based access control End-to-end auditability Data residency compliance Fully controlled inference pipelines 👉 In enterprise environments, AI success is driven by secure infrastructure—not just model accuracy. 2. Core Design Principle: Controlled Intelligence System Every AI request must follow a security-enforced execution pipeline: User Request ↓ Secure Edge (Application Gateway + WAF) ↓ API Governance Layer (API Management - Internal Mode) ↓ AI Orchestration Layer (AKS / App Services) ↓ Retrieval + Policy Layer (RAG + Guardrails) ↓ Private AI Services (Azure OpenAI) ↓ Observability Layer (AMPLS) ↓ Final Response Key Insight: This is not just an architecture—it is a controlled and auditable execution model. 3. Azure Enterprise AI Architecture (Production-Ready Pattern) A real-world architecture used in banking environments: 4. Private Connectivity Model (Critical for Compliance) Key components: Private Endpoints → Secure PaaS isolation Private DNS Zones → Controlled name resolution VNet Integration → Internal service communication Azure Firewall → Traffic inspection and control ⚠️ Common Production Failure: AKS pods fail to resolve Azure OpenAI private endpoint Root cause: Missing Private DNS links Incorrect VNet configuration 👉 This is one of the most frequent failures in enterprise AI deployments. “Debugging Private Endpoint Failures” Include: nslookup behavior in AKS DNS zone linking check VNet integration validation UDR / Firewall inspection 5. Identity-First Security Model (No Secrets Architecture) Modern banking architectures eliminate static credentials entirely. Authentication Flow: AKS Workload → Managed Identity → Azure AD → Azure Services Key Principle: 👉 Identity is the new security perimeter. Benefits: No API keys or secrets Simplified access management RBAC-based governance Fully auditable access 6. Secure AI Inference Pipeline A production AI request flow: def process_request(user_request): # 1. Authenticate user via Azure AD identity = authenticate_aad(user_request.token) if not identity or not identity.is_valid: return "ACCESS_DENIED" # 2. Enforce rate limiting per identity if not rate_limit(identity): return "RATE_LIMIT_EXCEEDED" # 3. Apply prompt security guardrails (injection protection) safe_prompt = apply_prompt_guardrails(user_request.prompt) # 4. Content safety filtering (PII / harmful content detection) if not content_filter(safe_prompt): return "CONTENT_BLOCKED" # 5. Retrieve secure RAG context context = retrieve_rag_context( query=safe_prompt, secure_mode=True ) # 6. Build final prompt final_prompt = merge_prompt_and_context(safe_prompt, context) # 7. Call Azure OpenAI with circuit breaker protection response = circuit_breaker( lambda: call_openai( prompt=final_prompt, identity=ManagedIdentity() ) ) # 8. Validate and sanitize model output validated_output = sanitize(response) # 9. Log everything for audit + compliance (AMPLS / SIEM) log_to_ampls( identity=identity, request=user_request, response=validated_output ) return validated_output Security controls include: Prompt injection filtering Context grounding (RAG) Output sanitization Full audit logging 7. RAG Architecture: Enterprise AI Backbone User Query → Embedding Model → Azure AI Search (Vector Store) → Context Retrieval → Azure OpenAI → Final Response Why RAG is preferred in banking: No model retraining required Controlled data exposure Easier compliance validation Real-time knowledge updates In banking systems, retrieval is not just about relevance—it is about controlled disclosure of sensitive context 8. Observability with AMPLS (A Critical Yet Overlooked Layer) AI telemetry flows through: Azure Services → Private Link → AMPLS → Log Analytics / App Insights Why this matters: Logs may contain: Sensitive financial data PII Prompt inputs 👉 AMPLS ensures telemetry remains private and compliant. 9. Regulatory Mapping: Banking Requirements to Azure Capabilities Requirement Azure Implementation No public exposure Private Endpoints Identity-based security Azure AD + Managed Identity Audit compliance Log Analytics + AMPLS Data protection Customer-Managed Keys (CMK) Network isolation VNet + Firewall Access governance RBAC + PIM 10. Real-World Production Challenges Common failure points in enterprise AI systems: DNS Misconfiguration – Private endpoints fail resolution Latency Chains – Excessive service hops OpenAI Rate Limits – High enterprise load Identity Propagation Issues – Cross-subscription failures Observability Gaps – Missing distributed tracing 11. Enterprise Architecture Best Practices Design with zero-trust principles Treat AI as a distributed system, not a single component Centralize governance using API Management Never expose AI services publicly Use identity everywhere—no secrets Separate: Control Plane (governance) Data Plane (inference execution) 12. Azure Service Mapping (Quick Reference) Layer Azure Services Edge Security Application Gateway (WAF) API Layer API Management Compute AKS / App Services AI Services Azure OpenAI Retrieval Azure AI Search Data Azure Storage / SQL Identity Azure AD + Managed Identity Networking Private Link + VNet Observability AMPLS + Log Analytics 13. Common Failure Patterns Issue Root Cause AI endpoint unreachable DNS / Private endpoint misconfig Data leakage risk Missing prompt filtering High latency Over-layered architecture Unauthorized access Identity misconfiguration Poor response quality Weak RAG implementation 14. Final Thought In enterprise banking AI systems: Models are replaceable. Architecture is not. The real challenge is designing a system where AI is: Secure Controlled Observable Fully compliant707Views0likes0Comments
Deploying Azure Redis Enterprise with Geo-Replication Using Terraform
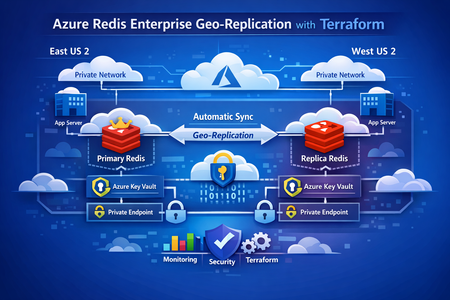
This post walks through a production‑proven pattern for running stateful services across Azure regions using Terraform. We’ll cover a primary–replica Redis architecture, regional isolation with Key Vault and networking, and a clean Terraform parameterization strategy that scales from development to production without duplication. Why Multi‑Region State Is Hard Running applications globally is easy when everything is stateless—if something fails, you redeploy. But stateful services tell a different story. Caches, message brokers, and data stores can’t be treated as disposable. They hold business‑critical data, and downtime or inconsistency quickly becomes customer‑visible. In real‑world systems, common requirements include: Low‑latency reads from multiple regions Automatic recovery when a region becomes unavailable Predictable data consistency Repeatable infrastructure from dev through production Manually configuring this per region doesn’t scale. Drift sets in. Failover is unclear. Backups get forgotten. That’s where Terraform + Azure Managed Redis geo‑replication shines. Github Link : https://github.com/vsakash5/Managed-redis.git High‑Level Architecture We use a primary–replica Redis Enterprise model: Primary Redis Single write endpoint Highly available inside its region Source of truth Replica Redis Read‑only Asynchronously synced from primary Can be promoted during disaster recovery Each region is fully isolated: Separate subnets Separate Key Vaults Private Endpoints only (no public exposure) This prevents shared failure domains and allows each region to operate independently if needed. The Terraform Design Principle Instead of maintaining separate Terraform stacks per region, the key idea is: One reusable module, one tfvars file per environment, multiple regions inside it. The module is written once. Regional differences are supplied via parameter suffixes like: _replica _secondary _tertiary This keeps logic centralized and environments consistent. Core Parameter Layers 1. Environment Identity (Shared) Terraform environment = "dev" # dev | staging | prod context_prefix = "app" Show more lines These values are reused everywhere—names, tags, and identifiers. 2. Primary Region Terraform location = "eastus2" resource_group_name = "rg-app-dev-primary" Show more lines 3. Replica Region Terraform location_replica = "uksouth" resource_group_name_replica = "rg-app-dev-replica" The symmetry is intentional. Terraform can now apply the same module twice without branching logic. Regional Isolation: Networking and Secrets Why isolation matters Geo‑replication copies data, not dependencies. If both Redis instances depend on: the same subnet the same Key Vault then a failure in one region can cascade into the other. Networking (One Subnet per Region) Benefits: Independent NSGs Independent routing Independent capacity planning Key Vault (One per Region) Why this matters: Redis credentials are not replicated Each region stores its own secrets A Key Vault outage doesn’t take both regions down Redis Configuration Primary Redis (Writes Enabled) The geo‑replication group name must match. That’s the logical binding Azure uses to link instances. Private Endpoint‑Only Access No Redis instance is exposed publicly. Each region uses: A private endpoint A workload subnet Internal DNS resolution This means: No public IPs No inbound attack surface Traffic stays on the Azure backbone Linking Primary and Replica Terraform explicitly defines the relationship: Terraform managed_redis_geo_replication_config = { primary_to_replica = { primary_redis_key = "primary" replica_keys = ["replica"] } } Terraform ensures: Primary is created first Replica is deployed second Geo‑replication is established last Environment Scaling: Dev → Staging → Prod The infrastructure pattern never changes. Only values do. Environment Group Name Dev dev-grp Staging stg-grp Prod prod-grp This is how you avoid “snowflake” environments. Disaster Recovery Strategy If the primary region fails: Applications fail over to the replica read endpoint Terraform configuration is updated to: Remove geo‑replication Promote replica config to primary Traffic is fully restored Once the original region recovers, roles can be re‑established cleanly. No click‑ops. No guesswork. Key Lessons Learned 1. Naming is Infrastructure Predictable names enable automation, discovery, and auditing. 2. Key Vault Isolation Beats Availability A shared Key Vault is a shared outage. 3. Parameterization Beats Copy‑Paste Fix once → benefit everywhere. 4. Geo‑Replication Is a Contract Matching replication group names is non‑negotiable. 5. The tfvars File Is the Source of Truth If it’s not in Terraform, it’s not real. Final Thoughts Running stateful services in multiple regions doesn’t require magic— it requires discipline: Isolate aggressively Parameterize consistently Automate everything Test failure often With this approach, adding a new region becomes configuration—not redesign. That’s how infrastructure scales.305Views1like0Comments
Guardrails for Generative AI: Securing Developer Workflows
Generative AI is revolutionizing software development that accelerates delivery but introduces compliance and security risks if unchecked. Tools like GitHub Copilot empower developers to write code faster, automate repetitive tasks, and even generate tests and documentation. But speed without safeguards introduces risk. Unchecked AI‑assisted development can lead to security vulnerabilities, data leakage, compliance violations, and ethical concerns. In regulated or enterprise environments, this risk multiplies rapidly as AI scales across teams. The solution? Guardrails—a structured approach to ensure AI-assisted development remains secure, responsible, and enterprise-ready. In this blog, we explore how to embed responsible AI guardrails directly into developer workflows using: Azure AI Content Safety GitHub Copilot enterprise controls Copilot Studio governance Azure AI Foundry CI/CD and ALM integration The goal: maximize developer productivity without compromising trust, security, or compliance. Key Points: Why Guardrails Matter: AI-generated code may include insecure patterns or violate organizational policies. Azure AI Content Safety: Provides APIs to detect harmful or sensitive content in prompts and outputs, ensuring compliance with ethical and legal standards. Copilot Studio Governance: Enables environment strategies, Data Loss Prevention (DLP), and role-based access to control how AI agents interact with enterprise data. Azure AI Foundry: Acts as the control plane for Generative AI turning Responsible AI from policy into operational reality. Integration with GitHub Workflows: Guardrails can be enforced in IDE, Copilot Chat, and CI/CD pipelines using GitHub Actions for automated checks. Outcome: Developers maintain productivity while ensuring secure, compliant, and auditable AI-assisted development. Why Guardrails Are Non-Negotiable AI‑generated code and prompts can unintentionally introduce: Security flaws — injection vulnerabilities, unsafe defaults, insecure patterns Compliance risks — exposure of PII, secrets, or regulated data Policy violations — copyrighted content, restricted logic, or non‑compliant libraries Harmful or biased outputs — especially in user‑facing or regulated scenarios Without guardrails, organizations risk shipping insecure code, violating governance policies, and losing customer trust. Guardrails enable teams to move fast—without breaking trust. The Three Pillars of AI Guardrails Enterprise‑grade AI guardrails operate across three core layers of the developer experience. These pillars are centrally governed and enforced through Azure AI Foundry, which provides lifecycle, evaluation, and observability controls across all three. 1. GitHub Copilot Controls (Developer‑First Safety) GitHub Copilot goes beyond autocomplete and includes built‑in safety mechanisms designed for enterprise use: Duplicate Detection: Filters code that closely matches public repositories. Custom Instructions: Enhance coding standards via .github/copilot-instructions.md. Copilot Chat: Provides contextual help for debugging and secure coding practices. Pro Tip: Use Copilot Enterprise controls to enforce consistent policies across repositories and teams. 2. Azure AI Content Safety (Prompt & Output Protection) This service adds a critical protection layer across prompts and AI outputs: Prompt Injection Detection: Blocks malicious attempts to override instructions or manipulate model behaviour. Groundedness Checks: Ensures outputs align with trusted sources and expected context. Protected Material Detection: Flags copyrighted or sensitive content. Custom Categories: Tailor filters for industry-specific or regulatory requirements. Example: A financial services app can block outputs containing PII or regulatory violations using custom safety categories. 3. Copilot Studio Governance (Enterprise‑Scale Control) For organizations building custom copilots, governance is non‑negotiable. Copilot Studio enables: Data Loss Prevention (DLP): Prevent sensitive data leaks from flowing through risky connectors or channels. Role-Based Access (RBAC): Control who can create, test, approve, deploy and publish copilots. Environment Strategy: Separate dev, test, and production environments. Testing Kits: Validate prompts, responses, and behavior before production rollout. Why it matters: Governance ensures copilots scale safely across teams and geographies without compromising compliance. Azure AI Foundry: The Platform That Operationalizes the Three Pillars While the three pillars define where guardrails are applied, Azure AI Foundry defines how they are governed, evaluated, and enforced at scale. Azure AI Foundry acts as the control plane for Generative AI—turning Responsible AI from policy into operational reality. What Azure AI Foundry Adds Centralized Guardrail Enforcement: Define guardrails once and apply them consistently across: Models, Agents, Tool calls and Outputs. Guardrails specify: Risk types (PII, prompt injection, protected material) Intervention points (input, tool call, tool response, output) Enforcement actions (annotate or block) Built‑In Evaluation & Red‑Teaming: Azure AI Foundry embeds continuous evaluation into the GenAIOps lifecycle: Pre‑deployment testing for safety, groundedness, and task adherence Adversarial testing to detect jailbreaks and misuse Post‑deployment monitoring using built‑in and custom evaluators Guardrails are measured and validated, not assumed. Observability & Auditability: Foundry integrates with Azure Monitor and Application Insights to provide: Token usage and cost visibility Latency and error tracking Safety and quality signals Trace‑level debugging for agent actions Every interaction is logged, traceable, and auditable—supporting compliance reviews and incident investigations. Identity‑First Security for AI Agents: Each AI agent operates as a first‑class identity backed by Microsoft Entra ID: No secrets embedded in prompts or code Least‑privilege access via Azure RBAC Full auditability and revocation Policy‑Driven Platform Governance: Azure AI Foundry aligns with the Azure Cloud Adoption Framework, enabling: Azure Policy enforcement for approved models and regions Cost and quota controls Integration with Microsoft Purview for compliance tracking How to Implement Guardrails in Developer Workflows Shift-Left Security Embed guardrails directly into the IDE using GitHub Copilot and Azure AI Content Safety APIs—catch issues early, when they’re cheapest to fix. Automate Compliance in CI/CD Integrate automated checks into GitHub Actions to enforce policies at pull‑request and build stages. Monitor Continuously Use Azure AI Foundry and governance dashboards to track usage, violations, and policy drift. Educate Developers Conduct readiness sessions and share best practices so developers understand why guardrails exist—not just how they’re enforced. Implementing DLP Policies in Copilot Studio Access Power Platform Admin Center Navigate to Power Platform Admin Centre Ensure you have Tenant Admin or Environment Admin role Create a DLP Policy Go to Data Policies → New Policy. Define data groups: Business (trusted connectors) Non-business Blocked (e.g., HTTP, social channels) Configure Enforcement for Copilot Studio Enable DLP enforcement for copilots using PowerShell Set-PowerVirtualAgentsDlpEnforcement ` -TenantId <tenant-id> ` -Mode Enabled Modes: Disabled (default, no enforcement) SoftEnabled (blocks updates) Enabled (full enforcement) Apply Policy to Environments Choose scope: All environments, specific environments, or exclude certain environments. Block channels (e.g., Direct Line, Teams, Omnichannel) and connectors that pose risk. Validate & Monitor Use Microsoft Purview audit logs for compliance tracking. Configure user-friendly DLP error messages with admin contact and “Learn More” links for makers. Implementing ALM Workflows in Copilot Studio Environment Strategy Use Managed Environments for structured development. Separate Dev, Test, and Prod clearly. Assign roles for makers and approvers. Application Lifecycle Management (ALM) Configure solution-aware agents for packaging and deployment. Use Power Platform pipelines for automated movement across environments. Govern Publishing Require admin approval before publishing copilots to organizational catalog. Enforce role-based access and connector governance. Integrate Compliance Controls Apply Microsoft Purview sensitivity labels and enforce retention policies. Monitor telemetry and usage analytics for policy alignment. Key Takeaways Guardrails are essential for safe, compliant AI‑assisted development. Combine GitHub Copilot productivity with Azure AI Content Safety for robust protection. Govern agents and data using Copilot Studio. Azure AI Foundry operationalizes Responsible AI across the full GenAIOps lifecycle. Responsible AI is not a blocker—it’s an enabler of scale, trust, and long‑term innovation.2.8KViews0likes0Comments