stored procedures
3 Topics
Need help for building a storeprocedure
Hi all, Urgent help is required. There are two pages now in my application. One is buildingblock page and another is volume page. Now in the buildingblock page I am choosing building blocks(Origin/destination type). Under each BB there are locations which are called as OriginCX/Destination Cx based on which BB type it is. I am making all possible pairs of them like origin - destination combinations and then in volume page I am displaying them as records in a grid with some other input fields. Example scenarios which are NOT passing now- Consider choosing 1 OriginCx and 1destinationCx of each BB type and they are the same location then after going to Volume page we can find a single record. When we are saving the record data and coming back to BB page then if we are deselecting either one location and saving data in BB page. Then moving forward no alert is being shown that location has been modified Another scenario which is also failing now is - If I am choosing a single BB location maybe as origin/destination and saving in BB page and moving forward to volume then we can find a dropdown with all available cities location to choose. Here if I am choosing any city and saving the data then alert is coming as Location has been modified. This condition no alert should come. This is all of my business logic500Views0likes1CommentThe Pipeline Is Slow, or Is SQL Waiting? Diagnosing Synapse-to-Azure SQL Regressions
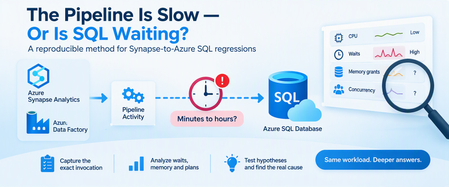
A query can consume very little CPU and still keep a pipeline waiting for hours. A pipeline activity that normally finishes in minutes suddenly starts taking hours. Nothing obvious has changed: The pipeline definition looks the same. The stored procedure looks the same. Azure SQL Database isn't showing sustained high CPU. Pipeline monitoring still points toward the SQL activity. At this point, saying "SQL is slow" isn't enough. The request may actually be: Executing expensive work. Waiting for memory. Blocked by another transaction. Reading more data than before. Running with a different execution plan. Competing with concurrent pipeline activities. Experiencing different cardinality because of different parameter values. The key is to connect the pipeline invocation to the database execution and determine where elapsed time is really going. 1. Define the Regression Precisely Before troubleshooting SQL, establish what actually changed. Capture: Expected pipeline duration. Observed pipeline duration. Pipeline activity involved. Stored procedure or statement invoked. Exact parameter values. Affected and unaffected executions. Pipeline concurrency. Retry behavior. Connection and command timeout. Deployment or configuration changes. For example: Evidence Baseline Regression Pipeline duration Minutes Much longer Stored procedure Same Same Parameter range A B Concurrent activities Low Higher Azure SQL CPU Normal Normal/moderate SQL wait behavior Unknown To investigate The most important rule is: Don't assume the SQL workload is identical simply because the stored procedure is identical. Different parameters can result in dramatically different: Row counts. Join choices. Memory grants. Sort requirements. Execution plans. Total duration. 2. Preserve the Exact Invocation One of the easiest ways to lose a performance regression is to reproduce it with different parameters. Capture the invocation before testing: Procedure name. Parameter values. Date range. Entity or partition identifier. Batch size. Pipeline run ID. Retry number. Number of parallel activities. Relevant timeout configuration. Then sanitize any business-sensitive values before sharing them outside your organization. The diagnostic principle is simple: Reproduce the same workload before trying to improve the workload. 3. Reproduce Safely Whenever possible, reproduce the issue using: A nonproduction database containing representative data. A controlled production troubleshooting window. The same stored procedure. The same parameter pattern. Comparable concurrency. For a controlled test, SQL execution statistics can help: SET STATISTICS IO ON; SET STATISTICS TIME ON; EXEC dbo.SampleProcedure @StartDate = '2026-01-01', @EndDate = '2026-01-31', @EntityID = 100; SET STATISTICS TIME OFF; SET STATISTICS IO OFF; Replace these synthetic names and values with the sanitized equivalent of the invocation you're investigating. Capture: Elapsed time. CPU time. Logical reads. Physical reads when relevant. Execution plan. Returned row count. The goal isn't simply to reproduce "slow." The goal is to understand why it is slow. 4. First Question: Is SQL Running or Waiting? This distinction changes the entire investigation. During the slow execution, examine the active request. SELECT r.session_id, r.request_id, r.status, r.command, r.start_time, r.cpu_time, r.total_elapsed_time, r.wait_type, r.wait_time, r.last_wait_type, r.wait_resource, r.blocking_session_id, r.reads, r.writes, r.logical_reads, r.row_count FROM sys.dm_exec_requests AS r WHERE r.database_id = DB_ID() ORDER BY r.total_elapsed_time DESC; sys.dm_exec_requests is supported for Azure SQL Database and exposes information about currently executing requests. Pay particular attention to the relationship between: cpu_time and: total_elapsed_time Suppose a request has: Very high elapsed time. Relatively little accumulated CPU time. A significant current wait. That's a strong reason to investigate waiting, rather than immediately treating the problem as insufficient CPU. Conversely: High elapsed time. High accumulated CPU. High logical reads. points more strongly toward expensive execution. 5. Identify Blocking Another request may be preventing the pipeline's SQL request from progressing. Start with: SELECT session_id, status, wait_type, wait_time, wait_resource, blocking_session_id, cpu_time, total_elapsed_time FROM sys.dm_exec_requests WHERE blocking_session_id <> 0 ORDER BY wait_time DESC; Blocking can explain a scenario where: Pipeline duration increases dramatically. Database CPU remains moderate. The SQL activity appears "active" for a long time. Microsoft documents sys.dm_exec_requests as one of the tools for identifying requests suspended on lock-related waits and tracing blocking behavior in Azure SQL Database. Don't confuse: "The SQL call took two hours." with: "SQL executed for two hours." Those statements aren't necessarily equivalent. 6. Look at the SQL That's Actually Running During an active incident, retrieve the request and its current SQL text: SELECT r.session_id, r.status, r.command, r.cpu_time, r.total_elapsed_time, r.wait_type, r.blocking_session_id, r.logical_reads, txt.text AS batch_text FROM sys.dm_exec_requests AS r CROSS APPLY sys.dm_exec_sql_text(r.sql_handle) AS txt WHERE r.database_id = DB_ID() ORDER BY r.total_elapsed_time DESC; sys.dm_exec_sql_text accepts the sql_handle exposed by sys.dm_exec_requests and returns the associated SQL batch text. This helps validate an important cross-service question: Is the database executing the statement we think the pipeline invoked? 7. Investigate Memory Grants Some operations need execution memory before they can proceed efficiently. Common examples include: Sorts. Hash joins. Hash aggregates. Some index operations. sys.dm_exec_query_memory_grants exposes queries that: Requested a memory grant and received one. Requested a memory grant and are still waiting. It is supported for Azure SQL Database. SELECT mg.session_id, mg.request_id, mg.dop, mg.request_time, mg.grant_time, mg.requested_memory_kb, mg.granted_memory_kb, mg.required_memory_kb, mg.used_memory_kb, mg.max_used_memory_kb, mg.query_cost, mg.timeout_sec, mg.resource_semaphore_id FROM sys.dm_exec_query_memory_grants AS mg ORDER BY mg.requested_memory_kb DESC; Interpret the important columns carefully: requested_memory_kb Memory requested by the query. granted_memory_kb Memory actually granted. required_memory_kb Minimum memory required for execution. used_memory_kb Memory currently being used. max_used_memory_kb Maximum used so far. grant_time NULL when the requested grant hasn't yet been granted. Microsoft specifically documents that queries waiting for memory grants appear in this DMV, and that grant_time remains NULL until the grant is provided. 8. Find Waiting Memory Grants During the active regression, focus specifically on requests that haven't received their grants: SELECT mg.session_id, mg.request_id, mg.request_time, mg.grant_time, mg.requested_memory_kb, mg.required_memory_kb, mg.granted_memory_kb, mg.timeout_sec, mg.dop, mg.query_cost FROM sys.dm_exec_query_memory_grants AS mg WHERE mg.grant_time IS NULL ORDER BY mg.request_time; If the affected session repeatedly appears here, you now have meaningful evidence supporting a memory-grant contention hypothesis. But that's still not enough to state: "Memory grants caused the pipeline regression." You should also establish: Whether the waiting session is actually the pipeline request. How long it remained waiting. Whether other statements were consuming large grants. Whether concurrency changed. Whether the execution plan requested unusually large memory. Why the query requested that amount of memory. That last question is particularly important. Memory-grant problems can be downstream symptoms of: Poor cardinality estimates. Large sorts. Large hash joins. Plan changes. Data growth. Parameter sensitivity. Microsoft's memory-grant troubleshooting guidance emphasizes that operations such as sorts and hash operations can require execution-memory reservations and that these grants exist for the lifetime of the query. Memory-grant contention is a diagnostic hypothesis until the evidence supports causality. 9. Pipeline Concurrency Is Database Concurrency This connection is easy to overlook. Suppose one stored-procedure invocation performs acceptably. Now imagine the orchestration layer starts: 2 copies concurrently. 5 copies concurrently. 10 copies concurrently. 20 copies concurrently. Each execution may individually be reasonable. Together, they can compete for: CPU. Workers. Memory grants. Buffer pool resources. I/O. Locks. This means: A pipeline concurrency change is also a database workload change. Even when: SQL code hasn't changed. Database configuration hasn't changed. Stored procedure code hasn't changed. As part of troubleshooting, compare: Single-execution performance. Typical production concurrency. Regression-period concurrency. Temporarily reducing pipeline concurrency can also be a valuable diagnostic experiment, provided the change is safe for the workload. 10. Capture the Live Execution Plan For a request that's still executing, Azure SQL Database supports sys.dm_exec_query_statistics_xml(), which returns Showplan XML containing transient execution statistics for an in-flight request. First identify the target session: SELECT session_id, request_id, status, command, cpu_time, total_elapsed_time, wait_type, logical_reads FROM sys.dm_exec_requests WHERE database_id = DB_ID() ORDER BY total_elapsed_time DESC; Then, for a known session: DECLARE @SessionID smallint = 123; SELECT qsx.session_id, qsx.request_id, qsx.query_plan FROM sys.dm_exec_query_statistics_xml(@SessionID) AS qsx; Replace 123 with the session being investigated. The live plan can help answer: Which operator is consuming time? How many rows are flowing through operators? Are estimates diverging significantly from runtime behavior? Are large joins or sorts involved? Where does execution appear to be spending time? Microsoft describes access to execution-plan runtime information as particularly useful when investigating long-running queries, because the information can be inspected without waiting for the query to finish. Use live-plan collection purposefully, especially on heavily loaded production systems. 11. Compare Historical Behavior in Query Store A live snapshot explains what's happening now. Query Store helps answer: What was happening when the query used to be fast? For example, find queries with multiple retained Query Store plans: SELECT TOP (50) q.query_id, COUNT(DISTINCT p.plan_id) AS plan_count, COUNT(DISTINCT p.query_plan_hash) AS distinct_plan_shapes, MIN(p.first_execution_time) AS first_plan_execution, MAX(p.last_execution_time) AS last_plan_execution FROM sys.query_store_query AS q JOIN sys.query_store_plan AS p ON q.query_id = p.query_id GROUP BY q.query_id HAVING COUNT(DISTINCT p.plan_id) > 1 ORDER BY plan_count DESC; Multiple plans aren't automatically evidence of a problem. Instead, investigate whether plan changes correlate with: Pipeline regressions. Duration changes. CPU changes. Logical-read changes. Memory behavior. Different parameter populations. 12. Compare Runtime Distributions, Not Just Averages Averages can hide regression patterns. Consider: Most executions take 10 seconds. A few take 45 minutes. The average won't fully describe the operational impact. For a known Query Store query_id, compare plans and runtime intervals: DECLARE @QueryID bigint = 123; SELECT p.plan_id, rsi.start_time, rsi.end_time, SUM(rs.count_executions) AS execution_count, CAST(AVG(rs.avg_duration) / 1000.0 AS decimal(18,2)) AS avg_duration_ms, CAST(MAX(rs.max_duration) / 1000.0 AS decimal(18,2)) AS max_duration_ms, CAST(AVG(rs.avg_cpu_time) / 1000.0 AS decimal(18,2)) AS avg_cpu_ms, CAST(AVG(rs.avg_logical_io_reads) AS decimal(18,2)) AS avg_logical_reads FROM sys.query_store_query AS q JOIN sys.query_store_plan AS p ON q.query_id = p.query_id JOIN sys.query_store_runtime_stats AS rs ON p.plan_id = rs.plan_id JOIN sys.query_store_runtime_stats_interval AS rsi ON rs.runtime_stats_interval_id = rsi.runtime_stats_interval_id WHERE q.query_id = @QueryID GROUP BY p.plan_id, rsi.start_time, rsi.end_time ORDER BY rsi.start_time DESC, p.plan_id; Replace 123 with the Query Store ID being investigated. Compare: Fast periods. Slow periods. Plans. Execution counts. CPU. Duration. Logical reads. This often produces a better picture than looking at lifetime averages. 13. Don't Force the Fastest Historical Plan Yet Suppose Query Store shows: Plan A took 30 seconds. Plan B takes 20 minutes. It might be tempting to immediately force Plan A. But first ask: How many times did Plan A execute? Which parameters used Plan A? Was the data distribution comparable? Was workload concurrency comparable? Did Plan A perform well repeatedly? Is the query parameter sensitive? A plan that was excellent for one parameter combination might be disastrous for another. The goal isn't to find the lowest historical duration. The goal is to find the plan behavior that's safe for the intended workload. If plan forcing is tested, define rollback criteria before deployment. 14. Test One Hypothesis at a Time Avoid simultaneously changing: Statistics. Indexes. Query code. Pipeline concurrency. Plan forcing. Compute tier. Doing everything together may improve performance, but you'll learn very little about why. Instead: Hypothesis: stale or inaccurate statistics Test: Appropriate statistics maintenance. Same parameters. Same concurrency. Then measure again. Hypothesis: memory-grant contention Test safely with: Reduced concurrency. Same parameter set. Same procedure. Same database configuration. Then compare: Grant wait behavior. Elapsed time. CPU time. Query plan. Hypothesis: plan regression Compare: Historical plans. Representative parameters. Runtime distributions. Only then evaluate targeted plan intervention. Hypothesis: poor cardinality Look for: Estimate-to-actual row differences. Parameter sensitivity. Implicit conversions. Sort/hash behavior. Excessive memory requests. This approach turns troubleshooting from guesswork into experimentation. 15. Correlation Is Not Root Cause This is perhaps the most important principle in cross-service troubleshooting. Suppose you see: A slow pipeline. A SQL memory-grant wait. Several concurrent activities. Those facts are correlated. They don't yet prove: "Memory contention caused the pipeline regression." A stronger conclusion requires a causal chain such as: The pipeline invokes the identified SQL request. That request repeatedly waits for execution memory during the regression. Competing queries hold substantial memory grants during the same period. Reducing the competing concurrency removes or materially reduces the grant wait. The same SQL invocation then returns toward its normal runtime. Repeating the workload reproduces the relationship. Now the evidence for causality is much stronger. This distinction matters because Azure SQL memory pressure can arise from several sources, including the chosen service objective, aggregate workload demand, and individual query memory demand. 16. Build a Cross-Service Evidence Package For difficult Synapse or Data Factory to Azure SQL regressions, both teams should be able to work from the same timeline. Capture: Pipeline evidence Pipeline run ID. Activity name. Activity start and end times. Sanitized parameters. Retry count. Timeout. Concurrent activities. Azure SQL evidence Session/request identification when captured live. Query Store query_id. Query Store plan_id. Runtime intervals. CPU time. Elapsed time. Logical reads. Wait type. Blocking session. Memory grant information. Execution plan. Investigation evidence Separate everything into: Facts Pipeline execution took longer than baseline. SQL request was identified. Request waited for memory. Multiple pipeline activities overlapped. A different plan appeared during the regression. Hypotheses Pipeline concurrency created memory-grant contention. Cardinality changes increased the requested memory grant. Parameter sensitivity caused a plan regression. Blocking contributed to runtime. Resource contention amplified an otherwise acceptable query. Experiments Document: What changed. Why it changed. Test duration. Result. Whether the hypothesis was strengthened or weakened. This prevents the pipeline and database teams from investigating two different incidents that simply happened at the same time. A Practical Decision Tree When a Synapse or Data Factory pipeline's Azure SQL activity suddenly becomes slow: 1. Can you identify the exact invocation? No Capture it before continuing. Yes Reproduce with equivalent parameters and concurrency. 2. Is SQL consuming significant CPU? Yes Investigate: Execution plan. Logical reads. Cardinality. Indexing. Parameter sensitivity. No Look at waits. 3. Is the request blocked? Yes Investigate: Blocking session. Transaction duration. Locking pattern. No Continue. 4. Is the request waiting for a memory grant? Yes Investigate: Requested versus granted memory. Other active grants. Sorts and hash operations. Cardinality estimates. Pipeline concurrency. No Investigate the actual current wait. 5. Did the execution plan change? Yes Compare: Runtime distributions. Parameter sets. CPU. Reads. Memory requirements. No Continue correlating waits, workload volume, and concurrency. 6. Does reducing concurrency improve the same invocation? Yes Resource competition becomes a stronger hypothesis. No Continue investigating query-specific behavior. Final Takeaway When a pipeline goes from minutes to hours, the fact that the Azure SQL activity is taking a long time doesn't automatically mean Azure SQL is spending all that time executing. The request might be spending much of its lifetime: Waiting for memory. Waiting behind another transaction. Waiting for another resource. Executing with a different plan. Processing a different parameter population. Competing with concurrent pipeline activities. A reliable investigation connects two perspectives: Pipeline context What exactly was invoked? With which parameters? At what time? At what concurrency? Database context Was the SQL request executing or waiting? How much CPU did it actually consume? What was it waiting for? Which plan did it use? How much memory did it request? What else was happening concurrently? sys.dm_exec_requests can identify active requests and their current execution state, while sys.dm_exec_query_memory_grants exposes statements that have requested or received execution memory. Azure SQL Database also supports obtaining transient plan information for in-flight requests through sys.dm_exec_query_statistics_xml(). Most importantly: Treat waits, memory grants, plan changes, and concurrency as evidence to test, not automatic root causes. That is how "the pipeline is slow" becomes a reproducible, evidence-backed performance diagnosis.