speech
72 TopicsVoice agents in Microsoft Foundry Agent Service now generally available
People want to talk to AI as naturally as they talk to each other, with instant responses in their preferred language and voices that sounds Human-like. For organizations, this opens a new way to serve customers, with conversations that feel personal at any scale. Voice agents in Microsoft Foundry Agent Service, now generally available, give teams one enterprise-grade platform to build, deploy, operate and continuously improve those experiences. Over the past year, Microsoft has made significant strides in bringing this vision to life. At Ignite 2025, Voice Live API became generally available, giving developers a unified API for natural, real-time voice conversations with any AI agent. At Build 2026, we introduced Voice Live integration with Microsoft Foundry prompt agents and hosted agents, making it easier to build voice-enabled AI experiences. Today’s release brings together advanced speech capabilities and comprehensive agent lifecycle management in a unified, enterprise-grade platform. Developers can now build, deploy, operate, and continuously optimize intelligent, speech-to-speech conversational agents, accelerating the journey from prototype to production. We're also announcing significant advancements to Speech in Microsoft Foundry: more accurate speech recognition, more natural and expressive voices, and expanded choices across languages, voices, and avatars. Together, these innovations empower organizations to create richer, more human-like voice experiences for customers around the world. Voice agents in Microsoft Foundry Agent Service Voice agents in Microsoft Foundry Agent Service are now generally available. It's an enterprise-grade platform for developers to build Speech to speech conversational voice agents by providing the leading Speech capabilities and supporting the full agent's lifecycle — from building and deployment to operations and continuous optimization. The general availability of voice agents in Microsoft Foundry Agent Service introduces a comprehensive set of capabilities designed to help developers build more natural, intelligent, and reliable voice experiences, while simplifying development and operations at enterprise scale. End-to-end voice agent lifecycle management Going beyond model APIs, Voice Agent builds on the Microsoft Foundry agent platform to help developers build, deploy, and operate enterprise-ready voice agents through a unified platform. Build and connect: Developers can create voice agents in minutes, connect them to enterprise knowledge through Foundry IQ, and integrate with rich tools through server-side MCP and client-side function calling, apply guardrails to help keep conversations safe and aligned with business policies, with private-network support for supported enterprise resources and integrations—helping teams control access to sensitive systems and data. Observe, evaluate, and improve: Built-in voice-native tracing, monitoring, and evaluation make conversations inspectable and quality measurable. For example, if a customer experiences a slow response during a billing inquiry, developers can inspect the turn-by-turn trace to determine whether the delay came from speech recognition, the model, a billing-system tool call, or speech synthesis—and replay the conversation when transcript and audio capture are enabled. Connect to existing channels with easy setup: Deploy voice agents on the web using audio or text input / output or connect them to existing telephony and contact-center infrastructure—including Teams Phone, Twilio, and Genesys—without rebuilding your customer experience. Bring AI-powered conversations to the channels customers already use, while managing agents through a unified platform. More natural, expressive, and intelligent voice conversations Deliver engaging, real-time conversations with greater flexibility in speech models and voices. Expanded choice of speech-to-speech models: Alongside existing GPT Realtime models, we’re introducing new options for more natural voice conversations, giving enterprises greater flexibility to balance conversational experience, agentic capabilities, and cost. GPT Live 1: Delivers full-duplex, highly natural, fluid conversations—from follow-up questions to complex, multi-step requests. Beyond delegating to specialized models, it can route tasks to Foundry prompt agents, and hosted agents across agent platforms, bringing their specialized knowledge, tools, and workflows into the conversation without breaking its flow. This lets enterprises combine an engaging voice experience with agents that handle work behind the scenes, for experiences where conversational richness and task completion both matter. Microsoft Realtime Flash 1: Combines low-cost serving with competitive conversational quality and agentic capabilities across typical voice-agent domains, including customer support, appointment scheduling, and routine service requests. It supports experiences where agents need to understand customer intent, sustain a natural conversation, and use tools to take action—not simply answer questions. Its cost-efficient approach helps enterprises move beyond small pilots toward the economics required for millions of calls per day, keeping operating costs manageable as adoption grows. The model is now in preview with Voice Live Lite tier pricing, offering an affordable path to scaling voice automation. Below is our internal test result on τ³-Voice benchmark. Microsoft Realtime Flash 1 achieved the highest reported average score in internal testing: 70.9 versus GPT-realtime-2.1’s 63.7—a 7.2-point improvement. Gains were strongest in telecom (+16.6 points) and retail (+3.5 points), while airline performance was lower (−6.0 points). Against GPT-realtime-2.1-Mini, the average improved by 39.2 points. More expressive voices: New HD V3 voices bring natural, real-time speech with greater expressiveness, optimized for customer service scenarios. Expanded language coverage includes English, Chinese, Filipino, Indonesian, Malay, and Indic languages. Developers can also control speaking styles and expressions using simple instruction tags, without learning complex markup languages. Enhanced conversation quality: Improved noise suppression helps voice agents stay focused on the primary speaker, reducing interference from television audio and background voices. Combined with more accurate turn-taking and end-of-speech detection, azure_semantic_vad v2 helps distinguish genuine interruptions from brief acknowledgments and speech directed at others—reducing unnecessary interruptions and premature responses for smoother, more natural full-duplex conversations than previous version. Below table reports our test results on Full-Duplex-Bench v1.5, a public benchmark that tests how a voice model behaves when someone else talks while it is speaking. Each column is the share of test cases where the model did the right thing (0 to 1). The total score is the plain average of the four columns. As you can see, the total score improved from 46.3% to 72.2%, a 25.9-percentage-point gain, with the largest improvements in handling speech directed at others and background voices. Customized voice and avatar experiences Create differentiated, branded experiences through customizable voices and avatars. Organizations can use their own data to develop custom voices that reflect their brand identity. We're also introducing VASA-2 Photo Avatar, which transforms a single photo into a lifelike, upper-body talking avatar. Building on VASA-1, VASA-2 delivers more natural movements and greater control over facial expressions, enabling richer and more engaging visual conversations. Flexible multi-agent orchestration for complex voice agents experiences Voice agents can seamlessly collaborate with Foundry prompt agents and hosted agents through flexible multi-agent patterns. Developers can choose the architecture that best fits their applications: Delegation to sub-agents: Voice agents handle real-time conversations while delegating complex reasoning and specialized tasks to backend agents. This keeps voice interactions responsive and low latency without sacrificing reasoning capabilities. Inline sub-agents: Developers can orchestrate multiple specialized voice agents in a graph-based workflow, each with its own instructions, tools, and voice. Agents can seamlessly transition between tasks during a conversation, improving accuracy, controllability, and cost efficiency. Hosted agents as conversation engines: Voice agents manage real-time speech input and output while communicating with hosted agents through bidirectional text streaming. This allows developers to preserve existing agent logic while adding advanced conversational voice capabilities. Together, these patterns make it easier to build sophisticated voice experiences that combine real-time responsiveness with powerful reasoning and enterprise workflows. Simplified development and enterprise integration Accelerate voice agent development with a streamlined developer experience and ready-to-use integrations. Unified developer tooling: Azure Developer CLI (AZD) and GitHub Copilot support help developers quickly build, test, and deploy voice agents using familiar development workflows. Ready-to-use templates: More than 40 industry-specific agent templates accelerate development across customer support and other business scenarios. Native telephony integration: Built-in Session Initiation Protocol (SIP) support enables voice agents to connect directly with existing contact center and telephony infrastructure, making it easier to bring AI-powered conversations into established customer service workflows. Since the public preview launch, thousands of customers have adopted voice agents across a wide range of scenarios, including customer service, automotive, education, human resources, personal assistants, public services, and more. Hear from customers already building voice agents in Foundry: "As a leading airline, Gulf Air is proud to work with Microsoft to advance how we use AI across our business. Through our collaboration, we have migrated and enhanced our existing voice agents in Microsoft Foundry, bringing voice, enterprise knowledge and intelligent tools together in a more integrated experience. This enables us to innovate faster and deliver even better experiences for our teams and customers." Ahmed AbdulJalil Ebranhim, Manager, Digital Innovation & Process Management, Gulf Air “The Hera companion is a voice agent built on Microsoft Foundry. What began as a proof of concept is now an operational experience. Anyone can talk to Hera: she listens and answers in real time. And she doesn’t just answer, she acts. Ask for a tour, and she turns the spacecraft to show you. Switch to Italian halfway through, and she keeps going. But a great voice isn’t enough; she has to be right. With voice agents in Foundry, Foundry IQ grounding and safety controls come together in one place, so every answer is grounded in ESA’s own mission knowledge and checked against Microsoft’s safety controls and our own rules." Daniele Montemaggiori, IT Cloud Services Architect, European Space Agency (ESA) "We tested multiple AI vendors and voice pipelines, and none delivered the customer experience we wanted. Voice agents in Microsoft Foundry finally made AI calls feel like a conversation instead of a phone tree - callers can interrupt, pause to think and speak naturally, and the agent keeps up. With a regional bank customer, our AI agent now handles 30% of calls from end to end. When a caller needs a person, it hands off to a human expert in Microsoft Teams on the same call, with full context." Matt Landis, CEO & Founder, Landis Technologies What’s new in Speech in Microsoft Foundry - More accurate, natural speech models Beyond powering voice agents described above, customers use Speech in Microsoft Foundry for live captions, meeting and call transcription and translation, voiceover for videos and e-learning, and reading content aloud. At Ignite 2026, we are making it more accurate, more natural and offering more choice across three core capabilities: speech to text, text to speech and avatars, and speech translation. Speech to text: understand more languages, faster and more accurately Speech to text converts streaming and file-based audio into high-quality transcripts for voice agents, live captions, contact center analytics, and meeting transcription. These scenarios increasingly involve many languages, speakers who switch languages mid-conversation, and large volumes of recorded audio. Our latest updates, all now generally available, address these needs across real-time transcription, Fast Transcription, and containers. Real-time transcription now offers native multilingual recognition across 50+ languages, with more on the way, so you no longer have to specify the language up front. Results arrive in about 100 milliseconds, with availability in select regions. Multichannel support transcribes two audio channels, such as agent and customer, separately and detects the language on each. For single-language audio, post-stream refinement now spans all language locales. To learn more, see our latest blogs on multichannel transcription and multilingual transcription. Fast Transcription and LLM Speech are now faster than ever, processing audio at a 100+ speed factor across 100+ multilingual languages, including expanded Indic language support. Mixed-language audio can now be transcribed in a single call. LLM Speech ranks among the leaders on Hugging Face's Open ASR Leaderboard and holds the top spot on the multilingual leaderboard, underscoring its quality across languages. Read more in our latest blog post and on the public documentation. Microsoft AI's MAI-Transcribe-2 is now available as an additional model option. On-Prem Containers now support Fast Transcription, letting you transcribe audio files on-premises with GPU inference through the same API you use in the cloud. Learn more Text to speech (TTS) and TTS avatar: more natural voices, more choice, more lifelike avatars Microsoft text to speech voices and avatars power many scenarios beyond voice agents mentioned in section 1 above. In addition, natural and expressive voices are required for voiceover, e-learning and read-aloud content, and other apps need voices that sound clear and engaging. At Ignite 2026, we are delivering two updates: a better and broader set of Neural HD standard voices, and the new VASA-2 photo avatar. New update for Neural HD standard voices: Besides the Neural HD v3 voices enhancement covered in voice agent scenario, we also extend our Neural HD standard voice offering with the Partner Voices (Public Preview), which brings HD voices built by partners such as DataoceanAI and Telus into Microsoft Foundry. Partner voices give customers more choices to find the right one for both their voice agents and content creation scenarios. Locale Voice Name Sample Script Audio Link En-CA TTS-354-F1 Oh no, I completely understand how that must feel—it can be really frustrating when things don’t go the way you expect. But don’t worry, you’re not alone. I’ll be with you every step of the way and make sure we get this sorted out quickly. Let’s take it one step at a time, okay? Ko-KR TTS-038 모두 50대 이상 중년층 고객이 가장 많이 증가한 것으로 나타 났다. Zh-CN TTS-373-F231 哎呀,我不是故意让你失望的!这样吧:如果你想要古怪又有趣、充满笑声的体验,就去看蓝人乐团。如果你想要令人惊叹又充满魔力的表演,太阳马戏团是最佳选择。两者都会让你的第一次约会难忘,所以无论选择哪一个都不会错。 New VASA-2 photo avatar (Public Preview): Avatar brings a face to voice agent and empowers content creation scenarios such as marketing video or training materials. VASA-2 photo avatar is specially designed to enrich the voice agent experience to be more engaged and personal. In Ignite 2026, we bring VASA-2 turns a single photo into a lifelike, upper-body talking avatar, an important upgrade from the talking head of VASA-1. It also moves more naturally and gives you more control over facial expressions to fit your scenario. Learn more. Speech translation: talk across languages in your own voice Language should not stand between people. Live Interpreter API, our real-time speech-to-speech translation service, now runs on a new LLM-based model that translates speech while people are still talking. Breakthrough translation quality: 30% fewer translation errors than the previous production model. Fast response: Translates end to end in under 3 seconds, on par with professional human interpreters. Your voice in every language: With Personal Voice, Live Interpreter API keeps the speaker's voice, style and tone in each language, so conversations feel natural and personal. Learn more Customers are already using Live Interpreter for contact center agent assist, on phones and smart devices such as earbuds and AI glasses, and in international meetings. Get started today Build voice agents: Getting started only takes a few steps: Open the Microsoft Foundry portal go to Build, Agents and New agent, select “Voice”. Choose a voice-optimized model and configure your agent's instructions. Connect knowledge sources and tools as needed for your scenario. Test conversations directly in the built-in voice playground. Deploy to your desired channels and monitor performance using built-in observability and evaluation capabilities. Explore Speech in Microsoft Foundry. Use the Speech playgrounds in Microsoft Foundry Portal to try Speech transcription, voices, avatars and Speech translation. When you’re ready to integrate speech into an application, start with the Speech SDK and Speech in Microsoft Foundry documentation.408Views0likes0CommentsBuild an Offline AI Voice Notebook on Raspberry Pi with Microsoft Foundry Local
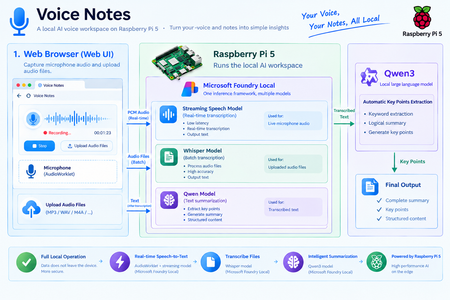
Can a Raspberry Pi turn spoken reflections into useful notes without sending audio to the cloud? In this walkthrough, you will build Voice Notes, a single-user voice notebook that captures speech in the browser, transcribes it with Microsoft Foundry Local, and drafts a summary on-device. Along the way, educators and learners can explore audio processing, web APIs, model lifecycle management, and responsible AI on resource-constrained hardware. Video demo: Watch the Voice Notes demo on Bilibili. Scope and versions: This is an educational prototype based on a recorded Raspberry Pi 5 experiment, not a managed classroom service or a Raspberry Pi hardware-certification statement. The walkthrough uses Microsoft Foundry Local Python SDK 2.1.0 and Foundry Local CLI Preview 0.10.3. These are separate packages with independent version numbers. Commands, model aliases, and APIs can change. The community sample is pinned to a specific revision so readers can follow the same implementation. What you'll build The finished application provides three workflows: Live transcription: Capture speech in the browser and display recognized text while recording. File transcription: Upload up to ten WAV or MP3 files and process them sequentially with Whisper. Local note generation: After a live recording ends, unload the speech model and use Qwen3 to extract topics, key points, decisions, and action items. Completed live sessions provide a playable WAV recording, a TXT transcript, and a JSON record. File-upload jobs provide TXT and JSON results; they do not create a new recording or automatically generate a summary. The sample's interface and generated summaries are in English. Transcripts retain the language recognized by the selected speech model. Local inference does not require an Azure subscription, an Azure resource, or a cloud inference API key. Installation, model acquisition, and any required runtime-component downloads need connectivity. After preparation, you will explicitly test the cached workflow without internet access rather than assuming it is offline-ready. Prerequisites Hardware and operating system Requirement Recommendation for this walkthrough Raspberry Pi Raspberry Pi 5 with 8 GB RAM; this matches the recorded device's memory capacity Operating system A 64-bit ARM Linux installation; the source experiment used Debian GNU/Linux 13, trixie Storage A 64 GB microSD card or SSD, with several gigabytes free for models and additional space for recordings Power and cooling A suitable Raspberry Pi 5 power supply and active cooling Audio input A USB microphone or a camera exposed to the Pi's operating system as an audio input Browser access A display connected to the Pi and a recent Chromium/Chrome/Edge/Firefox running on the Pi These are reproduction recommendations, not official minimum specifications. Software, accounts, and models You will need: Python 3.11 or later with an ARM64 wheel available for the selected SDK version. Git, curl, tar, and Python virtual-environment support. The sample's Python dependencies: Flask and foundry-local-sdk on Linux. A modern browser supporting getUserMedia, Web Audio, and AudioWorklet. Internet access for the initial downloads. A short speech recording you own or have permission to use. A GitHub account is not required to clone the public sample. The sample offers these model aliases: Task Alias used by the sample Starting point English live transcription nemotron-speech-streaming-en-0.6b Use for the English exercise below Multilingual live transcription nemotron-3.5-asr-streaming-0.6b Optional; validate the alias on the target device File transcription whisper-tiny, whisper-small Start with whisper-tiny Summarization qwen3-0.6b Loaded after speech recognition finishes The official live-transcription guide also shows the multilingual alias nvidia-nemotron-3.5-asr-streaming-multilingual-0.6b. Do not assume the two names are interchangeable in every catalog. The sample validates a fixed list of allowed aliases, so a catalog-name change must be reflected in the backend constants, not just typed into an API request. Architecture Foundry Local is an on-device runtime and SDK, not simply a command-line server. In this application, Flask calls Foundry Local in the same Python process. There is no separate Foundry REST endpoint in the application's inference path. Figure 2. Capture, web application, inference, and storage all run on the Raspberry Pi. Model acquisition needs connectivity; prepared inference uses local resources. The application runs one inference job at a time. This follows Foundry Local's single-user, hardware-constrained design and avoids keeping speech and chat models in memory together. For live audio, the browser sends approximately 100 ms of sound per chunk. Flask accepts ordered chunks, saves the recording, and feeds the native speech session. The UI polls for results, waiting 100 ms after each completed status request rather than issuing overlapping requests. Neither 100 ms chunks nor 100 ms polling means 100 ms recognition latency. Model processing and finalization are separate costs. The browser captures the Pi's microphone and sends audio only to the loopback-bound application on the same device. The inference path does not call a cloud model service. Step-by-step walkthrough All commands in this walkthrough run in a Bash terminal on the Raspberry Pi. Open the web application in a browser running on that same Pi. 1. Check the Pi and prepare the Python environment Confirm the architecture and available resources: uname -m cat /etc/os-release free -h df -h / Expect aarch64 for the ARM64 environment used here. armv7l indicates a 32-bit installation and cannot use the ARM64 archive below. Install the basic tools if necessary: sudo apt update sudo apt install -y git curl ca-certificates tar python3 python3-venv Clone the sample, select the article revision, and create an isolated environment: cd "$HOME" git clone https://github.com/shijiong/flask-audio-transcription.git cd flask-audio-transcription git checkout --detach e3047faa6e9181332e830b7f435b0ee6109521ef python3 -m venv .venv source .venv/bin/activate python -m pip install --upgrade pip python -m pip install -r requirements.txt "foundry-local-sdk==2.1.0" The repository allows a wider SDK 2.x dependency range. The explicit constraint above selects the version used in the source experiment; it does not claim that 2.1.0 is the latest version. Evaluate upgrades separately. On Linux, use foundry-local-sdk, not the Windows-specific foundry-local-sdk-winml package. Both expose the Python import name foundry_local_sdk. If pip cannot find a compatible distribution, check the operating-system architecture and Python version against the package's available wheels. Do not solve that error by installing an unrelated package or renaming the import. 2. Optionally install the CLI to validate file transcription The application does not require the CLI. This separate exercise is useful for checking the device, catalog, and a speech model before working through the web application. The CLI Preview 0.10.3 release includes a Linux ARM64 archive: cd "$HOME/Downloads" curl -fL -o foundry-0.10.3-linux-arm64.tar.gz https://github.com/microsoft/foundry-local/releases/download/cli-preview-0.10.3/foundry-0.10.3-linux-arm64.tar.gz printf '%s %s\n' 'c530e6354f29335fee4fd676b0f945e53a2dedcfc73c64fe336a39d27dbaec82' 'foundry-0.10.3-linux-arm64.tar.gz' | sha256sum --check Continue only if checksum verification reports OK. The digest above applies to this exact release asset. The screenshots in this step come from the original CLI 0.10.3 session. Some commands were run from its lib directory and the original audio filenames differ from the exercise filenames below. The commands in this article consistently use ./lib/foundry from the installation root. tar xzf foundry-0.10.3-linux-arm64.tar.gz -C "$HOME" cd "$HOME/foundry-0.10.3-linux-arm64" Keep the complete extracted directory; copying only the executable can omit required runtime files. Check the executable and inspect the device: ./lib/foundry --version ./lib/foundry status recorded status output identifies the device and resources. Inspect the command help and model catalog: ./lib/foundry --help ./lib/foundry model --help ./lib/foundry model list ./lib/foundry server status Inspect and cache the lightweight file-transcription model: ./lib/foundry model info whisper-tiny ./lib/foundry model download whisper-tiny ./lib/foundry transcribe --help For an existing English speech file saved as Documents/Recording.mp3, run: ./lib/foundry transcribe -m whisper-tiny -l en -f "$HOME/Documents/Recording.mp3" Replace the path with your actual recording. The screenshot below shows the original English MP3 test rather than the synthetic classroom reflection introduced later. For an existing Chinese recording, use a Chinese language hint: ./lib/foundry transcribe -m whisper-tiny -l zh -f "$HOME/Documents/output_16k_mono.wav" These file-based CLI checks are separate from the timed live-streaming benchmarks discussed in Test the solution. After this exercise, stop the CLI server so it does not compete with the web application for memory: ./lib/foundry server stop 3. Prepare the models through the application's SDK path Return to the sample and activate the same environment: cd "$HOME/flask-audio-transcription" source .venv/bin/activate Save the following as prepare_models.py in the repository root: from src.foundry_backend import FoundryBackend backend = FoundryBackend() aliases = ( "nemotron-speech-streaming-en-0.6b", "whisper-tiny", "qwen3-0.6b", ) for alias in aliases: with backend.model(alias, print) as model: print(f"Ready: {alias} -> {model.info.id}") Run it before starting Flask, not alongside another inference process: python prepare_models.py FoundryBackend is the sample's adapter, not a class supplied by the SDK. It initializes FoundryLocalManager, registers execution providers, looks up each alias through manager.catalog.get_model(), downloads the model, loads it, and unloads it when the context ends. A missing model causes an explicit error. The application does not silently substitute another model. Add the multilingual model or whisper-small to this preparation list only if you intend to use them. The adapter also contains a Linux SDK 2.1.0-specific compatibility workaround, setting CI=1 before SDK initialization for the issue described in the sample README. Treat this as version-scoped sample behavior, not a universal telemetry configuration or an offline guarantee. 4. Configure storage and start the workbench Use the default local data directory, or choose another writable location: export TRANSCRIPTION_DATA_DIR="$HOME/voice-notes-data" export PORT=5000 python src/app.py The sample binds to 127.0.0.1:5000 with debug mode disabled. Run a single application process: the active job, inference slot, and native sessions are held in memory. Multiple worker processes or the Flask debug reloader can create conflicting state and duplicate model allocations. On the Pi, open: http://127.0.0.1:5000 Browser microphone APIs require a secure context. The Pi's loopback address qualifies. Keep the application bound to loopback and use the browser and microphone on the Pi for this walkthrough. 5. Capture speech and generate notes Select Live transcription. Choose a microphone and nemotron-speech-streaming-en-0.6b. Select English and click Start live transcription. Grant microphone permission, wait for the model to become ready, and check that the input-level indicator responds. Speak a short reflection. Click Stop & summarize, then wait for finalization and summary generation. Behind the interface, the browser converts its microphone stream to 16 kHz, mono, signed 16-bit little-endian PCM. A full 100 ms chunk contains 1,600 samples, or 3,200 bytes. The last chunk may be shorter. Each upload carries an increasing X-Audio-Sequence number. Retrying an accepted sequence does not append duplicate audio. On stop, the browser flushes its remaining samples, uploads queued audio, and finishes the input stream before the native session closes. The UI understands interim and confirmed text, but a model is not guaranteed to emit interim results. Interim hypotheses replace earlier interim text; confirmed segments are appended; the final aggregate replaces the accumulated transcript rather than duplicating it. After recognition finishes, the service unloads the speech model and loads Qwen3. If summarization fails, the warning remains visible and the application still attempts to preserve the recording and transcript. 6. Transcribe existing audio files Select Audio files, choose whisper-tiny, select a language, and upload one or more WAV or MP3 files. The sample permits up to ten files and a 100 MiB total request limit. Files are processed sequentially. A decoding or inference failure for one accepted file does not discard successful results from the others. For a predictable first test, use 16 kHz mono audio and 16-bit PCM encoding for WAV. If FFmpeg is installed, an optional preparation command is: ffmpeg -i input.mp3 -ar 16000 -ac 1 -c:a pcm_s16le lesson.wav The web application does not run an external conversion step, and its extension checks do not validate every audio-format property. The published benchmark also demonstrates that the runtime accepted a 24 kHz stereo MP3. Therefore, 16 kHz mono is preparation guidance here, not a demonstrated universal file-input restriction. Code and configuration A compact file-to-summary pipeline To see model sequencing without the browser, save this as transcribe_and_summarize.py in the repository root, next to a short Recording.mp3 file: from pathlib import Path from src.foundry_backend import FoundryBackend audio_path = Path("Recording.mp3") if not audio_path.is_file(): raise FileNotFoundError(f"Audio file not found: {audio_path.resolve()}") backend = FoundryBackend() with backend.model("whisper-tiny", print) as speech_model: transcript = backend.transcribe(speech_model, audio_path, "en") if not transcript.strip(): raise RuntimeError("No speech was recognized. Check the audio and language.") print("\nTranscript:\n", transcript) summary = backend.summarize(transcript, print) print("\nDraft summary:\n", summary) Run it while Flask and other inference jobs are stopped: python transcribe_and_summarize.py The context manager unloads Whisper before summarize() loads Qwen3. This script deliberately adds a file-to-summary flow; it does not change the file-upload tab's transcription-only behavior. Summarization settings and longer recordings The pinned sample uses a native ChatSession with an OpenAI-format JSON payload. These are the relevant generation settings, excerpted from that payload: { "temperature": 0.2, "max_tokens": 700, "chat_template_kwargs": { "enable_thinking": false } } The prompt asks for English topics, key points, decisions, and action items, preserves names and numbers, and treats the transcript as data rather than instructions. The implementation disables Qwen's thinking mode explicitly, removes residual thinking markup, and reports an error for an empty answer. It does not substitute reasoning text for a summary. For transcripts longer than 3,500 characters, the adapter summarizes sections and combines their notes recursively, for at most eight levels. If compression stops reducing the text, it preserves section summaries instead of silently truncating the source transcript. Character limits are an implementation heuristic, not a model-independent token budget. Low temperature and a careful prompt do not guarantee faithful output or prevent all prompt-injection behavior. Keep the original transcript and require human review. Explore the full implementation Sample component What to inspect Flask application Host and origin checks, request tokens, input validation, and artifact routes Job service One-job scheduling, ordered audio, finalization, and persistent artifacts Foundry Local adapter SDK initialization, native audio sessions, file transcription, and hierarchical summaries AudioWorklet Continuous resampling, PCM encoding, level reporting, and final flush Test suite Fake inference backends, native buffer checks, and browser-side regression tests The native streaming implementation retains Python audio-buffer references until the native request, session, and queue close. If you adapt that code, preserve the lifetime handling: a successful queue insertion is not proof that native inference has finished reading the buffer. Test the solution Run the automated tests From the sample repository root: python -m pip install -r requirements-dev.txt python -m pytest tests -q -rs Most tests use fake inference backends. Native buffer tests require the standard SDK; browser regression tests require Chromium and can otherwise be skipped. Inspect the skip reasons. A passing test run does not establish real-model accuracy, microphone functionality, or catalog availability on your Pi. Recorded Raspberry Pi benchmark results The public benchmark results contain four complementary experiments: Whisper file transcription, English live transcription, Chinese live transcription, and Qwen3 summarization. The reports describe measurements made on October 19, 2026. The common platform was a Raspberry Pi 5 Model B Rev 1.1 with 8 GB RAM and four Cortex-A76 cores, running Linux ARM64 and Foundry Local SDK 2.1.0 with CPUExecutionProvider. The reports record Python 3.14.8; use the supported interpreter/wheel combination available for your own installation. Each model or scenario ran three times in a fresh process, with models already downloaded and no concurrent inference. Unless stated otherwise, times are medians, parenthesized intervals are observed minimum-to-maximum ranges, and memory is the maximum process peak RSS across the runs. Operating-system file caches and desktop background workloads were not cleared. Fresh processes are not equivalent to cold-machine tests. 1. Whisper: English audio-file transcription The Whisper report uses the original, unmodified 16.488-second, 24 kHz stereo MP3 with language auto-detection. The runtime handled decoding and preprocessing inside the measured transcription call. Metric whisper-tiny whisper-small Median model loading time 1.875 s (1.781-2.634) 2.810 s (2.754-5.656) Median transcription time 2.676 s (2.421-3.175) 10.398 s (10.239-10.803) Median real-time factor 0.162 0.631 Maximum process peak RSS 338.7 MiB 824.7 MiB Median SDK/catalog/cache/load-to-ready time 4.736 s 8.499 s Median SDK/catalog/cache/load-plus-transcription time 7.165 s 19.303 s The resolved variants were openai-whisper-tiny-generic-cpu:4 and openai-whisper-small-generic-cpu:4. Real-time factor = transcription time / audio duration. The medians correspond to approximately 6.16 times and 1.59 times real-time batch processing speed. Tiny transcribed this clip about 3.89 times faster; Small used about 2.43 times as much peak process memory. Small's text was more fluent in a text-only review, but there was no verified reference transcript or listening-based accuracy assessment. Do not infer word error rate, character error rate, or a general accuracy ranking from that observation. HTTP upload, artifact saving, summarization, and model unload are outside these timing boundaries. 2. English and Chinese live transcription The English live report and Chinese live report exercise the real NativeLiveSession and the application's transcript-assembly logic. They do not include browser capture, Flask HTTP, UI polling, or summary generation. English input: The same 16.488-second MP3, decoded with FFmpeg to 16 kHz mono PCM16LE before timing. The harness sent 527,616 bytes in 165 chunks at approximately real-time pacing. Chinese input: A 15.998563-second, 16 kHz mono PCM16 WAV. The harness extracted its original PCM without resampling and sent 511,954 bytes in 160 chunks. Language was explicitly zh-CN, not auto-detection. Pacing: A full chunk was 100 ms; the final shorter chunk was preserved. No additional trailing silence was inserted. Stream timing began immediately before the first audio append. Metric English live transcription Chinese live transcription Model alias nemotron-speech-streaming-en-0.6b nemotron-3.5-asr-streaming-0.6b Catalog download-size metadata 696 MB 756 MB Cached model loading time 3.197 s (3.162-6.185) 3.583 s (3.268-3.857) First nonempty interim/partial event No nonempty partials in any run No nonempty partials in any run First application-confirmed text 1.501 s (1.500-5.113) 1.482 s (1.468-4.996) First event containing a Chinese character Not applicable 1.482 s (1.468-4.996) Finish-to-stream-drained time 0.673 s (0.549-0.780) 0.559 s (0.546-2.066) First audio append to completed stream 17.161 s (17.037-17.269) 16.558 s (16.545-18.067) Maximum process peak RSS 936.8 MiB 994.0 MiB The Chinese final transcripts were identical across the three runs and contained 74 Chinese characters and two <zh-CN> markers. The first nonempty confirmed event already contained Chinese characters, so the first-Chinese-character metric was not shortened by a language tag arriving alone. The report flags wording in the raw output for human checking rather than silently correcting it. The English output also included awkward wording, such as You uh ban could give their fans. Successful streaming and repeatable output do not establish recognition accuracy. Preserve raw language tags and transcripts if you add display-layer cleanup. 3. Qwen3: English summarization of a completed transcript The Qwen3 report uses a 786-character English transcript containing language tags. Its subject is a trip to New York, not the classroom sensor example above. Each run called the real FoundryBackend.summarize() path with qwen3-0.6b-generic-cpu:4, temperature=0.2, max_tokens=700, and enable_thinking=false. Metric Recorded result Catalog download-size metadata 593 MB Model loading time 12.085 s (10.006-12.519) Model-ready summary-processing time 14.052 s (13.488-16.568) Complete summarize() call 26.842 s (23.751-28.945) Separately measured harness catalog lookup 62.864 s (62.763-63.508) Complete fresh benchmark subprocess 90.140 s (87.790-92.496) Maximum process peak RSS 1333.5 MiB Output lengths for runs 1, 2, and 3 532, 716, and 427 characters Hierarchical summarization Not triggered in any of the three runs The 14.052-second figure measures processing after the model is ready: prompt/payload construction, the native request, response parsing, and cleanup. It excludes model loading and unloading and is not a token-decoding-kernel measurement. The 26.842-second value includes the model context inside summarize(), but the harness had already initialized the SDK and queried metadata. The 90.140-second subprocess measurement additionally includes harness setup, a separate catalog lookup, cleanup, telemetry, and result writing. It is not a measured Flask/browser interaction time or pure inference time. These timing boundaries differ, and medians of separate stages need not sum to a combined median. Low temperature did not make the outputs identical. The report notes that some outputs were closer to sentence-by-sentence extraction and omitted details such as a travel companion or purchases. No human-reference summary score was calculated. Because the input was below 3,500 characters, this experiment does not validate long-transcript hierarchical summarization. Troubleshooting and considerations Common issues Symptom What to check CLI reports Permission denied Inspect the exact executable named in the error. Restore owner execute permission only for that trusted file; also check for a noexec mount. Do not use blanket chmod 777 or routinely run inference as root. CLI works but its server cannot start Inspect foundrylocald permissions and use ./lib/foundry server logs. This is separate from the SDK application's in-process inference path. No module named 'foundry_local_sdk' Use the same virtual-environment interpreter for dependency installation and Flask startup. Model alias is unavailable Check the target catalog and update the sample's allowed model constants if necessary; a UI option is not a hardware-availability guarantee. Browser microphone APIs are unavailable Open http://127.0.0.1:5000 in the browser running on the Pi and check microphone permission. Input level remains zero Check the selected microphone, browser permission, operating-system mute/input volume, and cable or USB connection. WAV contains speech but text is missing Check the model's language support, actual inference errors, and native buffer-lifetime handling if you changed the implementation. HTTP 409 while starting another job Wait for the active job, including summarization, to finish. A multilingual transcript contains language tags The model can emit markers such as <zh-CN>. Preserve raw output; make any display cleanup an explicit application choice. Edge-device and responsible-use considerations CPU, not assumed acceleration: The recorded Pi used CPU execution. An ARM64 package does not automatically enable the Pi GPU or an add-on AI accelerator; compatible drivers, execution providers, and model variants are required. Power and thermals: Use active cooling and stable power. Where available, inspect vcgencmd measure_temp and vcgencmd get_throttled; other Linux installations may not provide these utilities. Storage and memory: A 60-minute, 16 kHz mono PCM16 recording contains approximately 115.2 MB of audio before its small WAV header. The streaming adapter also retains approximately that much PCM in memory until the session closes, in addition to model and object overhead. Persistence is not disaster recovery: Completed artifacts remain on disk, but data is not deleted automatically. Active sessions cannot resume after a process restart, and power loss can leave an incomplete recording. Local is not automatically secure: The sample does not provide user accounts, per-user authorization, or encryption at rest. Its request token protects against cross-site writes; it is not user authentication. Do not expose the demo as a classroom server: Binding to all interfaces is not a deployment strategy. A networked service needs HTTPS, authentication, authorization, retention policies, rate limits, and an appropriate application-serving architecture. Check network and privacy requirements: Inference is local, but model downloads, updates, and SDK diagnostics or telemetry are separate concerns. Review the Foundry Local privacy FAQ and applicable terms, and verify the actual network behavior required by your environment. Keep people in the loop: Use synthetic or consented recordings for teaching. Review names, numbers, decisions, and action items before sharing notes. This prototype is not a validated accommodation service or a tool for high-stakes assessment. Next steps Start with one microphone, a short English recording, and the three prepared models. Once that path is reliable, extend the project deliberately: Compare model trade-offs. Use representative recordings and a human-verified reference to compare Whisper Tiny and Small on time, memory, and word or character error rate. Explore multilingual reflections. Verify a multilingual model on the Pi, test each intended language, and distinguish transcription language from English summary language. Improve note quality. Ask learners to compare summaries with transcripts, identify unsupported claims, and test whether a revised prompt actually improves factual fidelity. Add retention controls. Implement an explicit delete/export workflow and consider operating-system storage encryption before using sensitive material. Improve long-session robustness. Evaluate segmented recording, bounded native-session memory, and crash-safe artifact handling. Design a different architecture for shared use. A multi-user classroom application needs more than extra Flask workers; reassess state management, authorization, and the inference runtime. Useful resources: What is Foundry Local? Get started with Foundry Local Foundry Local architecture overview Tutorial: Build a voice-to-text note taker Live transcribe audio from a microphone Foundry Local CLI reference Complete Voice Notes community sample MDN: AudioWorklet MDN: Secure contexts365Views0likes1CommentBring Your Own Telephony to Voice Agents via SIP
Voice agents in Microsoft Foundry give developers an integrated way to build intelligent, natural voice experiences, bringing together models, agent capabilities, tools, and the platform capabilities needed to move from experimentation to production. Foundry continuously expands channel integration options to serve different organizational needs. Voice agents in Microsoft Foundry and Voice Live API now support Session Initiation Protocol (SIP), allowing phone calls to reach AI voice agents directly through SIP trunks. This enables low-latency voice interactions while letting you continue using your existing contact center telephony infrastructure. What is SIP - SIP (Session Initiation Protocol) is an industry-standard signaling protocol for establishing, managing, and terminating real-time communication sessions. It is widely used in IP telephony, including enterprise and contact center environments. Why voice agents need SIP for contact center telephony - Enterprise telephony and contact center environments commonly use SIP-based PBXs, session border controllers (SBCs), and carrier trunks. SIP enables voice agents to integrate with this existing telephony infrastructure for call signaling, routing, and media negotiation. Direct SIP vs. Customer-managed Audio Bridge - Direct SIP connects voice agents with existing telephony and contact center infrastructure through standard SIP interfaces. In comparison, a customer-managed audio bridge requires customers to build and operate an intermediary layer to relay real-time audio between their telephony infrastructure and the voice agent, typically over WebSocket or WebRTC. This adds integration complexity, potential latency, and operational overhead. Direct SIP significantly simplifies the architecture by eliminating the need for this intermediary audio layer. Understand the call flow: Caller (inbound) -> telephony provider or enterprise telephony system -> SIP trunk or SBC -> Foundry SIP endpoint -> telephony binding -> voice agent Get started with voice agents in Microsoft Foundry Getting started only takes a few steps: Open the Microsoft Foundry portal and create a new agent, select Voice as the agent type. Choose a voice-optimized model and configure your agent's instructions. Connect knowledge sources and tools as needed for your scenario. Test your agent directly in the built-in voice playground. Go to Channels tab -> Phone numbers -> Direct SIP. Add your SIP trunk connection using the same credentials provided by your SIP trunk provider, then bind the connection to the voice agent for inbound calls. (For outbound calls, no binding is required; configure the SIP connection through the SDK or REST API when placing a call). Copy the SIP binding URL and configure it with your SIP trunk provider to route calls to your voice agent. Make a test call, then monitor performance using built-in observability and evaluation capabilities. Learn More Introducing voice agents in Microsoft Foundry | Microsoft Community Hub Quickstart: Create a voice-based prompt agent - Microsoft Foundry | Microsoft Learn How-to: Connect a voice agent to telephony via SIP - Microsoft Foundry | Microsoft Learn How-to: Connect voice live API to telephony via SIP - Foundry Tools | Microsoft Learn554Views0likes0Comments
Introducing Dragon HD Omni: Azure Speech New Voice Type Now in Preview via Microsoft Foundry
Dragon HD Omni is Microsoft Azure Speech’s newest text‑to‑speech generation, delivering over 700 high‑quality voices with enhanced expressiveness, multi‑lingual fluency, and multi‑style control — all through a unified model built in Microsoft Foundry. It removes common developer pain points such as unnatural voice prosody, limited language coverage, and heavy SSML tuning effort. The result is a powerful value proposition: faster integration, richer user experiences, and production‑ready voice output with minimal effort. Azure speech offers a broad range of unique voices for applications like virtual agents, audiobooks, podcasts, and speech-to-speech tasks. Demo video 700+ prebuilt voices Dragon HD Omni offers a range of prebuilt voices with distinct personas and emotions, supporting diverse use cases from agent-based applications to content creation. These voices unlock endless possibilities, empowering users to enhance end-to-end applications. Full update for previous generation voices Dragon HD Omni merges a wide range of prebuilt voices into one, improving contextual adaptation, prosody, expression, and keeping each voice's unique character. This technology delivers more accurate, flexible, and lifelike speech for a variety of uses. Dragon HD Omni raises the standard for natural AI voices across customer service, accessibility, and creative projects, advancing human-computer interaction. You can explore some voices from voice list, such as: "en-US-Ava:DragonHDOmniLatestNeural" "en-US-Andrew:DragonHDOmniLatestNeural" "en-US-Dana:DragonHDOmniLatestNeural" "en-US-Caleb:DragonHDOmniLatestNeural" "zh-CN-Xiaoyue:DragonHDOmniLatestNeural" "zh-CN-Yunqi:DragonHDOmniLatestNeural" "en-US-Phoebe:DragonHDOmniLatestNeural" "en-US-Lewis:DragonHDOmniLatestNeural" They will be available to try directly via Speech Playground - Microsoft Foundry Or, you can use this voice name format by adding the suffix `:DragonHDOmniLatestNeural` to try the Omni version of the given voice via direct SSML call. For example: Previous neural voice Omni version voice name de-DE-ConradNeural de-DE-Conrad:DragonHDOmniLatestNeural AI-Generated Voices Dragon HD Omni now features nearly 300 brand‑new AI‑generated voices, carefully designed to deliver an unprecedented range of vocal diversity. These voices aren’t just more of the same — they’re built to give you choice, flexibility, and creative control. With variations across: Gender – male, female, and non‑binary options Age – youthful, mature, and senior tones Pitch & tone – from warm and friendly to authoritative and professional This expanded library means you can: Personalize experiences for different audiences, whether you’re building an educational app, a customer support bot, or a storytelling platform. Strengthen brand identity by selecting voices that reflect your company’s personality and values. Increase inclusivity with diverse vocal styles that resonate across cultures and communities. Unlock creativity by experimenting with unique voice personalities for podcasts, games, or immersive experiences. Speaker name – Description Sample en-us-graphiterhodium - A bold and dramatic male voice en-us-olivepoivre - An adult female voice that is calm and soothing. Check the full Dragon HD Omni voice list at here. Styles control Standard Azure voices have limited styles due to extensive tuning requirements. The Dragon HD Omni introduces automatic style prediction using natural language descriptions, enabling advanced customization, broader style support, reduced cost, and improved expressiveness. In the initial release, styles will launch for en-US-Ava and en-US-Andrew. Supported styles angry, chill surfer, confused, curious, determined, disgusted, embarrassed, emo teenager, empathetic, encouraging, excited, fearful, friendly, grateful, joyful, mad scientist, meditative, narration, neutral, new yorker, news, reflective, regretful, relieved, sad, santa, shy, soft voice, surprised Note that style result will be strongly influenced by the input content. SSML example <speak version="1.0" xmlns="http://www.w3.org/2001/10/synthesis" xmlns:mstts="http://www.w3.org/2001/mstts" xml:lang="en-US"> <voice name="en-us-ava:DragonHDOmniLatestNeural"> <mstts:express-as style="cheerful"> Wow! What an amazing day! I feel so full of energy, and everything around me seems brighter. My voice is bubbling with excitement, and I can’t stop smiling. I’m ready to take on anything that comes my way—let’s celebrate this wonderful moment together! </mstts:express-as> </voice> </speak> Multilingual and Accents All Dragon HD Omni voices support multiple languages, with the capability that can automatically predicting and generating output based on the input text. Additionally, you may utilize the tag to adjust speaking languages and accents, such as fr-FR for French, de-DE for German, etc. For a comprehensive list of supported languages and their associated syntax and attributes, please refer to the lang element. SSML example <speak version="1.0" xmlns="http://www.w3.org/2001/10/synthesis" xmlns:mstts="http://www.w3.org/2001/mstts" xml:lang="en-US"><voice name="en-us-ava:Dragon HD OmniLatestNeural"><lang xml:lang="fr-FR"> Bonjour ! Ce matin, j’ai pris un café au jardin du Luxembourg. Il faisait frais, mais très agréable. Ensuite, j’ai acheté une baguette et quelques macarons. Paris est vraiment charmant.</lang> </voice> </speak> Word Boundary Event Support Dragon HD Omni supports the word boundary event, which allows developers to track the precise timing of each word as it is spoken. This feature is essential for applications requiring word-level synchronization, such as karaoke, real-time captioning, or interactive voice experiences. When the event fires, it provides: Text: The word spoken AudioOffset: The time offset in the audio stream (milliseconds) TextOffset: The position of the word in the input text Example: Python Sample Using Wordboundary Event in Azure Speech SDK import azure.cognitiveservices.speech as speechsdk def word_boundary_cb(evt): print(f"Word: '{evt.text}', AudioOffset: {evt.audio_offset / 10000}ms, TextOffset: {evt.text_offset}") speech_config = speechsdk.SpeechConfig(subscription="YourSubscriptionKey", region="YourServiceRegion") synthesizer = speechsdk.SpeechSynthesizer(speech_config=speech_config) synthesizer.synthesis_word_boundary.connect(word_boundary_cb) ssml = """ <speak version="1.0" xmlns="http://www.w3.org/2001/10/synthesis" xmlns:mstts="http://www.w3.org/2001/mstts" xml:lang="en-US"> <voice name="en-us-ava:DragonHDOmniLatestNeural"> Hello Azure, welcome to Dragon HD Omni! </voice> </speak> """ result = synthesizer.speak_ssml_async(ssml).get() Sample Output: Word: 'Hello', AudioOffset: 110.0ms, TextOffset: 182 Word: 'Azure', AudioOffset: 590.0ms, TextOffset: 188 Word: ',', AudioOffset: 1110.0ms, TextOffset: 193 Word: 'welcome', AudioOffset: 1270.0ms, TextOffset: 195 Word: 'to', AudioOffset: 1750.0ms, TextOffset: 203 Word: 'Dragon HD Omni', AudioOffset: 1910.0ms, TextOffset: 206 Word: '!', AudioOffset: 2750.0ms, TextOffset: 216 Parameters Dragon HD Omni supports advanced parameter tuning to help you customize voice output for different scenarios. This guide explains each parameter in simple terms and provides recommendations for adjusting them based on your goals. Overview Parameter Default Range Purpose temperature 0.7 0.3 – 1.0 Controls creativity vs. stability top_p 0.7 0.3 – 1.0 Filters output for diversity top_k 22 1 – 50 Limits number of options considered cfg_scale 1.4 1.0 – 2.0 Adjusts relevance and speech speed Tuning for Expressiveness vs. Stability Higher values for temperature, top_p, and top_k result in more expressive, emotionally varied speech. Lower values produce more stable and predictable output. Recommendation: To increase expressiveness, raise all three parameters together. Keep top_p equal to temperature for best results. Tuning for Speed and Contextual Relevance cfg_scale affects how quickly the voice speaks and how well it aligns with the context. Higher values (e.g., 1.8–2.0): faster speech, stronger contextual relevance. Lower values (e.g., 1.0–1.2): slower speech, less contextual alignment. Suggested Tuning Strategies Goal Suggested Adjustment More expressive Increase temperature, top_p, and top_k together More stable Lower temperature first, then adjust top_p if needed Faster & relevant Increase cfg_scale Slower & neutral Decrease cfg_scale The following table describes the usage of the parameters above: Single parameter: <speak version="1.0" xmlns="http://www.w3.org/2001/10/synthesis" xmlns:mstts="http://www.w3.org/2001/mstts" xml:lang="en-US"> <voice name="en-us-ava:Dragon HD OmniLatestNeural" parameters="top_p=0.8"> Hello Azure! </voice> </speak> Multiple parameters: <speak version="1.0" xmlns="http://www.w3.org/2001/10/synthesis" xmlns:mstts="http://www.w3.org/2001/mstts" xml:lang="en-US"> <voice name="en-us-ava:Dragon HD OmniLatestNeural" parameters="top_p=0.8;top_k=22;temperature=0.7;cfg_scale=1.2"> Hello Azure! Hello Azure! </voice> </speak> Get Started In our ongoing journey to enhance multilingual capabilities in text to speech (TTS) technology, we strive to deliver the best voices to empower your applications. Our voices are designed to be incredibly adaptive, seamlessly switching between languages based on the text input. They deliver natural-sounding speech with precise pronunciation and prosody, making them invaluable for applications like language learning, travel guidance, and international business communication. Microsoft offers an extensive portfolio of over 600 neural voices, covering more than 150 languages and locales. These TTS voices can quickly add read-aloud functionality for a more accessible app design or provide a voice to chatbots, elevating the conversational experience for users. With the Custom Neural Voice capability, businesses can also create unique and distinctive brand voices effortlessly. With these advancements, we continue to push the boundaries of what’s possible in TTS technology, ensuring that our users have access to the most versatile, high-quality voices for their needs. For more information Try our demo to listen to existing neural voices Add Text to speech to your apps today Apply for access to Custom Neural Voice Join Discord to collaborate and share feedback Contact us ttsvoicefeedback@microsoft.com5.2KViews0likes1CommentVoice agents in Foundry Agent Service: architecture, trust boundaries, and real-audio latency
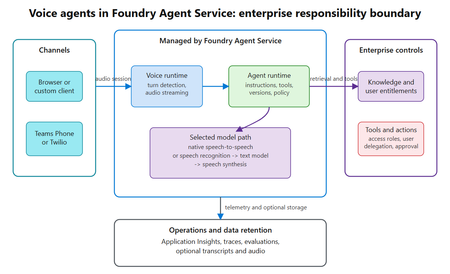
Assess where voice agents in Foundry Agent Service simplify the runtime, where enterprise trust boundaries remain, and what a 300-turn real-audio benchmark reveals about latency across six configurations.553Views0likes0CommentsIntroducing GPT-transcribe and GPT-live-transcribe in Microsoft Foundry
A transcription model hears “account number 8-4-7-2” but returns “account number eighty-four seventy-two.” A single error can break a downstream automation workflow. Developers building voice applications need transcription models that can handle real-world audio conditions, natural speech patterns, and business-critical details, including codes, dates, addresses, account numbers, mixed-language conversations, specialized terminology, and quiet or low-volume speech. GPT-transcribe and GPT-live-transcribe do just that and are available in Microsoft Foundry today. Two updates to the audio model family designed to improve automatic speech recognition across asynchronous transcription and live streaming scenarios. Built for More Accurate Transcription in Real-World Audio GPT-transcribe is the highest accuracy ASR model from Open AI, designed for asynchronous speech-to-text transcription of completed audio files and batch workloads. It accepts audio input and returns text output, making it a strong fit for workflows that process recorded, uploaded, or submitted audio, including meeting recordings, voicemails, and media files. GPT-live-transcribe is designed for low-latency streaming transcription through the Realtime API. It supports real-time audio input and text output, helping developers build live experiences where speech needs to be transcribed continuously as audio arrives. This model also introduces “tunable latency” where developers can adjust the latency/accuracy trade-off for streaming. It is a strong fit for live captions, voice assistants, contact center workflows, accessibility experiences, field service applications, real-time intake, and monitoring systems. Together, these models give developers transcription options in Microsoft Foundry for stored audio and live voice interactions. Their text output can support downstream workflows such as search, summarization, routing, analytics, automation, and quality review. What’s New in Both Models The features of the new transcription models focus on improving transcription quality in real-world audio environments where speech can be brief, noisy, accented, quiet, domain-specific, or mixed across languages. Key capabilities include: Background noise: Helps isolate speech in noisy environments so transcription quality can remain more reliable when audio conditions are not controlled. Short utterances: Improves recognition of brief commands, confirmations, interruptions, and clipped speech that can be difficult to capture accurately. Alphanumeric perception: Strengthens transcription of IDs, codes, phone numbers, dates, addresses, account numbers, and mixed letter-number sequences. Domain terminology understanding: Improves recognition of specialized vocabulary used in product, workflow, industry, and business-process contexts. Codemix: Improves understanding when speakers switch between languages within a conversation or utterance. Context awareness: Uses topic hints and past conversation context to improve transcription accuracy and help maintain consistency. Accent robustness: Improves handling of regional accents, non-native accents, dialects, and varied speaking styles. Whispering: Improves recognition of quiet or low-volume speech, including whispered commands and private dictation. Live captioning and accessibility experiences: Generate real-time captions for meetings, events, media experiences, and assistive applications. Contact center and voice workflows: Capture spoken details as conversations happen, supporting routing, quality review, summarization, and downstream automation. Monitoring, analytics, and compliance workflows: Provide text visibility into ongoing spoken input so teams can analyze, review, and act on conversation data. Also Available: GPT-realtime-2.1 and GPT-realtime-mini-2.1 gpt-realtime-2.1 and gpt-realtime-mini-2.1 are also available in Microsoft Foundry for developers building speech-to-speech applications. Unlike GPT-transcribe and GPT-live-transcribe, which return text, these models accept audio and generate audio for low-latency conversational experiences over the Realtime API. gpt-realtime-2.1 focuses on interaction quality and robustness, while gpt-realtime-mini-2.1 provides a smaller, faster, and more cost-efficient option for high-volume deployments. Together with GPT-transcribe and GPT-live-transcribe, these realtime audio updates give developers more flexibility to build voice applications that need both accurate transcription and responsive spoken interaction, whether the experience is centered on capturing speech as text, responding with audio, or combining both patterns in a single workflow. Use Cases by Model GPT-transcribe Use GPT-transcribe when the application needs accurate text transcripts from recorded, uploaded, or submitted audio. It is a strong fit for meeting and call transcription, media transcription, customer support intake, voicemail and message processing, quality review, compliance workflows, and domain-specific transcription where short utterances, structured alphanumeric details, specialized terminology, accents, background noise, code-mixed speech, or quiet audio can affect downstream accuracy. GPT-live-transcribe Use GPT-live-transcribe when the application needs live streaming transcription with low latency. It is designed for real-time captions, accessibility experiences, contact center transcription, voice-enabled workflows, live monitoring, operational dashboards, and agent-assist scenarios where spoken input needs to become text continuously as the interaction unfolds. Pricing The following pricing example shows Global Standard rates by model and modality. Rates for GPT-realtime-2.1 and GPT-realtime-mini-2.1 are listed per 1 million tokens. GPT-transcribe and GPT-live-transcribe are listed per audio hour. Model Deployment Modality Input Cached Input Output GPT-realtime-2.1 Global Standard Audio $32.00 $0.40 $64.00 Text $4.00 $0.40 $24.00 Image $5.00 $0.50 -- GPT-realtime-mini-2.1 Global Standard Audio $10.00 $0.30 $20.00 Text $0.60 $0.06 $2.40 Image $0.80 $0.08 -- GPT-live-transcribe Global Standard Audio -- -- $1.02/hour GPT-transcribe Global Standard Audio -- -- $0.27/hour Getting Started Choose GPT-transcribe when your application processes complete audio files asynchronously, or GPT-live-transcribe when it needs text continuously as speech arrives. Try the models in Microsoft Foundry, then use the resources below to explore the Realtime API, follow the audio quickstart, compare available models, and review Azure OpenAI in Foundry Models documentation. For asynchronous transcription, submit a complete audio file to GPT-transcribe and process the returned transcript after the request completes. This pattern works well for recordings, voicemails, and uploaded media. For streaming transcription, open a Realtime API session with GPT-live-transcribe, send audio as it is captured, and handle incremental transcript events. This pattern supports live captioning and agent-assist experiences that need text during an active interaction. Refer to the linked quickstart and Realtime API documentation for current SDK setup, authentication, request schemas, and supported audio formats. Explore Microsoft Learn documentation to learn more: Use GPT Realtime API for speech and audio with Azure OpenAI in Foundry Models GPT Realtime audio quickstart Azure OpenAI in Foundry Models overview4KViews0likes0CommentsPost-Stream Refinement is now generally available in Microsoft Foundry
When we introduced Post-Stream Refinement in public preview earlier this year, it closed the oldest trade-off in real-time speech: you could finally keep instant streaming results and get a highly accurate final transcript, with no penalty to first-token latency. A second recognition pass runs in parallel with streaming and replaces each final segment with a more accurate version once the utterance completes. Today, Post-Stream Refinement reaches general availability for Azure AI Speech in Microsoft Foundry, backed by a production SLA. Just as important, it now ships with the capabilities production transcription actually depends on: diarization to preserve who said what, phrase lists for your product names and domain vocabulary, and a much wider footprint of 19 locales across 22 Azure regions. Everything you already know about Post-Stream Refinement still applies. The real-time contract is unchanged, your partial results stream exactly as before, and you enable refinement by setting a single property on your existing SpeechConfig. What changes at GA is that the refined transcript is now production-grade and speaker-aware. 📖 Read the Documentation What's new at general availability If you have already used Post-Stream Refinement in preview, here is exactly what changes at GA, and what stays the same. The streaming path and SDK contract are untouched; the refinement pass is now production-ready and gains speaker and vocabulary features. How Post-Stream Refinement works Real-time and final results serve different needs. Partial results must appear quickly so captions, voice interfaces, and agent turn-taking stay responsive. Final results need enough context to support storage, search, summarization, and business workflows. Post-Stream Refinement runs both at once: a fast streaming pass and a deeper refinement pass over the same audio, in parallel. Because the two passes share one input stream, enabling refinement does not require a second transcription job or a separate client pipeline. Your existing recognition events and partial-result handling stay exactly as they are. Speaker attribution with diarization New at GA, diarization is supported on the Post-Stream Refinement path, so the refined final transcript keeps its speaker labels. That makes the release a strong fit for meetings, contact centers, interviews, and any workflow where the transcript needs to identify who spoke, not just what was said. The refinement pass improves the wording, including proper nouns and named entities, while every utterance stays attributed to the right speaker. Phrase lists for your vocabulary Phrase lists let the recognizer prioritize the names and terms that matter to your application: product catalogs, medical and technical vocabulary, organization names, and acronyms that general speech models might not recognize consistently. At GA you can pair phrase lists with refinement so the second pass has both broad audio context and your domain vocabulary to draw on, which is where the largest accuracy gains on named entities show up. Quality impact In internal testing and partner evaluations across supported locales, Post-Stream Refinement reduced final-transcript word error rate by double-digit relative percentages compared with standard real-time transcription, with the largest gains on the hardest content: long utterances, proper nouns, and domain-specific speech. Pairing phrase lists with refinement improves named-entity accuracy further. Partial-result latency is unchanged; only the final transcript is refined. The refined final result may add a small amount of latency to the final segment because refinement happens after the segment audio is received. Partial results are unaffected. Supported languages and regions General availability supports 19 locales. You declare one locale per session, so the service is tuned to the language you expect. Alongside the Tier-1 languages, GA adds Indic locales, including Bengali, Marathi, Punjabi, and Telugu. Post-Stream Refinement is generally available in 22 Azure regions across the Americas, Europe, and Asia Pacific. Proven at Microsoft scale The technology behind Post-Stream Refinement already powers meeting transcription and Microsoft 365 Copilot experiences in Microsoft Teams, serving millions of users across meetings, webinars, and live events every day. General availability brings the same quality bar to every Azure AI Speech customer through a supported SDK integration, not a research prototype. Preview customers across industries, including automotive, consumer electronics, and aviation, reported positive gains in transcription quality, with the clearest improvements on the hardest content: proper nouns, long-form speech, and domain-specific audio. Several are now moving those workloads into production on the GA release. Get started Enabling Post-Stream Refinement is a small configuration change on your existing SpeechConfig. You will need: Speech SDK 1.50 or later. Earlier versions do not support the refinement path. A Speech resource in one of the supported regions listed above. The session locale you expect, set on the recognizer. Set the post-processing option to PostRefinement. The example below also shows the optional phrase list for your domain vocabulary. import azure.cognitiveservices.speech as speechsdk speech_config = speechsdk.SpeechConfig( subscription="YourSpeechKey", region="YourSpeechRegion") # Declare one locale for the session speech_config.speech_recognition_language = "en-US" # 1) Refine the final transcript (Post-Stream Refinement) speech_config.set_property( speechsdk.PropertyId.SpeechServiceResponse_PostProcessingOption, "PostRefinement") audio_config = speechsdk.AudioConfig(use_default_microphone=True) recognizer = speechsdk.SpeechRecognizer( speech_config=speech_config, audio_config=audio_config) # 2) (Optional) Phrase list for names, acronyms, and domain terms phrase_list = speechsdk.PhraseListGrammar.from_recognizer(recognizer) for term in ["Contoso", "Fabrikam", "Foundry", "OAuth"]: phrase_list.addPhrase(term) Your existing recognition events and partial-result handling remain unchanged. For speaker attribution, enable diarization through the established real-time diarization path; refinement applies to the final transcript while speaker labels are preserved. Choose the right release for your workload Post-Stream Refinement now has two paths. They are the same product family with a different feature boundary, so match the path to what your customer needs. Monolingual PSR — generally available Multilingual PSR — public preview Language selection One locale declared per session Automatic detection and code-switching in a single stream (open-range, no locale declared) Supported locales 19 locales, including Indic bn / mr / pa / te 25 languages / 29 locales, auto-detected Azure regions 22 Azure regions across the Americas, Europe, and Asia Pacific 6 Azure regions Phrase lists & diarization Supported Only diarization is supported Working across languages? If a single stream needs to handle multiple languages or code-switching without a declared locale, use Multilingual Post-Stream Refinement, now in public preview. For a known session locale with phrase lists and diarization, monolingual GA is the right path. Try Post-Stream Refinement Today Turn on higher-accuracy, language-aware transcription in your Azure AI Speech applications with a single configuration change. 📖 Read the Documentation We would love your feedback. Try Post-Stream Refinement in your applications and tell us how it improves your transcription quality.954Views0likes0CommentsFor the first time, real-time transcription goes multilingual
When we introduced Post-Stream Refinement earlier this year, it closed the oldest gap in real-time speech: you could finally get instant streaming results and a highly accurate final transcript, with no latency penalty. But it kept one hard requirement — you had to tell the service, up front, which single language to expect. Real-world speech does not work that way. People code-switch mid-sentence, product and brand names cross languages, and a global app serves users who simply speak differently from one session to the next. Today we remove that requirement. Multilingual Post-Stream Refinement enters public preview for Azure AI Speech in Microsoft Foundry, and for the first time ever a single real-time stream can transcribe multiple languages in one session — the spoken language is detected automatically, no locale is declared in advance, and the final transcript is refined for accuracy. Everything you already know about Post-Stream Refinement still applies; what changes is that the refinement pass itself is now multilingual. 📖 Read the Documentation What's New in This Release If you have already used Post-Stream Refinement, here is exactly what changes with the multilingual preview — and what stays the same: Quality Impact In internal testing and partner evaluations across Tier-1 locales, multilingual Post-Stream Refinement reduced word error rate (WER) by approximately 10% relative on average, with double-digit relative reductions on the hardest cases — long utterances, proper nouns, and multilingual or code-switched speech. Partial-result latency is unchanged; only the final transcript is refined. Gains are relative reductions versus the standard real-time model and vary by language, acoustic conditions, and content type. The refined final result may add a small amount of latency to the final segment; partial results are unaffected. Supported Languages and Regions The public preview supports 15 Tier-1 locales. Because language is detected automatically, a single stream can contain any mix of them: Available in these Azure regions: Real-World Impact Preview customers across industries — including travel, consumer electronics, automotive, aviation, and media — have reported positive gains in transcription quality. Customers testing multilingual and domain-specific audio have observed the clearest improvements on the hardest content: proper nouns, code-switching, and long-form speech. Several are actively validating the feature on their own audio ahead of general availability. Get Started Enabling multilingual Post-Stream Refinement is a small configuration change on your existing SpeechConfig. You will need: Speech SDK 1.50 or later. Earlier versions do not support the multilingual path. A Speech resource in one of the supported regions listed above. Auto-detect language configuration (open range) so the service identifies the language from the audio — no candidate list required. Set the post-processing option to PostRefinement and pass an open-range AutoDetectSourceLanguageConfig when you create the recognizer. Here is a complete, copy-paste Python example, including the optional end-of-utterance detection line: import azure.cognitiveservices.speech as speechsdk speech_config = speechsdk.SpeechConfig( subscription="YourSpeechKey", region="YourSpeechRegion") # 1) Refine the final transcript (Post-Stream Refinement) speech_config.set_property( speechsdk.PropertyId.SpeechServiceResponse_PostProcessingOption, "PostRefinement") # 2) Multilingual auto-detect - no candidate language list needed auto_detect_config = speechsdk.languageconfig.AutoDetectSourceLanguageConfig() audio_config = speechsdk.AudioConfig(use_default_microphone=True) recognizer = speechsdk.SpeechRecognizer( speech_config=speech_config, auto_detect_source_language_config=auto_detect_config, audio_config=audio_config) 💡 Tip: Refinement matters most for applications that store or process the final transcript — meeting notes, call analytics, compliance archives, AI summarization. If you only use partial results for a live display and discard them, your real-time UX (already fast) is unchanged, while any final transcript you keep improves. Try Multilingual Post-Stream Refinement Today Turn on higher-accuracy, language-aware transcription in your Azure AI Speech applications with a single configuration change. Available now in public preview in Microsoft Foundry. 📖 Read the Documentation We would love your feedback. Try Post-Stream Refinement in your applications and tell us how it improves your transcription quality.925Views0likes0CommentsEvaluate before you ship: introducing the Voice Live Evaluation Harness
You've built a voice agent on Azure Voice Live. It demos beautifully. Then a teammate asks the question that keeps every voice-agent team up at night: "How do we know it's actually good — across 200 customer calls, not the three we just listened to?" Until today, the honest answer was: put on headphones. Manual listening. Subjective scoring in a spreadsheet. No baseline, no regression signal, no way to defend a model swap with data. We're releasing the Voice Live Evaluation Harness to change that. It's an open-source, deployable evaluation pipeline that runs pre-recorded multi-turn audio through your Voice Live agent and scores every turn with the same evaluators built into Microsoft Foundry — automatically, repeatably, and in parallel. TL;DR Two flavors, one repo. Run the CLI harness locally against a Foundry project for fast iteration, or deploy the evaluation agent into your Azure subscription with the Azure Developer CLI (azd) for a fully-hosted evaluation backend. 13 built-in evaluators score every turn — intent resolution, task adherence, task completion, response completeness, tool-call accuracy, groundedness, and more — viewable per-turn and in aggregate inside the Foundry portal. Supports the three Voice Live modes you actually ship in — Semantic VAD, Push-to-Talk, and Foundry Agent mode — including multi-turn conversations with tool calls and grounding. Grows with your agent. Start with the sample datasets, then layer in audio collected from user testing and production traffic so your evaluation set matures alongside the agent. 🔗 Repo: microsoft-foundry/voicelive-evaluation · Docs: Evaluate Voice Live agents (preview) Why systematic evaluation matters for voice agents Text agents have a mature evaluation story. Voice agents don't — and the gaps actually matter more, because every voice failure happens in real time, in front of a customer, on a phone line you can't easily replay. The Voice Live Evaluation Harness closes that gap with four concrete capabilities: Establish a quality baseline. Run a representative audio dataset through your agent and get scores you can publish as your launch bar. Compare configurations side-by-side. Swap the underlying model (GPT-Realtime 1.5, Azure-Realtime, MAI-Transcribe-1.5), change the voice, tune VAD thresholds — and see exactly which knobs moved which scores. Catch regressions before users do. Wire it into CI and fail the build when intent resolution drops below your threshold. Optimize with data, not vibes. When task-completion drops, drill into the per-turn scores to see whether the agent failed to call the right tool, misunderstood intent, or generated an incomplete response. Keep iterating as production data rolls in. Start with the sample datasets, then grow your evaluation set with audio captured from internal testing, pilot users, and real production traffic. Re-run after every prompt tweak or model swap so the harness becomes a continuous quality signal — not a one-time launch checklist. How it works The pipeline is a five-stage loop: Audio Dataset. Multi-turn audio + expected behaviors in a simple JSONL schema. Four sample datasets ship in the repo (travel planning, complex data analytics, tool-calling tests, batch multi-conversation) so you can run end-to-end on day one. Voice Live API. Pick your Voice Live mode (Semantic VAD, PTT, or Foundry Agent), model, voice, and turn-detection settings via a JSON config file, then stream each turn of audio through the API — locally with the CLI harness, or, if you've deployed the evaluation agent, via the hosted Container App for long-running batches in your own subscription. Transcript + Response. Every turn produces an agent transcript, the model's response, and any tool calls it made — captured automatically for scoring. Foundry Evaluators. 13 built-in evaluators — powered by the same Foundry evaluator models (GPT-4.1-mini and o4-mini) used across Microsoft Foundry — judge every turn on intent resolution, task adherence, tool-call accuracy, groundedness, and more. Quality Scores. Per-turn and aggregate scores land in the Microsoft Foundry portal under your project's Evaluation tab — sortable, filterable, comparable across runs. Then loop. Audio captured from internal testing, pilots, and production traffic feeds back into the dataset — each pass makes the next evaluation more representative of what users actually do. What gets measured The accelerator ships 13 built-in evaluators out of the box, covering the dimensions that matter most for production voice agents: Category Evaluators Intent & task quality Intent Resolution · Task Adherence · Task Completion · Response Completeness Tool calling Tool Call Accuracy · Tool Call Parameter Validity · Tool Result Usage · Tool Call Success Content quality Groundedness · Relevance · Fluency · Coherence Conversational dynamics Turn-taking quality Every evaluator runs against the same Foundry evaluator models (GPT-4.1-mini and o4-mini) that power evaluation across the rest of Microsoft Foundry — so your voice-agent scores are directly comparable to your text-agent scores. Run the CLI locally against your existing Voice Live endpoint If you already have a Voice Live agent deployed and just want fast iteration on a laptop: git clone https://github.com/microsoft-foundry/voicelive-evaluation.git cd voicelive-evaluation/evaluation_harness python -m venv .venv && source .venv/bin/activate pip install -r requirements.txt cp .sample_env .env # Edit .env with your AZURE_VOICELIVE_ENDPOINT python voice_agent_evaluation.py \ --config configs/sample_vad_realtime.json The full walkthrough — dataset schema, configuration reference, score interpretation, and troubleshooting — is in the documentation. Get started Repo: microsoft-foundry/voicelive-evaluation Docs: How to evaluate Voice Live agents (preview) We'd love your feedback — try it, file issues, and tell us which evaluators you wish you had.638Views0likes0CommentsModel Mondays S2E11: Exploring Speech AI in Azure AI Foundry
1. Weekly Highlights This week’s top news in the Azure AI ecosystem included: Lakuna — Copilot Studio Agent for Product Teams: A hackathon project built with Copilot Studio and Azure AI Foundry, Lakuna analyzes your requirements and docs to surface hidden assumptions, helping teams reflect, test, and reduce bias in product planning. Azure ND H200 v5 VMs for AI: Azure Machine Learning introduced ND H200 v5 VMs, featuring NVIDIA H200 GPUs (over 1TB GPU memory per VM!) for massive models, bigger context windows, and ultra-fast throughput. Agent Factory Blog Series: The next wave of agentic AI is about extensibility: plug your agents into hundreds of APIs and services using Model Connector Protocol (MCP) for portable, reusable tool integrations. GPT-5 Tool Calling on Azure AI Foundry: GPT-5 models now support free-form tool calling—no more rigid JSON! Output SQL, Python, configs, and more in your preferred format for natural, flexible workflows. Microsoft a Leader in 2025 Gartner Magic Quadrant: Azure was again named a leader for Cloud Native Application Platforms—validating its end-to-end runway for AI, microservices, DevOps, and more. 2. Spotlight On: Azure AI Foundry Speech Playground The main segment featured a live demo of the new Azure AI Speech Playground (now part of Foundry), showing how developers can experiment with and deploy cutting-edge voice, transcription, and avatar capabilities. Key Features & Demos: Speech Recognition (Speech-to-Text): Try real-time transcription directly in the playground—recognizing natural speech, pauses, accents, and domain terms. Batch and Fast transcription options for large files and blob storage. Custom Speech: Fine-tune models for your industry, vocabulary, and noise conditions. Text to Speech (TTS): Instantly convert text into natural, expressive audio in 150+ languages with 600+ neural voices. Demo: Listen to pre-built voices, explore whispering, cheerful, angry, and more styles. Custom Neural Voice: Clone and train your own professional or personal voice (with strict Responsible AI controls). Avatars & Video Translation: Bring your apps to life with prebuilt avatars and video translation, which syncs voice-overs to speakers in multilingual videos. Voice Live API: Voice Live API (Preview) integrates all premium speech capabilities with large language models, enabling real-time, proactive voice agents and chatbots. Demo: Language learning agent with voice, avatars, and proactive engagement. One-click code export for deployment in your IDE. 3. Customer Story: Hilo Health This week’s customer spotlight featured Helo Health—a healthcare technology company using Azure AI to boost efficiency for doctors, staff, and patients. How Hilo Uses Azure AI: Document Management: Automates fax/document filing, splits multi-page faxes by patient, reduces staff effort and errors using Azure Computer Vision and Document Intelligence. Ambient Listening: Ambient clinical note transcription captures doctor-patient conversations and summarizes them for easy EHR documentation. Genie AI Contact Center: Agentic voice assistants handle patient calls, book appointments, answer billing/refill questions, escalate to humans, and assist human agents—using Azure Communication Services, Azure Functions, FastAPI (community), and Azure OpenAI. Conversational Campaigns: Outbound reminders, procedure preps, and follow-ups all handled by voice AI—freeing up human staff. Impact: Hilo reaches 16,000+ physician practices and 180,000 providers, automates millions of communications, and processes $2B+ in payments annually—demonstrating how multimodal AI transforms patient journeys from first call to post-visit care. 4. Key Takeaways Here’s what you need to know from S2E11: Speech AI is Accessible: The Azure AI Foundry Speech Playground makes experimenting with voice recognition, TTS, and avatars easy for everyone. From Playground to Production: Fine-tune, export code, and deploy speech models in your own apps with Azure Speech Service. Responsible AI Built-In: Custom Neural Voice and avatars require application and approval, ensuring ethical, secure use. Agentic AI Everywhere: Voice Live API brings real-time, multimodal voice agents to any workflow. Healthcare Example: Hilo’s use of Azure AI shows the real-world impact of speech and agentic AI, from patient intake to after-visit care. Join the Community: Keep learning and building—join the Discord and Forum. Sharda's Tips: How I Wrote This Blog I organize key moments from each episode, highlight product demos and customer stories, and use GitHub Copilot for structure. For this recap, I tested the Speech Playground myself, explored the docs, and summarized answers to common developer questions on security, dialects, and deployment. Here’s my favorite Copilot prompt this week: "Generate a technical blog post for Model Mondays S2E11 based on the transcript and episode details. Focus on Azure Speech Playground, TTS, avatars, Voice Live API, and healthcare use cases. Add practical links for developers and students!" Coming Up Next Week Next week: Observability! Learn how to monitor, evaluate, and debug your AI models and workflows using Azure and OpenAI tools. Register For The Livestream – Sep 1, 2025 Register For The AMA – Sep 5, 2025 Ask Questions & View Recaps – Discussion Forum About Model Mondays Model Mondays is your weekly Azure AI learning series: 5-Minute Highlights: Latest AI news and product updates 15-Minute Spotlight: Demos and deep dives with product teams 30-Minute AMA Fridays: Ask anything in Discord or the forum Start building: Register For Livestreams Watch Past Replays Register For AMA Recap Past AMAs Join The Community Don’t build alone! The Azure AI Developer Community is here for real-time chats, events, and support: Join the Discord Explore the Forum About Me I'm Sharda, a Gold Microsoft Learn Student Ambassador focused on cloud and AI. Find me on GitHub, Dev.to, Tech Community, and LinkedIn. In this blog series, I share takeaways from each week’s Model Mondays livestream.565Views0likes0Comments