security
136 Topics
Central pki
Has anyone implemented a centralised PKI where the Root CA is stored in Azure Key Vault and workloads can automatically obtain the Root CA when they are deployed, as well as receive updated versions when the Root CA needs to be rotated or renewed? I’m looking to implement a centralised PKI for an Azure hub-and-spoke architecture, where workloads across the spokes can automatically obtain and trust the Root CA. The workloads could include VMs, AKS, containers, App Services and Azure Functions. I’m aware that Azure Machine Configuration can be used to deploy certificates to VMs, but this is specific to VMs. What is the recommended approach for distributing the Root CA to the other Azure workload types using a consistent and automated mechanism? Ideally, I’d like the solution to be fully automated, so that new workloads receive the current Root CA during deployment and existing workloads automatically receive updated versions whenever the Root CA is rotated or renewed. I will be deploying the root ca in a key vault via terraform a project for the root ca only to update whenever is needed and then each resources to be able to get the latest root ca. Has anyone implemented something similar, or could you provide guidance on the recommended architecture and distribution mechanism?141Views0likes1CommentBookshelf search blocked by Smart App Control (unsigned GRZ runtime)
I am seeing GraphRAG Zero health checks and Bookshelf search fail on Windows 11 when Smart App Control is enabled. Environment - Discovery App: 0.15.14-preview - GRZ runtime: 0.9.0-ci.20260830.3873.1.abbf9992 - OS: Windows 11 - Smart App Control: On when the failure occurred Error ImportError: DLL load failed while importing _socket: An Application Control policy has blocked this file. Windows Code Integrity logs show Event IDs 3033 and 3077. The blocked modules are _internal\_socket.pyd and _internal\_ctypes.pyd, and they and grz-worker.exe are reported as NotSigned. Bookshelf ingestion completes, but GraphRAG semantic search and related chunk retrieval fail. As a diagnostic test, I turned Smart App Control off. GraphRAG search then succeeded. This workaround lowers protection for the entire PC, so I would prefer not to rely on it. Is this a known compatibility issue with Smart App Control? Is a signed GRZ runtime planned, or is there a supported workaround that allows Bookshelf search to work while keeping Smart App Control enabled?Applying Site Reliability Engineering to Autonomous AI Agents
If you practice SRE, you already have a mental model for running reliable production systems. You define SLOs. You track error budgets. You use circuit breakers to stop cascading failures. You run chaos experiments to find weaknesses before customers do. You treat every operational decision as a tradeoff between reliability and velocity. That mental model transfers directly to AI agents. It just needs four new ideas. In the Agent Governance Toolkit: Architecture Deep Dive, Policy Engines, Trust, and SRE for AI Agents, we covered Agent SRE briefly as one of AGT's nine packages: SLOs, error budgets, circuit breakers, chaos engineering, and progressive delivery, adapted from the patterns your SRE team already applies to microservices. Several teams asked for the full story. This is it. Agent SRE is one of the more novel parts of the toolkit. The policy engine, zero-trust identity, and execution sandboxing have clear analogs in existing security practice. Agent SRE explores newer ground. Established patterns for defining SLOs for AI agent behavior, building chaos experiments for LLM provider failures, or applying error budgets to agent autonomy are still emerging across the industry. We built these capabilities because running agents in production without them is the equivalent of running a fleet of microservices without circuit breakers, health checks, or an on-call runbook. This post is for SRE teams, platform engineers, and anyone responsible for running AI agents in production. You do not need to be an AI specialist. If you know what a burn rate is, you are ready for this. The Problem: Agents Fail in Ways Your Existing SRE Tooling Cannot See When a service fails, your observability stack tells you: latency went up, error rate crossed the SLO threshold, the circuit breaker opened. You page the on-call engineer. They look at traces and find the slow database query. When an AI agent fails, your observability stack is silent. The agent returned HTTP 200. Latency was normal. Error rate was zero. But the agent quietly approved a transaction it was not authorized to approve, hallucinated a database path and wrote to the wrong table, or got stuck in a reasoning loop that consumed $800 of LLM API budget before anyone noticed. These are not infrastructure failures. They are behavioral failures. And they are invisible to monitoring tools built for stateless, deterministic services, because those tools only watch for crashes and timeouts. They do not watch for wrong behavior. This gap is the problem Agent SRE was designed to solve. The solution borrows everything from the SRE playbook and adds one concept that extends it: the Safety SLI. The Safety SLI: A New Reliability Dimension Traditional SLIs measure system behavior from the user's perspective: latency, availability, error rate, throughput. They answer: did the service respond correctly? For AI agents, correctness is not enough. An agent that responds correctly but acts outside its authorized scope has not succeeded. It has failed in a way that none of your existing SLIs can detect. The Safety SLI answers a different question: did the agent act within policy? from agent_sre import SLO, ErrorBudget from agent_sre.slo.indicators import PolicyCompliance # Define a safety SLO: 99% of agent actions must comply with policy safety_slo = SLO( name="safety-compliance", indicators=[ PolicyCompliance( target=0.99, window="7d", ), ], error_budget=ErrorBudget( total=0.01, # 1% budget (1 - 0.99 target) window_seconds=2592000, # 30-day window burn_rate_alert=2.0, # warn at 2x sustainable rate burn_rate_critical=5.0, # page at 5x sustainable rate ), ) When an agent's policy compliance rate drops below 99%, the error budget starts burning. The ErrorBudget tracks consumption automatically and exposes burn rate alerts through its firing_alerts() method. When the budget is exhausted, the configured exhaustion_action determines the system response: from agent_sre.slo.objectives import ExhaustionAction # Configure what happens when error budget is exhausted safety_slo = SLO( name="safety-compliance", indicators=[PolicyCompliance(target=0.99, window="7d")], error_budget=ErrorBudget( total=0.01, window_seconds=2592000, burn_rate_alert=2.0, # fires at 2x sustainable burn rate burn_rate_critical=5.0, # fires at 5x sustainable burn rate exhaustion_action=ExhaustionAction.CIRCUIT_BREAK, # suspend agent when budget is gone ), ) # In your monitoring loop, check for firing alerts alerts = safety_slo.error_budget.firing_alerts() for alert in alerts: print(f"Alert firing: {alert.name} (severity: {alert.severity})") # Check budget status print(f"Budget remaining: {safety_slo.error_budget.remaining_percent:.1f}%") print(f"Current burn rate: {safety_slo.error_budget.burn_rate():.2f}x") print(f"Exhausted: {safety_slo.error_budget.is_exhausted}") This is the governance dial from the other direction. The error budget is not just a metric: it is the mechanism that drives agent autonomy decisions. An agent with a clean 30-day safety record earns autonomy. An agent whose budget is burning at 5x the sustainable rate triggers a critical alert, and when the budget is exhausted, the exhaustion_action fires: ALERT, THROTTLE, FREEZE_DEPLOYMENTS, or CIRCUIT_BREAK. The graduated response mirrors what SRE teams already do with service SLOs, applied to agent behavior. There are multiple SLI dimensions built into Agent SRE. Safety SLIs and Performance SLIs track different aspects of the same agent: SLI Type What It Measures Target Pattern When Budget Burns Safety SLI PolicyCompliance -- fraction of actions within authorized scope >= 99% Restrict capabilities, increase human oversight Performance SLI TaskSuccessRate, ResponseLatency, CostPerTask Configurable per workload Alert, throttle, or circuit-break LLM provider Additional built-in indicators include ToolCallAccuracy, DelegationChainDepth, HallucinationRate, and CalibrationDeltaSLI. Both SLOs feed into the same error budget dashboard. An agent can have excellent performance but a degrading safety record, or perfect safety compliance and terrible cost efficiency. You need both dimensions to understand whether an agent is production-ready. Circuit Breakers: Governing Agent Failure Modes That Don't Exist in Microservices Circuit breakers for services protect against one failure mode: a backend that is slow or unreachable. The pattern is CLOSED -> OPEN -> HALF_OPEN. You know it well. Agent SRE implements the same state machine for failure modes that are specific to autonomous reasoning systems and do not exist in traditional microservice architectures: from agent_sre.cascade.circuit_breaker import CircuitBreakerConfig, CircuitBreaker from agent_sre.chaos.engine import FaultType config = CircuitBreakerConfig( failure_threshold=5, # Open after 5 failures in the window recovery_timeout_seconds=60, # Stay OPEN for 60s before HALF_OPEN half_open_max_calls=3, # Allow 3 probes in HALF_OPEN ) breaker = CircuitBreaker(agent_id="analyst-agent-001", config=config) # Failure modes tracked by the circuit breaker: tracked_faults = [ FaultType.POLICY_BYPASS, # Agent exceeds authorized scope FaultType.ERROR_INJECTION, # Upstream model API fails FaultType.TIMEOUT_INJECTION, # Tool calls exceed time budget FaultType.TRUST_PERTURBATION, # Agent trust score falls below threshold FaultType.DEADLOCK_INJECTION, # Agent stuck in iterative reasoning ] Each failure mode has different circuit-breaking semantics: Failure Mode What Triggers It Circuit-Break Behavior Policy bypass Action denied by policy engine Count toward threshold; log with full context LLM provider error HTTP 5xx from model API Immediately open; route to fallback model if configured Tool timeout Tool call exceeds timeout_ms Count toward threshold; cancel in-flight call Trust score degradation Agent trust score drops below configured floor Open; escalate to Ring 3 (untrusted) until score recovers Reasoning loop / deadlock Token or iteration count exceeds budget Open; trigger human review before resuming The reasoning loop breaker deserves attention. A microservice cannot get stuck reasoning. An AI agent absolutely can, and when it does, the failure is not an error code: it is an agent that keeps calling tools, consuming tokens, and generating audit events indefinitely. The circuit breaker detects this pattern from the iteration count and token budget and terminates the loop: # Reasoning loop detection configuration loop_detection_config = { "max_iterations": 15, # Hard stop after 15 reasoning steps "max_tokens_per_session": 50000, # Hard stop on token consumption "repetition_threshold": 0.85, # Stop if >85% of recent actions repeat prior ones "on_detection": "circuit_break_and_escalate", } The state machine behaves identically to what you know from Hystrix or Resilience4j. What changes is the definition of "failure." CLOSED (serving) | | failure_threshold crossed for any tracked fault v OPEN (rejecting -- agent action denied, fallback or human-in-loop fires) | | recovery_timeout expires v HALF_OPEN (probe -- limited requests allowed through) | |-- success_threshold met --> CLOSED |-- any failure --> OPEN (reset timeout) Chaos Engineering for Agents: Fault Injection for Autonomous Systems The only way to know if your agent system is resilient is to break it intentionally. Traditional chaos engineering targets infrastructure: kill a pod, inject network latency, saturate a disk. Agent chaos engineering targets the failure modes specific to autonomous reasoning systems. Agent SRE ships fault injection templates that cover the failure modes teams consistently underestimate until they hit production: from agent_sre.chaos.engine import ChaosExperiment, Fault, FaultType # Experiment 1: LLM provider degrades -- model returns valid responses but with # increased latency and occasional malformed outputs experiment = ChaosExperiment( name="llm-degradation-resilience", target_agent="analyst-agent-001", description="Test agent behavior under degraded LLM provider", faults=[ Fault.latency_injection(target="llm-provider", delay_ms=8000), Fault.error_injection(target="llm-provider", rate=0.05), ], duration_seconds=300, ) # Experiment 2: Trust score manipulation -- simulates an agent receiving # messages from a peer with a spoofed trust score trust_experiment = ChaosExperiment( name="trust-manipulation-resilience", target_agent="orchestrator-001", faults=[ Fault( fault_type=FaultType.TRUST_PERTURBATION, target="did:mesh:orchestrator-001", params={"spoofed_score": 950}, ), ], duration_seconds=120, ) # Experiment 3: Tool timeout cascade -- multiple tools time out simultaneously, # testing whether the agent abandons gracefully or enters a reasoning loop cascade_experiment = ChaosExperiment( name="tool-timeout-cascade", target_agent="analyst-agent-001", faults=[ Fault.timeout_injection(target="database.read", delay_ms=30000), Fault.timeout_injection(target="api.call", delay_ms=30000), ], duration_seconds=180, ) # Run the experiment experiment.start() # ... inject faults during agent execution ... resilience = experiment.calculate_resilience( baseline_success_rate=0.95, experiment_success_rate=0.87, recovery_time_ms=48000, ) experiment.complete(resilience=resilience) print(f"Resilience score: {resilience.overall}/100 -- {'PASSED' if resilience.passed else 'FAILED'}") Additional fault types built into the chaos engine cover: prompt injection attempts, privilege escalation, data exfiltration attempts, identity spoofing, deadlock injection, and contradictory instruction scenarios. Each maps to a FaultType enum value and can be composed into multi-fault experiments. Important: The chaos engine records that a fault was injected and triggers the governance response pipeline. Actual infrastructure-level fault injection (network partition, process kill) should be implemented using your existing chaos tooling (Chaos Mesh, Gremlin, Azure Chaos Studio, or similar). Agent SRE governs the agent's behavioral response to faults; it does not own infrastructure manipulation. These two layers are designed to compose. Each chaos experiment produces a structured resilience score via calculate_resilience(), which compares baseline and experiment success rates. A score of 90+ with passed=True means the agent maintained at least 90% of its baseline performance under fault conditions. Teams use this to set minimum resilience thresholds for production readiness. Replay Debugging: Reproduce Behavioral Failures Exactly Infrastructure incidents are reproducible because infrastructure is deterministic. AI agent incidents are hard to reproduce because agent behavior depends on model state, context window content, and the sequence of tool call results, none of which are preserved by default after a session ends. Agent SRE's replay engine records every agent session as a replayable artifact: the full trace at each step, every tool call with its inputs and outputs, every policy evaluation with its decision, and every trust score at the time of each inter-agent message. from agent_sre.replay.capture import TraceStore from agent_sre.replay.engine import ReplayEngine, ReplayMode # Traces are captured automatically when SRE tracing is active store = TraceStore( backend="azure_blob", retention_days=30, ) # When an incident occurs, replay the session exactly engine = ReplayEngine(store=store) # Full replay: re-run the session against the same recorded inputs # Uses recorded tool outputs -- no live tool calls -- so replay is deterministic result = await engine.replay( trace_id="trace_2026_05_a7f3b2", mode=ReplayMode.FULL, ) for step in result.steps: print(f"Step {step.index}: {step.action} -> {step.decision}") # Divergence analysis: replay with a policy change applied # Shows exactly which actions would have been blocked under the new policy diff_result = await engine.diff( trace_id="trace_2026_05_a7f3b2", policy_override="policies/stricter-v2.yaml", ) for diff in diff_result.diffs: if diff.description: print(f"Step {diff.span_name}: was {diff.original}, " f"would be {diff.replayed} under new policy") The divergence analysis is the feature teams use most. When a policy change is proposed, you replay recent production traces against the new policy to see how many actions would have been blocked, which sessions would have failed, and what the error budget impact would have been. Policy changes stop being guesswork. Progressive Delivery: Safely Rolling Out New Agent Capabilities When you ship a new service version, you do not send it to all traffic at once. You use canary deployments, feature flags, or traffic splitting. You watch the SLOs. If they degrade, you roll back. Agent SRE brings the same discipline to agent capability rollout. When you expand an agent's authorized scope, giving it write access it did not have, connecting it to a new tool, or raising its trust floor, you do not expand to the full fleet immediately. You expand progressively, with automated SLO gates controlling each stage. from agent_sre.delivery.rollout import ( AnalysisCriterion, CanaryRollout, RollbackCondition, RolloutStep, ) rollout = CanaryRollout( name="database-write-capability", steps=[ RolloutStep( name="canary", weight=0.05, # 5% of agents get the new capability duration_seconds=86400, # 24 hours analysis=[ AnalysisCriterion(metric="safety_sli", threshold=0.995), AnalysisCriterion(metric="performance_sli", threshold=0.90), AnalysisCriterion( metric="error_budget_consumed", threshold=0.10, comparator="lte", # canary can burn at most 10% ), ], ), RolloutStep( name="early-adopters", weight=0.25, # 25% traffic duration_seconds=172800, # 48 hours analysis=[ AnalysisCriterion(metric="safety_sli", threshold=0.990), AnalysisCriterion(metric="performance_sli", threshold=0.88), ], ), RolloutStep( name="general-availability", weight=1.0, # 100% traffic duration_seconds=604800, # 1 week of full observation analysis=[ AnalysisCriterion(metric="safety_sli", threshold=0.990), AnalysisCriterion(metric="performance_sli", threshold=0.85), ], ), ], rollback_conditions=[ RollbackCondition(metric="safety_sli", threshold=0.95, comparator="lte"), ], ) # Start the rollout -- SLO gates evaluate at each step rollout.start() # Advance to next step when analysis criteria pass if rollout.advance(): print(f"Advanced to step: {rollout.current_step.name}") print(f"Progress: {rollout.progress_percent:.0f}%") The SLO gate at each step is the same mechanism as a CI/CD quality gate, but measured on live production behavior rather than test results. An agent capability that degrades the safety SLI during canary does not promote to the next step. If a RollbackCondition fires, the rollout rolls back automatically. This is the mechanism that makes it operationally safe to expand agent autonomy: every expansion is measurable, every measurement gates the next expansion, and rollback is automatic. Health Checks and Backpressure Traditional health checks answer: is the service alive? For agents, alive is not enough. A healthy agent is one that is alive, operating within policy, consuming resources within budget, and maintaining a trust score above the Ring threshold it was assigned. # Agent health check covering multiple dimensions health = await agent_health_check( agent_id="analyst-agent-001", dimensions=[ "liveness", # Is the agent process running? "policy_compliance", # Is safety SLI above threshold? "trust_score", # Is trust score above Ring floor? "resource_budget", # Is token/API spend within limits? "tool_availability", # Are the tools the agent needs reachable? ], ) # health.status: "healthy" | "degraded" | "unhealthy" # health.dimensions: per-dimension pass/fail with values # health.recommended_action: "none" | "restrict" | "suspend" | "terminate" When health checks report degradation, backpressure controls engage before the circuit breaker opens. Backpressure is the earlier, softer response: accept fewer concurrent tasks, reject low-priority work, drain in-flight tasks gracefully before the situation escalates. # Backpressure configuration backpressure_config = { "backpressure_threshold": 0.80, # Engage when resource utilization > 80% "max_concurrent": 5, # Hard cap on simultaneous agent tasks "priority_shedding": True, # Drop low-priority tasks first "drain_timeout_seconds": 30, # Allow in-flight tasks to complete } The ordering matters: backpressure first, then circuit breaker, then suspension. Each stage is recoverable. Each stage preserves more agent state than the next. The SRE principle of graduated response applies to agents exactly as it applies to services. Observability: Governance Metrics Flow Into Your Existing Stack Agent SRE does not ask you to adopt a new observability platform. Governance metrics are exported through the same adapters your infrastructure monitoring already uses, including OpenTelemetry, Prometheus, Datadog, and others. from agent_sre.tracing.exporters import configure_exporters configure_exporters( backends=[ {"type": "prometheus", "endpoint": "http://prometheus:9090"}, {"type": "opentelemetry", "endpoint": "http://otel-collector:4317"}, ], include_metrics=[ "slo.safety_sli", # Per-agent safety compliance rate "slo.error_budget_remaining", # Error budget in percentage "slo.burn_rate", # Current burn rate vs sustainable "circuit_breaker.state", # CLOSED / OPEN / HALF_OPEN "circuit_breaker.failure_count", "trust_score.current", # Agent trust score (0-1000) "trust_score.ring", # Current execution ring "chaos.experiments_run", # Chaos experiment telemetry "health.status", # Aggregate health status "backpressure.load", # Current load vs threshold ], ) Key governance metrics available in your existing dashboards: Metric What It Tells You Alert Condition slo.safety_sli Fraction of agent actions within policy < 0.99 slo.burn_rate Rate at which error budget is consumed > 2.0 (warn), > 5.0 (page) slo.error_budget_remaining Budget left for the SLO window < 20% circuit_breaker.state Current breaker state per agent OPEN or HALF_OPEN trust_score.ring Execution ring (privilege level) Ring 3 (untrusted) health.status Aggregate health across all dimensions degraded or unhealthy If you are already running Grafana dashboards for your services, a governance dashboard for your agent fleet is a new data source and a new set of panels, not a new monitoring stack. The SRE Mental Model for Agents: Four New Concepts Everything in Agent SRE is built on the SRE mental model you already have, extended with four concepts that adapt traditional reliability thinking for autonomous systems: Traditional SRE Agent SRE Equivalent What Changes Latency SLI Safety SLI Correctness of *action*, not speed of *response* Error budget Autonomy budget Burns on policy violations, not just errors Circuit breaker Behavioral circuit breaker Opens on wrong *behavior*, not just failure codes Canary deployment Capability rollout Rolls out *scope*, not just code The governance insight is that error budgets work in both directions for agents. A service's error budget only decreases. An agent's autonomy is also a budget: it grows when the safety SLI is strong and shrinks when it degrades. The error budget mechanism becomes the operational mechanism for expanding and contracting agent autonomy in response to evidence, which is exactly what regulated industries and risk-averse enterprise teams need before they will trust an autonomous agent with consequential actions. Getting Started with Agent SRE pip install agent-sre A minimal Agent SRE integration requires three things: a safety SLO definition, a circuit breaker, and a health check. The progressive delivery and chaos engineering features layer on top when you are ready for them. from agent_sre import SLO, ErrorBudget from agent_sre.slo.indicators import TaskSuccessRate from agent_sre.cascade.circuit_breaker import CircuitBreakerConfig, CircuitBreaker # Step 1: Define your safety SLO slo = SLO( name="production-safety", indicators=[TaskSuccessRate(target=0.99, window="24h")], error_budget=ErrorBudget(total=0.01, burn_rate_alert=2.0, burn_rate_critical=5.0), ) # Step 2: Configure a circuit breaker breaker_config = CircuitBreakerConfig( failure_threshold=5, recovery_timeout_seconds=60, half_open_max_calls=3, ) breaker = CircuitBreaker(agent_id="my-agent", config=breaker_config) # Step 3: Wire into your existing agent loop async def governed_agent_loop(agent, task): # Check health first if not await agent_is_healthy(agent.id): return {"error": "agent suspended", "reason": "health check failed"} # Run within circuit breaker protection async with breaker: result = await agent.run(task) slo.record_event(good=result.policy_compliant) return result The quickstart in the repository walks through a complete setup with safety SLOs, circuit breakers, and a Prometheus dashboard export in under 50 lines. Why This Matters Most AI observability tools today focus on what you might call model quality: hallucination rate, latency, token cost, task completion. These are useful metrics. They are not SRE metrics. They do not answer whether the agent acted within its authorized scope, whether its behavioral error budget is burning at a dangerous rate, or whether it would survive the LLM provider going down. Agent SRE answers those questions using the operational vocabulary that SRE teams already understand: SLOs, error budgets, circuit breakers, chaos experiments, and health checks. The goal is not to replace your observability stack. It is to make agent governance visible inside it. The reliability of an autonomous agent is not a property of the model. It is a property of the governance infrastructure around it. Agent SRE is that infrastructure. Resources GitHub: github.com/microsoft/agent-governance-toolkit Install: pip install agent-sre Tutorials: 40+ tutorials including dedicated Agent SRE walkthroughs for SLO setup, chaos experiments, and progressive delivery Architecture reference: ARCHITECTURE.md OWASP compliance mapping: OWASP-COMPLIANCE.md -- Agent SRE addresses ASI-08 (Cascading Failures) directly through circuit breakers and SLO-based fault detection Part 1 -- Runtime governance: Policy engines, trust, and SRE overview Part 2 -- Shift-left governance: Catching violations before production Part 3 -- Post-hoc accountability: After the agent acts The Agent Governance Toolkit is an open-source project released under the MIT License. All features described in this post are available in the public repository. The `agent-sre` package is currently in public preview; APIs may change before general availability. Questions about Agent SRE in your environment? Open an issue at aka.ms/agent-governance-toolkit or start a discussion in the comments below.1.2KViews1like1CommentWho Can Access What? Designing RBAC and Identity in Azure
Who should be allowed to access an Azure resource? Azure makes it easy to create resources. The harder question comes afterwards: who should be allowed to access them? A Function App may need to read secrets from Key Vault. A Logic App may need to call APIs through API Management. A developer may need to deploy to Dev but have no access to Production. A CI/CD pipeline may need to deploy infrastructure without becoming an Owner of the entire subscription. This is where Azure Role-Based Access Control (RBAC) and Managed Identity become critical. In this article, I look at how to design access around people, applications and deployment pipelines, while keeping permissions as narrow as practical. The article covers: Azure RBAC and access scopes Least-privilege access Managed Identities Developer vs Production access boundaries Application identities CI/CD deployment permissions RBAC vs API authentication Privileged access and PIM Common RBAC design mistakes One of the key principles is simple: Give an identity only the permissions it actually needs. For example, if a Function App only needs to read secrets from Key Vault, giving it Contributor access to the entire Resource Group solves the problem with a much broader permission than necessary. Good RBAC design is not about assigning more permissions. It is about understanding: Who needs access? Why do they need it? What exactly do they need to do? At what scope should access be granted? How can that access be managed securely over time? I would be interested to hear how others approach RBAC and identity design in enterprise Azure environments. Full article: https://www.linkedin.com/pulse/who-can-access-what-designing-rbac-identity-azure-chethan-raj-ud6gc/165Views0likes0Comments
Support Live Session Migration for Windows 11 Enterprise Multi-Session AVD Hosts
Description Azure Virtual Desktop administrators regularly encounter maintenance scenarios where a Windows 11 Enterprise Multi-Session session host must be removed from service to apply urgent patches, investigate platform issues, replace a host, or perform emergency maintenance. The current approach requires placing the session host into drain mode and waiting for active user sessions to disconnect or forcing user logoff, which can disrupt productivity and user experience. It would be valuable if Azure Virtual Desktop supported live migration of active user sessions between Windows 11 Enterprise Multi-Session hosts within the same host pool, similar to the way virtual machine live migration minimises downtime during infrastructure maintenance. This capability would allow administrators to move active sessions from one session host to another without requiring user disconnection or application interruption. This feature would provide significant operational benefits, including: Reduced user disruption during planned and emergency maintenance. Faster remediation of unhealthy or degraded session hosts. Improved patching and update operations. Reduced dependency on large maintenance windows. Improved service availability for business-critical AVD environments. Better support for future hot patching and rolling maintenance scenarios. While Windows 11 Enterprise Multi-Session differs significantly from Windows Server and traditional VM live migration technologies, the ability to seamlessly relocate active user sessions between healthy hosts in a host pool would be a major enhancement for enterprise Azure Virtual Desktop deployments operating at scale.155Views5likes0CommentsFrom Policy to Practice: Built-In CIS Benchmarks on Azure - Flexible, Hybrid-Ready
Security is more important than ever. The industry-standard for secure machine configuration is the Center for Internet Security (CIS) Benchmarks. These benchmarks provide consensus-based prescriptive guidance to help organizations harden diverse systems, reduce risk, and streamline compliance with major regulatory frameworks and industry standards like NIST, HIPAA, and PCI DSS. In our previous post, we outlined our plans to improve the Linux server compliance and hardening experience on Azure and shared a vision for integrating CIS Benchmarks. Today, that vision has turned into reality. We're now announcing the next phase of this work: Center for Internet Security (CIS) Benchmarks are now available on Azure for all Azure endorsed distros, at no additional cost to Azure and Azure Arc customers. With today's announcement, you get access to the CIS Benchmarks on Azure with full parity to what’s published by the Center for Internet Security (CIS). You can adjust parameters or define exceptions, tailoring security to your needs and applying consistent controls across cloud, hybrid, and on-premises environments - without having to implement every control manually. Thanks to this flexible architecture, you can truly manage compliance as code. How we achieve parity To ensure accuracy and trust, we rely on and ingest CIS machine-readable Benchmark content (OVAL/XCCDF files) as the source of truth. This guarantees that the controls and rules you apply in Azure match the official CIS specifications, reducing drift and ensuring compliance confidence. What’s new under the hood At the core of this update is kompli - a lightweight, open-source module developed by the Azure Core Linux team. It evaluates Linux systems directly against industry-standard benchmarks like CIS, supporting both audit and, in the future, auto-remediation. This enables accurate, scalable compliance checks across large Linux fleets. Here you can read more about kompli. Dynamic rule evaluation The new compliance engine supports simple fact-checking operations, evaluation of logic operations on them (e.g., anyOf, allOf) and Lua based scripting, which allows to express complex checks required by the CIS Critical Security Controls - all evaluated natively without external scripts. Scalable architecture for large fleets When the assignment is created, the Azure control plane instructs the machine to pull the latest Policy package via the Machine Configuration agent. kompli is integrated as a light-weight library to the package and called by Machine Configuration agent for evaluation – which happens every 15-30minutes. This ensures near real-time compliance state without overwhelming resources and enables consistent evaluation across thousands of VMs and Azure Arc-enabled servers. Future-ready for remediation and enforcement While the Public Preview starts with audit-only mode, the roadmap includes per-rule remediation and enforcement using technologies like eBPF for kernel-level controls. This will allow proactive prevention of configuration drift and runtime hardening at scale. Please reach out if you interested in auto-remediation or enforcement. Extensibility beyond CIS Benchmarks The architecture was designed to support other security and compliance standards as well and isn’t limited to CIS Benchmarks. The compliance engine is modular, and we plan to extend the platform with STIG and other relevant industry benchmarks. This positions Azure as a platform for a place where you can manage your compliance from a single control-plane without duplicating efforts elsewhere. Collaboration with the CIS This milestone reflects a close collaboration between Microsoft and the CIS to bring industry-standard security guidance into Azure as a built-in capability. Our shared goal is to make cloud-native compliance practical and consistent, while giving customers the flexibility to meet their unique requirements. We are committed to continuously supporting new Benchmark releases, expanding coverage with new distributions and easing adoption through built-in workflows, such as moving from your current Benchmark version to a new version while preserving your custom configurations. Certification and trust We can proudly announce that kompli has met all the requirements and is officially certified by the CIS for Benchmark assessment, so you can trust compliance results as authoritative. Minor benchmark updates will be applied automatically, while major version will be released separately. We will include workflows to help migrate customizations seamlessly across versions. Key Highlights Built-in CIS Benchmarks for Azure Endorsed Linux distributions Full parity with official CIS Benchmarks content and certified by the CIS for Benchmark Assessment Flexible configuration: adjust parameters, define exceptions, tune severity Hybrid support: enforce the same baseline across Azure, on-prem, and multi-cloud with Azure Arc Reporting format in CIS tooling style Supported use cases Certified CIS Benchmarks for all Azure Endorsed Distros - Audit only (L1/L2 server profiles) Hybrid / On-premises and other cloud machines with Azure Arc for the supported distros Compliance as Code (example via Github -> Azure OIDC auth and API integration) Compatible with GuestConfig workbook What’s next? Our next mission is to bring the previously announced auto-remediation capability into this experience, expand the distribution coverage and elevate our workflows even further. We’re focused on empowering you to resolve issues while honoring the unique operational complexity of your environments. Stay tuned! Get Started Documentation link for this capability Enable CIS Benchmarks in Machine Configuration and select the “Official Center for Internet Security (CIS) Benchmarks for Linux Workloads” then select the distributions for your assignment, and customize as needed. In case if you want any additional distribution supported or have any feedback for kompli – please open an Azure support case or a Github issue here Relevant Ignite 2025 session: Hybrid workload compliance from policy to practice on Azure Connect with us at Ignite Meet the Linux team and stop by the Linux on Azure booth to see these innovations in action: Session Type Session Code Session Name Date/Time (PST) Theatre THR 712 Hybrid workload compliance from policy to practice on Azure Tue, Nov 18/ 3:15 PM – 3:45 PM Breakout BRK 143 Optimizing performance, deployments, and security for Linux on Azure Thu, Nov 20/ 1:00 PM – 1:45 PM Breakout BRK 144 Build, modernize, and secure AKS workloads with Azure Linux Wed, Nov 19/ 1:30 PM – 2:15 PM Breakout BRK 104 From VMs and containers to AI apps with Azure Red Hat OpenShift Thu, Nov 20/ 8:30 AM – 9:15 AM Theatre THR 701 From Container to Node: Building Minimal-CVE Solutions with Azure Linux Wed, Nov 19/ 3:30 PM – 4:00 PM Lab Lab 505 Fast track your Linux and PostgreSQL migration with Azure Migrate Tue, Nov 18/ 4:30 PM – 5:45 PM PST Wed, Nov 19/ 3:45 PM – 5:00 PM PST Thu, Nov 20/ 9:00 AM – 10:15 AM PST1.7KViews0likes0CommentsNow Generally Available: Built-in CIS Benchmark Auditing for Linux on Azure
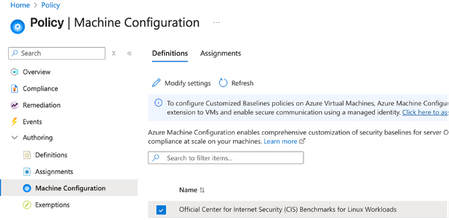
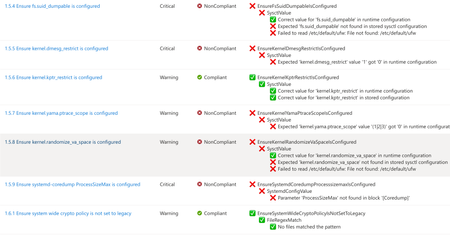
A few months ago, in From Policy to Practice: Built-in CIS Benchmarks on Azure – Flexible, Hybrid-Ready, we introduced a new way to bring Center for Internet Security (CIS) Benchmarks to your Linux estate using Azure Policy with Machine Configuration. It builds on the broader customizable security baseline policies in Machine Configuration capability. Today we're excited to share the next milestone: the audit capability for CIS Benchmarks on Linux is now Generally Available (GA). This release is officially powered by kompli - our native Linux compliance and hardening engine for CIS, STIG, and custom baselines. kompli is the evolution of the engine that drove the preview, now established as the dedicated home for this capability going forward. What "GA" means for you The audit experience is now ready for production use. You can continuously assess your Linux workloads against official, CIS-certified benchmarks - at scale, across Azure and hybrid environments through Azure Arc - and get clear, CIS-style compliance reporting directly in Azure Policy and Azure Resource Graph. If you've read the previous post, the how hasn't changed, so we'll keep this one short: Automated compliance assessment - continuously monitor Linux systems against official CIS benchmarks. Tailored benchmarks - customize evaluations with exceptions and custom parameters, no code changes required. Compliance reporting - detailed, CIS-style reports across your fleet. Hybrid-ready - the same baselines apply to Azure VMs and Arc-enabled servers on-premises or in other clouds. All supported benchmarks are CIS Benchmark Assessment Certified and stay in parity with the content published on the CIS website. Supported distributions and benchmark versions With this release, audit is GA across the following distributions, covering Level 1 + Level 2 Server profiles: Distribution CIS Benchmark Version(s) Profiles Audit Ubuntu 20.04 / 22.04 / 24.04 LTS + Pro v3.0.0 / v2.0.0 + v3.0.0 / v1.0.0 L1 + L2 Server ✓ Red Hat Enterprise Linux 8 / 9 / 10 v3.0.0 + v4.0.0 / v2.0.0 / v1.0.1 L1 + L2 Server ✓ AlmaLinux 8 / 9 v3.0.0 + v4.0.0 / v2.0.0 L1 + L2 Server ✓ Rocky Linux 8 / 9 v2.0.0 + v3.0.0 / v2.0.0 L1 + L2 Server ✓ Oracle Linux 8 / 9 v3.0.0 + v4.0.0 / v2.0.0 L1 + L2 Server ✓ Debian 11 / 12 v2.0.0 / v1.1.0 L1 + L2 Server ✓ SUSE Linux Enterprise 12 / 15 v3.2.1 / v2.0.1 L1 + L2 Server ✓ AKS Optimized Azure Linux 3 v1.0.0 L1 + L2 Server ✓ This GA covers the audit (assessment) capability. Looking ahead, STIG benchmarks are coming next, followed by a granular per-rule auto-remediation capability with dynamic scope assignments. You can run these benchmarks against your own hardened images, against CIS hardened images, and against custom images built on top of vanilla distros — as long as /etc/os-release retains its original content. We're also working with vendors to minimize deviations. Getting started Open Azure Policy in the Azure portal. Under Authoring, select the new Machine Configuration blade. Choose Official Center for Internet Security (CIS) Benchmarks for Linux Workloads, then Modify Settings to pick the distributions you want to assess. Full documentation, including per-distribution rule details, supported parameters, and any known deviations from the official CIS toolset, is available here: Overview: CIS Security Benchmarks for Linux Workloads Per-distribution references: AlmaLinux, Azure Linux, Debian, Oracle Linux, Red Hat Enterprise Linux, Rocky Linux, SUSE Linux Enterprise, and Ubuntu - all linked from the overview page. We're building this with you As part of this GA release, we've also expanded the set of exposed rule parameters compared to the preview - giving you more out-of-the-box customization across rules and distributions. That said, our customer-driven approach still stands: we keep the experience clean by enabling parameters based on real demand, so if there's a rule, benchmark version, or distribution you'd like parameters enabled for - or any feedback on rules, evaluations, or distro coverage - let us know: Open a GitHub issue in the kompli repository Open an Azure support case Try it out, tell us what you think, and help shape what we build next.519Views1like0CommentsAnnouncing the Open-Source Release of ML Video Codec (MLVC)
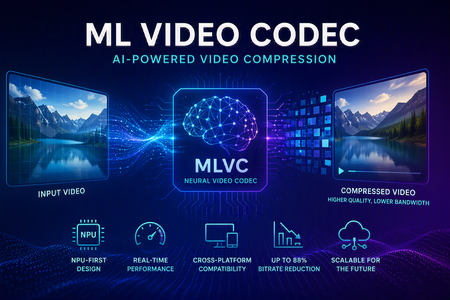
Video codecs compress video for transmission or storage, reducing bandwidth and storage requirements. MLVC is a modern machine-learning-based codec that uses substantially less bandwidth than conventional codecs, improving streaming and video-call quality—especially on constrained or unreliable networks—while lowering delivery and storage costs. MLVC is the product iteration of DCVC (Deep Contextual Video Compression) family of NVC (Neural Video Codec), open sourced by Microsoft Research since 2021, with improved compression efficiency, real-time performance on commodity Neural Processing Units (NPUs), and cross-platform support. We recently published this work in the paper MLVC: Multi-platform Learned Video Codec for Real-World Deployment. We are releasing the source code because we believe the next generation of video coding will be built openly, and we want the broader community — researchers, video codec engineers, platform vendors, product teams, as well as general developer community — to build it with us. Why MLVC Traditional video codecs (e.g., H.264/AVC, H.265/HEVC) have served the industry for a long time, but each generation requires enormous engineering effort for incremental gains and needs dedicated hardware which takes years to become commonly available. MLVC replaces conventional primitives — motion estimation, transforms, entropy modeling — with end-to-end learned neural compression, trained directly against rate-distortion objectives, and run on general-purpose NPU devices. The table below compares MLVC to popular video codecs, showing its lower bitrate and resulting savings in bandwidth and storage. Resolution vs H.264 vs H.265 360p 87.8% 75.5% 540p 82.7% 65.4% For example, for 360p video at 30 fps, where H.264 requires 1 Mbps, MLVC requires roughly 122 kbps for equivalent quality — about one-eight the bitrate under real-time conditions. The inference compute was kept approximately equal for the 360p and 540p resolutions. These results are based on a P.910 subjective test and are based on the Video Conferencing Dataset (VCD) dataset that we developed and also recently released as an open-source project. The following video demo illustrates the extent of quality enhancement achieved by MLVC relative to H.265/HEVC at the same bitrate of 200kbps (please watch by opening in a new window for better demonstration) \ Beyond video compression efficiency, MLVC also offers: NPU-first design. MLVC is built to run almost entirely on the AI accelerators already shipping in modern devices — Apple Neural Engine, Qualcomm and Intel NPUs — at no more than 50% NPU utilization, leaving NPU headroom for the rest of the system. Real-time execution at the targeted operating points. Demonstrated 540p at 30 fps on Apple, Intel, and Qualcomm hardware. A scaling-law trajectory. Empirically, MLVC's coding efficiency improves with increased model capacity and additional training compute. Content-adaptive behavior out of the box, without hand-tuned Rate Distortion Optimization heuristics. Already running in Microsoft Teams MLVC is more than just a research concept for Microsoft. We are currently rolling it out in Microsoft Teams, where it is being validated on real peer-to-peer video calls with active telemetry and A/B testing. The integration runs alongside fallback to conventional video codecs for hardware or reliability constraints — the kind of mixed-environment deployment that real products need. The scaling and reliability insights from this rollout are shaping the codec and its roadmap. We welcome your contributions We can not cover every use case, every device class, or every content domain by ourselves. That is why we are open sourcing MLVC. If you work on: Streaming, Video On Demand (VOD), or live broadcast Real-time communication and conferencing Cloud gaming or remote rendering Surveillance, drones, or robotics Mobile capture, Augmented Reality (AR) / Virtual Reality (VR), or volumetric video Codec hardware, NPUs, or inference runtimes We would love your help. Contributions of all kinds are welcome, including model improvements, training recipes, new platform ports and conversion targets, runtime backends, domain-specific fine-tunes, evaluation tooling, bug reports, and feedback on what is missing for your scenario. We particularly welcome platform ports that expand NPU coverage and efficiency improvements that push the rate-distortion frontier. What's in the release The MLVC repository is available at https://github.com/microsoft/mlvc and shared under the MIT License. It includes: MLVC model source code of the full network architecture. Trained model weights ready to run. Training scripts used to produce shipping models. Training data collection documentation to help reproduce and improve MLVC. Platform conversion scripts to target different NPUs and runtimes. Issues and pull requests will be open from day one. A follow-up release will add a C++ codec library, simplifying integration into real-world applications. Where we're heading Our long-term goal with MLVC is to create an open, learned video codec that meets or exceeds the coding efficiency of the best conventional codecs across the full range of video content, runs efficiently on the AI hardware already shipping in client and cloud devices, scales with compute the way modern ML systems do, and evolves in the open at the pace of the ML community rather than the pace of standardization cycles. In the near term that means stabilizing 540p real-time performance, expanding hardware coverage, and improving loss resilience. In the medium term: higher resolution, e.g., 1080p, and broader streaming scenarios. In the long term: an open video codec ecosystem that meaningfully replaces legacy stacks where it makes sense to. We can't create the future of MLVC alone. We're glad you're here, and we are looking forward to building the next-generation video codec with you. Who are we MLVC is brought to you by the following awesome folks working on the project at Microsoft: Ross Cutler, Ando Saabas, Tanel Pärnamaa, Ardi Loot, Haiyan Xie, Lauri Ehrenpreis, Andrei Znobishchev, Martin Lumiste, Evgenii Indenbom, Yan Lu, Bin Li, Jiahao Li, Naba Kumar, Babak Naderi, Juhee Cho, Badal Yadav, Jinxin Zhou, Tianyu Ding, Patrick Gregory. — The MLVC Team, Microsoft16KViews0likes4CommentsDesigning for cloud sovereignty with Radius and Dapr
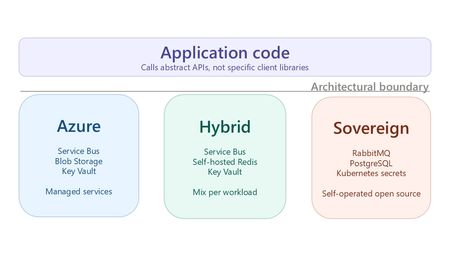
In 2026, cloud sovereignty matters more than ever. It has moved from a policy discussion to an operational and architectural problem. The word “sovereignty” gets used loosely, and it can mean different things to different people. While definitions vary, in this post we define “cloud sovereignty” as the ability for an organization to retain control over where its data and compute run, which jurisdictions govern them, who operates them, and how its applications can adapt as regulatory, commercial, or operational requirements shift. This is especially relevant for developers and platform teams building applications that need to run on hyperscaler infrastructure, such as Azure, as well as in sovereign environments. Those requirements may come from regulation, procurement policies, customer expectations, or internal risk management. In Europe, this pressure is already visible through measures such as the EU Data Act, in force since September 12, 2025, which mandates data portability and interoperability between cloud and edge data processing services. More recently, the European Commission proposed the Cloud and AI Development Act (CADA) as part of its broader European Technological Sovereignty Package. For application teams, the practical takeaway is clear: more organizations need applications that can adapt to changing deployment requirements without requiring a rewrite. Portability is therefore a real engineering concern, not a theoretical one. If requirements change, moving a workload that is deeply integrated with provider-specific APIs can mean rewriting application code, not just reconfiguring infrastructure. Portable applications for sovereign environments The goal is to use the right managed service for each environment while keeping application code portable across environments. Microsoft Sovereign Cloud provides the platform foundation for digital sovereignty across sovereign public cloud, sovereign private cloud, and national partner cloud deployment models. Azure managed services provides strong platform capabilities for regulated workloads. Open source can help, especially when the same technology can be used as a managed service in one environment and self-operated in another. CADA also elevates an explicit "open source first" principle, reflecting how inspectable, portable components can reinforce resilience and reduce strategic dependency. Even with those options, portability is not automatic - applications still need a clear architectural boundary between the capabilities they require and the infrastructure selected for each environment. This boundary is what lets organizations use the right services in each deployment model while keeping workloads adaptable as regulatory, commercial, or operational requirements change. See the diagram below: To address building applications that are cleanly separated from their infrastructure, lets look at Radius, a CNCF project that provides a cloud native application model that addresses the boundary at the deployment layer by letting teams define applications in terms of what they need, while platform teams decide how those needs are met in each environment. For the runtime layer, lets consider Dapr, also a CNCF project which complements Radius by giving application code consistent APIs for common distributed application capabilities. Radius: portability at the deployment layer Radius provides a cloud-native application model. It separates the concerns of what an application needs from how those needs are met in each environment. Resource Types define the interface that developers use to build applications. Radius ships with built-in types and supports user-defined Resource Types for an organization's own abstractions. Recipes implement a Resource Type for a given environment. A Recipe is Infrastructure as Code; a Bicep template or a Terraform configuration that provisions infrastructure and returns the connection details. The same Resource Type can have different Recipes for different environments. Environments bind a set of Recipes against the compute target and credentials for a given deployment context (local Kubernetes, AKS, AKS enabled by Azure Arc, or others). Applications define the full set of resources (containers, Dapr building blocks, databases) and their relationships. At deploy time, Radius resolves each Resource Type to the Recipe registered in the target Environment provisions the infrastructure, and captures the result in an Application Graph that developers and operators can query. Dapr: runtime portability for Radius applications Dapr provides building block APIs for common distributed systems concerns: state management, publish and subscribe messaging, service invocation, workflows, secrets, and more. Dapr runs as a sidecar alongside each service and exposes its APIs over HTTP or gRPC. Application code calls the Dapr API instead of the underlying technology directly, which helps keep runtime dependencies more portable across environments. In a Radius application, Dapr building blocks such as state stores, pub/sub brokers, and secret stores can be declared as application resources. Radius binds those resources to the right infrastructure for each environment, while Dapr exposes them to the application through consistent runtime APIs. A concrete example: order-console The order-console sample, available in the official Radius project labs repo, demonstrates this architectural pattern end to end. It is a three-service order-management application (a Next.js frontend, an orders-api, and a fulfillment-worker) wired through Dapr state management and Dapr pub/sub. The sample ships two Radius environments: A Kubernetes environment that provisions PostgreSQL and Apache Kafka in-cluster. An Azure environment that provisions Azure Database for PostgreSQL Flexible Server and Azure Event Hubs in Kafka mode. The same app.bicep deploys against both environments. Container images, Dapr component names, and application code are identical across both. Only the Recipes change. The Recipes are written in Terraform, which Radius supports as a first-class IaC option alongside Bicep. For a step-by-step walkthrough, including the Bicep application model, the Resource Type definitions, the Terraform Recipes, and deployment instructions, see the order-console walkthrough. Don’t let the app become the lock-in What Radius and Dapr contribute is the application architecture layer: a way to ensure the application itself does not become the reason a workload cannot move to a more sovereign environment when requirements change. Radius Resource Types and Recipes allow platform teams to define governance requirements such as data residency, encryption standards, and audit integration as part of the platform definition. This helps ensure that workloads are deployed consistently and in line with organizational policies, regardless of the target environment. Because these requirements are abstracted from the underlying infrastructure, the same application can be deployed across public cloud, on-premises, and sovereign environments without requiring changes to the application itself. Where a workload runs, and under which controls, becomes a deployment decision rather than a redevelopment project. Learn more To learn more about Radius and Dapr, explore the resources below: Radius documentation Radius Resource Types concept Dapr documentation Expanding platform engineering capabilities with Radius Resource Types2KViews1like0CommentsIntroducing kars - an Agent Reference Stack for Kubernetes
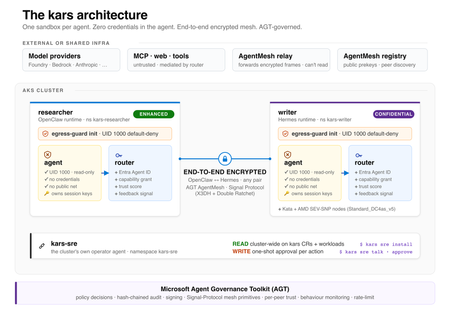
kars is an open-source, Kubernetes-native runtime for AI agents on Azure. It treats every agent as untrusted code - per-pod kernel isolation, zero credentials in the agent process, and an end-to-end encrypted inter-agent mesh - and governs agents on any framework with one set of Kubernetes policies via the Microsoft Agent Governance Toolkit. kars dev runs a governed agent on your laptop in minutes.2.6KViews1like2Comments