query store
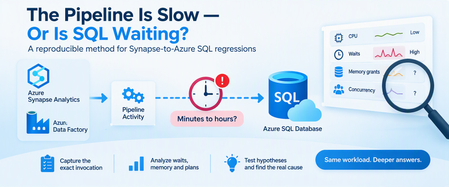
11 TopicsThe Pipeline Is Slow, or Is SQL Waiting? Diagnosing Synapse-to-Azure SQL Regressions
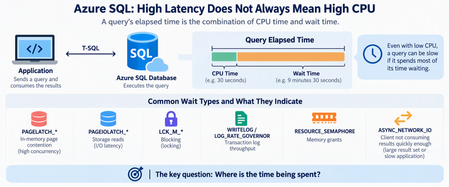
A query can consume very little CPU and still keep a pipeline waiting for hours. A pipeline activity that normally finishes in minutes suddenly starts taking hours. Nothing obvious has changed: The pipeline definition looks the same. The stored procedure looks the same. Azure SQL Database isn't showing sustained high CPU. Pipeline monitoring still points toward the SQL activity. At this point, saying "SQL is slow" isn't enough. The request may actually be: Executing expensive work. Waiting for memory. Blocked by another transaction. Reading more data than before. Running with a different execution plan. Competing with concurrent pipeline activities. Experiencing different cardinality because of different parameter values. The key is to connect the pipeline invocation to the database execution and determine where elapsed time is really going. 1. Define the Regression Precisely Before troubleshooting SQL, establish what actually changed. Capture: Expected pipeline duration. Observed pipeline duration. Pipeline activity involved. Stored procedure or statement invoked. Exact parameter values. Affected and unaffected executions. Pipeline concurrency. Retry behavior. Connection and command timeout. Deployment or configuration changes. For example: Evidence Baseline Regression Pipeline duration Minutes Much longer Stored procedure Same Same Parameter range A B Concurrent activities Low Higher Azure SQL CPU Normal Normal/moderate SQL wait behavior Unknown To investigate The most important rule is: Don't assume the SQL workload is identical simply because the stored procedure is identical. Different parameters can result in dramatically different: Row counts. Join choices. Memory grants. Sort requirements. Execution plans. Total duration. 2. Preserve the Exact Invocation One of the easiest ways to lose a performance regression is to reproduce it with different parameters. Capture the invocation before testing: Procedure name. Parameter values. Date range. Entity or partition identifier. Batch size. Pipeline run ID. Retry number. Number of parallel activities. Relevant timeout configuration. Then sanitize any business-sensitive values before sharing them outside your organization. The diagnostic principle is simple: Reproduce the same workload before trying to improve the workload. 3. Reproduce Safely Whenever possible, reproduce the issue using: A nonproduction database containing representative data. A controlled production troubleshooting window. The same stored procedure. The same parameter pattern. Comparable concurrency. For a controlled test, SQL execution statistics can help: SET STATISTICS IO ON; SET STATISTICS TIME ON; EXEC dbo.SampleProcedure @StartDate = '2026-01-01', @EndDate = '2026-01-31', @EntityID = 100; SET STATISTICS TIME OFF; SET STATISTICS IO OFF; Replace these synthetic names and values with the sanitized equivalent of the invocation you're investigating. Capture: Elapsed time. CPU time. Logical reads. Physical reads when relevant. Execution plan. Returned row count. The goal isn't simply to reproduce "slow." The goal is to understand why it is slow. 4. First Question: Is SQL Running or Waiting? This distinction changes the entire investigation. During the slow execution, examine the active request. SELECT r.session_id, r.request_id, r.status, r.command, r.start_time, r.cpu_time, r.total_elapsed_time, r.wait_type, r.wait_time, r.last_wait_type, r.wait_resource, r.blocking_session_id, r.reads, r.writes, r.logical_reads, r.row_count FROM sys.dm_exec_requests AS r WHERE r.database_id = DB_ID() ORDER BY r.total_elapsed_time DESC; sys.dm_exec_requests is supported for Azure SQL Database and exposes information about currently executing requests. Pay particular attention to the relationship between: cpu_time and: total_elapsed_time Suppose a request has: Very high elapsed time. Relatively little accumulated CPU time. A significant current wait. That's a strong reason to investigate waiting, rather than immediately treating the problem as insufficient CPU. Conversely: High elapsed time. High accumulated CPU. High logical reads. points more strongly toward expensive execution. 5. Identify Blocking Another request may be preventing the pipeline's SQL request from progressing. Start with: SELECT session_id, status, wait_type, wait_time, wait_resource, blocking_session_id, cpu_time, total_elapsed_time FROM sys.dm_exec_requests WHERE blocking_session_id <> 0 ORDER BY wait_time DESC; Blocking can explain a scenario where: Pipeline duration increases dramatically. Database CPU remains moderate. The SQL activity appears "active" for a long time. Microsoft documents sys.dm_exec_requests as one of the tools for identifying requests suspended on lock-related waits and tracing blocking behavior in Azure SQL Database. Don't confuse: "The SQL call took two hours." with: "SQL executed for two hours." Those statements aren't necessarily equivalent. 6. Look at the SQL That's Actually Running During an active incident, retrieve the request and its current SQL text: SELECT r.session_id, r.status, r.command, r.cpu_time, r.total_elapsed_time, r.wait_type, r.blocking_session_id, r.logical_reads, txt.text AS batch_text FROM sys.dm_exec_requests AS r CROSS APPLY sys.dm_exec_sql_text(r.sql_handle) AS txt WHERE r.database_id = DB_ID() ORDER BY r.total_elapsed_time DESC; sys.dm_exec_sql_text accepts the sql_handle exposed by sys.dm_exec_requests and returns the associated SQL batch text. This helps validate an important cross-service question: Is the database executing the statement we think the pipeline invoked? 7. Investigate Memory Grants Some operations need execution memory before they can proceed efficiently. Common examples include: Sorts. Hash joins. Hash aggregates. Some index operations. sys.dm_exec_query_memory_grants exposes queries that: Requested a memory grant and received one. Requested a memory grant and are still waiting. It is supported for Azure SQL Database. SELECT mg.session_id, mg.request_id, mg.dop, mg.request_time, mg.grant_time, mg.requested_memory_kb, mg.granted_memory_kb, mg.required_memory_kb, mg.used_memory_kb, mg.max_used_memory_kb, mg.query_cost, mg.timeout_sec, mg.resource_semaphore_id FROM sys.dm_exec_query_memory_grants AS mg ORDER BY mg.requested_memory_kb DESC; Interpret the important columns carefully: requested_memory_kb Memory requested by the query. granted_memory_kb Memory actually granted. required_memory_kb Minimum memory required for execution. used_memory_kb Memory currently being used. max_used_memory_kb Maximum used so far. grant_time NULL when the requested grant hasn't yet been granted. Microsoft specifically documents that queries waiting for memory grants appear in this DMV, and that grant_time remains NULL until the grant is provided. 8. Find Waiting Memory Grants During the active regression, focus specifically on requests that haven't received their grants: SELECT mg.session_id, mg.request_id, mg.request_time, mg.grant_time, mg.requested_memory_kb, mg.required_memory_kb, mg.granted_memory_kb, mg.timeout_sec, mg.dop, mg.query_cost FROM sys.dm_exec_query_memory_grants AS mg WHERE mg.grant_time IS NULL ORDER BY mg.request_time; If the affected session repeatedly appears here, you now have meaningful evidence supporting a memory-grant contention hypothesis. But that's still not enough to state: "Memory grants caused the pipeline regression." You should also establish: Whether the waiting session is actually the pipeline request. How long it remained waiting. Whether other statements were consuming large grants. Whether concurrency changed. Whether the execution plan requested unusually large memory. Why the query requested that amount of memory. That last question is particularly important. Memory-grant problems can be downstream symptoms of: Poor cardinality estimates. Large sorts. Large hash joins. Plan changes. Data growth. Parameter sensitivity. Microsoft's memory-grant troubleshooting guidance emphasizes that operations such as sorts and hash operations can require execution-memory reservations and that these grants exist for the lifetime of the query. Memory-grant contention is a diagnostic hypothesis until the evidence supports causality. 9. Pipeline Concurrency Is Database Concurrency This connection is easy to overlook. Suppose one stored-procedure invocation performs acceptably. Now imagine the orchestration layer starts: 2 copies concurrently. 5 copies concurrently. 10 copies concurrently. 20 copies concurrently. Each execution may individually be reasonable. Together, they can compete for: CPU. Workers. Memory grants. Buffer pool resources. I/O. Locks. This means: A pipeline concurrency change is also a database workload change. Even when: SQL code hasn't changed. Database configuration hasn't changed. Stored procedure code hasn't changed. As part of troubleshooting, compare: Single-execution performance. Typical production concurrency. Regression-period concurrency. Temporarily reducing pipeline concurrency can also be a valuable diagnostic experiment, provided the change is safe for the workload. 10. Capture the Live Execution Plan For a request that's still executing, Azure SQL Database supports sys.dm_exec_query_statistics_xml(), which returns Showplan XML containing transient execution statistics for an in-flight request. First identify the target session: SELECT session_id, request_id, status, command, cpu_time, total_elapsed_time, wait_type, logical_reads FROM sys.dm_exec_requests WHERE database_id = DB_ID() ORDER BY total_elapsed_time DESC; Then, for a known session: DECLARE @SessionID smallint = 123; SELECT qsx.session_id, qsx.request_id, qsx.query_plan FROM sys.dm_exec_query_statistics_xml(@SessionID) AS qsx; Replace 123 with the session being investigated. The live plan can help answer: Which operator is consuming time? How many rows are flowing through operators? Are estimates diverging significantly from runtime behavior? Are large joins or sorts involved? Where does execution appear to be spending time? Microsoft describes access to execution-plan runtime information as particularly useful when investigating long-running queries, because the information can be inspected without waiting for the query to finish. Use live-plan collection purposefully, especially on heavily loaded production systems. 11. Compare Historical Behavior in Query Store A live snapshot explains what's happening now. Query Store helps answer: What was happening when the query used to be fast? For example, find queries with multiple retained Query Store plans: SELECT TOP (50) q.query_id, COUNT(DISTINCT p.plan_id) AS plan_count, COUNT(DISTINCT p.query_plan_hash) AS distinct_plan_shapes, MIN(p.first_execution_time) AS first_plan_execution, MAX(p.last_execution_time) AS last_plan_execution FROM sys.query_store_query AS q JOIN sys.query_store_plan AS p ON q.query_id = p.query_id GROUP BY q.query_id HAVING COUNT(DISTINCT p.plan_id) > 1 ORDER BY plan_count DESC; Multiple plans aren't automatically evidence of a problem. Instead, investigate whether plan changes correlate with: Pipeline regressions. Duration changes. CPU changes. Logical-read changes. Memory behavior. Different parameter populations. 12. Compare Runtime Distributions, Not Just Averages Averages can hide regression patterns. Consider: Most executions take 10 seconds. A few take 45 minutes. The average won't fully describe the operational impact. For a known Query Store query_id, compare plans and runtime intervals: DECLARE @QueryID bigint = 123; SELECT p.plan_id, rsi.start_time, rsi.end_time, SUM(rs.count_executions) AS execution_count, CAST(AVG(rs.avg_duration) / 1000.0 AS decimal(18,2)) AS avg_duration_ms, CAST(MAX(rs.max_duration) / 1000.0 AS decimal(18,2)) AS max_duration_ms, CAST(AVG(rs.avg_cpu_time) / 1000.0 AS decimal(18,2)) AS avg_cpu_ms, CAST(AVG(rs.avg_logical_io_reads) AS decimal(18,2)) AS avg_logical_reads FROM sys.query_store_query AS q JOIN sys.query_store_plan AS p ON q.query_id = p.query_id JOIN sys.query_store_runtime_stats AS rs ON p.plan_id = rs.plan_id JOIN sys.query_store_runtime_stats_interval AS rsi ON rs.runtime_stats_interval_id = rsi.runtime_stats_interval_id WHERE q.query_id = @QueryID GROUP BY p.plan_id, rsi.start_time, rsi.end_time ORDER BY rsi.start_time DESC, p.plan_id; Replace 123 with the Query Store ID being investigated. Compare: Fast periods. Slow periods. Plans. Execution counts. CPU. Duration. Logical reads. This often produces a better picture than looking at lifetime averages. 13. Don't Force the Fastest Historical Plan Yet Suppose Query Store shows: Plan A took 30 seconds. Plan B takes 20 minutes. It might be tempting to immediately force Plan A. But first ask: How many times did Plan A execute? Which parameters used Plan A? Was the data distribution comparable? Was workload concurrency comparable? Did Plan A perform well repeatedly? Is the query parameter sensitive? A plan that was excellent for one parameter combination might be disastrous for another. The goal isn't to find the lowest historical duration. The goal is to find the plan behavior that's safe for the intended workload. If plan forcing is tested, define rollback criteria before deployment. 14. Test One Hypothesis at a Time Avoid simultaneously changing: Statistics. Indexes. Query code. Pipeline concurrency. Plan forcing. Compute tier. Doing everything together may improve performance, but you'll learn very little about why. Instead: Hypothesis: stale or inaccurate statistics Test: Appropriate statistics maintenance. Same parameters. Same concurrency. Then measure again. Hypothesis: memory-grant contention Test safely with: Reduced concurrency. Same parameter set. Same procedure. Same database configuration. Then compare: Grant wait behavior. Elapsed time. CPU time. Query plan. Hypothesis: plan regression Compare: Historical plans. Representative parameters. Runtime distributions. Only then evaluate targeted plan intervention. Hypothesis: poor cardinality Look for: Estimate-to-actual row differences. Parameter sensitivity. Implicit conversions. Sort/hash behavior. Excessive memory requests. This approach turns troubleshooting from guesswork into experimentation. 15. Correlation Is Not Root Cause This is perhaps the most important principle in cross-service troubleshooting. Suppose you see: A slow pipeline. A SQL memory-grant wait. Several concurrent activities. Those facts are correlated. They don't yet prove: "Memory contention caused the pipeline regression." A stronger conclusion requires a causal chain such as: The pipeline invokes the identified SQL request. That request repeatedly waits for execution memory during the regression. Competing queries hold substantial memory grants during the same period. Reducing the competing concurrency removes or materially reduces the grant wait. The same SQL invocation then returns toward its normal runtime. Repeating the workload reproduces the relationship. Now the evidence for causality is much stronger. This distinction matters because Azure SQL memory pressure can arise from several sources, including the chosen service objective, aggregate workload demand, and individual query memory demand. 16. Build a Cross-Service Evidence Package For difficult Synapse or Data Factory to Azure SQL regressions, both teams should be able to work from the same timeline. Capture: Pipeline evidence Pipeline run ID. Activity name. Activity start and end times. Sanitized parameters. Retry count. Timeout. Concurrent activities. Azure SQL evidence Session/request identification when captured live. Query Store query_id. Query Store plan_id. Runtime intervals. CPU time. Elapsed time. Logical reads. Wait type. Blocking session. Memory grant information. Execution plan. Investigation evidence Separate everything into: Facts Pipeline execution took longer than baseline. SQL request was identified. Request waited for memory. Multiple pipeline activities overlapped. A different plan appeared during the regression. Hypotheses Pipeline concurrency created memory-grant contention. Cardinality changes increased the requested memory grant. Parameter sensitivity caused a plan regression. Blocking contributed to runtime. Resource contention amplified an otherwise acceptable query. Experiments Document: What changed. Why it changed. Test duration. Result. Whether the hypothesis was strengthened or weakened. This prevents the pipeline and database teams from investigating two different incidents that simply happened at the same time. A Practical Decision Tree When a Synapse or Data Factory pipeline's Azure SQL activity suddenly becomes slow: 1. Can you identify the exact invocation? No Capture it before continuing. Yes Reproduce with equivalent parameters and concurrency. 2. Is SQL consuming significant CPU? Yes Investigate: Execution plan. Logical reads. Cardinality. Indexing. Parameter sensitivity. No Look at waits. 3. Is the request blocked? Yes Investigate: Blocking session. Transaction duration. Locking pattern. No Continue. 4. Is the request waiting for a memory grant? Yes Investigate: Requested versus granted memory. Other active grants. Sorts and hash operations. Cardinality estimates. Pipeline concurrency. No Investigate the actual current wait. 5. Did the execution plan change? Yes Compare: Runtime distributions. Parameter sets. CPU. Reads. Memory requirements. No Continue correlating waits, workload volume, and concurrency. 6. Does reducing concurrency improve the same invocation? Yes Resource competition becomes a stronger hypothesis. No Continue investigating query-specific behavior. Final Takeaway When a pipeline goes from minutes to hours, the fact that the Azure SQL activity is taking a long time doesn't automatically mean Azure SQL is spending all that time executing. The request might be spending much of its lifetime: Waiting for memory. Waiting behind another transaction. Waiting for another resource. Executing with a different plan. Processing a different parameter population. Competing with concurrent pipeline activities. A reliable investigation connects two perspectives: Pipeline context What exactly was invoked? With which parameters? At what time? At what concurrency? Database context Was the SQL request executing or waiting? How much CPU did it actually consume? What was it waiting for? Which plan did it use? How much memory did it request? What else was happening concurrently? sys.dm_exec_requests can identify active requests and their current execution state, while sys.dm_exec_query_memory_grants exposes statements that have requested or received execution memory. Azure SQL Database also supports obtaining transient plan information for in-flight requests through sys.dm_exec_query_statistics_xml(). Most importantly: Treat waits, memory grants, plan changes, and concurrency as evidence to test, not automatic root causes. That is how "the pipeline is slow" becomes a reproducible, evidence-backed performance diagnosis.132Views0likes0CommentsWhen More vCores Aren’t the Fix: Diagnosing Azure SQL CPU and Compilation Storms
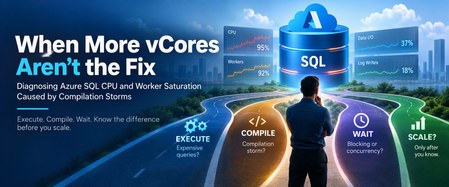
Before changing MAXDOP or adding compute, answer one question: Is the database executing work, compiling work, or waiting for work? When an Azure SQL Database approaches its CPU or worker limits, the natural reaction is often straightforward: Add more vCores. Move to a higher service objective. Change MAXDOP. Find the most expensive query. Add an index. Sometimes one of those actions is exactly what the workload needs. But not always. A database experiencing very high CPU does not necessarily have an execution CPU problem. It might instead be spending substantial resources: Repeatedly compiling queries. Generating plans that aren't efficiently reused. Processing excessive application concurrency. Holding workers while requests wait. Handling large numbers of inexpensive but extremely frequent queries. Recompiling statements because workload characteristics keep changing. Adding compute can make these symptoms less visible without making the workload healthier. The more useful question is: Where is the resource pressure actually coming from? In this article, we'll build a practical troubleshooting workflow to distinguish: Execution CPU. Compilation and recompilation pressure. Worker saturation. Blocking and concurrency. Plan instability. Parameterization problems. I/O and transaction-log pressure. Genuine capacity constraints. The goal isn't to avoid scaling. The goal is to understand the workload before deciding that scaling is the solution. 1. Start With the Symptom, Not the Conclusion Imagine an incident where you observe: CPU approaching the database's resource limit. Worker utilization rising rapidly. Application latency increasing. More active sessions than usual. Intermittent application timeouts. No obvious increase in legitimate business volume. It's tempting to conclude: "We don't have enough CPU or workers." That conclusion is premature. High worker utilization tells us that many workers are being consumed. It doesn't explain why. The underlying cause might include: Expensive queries actively consuming CPU. Large numbers of concurrent requests. Parallel query execution. Blocking. Long-running requests. Query compilation or recompilation. Excessive application calls. Several of these conditions happening simultaneously. The first step is therefore to correlate Azure SQL's primary database resource measurements. 2. Establish the Resource Timeline For recent diagnosis, sys.dm_db_resource_stats provides resource utilization samples for the current database. Run this inside the Azure SQL Database you're investigating: SELECT TOP (240) end_time, avg_cpu_percent, avg_data_io_percent, avg_log_write_percent, avg_memory_usage_percent, max_worker_percent, max_session_percent FROM sys.dm_db_resource_stats ORDER BY end_time DESC; This gives us several important signals: avg_cpu_percent CPU utilization relative to the database resource limit. avg_data_io_percent Data I/O utilization. avg_log_write_percent Transaction log write utilization. avg_memory_usage_percent Memory usage. max_worker_percent Worker utilization. max_session_percent Session utilization. sys.dm_db_resource_stats returns approximately one hour of resource data at roughly 15-second intervals for Azure SQL Database. A useful summary is: SELECT MIN(end_time) AS sample_start_utc, MAX(end_time) AS sample_end_utc, CAST(AVG(avg_cpu_percent) AS decimal(10,2)) AS avg_cpu_percent, CAST(MAX(avg_cpu_percent) AS decimal(10,2)) AS max_cpu_percent, CAST(MAX(max_worker_percent) AS decimal(10,2)) AS max_worker_percent, CAST(MAX(max_session_percent) AS decimal(10,2)) AS max_session_percent, CAST(MAX(avg_data_io_percent) AS decimal(10,2)) AS max_data_io_percent, CAST(MAX(avg_log_write_percent) AS decimal(10,2)) AS max_log_write_percent, CAST(MAX(avg_memory_usage_percent) AS decimal(10,2)) AS max_memory_usage_percent FROM sys.dm_db_resource_stats; Look for relationships between: CPU and workers. Workers and sessions. CPU and data I/O. CPU and log writes. Memory and concurrency. When the spike begins. How long it persists. How quickly the database returns to normal. Important: sys.dm_db_resource_stats provides recent, high-resolution resource statistics. For longer historical analysis, Azure SQL also exposes sys.resource_stats from the logical server's master database, with five-minute aggregation and longer retention. 3. First Classification: Executing, Compiling, or Waiting? Before tuning anything, classify the workload. Scenario A: The database is executing expensive work Typical evidence includes: High CPU. A small set of queries dominates total CPU. High logical reads. Large joins or aggregations. Expensive scans. Parallel query execution. Execution plans that explain the consumption. In this case, compilation may be perfectly normal. The database is simply performing expensive execution work. Scenario B: The workload may have excessive compilation Typical evidence might include: Many similar query shapes. Large numbers of distinct query texts. High compile counts. Frequent recompilation. Poor parameterization. Very frequent short-running queries. Temporary-object-heavy procedures. CPU usage not fully explained by the top executing queries. None of these signals alone proves that a compilation storm exists. The key is correlation. Scenario C: Workers are waiting rather than computing Typical evidence includes: High worker utilization. CPU that isn't proportionally high. Significant blocking. Lock waits. Long-running transactions. Many concurrent requests. Requests holding workers while waiting for resources. The remedy here can be completely different from an execution CPU problem. 4. Build a Minimum Evidence Packet Before making configuration changes, capture enough evidence to explain the incident. At minimum, collect: Exact incident window in UTC. CPU utilization. Worker utilization. Session utilization. Data I/O. Log-write utilization. Memory utilization. Top queries by CPU. Top queries by duration. Execution counts. Query Store wait categories. Number of relevant Query Store plans. Compile counts. Application deployment timestamps. Scheduled workload timestamps. Blocking information, if the incident is currently happening. Query Store is particularly useful because it provides historical information about: Query text. Execution plans. Runtime statistics. Execution counts. Query performance over time. Query Store wait categories. 5. Find the Queries Consuming the Most CPU Don't rely only on whatever happens to be executing at the moment you connect. Query Store can help determine which queries consumed CPU during the period under investigation. The following example examines approximately the last hour. DECLARE @StartTime datetimeoffset = DATEADD(HOUR, -1, SYSUTCDATETIME()); WITH RuntimeStats AS ( SELECT rs.plan_id, rs.runtime_stats_interval_id, rs.execution_type, SUM(rs.count_executions) AS execution_count, SUM ( CONVERT(decimal(38,4), rs.avg_cpu_time) * rs.count_executions ) AS total_cpu_us FROM sys.query_store_runtime_stats AS rs GROUP BY rs.plan_id, rs.runtime_stats_interval_id, rs.execution_type ) SELECT TOP (20) q.query_id, qt.query_sql_text, SUM(r.execution_count) AS executions, CAST ( SUM(r.total_cpu_us) / NULLIF(SUM(r.execution_count), 0) AS decimal(20,2) ) AS weighted_avg_cpu_us, CAST ( SUM(r.total_cpu_us) AS decimal(38,2) ) AS total_cpu_us FROM RuntimeStats AS r JOIN sys.query_store_runtime_stats_interval AS rsi ON r.runtime_stats_interval_id = rsi.runtime_stats_interval_id JOIN sys.query_store_plan AS p ON r.plan_id = p.plan_id JOIN sys.query_store_query AS q ON p.query_id = q.query_id JOIN sys.query_store_query_text AS qt ON q.query_text_id = qt.query_text_id WHERE r.execution_type = 0 AND rsi.end_time > @StartTime GROUP BY q.query_id, qt.query_sql_text ORDER BY total_cpu_us DESC; A few important details: Query Store CPU statistics are reported in microseconds. The query pre-aggregates Query Store runtime rows. execution_type = 0 restricts the analysis to normally completed executions. The average CPU calculation is weighted by execution count. Now ask the critical question: Do the highest-CPU queries explain the database-level CPU spike? If they do, investigate: Execution plans. Logical reads. Indexing. Cardinality estimates. Join strategies. Parallelism. Parameter sensitivity. If they don't, widen the investigation. Compilation, concurrency, waits, application request volume, or another engine activity may deserve more attention. 6. Don't Ignore Execution Frequency A query doesn't need to be individually expensive to create substantial pressure. Imagine: Query A consumes 500 ms of CPU and runs 20 times. Query B consumes 2 ms of CPU but runs 200,000 times. Query B may represent far more total work. Use Query Store to identify high-frequency queries: DECLARE @StartTime datetimeoffset = DATEADD(HOUR, -1, SYSUTCDATETIME()); WITH RuntimeStats AS ( SELECT rs.plan_id, rs.runtime_stats_interval_id, rs.execution_type, SUM(rs.count_executions) AS execution_count, SUM ( CONVERT(decimal(38,4), rs.avg_cpu_time) * rs.count_executions ) AS total_cpu_us FROM sys.query_store_runtime_stats AS rs GROUP BY rs.plan_id, rs.runtime_stats_interval_id, rs.execution_type ) SELECT TOP (20) q.query_id, qt.query_sql_text, SUM(r.execution_count) AS executions, CAST ( SUM(r.total_cpu_us) AS decimal(38,2) ) AS total_cpu_us FROM RuntimeStats AS r JOIN sys.query_store_runtime_stats_interval AS rsi ON r.runtime_stats_interval_id = rsi.runtime_stats_interval_id JOIN sys.query_store_plan AS p ON r.plan_id = p.plan_id JOIN sys.query_store_query AS q ON p.query_id = q.query_id JOIN sys.query_store_query_text AS qt ON q.query_text_id = qt.query_text_id WHERE r.execution_type = 0 AND rsi.end_time > @StartTime GROUP BY q.query_id, qt.query_sql_text ORDER BY executions DESC; This becomes particularly important when diagnosing compilation problems because a high-frequency workload can amplify a relatively small inefficiency thousands of times per second. 7. What Does a Compilation Storm Look Like? A compilation storm usually isn't one expensive compilation. It's a workload pattern. Signals worth investigating include: Large numbers of nearly identical queries. Literal values embedded into otherwise identical SQL statements. Poor plan reuse. Elevated compile counts. Rapid plan generation. Temporary-object-heavy execution. Dynamically generated SQL where query text changes unnecessarily. Application parameter types that don't align with SQL types. For example, an application might continuously submit: SELECT OrderID, OrderDate FROM dbo.Orders WHERE CustomerID = 1001; Then: SELECT OrderID, OrderDate FROM dbo.Orders WHERE CustomerID = 1002; Then: SELECT OrderID, OrderDate FROM dbo.Orders WHERE CustomerID = 1003; Compare that with an appropriately parameterized application call: DECLARE @CustomerID int = 1001; EXEC sys.sp_executesql N' SELECT OrderID, OrderDate FROM dbo.Orders WHERE CustomerID = @CustomerID; ', N'@CustomerID int', @CustomerID = @CustomerID; Parameterized SQL can make plan reuse possible when the workload characteristics make reuse appropriate. But there's an important caveat: Parameterization itself is not universally better. Highly skewed data distributions can produce different optimal plans for different parameter values. The target isn't: "Reuse every plan." It's: Avoid unnecessary compilation while preserving appropriate plan choices. 8. Look for Plan Churn and Compilation Activity Query Store can help identify queries associated with multiple retained plans and elevated compile activity. SELECT TOP (50) q.query_id, COUNT(DISTINCT p.plan_id) AS plan_count, COUNT(DISTINCT p.query_plan_hash) AS distinct_plan_shapes, q.count_compiles, q.initial_compile_start_time, q.last_compile_start_time, CAST ( q.avg_compile_duration AS decimal(20,2) ) AS avg_compile_duration_us, q.last_compile_duration AS last_compile_duration_us, CAST ( q.avg_optimize_cpu_time AS decimal(20,2) ) AS avg_optimize_cpu_time_us FROM sys.query_store_query AS q JOIN sys.query_store_plan AS p ON q.query_id = p.query_id GROUP BY q.query_id, q.count_compiles, q.initial_compile_start_time, q.last_compile_start_time, q.avg_compile_duration, q.last_compile_duration, q.avg_optimize_cpu_time HAVING COUNT(DISTINCT p.plan_id) > 1 ORDER BY plan_count DESC, q.count_compiles DESC; This distinction is important: Multiple Query Store plans do not automatically mean harmful plan churn. Query Store intentionally maintains query and plan history. Multiple plans may be perfectly legitimate because of: Plan changes over time. Statistics changes. Index changes. Parameter-sensitive behavior. Database changes. Query Store history. Intentional plan management. The signal becomes more interesting when multiple plans correlate with: High compile counts. Compilation during the incident. Rising CPU. Large latency variation. Performance regression. Also compare: COUNT(DISTINCT p.plan_id) with: COUNT(DISTINCT p.query_plan_hash) Several retained plan records don't necessarily mean several materially different plan shapes. 9. Look for Queries With Large Duration Variation Average latency can hide an important problem. A query averaging 30 ms might look harmless until some executions take several seconds. Use Query Store to identify significant variation: DECLARE @StartTime datetimeoffset = DATEADD(HOUR, -1, SYSUTCDATETIME()); WITH RuntimeStats AS ( SELECT rs.plan_id, rs.runtime_stats_interval_id, rs.execution_type, SUM(rs.count_executions) AS execution_count, SUM ( CONVERT(decimal(38,4), rs.avg_duration) * rs.count_executions ) AS total_duration_us, MAX(rs.max_duration) AS max_duration_us FROM sys.query_store_runtime_stats AS rs GROUP BY rs.plan_id, rs.runtime_stats_interval_id, rs.execution_type ) SELECT TOP (30) q.query_id, COUNT(DISTINCT p.plan_id) AS plan_count, SUM(r.execution_count) AS execution_count, CAST ( SUM(r.total_duration_us) / NULLIF(SUM(r.execution_count), 0) AS decimal(20,2) ) AS weighted_avg_duration_us, MAX(r.max_duration_us) AS max_duration_us, CAST ( MAX(r.max_duration_us) / NULLIF ( SUM(r.total_duration_us) / NULLIF(SUM(r.execution_count), 0), 0 ) AS decimal(20,2) ) AS max_to_average_ratio FROM RuntimeStats AS r JOIN sys.query_store_runtime_stats_interval AS rsi ON r.runtime_stats_interval_id = rsi.runtime_stats_interval_id JOIN sys.query_store_plan AS p ON r.plan_id = p.plan_id JOIN sys.query_store_query AS q ON p.query_id = q.query_id WHERE r.execution_type = 0 AND rsi.end_time > @StartTime GROUP BY q.query_id ORDER BY max_to_average_ratio DESC; Large variation can justify investigating: Parameter-sensitive behavior. Blocking. Different execution plans. Data skew. Changing memory requirements. Concurrent workload effects. It doesn't, by itself, tell us which one is responsible. 10. Use Query Store Wait Categories Correctly Wait information provides another dimension. Query Store can associate wait categories with query plans and runtime intervals. That's an important distinction. Query Store isn't intended to provide a historical record of every individual SQL Server wait type. The following query summarizes Query Store waits for approximately the last hour: DECLARE @StartTime datetimeoffset = DATEADD(HOUR, -1, SYSUTCDATETIME()); WITH WaitStats AS ( SELECT ws.plan_id, ws.runtime_stats_interval_id, ws.execution_type, ws.wait_category, ws.wait_category_desc, SUM(ws.total_query_wait_time_ms) AS total_wait_ms FROM sys.query_store_wait_stats AS ws GROUP BY ws.plan_id, ws.runtime_stats_interval_id, ws.execution_type, ws.wait_category, ws.wait_category_desc ) SELECT TOP (30) w.wait_category_desc, SUM(w.total_wait_ms) AS total_wait_ms FROM WaitStats AS w JOIN sys.query_store_runtime_stats_interval AS rsi ON w.runtime_stats_interval_id = rsi.runtime_stats_interval_id WHERE w.execution_type = 0 AND rsi.end_time > @StartTime GROUP BY w.wait_category_desc ORDER BY total_wait_ms DESC; Look for categories associated with: Locking. CPU. Parallelism. Buffer I/O. Transaction log activity. Memory. Other resource pressure. Use these categories to determine where the next investigation should go, not as standalone proof of root cause. 11. Capture Exact Wait Types During an Active Incident When the issue is occurring now, live DMVs can provide more specific evidence. For example: SELECT wt.session_id, wt.exec_context_id, wt.wait_type, wt.wait_duration_ms, wt.blocking_session_id, r.status, r.command, r.cpu_time, r.total_elapsed_time, r.logical_reads, r.reads, r.writes, wt.resource_description FROM sys.dm_os_waiting_tasks AS wt LEFT JOIN sys.dm_exec_requests AS r ON wt.session_id = r.session_id WHERE wt.session_id <> @@SPID ORDER BY wt.wait_duration_ms DESC; This creates an important analytical distinction. Query Store Use it for: Historical query behavior. Historical plan behavior. Runtime statistics. Historical wait categories. Live DMVs Use them for: Specific waits occurring now. Current requests. Current blocking. Current resource use. For example, individual waits such as: RESOURCE_SEMAPHORE_QUERY_COMPILE or: SOS_SCHEDULER_YIELD need to be interpreted alongside the rest of the evidence. A compile-related wait doesn't automatically prove that compilation CPU caused the incident. Likewise, a scheduler-related wait doesn't automatically prove that MAXDOP is wrong. 12. Don't Ignore Data-Type Mismatches Another frequently overlooked issue is inconsistent data types between the application and database. Imagine a column defined as: CustomerCode varchar(30) while the application sends: @CustomerCode nvarchar(30) Or perhaps the column is: CustomerID int while the application uses: bigint Depending on the particular expression and conversion direction, an implicit conversion may affect: Index access methods. Cardinality estimation. Plan selection. Reads. CPU consumption. As a general principle: Application parameter definitions should align with the corresponding database column types wherever practical. Compare: Data type. Length. Precision. Scale. Unicode versus non-Unicode. Collation when relevant. Don't reach for a hint when the underlying problem is an application/database contract mismatch. 13. Temporary Tables Require Evidence, Not Assumptions Temporary tables are useful and common SQL Server constructs. They're not inherently a performance problem. However, some workloads repeatedly: Create temporary tables. Populate them. Modify them. Create or drop temporary indexes. Execute queries heavily dependent on temporary-table cardinality. Those patterns can affect optimization and recompilation behavior. The important troubleshooting principle is: Don't rewrite temporary-table logic just because compilation appears high. First demonstrate the relationship. Correlate: Compilation timing. Procedure executions. Query Store history. CPU peaks. Plan variation. Application workload cycles. Then decide whether temporary-table behavior actually requires modification. 14. OPTION (RECOMPILE) Is Not a Universal Compilation Fix This hint deserves particular care: SELECT ... FROM ... WHERE ... OPTION (RECOMPILE); OPTION (RECOMPILE) instructs SQL Server to compile a new temporary plan for that execution rather than reuse the normal cached plan for the statement. That can be very useful for certain parameter-sensitive workloads. For example: A query behaves very differently for different parameter populations. Reusing one cached plan consistently produces poor performance. Compilation cost is small compared with savings in execution cost. But consider the problem we're investigating. If the workload already suffers from excessive compilation, broadly introducing OPTION (RECOMPILE) may increase compilation work. Treat it as: A targeted tool. A workload-specific optimization. A controlled experiment. A change requiring before-and-after measurement. Not as: A universal response to high CPU. A default fix for plan instability. A general cure for compilation storms. 15. MAXDOP Is Not a Universal CPU Fix Either Suppose CPU and worker utilization are both elevated. Should we immediately lower MAXDOP? Not necessarily. MAXDOP controls the maximum degree of parallelism available to a parallel query plan. It doesn't directly fix: Excessive compilation. Poor parameterization. Blocking. Inefficient serial queries. Excessive application concurrency. Data-type mismatches. Poor indexes. Check the database-scoped setting: SELECT name, value, value_for_secondary FROM sys.database_scoped_configurations WHERE name = N'MAXDOP'; Then determine whether parallelism is genuinely implicated. Ask: Are the CPU-dominant queries running parallel plans? Are parallel requests consuming a meaningful share of workers? Does the workload benefit from parallelism? Would reducing parallelism decrease worker pressure but increase latency? Is concurrency the real problem instead? The correct reasoning is not: High workers = reduce MAXDOP. It is: Determine whether intra-query parallelism is materially contributing to the observed resource pressure. Also remember that database-scoped configuration changes can result in plan invalidation and subsequent recompilation. Configuration experiments should therefore be controlled and monitored. 16. Be Careful With Forced Plans Query Store allows you to force a selected plan. That's an extremely useful capability. It's also easy to misuse. A plan that was historically fast isn't automatically safe for: Every parameter value. Every data distribution. Every concurrency level. Every future workload. Before forcing a plan, evaluate: Parameter sensitivity. Data distribution. Query execution frequency. CPU. Duration. Logical reads. Memory use. Concurrency. Performance across representative parameter values. If the evidence supports a controlled test: EXEC sys.sp_query_store_force_plan @query_id = 123, plan_id = 456; Monitor forcing status: SELECT plan_id, query_id, is_forced_plan, force_failure_count, last_force_failure_reason, last_force_failure_reason_desc FROM sys.query_store_plan WHERE query_id = 123; And have a rollback path: EXEC sys.sp_query_store_unforce_plan @query_id = 123, plan_id = 456; Replace the sample IDs with the Query Store identifiers from your own database. Most importantly: Plan forcing attempts to reproduce the selected plan. It shouldn't be treated as a guarantee that future execution will always behave exactly like the historical execution you're trying to reproduce. Treat plan forcing as a controlled intervention rather than an automatic response to plan variation. 17. A Practical Remediation Ladder Once you've identified the likely source of resource consumption, move from structural corrections toward infrastructure scaling. Step 1: Correct data-type mismatches Align: Application parameters. Database columns. Stored procedure parameters. Dynamic SQL parameter definitions. Step 2: Reduce unnecessary query-shape variation Use appropriate parameterization where the workload benefits from plan reuse. Avoid generating thousands of logically identical query strings simply because literal values change. Step 3: Investigate high-frequency workload patterns Determine whether the problem is a single expensive query or thousands of inexpensive queries executed continuously. Step 4: Investigate temporary-table behavior Only redesign temporary-table logic when evidence links it to: Recompilation. Poor cardinality estimates. Plan instability. Excessive CPU. Step 5: Control burst concurrency If large numbers of requests arrive simultaneously, consider: Application-side throttling. Batching. Queuing. Staggering jobs. Reducing redundant requests. Controlling parallel application calls. Step 6: Optimize genuinely expensive execution Investigate: Index design. Logical reads. Access methods. Cardinality estimates. Join strategies. Memory grants. Parameter-sensitive behavior. Parallel execution. Step 7: Use targeted plan interventions Where supported by evidence, consider: Query Store plan forcing. Query Store hints. Carefully tested query hints. Always define: What behavior you're trying to change. What success looks like. How long you'll observe it. What triggers rollback. Step 8: Scale when the workload genuinely requires it Scaling is completely reasonable when: Workload optimization has been assessed. Business growth has increased concurrency. CPU demand represents useful execution work. Latency requirements justify additional compute. Scaling is the lowest-risk mitigation for an active business impact. The optimized workload legitimately requires more capacity. The important distinction is: Scaling should solve a capacity problem, not simply hide an unexplained workload problem. 18. Scale or Fix? Use the following matrix as a starting point. Observation Likely investigation First response High CPU + a few queries dominate CPU Execution pressure Investigate plans, reads, indexes, and query design High CPU + many similar query texts Parameterization/compilation Investigate query generation and plan reuse High workers + moderate CPU + blocking Waiting/concurrency Investigate blockers and transaction duration High CPU + high Data I/O Data-access pressure Investigate scans, logical/physical reads, and indexes High CPU + large plan variation Plan instability Correlate Query Store plans with performance periods Sudden spike after application release Workload change Compare deployment timing with query behavior Predictable scheduled spike Burst workload Tune, stagger, batch, or provide appropriate capacity Optimized workload + sustained legitimate CPU demand Capacity Consider scaling Scaling helps temporarily but the pattern repeatedly returns Workload or capacity issue still unexplained Revisit root-cause evidence This matrix is diagnostic, not an Azure SQL service guarantee. There is no universal CPU percentage or worker percentage at which every workload should automatically scale. 19. Validate the Fix A performance investigation isn't complete when CPU drops once. Validate the change against an equivalent workload cycle. Compare: CPU utilization. Worker utilization. Session utilization. Execution counts. Query CPU. Query duration. Query Store wait categories. Relevant plan counts. Application latency. Application timeouts. Start again with: SELECT end_time, avg_cpu_percent, max_worker_percent, max_session_percent, avg_data_io_percent, avg_log_write_percent, avg_memory_usage_percent FROM sys.dm_db_resource_stats ORDER BY end_time DESC; Whenever possible, compare equivalent periods: Same business workload. Same scheduled job. Similar request volume. Similar concurrency. Similar parameter distribution. Don't declare success simply because the workload disappeared. 20. Define Regression Criteria Before Deployment Before applying a tuning change, decide what constitutes failure. Possible rollback signals include: CPU becomes materially worse. P95 or P99 application latency regresses. Worker utilization rises. Timeouts increase. Logical reads rise materially. Another parameter population becomes slower. Query Store reveals a plan regression. These aren't universal thresholds. Define them according to: Your workload baseline. Application requirements. Business SLAs or SLOs. Normal workload variation. 21. Build an Escalation-Ready Evidence Package If further investigation or escalation is required, a clear evidence package dramatically reduces troubleshooting time. Include: Incident start and end in UTC. CPU timeline. Worker timeline. Session timeline. Memory timeline. Data I/O timeline. Log-write timeline. Sanitized Query Store identifiers. Relevant execution plans. Query Store wait categories. Live wait types captured during the incident. Compile counts. Query execution counts. Application deployment timeline. Scheduled workload information. Reproduction steps, when available. Separate your conclusions into two categories. Facts Examples: CPU increased during the incident window. Worker utilization increased at the same time. Query Store contained multiple plans. Compile counts were elevated. Execution count rose. Blocking was observed. Latency increased following a deployment. Hypotheses Examples: Compilation contributed materially to CPU utilization. Application-generated query variation reduced plan reuse. Temporary-table behavior contributed to recompilation. Parameter sensitivity contributed to latency variation. Increased concurrency amplified an existing query-performance problem. This distinction matters. Correlation is evidence. It isn't automatically root cause. 22. The Complete Diagnostic Decision Tree When Azure SQL CPU or worker utilization suddenly climbs, use this sequence. Question 1: Is CPU high? No Investigate: Workers. Blocking. Waits. Sessions. Long-running transactions. Concurrency. Yes Continue. Question 2: Do a small number of queries explain most execution CPU? Yes Investigate: Execution plans. Logical reads. Indexing. Cardinality estimates. Parallelism. Parameter sensitivity. No Broaden the investigation toward: Compilation. Query frequency. Concurrency. Workload shape. Question 3: Is there significant query-text or plan variation? Yes Investigate: Application parameterization. Dynamic SQL generation. Compile counts. Plan history. Parameter sensitivity. No Continue. Question 4: Are workers primarily waiting? Yes Investigate: Blocking. Locks. Long-running transactions. Current waits. Application concurrency. No Continue. Question 5: Are data I/O or log-write resources saturated? Yes Investigate those as potential independent bottlenecks. No Continue CPU-focused analysis. Question 6: Does compilation activity correlate with the CPU window? Yes Investigate: Query-shape variation. Parameterization. Recompilation. Application request patterns. Temporary-object behavior. No Return to: Execution CPU. Concurrency. Parallelism. Other engine work. Question 7: Does the workload still need additional compute after optimizations are assessed? Yes Scaling is appropriate. No Fix the workload behavior first. Final Takeaway The most important lesson is simple: High CPU describes a symptom. It doesn't identify the cause. The same applies to workers. High worker utilization doesn't necessarily mean Azure SQL Database needs more workers or more vCores. Before scaling or changing MAXDOP, determine whether the database is primarily: Executing expensive work. Executing inexpensive work far too frequently. Compiling excessive work. Waiting on other work. Handling excessive concurrency. Moving too much data. Generating unnecessary query variations or plans. The strongest diagnosis comes from correlating multiple sources of evidence: sys.dm_db_resource_stats. Query Store execution statistics. Query Store plan history. Query Store compilation information. Query Store wait categories. Live wait information. Execution plans. Application and deployment timelines. Sometimes the correct answer really is more compute. But if the underlying problem is unnecessary compilation, poor parameterization, blocking, uncontrolled concurrency, or inefficient queries, additional compute might simply give the problem more room to grow. Diagnose first. Optimize where the evidence points. Scale when the workload actually needs it. Further Reading For more information on the concepts and diagnostic techniques discussed in this article, refer to the following official Microsoft documentation: https://learn.microsoft.com/en-us/sql/relational-databases/system-dynamic-management-views/sys-dm-db-resource-stats-azure-sql-database sys.resource_stats (Azure SQL Database) Monitor performance by using the Query Store Best practices for monitoring workloads with Query Store sys.query_store_query (Transact-SQL) sys.query_store_plan (Transact-SQL) sys.query_store_runtime_stats (Transact-SQL) sys.query_store_wait_stats (Transact-SQL) https://learn.microsoft.com/en-us/sql/relational-databases/system-dynamic-management-views/sys-dm-os-waiting-tasks-transact-sql sp_query_store_force_plan (Transact-SQL) Configure the maximum degree of parallelism (MAXDOP) in Azure SQL Database https://learn.microsoft.com/en-us/sql/relational-databases/performance/query-store-hints Query Store hints best practices275Views0likes0CommentsLessons Learned #562: Measuring the Work Behind Statistics Updates in Azure SQL Database
A few extra milliseconds during a stress test While working on a support case, our customer was running stress tests against an Azure SQL Database. They noticed a small but interesting variation: occasionally, a query took a few milliseconds longer and appeared to use slightly more CPU. They wanted to understand what was happening during those executions. The difference was small, but the question was useful. What additional work was being performed during those periods, and could we measure it? While reviewing Query Store, I came across queries containing a familiar pattern: SELECT StatMan(...). They reminded me of an article I had written some time ago, Lesson Learned #498: Understanding the Role of STATMAN in SQL Server and Its Resource Consumption, about the internal work involved in statistics updates. Recognizing that pattern gave me a starting point: I could use the execution statistics recorded in Query Store to investigate how much time, CPU, and I/O those statements had consumed during the stress test I would like to share what I found and the query I used to inspect that work. It provides a way to measure the duration, CPU, and reads attributed to recorded StatMan executions, and then compare their activity with the period being investigated. Finding that statistics calculation consumed resources is one part of the investigation. Establishing how much it contributed to the customer's extra milliseconds requires correlating those records with the affected workload. The sections below explain both what we can measure and how to interpret it. Looking beyond the last update time sys.dm_db_stats_properties provides the last update time and sampling information, but does not preserve the duration or resource consumption of the update. The workload query plan identifies statistics loaded during compilation through OptimizerStatsUsage, but does not provide a separate runtime measurement for each statistics calculation. Because Query Store already contained these internal statements in our test, we could inspect their historical resource consumption without configuring a new Extended Events session. Finding StatMan in Query Store StatMan is used internally during statistics calculation. Its query text can include the table and columns being processed and an alias such as _MS_UPDSTATS_TBL. We are inspecting recorded engine-generated statements, not invoking StatMan directly. The following read-only query was tested successfully in our Azure SQL Database. Run it in the database being investigated and adjust the UTC dates. It returns statistics by query, plan, interval, and execution type. Query Store must already contain the relevant statements and runtime data. Query Store inspection query DECLARE @FromUtc datetimeoffset = '2026-10-20T00:00:00+00:00'; DECLARE @ToUtc datetimeoffset = '2026-10-26T00:00:00+00:00'; ;WITH RuntimeStats AS ( SELECT rs.plan_id, rs.runtime_stats_interval_id, rs.execution_type_desc, MIN(rs.first_execution_time) AS first_execution_end_utc, MAX(rs.last_execution_time) AS last_execution_end_utc, SUM(rs.count_executions) AS executions, SUM(rs.avg_duration * rs.count_executions) AS total_duration_us, MAX(rs.max_duration) AS max_duration_us, SUM(rs.avg_cpu_time * rs.count_executions) AS total_cpu_us, SUM(rs.avg_logical_io_reads * rs.count_executions) AS total_logical_reads, SUM(rs.avg_physical_io_reads * rs.count_executions) AS total_physical_reads FROM sys.query_store_runtime_stats AS rs JOIN sys.query_store_runtime_stats_interval AS i ON i.runtime_stats_interval_id = rs.runtime_stats_interval_id WHERE i.start_time < @ToUtc AND i.end_time > @FromUtc GROUP BY rs.plan_id, rs.runtime_stats_interval_id, rs.execution_type_desc ) SELECT q.query_id, p.plan_id, q.is_internal_query, i.start_time AS interval_start_utc, i.end_time AS interval_end_utc, r.execution_type_desc, r.first_execution_end_utc, r.last_execution_end_utc, r.executions, r.total_duration_us / NULLIF(r.executions, 0) / 1000.0 AS avg_duration_ms, r.max_duration_us / 1000.0 AS max_duration_ms, r.total_duration_us / 1000000.0 AS total_duration_seconds, r.total_cpu_us / 1000000.0 AS total_cpu_seconds, r.total_logical_reads, r.total_physical_reads, qt.query_sql_text FROM RuntimeStats AS r JOIN sys.query_store_plan AS p ON p.plan_id = r.plan_id JOIN sys.query_store_query AS q ON q.query_id = p.query_id JOIN sys.query_store_query_text AS qt ON qt.query_text_id = q.query_text_id JOIN sys.query_store_runtime_stats_interval AS i ON i.runtime_stats_interval_id = r.runtime_stats_interval_id WHERE qt.query_sql_text LIKE N'%StatMan%' AND qt.query_sql_text NOT LIKE N'%query_store%' ORDER BY total_duration_seconds DESC; Reading the results Start by checking query_sql_text to confirm that a returned row is an actual SELECT StatMan(...) statement. The text filter is a search aid, not a definitive classification. The second predicate excludes common diagnostic queries that reference Query Store while searching for StatMan. executions shows the number of recorded executions for that plan, interval, and execution type. avg_duration_ms is the execution-count-weighted average duration. max_duration_ms identifies the slowest recorded execution within the group. total_duration_seconds and total_cpu_seconds estimate accumulated execution duration and CPU from the recorded averages multiplied by execution counts. total_logical_reads and total_physical_reads estimate accumulated page reads from the recorded averages. Query Store reports these reads as counts of 8 KB pages. is_internal_query identifies whether Query Store marks the query as internally generated. Inspect execution_type_desc to distinguish regular, aborted, and exception executions. Query Store reports runtime duration and CPU in microseconds. The query converts them to milliseconds or seconds as indicated by the output names. Its grouping also accounts for multiple runtime-statistics rows that can exist for the active interval. Interpreting the time window The date filter selects intervals that overlap the requested window. Those intervals are included in full, including executions outside the precise requested boundaries. Use interval boundaries aligned with your investigation when possible. first_execution_end_utc and last_execution_end_utc identify execution completion times, not start times. Query Store aggregates executions. When executions is greater than one, a row does not describe one individual update. Summed durations are not an end-to-end wall-clock measurement, especially when operations overlap. CPU can also exceed elapsed time when execution is parallel. From recorded consumption to workload impact The results quantify the recorded work attributed to StatMan. A high total can justify investigating its contribution to CPU or I/O during the same period, but does not by itself prove that it caused application latency or blocking. Correlate those observations with workload performance and resource metrics. The StatMan statement need not include every phase of the surrounding statistics update. Its text alone does not establish whether the update was automatic or explicitly requested. If the query returns no rows, it does not prove that statistics were not updated. The relevant statements may not have been captured or retained, or their runtime data may not be available in the selected window. Extended Events as an alternative We also observed StatMan through sp_statement_completed in a database-scoped Extended Events session during testing. Extended Events can provide individual statement observations when a suitable capture is available. Lessons learned When StatMan is present in Query Store, we can examine historical duration, CPU, and reads for the statistics-calculation statements already recorded. This provides a practical starting point for understanding their resource consumption while preserving the distinction between internal statement cost, the full statistics update, and impact on the workload. References Query Store runtime statistics Query Store query metadata Statistics in SQL Server and Azure SQL Database Lesson Learned 498 Understanding the Role of STATMAN in SQL Server and Its Resource Consumption257Views2likes0CommentsLessons Learned #560: SQL Is Slow — What Can Query Store and SSMS Copilot Uncover?
In our recently delivered session, “SQL Is Slow — What Can Query Store and SSMS Copilot Uncover?”, we demonstrated step by step how to investigate a performance problem by combining Query Store with Copilot’s capabilities in SSMS. The demonstration starts with a PHP program executing queries while we grow a table from a few hundred to millions of rows. As different execution plans appear and performance changes, we follow the evidence in Query Store to uncover what is happening and decide what to investigate next. One clue stood out. The query took about 12 milliseconds per execution in one interval and almost 2.5 seconds in another interval under the same Plan ID. Other plans appeared during the complete lab. Understanding both the differences between plans and the changes within a plan became part of the investigation. Along the way, we demonstrated how a guided conversation with Copilot can become an Agent investigation, and how the investigation itself can be captured in a reusable skill. The useful result was a method that keeps asking for evidence before accepting an explanation. The session brings the two tools together: Query Store supplies the recorded history, and Copilot helps us examine it and decide what to investigate next. The same troubleshooting story lets the audience follow Ask mode, Agent mode and the reusable skill without losing the connection to the underlying SQL evidence. A growing table and several execution plans For our sessions, we use a PHP program that generates 16 different simulations of performance and connectivity problems, allowing us to demonstrate how to investigate these scenarios through practical demos. We also have code developed in .NET and Java. In this demonstration, we add records to dbo.Notes in stages, reaching approximately 200, 32,000, 65,000, 2 million, and 4 million rows, while the PHP program executes dbo.GiveNotes with different @N values. This lets us observe how performance and execution plans evolve as the data volume grows. Several execution plans accumulated during the complete demonstration. We compared all of them, then inspected the runtime intervals within each Plan ID. The reference run revealed this change within the history of one plan: Average per execution Healthy interval Degraded interval Approximate increase CPU 7.69 ms 1,443.19 ms 188 times Duration 12.39 ms 2,473.68 ms 200 times Logical reads 68.39 12,233.10 179 times The duration increase was approximately 200 times. This comparison covers two intervals for one Plan ID, not the whole sequence of table sizes. It does not assign a particular plan or timing to each row-count stage. These are lab observations; identifiers and timings vary between runs. The reads were particularly revealing. Each execution was touching far more pages. A later plan change could not, by itself, explain degradation that had already started while the earlier plan remained in use. The next step was to investigate what had increased the work per execution. Build the timeline before choosing the explanation We first compared workload contributors using total CPU, elapsed duration, logical reads and execution count. Total consumption identified where the workload impact was concentrated; averages per execution helped distinguish expensive executions from a high volume of individually inexpensive calls. Next, we collected every plan for the selected query and compared runtime intervals chronologically. We discovered the identifiers from the database instead of supplying fixed Query IDs or Plan IDs. We asked both when another plan appeared and whether the cost had already increased before that change. A plan summary alone can hide this story. One average across a plan’s entire history blends its healthy and degraded periods. The interval history shows when the work changed and whether that happened before another plan appeared. Aggregation mattered. When combining runtime statistics, we weighted each average by its execution count. A simple average of interval averages would give a lightly used interval the same influence as a heavily used one. We also kept units explicit and separated execution types where needed. Weighted average = SUM(average value * execution count) / SUM(execution count) The increase in logical reads directed the investigation toward the amount of data processed and the access path. Waits could help explain elapsed time, but waits alone would not explain that increase in reads. dbo.GiveNotes filtered dbo.Notes on ID < @N and grouped by Name. The clustered primary key was on id2, a different column from the predicate. As rows were added, a reused plan could process more data; changing @N could also change how many rows qualified. A new Plan ID was a separate event to investigate, not an explanation to assume. Different @N values can qualify different numbers of rows, and table growth can increase the work even with an unchanged plan. We inspected distribution, statistics and access paths to test that explanation. Query Store interval averages alone do not tell us the parameter used by every execution, and parameter-sensitive behavior does not automatically prove parameter sniffing. One investigation through three Copilot experiences In Ask mode, we guided the conversation one question at a time. We first requested the Query Store overview, then asked which contributor to investigate and how its plans behaved over time. The staged prompts delayed statistics, index and parameter analysis until the runtime evidence justified those questions. Where required, we ran generated diagnostic T-SQL and brought the results back into the conversation. In Agent mode, we supplied the investigation goal and allowed Copilot to choose and execute diagnostic steps using the available SQL tools. We reviewed the proposed actions and kept the investigation read-only. The agent could use each result to decide what to inspect next. Finally, we captured the sequence in an Agent Skill. We wanted the next investigation to preserve the critical question: did the query become more expensive while the same plan was still being reused? Agent Skills provide task-specific instructions that Copilot can discover and use in Agent mode. We also demonstrated the reusable method through GitHub Copilot CLI. Database execution still requires a configured SQL tool or MCP server; without that capability, the workflow must generate diagnostics for the engineer to run. What we put into the reusable skill The SQL Performance Investigator pack captures the diagnostic sequence alongside the calculation rules and starting prompts. The agent is instructed to: Identify the main workload contributor and retain its Query ID. Collect all associated plans and their runtime history. Check whether degradation began while the same plan remained in use. Investigate relevant selectivity, statistics and index evidence. Separate confirmed observations from hypotheses and propose validation. A skill makes the method reusable; it does not guarantee the diagnosis is correct. Missing history, incorrect aggregation or a plausible but unsupported inference still need an engineer’s attention. We kept discovery read-only, with SQL permissions enforcing the access boundary. A proposed index still needs evidence of improvement In the demonstration, we evaluated an index with ID as its leading key and Name as an included column: CREATE NONCLUSTERED INDEX NOTES_IX1 ON dbo.Notes (ID) INCLUDE (Name); The key matches the range predicate, while the included column makes Name available for the aggregation. Whether this improves the workload depends on selectivity, data volume and the competing plans. Its storage and write costs also matter. We treated this as a remediation candidate. Validation requires a comparable workload, including parameter distribution and concurrency, followed by a Query Store comparison of reads, CPU, duration and variability. We did not equate an index recommendation with a demonstrated improvement. Statistics also need careful interpretation. An index histogram describes its leading key; adding Name as an INCLUDE column does not create a histogram on Name. An existing auto-created statistic should not be dropped merely because its column appears in a covering index. The lesson we took from the demonstration The complete story contained a growing table and multiple plans. Within that history, one plan became much more expensive before a later plan could explain the change. Comparing plans and examining changes within each plan gave us complementary evidence. Copilot helped us follow it, and the skill preserved the investigation sequence for another database. We enjoyed presenting this session. For DBAs, developers and support engineers, the session offers a practical way to watch a performance investigation unfold, from the PHP workload and Query Store history to the prompts and reusable skill. We look forward to continuing this demonstration and discussion with SQL user groups and the wider technical community. If you have encountered a query that became slower while the same plan remained in use, which evidence helped you explain the change? We would be interested to hear how you approached it. References and prerequisites For the SSMS Agent and Skills experience described here, Microsoft documents SSMS 22.7 or later with the AI Assistance workload and GitHub Copilot access. Query Store must be enabled with relevant history available. Specify the target server and database in the Agent prompt rather than relying on the active editor context. Check the current documentation before reproducing the session. GitHub Copilot Agent mode in SSMS Agent Skills in SSMS Monitoring performance by using Query Store Query Store runtime statistics Try the investigation with our prompts These prompts offer a practical starting point for the method demonstrated in our session. The Ask prompt is the opening prompt from our session workflow. The Agent prompts are adapted from our accompanying pack to make the target server, database and investigation window explicit. Replace the angle-bracket placeholders before submitting them. Start with Ask mode We began with a request for evidence, deliberately postponing diagnosis. Run the generated diagnostic query against the intended lab database and use its results for the next questions. I want to start a SQL performance troubleshooting investigation using Query Store. Generate a single read-only T-SQL query that I can execute in the current database to identify the main performance contributors. The query must use Query Store and return, for each query: * Query ID * Query text * Object or stored procedure name, when available * Number of execution plans * Number of executions * Total CPU time * Average CPU time per execution * Total duration * Average duration per execution * Total logical reads * Average logical reads per execution Aggregate Query Store runtime statistics correctly across runtime intervals and execution plans. Use weighted calculations based on count_executions. Do not calculate averages by simply averaging Query Store average values. Return CPU and duration values in milliseconds. Rank the results by total CPU consumption, but include all the metrics above so that we can determine later which resource is having the highest impact. Do not perform root-cause analysis yet. Do not include execution plan analysis, parameter sensitivity, statistics analysis, index analysis, or remediation recommendations. Only generate the read-only diagnostic T-SQL query that I should execute. We then asked which resource deserved investigation, which query contributed most, how all its plans performed over time, and whether the same Plan ID had become more expensive. Only after those answers did we investigate selectivity, statistics and indexes. The complete session workflow contains the staged follow-up prompts. Convert the conversation into an Agent investigation We moved the recurring calculation rules and diagnostic sequence into sql-performance-investigator. The starting prompt could then state the goal, scope and execution boundaries. The skill supplies the detailed method; the available SQL tools supply execution capability. The agent retains the discovered query and plan identifiers within the investigation. It should not ask the engineer to copy them between steps or assume the identifiers from a previous lab run. Run the method in SSMS Agent mode Make the skill available to SSMS, select Agent mode and verify the SQL tools are enabled. Specify the target explicitly because Agent mode does not inherit the active query editor context. Investigate the SQL performance problem on server <server>, database <database>, using Query Store for <UTC start> to <UTC end>. Use the sql-performance-investigator skill. Use the available sql-tools to execute read-only diagnostics and continue through the investigation, requesting approval where the host requires it. Automatically discover the dominant performance metric, target query, Query ID, all Plan IDs, runtime history, and any same-plan degradation. Retain the discovered identifiers internally. Investigate the evidence needed to explain the change, including selectivity, data distribution, statistics and existing indexes when relevant. Do not assume a plan change caused the degradation or label it parameter sniffing without evidence. Keep confirmed evidence, inference, hypotheses and missing evidence separate. Use execution-weighted averages and explicit units. If the requested history or permissions are unavailable, report the limitation. Do not create/drop indexes, update/drop statistics, force plans, clear caches, modify Query Store, or change data/schema. Finish with a supported diagnosis or remaining uncertainty, a proposed remediation if justified, and a Query Store before/after validation plan. Do not execute remediation. Use the same method in GitHub Copilot Our pack places the skill at .github/skills/sql-performance-investigator/SKILL.md and the Custom Agent at .github/agents/sql-performance-investigator.agent.md. The skill references workflow.md and query-store-rules.md for the detailed method. In GitHub Copilot CLI, select the SQL Performance Investigator custom agent and use this adapted starting prompt: Use the SQL Performance Investigator custom agent and the sql-performance-investigator skill. Investigate SQL performance on <server>, database <database>, for <UTC start> to <UTC end>, using Query Store from evidence to diagnosis. If a SQL execution tool/MCP is available, run only read-only diagnostics and continue through the investigation. Discover Query IDs and Plan IDs automatically and retain them internally. Follow the host approval requirements. If no SQL execution capability is available, generate one self-contained read-only diagnostic batch for me to run, then continue when I provide the result. Do not claim that SQL was executed. Do not apply remediation. Propose an index/statistics action only after the evidence supports it. Finish with a before/after Query Store validation plan. The reusable asset is the investigation procedure behind these prompts. Query Store supplies the evidence, Copilot helps carry out the investigation, and the engineer reviews whether the explanation and proposed change are supported by the results.281Views0likes0CommentsAzure SQL Performance Troubleshooting: When High Latency Is Not High CPU
When an application connected to Azure SQL Database becomes slow or starts timing out, one of the first questions is usually: Is the database running out of CPU? It's a reasonable starting point, but CPU is only one part of the performance story. Some Azure SQL performance problems occur while CPU, Data IO, and worker utilization appear healthy. The database may have plenty of compute capacity while queries spend most of their time waiting rather than executing. The key troubleshooting question is therefore not simply: "How much CPU is Azure SQL using?" Instead, ask: "Where is the elapsed time being spent?" Start With Resources, But Don't Stop There Resource utilization should still be the first checkpoint. A simple query using sys.dm_db_resource_stats can help identify whether Azure SQL is approaching CPU, Data IO, Log IO, memory, or worker limits: SELECT DB_NAME() AS database_name, AVG(avg_cpu_percent) AS avg_cpu_percent, MAX(avg_cpu_percent) AS max_cpu_percent, MAX(avg_data_io_percent) AS max_data_io_percent, MAX(avg_log_write_percent) AS max_log_write_percent, MAX(avg_memory_usage_percent) AS max_memory_percent, MAX(max_worker_percent) AS max_worker_percent FROM sys.dm_db_resource_stats; If CPU is consistently near 100%, investigate CPU consumption. If Log IO reaches its limit, investigate transaction-log generation. If workers are exhausted, investigate concurrency. But if none of these resources is saturated, don't conclude that Azure SQL is healthy. Move to wait analysis. Follow the Waits A useful simplified model is: Query elapsed time = CPU execution If a query runs for 10 minutes but uses only 30 seconds of CPU, most of its elapsed time occurred somewhere else. Common wait patterns can point the investigation in different directions: Wait Area to investigate PAGELATCH_* In-memory page contention PAGEIOLATCH_* Storage reads LCK_M_* Blocking WRITELOG Transaction log LOG_RATE_GOVERNOR Log throughput RESOURCE_SEMAPHORE Memory grants ASYNC_NETWORK_IO Client/result consumption The wait type is not automatically the root cause. Think of it as a sign telling you: Look in this direction next. PAGELATCH Does Not Mean Slow Storage One important distinction is: PAGELATCH versus: PAGEIOLATCH Despite their similar names, they represent different problems. PAGEIOLATCH is associated with waiting for data pages involved in physical I/O. PAGELATCH, however, is synchronization around pages that are already in memory. Consider a highly concurrent workload: Hundreds of sessions ↓ Same memory page ↓ Latch contention ↓ Sessions wait ↓ Application CPU may still have available capacity. This is why increasing vCores doesn't necessarily eliminate latch contention. Additional compute provides more workload headroom, but it doesn't automatically remove a serialization point around a hot page. Microsoft's I/O troubleshooting guidance also distinguishes PAGEIOLATCH and other I/O-related waits when diagnosing storage-performance problems. Microsoft Learn: Troubleshoot SQL Server I/O performance Query Frequency Matters Too Another common mistake is focusing only on individually expensive queries. Imagine a query that takes only 20 milliseconds but executes hundreds of thousands of times, often concurrently. Its impact is better thought of as: Workload Impact = Cost per execution × Execution frequency × A small metadata lookup or initialization query can become significant when hundreds of application instances execute it simultaneously. This is where Query Store becomes particularly useful. Query Store preserves query, execution-plan, and runtime history, allowing you to compare executions, duration, CPU, plans, and other performance characteristics over time. Microsoft Learn: Monitor performance using Query Store Instead of asking only: "What's my most expensive query?" also ask: "What changed in the workload?" When Nine Hours of Duration Is Only One Minute of CPU Now consider the opposite problem. Suppose Query Store shows something like: Elapsed time 9 hours SQL CPU time 1 minute Returned rows 750,000+ Dominant wait ASYNC_NETWORK_IO Would adding CPU solve this? Probably not. CPU represents only a tiny fraction of the elapsed time. ASYNC_NETWORK_IO commonly occurs when SQL Server has results available but the client application is not consuming them quickly enough. Microsoft documents several possible causes, including: large result sets; slow application processing; applications fetching rows slowly; network-related delays. Microsoft Learn: Troubleshoot ASYNC_NETWORK_IO Importantly: ASYNC_NETWORK_IO does not automatically mean the network is slow. The bottleneck might actually be the application. Measure Time to First Row A useful troubleshooting technique is to separate database response time from result-consumption time. Instead of measuring only: Query start → Application finished measure: T0 = Query submitted T1 = First row received T2 = Last row received T3 = Application processing completed You can then separate: Database response = T1 - T0 Result consumption = T2 - T1 Application For example: First row received: 2 seconds Last row received: 2 hours Processing completed: 2.5 hours Calling this a "2.5-hour SQL query" would be misleading. SQL started returning results after two seconds. Most of the time was spent transferring or processing them. Don't Forget Blocking Low CPU can also be caused by blocking. If many sessions are waiting behind a transaction, increasing CPU isn't going to solve the problem. During an active incident, check requests and their waits: SELECT r.session_id, r.blocking_session_id, r.status, r.wait_type, r.wait_time, r.wait_resource, r.cpu_time, r.total_elapsed_time, st.text FROM sys.dm_exec_requests AS r CROSS APPLY sys.dm_exec_sql_text(r.sql_handle) AS st WHERE r.blocking_session_id <> 0 ORDER BY r.wait_time DESC; This helps determine whether the application is experiencing a resource problem or simply waiting behind another transaction. Why Scaling Can Be Misleading Imagine this sequence: Application slow ↓ Scale database ↓ Performance improves It's tempting to conclude: "We needed more CPU." But scaling can change more than CPU availability. Depending on the operation and environment, it can alter resource availability or execution conditions. Therefore: A successful mitigation does not automatically prove the root cause. Always distinguish between: What made the symptoms disappear? and: What originally caused the symptoms? A Practical Troubleshooting Workflow When investigating Azure SQL performance, I use the following approach: 1. Define the exact incident window Preferably using UTC timestamps. 2. Check core resources Look at: CPU Data IO Log IO memory workers 3. Compare CPU time with elapsed time If: Elapsed ≈ CPU investigate computational workload. If: Elapsed >>> CPU investigate waits. 4. Identify dominant waits Ask what prevented SQL from continuing execution. 5. Check blocking Determine whether requests are waiting behind other transactions. 6. Use Query Store Compare healthy and problematic periods for: execution count; CPU; duration; logical reads; plans; wait behavior. Microsoft provides Query Store examples specifically for workload and performance investigation. Microsoft Learn: Tune performance with Query Store 7. Inspect the execution plan Look for inefficient access patterns, cardinality problems, excessive reads, repeated lookups, spills, scans, or plan changes. 8. Investigate the application Especially when SQL CPU is low but result-transfer waits are high. Look at: rows returned; fetch size; batch size; application processing; concurrency; downstream dependencies. 9. Compare healthy vs unhealthy periods Don't analyze an incident in isolation. Ask: What changed? Common Misdiagnoses "CPU isn't 100%, so SQL is healthy." Not necessarily. Queries might simply be waiting. "ASYNC_NETWORK_IO means we have a network problem." Not necessarily. The client may be consuming results slowly. "PAGELATCH means storage is slow." No. Don't confuse PAGELATCH with PAGEIOLATCH. "Scaling fixed the problem, so CPU was the root cause." Not necessarily. Mitigation and root cause are different concepts. "The slowest query must be the problem." Not always. A small query executed extremely frequently can generate larger cumulative impact. Final Thought: Follow the Time When Azure SQL becomes slow, avoid jumping directly from: Slow database → Add more vCores Instead, work through: High latency ↓ Resource utilization ↓ CPU vs elapsed time ↓ Wait statistics ↓ Query Store ↓ Execution plan ↓ Application behavior ↓ Root cause ↓ Targeted optimization Performance troubleshooting becomes much easier once you stop asking only: "How busy is Azure SQL?" and start asking: "Where did the time go?" Because sometimes the database isn't busy at all. It's waiting. References Monitor Performance by Using the Query Store Tune performance with the Query Store Troubleshoot slow queries resulting from ASYNC_NETWORK_IO Troubleshoot slow SQL Server performance caused by I/O issues301Views0likes0CommentsLessons Learned #557: Investigating an unexpected query slowdown
While working on a support case, our customer told us that the application was performing very poorly. We identified the affected query and found two execution plans in Query Store. When we compared them, we saw a clear difference: one plan used the CustomerId index, while the other scanned the table's clustered index. That led us to investigate why the query was no longer using that index. The following example reproduces this scenario with 100,000 fictional orders in an existing test database in Azure SQL Database. Follow the execution history In the example, query_id 231 has two captured plans, 243 and 251. Comparing their XML revealed the following differences: Access operator property With the CustomerId index Without the CustomerId index PhysicalOp Index Seek Clustered Index Scan Object / Index IX_TmpOrdersExample_MS_CustomerId Clustered primary key Filter placement SeekPredicates on CustomerId Predicate evaluated during the scan EstimatedRowsRead 10 100,000 EstimateRows after the filter 10 11.6601 ParameterCompiledValue 42 42 The scan references PK__TmpOrder__C3905BCF2BEADCD8. It still uses an index, but it no longer uses the nonclustered CustomerId index. The most useful difference for our investigation was EstimatedRowsRead: 10 for the seek and 100,000 for the scan, with the same compiled parameter value of 42. The XML also identifies each plan through QueryPlanHash: 0xA9A905E8788F2826 for the seek and 0xD122865CD758CA3C for the scan. Investigate why the index was no longer used The plan comparison showed a change from an Index Seek to a Clustered Index Scan, but it did not explain why that change occurred. I therefore reviewed the Query Store metadata for both plans to check. DECLARE @QueryId bigint = 231; SELECT * FROM sys.query_store_plan WHERE query_id = @QueryId ORDER BY plan_id; The results were: Plan 243 had is_forced_plan = 1, force_failure_count = 1 and last_force_failure_reason_desc = NO_INDEX. Plan 251 was not marked as forced. This is where we discovered that the earlier plan had been configured as forced and that an attempt to apply it had failed. NO_INDEX identifies an unavailable index dependency. The forcing flag records configuration, while the failure fields record unsuccessful attempts. The counter increments on recompilation failures and resets when forcing changes from off to on. This gives us a specific explanation. The expected plan references an index that was removed. The engine could not apply that plan and could optimize the query normally instead. The query can therefore continue returning the correct result while its execution strategy changes. Check the actual index definition and the deployment changes, then inspect the alternative plan. The NO_INDEX result explains the forcing failure; demonstrating that the alternative caused the reported slowdown still requires the runtime comparison. This is one possible cause of a regression, not an explanation for every slow query. Review forcing failures during maintenance This case also gave us a useful maintenance check. Instead of looking only for NO_INDEX, we can review the other forcing failures recorded by sys.query_store_plan. The following query groups affected plans by their last reported reason. Run it in the database being reviewed. DECLARE @SinceUtc datetimeoffset = DATEADD(day, -7, SYSUTCDATETIME()); SELECT last_force_failure_reason_desc AS LastFailureReason, COUNT_BIG(*) AS PlansWithFailures, COUNT(DISTINCT query_id) AS AffectedQueries, SUM(CASE WHEN is_forced_plan = 1 THEN CONVERT(bigint, 1) ELSE 0 END) AS CurrentlyForcedPlans, SUM(force_failure_count) AS CumulativeFailureCount FROM sys.query_store_plan WHERE force_failure_count > 0 AND (@SinceUtc IS NULL OR last_execution_time >= @SinceUtc) GROUP BY last_force_failure_reason_desc ORDER BY PlansWithFailures DESC; Use @SinceUtc to focus on plans with execution activity since a date, or set it to NULL to review all retained plans with failures. The date filters activity, not the time of the forcing failure. The counters are cumulative and may include older failures or failures with a different earlier reason. Identify queries that reference an index before removing it Before removing an index, we can ask a related question: which captured query plans read from it, and how often have those plans executed recently? The following query searches the retained plan XML for the index and returns one row per matching plan. Change the schema, table, index and UTC dates. This example looks for the CustomerId index used in my labs. DECLARE @SchemaName sysname = N'dbo'; DECLARE @TableName sysname = N'TmpOrdersExample_MS'; DECLARE @IndexName sysname = N'IX_TmpOrdersExample_MS_CustomerId'; DECLARE @SinceUtc datetimeoffset = DATEADD(day, -7, SYSUTCDATETIME()); DECLARE @UntilUtc datetimeoffset = SYSUTCDATETIME(); DECLARE @XmlDatabase nvarchar(258) = QUOTENAME(DB_NAME()); DECLARE @XmlSchema nvarchar(258) = QUOTENAME(@SchemaName); DECLARE @XmlTable nvarchar(258) = QUOTENAME(@TableName); DECLARE @XmlIndex nvarchar(258) = QUOTENAME(@IndexName); ;WITH XMLNAMESPACES (DEFAULT 'http://schemas.microsoft.com/sqlserver/2004/07/showplan'), Plans AS ( SELECT query_id, plan_id, is_forced_plan, TRY_CONVERT(xml, query_plan) AS PlanXml FROM sys.query_store_plan ) SELECT p.query_id, p.plan_id, p.is_forced_plan, COALESCE(r.Executions, 0) AS CapturedExecutions, r.FirstIntervalStartUtc, r.LastIntervalEndUtc FROM Plans AS p OUTER APPLY ( SELECT SUM(rs.count_executions) AS Executions, MIN(i.start_time) AS FirstIntervalStartUtc, MAX(i.end_time) AS LastIntervalEndUtc FROM sys.query_store_runtime_stats AS rs JOIN sys.query_store_runtime_stats_interval AS i ON i.runtime_stats_interval_id = rs.runtime_stats_interval_id WHERE rs.plan_id = p.plan_id AND rs.execution_type = 0 AND i.start_time >= @SinceUtc AND i.end_time <= @UntilUtc ) AS r WHERE p.PlanXml.exist(' //RelOp/IndexScan/Object[ @Database = sql:variable("@XmlDatabase") and Schema = sql:variable("@XmlSchema") and @Table = sql:variable("@XmlTable") and @Index = sql:variable("@XmlIndex") ]') = 1 ORDER BY CapturedExecutions DESC, p.query_id, p.plan_id; Read the output in three steps: query_id and plan_id identify the captured plans to inspect. The same query can appear with several plans. CapturedExecutions counts successful executions of those plans in intervals fully inside the requested window. is_forced_plan = 1 highlights a current forcing dependency, even when the plan has no executions in that window. These are plan execution counts, not exact counts of index operator executions: an operator in a conditional branch may not run every time. A missing result does not prove that an index is unused. Check Query Store capture and retention, infrequent jobs, read replicas, index hints and constraints before deciding to remove it. Compare with index usage counters We can also check the current index usage counters. This query provides a second view of the same index: SELECT i.name AS IndexName, u.user_seeks, u.user_scans, u.user_lookups, u.user_updates, u.last_user_seek, u.last_user_scan, u.last_user_lookup, u.last_user_update FROM sys.indexes AS i LEFT JOIN sys.dm_db_index_usage_stats AS u ON u.database_id = DB_ID() AND u.object_id = i.object_id AND u.index_id = i.index_id WHERE i.object_id = OBJECT_ID(N'dbo.TmpOrdersExample_MS') AND i.name = N'IX_TmpOrdersExample_MS_CustomerId'; These counters describe index operations, not distinct queries, and they have their own reset history. They are not limited to the Query Store date window. For a maintenance review, save two snapshots and compare them only after checking for resets or index changes. Use Query Store to identify the queries and these counters to understand the recorded read and write activity. Neither source alone proves that removing an index is safe. Lessons learned A forced plan is a configuration that still has dependencies. In this example, NO_INDEX explains why the intended index could not be used. Query Store shows the latest forcing status and counters, while an event capture provides dated evidence. Before removing an index, inspect recent captured plans and current forcing dependencies, then assess whether the observation period represents the workload that matters. Public references sys.query_store_plan sp_query_store_force_plan Query Store monitoring best practices Extended Events in Azure SQL Create an event session with a ring buffer target sys.query_store_runtime_stats sys.query_store_runtime_stats_interval sys.dm_db_index_usage_stats sys.query_store_query sys.query_context_settings245Views0likes0CommentsLessons Learned #556: Finding the SQL Statement Behind a Query Hash in Azure SQL Database
Recently, I worked on a performance investigation in which several queries were identified by their query hashes. The hashes helped us discuss the workload, but the customer still needed to answer a practical question: which SQL statements were behind them? A value such as 0x0123456789ABCDEF does not tell an application developer which statement to review. Fortunately, if Query Store captured the query and still retains it, the customer can use that hash to find the SQL text and the query ID in their own database. In this article, I will show that lookup and explain what to do with the result. The hash used below is a placeholder; replace it with a hash from your investigation. A hash is a lookup key rather than the SQL text A query hash is an eight-byte value derived from the shape of a query. It cannot be decoded back into the original statement. We need a source that stores the relationship between the hash and the text. Query Store provides that relationship through two catalog views. sys.query_store_query contains the query hash and query ID. Its query_text_id links to sys.query_store_query_text, where we can retrieve the SQL text. That gives us a small, read-only query to answer the customer’s question. Find the statement in the correct database Connect directly to the Azure SQL Database that executed the workload, rather than master or another database on the same logical server. Use an account with the permissions required to read Query Store information. Then run the following query, replacing the example hash: DECLARE @QueryHash binary(8) = 0x0123456789ABCDEF; SELECT CONVERT(varchar(18), q.query_hash, 1) AS query_hash, q.query_id, q.context_settings_id, qt.query_sql_text FROM sys.query_store_query AS q JOIN sys.query_store_query_text AS qt ON qt.query_text_id = q.query_text_id WHERE q.query_hash = @QueryHash ORDER BY q.query_id; Use the hexadecimal value with its 0x prefix, as shown, without quotation marks. The returned hash is formatted in the same hexadecimal notation so you can compare it with the original value. This lookup does not need a date filter: it searches the query records that Query Store currently retains. Reviewing performance during a particular incident is the next step, after identifying the matching queries. One hash can return more than one query ID Suppose the lookup returns query IDs 125 and 206. Those are illustrative IDs, but they show an important point: we should inspect both rows rather than select the first one automatically. Each query ID can also have more than one execution plan. This simple lookup intentionally returns query records without joining the plan table, so multiple plans do not repeat the SQL text in the results. Use the query ID to continue in SSMS Once the text is identified, the hash has done its job. In SQL Server Management Studio, expand the database, open Query Store, and select Tracked Queries. Enter a returned query ID and choose the period you want to investigate. From there, review the available execution plans and compare CPU, duration, reads, and execution frequency. Repeat the review for other matching query IDs where necessary. Finding the statement does not prove that it caused a particular resource spike. That conclusion still requires performance statistics and an appropriate time correlation. The useful outcome here is that the customer now knows which SQL statement to review. What if the lookup returns no rows An empty result does not prove that the query never ran. First confirm the database and the hash. Then check whether Query Store captured the query and whether its history remains available. Capture policy, cleanup, or Query Store being disabled during execution can explain a missing record. Enabling Query Store now cannot recreate a statement that was never captured. If the workload runs again, capture it and repeat the lookup after verifying that Query Store is collecting the relevant activity. References sys.query_store_query and the query hash. sys.query_store_query_text and SQL text. Monitor performance using Query Store.243Views0likes0Comments
End-to-end workload observability with Query Store for primary and replicas
Query performance doesn’t stop at the primary Most PostgreSQL architectures don’t run on a single node anymore. Reads get offloaded. Replica chains grow. And when performance issues hit, the hardest part is often simple: where did the queries actually run? With the latest query store capabilities in Azure Database for PostgreSQL flexible server, you can now capture workload executed not just on the primary, but also on read replicas—including cascading read replicas—and export the captured runtime stats, wait stats, and query text into Azure Monitor Logs (Log Analytics workspace / LAWS). See the real hotspot: isolate which node (primary vs replica) is slow. Know why: break down time by waits (CPU, I/O, locks) per query. Connect the dots: correlate query IDs to query text, and inspect sampled parameters locally in azure_sys on the primary when you need input context (parameters aren’t exported to LAWS). Centralize analysis: query everything with KQL in LAWS, across servers. What you’ll build This post walks through a reproducible demo that provisions a primary server, a read replica, and a cascading read replica, then runs a TPC-H–based workload across all three to generate query store data you can analyze locally and in Log Analytics. Enable query store capture (including query text) and parameter sampling for parameterized queries. Enable wait sampling so query store can record wait statistics. Export runtime stats, wait stats, and SQL text to LAWS using resource-specific tables. Validate capture on read replicas and cascading read replicas (not just the primary). Prerequisites Azure CLI logged in (az login) and permission to create a resource group, Log Analytics workspace, and PostgreSQL flexible servers. psql and curl available on your machine. PostgreSQL flexible server on General Purpose or Memory Optimized tier (query store and replicas aren’t supported on Burstable). PostgreSQL 14+ to test out cascading replicas. Networking: the script opens firewall access broadly for demos—tighten for production. Architecture (primary + replica chain + LAWS) You’ll deploy four resources: Primary server: read/write node. Read replica (level 1): read-only node created from the primary. Cascading read replica (level 2): read-only node created from replica level 1. Log Analytics workspace (LAWS): central place to query Query Store telemetry across all nodes. If Diagnostic Settings is properly configured, each server streams query store telemetry to LAWS—but how it’s kept locally differs by role. On the primary, query store data is recorded in-memory, then persisted locally in the azure_sys database, and then exported to LAWS. On read replicas (including cascading replicas), query store data is recorded in-memory only and then exported to LAWS. Bottom line: use LAWS for fleet-wide visibility, and use the primary’s azure_sys when you need deep local inspection (like parameter samples). Deploy the demo environment The fastest way to reproduce the scenario is to run the end-to-end bash script which you can download from https://raw.githubusercontent.com/Azure-Samples/azure-postgresql-query-store/refs/heads/main/may2026/script/query_store_demo.sh Save the file to a local directory in your Linux shell, and name the file query_store_demo.sh. To invoke the script, at minimum, you must assign a string password for the administrator login of the instances of the flexible servers it creates, and invoke the script like this: ADMIN_PASSWORD=<Your_Strong_Password> ./query_store_demo.sh Optionally, you can also override default values for other environment variables used by the script: Variable Purpose Default SUBSCRIPTION_ID Azure subscription ID to use (current default subscription) BASE_NAME Base name for all resources (used in naming servers, resource groups, etc.) pgqswait{YYYYMMDDHHMMSS} RESOURCE_GROUP Azure resource group name rg-{BASE_NAME} LOCATION Azure region for resources southeastasia PRIMARY_SERVER Name of primary PostgreSQL server {BASE_NAME}-primary REPLICA_1 Name of first-level read replica {BASE_NAME}-readreplica REPLICA_2 Name of second-level cascading read replica {BASE_NAME}-cascadereadreplica LOG_ANALYTICS_WORKSPACE Log Analytics workspace name law-{BASE_NAME} LOG_ANALYTICS_LOCATION Azure region for Log Analytics workspace southeastasia ADMIN_USER PostgreSQL admin username pgadmin ADMIN_PASSWORD PostgreSQL admin password (REQUIRED) SKU_NAME PostgreSQL server SKU (compute tier) Standard_D4ds_v5 TIER PostgreSQL pricing tier GeneralPurpose STORAGE_SIZE Storage size in GB 64 VERSION PostgreSQL version (minimum 14 for cascading replicas) 17 PRIMARY_DATABASE Initial database name postgres SQL_BASE_URL Base URL for downloading SQL scripts https://raw.githubusercontent.com/Azure-Samples/azure-postgresql-query-store/refs/heads/main/may2026/script/query_store_demo.sh TPCH_DDL_URL URL for TPC-H schema DDL file {SQL_BASE_URL}/schema/tpch_ddl.sql WORKLOAD_REPETITIONS Number of times to execute each workload query (minimum 5) 10 AUTO_APPROVE Skip confirmation prompt and proceed automatically false If, for example, you want to not only pass the ADMIN_PASSWORD but also override the LOCATION, you could do it like this: ADMIN_PASSWORD=<Your_Strong_Password> LOCATION=canadacentral ./query_store_demo.sh In a bit over 1 hour, the script will do the following steps: Step 1 — Provision first part of the infrastructure The infrastructure provisioned in this phase consists of: A resource group in which all resources are deployed. An instance of Log Analytics workspace, where all flexible server instances will send their query store related logs. A primary (read-write) flexible server. Step 2 — Configure primary server Now it's time to configure one new server parameters on your primary server so that query store emits query text to LAWS, so that we can correlate quey IDs to something recognizable. Query IDs are great for aggregation—but you still need the SQL. Turn on query text emission so you can correlate runtime and waits back to the actual statement text. Do this by setting pg_qs.emit_query_text to on. Refer to our documentation to learn how to set the value of a server parameter. Step 3 — Provision second part of the infrastructure The infrastructure provisioned in this phase consists of: A read replica (read-only) whose source is the primary server. A cascade read replica (read-only), whose source is the previously created read replica. Notice that when read replicas are created, they inherit the server parameter values from their source server. Because we have configured query store related settings on the primary server already, the intermediate read replica inherits its server parameters from that primary, and the cascade read replica inherits them from the intermediate replica. Step 4 — Export query store to Log Analytics (LAWS) Now for the payoff, we want to stream the data to Log Analytics so you can query across nodes, build dashboards, and alert. The script configures diagnostic settings on the primary and both replicas to send logs to a Log Analytics workspace using resource-specific tables. This is the key to cross-node visibility: each server exports its own captured telemetry, and you can slice by resource in a single KQL query. Query store runtime stats: execution counts, elapsed time, and other performance counters. Query store wait stats: wait breakdown attributed to queries. Query store SQL text: query text to decode query IDs. Note: Query store parameter samples are not included in the Log Analytics export. Parameters are stored locally per server in azure_sys, and on read replicas azure_sys is read-only—so don’t depend on replicas for parameter inspection. LAWS receives runtime stats, wait stats, and query text. Diagnostics settings for an instance of flexible server can be configured via portal. In the resource menu, under Monitoring, select Diagnostic settings. Add a new diagnostic setting, select a destination Log Analytics workspace, and the individual log catergories which you want to stream to that LAWS, and save the changes. For Destination table it's highly recommended to use Resource specific (one table per signal with proper schema) over Azure diagnostics (legacy one table for everything). With Azure diagnostics, all logs from all resource types land into a single table (AzureDiagnostics). It's a wide table with many columns. New columns get added as services emit new fields. If the 500 column limit is hit, extra fields go into the AdditionalFields column (a dynamic JSON). Querying on attributes stored in that column might have huge performance and query cost impact. The schema is inconsistent and difficult to discover. You must always filter events in that table by ResourceType and Category. On the other hand, with Resource specific, logs are written to separate tables per resource type and category. Therefore, each table has a well-defined schema and columns are strongly typed. Tables are smaller and faster to query. Queries on these tables are simpler don't need filtering by ResourceType and Category. Performance-wise, they also support faster ingestion and faster querying. They also support selecting different table plans and retention settings for each table. And, more importantly, role-based access control (RBAC) permissions can be applied at table level, allowing you to control access to telemetry in a more granular way. Note: If you want to see any of the images in this article in better quality, click on them to see them in their original size. This can also be configured using Azure CLI command az monitor diagnostic-settings create. Make sure that the --export-to-resource-specific parameter is set to true, which is the equivalent of selecting Resource specific for Destination table in portal UI. Setting this parameter to false, would mean that you want to use AzureDiagnostics as the destination table, which we don't recommend using. Step 5 — Run some workload In this phase the script loads a TPC-H schema and executes workload SQL across different nodes so that you can prove replica capture. Query it in Log Analytics Once the workload completed and data was streamed to Log Analytics, you can open your Log Analytics workspace, and start querying the relevant tables. If you don't know how to start issuing queries in a Log Analytics workspace, refer to Get started with log queries in Azure Monitor Logs. In your Log Analytics workspace, when you select Logs in the resource menu, you can access the Queries hub. By default, it should open automatically unless you have configured it to not show, in which case you can open by selecting Queries hub on the top right corner of the Logs home screen. If you add a filter in the queries hub for Resource type equals Azure Database for PostgreSQL Flexible Server, you'll be able to access multiple examples of queries which might help you get started querying the log categories we support for our service. You can run any of them by selecting Run on the summarization card that describes the query or, if you hover the mouse over the card, you can select Load to editor so that the query is copied over to the active query window, and you can run it or modified it further. Following, there are a few more query examples which can be useful to analyze the workload executed in this experiment. Top queries by total time (across all nodes) To get the list of 10 queries with higher duration from the ones that ran on any of the three nodes. KQL PGSQLQueryStoreRuntime | summarize total_time_ms = sum(TotalExecDurationMs) by QueryId, LogicalServerName | top 10 by total_time_ms desc Results Important: Results might be slightly different on each execution of the experiment. Where queries wait on each node List the most frequent wait events observed on user initiated queries across all nodes. KQL PGSQLQueryStoreWaits | join kind=inner (PGSQLQueryStoreRuntime) on QueryId | summarize total_waits_sampled = sum(Calls) by Event, EventType, LogicalServerName | order by total_waits_sampled desc Results Important: Results might be slightly different on each execution of the experiment. Decode query IDs (join runtime stats with SQL text) Top 20 queries the most frequent wait events observed on user initiated queries across all nodes. KQL PGSQLQueryStoreRuntime | join kind=inner (PGSQLQueryStoreQueryText) on QueryId | where QueryType == 'select' | project LogicalServerName, QueryId, TotalExecDurationMs, QueryText | top 20 by TotalExecDurationMs desc Results Important: Results might be slightly different on each execution of the experiment. Compare primary vs replicas (workload distribution) Find total number of query executions and accumulated duration of all those executions for each node. KQL PGSQLQueryStoreRuntime | summarize execs = sum(Calls), total_time_ms = sum(TotalExecDurationMs) by LogicalServerName | order by total_time_ms desc Results Important: Results might be slightly different on each execution of the experiment. Replica-only hotspots (find what’s slow off the primary) Find top 10 queries executed by their aggregated duration, focusing on what was executed on read replicas only. KQL let Replicas = dynamic(["pgqswait20260505220501-readreplica", "pgqswait20260505220501-cascadereadreplica"]); PGSQLQueryStoreRuntime | where LogicalServerName in (Replicas) | summarize total_time_ms = sum(TotalExecDurationMs) by QueryId, LogicalServerName | top 10 by total_time_ms desc Results Important: Results might be slightly different on each execution of the experiment. QPI now supports query store stats collected on replicas You can now use Query Performance Insight workbooks to analyze query store information not only on your primary server, as you were used to, but you can also get that valuable information on your read replicas. Why replica workload capture is a big deal This is the unlock: you can now answer performance questions in replica-heavy architectures without stitching together partial signals. Per-node truth: see the slow queries on the node where they actually ran (primary vs replica vs cascading replica). Faster root cause: runtime + waits gives you “slow” and “why” in one place. Replica tuning that sticks: identify replica-specific bottlenecks (I/O saturation, lock waits, CPU pressure) and tune with evidence. Centralized observability: export to LAWS so you can build dashboards, alerts, and cross-server comparisons with KQL. Unlock query visibility: Access query text without database permissions. Fine grain control on who can view query text: Using resource specific tables in LAWS, you can decide which users can access the table in which text of the queries is kept. Parameter-aware debugging: sampled parameters can help reproduce issues and explain plan changes, but they’re stored locally in azure_sys and not exported to LAWS. In practice, rely on the primary for parameter inspection (replicas have read-only azure_sys). Operational notes (quick but important) Expect a delay: Query store stats and LAWS ingestion aren’t instant. Give it a few minutes after running workload. Mind retention: Query store retention and Log Analytics retention are separate knobs. Tune them to balance troubleshooting value and cost. Production hygiene: don’t use wide-open firewall rules outside of a demo. Clean up When you’re done, delete the resource group: az group delete --name <RESOURCE_GROUP> --yes --no-wait Bottom line Query store in Azure Database for PostgreSQL flexible server now matches how modern architectures run—across primary, read replicas, and cascading replicas—and LAWS gives you a single place to query, compare, and act.721Views13likes0Comments