python
86 TopicsBuilding Autonomous Agents with Microsoft Agent Framework and GitHub Copilot SDK Part 2/5
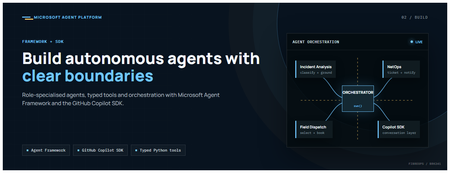
This is the second post in our series on the Microsoft agent platform. Here we dive deep into building autonomous agents, the development experience, the Microsoft Agent Framework, tool design patterns, and how the GitHub Copilot SDK brings conversational AI to your agent system. All examples reference the FibreOps repository, an autonomous fibre outage response system demonstrated at Microsoft Build BRK241. The Microsoft Agent Framework The Microsoft Agent Framework (now GA) provides a unified programming model for building agents. It supports multiple backends through a single .run() contract: Hosted — FoundryAgent connected to a Prompt Agent published to Microsoft Foundry Agent Service. Foundry — Agent + FoundryChatClient with the definition resolved locally (ideal for prompt iteration). Local — Deterministic LocalAgent for offline development and testing. This design means your orchestration code never changes regardless of where the agent runs. The factory pattern in FibreOps selects the backend at startup: # src/fibreops/agents/factory.py — simplified from agent_framework_foundry import FoundryAgent from agent_framework import Agent, FoundryChatClient def build_agent(role: str, backend: str, config: Config): if backend == "hosted": return FoundryAgent(agent_id=config.foundry_agents[role]) elif backend == "foundry": return Agent( instructions=get_instructions(role), chat_client=FoundryChatClient(endpoint=config.endpoint), tools=get_tools(role), ) else: return LocalAgent(role=role) Set FIBREOPS_AGENT_BACKEND to override the backend, or leave it as auto for intelligent detection. Designing Role-Specialised Agents FibreOps demonstrates a key pattern: role specialisation. Rather than one monolithic agent, the system uses three focused agents, each with a clear responsibility boundary: Agent Role Tools Available IncidentAnalysisAgent Classify severity, find root cause, retrieve SOP Knowledge (SOPs + topology), Web IQ, Work IQ NetOpsCoordinatorAgent File D365 incident, post Teams notice Ticketing, Teams, Memory FieldDispatchAgent Select engineer, book resource, update team Dispatch, Teams, Voice Why Role Specialisation? Focused system prompts — Each agent has a tightly scoped instruction set, reducing hallucination and improving reliability. Independent evaluation — You can score each agent separately against role-specific criteria. Parallel development — Teams can iterate on agents independently. Selective upgrade — Swap one agent's model or implementation without touching others. Tool Design: Typed Python Functions Tools in the Microsoft Agent Framework are typed Python functions that the runtime supplies to the hosted agent definition. FibreOps demonstrates several tool categories: Knowledge Tools # src/fibreops/tools/knowledge.py — simplified def sop_lookup(node_id: str, signal_type: str) -> dict: """Retrieve the Standard Operating Procedure for a given signal type. Args: node_id: The fibre node identifier (e.g., FN-LDN-001) signal_type: The type of signal (loss_of_light, high_ber, signal_degradation) Returns: SOP with steps, escalation path, and estimated resolution time. """ # Load from local markdown SOPs or Foundry IQ ... def web_iq_search(query: str, *, limit: int = 5) -> list[dict]: """Search public web for context relevant to the incident. Grounding against roadworks, weather, power outages, splice guidance. Falls back to deterministic fixtures when endpoint is unset. """ ... def work_iq_search(query: str, *, limit: int = 5) -> list[dict]: """Search enterprise knowledge for context relevant to the incident. Site surveys, SLA tiers, competency matrix, MTTR trends. """ ... Integration Tools # src/fibreops/tools/teams.py — simplified def post_outage_notice( incident_id: str, node_id: str, severity: str, summary: str, engineer: str | None = None, ) -> dict: """Post an Adaptive Card outage notice to the configured Teams channel. If TEAMS_WEBHOOK_URL is not set, appends to state/teams_outbox.jsonl for offline review. """ card = build_adaptive_card(incident_id, node_id, severity, summary, engineer) if config.teams_webhook_url: requests.post(config.teams_webhook_url, json=card) else: append_to_outbox(card) return {"status": "posted", "incident_id": incident_id} Design Principles for Agent Tools Typed parameters with docstrings — The runtime uses type hints and docstrings to generate the tool schema for the LLM. Graceful degradation — Every tool works offline by falling back to local fixtures or file-based state. Idempotent where possible — Tools that create resources return existing records if called with the same parameters. Observable — Every tool invocation emits an OpenTelemetry span for tracing and debugging. The Orchestrator Pattern The orchestrator drives signals through the agent pipeline. It is deliberately simple — a linear flow with error handling: # src/fibreops/orchestrator.py — simplified async def handle_signal(signal: TelemetrySignal) -> RunResult: """Process a telemetry signal through the agent pipeline.""" # Stage 1: Incident Analysis analysis = await incident_agent.run( f"Analyse this signal: {signal.model_dump_json()}" ) # Stage 2: NetOps Coordination coordination = await netops_agent.run( f"Coordinate response for: {analysis.summary}" ) # Stage 3: Field Dispatch dispatch = await dispatch_agent.run( f"Dispatch engineer for incident: {coordination.incident_id}" ) return RunResult( signal=signal, analysis=analysis, coordination=coordination, dispatch=dispatch, ) The orchestrator honours the same contract regardless of backend — hosted , foundry , or local — because all backends implement await agent.run(prompt) . GitHub Copilot SDK Integration (GA) The GitHub Copilot SDK enables conversational interaction with your agent system. FibreOps implements FibreOpsCopilotClient with the same interface as github/copilot-sdk : # src/fibreops/sdk/__init__.py — simplified from fibreops.sdk.client import FibreOpsCopilotClient client = FibreOpsCopilotClient() session = client.create_session() # Query agent status response = session.send_and_wait("status") print(response.text) # Human-readable summary print(response.data) # Structured JSON # Inject a telemetry signal via conversation response = session.send_and_wait(json.dumps({ "signal_id": "sig-demo", "node_id": "FN-LDN-001", "signal_type": "loss_of_light", "severity": "critical" })) The adapter routes prompts by shape: JSON signal-shaped dicts — Forwarded to the orchestrator for processing. Free-form text — Answered by a deterministic responder ( help , status , nodes , engineers , optimiser , dispatch ). Drive it from the terminal: python -m fibreops.demo chat "help" python -m fibreops.demo chat "status" python -m fibreops.demo chat '{"signal_id":"sig-demo","node_id":"FN-LDN-001","signal_type":"loss_of_light","severity":"critical"}' Or hit the embedded HTTP endpoint when the NOC console is running: Invoke-RestMethod -Method Post http://127.0.0.1:8800/sdk/chat -Body '{"prompt":"status"}' -ContentType application/json Development Workflow with Foundry Toolkit for VS Code The Foundry Toolkit for VS Code provides an integrated development experience: Author prompts — Edit system instructions with live preview and token counting. Test locally — Run against the foundry backend with FoundryChatClient pointing at your development model. Iterate fast — The foundry backend resolves definitions locally, so prompt changes take effect immediately without republishing. Publish when ready — python -m fibreops.demo publish creates hosted Prompt Agents in Foundry. Multi-Model Support The Microsoft Agent Framework supports multiple models. FibreOps defaults to gpt-4.1-mini (the model available in most demo Foundry accounts), but any chat-completions deployment works: # .env AZURE_AI_MODEL_DEPLOYMENT=gpt-4.1-mini # or gpt-4o-mini, gpt-4o, gpt-4.1 The framework also supports Claude Code connectors and Magentic-One for multi-agent collaboration scenarios. Testing Strategy FibreOps demonstrates a layered testing approach: Unit tests — Test tools in isolation with mocked dependencies. Local backend tests — Run the full pipeline with LocalAgent for deterministic assertions. Integration tests — Run against real Foundry agents with pytest -q . Rubric evaluation — The optimizer scores every run against defined criteria. # Run the test suite .\.venv\Scripts\python.exe -m pytest -q Key Takeaways The Microsoft Agent Framework provides a unified .run() contract across hosted, foundry, and local backends. Role specialisation keeps agents focused, testable, and independently evolvable. Tools are typed Python functions with docstrings — the runtime generates schemas automatically. The GitHub Copilot SDK (GA) enables conversational interaction with any agent system. Graceful degradation means the entire system works offline for development. The factory pattern lets you switch backends without changing orchestration code. Next Steps Clone the FibreOps repository and run python -m fibreops.demo --signals 3 Microsoft Agent Framework documentation Next in this series: Running Hosted Agents in Microsoft Foundry Agent Service
Vector search finds candidates. Reranking decides what your RAG app reads
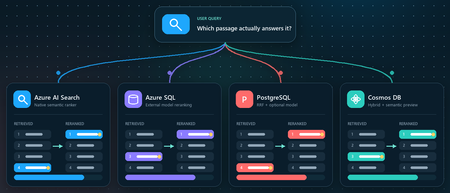
You ask a retrieval-augmented generation (RAG) application a question. Vector search returns ten passages that are clearly related to the topic. The passage that actually contains the answer, however, is ranked seventh, while the language model receives only the first five. Retrieval did not completely fail. It found the evidence, but ordered it below less useful context. Reranking addresses that gap between a passage that is semantically similar and a passage that is relevant to the user's specific question. This article demonstrates that pattern in four Azure services using the Stanford Question Answering Dataset (SQuAD). The goal is not to declare a winning service or publish a quality benchmark. It is to show where retrieval, rank fusion, and model-based reranking run in each architecture, and to illustrate how the position of a known source passage can change. What this demonstration establishes The examples show rank movement for three selected questions. They do not establish that one reranker or service is universally more accurate. A production decision requires a larger, representative query set and aggregate relevance, latency, and cost measurements. Get the full Python implementation: pauldj54/azure-vector-reranking-squad Retrieval and reranking are different stages A production search pipeline commonly uses two stages: Retrieve for recall. Fast retrieval narrows a large corpus to a bounded candidate set. It can use vector search, keyword search, or both. Rerank for precision. A more expensive model evaluates only those candidates against the original query and produces the final order. Reciprocal Rank Fusion (RRF) belongs between those two ideas. RRF is a model-free rank aggregation method that merges independent result lists, usually vector and keyword results. For a document d, a typical score is: RRF(d) = ∑ r ∈ R 1 k + rank r (d) Here, R is the set of ranked lists and k is commonly 60. RRF works with positions rather than raw scores, so it can combine signals such as cosine distance and BM25 without pretending their score scales are comparable. This gives a clearer three-part vocabulary: Stage Purpose Typical mechanism Retrieve Find broad candidate set Vector search, BM25, filters Fuse Combine independent rankings RRF Rerank Reassess query-document relevance Semantic ranker or cross-encoder RRF often improves hybrid retrieval when exact names, dates, identifiers, or terms matter. A learned reranker can then read the query and each candidate together, capturing interactions that separately generated embeddings can miss. The learned stage costs more, so it should operate on tens of candidates rather than the whole corpus. The following image describes the general process: Why use SQuAD for this demonstration? SQuAD 1.1 contains crowd-written questions over more than 500 Wikipedia articles. Its packaged splits contain 87,599 training rows and 10,570 validation rows. Each row includes a question, a context passage, and one or more answer spans inside that passage. That source-context mapping gives this demonstration a useful label: the context associated with a question is treated as its gold passage. We can then inspect whether each search stage moves that passage up or down. This is convenient, but it is not a perfect passage-ranking benchmark. SQuAD was designed for extractive question answering, and another passage in the corpus might also answer a question. The gold context is therefore a reproducible reference, not proof that every other passage is irrelevant. The results shown here use the 2,067 unique contexts in the SQuAD validation split and 1,536-dimensional embeddings. The repository default should be set to the same corpus size before treating the screenshots or rank transitions as directly reproducible. Three illustrative questions Question Expected answer Gold context According to game stats, which Super Bowl 50 quarterback had his worst year since his first NFL season? Peyton Manning 12, Super Bowl 50 What else did Tesla do for work at this time? Various electrical repair jobs 165, Nikola Tesla Who acts as laborer, paymaster, and design team for a renovation project? The property owner 1306, Construction Each notebook selects a seeded demonstration question when it runs. The three saved examples were collected across separate runs; the current notebooks do not execute all three questions in one pass. A benchmark harness should iterate over a fixed question list and save all stage results in one structured output. Capability boundaries at a glance Service Retrieval and Fusion Learned Reranking Boundary to Keep in Mind Azure AI Search Native keyword and vector retrieval with native RRF Built-in semantic ranker Semantic ranking only reorders the retrieved top 50 Azure SQL Database Exact vector retrieval in the current notebook External Cohere model invoked through native REST procedure SQL issues the HTTPS request; Foundry performs inference PostgreSQL Flexible Server pgvector plus hand-written SQL RRF over full-text search Optional external Cohere call from Python Retrieval primitives are native; this RRF query and Cohere path are application code Azure Cosmos DB for NoSQL Native vector search and native hybrid RRF SDK-integrated Semantic Reranker, currently preview Reranking is a separate inference call over at most 50 supplied documents Azure AI Search: native hybrid retrieval and semantic ranking How it works: Azure AI Search provides the most integrated pipeline in this demonstration. A hybrid query runs keyword and vector retrieval, combines the lists with RRF, and passes up to the top 50 results to the built-in semantic ranker. The semantic ranker assigns @search.rerankerScore values from 0 to 4 and can return extractive captions and answers. The semantic configuration identifies the fields that carry the meaning of each document: semantic_search = SemanticSearch( configurations=[ SemanticConfiguration( name=SEMANTIC_CONFIG, prioritized_fields=SemanticPrioritizedFields( title_field=SemanticField(field_name="title"), content_fields=[SemanticField(field_name="content")], ), ) ] ) This tells the semantic ranker which text fields to evaluate. The query then enables semantic ranking after hybrid retrieval: results = search_client.search( search_text=question, vector_queries=[vector_query], query_type="semantic", semantic_configuration_name=SEMANTIC_CONFIG, top=10, ) The important constraint is candidate recall. Semantic ranking does not search the corpus again. If the correct passage is absent from the hybrid top 50, the semantic stage cannot recover it. See 01_azure_ai_search_reranking.ipynb for the complete setup and query path. Test results for Azure AI Search These examples show that semantic reranking improves relevance selectively, not universally. It strongly helps the construction query, moving the correct passage from rank 4 to rank 1, but slightly degrades the Super Bowl and Tesla queries by one position. This reinforces that semantic ranking should be evaluated across a representative query set using aggregate metrics such as MRR or NDCG, rather than judged from a single result. Azure SQL Database: vector retrieval plus external Cohere reranking How it works. The Azure SQL notebook retrieves 20 candidates with exact cosine distance and sends their text to Cohere Rerank v4.0 Fast through sys.sp_invoke_external_rest_endpoint. The vector column and query vector must have the same dimensions. This repository uses 1,536-dimensional embeddings: SELECT TOP (@ candidate_count) context_id, title, content, 1 - VECTOR_DISTANCE( 'cosine', CAST(@ query_vector AS VECTOR(1536)), embedding ) AS similarity FROM dbo.documents ORDER BY similarity DESC; For reranking, we selected Cohere Rerank v4.0 Fast (Cohere-rerank-v4.0-fast), a fast version of Cohere’s fourth-generation relevance-ranking model. The model is deployed in Microsoft Foundry, where its Azure Direct inference endpoint is available in the deployment details within the Foundry portal. Azure SQL can call REST APIs directly using sp_invoke_external_rest_endpoint. Because Azure SQL allowlists Azure AI’s *.cognitiveservices.azure.com domain, we translate the equivalent Foundry endpoint from *.services.ai.azure.com while preserving the Cohere reranking route. from urllib.parse import urlsplit, urlunsplit def sql_compatible_endpoint(endpoint: str) -> str: """Convert an Azure Direct endpoint to Azure SQL's allowed hostname.""" parts = urlsplit(endpoint) if parts.hostname.endswith(".services.ai.azure.com"): resource = parts.hostname.removesuffix(".services.ai.azure.com") hostname = f"{resource}.cognitiveservices.azure.com" elif parts.hostname.endswith(".cognitiveservices.azure.com"): hostname = parts.hostname else: raise ValueError("Expected an Azure AI Services endpoint.") return urlunsplit( (parts.scheme, hostname, parts.path, parts.query, "") ) Then I defined a re-rank with cohere function, starting by loading the endpoint and setting the authentication: def rerank_with_cohere( cursor, question: str, candidates: list[dict], top_n: int = 10, ) -> list[dict]: """ Rerank candidate documents by calling Cohere through Azure SQL. Each candidate must contain a 'content' field. """ if not candidates: return [] sql_endpoint = sql_compatible_endpoint( os.environ["COHERE_RERANK_ENDPOINT"] ) model = os.environ["COHERE_RERANK_MODEL"] access_token = credential.get_token( "https://cognitiveservices.azure.com/.default" ).token headers = json.dumps({"Authorization": f"Bearer {access_token}"}) payload = json.dumps( { "model": model, "query": question, "documents": [row["content"] for row in candidates], "top_n": min(k, len(candidates)), }, ensure_ascii=False, ) cursor.execute( """ DECLARE @url NVARCHAR(4000) = CAST(? AS NVARCHAR(4000)); DECLARE @headers NVARCHAR(4000) = CAST(? AS NVARCHAR(4000)); DECLARE Payload NVARCHAR(MAX) = CAST(? AS NVARCHAR(MAX)); DECLARE Response NVARCHAR(MAX); DECLARE @status INT; EXEC @status = sys.sp_invoke_external_rest_endpoint @url = @url, @method = 'POST', @headers = @headers, Payload = Payload, @timeout = 60, @retry_count = 2, Response = Response OUTPUT; SELECT @status, Response; """, sql_endpoint, headers, payload, ) status, response_text = cursor.fetchone() if status != 0: raise RuntimeError(f"Reranker endpoint returned HTTP status {status}.") response = json.loads(response_text)["result"] You can see the complete implementation in the 02_azure_sql_reranking.ipynb notebook. Test results for Azure SQL Db Across the three sample questions, Cohere reranking consistently moved the correct SQuAD passage closer to the top: from rank 5 to 1 for the Super Bowl question, 3 to 2 for the Tesla question, and 8 to 1 for the construction question. These examples show how vector search provides a strong candidate set, while reranking applies deeper query-document relevance scoring to improve the final ordering. The results are illustrative rather than a complete quality benchmark, so broader evaluation across many queries is still recommended. Azure Database for PostgreSQL flexible server: pgvector, SQL RRF, and an optional model How it works: PostgreSQL makes the pipeline components explicit. The notebook uses pgvector for vector similarity, PostgreSQL full-text search for keyword retrieval, and SQL to implement RRF. Vector retrieval uses cosine distance: SELECT context_id, title, content, 1 - (embedding <= > % (query_vector) s:: vector) AS similarity FROM squad_docs ORDER BY embedding <= > % (query_vector) s:: vector LIMIT % (candidate_count) s; The hybrid query independently ranks vector and keyword hits, then combines positions rather than raw scores: SELECT d.context_id, COALESCE(1.0 / (60 + v.rank), 0) + COALESCE(1.0 / (60 + k.rank), 0) AS rrf_score FROM squad_docs AS d LEFT JOIN vector_hits AS v USING (context_id) LEFT JOIN keyword_hits AS k USING (context_id) WHERE v.context_id IS NOT NULL OR k.context_id IS NOT NULL ORDER BY rrf_score DESC; This is not a built-in PostgreSQL RRF operator. It is transparent, hand-written SQL over native retrieval primitives, which makes weighting and debugging flexible but leaves implementation and tuning with the application team. The notebook's optional learned stage sends the vector candidates from Python to a Foundry deployment of Cohere Rerank v4.0 Fast. This path was chosen because the tested Flexible Server azure_ai extension version expected the older serverless reranking endpoint contract. Microsoft documentation still describes azure_ai.rank() as a preview function whose default model is Cohere Rerank v3.5, even though that model retired on May 14, 2026. Treat this as a version-specific compatibility issue and verify current extension behavior before selecting an architecture. Azure HorizonDB is a different product path. Its AI Model Management feature can provision Cohere Rerank v4.0 Fast as default-reranker, but that management feature is currently a limited preview. It should not be described as a generally available Flexible Server capability. See 03_azure_postgres_reranking.ipynb for the full SQL and optional external model path. Test results for Azure SQL for PostgreSQL Flexible Server The tests show that PostgreSQL vector search provides a useful candidate set, SQL RRF can substantially improve results when keyword evidence is strong, and the Cohere semantic reranker is the most consistent overall: it moved the correct passage to rank 1 in two tests and from rank 3 to rank 2 in the Tesla test. RRF produced the biggest gain for the construction question, moving the correct passage from outside the vector top five to rank 1, but did not improve every query. The scores across stages are not directly comparable because cosine similarity, RRF score, and Cohere relevance use different scales. Azure Cosmos DB for NoSQL: hybrid search with built-in RRF How it works: Azure Cosmos DB for NoSQL supports native hybrid ranking with VectorDistance, FullTextScore, and RRF inside ORDER BY RANK: SELECT TOP K C.context_id, c.title, c.text FROM c ORDER BY RANK RRF( VectorDistance(c.vector, @query_vector), FullTextScore(c.text, @term1, @term2, @term3) ) The notebook extracts distinct terms from the question before building the full-text part of the query. That token selection is application logic and can materially affect the hybrid ranking, so production evaluation should test analyzers, languages, term extraction, and optional RRF weights. Cosmos DB Semantic Reranker is an SDK-integrated preview feature. The application first runs a query, serializes the resulting documents, and submits those documents with the user's context string: result = container.semantic_rerank( context=question, documents=documents, options={ "return_documents": False, "top_k": min(k, len(documents)), "sort": True, "document_type": "json", "target_paths": "title,text", }, ) The service accepts at most 50 documents per rerank call and returns relevance scores from 0 to 1, plus inference latency and token usage. It uses the Microsoft semantic ranking model also used by Azure AI Search. The reranking call requires Microsoft Entra authentication, the appropriate Semantic Reranker role, and an account-linked inference endpoint. The 04_azure_cosmosdb_reranking.ipynb in the shared repo contains and end-to-end implementation. Test results for Azure Cosmos Db The results show that vector search provides a strong baseline, while hybrid RRF and semantic reranking improve different queries in different ways. Hybrid RRF helps when exact keywords matter, moving the construction answer into the top results, while the semantic reranker delivers the strongest overall ordering, promoting the correct construction passage from hybrid rank 3 to rank 1 and improving the Super Bowl answer from rank 5 to rank 2. However, it does not always place the gold passage first, as seen in the Tesla example, confirming that reranking improves relevance but is query-dependent and should be evaluated across a larger test set. What the examples do and do not show The four services expose different ownership boundaries: • Azure AI Search owns hybrid fusion and learned semantic ranking inside the search service. • Azure SQL owns vector retrieval and outbound REST invocation in this example, while Foundry owns model inference. • PostgreSQL supplies vector and full-text primitives; the application owns the RRF SQL and optional Cohere call. • Cosmos DB provides native hybrid RRF and integrates a separate preview inference call through its SDK. Across three selected questions, the known source passage often moved substantially. That supports the practical value of testing a second-stage ranker. It does not prove that semantic reranking always improves top-1 accuracy, that RRF is universally beneficial, or that scores from different stages can be compared directly. Cosine similarity, RRF score, Azure AI Search reranker score, Cohere relevance, and Cosmos DB semantic relevance all have different definitions and scales. Compare rank positions and task-level metrics, not raw values across systems. Turn the demonstration into an evaluation For a production RAG system, convert the notebook pattern into a repeatable evaluation harness: Build a representative labeled query set from real user tasks. Freeze corpus, chunking, embedding model, dimensions, and candidate counts for each run. Record ranks after retrieval, fusion, and learned reranking. Measure Recall@k or Hit@k to verify that retrieval finds relevant evidence. Measure Mean Reciprocal Rank (MRR) when the position of the first relevant result matters. Use NDCG when judgments include multiple passages or graded relevance. Record latency percentiles, inference usage, request cost, and failure rates. Evaluate the generated answer separately for correctness, citation support, and refusal behavior. Also test the operational cases that a three-question demonstration cannot cover: empty keyword results, missing gold passages, long documents, multilingual text, filters, partial outages, token expiration, throttling, model retirement, and low-confidence scores. Practical guidance Retrieve broadly enough that the correct evidence can reach the learned stage. Use RRF when vector and keyword retrieval provide complementary signals. Rerank a bounded candidate set, commonly 20 to 50 passages, and measure the latency cost. Keep citations and source identifiers through every rank transformation. Version the corpus, embedding model, dimensions, query set, and reranker deployment. Do not hard-code assumptions about model endpoints or lifecycle dates. Verify current service documentation and the deployed extension or SDK version. Add thresholds or fallback behavior only after calibrating scores on your own data. Judge the full RAG chain. Better passage order is valuable only when it improves grounded answers for users. Vector search is built to find plausible candidates quickly. Rank fusion can reconcile retrieval signals, and a learned reranker can decide which candidates best address the question. The right architecture depends on where your data lives, which service boundaries you want to operate, and what your evaluation says about quality, latency, and cost. Resources Companion repository Azure AI Search semantic ranker Azure SQL VECTOR_DISTANCE Azure SQL sp_invoke_external_rest_endpoint Azure Database for PostgreSQL AI functions Microsoft Foundry model retirement schedule Azure Cosmos DB hybrid search Azure Cosmos DB Semantic Reranker SQuAD dataset card Dataset attribution Rajpurkar, P., Zhang, J., Lopyrev, K., and Liang, P. (2016). SQuAD: 100,000+ Questions for Machine Comprehension of Text. EMNLP 2016. SQuAD 1.1 is distributed under CC BY-SA 4.0.Learn how to use the four IQs: Web IQ, Work IQ, Fabric IQ, Foundry IQ
We just concluded Microsoft IQ Deep Dive with Python, a three-part livestream series all about Microsoft IQ. We showed how to use the four IQs to ground your AI applications and agents: Work IQ: user-specific retrieval of M365 data, like Teams chats, emails, and calendar events. Fabric IQ: retrieval of data stored in OneLake, via Fabric ontologies, graphs, and data agents. Web IQ: real-time web results with super low latency Foundry IQ: multi-source agentic retrieval on search indexes plus remote sources (including Web IQ, Work IQ, and Fabric IQ) The four IQs are all exposed as MCP endpoints, so you can easily integrate into your own agents, or add to your Foundry agents via the Foundry Toolbox. Check out our code samples for Python notebooks and agents that use each of the MCP servers and APIs. All of the materials from our series are available for you to keep learning from, and linked below: Video recordings of each stream PowerPoint slides that you can use for reviewing or even teaching the material to your own community An annotated write-up of each presentation, so you can quickly read through 🙋🏽♂️ Have follow up questions? Join the weekly Python+AI office hours on Foundry Discord. Microsoft IQ Deep Dive with Python: Foundry IQ 📺 Watch YouTube recording In the first session, we dived into Foundry IQ (Azure AI Search), exploring how it helps agents and applications work with curated knowledge and organizational context. We built knowledge bases in Python and connected them to multiple knowledge sources, including file knowledge sources, search indexes built from ingested data, and the Web IQ MCP server. Then we performed multi-source agentic retrieval on those knowledge bases, which executes queries in parallel and merges the results with state-of-the-art ranking models. Finally, we built agents in Python using Microsoft Agent Framework and grounded their responses in Foundry IQ results three different ways: a custom tool calling the knowledge base API, the knowledge base MCP endpoint, and a Foundry Toolbox. We deployed those agents to Foundry Agent Service as hosted agents and published one to Teams. 🖼️ Slides for this session 📝 Write-up for this session 💻 Code repository with examples: iqdeepdive Microsoft IQ Deep Dive with Python: Work IQ 📺 Watch YouTube recording In the second session, we focused on Work IQ and how it brings workplace context into AI-powered experiences. We compared Work IQ to Microsoft Graph, then explored all three protocols it speaks — A2A, MCP, and REST — with runnable Python notebooks for each. We walked through the 10 generic tools that Work IQ exposes over MCP, including ask, which calls Microsoft 365 Copilot directly, and do_action, the only write path. We also connected Work IQ to a Foundry IQ knowledge base as a knowledge source, so a single query returns a blended answer across indexed HR documents and live work context. Then we wired Work IQ into a Microsoft Agent Framework agent as an MCP tool, and finished with Agent 365 autopilots — agents that get their own Microsoft 365 identity, mailbox, and place in the org chart, and act as themselves rather than on behalf of you. A live demo showed the Work Mate autopilot reading its own mailbox in Teams and emailing a customer directly. 🖼️ Slides for this session 📝 Write-up for this session 💻 Code repository with examples: iqdeepdive Microsoft IQ Deep Dive with Python: Fabric IQ 📺 Watch YouTube recording In the final session, we explored Fabric IQ and how it connects AI experiences to structured business data stored in Microsoft Fabric's OneLake. We introduced the key components of Fabric IQ — ontologies, graphs, semantic models, and data agents — and showed how each one helps describe, organize, and reason over operational data. Ontologies provide a shared business vocabulary that maps entity types, properties, and relationships to actual OneLake data. Graphs offer dedicated graph database capabilities for queries requiring extensive relationship traversal. Semantic models expose Power BI analytics through DAX measures on star-schema tables. Data agents combine all of these behind a single conversational interface that selects the right source and query language automatically. For each component, we demonstrated the Ontology MCP server and Data Agent MCP server for agent integration, and showed how to add each as a knowledge source to Foundry IQ knowledge bases for multi-source retrieval. 🖼️ Slides for this session 📝 Write-up for this session 💻 Code repository with examples: iqdeepdive1.8KViews2likes0CommentsJoin our free livestream series on using Microsoft IQ with Python
Join us for a new 3-part livestream series where we take a deep technical look at Microsoft IQ, the knowledge layer for the next generation of AI experiences. You'll learn how Foundry IQ, Work IQ, and Fabric IQ can be used to ground AI systems in organizational knowledge, workplace context, and structured business data. Our series will cover: Foundry IQ for multi-source agentic retrieval on search indexes, SharePoint, websites, and more Work IQ for user-specific retrieval of M365 data, like Teams chats, emails, and calendar events Fabric IQ for retrieval of data stored in OneLake, via Fabric ontologies and data agents Building agents with Microsoft Agent Framework to connect to Foundry IQ, Fabric IQ, and Work IQ Throughout the series, we’ll use Python for all examples and share full code so you can run everything yourself in your own Foundry projects. 👉 Register for the full series. In addition to the live streams, you can also join the Microsoft Foundry Discord to ask follow-up questions after each stream. If you are new to generative AI with Python, start with our 9-part Python + AI series, which covers topics such as LLMs, embeddings, RAG, tool calling, MCP, and agents. If you are new to Microsoft Agent Framework, watch our 6-part Python + Agent series which dives deep into agents and workflows. To learn more about each live stream or register for individual sessions, scroll down: Day 1: Foundry IQ 28 July, 2026 | 5:00 PM - 6:00 PM (UTC) Coordinated Universal Time Register for the stream on Reactor In the first session of our Microsoft IQ Deep Dive with Python series, we’ll kick things off with an introduction to the Microsoft IQ family: Foundry IQ, Work IQ, Fabric IQ, and Web IQ. We’ll then take a deeper look at Foundry IQ (Azure AI Search), exploring how it helps agents and applications work with curated knowledge and organizational context. We'll build a knowledge base and connect it to multiple knowledge sources, including the new IQs, MCP servers, and search indexes built from ingested data. Then we'll perform multi-source agentic retrieval on the knowledge base, which executes queries in parallel and merges the results with state-of-the-art ranking models. Finally, we will build an agent in Python using Microsoft Agent Framework and ground the agent's responses in results from the Foundry IQ knowledge base. All code demos will use Python and will be available in an open-source repository for you to deploy yourself. After the stream, join office hours in the Microsoft Foundry Discord to ask follow-up questions. Day 2: Work IQ 29 July, 2026 | 5:00 PM - 6:00 PM (UTC) Coordinated Universal Time Register for the stream on Reactor In the second session of our Microsoft IQ Deep Dive with Python series, we’ll focus on Work IQ and how it brings workplace context into AI-powered experiences. We’ll explore how developers can use Work IQ through APIs, A2A patterns, MCP integration, and tool-based workflows. We’ll look at two practical tool examples, then show how Work IQ can be used from Copilot and from a Microsoft Agent Framework agent. All code demos will use Python and will be available in an open-source repository for you to deploy yourself. After the stream, join office hours in the Microsoft Foundry Discord to ask follow-up questions. Day 3: Fabric IQ 30 July, 2026 | 5:00 PM - 6:00 PM (UTC) Coordinated Universal Time Register for the stream on Reactor In the final session of our Microsoft IQ Deep Dive with Python series, we’ll explore Fabric IQ and how it connects AI experiences to structured business data. We’ll introduce the key concepts behind Fabric IQ, including ontologies and data agents, and show how they help describe, organize, and reason over operational data stored in OneLake. We’ll use the Microsoft Fabric API SDK in Python to connect to Fabric IQ, so that we can programmatically configure ontologies and answer questions about our data. All code demos will use Python and will be available in an open-source repository for you to deploy yourself. After the stream, join office hours in the Microsoft Foundry Discord to ask follow-up questions.Enhancing Data Security and Digital Trust in the Cloud using Azure Services.
Enhancing Data Security and Digital Trust in the Cloud by Implementing Client-Side Encryption (CSE) using Azure Apps, Azure Storage and Azure Key Vault. Think of Client-Side Encryption (CSE) as a strategy that has proven to be most effective in augmenting data security and modern precursor to traditional approaches. CSE can provide superior protection for your data, particularly if an authentication and authorization account is compromised.3.1KViews0likes0CommentsBuilding Agentic Systems on Azure: Microsoft Foundry Agents SDK vs Microsoft Agent Framework
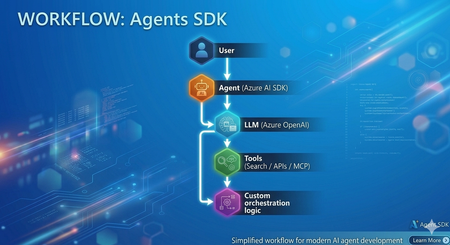
In my recent experience as a Senior Consultant at Microsoft, I’ve been actively involved in designing and delivering AI-driven solutions, with a strong focus on building intelligent agents using modern frameworks. Along the way, I've built agents using both Microsoft Foundry Agents SDK (hereafter "Agents SDK") and Microsoft Agent Framework (MAF) Both approaches are powerful and capable. However, once you move beyond simple proofs of concept, the developer experience and architectural patterns start to differ significantly. This article provides a practical comparison based on real implementation experience and aims to help developers choose the right approach. Approach 1: Agents SDK Agents SDK provides a straightforward way to create agents with integrated tools and models. Example: Creating an Agent from azure.ai.projects import AIProjectClient from azure.ai.agents.models import AzureAISearchTool, AzureAISearchQueryType from azure.identity import DefaultAzureCredential client = AIProjectClient(credential=DefaultAzureCredential(), endpoint=os.getenv("AZURE_AI_PROJECT_ENDPOINT")) # Configure tools ai_search = AzureAISearchTool( index_connection_id=conn_id, index_name="my-index", query_type=AzureAISearchQueryType.SEMANTIC, ) # Create agent (persisted in Foundry portal) agent = client.agents.create_agent( model=os.getenv("AZURE_AI_AGENT_DEPLOYMENT_NAME"), name="MyAgent", instructions="You are a helpful assistant.", tool_resources=ai_search.resources, tools=ai_search.definitions, ) # Run conversation thread = client.agents.threads.create() client.agents.messages.create(thread_id=thread.id, role="user", content="Hello") run = client.agents.runs.create(thread_id=thread.id, agent_id=agent.id) What this approach provides Native integration with Azure AI services (OpenAI, AI Search, MCP) Managed execution environment Simple and quick agent setup Conceptually, this approach can be summarized as: Model + Tools + Execution Strengths ✅ Rapid development and onboarding ✅ Strong integration within the Azure ecosystem ✅ Well-suited for single-agent or tool-driven use cases ✅ Minimal infrastructure overhead Challenges observed in practice As the complexity of scenarios increases, certain limitations become more visible: Multi-agent workflows require custom orchestration logic Agent handoffs must be implemented manually Context sharing across agents requires additional design effort While this approach offers flexibility, it shifts orchestration complexity to the developer. Approach 2: Microsoft Agent Framework (MAF) Microsoft Agent Framework introduces a higher-level abstraction, focused on agent orchestration and system design. Creating an Agent from agent_framework import Agent, WorkflowBuilder, Message from agent_framework.foundry import FoundryChatClient from azure.identity import DefaultAzureCredential client = FoundryChatClient( project_endpoint=os.getenv("FOUNDRY_PROJECT_ENDPOINT"), model=os.getenv("FOUNDRY_MODEL_DEPLOYMENT_NAME"), credential=DefaultAzureCredential(), ) # Create agents (in-process only, not persisted in portal) researcher = Agent(client, name="ResearcherAgent", instructions="Research topics thoroughly.") writer = Agent(client, name="WriterAgent", instructions="Write concise summaries.") # Build and run multi-agent workflow workflow = WorkflowBuilder(start_executor=researcher).add_edge(researcher, writer).build() async for event in workflow.run(Message("user", "Summarize migration best practices"), stream=True): print(event.content) What this approach provides Built-in orchestration capabilities Native support for multi-agent workflows Structured agent lifecycle management Context and memory handling Conceptually, this can be viewed as: Agents + Orchestration + System Design Observations from implementation When implementing similar use cases using MAF: Agent responsibilities became clearly defined Routing and delegation patterns were significantly simplified Overall system architecture became easier to maintain and scale This approach encourages thinking in terms of agent ecosystems rather than isolated agents. Architecture Comparison Agents SDK Microsoft Agent Framework (MAF) Choosing the Right Approach Use Agents SDK when: You need rapid development for a single-agent use case The workflow is relatively straightforward You prefer flexibility and lower-level control Use Microsoft Agent Framework when: You are designing multi-agent systems Your solution requires routing, delegation, or handoffs Long-term scalability and maintainability are essential Pros and Cons Summary Agents SDK Pros Easy to get started Strong Azure integration Flexible design Cons Manual orchestration required Limited native multi-agent support Complexity increases as scenarios grow Microsoft Agent Framework (MAF) Pros Built-in orchestration Native multi-agent support Scalable and structured architecture Cons Learning curve for new developers More opinionated framework design Reduced low-level control compared to SDK-based approach References and Repositories 🔗 Microsoft Agent Framework (MAF) Microsoft Agent Framework – GitHub Repository Microsoft Agent Framework Samples – Tutorials & Examples Workflow Samples (Multi-agent patterns) FoundryChatClient sample (Python) Agent Framework demos - GitHub Source 📘 Documentation Microsoft Agent Framework Overview (Microsoft Learn) Agent Framework + Microsoft Foundry provider docs 🔗 Azure AI Projects / Agents SDK Azure AI Projects SDK – Python (GitHub Source) Azure AI Projects Agents (.NET SDK repo) 📘 Documentation Azure AI Projects SDK (Python) – Microsoft Learn Azure AI Agents SDK – Microsoft Learn Conclusion Azure AI Projects and Microsoft Agent Framework both play important roles in the modern agent development landscape. Agents SDK enables quick and flexible agent development Microsoft Agent Framework enables structured, scalable agent systems In practice, the choice depends on whether you are building a single agent feature or a multi-agent system. Final Thought Agents SDK helps you get started quickly. Microsoft Agent Framework helps you scale with confidence In a follow-up blog, I’ll dive into how the M365 Agents SDK compares with Microsoft Agent Framework, especially in the context of enterprise productivity and Copilot experiences.Foundry Toolkit for VS Code at //build: Hosted Agents End-to-End, a Smarter Toolbox, and More
We’re excited to share what’s new for Foundry Toolkit for Visual Studio Code at //build 2026. Since going generally available, the toolkit has kept moving fast, and this release is a big one. The headline: a complete, end-to-end Hosted Agent experience, scaffold, run, deploy, and observe without ever leaving VS Code. On top of that, we’ve expanded the Toolbox with native enterprise integrations and shipped a wave of LangGraph samples so every developer has a clear path from idea to production. From your first prompt to a production-grade, observable agent, Foundry Toolkit meets you where you are. Hosted Agents, End to End Building an agent is the easy part; getting it from a first draft to a production-grade, observable service is what matters. This release makes the full Hosted Agent lifecycle available in VS Code, and it follows the way you actually work — scaffold, run, deploy, observe. Scaffold — start from a rich set of samples Hosted Agent creation now opens with a refreshed scaffolding experience and a rich sample selection, so you start from a working, framework-appropriate template instead of a blank file. Creation is smarter, too: we auto-select your subscription when there’s only one, gate tabs more clearly, and tightened spacing for a cleaner setup flow. Run (F5) — inspect as you build Press F5 and your agent runs locally with the Agent Inspector, now aligned with the rest of the extension and featuring Copilot SDK visualization so you can see what the Inspector visualizes as the agent executes. It’s the fastest loop from change to verification before anything leaves your machine. Deploy — a new UX and new ways to ship Different teams ship differently, so deployment got a refreshed UX and two new options for Hosted Agents: ZIP Code Deploy: Package your agent source as a ZIP and deploy it directly to Microsoft Foundry Agent Service. Bring-Your-Own-Image (BYOI): Already have a pre-built container in your own Azure Container Registry? Deploy straight from it. Observe — know it works in production Once deployed, the full observability story is now available: Hosted Agent Tracing: Inspect end-to-end traces of Hosted Agent invocations directly from VS Code — tool calls, delegation chains, and timing for real debugging instead of guesswork. Continuous Evaluation Settings: A new page to configure ongoing evaluation for deployed Hosted Agents, so quality is measured continuously — not just at ship time. Evaluations Node: One-click access to evaluation runs and results right from the Foundry project tree. A Smarter, More Connected Toolbox What it is, and why it matters A Toolbox is how your agent gets its capabilities — the curated set of tools, knowledge sources, and integrations it can call at runtime. Instead of hand-wiring each connection, you assemble a Toolbox once and your agent consumes it consistently across local runs and production. The result: agents that can act on real enterprise data and systems, with the connections managed in one place. From what to how: create, connect, consume Create: Start a new Toolbox from the Foundry Toolkit sidebar “Tools Catalog” and pick the capabilities your agent needs. Connect: Configure and wire in enterprise systems through native, first-class connections once, and use it for all your agents. Consume: Reference the Toolbox from your Hosted Agent so its tools are available the moment the agent runs, locally (F5) and once deployed. New this release Building on that flow, the Toolbox is now richer and more enterprise-ready: WorkIQ as a Built-in Tool: A first-class WorkIQ experience powered by A2A connections — no MCP fallback required. End-to-end toolbox creation with WorkIQ works out of the box. Fabric IQ (OneLake Catalog) Integration: Connect your agents to Microsoft Fabric OneLake catalogs directly from the Toolbox. Toolbox Guardrails: Apply content-safety guardrails to your Toolbox for safer agent execution. Faster discovery: A new Toolbox Search Toggle and Agent Tool Multi-Select let you find and wire in multiple tools in a single action. LangGraph Reaches Parity LangGraph developers, this one is for you. We’ve added five new Hosted Agent samples that bring LangGraph to full parity with the Agent Framework Responses learning path — so you get an equivalent, end-to-end walkthrough no matter which framework you prefer: MCP — tool loading from a remote MCP server (defaults to GitHub Copilot MCP) via MultiServerMCPClient. Workflows — a custom StateGraph chaining three specialized LLM nodes: slogan writer, legal reviewer, and formatter. Files — local filesystem tools plus the Foundry-Toolbox code_interpreter working over session-uploaded files. Human-in-the-Loop — a StateGraph that drafts a proposal and pauses for approval via langgraph.types.interrupt. Observability — GenAI OpenTelemetry tracing with enable_auto_tracing(); spans, metrics, and logs flow to Application Insights. We’ve also refreshed the existing bring-your-own LangGraph samples against the new hosting layer (chat with local tools, Foundry-managed Toolbox loading, and SSE-streamed multi-turn sessions backed by a MemorySaver checkpointer), so every sample reflects how Hosted Agents work today. Polish Across the Board A release is more than headline features. This one also includes a redesigned Prompt Builder “Improve an Instruction” dialog for faster iteration, fixes for MCP toolbox tool icons, clearer ZIP-deploy error surfacing, and assorted Agent Builder and Playground regression fixes — the whole experience feels tighter end to end. Get Started Today Install: Foundry Toolkit on the VS Code Marketplace Quick Start: Follow our getting-started tutorial to build your first Hosted Agent Deep Dive: Explore the documentation, samples, and LangGraph parity walkthroughs Join the Community Share your projects, file issues, or suggest features on our GitHub repository. We can’t wait to see what you build. Welcome to the next chapter of AI development!366Views0likes0Comments
Building an End-to-End Azure RAG Strategy Agent with MS Foundry
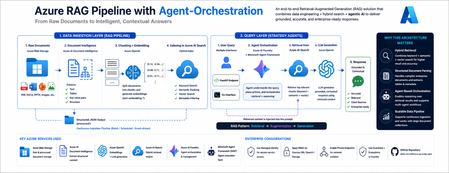
High-Level Architecture This architecture represents an end-to-end Retrieval-Augmented Generation (RAG) pipeline where raw documents are ingested from Azure Blob Storage, processed using Document Intelligence, transformed into embeddings via Azure OpenAI, and indexed in Azure AI Search for hybrid retrieval. A Foundry/MAF-based agent orchestrates query processing by combining user input with relevant search results and generates contextual responses, which are exposed through a FastAPI or CLI interface. This solution is composed of two main layers: 1. Data Ingestion Layer (RAG Pipeline) This layer transforms raw enterprise documents into searchable knowledge. Flow: Raw documents stored in Azure Blob Storage Supported formats: PDF, DOCX, PPTX, images, etc. Document Intelligence extraction Extracts: Text Tables Key-value pairs Structure Writes output as structured JSON back to Blob (processed/) Chunking + Embedding Documents are split into chunks Each chunk is embedded using Azure OpenAI (text-embedding-*) Indexing into Azure AI Search Creates a hybrid index: Keyword search Semantic ranking Vector search Enables flexible retrieval strategies 2. Query Layer (Strategy Agents) This layer enables intelligent query answering. Flow: User sends a query via: FastAPI endpoint CLI interface Query is handled by: Microsoft Agent Framework (MAF) agent Running on Azure AI Foundry Agent: Queries Azure AI Search Retrieves top relevant chunks Injects them into LLM prompt LLM generates grounded response This follows the standard RAG pattern: Retrieval → Augmentation → Generation End-to-End Flow Key Azure Services Used Service Purpose Azure Blob Storage Raw + processed document storage Azure AI Document Intelligence Extract structured content Azure OpenAI Embeddings + LLM generation Azure AI Search Hybrid retrieval engine Azure AI Foundry Agent orchestration Microsoft Agent Framework Agent execution layer Why this Architecture Matters This solution goes beyond basic RAG and provides: Hybrid Retrieval Combines keyword + semantic + vector search Improves recall and accuracy Structured Document Parsing Handles complex enterprise documents Extracts tables and metadata Agent-Based Orchestration Enables reasoning over retrieval results Extensible for multi-agent workflows Scalable Data Pipeline Supports continuous ingestion Works with large document collections Enterprise Considerations Use Managed Identity for secure service access Apply RBAC on Cosmos DB / Search / Storage Enable Private Endpoints for network isolation Use Guardrails + Evaluations in Foundry Summary This repository demonstrates a production-ready Azure RAG architecture: Ingest → Extract → Chunk → Embed → Index Retrieve → Reason → Generate Powered by Azure AI Foundry + Agent Framework By combining data engineering + AI orchestration, it enables enterprise AI systems that are: Accurate Grounded Extensible Repo: https://github.com/snd94/azure-rag-strategy-agent Please refer to the Microsoft Learn Documentation for further information: Azure AI Search documentation - Azure AI Search | Microsoft Learn Document Intelligence documentation - Quickstarts, Tutorials, API Reference - Foundry Tools | Microsoft Learn How to generate embeddings with Azure OpenAI in Microsoft Foundry Models - Microsoft Foundry | Microsoft Learn How to generate embeddings with Azure OpenAI in Microsoft Foundry Models - Microsoft Foundry | Microsoft Learn Microsoft Agent Framework Overview | Microsoft Learn What is Microsoft Foundry? - Microsoft Foundry | Microsoft LearnBuilding AI Agents with Microsoft Foundry: A Progressive Lab from Hello World to Self-Hosted
AI agent development has a steep on-ramp. The combination of new SDKs, tool-calling patterns, model selection decisions, retrieval-augmented generation, and deployment concerns means most developers spend more time wiring things together than actually building anything useful. The Microsoft Foundry Agent Lab is a structured, open-source demo series designed to change that — nine self-contained demos, each adding exactly one new concept, all built on the same Microsoft Foundry SDK and a single model deployment. This post walks through what the lab contains, how each demo works under the hood, and the architectural decisions that make it a useful reference for AI engineers building production agents. Why a Progressive Lab? Agent frameworks can be overwhelming. A developer who opens a rich example with RAG, tool-calling, streaming, and a custom UI all at once has no clear line of sight to which parts are essential and which are embellishments. The Foundry Agent Lab takes the opposite approach: start with the absolute minimum and introduce one new primitive per demo. By the time you reach Demo 8, you have seen every major capability — not in one monolithic sample, but in a layered sequence where each addition is visible and understandable. # Demo New Concept Tool Used UX 0 hello-demo Agent creation, Responses API, conversations None Terminal 1 tools-demo Function calling, tool-calling loop, live API FunctionTool Terminal 2 desktop-demo UI decoupling — same agent, different surface None Desktop (Tkinter) 3 websearch-demo Server-side built-in tools, no client loop WebSearchTool Terminal 4 code-demo Code execution in sandbox, Gradio web UI CodeInterpreterTool Web (Gradio) 5 rag-demo Document upload, vector stores, RAG grounding FileSearchTool Terminal 6 mcp-demo MCP servers, human-in-the-loop approval MCPTool Terminal 7 toolbox-demo Centralized tool governance, Toolbox versioning Toolbox Terminal 8 hosted-demo Self-hosted agent with Responses protocol Custom server Terminal + Agent Inspector The Model Router: One Deployment to Rule Them All Before diving into the demos, it is worth understanding the one architectural decision that ties the entire lab together: every agent uses model-router as its model deployment. MODEL_DEPLOYMENT=model-router Model Router is a Microsoft Foundry capability that inspects each request at inference time and routes it to the optimal available model — weighing task complexity, cost, and latency. A simple factual question goes to a fast, cheap model. A complex tool-calling chain with code generation gets routed to a frontier model. You write zero routing logic. The lab's MODEL-ROUTER.md file contains empirical observations from running all nine demos. A sample of what the router selected: Demo Query Task Type Model Selected hello "What's the capital of WA state?" Factual recall grok-4-1-fast-reasoning hello "Summarize our conversation" Summarization gpt-5.2-chat-2025-12-11 tools "What's the weather in Seattle?" Tool-using gpt-5.4-mini-2026-03-17 code Data analysis with code generation Code generation + execution gpt-5.4-2026-03-05 rag HR policy document question Retrieval + synthesis gpt-5.3-chat-2026-03-03 This is the strongest signal in the lab: you do not need to reason about model selection. You declare what your agent needs to do; the router handles the rest, and it chooses correctly. Demo 0: The Minimum Viable Agent The hello-demo establishes the baseline pattern used by every subsequent demo. Two files: one to register the agent, one to chat with it. Registering the agent from azure.identity import DefaultAzureCredential from azure.ai.projects import AIProjectClient from azure.ai.projects.models import PromptAgentDefinition credential = DefaultAzureCredential() project = AIProjectClient(endpoint=PROJECT_ENDPOINT, credential=credential) agent = project.agents.create_version( agent_name=AGENT_NAME, definition=PromptAgentDefinition( model=MODEL_DEPLOYMENT, instructions="You are a helpful, friendly assistant.", ), ) Authentication uses DefaultAzureCredential , which works with az login locally and with managed identity in production — no API keys anywhere in the code. Chatting with the agent # Create a server-side conversation (persists history across turns) conversation = openai.conversations.create() # Each turn sends the user message; the agent sees full history response = openai.responses.create( input=user_input, conversation=conversation.id, extra_body={"agent_reference": {"name": AGENT_NAME, "type": "agent_reference"}}, ) print(response.output_text) The conversation object is server-side. You pass its ID on every turn; the history lives in Foundry, not in a local list. This is the Responses API pattern — distinct from the older Completions or Chat Completions APIs. Demo 1: Function Tools and the Tool-Calling Loop Demo 1 adds function calling against a real weather API. The key insight here is that the model does not execute the function — it requests the execution, and your code executes it locally, then feeds the result back. Declaring a function tool from azure.ai.projects.models import FunctionTool, PromptAgentDefinition func_tool = FunctionTool( name="get_weather", description="Get the current weather for a given city.", parameters={ "type": "object", "properties": {"city": {"type": "string", "description": "City name"}}, "required": ["city"], }, strict=True, ) agent = project.agents.create_version( agent_name=AGENT_NAME, definition=PromptAgentDefinition( model=MODEL_DEPLOYMENT, tools=[func_tool], instructions="You are a weather assistant...", ), ) The tool-calling loop response = openai.responses.create(input=user_input, conversation=conversation.id, ...) # Loop while the model is requesting tool calls while any(item.type == "function_call" for item in response.output): input_list = [] for item in response.output: if item.type == "function_call": args = json.loads(item.arguments) result = get_weather(args["city"]) # execute locally input_list.append(FunctionCallOutput(call_id=item.call_id, output=result)) # Send results back to the agent response = openai.responses.create(input=input_list, conversation=conversation.id, ...) print(response.output_text) The strict=True parameter on FunctionTool enforces structured outputs — the model must return arguments that match the declared JSON schema exactly. This eliminates argument parsing errors in production. Demo 2: UI Is Not Your Agent Demo 2 runs the exact same agent as Demo 1 but surfaces it in a Tkinter desktop window. The point is pedagogical: your agent definition, conversation management, and tool-calling logic are entirely independent of your UI layer. Swapping from terminal to desktop requires changing only the presentation code — nothing in the agent or conversation path changes. This is a principle worth internalising early: agent logic and UI logic should never be entangled. The lab enforces this separation structurally. Demo 3: Server-Side Built-In Tools The web search demo introduces a sharp contrast with Demo 1. With WebSearchTool , the tool-calling loop disappears entirely from client code: from azure.ai.projects.models import WebSearchTool agent = project.agents.create_version( agent_name="Search-Agent", definition=PromptAgentDefinition( model=MODEL_DEPLOYMENT, tools=[WebSearchTool()], instructions="You are a research assistant...", ), ) The agent decides when to search, executes the search server-side, and returns a grounded response with citations. Your client code looks identical to Demo 0 — a simple responses.create() call with no tool loop. The distinction matters architecturally: Function tools (Demo 1) — tool execution happens on your client; you control the code, the API call, the error handling. Built-in tools (Demo 3+) — tool execution happens inside Foundry; you get results without managing execution. Demo 4: Code Interpreter and the Gradio Web UI Demo 4 attaches CodeInterpreterTool , which gives the agent a sandboxed Python execution environment inside Foundry. The agent can write code, run it, observe output, and iterate — all server-side. Combined with a Gradio web interface, this demo shows an agent that can perform data analysis, generate charts, and explain results through a browser UI. Model Router is particularly interesting here: the empirical data shows it selects a more capable frontier model ( gpt-5.4-2026-03-05 ) for code-generation tasks, while simpler conversational turns stay on lighter models. Demo 5: Retrieval-Augmented Generation with FileSearchTool Demo 5 introduces RAG. The setup phase uploads a document, creates a vector store, and attaches it to the agent: # Upload document and create a vector store vector_store = openai.vector_stores.create(name="employee-handbook-store") with open("data/employee-handbook.md", "rb") as f: openai.vector_stores.files.upload_and_poll( vector_store_id=vector_store.id, file=f ) # Attach the vector store to the agent agent = project.agents.create_version( agent_name="RAG-Agent", definition=PromptAgentDefinition( model=MODEL_DEPLOYMENT, tools=[FileSearchTool(vector_store_ids=[vector_store.id])], instructions="Answer questions using only the provided documents...", ), ) At query time, the agent embeds the question, searches the vector store semantically, retrieves matching chunks, and generates an answer grounded in the retrieved content — entirely server-side. The client code remains a plain responses.create() call. An important detail: the .vector_store_id file is written to disk during setup and read back during the chat session, so the demo survives process restarts without re-uploading the document. The .gitignore excludes this file from source control. Demo 6: Model Context Protocol Demo 6 connects the agent to a GitHub MCP server, giving it access to repository and issue data via the open Model Context Protocol standard. MCP servers expose tools over a standardised wire protocol; the agent discovers and calls them without any client-side function declarations. The demo also demonstrates human-in-the-loop approval: before executing any MCP tool call, the agent surfaces the proposed action and waits for the user to confirm. This is an important safety pattern for agents that can trigger side effects on external systems. Demo 7: Toolbox — Centralised Tool Governance Where Demo 6 connects to a single MCP server directly, Demo 7 uses a Toolbox — a managed Microsoft Foundry resource that bundles multiple tools into a single, versioned, MCP-compatible endpoint. The Toolbox in this demo exposes both GitHub Issues and GitHub Repos tools, curated into an immutable versioned snapshot. This pattern is significant for production multi-agent systems: Centralised governance — one team owns the tool definitions; all agents consume them via a single endpoint. Versioned snapshots — promoting a new Toolbox version is explicit; agents pin to a version and upgrade intentionally. MCP compatibility — any MCP-capable agent or framework can connect, not just Foundry SDK agents. from azure.ai.projects.models import McpTool toolbox_tool = McpTool( server_label="toolbox", server_url=TOOLBOX_ENDPOINT, allowed_tools=[], # empty = all tools in the Toolbox version headers={"Authorization": f"Bearer {token}"}, ) Demo 8: Self-Hosted Agent with the Responses Protocol The final demo departs from the prompt-agent pattern. Instead of registering a declarative agent in Foundry, Demo 8 implements a custom agent server using the Responses protocol. The server exposes a streaming HTTP endpoint; Foundry's Agent Inspector can connect to it and route user turns to it just as it would to a hosted prompt agent. This demo includes a Dockerfile and an agent.yaml , enabling deployment to Foundry's container hosting service. It uses gpt-4.1-mini directly rather than the model router, because the custom server owns the entire inference path. When to consider this pattern: Your agent requires custom pre- or post-processing logic that cannot be expressed in a system prompt. You need to integrate with infrastructure that is not reachable through MCP or built-in tools. You want to own the inference call for cost control, A/B testing, or compliance reasons. You are building a multi-agent orchestrator that needs to expose itself as an agent to other orchestrators. Getting Started The lab requires Python 3.10 or higher, an Azure subscription with a Microsoft Foundry project, and the Azure CLI. 1. Clone and set up the virtual environment git clone https://github.com/microsoft-foundry/Foundry-Agent-Lab.git cd Foundry-Agent-Lab # Create and activate the virtual environment python -m venv .venv # Windows Command Prompt .venv\Scripts\activate.bat # Windows PowerShell .venv\Scripts\Activate.ps1 # macOS / Linux source .venv/bin/activate pip install -r requirements.txt 2. Configure a demo copy hello-demo\.env.sample hello-demo\.env # Edit hello-demo\.env and set PROJECT_ENDPOINT Your PROJECT_ENDPOINT is on the Overview page of your Foundry project in the Azure portal. It takes the form https://your-resource.ai.azure.com/api/projects/your-project . 3. Run the demo az login 0-hello-demo Each numbered batch file at the root activates the virtual environment, runs create_agent.py , and launches chat.py . Append log to capture the full session transcript: 0-hello-demo log Reset between runs hello-demo\reset.bat Every demo includes a reset.bat that deletes the registered agent and any associated resources (vector stores, uploaded files). Demos are fully repeatable. Architecture Principles Demonstrated Across the nine demos, the lab illustrates a set of design principles that apply directly to production agent systems: Keyless authentication throughout Every demo uses DefaultAzureCredential . No API keys appear anywhere in the code. Locally, az login provides credentials. In production, managed identity takes over automatically — same code, no secrets to rotate. Server-side conversation state The Responses API stores conversation history server-side. Your application passes a conversation ID; Foundry maintains the thread. This eliminates the common bug of truncating history due to local list management and makes multi-process or multi-instance deployments straightforward. Client-side vs server-side tool execution The lab makes the distinction explicit. Function tools execute in your process — you control the code, the external call, and the error handling. Built-in tools (WebSearch, CodeInterpreter, FileSearch) execute inside Foundry — you get results without managing execution infrastructure. MCP tools (Demo 6, 7) fall between these: they execute in a separately deployed server, with the protocol mediating the call. Progressive tool introduction Each demo's create_agent.py registers the agent once. The chat.py file handles the conversation loop. These two responsibilities are always separate, making it easy to update agent definitions without modifying conversation logic, and vice versa. Security Considerations When building agents for production, keep the following in mind: Never commit .env files. The .gitignore excludes them, but verify this before pushing. Use Azure Key Vault or environment variable injection in CI/CD pipelines. Use managed identity in production. DefaultAzureCredential automatically picks up managed identity when deployed to Azure, eliminating the need for any stored credentials. Apply human-in-the-loop for side-effecting tools. Demo 6 demonstrates this pattern for MCP tool calls. Any agent that can modify external state (create issues, send emails, write files) should surface proposed actions for confirmation. Validate tool outputs before use. Treat data returned by external tools (weather APIs, search results, document retrieval) as untrusted input. Prompt injection through tool results is a real attack surface; grounding instructions in your system prompt reduce but do not eliminate this risk. Scope Toolbox permissions narrowly. When using a Toolbox (Demo 7), use allowed_tools to restrict which tools the agent can call, rather than granting access to all tools in a Toolbox version. Key Takeaways Start with the minimum. A prompt agent with no tools requires fewer than 30 lines of code using the Foundry SDK. Add tools only when the use case demands them. Use model-router unless you have a specific reason not to. The empirical data in the lab shows the router selects appropriate models across all task types — factual, creative, tool-calling, RAG, and code generation. Understand the client/server tool boundary. Function tools give you control; built-in tools give you simplicity. MCP and Toolbox give you governance and interoperability. Choose based on where you need control and where you need scale. Conversation state belongs on the server. Do not maintain conversation history in application memory if you can avoid it. The Responses API conversation object is designed for this. The hosted-demo pattern is for when you need to own the inference path. For most use cases, a declarative prompt agent is sufficient and far simpler to operate. Next Steps Explore the repo: github.com/microsoft-foundry/Foundry-Agent-Lab Microsoft Foundry SDK documentation: learn.microsoft.com/azure/ai-studio/ Responses API quickstart: Prompt agent quickstart Model Router conceptual documentation: Model Router for Microsoft Foundry Model Context Protocol: modelcontextprotocol.io Azure Identity SDK (DefaultAzureCredential): azure-identity Python SDK The Foundry Agent Lab is open source under the MIT licence. Contributions, bug reports, and feature requests are welcome through GitHub Issues. See CONTRIBUTING.md for guidelines.
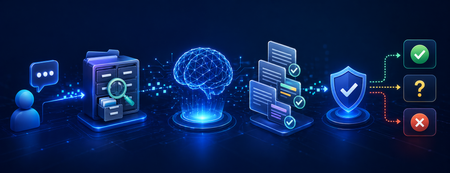
Confidence-Aware RAG: Teaching Your AI Pipeline to Acknowledge Uncertainty
Introduction Retrieval-Augmented Generation (RAG) has become the standard architecture for grounding Large Language Models (LLMs) with enterprise data. By retrieving relevant documents before generating a response, RAG helps reduce hallucinations compared to relying on model knowledge alone. However, an important limitation remains in most implementations: RAG systems can produce confident-sounding answers even when the underlying data is incomplete, irrelevant, or missing. This happens when: • Retrieved documents are loosely related to the query • The answer exists partially but lacks key details • Retrieved sources contradict each other • The query falls entirely outside the knowledge base In enterprise environments, this behavior carries real risk. A reliable AI system must not only answer well - it must also know when not to answer. This article presents a practical confidence-aware RAG architecture using three layered strategies: retrieval confidence scoring, citation validation, and LLM-based abstention - all implemented with Azure AI Search and Azure OpenAI. The Problem: Confident Hallucination Consider a real-world enterprise scenario. An employee asks: "What is our company's parental leave policy for contractors?""What is our company's parental leave policy for contractors?" The knowledge base contains parental leave policies for full-time employees - but nothing specific to contractors. A standard RAG pipeline retrieves the closest matching document and confidently presents full-time employee policy as the answer. This outcome is worse than returning no answer. The user trusts the system, acts on incorrect information, and the error may not surface until real consequences follow. This pattern is sometimes called hallucination laundering - the RAG architecture creates the appearance of factual grounding while the response is not actually supported by the retrieved evidence. Fixing this requires deliberate confidence checkpoints at each stage of the pipeline. Architecture Overview A standard RAG pipeline follows a simple path: User Query → Retrieve Documents → Generate Answer A confidence-aware pipeline adds two explicit decision checkpoints: Each layer catches failures the previous one may miss. Together, they form a defense-in-depth approach to output reliability. Strategy 1: Retrieval Confidence Scoring The first checkpoint evaluates whether retrieved documents are genuinely relevant before passing them to the LLM. Azure AI Search returns a @search.rerankerScore when semantic ranking is enabled - a value on the 0-4 scale that reflects how well each document matches the query intent, not just keyword overlap. from azure.search.documents import SearchClient from azure.identity import DefaultAzureCredential search_client = SearchClient( endpoint=AZURE_SEARCH_ENDPOINT, index_name="enterprise-knowledge-base", credential=DefaultAzureCredential() ) def retrieve_with_confidence(query: str, threshold: float = 1.5, top_k: int = 5): results = search_client.search( search_text=query, query_type="semantic", semantic_configuration_name="default", top=top_k, select=["content", "title", "source"] ) confident_results = [] for result in results: reranker_score = result.get("@search.rerankerScore", 0) if reranker_score >= threshold: confident_results.append({ "content": result["content"], "title": result["title"], "source": result["source"], "score": reranker_score }) return confident_results If no documents clear the threshold, the pipeline abstains rather than forcing a low-quality answer: results = retrieve_with_confidence(user_query, threshold=1.5) if not results: return { "answer": ( "I don't have enough information in the knowledge base to answer " "this question. Please contact the relevant team for assistance." ), "status": "abstained_retrieval" } Threshold tuning: Start at 1.5 on the 0-4 scale. Evaluate against a labeled test set and adjust based on your precision/recall requirements. Higher thresholds reduce false positives but may increase abstention on edge cases. Strategy 2: Citation Validation Even when retrieval scores are high, the LLM may synthesize information that does not exist in the retrieved context. Citation validation addresses this by requiring the model to ground every factual claim in a specific named source - and then programmatically verifying those citations exist in the retrieved set. from openai import AzureOpenAI client = AzureOpenAI( api_key=AZURE_OPENAI_API_KEY, azure_endpoint=AZURE_OPENAI_ENDPOINT, api_version="2025-12-01-preview" ) ANSWER_WITH_CITATIONS_PROMPT = """ You are an enterprise assistant. Answer the question using ONLY the provided context. RULES: 1. Every factual claim MUST include a citation in the format [Source: <title>]. 2. If the context does not contain enough information, respond with: "I don't have sufficient information to answer this question." 3. Do NOT infer, assume, or use knowledge outside the provided context. 4. If context partially answers the question, state what you know and explicitly note what information is missing. Context: {context} Question: {question} Answer: """ def generate_answer(question: str, context: str, sources: list) -> dict: prompt = ANSWER_WITH_CITATIONS_PROMPT.format( context=context, question=question ) response = client.chat.completions.create( model=AZURE_DEPLOYMENT_NAME, messages=[{"role": "user", "content": prompt}], temperature=0 ) answer = response.choices[0].message.content.strip() validation = validate_citations(answer, sources) return {"answer": answer, "citation_check": validation} The validation function checks that every citation in the answer maps to a document that was actually retrieved: import re def validate_citations(answer: str, sources: list) -> dict: cited = re.findall(r'\[Source:\s*(.+?)\]', answer) source_titles = {s["title"].lower().strip() for s in sources} valid, invalid = [], [] for citation in cited: if citation.lower().strip() in source_titles: valid.append(citation) else: invalid.append(citation) return { "total_citations": len(cited), "valid": valid, "invalid": invalid, "is_trustworthy": len(invalid) == 0 and len(cited) > 0 } If is_trustworthy is False, the pipeline flags the response for review or suppresses it: if not generation["citation_check"]["is_trustworthy"]: return { "answer": "I found related information but cannot provide a reliable answer based on the available sources.", "status": "abstained_citation" } Strategy 3: LLM-Based Abstention Scoring The third layer adds a second LLM call that acts as a quality judge - explicitly evaluating whether the generated answer is well-supported by the retrieved context, independent of citation formatting. ABSTENTION_JUDGE_PROMPT = """ You are an answer quality judge. Given a question, retrieved context, and a generated answer, evaluate whether the answer is fully supported by the context. Respond ONLY in JSON format: {{ "verdict": "supported" | "partial" | "unsupported", "confidence": <float between 0.0 and 1.0>, "reasoning": "<brief explanation>" }} Question: {question} Context: {context} Answer: {answer} """ def judge_answer(question: str, context: str, answer: str) -> dict: import json prompt = ABSTENTION_JUDGE_PROMPT.format( question=question, context=context, answer=answer ) response = client.chat.completions.create( model=AZURE_DEPLOYMENT_NAME, messages=[{"role": "user", "content": prompt}], temperature=0 ) return json.loads(response.choices[0].message.content.strip()) Integrate the judge with a confidence threshold of 0.6: judgement = judge_answer(user_query, context, generation["answer"]) if judgement["verdict"] == "unsupported" or judgement["confidence"] < 0.6: return { "answer": "I don't have sufficient information to answer this question confidently.", "status": "abstained_judge" } if judgement["verdict"] == "partial": generation["answer"] += ( "\n\nNote: This answer may be incomplete. " "Some aspects of your question were not covered in the available documents." ) End-to-End Pipeline Combining all three strategies gives a complete confidence-aware pipeline: def confidence_aware_rag(user_query: str) -> dict: # Layer 1: Retrieve with confidence gating results = retrieve_with_confidence(user_query, threshold=1.5) if not results: return { "answer": "I don't have enough information in the knowledge base to answer this.", "status": "abstained_retrieval" } context = "\n\n".join(r["content"] for r in results) # Layer 2: Generate with citation requirements generation = generate_answer(user_query, context, results) if not generation["citation_check"]["is_trustworthy"]: return { "answer": "I found related information but cannot provide a reliable answer.", "status": "abstained_citation" } # Layer 3: Judge the answer judgement = judge_answer(user_query, context, generation["answer"]) if judgement["verdict"] == "unsupported" or judgement["confidence"] < 0.6: return { "answer": "I don't have sufficient information to answer this question confidently.", "status": "abstained_judge" } if judgement["verdict"] == "partial": generation["answer"] += ( "\n\nNote: This answer may be incomplete. " "Some aspects of your question were not covered in available documents." ) return { "answer": generation["answer"], "status": "answered", "confidence": judgement["confidence"], "sources": [r["source"] for r in results[:3]] }def confidence_aware_rag(user_query: str) -> dict: # Layer 1: Retrieve with confidence gating results = retrieve_with_confidence(user_query, threshold=1.5) if not results: return { "answer": "I don't have enough information in the knowledge base to answer this.", "status": "abstained_retrieval" } context = "\n\n".join(r["content"] for r in results) # Layer 2: Generate with citation requirements generation = generate_answer(user_query, context, results) if not generation["citation_check"]["is_trustworthy"]: return { "answer": "I found related information but cannot provide a reliable answer.", "status": "abstained_citation" } # Layer 3: Judge the answer judgement = judge_answer(user_query, context, generation["answer"]) if judgement["verdict"] == "unsupported" or judgement["confidence"] < 0.6: return { "answer": "I don't have sufficient information to answer this question confidently.", "status": "abstained_judge" } if judgement["verdict"] == "partial": generation["answer"] += ( "\n\nNote: This answer may be incomplete. " "Some aspects of your question were not covered in available documents." ) return { "answer": generation["answer"], "status": "answered", "confidence": judgement["confidence"], "sources": [r["source"] for r in results[:3]] } Choosing the Right Strategies for Your Use Case Each strategy adds a layer of safety at a different cost. The right combination depends on the stakes involved in your deployment. Strategy Added Cost Latency Best For Retrieval Confidence Scoring None (uses existing search scores) None All RAG applications - this should be universal Citation Validation Minimal (regex post-processing) Negligible Regulated industries, compliance, audit trails LLM Abstention Judge One additional LLM call +1-3 seconds High-stakes decisions - financial, legal, medical For most enterprise applications, combining retrieval scoring and citation validation provides a strong baseline with minimal overhead. The judge layer is most valuable when incorrect answers carry significant business or compliance risk. Threshold calibration There is a meaningful tradeoff in threshold selection. Setting thresholds too high reduces hallucination but increases abstention - the system may refuse to answer even when reliable information is available. The recommended approach is to build a labeled evaluation set of query/answer pairs, run the pipeline at multiple threshold values, and select the point that meets your precision/recall requirements for the specific domain. When to Apply This Pattern Confidence-aware RAG is most valuable in deployments where: Data coverage is uneven - the knowledge base may have detailed coverage in some areas and gaps in others, making it difficult to predict when retrieval will be reliable Errors carry downstream consequences - healthcare documentation, legal and compliance search, financial reporting, and regulated industries where a wrong answer is worse than no answer Users have varying expertise - non-expert users may not recognize a plausible-sounding but incorrect response, making transparent uncertainty signals especially important Audit or traceability requirements apply - the ability to trace each answer back to a specific source with a confidence signal supports governance and review workflows Conclusion Building a RAG system that retrieves documents and generates responses is relatively straightforward. Building one that understands the limits of its own knowledge requires deliberate design. The three strategies covered here - retrieval confidence scoring, citation validation, and LLM-based abstention - form a layered defense against the most common failure mode in production RAG systems: the confident, well-formatted, completely unreliable answer. The most dangerous AI system is not one that fails openly. It is one that fails silently, with confidence. Teaching your pipeline to say "I don't know" is not a limitation. It is a feature that builds user trust and makes enterprise AI adoption sustainable over time.