performance
583 TopicsAnnouncing Premium SSD v2 for Azure Database for MySQL - Public Preview at Ignite 2026
We’re excited to introduce Premium SSD v2 (Managed Disk) support for Azure Database for MySQL in Public Preview. This new storage option offers greater control over database storage performance and capacity, helping optimize price-performance for a wide range of MySQL workloads. As application workloads evolve, performance requirements can increase without a corresponding need for additional storage capacity. Premium SSD v2 offers the flexibility to independently configure storage capacity, input/output operations per second (IOPS), and throughput. This capability enables precise performance tuning to meet changing workload demands while optimizing resource utilization and cost. What is Premium SSD v2? Premium SSD v2 is a next-generation Azure managed disk offering designed for performance-sensitive workloads. Its integration with Azure Database for MySQL server enables greater flexibility in storage configuration, allowing resources to be tailored to application performance requirements. Key benefits are listed below: Modernization of the Compute and Storage Stack Azure Database for MySQL is moving to a modern compute and storage platform built on Premium SSD v2, with a gradual move away from Premium File Share (PFS). Premium SSD v2 supports the latest General Purpose and Memory Optimized V6 compute families. It allows storage capacity, IOPS, and throughput to be configured independently, making it easier to meet different workload needs. The foundation for what's next - All next-generation compute families for Azure Database for MySQL will use Premium SSD v2, establishing a consistent, flexible foundation for future workloads. For workloads that need even higher storage performance, Ultra Disk will provide another option. Together, these changes will modernize the platform and support future workload needs as we gradually move away from Premium File Share (PFS). Quick glance at Azure MySQL with Premium File Share vs Premium SSD v2 Premium SSD v2 lets you set storage capacity, IOPS and throughput independently, unlike Premium File Share (PFS). You can get the performance your workload needs without over-provisioning storage. Each Premium SSD v2 disk supports up to 80,000 IOPS and 2,000 MB/s. Actual MySQL performance depends on your compute SKU, storage configuration and workload. In internal out-of-box (OOB) TPCC benchmarks, conducted without additional tuning, Azure Database for MySQL on Premium SSD v2 delivered approximately 53-65% higher NOPM than Azure Database for MySQL on Premium File Share (PFS) with Accelerated Logs (AL) enabled across 128-512 virtual users in TPC-C HammerDB tests. These results demonstrate a significant improvement in transaction throughput for the workloads tested. How to Deploy Azure Database for MySQL with Premium SSD v2 In the Azure portal, when you create an Azure Database for MySQL server, from the Compute + storage section click Configure Server. Go to the Storage section, select Storage type, and choose Premium SSD v2. Provide your desired disk size for Storage size (in GiB). Select your IOPS as per your workload requirements. By default, 3000 IOPS are included free of cost for all premium SSD v2 disks. Provide your Throughput details. By default, 125Mib/Sec throughput is included free of cost for all premium SSD v2 disks. Click Save. Billing Premium SSD v2 disks are billed hourly based on the provisioned capacity, IOPS, and throughput. Let us take an example of a disk that you provision with 200 GiB capacity, 7,000 IOPS, and 250 MBPS throughput. Premium SSD v2 is billed per GiB of the provisioned capacity. Hence, you will be charged for 200 GiB of the provisioned capacity. The disk is billed for any additional IOPS provisioned over the free baseline of 3,000 IOPS. In this case, since you provisioned 7,000 IOPS, you will be billed for the additional 4,000 IOPS. The disk is billed for any additional throughput over the free baseline throughput of 125 MBPS. In this case, since you provisioned 250 MBPS throughput, you will be billed for an additional 125 MBPS throughput. For additional details, refer Azure Pricing Calculator. Getting Started: Excited to experience the unmatched power of Premium SSD v2? Dive into our official documentation to explore all the features, region availability, and early preview limitations. We are always here to assist you on your journey. To learn even more about our Azure Database for MySQL service, see the documentation. To learn more about the latest features released, see what's new. If you have any questions or need guidance, don't hesitate to reach out to us at Ask Azure DB for MySQL.127Views0likes0Comments
End-to-end workload observability with Query Store for primary and replicas
Query performance doesn’t stop at the primary Most PostgreSQL architectures don’t run on a single node anymore. Reads get offloaded. Replica chains grow. And when performance issues hit, the hardest part is often simple: where did the queries actually run? With the latest query store capabilities in Azure Database for PostgreSQL flexible server, you can now capture workload executed not just on the primary, but also on read replicas—including cascading read replicas—and export the captured runtime stats, wait stats, and query text into Azure Monitor Logs (Log Analytics workspace / LAWS). See the real hotspot: isolate which node (primary vs replica) is slow. Know why: break down time by waits (CPU, I/O, locks) per query. Connect the dots: correlate query IDs to query text, and inspect sampled parameters locally in azure_sys on the primary when you need input context (parameters aren’t exported to LAWS). Centralize analysis: query everything with KQL in LAWS, across servers. What you’ll build This post walks through a reproducible demo that provisions a primary server, a read replica, and a cascading read replica, then runs a TPC-H–based workload across all three to generate query store data you can analyze locally and in Log Analytics. Enable query store capture (including query text) and parameter sampling for parameterized queries. Enable wait sampling so query store can record wait statistics. Export runtime stats, wait stats, and SQL text to LAWS using resource-specific tables. Validate capture on read replicas and cascading read replicas (not just the primary). Prerequisites Azure CLI logged in (az login) and permission to create a resource group, Log Analytics workspace, and PostgreSQL flexible servers. psql and curl available on your machine. PostgreSQL flexible server on General Purpose or Memory Optimized tier (query store and replicas aren’t supported on Burstable). PostgreSQL 14+ to test out cascading replicas. Networking: the script opens firewall access broadly for demos—tighten for production. Architecture (primary + replica chain + LAWS) You’ll deploy four resources: Primary server: read/write node. Read replica (level 1): read-only node created from the primary. Cascading read replica (level 2): read-only node created from replica level 1. Log Analytics workspace (LAWS): central place to query Query Store telemetry across all nodes. If Diagnostic Settings is properly configured, each server streams query store telemetry to LAWS—but how it’s kept locally differs by role. On the primary, query store data is recorded in-memory, then persisted locally in the azure_sys database, and then exported to LAWS. On read replicas (including cascading replicas), query store data is recorded in-memory only and then exported to LAWS. Bottom line: use LAWS for fleet-wide visibility, and use the primary’s azure_sys when you need deep local inspection (like parameter samples). Deploy the demo environment The fastest way to reproduce the scenario is to run the end-to-end bash script which you can download from https://raw.githubusercontent.com/Azure-Samples/azure-postgresql-query-store/refs/heads/main/may2026/script/query_store_demo.sh Save the file to a local directory in your Linux shell, and name the file query_store_demo.sh. To invoke the script, at minimum, you must assign a string password for the administrator login of the instances of the flexible servers it creates, and invoke the script like this: ADMIN_PASSWORD=<Your_Strong_Password> ./query_store_demo.sh Optionally, you can also override default values for other environment variables used by the script: Variable Purpose Default SUBSCRIPTION_ID Azure subscription ID to use (current default subscription) BASE_NAME Base name for all resources (used in naming servers, resource groups, etc.) pgqswait{YYYYMMDDHHMMSS} RESOURCE_GROUP Azure resource group name rg-{BASE_NAME} LOCATION Azure region for resources southeastasia PRIMARY_SERVER Name of primary PostgreSQL server {BASE_NAME}-primary REPLICA_1 Name of first-level read replica {BASE_NAME}-readreplica REPLICA_2 Name of second-level cascading read replica {BASE_NAME}-cascadereadreplica LOG_ANALYTICS_WORKSPACE Log Analytics workspace name law-{BASE_NAME} LOG_ANALYTICS_LOCATION Azure region for Log Analytics workspace southeastasia ADMIN_USER PostgreSQL admin username pgadmin ADMIN_PASSWORD PostgreSQL admin password (REQUIRED) SKU_NAME PostgreSQL server SKU (compute tier) Standard_D4ds_v5 TIER PostgreSQL pricing tier GeneralPurpose STORAGE_SIZE Storage size in GB 64 VERSION PostgreSQL version (minimum 14 for cascading replicas) 17 PRIMARY_DATABASE Initial database name postgres SQL_BASE_URL Base URL for downloading SQL scripts https://raw.githubusercontent.com/Azure-Samples/azure-postgresql-query-store/refs/heads/main/may2026/script/query_store_demo.sh TPCH_DDL_URL URL for TPC-H schema DDL file {SQL_BASE_URL}/schema/tpch_ddl.sql WORKLOAD_REPETITIONS Number of times to execute each workload query (minimum 5) 10 AUTO_APPROVE Skip confirmation prompt and proceed automatically false If, for example, you want to not only pass the ADMIN_PASSWORD but also override the LOCATION, you could do it like this: ADMIN_PASSWORD=<Your_Strong_Password> LOCATION=canadacentral ./query_store_demo.sh In a bit over 1 hour, the script will do the following steps: Step 1 — Provision first part of the infrastructure The infrastructure provisioned in this phase consists of: A resource group in which all resources are deployed. An instance of Log Analytics workspace, where all flexible server instances will send their query store related logs. A primary (read-write) flexible server. Step 2 — Configure primary server Now it's time to configure one new server parameters on your primary server so that query store emits query text to LAWS, so that we can correlate quey IDs to something recognizable. Query IDs are great for aggregation—but you still need the SQL. Turn on query text emission so you can correlate runtime and waits back to the actual statement text. Do this by setting pg_qs.emit_query_text to on. Refer to our documentation to learn how to set the value of a server parameter. Step 3 — Provision second part of the infrastructure The infrastructure provisioned in this phase consists of: A read replica (read-only) whose source is the primary server. A cascade read replica (read-only), whose source is the previously created read replica. Notice that when read replicas are created, they inherit the server parameter values from their source server. Because we have configured query store related settings on the primary server already, the intermediate read replica inherits its server parameters from that primary, and the cascade read replica inherits them from the intermediate replica. Step 4 — Export query store to Log Analytics (LAWS) Now for the payoff, we want to stream the data to Log Analytics so you can query across nodes, build dashboards, and alert. The script configures diagnostic settings on the primary and both replicas to send logs to a Log Analytics workspace using resource-specific tables. This is the key to cross-node visibility: each server exports its own captured telemetry, and you can slice by resource in a single KQL query. Query store runtime stats: execution counts, elapsed time, and other performance counters. Query store wait stats: wait breakdown attributed to queries. Query store SQL text: query text to decode query IDs. Note: Query store parameter samples are not included in the Log Analytics export. Parameters are stored locally per server in azure_sys, and on read replicas azure_sys is read-only—so don’t depend on replicas for parameter inspection. LAWS receives runtime stats, wait stats, and query text. Diagnostics settings for an instance of flexible server can be configured via portal. In the resource menu, under Monitoring, select Diagnostic settings. Add a new diagnostic setting, select a destination Log Analytics workspace, and the individual log catergories which you want to stream to that LAWS, and save the changes. For Destination table it's highly recommended to use Resource specific (one table per signal with proper schema) over Azure diagnostics (legacy one table for everything). With Azure diagnostics, all logs from all resource types land into a single table (AzureDiagnostics). It's a wide table with many columns. New columns get added as services emit new fields. If the 500 column limit is hit, extra fields go into the AdditionalFields column (a dynamic JSON). Querying on attributes stored in that column might have huge performance and query cost impact. The schema is inconsistent and difficult to discover. You must always filter events in that table by ResourceType and Category. On the other hand, with Resource specific, logs are written to separate tables per resource type and category. Therefore, each table has a well-defined schema and columns are strongly typed. Tables are smaller and faster to query. Queries on these tables are simpler don't need filtering by ResourceType and Category. Performance-wise, they also support faster ingestion and faster querying. They also support selecting different table plans and retention settings for each table. And, more importantly, role-based access control (RBAC) permissions can be applied at table level, allowing you to control access to telemetry in a more granular way. Note: If you want to see any of the images in this article in better quality, click on them to see them in their original size. This can also be configured using Azure CLI command az monitor diagnostic-settings create. Make sure that the --export-to-resource-specific parameter is set to true, which is the equivalent of selecting Resource specific for Destination table in portal UI. Setting this parameter to false, would mean that you want to use AzureDiagnostics as the destination table, which we don't recommend using. Step 5 — Run some workload In this phase the script loads a TPC-H schema and executes workload SQL across different nodes so that you can prove replica capture. Query it in Log Analytics Once the workload completed and data was streamed to Log Analytics, you can open your Log Analytics workspace, and start querying the relevant tables. If you don't know how to start issuing queries in a Log Analytics workspace, refer to Get started with log queries in Azure Monitor Logs. In your Log Analytics workspace, when you select Logs in the resource menu, you can access the Queries hub. By default, it should open automatically unless you have configured it to not show, in which case you can open by selecting Queries hub on the top right corner of the Logs home screen. If you add a filter in the queries hub for Resource type equals Azure Database for PostgreSQL Flexible Server, you'll be able to access multiple examples of queries which might help you get started querying the log categories we support for our service. You can run any of them by selecting Run on the summarization card that describes the query or, if you hover the mouse over the card, you can select Load to editor so that the query is copied over to the active query window, and you can run it or modified it further. Following, there are a few more query examples which can be useful to analyze the workload executed in this experiment. Top queries by total time (across all nodes) To get the list of 10 queries with higher duration from the ones that ran on any of the three nodes. KQL PGSQLQueryStoreRuntime | summarize total_time_ms = sum(TotalExecDurationMs) by QueryId, LogicalServerName | top 10 by total_time_ms desc Results Important: Results might be slightly different on each execution of the experiment. Where queries wait on each node List the most frequent wait events observed on user initiated queries across all nodes. KQL PGSQLQueryStoreWaits | join kind=inner (PGSQLQueryStoreRuntime) on QueryId | summarize total_waits_sampled = sum(Calls) by Event, EventType, LogicalServerName | order by total_waits_sampled desc Results Important: Results might be slightly different on each execution of the experiment. Decode query IDs (join runtime stats with SQL text) Top 20 queries the most frequent wait events observed on user initiated queries across all nodes. KQL PGSQLQueryStoreRuntime | join kind=inner (PGSQLQueryStoreQueryText) on QueryId | where QueryType == 'select' | project LogicalServerName, QueryId, TotalExecDurationMs, QueryText | top 20 by TotalExecDurationMs desc Results Important: Results might be slightly different on each execution of the experiment. Compare primary vs replicas (workload distribution) Find total number of query executions and accumulated duration of all those executions for each node. KQL PGSQLQueryStoreRuntime | summarize execs = sum(Calls), total_time_ms = sum(TotalExecDurationMs) by LogicalServerName | order by total_time_ms desc Results Important: Results might be slightly different on each execution of the experiment. Replica-only hotspots (find what’s slow off the primary) Find top 10 queries executed by their aggregated duration, focusing on what was executed on read replicas only. KQL let Replicas = dynamic(["pgqswait20260505220501-readreplica", "pgqswait20260505220501-cascadereadreplica"]); PGSQLQueryStoreRuntime | where LogicalServerName in (Replicas) | summarize total_time_ms = sum(TotalExecDurationMs) by QueryId, LogicalServerName | top 10 by total_time_ms desc Results Important: Results might be slightly different on each execution of the experiment. QPI now supports query store stats collected on replicas You can now use Query Performance Insight workbooks to analyze query store information not only on your primary server, as you were used to, but you can also get that valuable information on your read replicas. Why replica workload capture is a big deal This is the unlock: you can now answer performance questions in replica-heavy architectures without stitching together partial signals. Per-node truth: see the slow queries on the node where they actually ran (primary vs replica vs cascading replica). Faster root cause: runtime + waits gives you “slow” and “why” in one place. Replica tuning that sticks: identify replica-specific bottlenecks (I/O saturation, lock waits, CPU pressure) and tune with evidence. Centralized observability: export to LAWS so you can build dashboards, alerts, and cross-server comparisons with KQL. Unlock query visibility: Access query text without database permissions. Fine grain control on who can view query text: Using resource specific tables in LAWS, you can decide which users can access the table in which text of the queries is kept. Parameter-aware debugging: sampled parameters can help reproduce issues and explain plan changes, but they’re stored locally in azure_sys and not exported to LAWS. In practice, rely on the primary for parameter inspection (replicas have read-only azure_sys). Operational notes (quick but important) Expect a delay: Query store stats and LAWS ingestion aren’t instant. Give it a few minutes after running workload. Mind retention: Query store retention and Log Analytics retention are separate knobs. Tune them to balance troubleshooting value and cost. Production hygiene: don’t use wide-open firewall rules outside of a demo. Clean up When you’re done, delete the resource group: az group delete --name <RESOURCE_GROUP> --yes --no-wait Bottom line Query store in Azure Database for PostgreSQL flexible server now matches how modern architectures run—across primary, read replicas, and cascading replicas—and LAWS gives you a single place to query, compare, and act.Seconds of Downtime, Hours of Confusion: Handling Transient Azure SQL Disconnects
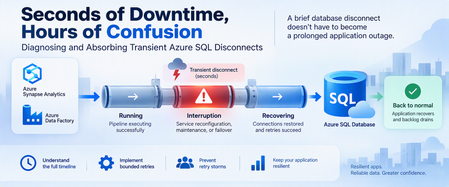
A database can recover in seconds while an application remains unavailable for much longer. Brief connectivity interruptions are expected failure modes that cloud applications should be designed to tolerate. With Azure SQL Database, transient connectivity errors can occur during short-lived service reconfiguration events. Microsoft notes that many such reconfiguration events complete in less than 60 seconds and recommends that applications implement retry logic rather than immediately surfacing transient failures to users. But the database interruption is only part of the story. An application might continue experiencing problems because of: Failed connections. Lost in-flight operations. Retry behavior. Connection-pool recovery. Authentication or token issues. Queued requests. Application instances retrying simultaneously. Backlogs that must drain after connectivity returns. This leads to an important troubleshooting principle: Database recovery and application recovery are separate milestones. Understanding that difference can turn a confusing availability incident into a defensible timeline and, more importantly, a more resilient application design. 1. Transient Does Not Mean Harmless A transient interruption is temporary, but its application impact doesn't have to be. Consider a simplified timeline: Time Event T0 Application healthy T1 Database connectivity is interrupted T2 Database connectivity becomes available again T3 Applications reconnect T4 Request backlog begins draining T5 Application returns to normal The actual database connectivity event is: T1 → T2 But users might experience impact across: T1 → T5 Calling the entire T1-to-T5 period a continuous database outage would be inaccurate unless evidence proves that the database itself remained unavailable. Instead, investigate the periods separately. 2. Build a Three-Layer Timeline A good post-incident investigation should correlate three timelines. Layer 1: Database/connectivity behavior Capture: Connection failures. Successful reconnections. Relevant Azure monitoring signals. Azure Service Health information when applicable. Database resource behavior. Layer 2: Client connectivity Capture: SQL exception number. Exception timestamp in UTC. Connection timeout. Retry attempts. Retry delays. Authentication failures. Network errors. Azure SQL troubleshooting guidance recommends logging failure timestamps and notes that SQL Database can return tracing information helpful during connectivity investigations. Layer 3: Application recovery Capture: Application health. Request failures. Queue depth. Retry volume. Connection-pool recovery. Backlog drain time. Time when users actually recovered. The timelines might reveal: Database connectivity restored │ ▼ Applications reconnect │ ▼ Backlog continues │ ▼ Application fully recovered That distinction is essential. 3. Classify the Failure Before Retrying It Not every SQL connectivity error means the same thing. Classify the symptom into categories such as: Transient availability/connectivity failure. Authentication failure. Token-related failure. Network-path problem. DNS problem. Firewall/configuration issue. Resource-governance condition. Application timeout. Long application recovery after SQL connectivity returns. Azure SQL Database documents multiple connectivity failure categories, including transient fault errors such as 40197 and 40613, authentication failures such as 18456, network termination conditions, firewall issues, and connection timeouts. The classification matters because: Not every failure should be retried in the same way. 4. Use Azure SQL Connectivity History Carefully Azure SQL Database exposes connectivity-event information through system views in the logical server's master database. One useful view is: sys.database_connection_stats It provides aggregated connection success and failure information in five-minute intervals. Connect to the logical server's master database and run: DECLARE @StartTime datetime2 = DATEADD(HOUR, -2, SYSUTCDATETIME()); SELECT database_name, start_time, end_time, success_count, total_failure_count, connection_failure_count FROM sys.database_connection_stats WHERE start_time >= @StartTime ORDER BY start_time DESC; This can help answer: Did connection failures occur? Which database was affected? In which five-minute interval? Were successful connections also occurring? But there's an important limitation. This is aggregated historical information, not a second-by-second outage trace. The data can also arrive later, with Microsoft documenting that it can take up to 24 hours for all information to appear. Therefore, don't use one five-minute bucket containing failures to claim: "The database was unavailable for five minutes." The evidence only tells you connection failures were recorded during that interval. 5. Look Deeper With sys.event_log For additional connectivity-event information, Azure SQL Database exposes: sys.event_log This view records successful database connections and connection failures and is intended to help track and troubleshoot Azure SQL Database connectivity activity. Again, connect to master. DECLARE @StartTime datetime2 = DATEADD(HOUR, -2, SYSUTCDATETIME()); SELECT database_name, start_time, end_time, event_category, event_type, event_subtype, event_subtype_desc, severity, event_count, description FROM sys.event_log WHERE start_time >= @StartTime AND event_category = N'connectivity' ORDER BY start_time DESC; Useful columns include: start_time end_time event_category event_type event_subtype_desc severity event_count description Microsoft cautions that querying sys.event_log can consume significant resources on logical servers with many databases or high login volumes, so keep the time range and other filters appropriately narrow. 6. Correlate SQL Evidence With Application Errors Now correlate the Azure SQL evidence with client telemetry. For every important application-side SQL exception, capture: UTC timestamp. SQL error number. Error message. Application instance. Operation. Retry attempt. Retry delay. Final outcome. Correlation or request ID when available. For example: UTC Layer Observation 10:00:02 Application SQL connection exception 10:00:04 Application Retry 1 fails 10:00:08 Application Retry 2 fails 10:00:15 SQL Connectivity succeeds 10:00:18 Application New connection succeeds 10:01:30 Application Queue still processing 10:05:00 Application Normal service restored Now you can separate: Connectivity interruption. Reconnection period. Application recovery period. That's substantially more useful than describing the full period as: "SQL was down." 7. Understand Connectivity and Reconfiguration Applications connect to the Azure SQL Database gateway, after which traffic is handled according to the effective connection policy and directed to the appropriate database environment. In a managed database service, applications must be designed for transient connectivity interruption. Microsoft specifically describes transient faults as conditions whose underlying cause resolves itself and notes that service reconfiguration can temporarily affect database connectivity. The application therefore shouldn't depend on one connection remaining valid indefinitely. Design for: Connections occasionally being terminated. New connection attempts occasionally failing. In-flight work requiring recovery. DNS and network paths needing to remain correctly configured. Authentication credentials or tokens remaining valid. Retry behavior that allows the system time to recover. Avoid guessing at undocumented platform internals when investigating an event. If evidence establishes only: "Connections failed briefly." Don't convert that into an unsupported explanation of why the platform changed state. 8. Retry Smartly, Not Aggressively Retry logic is essential for cloud applications that connect to Azure SQL Database. Microsoft explicitly recommends retry logic for transient connection failures. But a retry strategy needs boundaries. A good strategy considers: Number of attempts. Delay between attempts. Increasing delay. Random jitter. Maximum interval. Total retry budget. Whether the operation can safely be repeated. A bad strategy looks like: Failure ↓ Retry immediately ↓ Failure ↓ Retry immediately ↓ Failure ↓ Retry immediately... Across hundreds of application instances, this behavior can make recovery harder. A better pattern is: Failure ↓ Wait + jitter ↓ Retry ↓ Longer wait + jitter ↓ Retry ↓ Stop after bounded attempts 9. Use Microsoft.Data.SqlClient Retry Logic For .NET applications using Microsoft.Data.SqlClient, configurable retry logic is available in version 3.0 and later. Microsoft documents providers for configuring connection and command retries. A connection retry provider can be configured like this: var options = new SqlRetryLogicOption() { NumberOfTries = 5, DeltaTime = TimeSpan.FromSeconds(1), MaxTimeInterval = TimeSpan.FromSeconds(20) }; SqlRetryLogicBaseProvider provider = SqlConfigurableRetryFactory.CreateExponentialRetryProvider(options); using var connection = new SqlConnection(connectionString); connection.RetryLogicProvider = provider; connection.Open(); With this configuration: NumberOfTries = 5 Allows one initial attempt and up to four retries. DeltaTime Influences the delay between attempts. MaxTimeInterval Caps an individual retry delay. The exponential provider adds randomized jitter to retry intervals. The actual values should be tested against your application's: Latency requirements. Failure budget. Traffic volume. Concurrency. User experience. They're not universal service recommendations. 10. Connection Retry and Command Retry Are Different This is one of the most important resiliency distinctions. Suppose this fails: connection.Open(); Retrying the connection after an appropriate delay is generally straightforward for a transient connection condition. But suppose this fails: UPDATE dbo.Orders SET ProcessingStatus = N'Completed' WHERE OrderID = @OrderID; The application now has a harder question: Did the UPDATE execute before the connection was lost? Blindly repeating the command isn't always safe. Microsoft's Azure SQL guidance recommends establishing a fresh connection after a transient command failure before retrying, and retry logic must correctly account for the transaction's outcome. 11. Idempotency Matters Different operations require different retry treatment. Read-only operation For example: SELECT OrderID, ProcessingStatus FROM dbo.Orders WHERE OrderID = @OrderID; Repeating a read is often relatively straightforward, subject to your application's consistency requirements. Update operation For example: UPDATE dbo.Orders SET ProcessingStatus = N'Completed' WHERE OrderID = @OrderID; The client must determine whether repeating this operation is safe. Insert operation Consider: INSERT dbo.PaymentRequests ( RequestID, AccountID, Amount ) VALUES ( @RequestID, @AccountID, @Amount ); If the connection disappears after the server commits but before the client receives confirmation, an unconditional retry could create duplicate business activity unless the application and schema provide an idempotency mechanism. For example, a unique request identifier can make duplicate detection possible. The important principle is: Retryability is a business-operation property, not simply a SQL error property. 12. Transactions Need Special Treatment Be particularly careful with multi-statement transactions. Consider: BEGIN TRANSACTION; UPDATE dbo.Inventory SET Quantity = Quantity - @Quantity WHERE ProductID = @ProductID; INSERT dbo.ShipmentQueue ( RequestID, ProductID, Quantity ) VALUES ( @RequestID, @ProductID, @Quantity ); COMMIT TRANSACTION; If connectivity is interrupted, don't simply reconnect and retry the last statement. Your application needs a strategy that protects the integrity of the entire unit of work. Microsoft's retry documentation specifically cautions that if a transient failure invalidates an active transaction, the application should retry the entire transaction rather than only the failed statement. 13. Prevent the Retry Storm Imagine 500 application instances lose connectivity simultaneously. If every instance retries immediately: 500 requests fail ↓ 500 immediately retry ↓ Another synchronized wave ↓ Another synchronized wave Recovery traffic itself can become disruptive. Exponential backoff with jitter helps spread retries across time instead of concentrating them into synchronized bursts. The configurable retry provider in Microsoft.Data.SqlClient supports exponential retry behavior with randomized jitter. Also consider application-level resilience mechanisms such as: Circuit breakers. Back-pressure. Queueing. Controlled concurrency. Connection-pool recovery. Rate limiting. Load shedding where appropriate. The objective isn't: "Retry until SQL succeeds." It's: Recover gracefully without creating a second problem. 14. Don't Ignore the Network Path Not every SQL connection failure originates from the database. Azure SQL Database connectivity includes several components between the application and database, with connection behavior also influenced by the configured connection policy. Troubleshooting may need to include: DNS. Firewall configuration. Private endpoints. Network security rules. Client outbound connectivity. Connection policy. Authentication. Application host health. Azure SQL supports Redirect, Proxy, and Default connection-policy configurations depending on the environment and configuration. In Redirect mode, clients establish connections directly to the node hosting the database after the initial gateway interaction, which requires appropriate network access. This is another reason not to classify every connection exception as: "Azure SQL outage." 15. Test Resiliency Before an Incident Don't wait for a real platform event to discover whether your application's recovery logic works. Test controlled failure scenarios involving: New connections. Existing connections. Read-only requests. Writes. Multi-statement transactions. Multiple application instances. Queued workloads. Connection pools. Measure: Time to detect failure. First retry delay. Number of attempts. Time to establish a new connection. Failed user requests. Queue growth. Queue drain time. Full application recovery. The real success metric isn't merely: "Can I connect to the database again?" It's: "How quickly can the application return to normal service without compromising correctness?" 16. Write a Defensible Post-Incident Report A strong post-incident report separates facts, inferences, and unknowns. Confirmed facts Examples: Client connection failures were recorded during a specific UTC interval. Successful connections later resumed. Certain client instances continued failing after initial connectivity returned. Application backlog persisted beyond the connectivity event. Retry activity increased during recovery. Supported inference Example: Aggressive retry behavior likely contributed to slower application recovery. Use this classification only when application telemetry supports the relationship. Unknowns Examples: The exact internal platform operation responsible for a transient event. Whether an unrelated network event contributed. Whether a capacity change affected recovery. Don't fill gaps in telemetry with assumptions. 17. A Practical Decision Tree When an application reports an Azure SQL connectivity incident: 1. Is the database reachable now? No Check current Azure status and application connectivity. Validate networking, DNS, firewall, authentication, and Azure SQL availability. Yes Continue reconstructing the historical incident. 2. Did Azure SQL record connection failures? Yes Correlate: sys.event_log. sys.database_connection_stats. Application timestamps. Azure monitoring evidence. No or evidence isn't yet available Continue investigating application and network telemetry. Remember that historical connectivity data can arrive later. 3. Did the application retry? No Implement a bounded transient-fault handling strategy. Yes Evaluate: Retry count. Delay. Backoff. Jitter. Error classification. 4. Did many instances retry simultaneously? Yes Investigate: Retry synchronization. Circuit breaking. Back-pressure. Queue recovery. Connection pools. 5. Were writes or transactions interrupted? Yes Validate: Transaction outcome. Idempotency. Duplicate prevention. Whole-transaction retry behavior. 6. Did the application remain unhealthy after connections succeeded? Yes Measure application recovery separately from the original database connectivity event. Final Takeaway The hardest part of a transient Azure SQL event isn't always the interruption itself. Sometimes it's the application's response. A resilient architecture recognizes three separate timelines: Connectivity interruption Database/connectivity recovery Application recovery Azure SQL Database is designed as a cloud service where applications should expect and tolerate transient connectivity conditions. Microsoft recommends implementing retry logic rather than exposing appropriate transient failures directly to users. But resilient retry logic must be: Bounded. Delayed. Appropriately randomized. Error-aware. Transaction-aware. Idempotency-aware. Observable. And post-incident analysis should distinguish: What is confirmed. What is inferred. What remains unknown. Because: A brief database disconnect doesn't have to become a prolonged application outage. The objective isn't to design an application that never experiences a disconnected connection. The objective is to design an application that absorbs the interruption, recovers safely, and returns to normal operation predictably. Further reading Working with Transient Errors in Azure SQL Database Troubleshoot Common Connection Issues in Azure SQL Configure Retry Logic in Microsoft.Data.SqlClient Azure SQL Database Connectivity Architecture sys.event_log for Azure SQL Database sys.database_connection_stats for Azure SQL Database196Views0likes0CommentsSystem Windows Ram Problem Fix
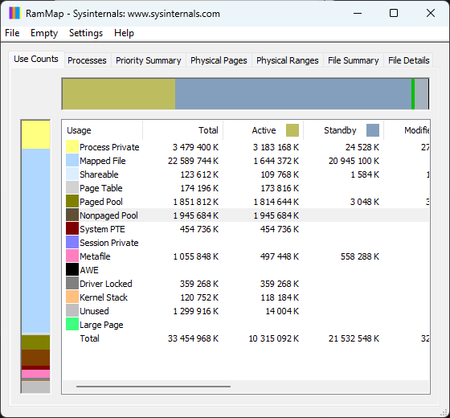
You’ve probably seen this happen — you leave your desktop or laptop running, and after a while the system starts eating a huge chunk of your RAM, even on modern hardware. Today I’m bringing a fix that removes this issue permanently and gives Windows back the speed, stability, and clean behavior it should have. By disabling two legacy predictive mechanisms (SysMain + Prefetch), the system stops aggressively caching applications, idle RAM usage drops significantly, and micro‑lags disappear. The attached screenshots show the system before and after applying the fix. This solution works on both Windows 10 and Windows 11, and it’s safe, reversible, and the improvement is immediate. System Ram Before: System Ram After: Step‑by‑step guide (Windows 10 / 11 RAM issue fix) Note: This is a safe and fully reversible system tweak. You’re simply disabling two legacy predictive mechanisms that no longer make sense on modern hardware. 1️⃣ Disable the SysMain service Press Win + R Type services.msc → press Enter Find SysMain in the list Double‑click it Set Startup type to Disabled Click Stop if the service is running Confirm with Apply and OK 2️⃣ Disable Prefetch in the Registry Press Win + R Type regedit → press Enter Navigate to: HKEY_LOCAL_MACHINE\SYSTEM\CurrentControlSet\Control\Session Manager\Memory Management\PrefetchParameters Find the value EnablePrefetcher Double‑click it and set the value to: 0 Confirm with OK 3️⃣ Restart your system After rebooting, your RAM usage in idle should drop noticeably, and the system will feel cleaner, faster, and more responsive. 4️⃣ How to revert (optional) If you ever want to undo the changes: SysMain: set Startup type back to Automatic and start the service EnablePrefetcher: set the value back to 3 (default) With my regular applications open, RAM usage dropped from 60–70% to just 33%. This is how Windows should have behaved from the beginning. On top of that, overall system responsiveness improved by roughly 50% — even weaker hardware feels noticeably faster almost immediately. This RAM regression has been around since Windows 7. After the kernel overhaul in Windows 8.1 it actually got worse, and it has followed every version of Windows all the way to today. RAM stability after - optimization results: RAM stability after 21 hours uptime – optimization results | Microsoft Community Hub3KViews0likes3CommentsEngineering Agentic Recall Controls with MCP and Microsoft Foundry
AI agents become operationally interesting when they can reach real systems. They also become operationally dangerous at exactly the same moment. Caldova Recall Control Tower is a developer demonstration built around that tension. It uses a fictional pharmaceutical recall to show how an agent can gather evidence and prepare a decision while deterministic application code retains authority over approval and inventory mutation. The implementation combines the Model Context Protocol (MCP), Microsoft Agent Framework, a Microsoft Foundry Hosted Agent, FastAPI, Microsoft Entra authentication, managed identity, and optimistic concurrency in Azure Blob Storage. Central design rule: Let the model interpret and recommend. Make ordinary code authenticate, authorize, mutate, and prove what happened. Caldova is fictional, all operational data is synthetic, and this sample is not a production recall system or a source of clinical advice. The scenario: useful reasoning, consequential action The demo starts with a temperature excursion affecting batch B-2408-AX7 of Caldova Relief 20 mg tablets. The synthetic inventory contains 2,196 units across two distribution centers and two retail stores. A useful system must establish the notice, locate every affected position, check supplier status, explain uncertainty, and recommend an action. That analysis is a good fit for specialized agents. Quarantining inventory is not. Quarantine changes operational state. It therefore needs an authenticated human, explicit authorization, a batch-scoped approval, concurrency control, idempotency, and an audit record. None of those guarantees should depend on a prompt being followed. The authenticated hosted application at the start of the fictional recall. Architecture: separate reasoning from authority The solution has two related but deliberately separate paths. Caldova separates model reasoning from application authority. Official Microsoft service icons identify Foundry Agent Service, App Service, Managed Identity, and Blob Storage. The reasoning path invokes a Hosted Agent through the Responses protocol. Four agents run in a fixed sequence: triage, inventory impact, supplier/compliance, and supervisor. The first three have narrow read-only tools. The supervisor has no tools and synthesizes the accumulated context into a decision brief. The authority path remains in the web application. It validates the EasyAuth identity claims, checks an approver allowlist, binds approval to the caller, batch, action, and current demo generation, and only then calls deterministic domain code. State is stored per actor in Blob Storage and updated with ETag match conditions so concurrent writes fail instead of silently overwriting each other. There is also a deterministic localhost demo. It reuses synthetic domain fixtures and demonstrates MCP contracts, approval, quarantine, and replay without a model or cloud account. It is useful for development, but its typed approver name and in-memory state are not production identity or durable compliance evidence. Building a narrow MCP surface MCP standardizes how an AI application discovers and calls external tools. It does not remove the need to design those tools carefully. Caldova exposes small, typed operations such as get_recall_notice , locate_inventory , and get_supplier_status . Inputs are constrained with Pydantic, and tool annotations tell clients that these operations are read-only and closed-world: @mcp.tool( title="Locate affected inventory", annotations=ToolAnnotations( read_only_hint=True, open_world_hint=False, ), ) def locate_inventory(batch_id: BatchId) -> dict[str, Any]: return STORE.locate_inventory(batch_id) The mutation tool is separately marked destructive and requires a batch-scoped approval token. Those annotations improve discovery and planning, but they are metadata, not an authorization boundary. The real check occurs inside quarantine_batch , below the model and below the tool description. The Hosted Agent does not receive the mutation tools at all. Its specialists call only three read operations through an isolated MCP stdio subprocess. This is stronger than asking an all-powerful agent to "please remain read-only": capability is constrained by construction. The subprocess boundary also keeps MCP v2 dependencies isolated from the Foundry hosting environment. Each call has a timeout, bounded concurrency, structured JSON handling, and a generic failure response that does not leak subprocess details. Fixed workflows beat vague autonomy for this case Multi-agent does not have to mean dynamic routing. Caldova uses an explicit sequence because the business dependency is explicit: validate the notice before locating inventory, locate inventory before checking supplier implications, and synthesize only after all three specialist outputs exist. return ( WorkflowBuilder(start_executor=triage, output_from=[supervisor]) .add_edge(triage, inventory) .add_edge(inventory, compliance) .add_edge(compliance, supervisor) .build() .as_agent() ) This topology is easier to test and reason about than an unconstrained planner. Each specialist has one job and one tool allowlist. Full context is passed where synthesis requires it, while the supervisor remains tool-free. Request isolation matters too. A hosted process can serve concurrent users, so workflow state must not leak between requests. The sample creates a fresh workflow agent for each request context rather than reusing mutable agent state globally. What the live hosted run showed The hosted application completed a read-only assessment for the synthetic batch. The resulting brief reported: 2,196 affected units across four locations. A high-risk inbound temperature excursion. Supplier acknowledgement, a 36-hour replacement estimate, and a drafted credit note. Unknown transit temperature details, excursion duration, stability impact, final supplier disposition, and potentially issued stock. A recommendation to hold or quarantine stock, explicitly stating that no quarantine had occurred. A required human approval before any inventory restriction. The live Hosted Agent decision brief. Transient response and correlation identifiers are masked; the operations rail is excluded because it contains actor-scoped audit data. The screenshot also shows an important truthfulness choice: the UI says Hosted workflow trace unavailable. The application does not invent stage completion or tool-call evidence when the hosted endpoint does not return trustworthy trace data. The answer can be displayed, but it must not be presented as proof of an internal execution path. Approval is a protocol, not a button The hosted web path uses App Service authentication with Microsoft Entra. The application accepts the injected principal only on the configured App Service host, validates tenant and object identifiers, applies a user allowlist, and performs an additional approver check for mutation requests. State-changing calls also require the expected origin and an application request header. Approval is then bound to five facts: The authenticated actor. The current demo generation. The affected batch. The quarantine action. A ten-minute validity window until first use. Resetting the demo creates a new generation, invalidating old handles. Consuming an approval does not make replay unsafe: the same bound handle can repeat the same quarantine operation, but domain code changes only positions that are not already quarantined. A second call reports an idempotent replay with zero additional positions changed. This is the difference between a human-in-the-loop interface and a human-authorized system. A modal dialog provides user experience; identity binding and deterministic policy provide control. Durable state needs concurrency semantics The hosted application stores each actor's synthetic session in a separate Blob object. A load returns both JSON state and its ETag. A save uses IfNotModified semantics; if another request updated the same state first, Azure Storage rejects the stale write and the API returns a conflict. conditions = ( {"etag": etag, "match_condition": MatchConditions.IfNotModified} if etag else {} ) await blob.upload_blob( json.dumps(state), overwrite=etag is not None, **conditions, ) Without that condition, two browser requests could both read the same approval state and overwrite one another using last-writer-wins behavior. Agent systems do not get a concurrency exemption: ordinary distributed-systems rules still apply. Fail closed, and make the failure legible The analysis adapter accepts only HTTPS Foundry endpoints with the expected path, uses a managed-identity token for https://ai.azure.com/.default , disables redirects, and enforces bounded connect and overall timeouts. It accepts only a completed assistant response with non-empty output text. If the endpoint times out, returns partial output, returns malformed data, or becomes unavailable, the application clears the analysis lease and reports that no inventory changed. It does not substitute a local answer and label it as hosted. Approval remains locked until a new hosted analysis succeeds. This can feel strict during a demo, but it protects provenance. A degraded fallback is useful only when the UI and audit model can identify it accurately. What is proven, and what is not The sample provides useful evidence for several engineering claims: Typed MCP tools reject malformed input. Hosted specialists receive read-only capabilities only. Approval is checked below the model and bound to identity and session state. Quarantine is idempotent in the synthetic domain. Blob ETags prevent stale session writes. Empty, partial, failed, and timed-out hosted responses fail closed. Local tests cover domain, MCP, workflow, API, and repository-hygiene behavior. It does not prove that the sample is a production recall platform. The scenario is synthetic. The local audit log is not tamper-evident. The hosted UI currently lacks trustworthy per-stage and per-tool trace rendering. Deployment-specific RBAC, EasyAuth configuration, telemetry access, model behavior, load characteristics, costs, and recovery procedures require validation in each environment. Evaluation evidence also expires. Golden cases and evaluator configuration are useful assets, but historical results are not a current release certificate. Re-run evaluations against the deployed agent version and inspect failures before making quality claims. Try the pattern Start with the deterministic path before provisioning cloud resources: Set-Location (git rev-parse --show-toplevel) py -3.13 -m venv caldova-recall-control/.venv ./caldova-recall-control/.venv/Scripts/python.exe -m pip install ` -r caldova-recall-control/requirements-ui.txt ./caldova-recall-control/.venv/Scripts/python.exe -m uvicorn ` control_tower_api:app ` --app-dir caldova-recall-control/src ` --host 127.0.0.1 ` --port 8091 Then inspect the MCP server over stdio: ./caldova-recall-control/.venv/Scripts/python.exe ` caldova-recall-control/scripts/inspect_mcp.py The inspector discovers the real tool schemas, reads the synthetic inventory, rejects malformed input and an unapproved mutation, and confirms the stock remains unchanged. Only after that local contract is understood should you configure a Foundry project, deployment identity, model deployment, and Hosted Agent. Engineering takeaways The most reusable lesson in Caldova is not the number of agents. It is the placement of authority. Give each model the smallest useful toolset. Prefer explicit workflow topology when the business process is known. Treat tool annotations as descriptive metadata, not access control. Bind consequential approval to authenticated identity, resource, action, and session generation. Put mutation and idempotency in deterministic domain code. Use optimistic concurrency for durable web state. Preserve provenance by failing closed instead of silently changing execution paths. Show only evidence the system actually captured. Agents are excellent at turning fragmented evidence into an actionable brief. Reliable systems make sure the brief and the action remain two different things. References Caldova source repository Model Context Protocol introduction Microsoft Agent Framework workflow capabilities Deploy a Hosted Agent in Microsoft Foundry Configure Microsoft Entra authentication for Azure App Service Manage concurrency in Azure Blob StorageGeneric Best Practices for HikariCP with Azure Database for PostgreSQL
Author: Mohamed Baioumy Technology: Azure Database for PostgreSQL (Flexible Server & Single Server) Category: Connectivity | Performance | Application Design Introduction Connection pooling is a critical component of application performance when connecting to Azure Database for PostgreSQL. Creating a new PostgreSQL connection is an expensive operation that consumes CPU, memory, and networking resources. Reusing existing connections through a connection pool significantly reduces connection latency, improves throughput, and helps applications scale more efficiently. Many Java applications use HikariCP, one of the most popular high-performance JDBC connection pools. While HikariCP provides excellent performance out of the box, improperly configured connection pool settings can lead to issues such as: Connection pool exhaustion Stale or invalid connections Increased connection acquisition latency Excessive connection creation and destruction Database resource contention Application timeouts This article summarizes generic guidance and best practices for configuring HikariCP when working with Azure Database for PostgreSQL Flexible Server and Azure Database for PostgreSQL Single Server. Understanding Key HikariCP Parameters 1. Maximum Lifetime (maxLifetime) The maxLifetime property controls how long a connection can remain in the pool before HikariCP retires it and creates a new one. Why It Matters Connections can become stale over time due to: Network interruptions Infrastructure updates Connection state changes TCP idle behavior Recycling connections periodically helps prevent applications from using long-lived connections that may no longer be healthy. Recommended Practice Avoid configuring the value too low. When maxLifetime is set aggressively, HikariCP continuously destroys and recreates connections, resulting in: Additional authentication overhead Increased connection establishment latency Higher CPU utilization Reduced application throughput A reasonable starting point is: spring.datasource.hikari.maxLifetime=1800000 30 minutes (1,800,000 ms) is commonly used and aligns well with many production workloads. Depending on workload characteristics, values between 30 minutes and 1 hour are generally suitable Avoid maxLifetime=300000 (5 minutes) This often causes unnecessary connection churn without providing additional benefits. 2. Minimum Idle Connections (minimumIdle) The minimumIdle setting defines how many idle connections HikariCP should keep ready for immediate use. Why It Matters A pool with available idle connections can serve application requests immediately without waiting for new connections to be established. However, maintaining too many idle connections consumes unnecessary database resources. Recommended Practice For most workloads: minimumIdle = maximumPoolSize Or minimumIdle slightly lower than maximumPoolSize This ensures sufficient connections are already available during traffic spikes while avoiding excessive connection creation delays. Example maximumPoolSize=20 minimumIdle=15 Avoid maximumPoolSize=20 minimumIdle=20 only when the application experiences long periods of inactivity and conserving resources is more important than immediate responsiveness. 3. Idle Timeout (idleTimeout) The idleTimeout property determines how long an unused connection remains in the pool before being removed. Why It Matters Connections that sit idle for extended periods consume resources on both: The application server Azure Database for PostgreSQL However, removing idle connections too quickly causes the application to repeatedly establish new connections. Recommended Practice Keep the default value unless there is a specific requirement. spring.datasource.hikari.idleTimeout=600000 which equals: 10 minutes (600,000 ms) This setting provides a good balance between resource utilization and responsiveness. [Re: EXT: R...0040002947 | Outlook] The timeout should also be comfortably longer than any expected short application idle periods. Avoid idleTimeout=10000 (10 seconds) Such aggressive settings often result in unnecessary connection creation cycles. 4. Maximum Pool Size (maximumPoolSize) This parameter determines the maximum number of concurrent database connections the application can maintain. Why It Matters This is often the most important HikariCP setting. If the Pool Is Too Small Applications may experience: Connection is not available, request timed out because all available connections are already in use. Similar scenarios have been observed during customer investigations involving Hikari pool exhaustion. If the Pool Is Too Large Applications can overwhelm the database server with excessive concurrent sessions, resulting in: Connection contention Increased context switching Higher memory consumption Reduced overall performance Recommended Practice Pool size should be based on: Database compute configuration CPU core count Query execution duration Application concurrency requirements Workload characteristics There is no universal value that fits every workload. Start conservatively: maximumPoolSize=10 or maximumPoolSize=20 maximumPoolSize=20 and increase only after load testing demonstrates a need for additional concurrency. Fixed-Size Pool Recommendation For many production workloads, a fixed-size pool provides the simplest and most predictable behavior. Configure: maximumPoolSize=20 minimumIdle=20 or omit minimumIdle entirely so it defaults to maximumPoolSize. HikariCP commonly recommends maintaining a fixed-size pool for responsiveness during demand spikes. Benefits Faster connection acquisition Predictable performance Reduced connection creation latency Better handling of traffic spikes When using a small fixed-size pool, there is often little need to aggressively tune: minimumIdle idleTimeout Instead, simply recycle connections using: maxLifetime maxLifetime Additional Recommendations Enable TCP Keepalive One common cause of stale connections is network devices silently dropping inactive TCP sessions. For PostgreSQL applications, consider enabling TCP keepalive: tcpKeepAlive=true tcpKeepAlive=true The HikariCP project specifically recommends enabling TCP keepalive to prevent rare situations where pools can lose valid connections. Monitor Connection Usage Track: Active connections Idle connections Connection acquisition time Pool exhaustion events Database connection counts These metrics help identify whether pool sizing is appropriate. Investigate Long-Running Queries Connection pool problems are often symptoms rather than root causes. A frequent scenario is: A query becomes slow. Connections remain occupied longer. The pool becomes exhausted. Applications start timing out. When analyzing HikariCP issues, always review: Query performance Blocking situations Database resource utilization Application connection handling logic Sample Production Configuration spring.datasource.hikari.maximumPoolSize=20 spring.datasource.hikari.minimumIdle=15 spring.datasource.hikari.maxLifetime=1800000 spring.datasource.hikari.idleTimeout=600000 spring.datasource.hikari.connectionTimeout=30000 spring.datasource.hikari.keepaliveTime=60000 spring.datasource.hikari.maximumPoolSize=20 spring.datasource.hikari.minimumIdle=15 spring.datasource.hikari.maxLifetime=1800000 spring.datasource.hikari.idleTimeout=600000 spring.datasource.hikari.connectionTimeout=30000 spring.datasource.hikari.keepaliveTime=60000 This configuration provides a solid starting point for many Azure Database for PostgreSQL workloads and can be adjusted based on application-specific requirements. a { text-decoration: none; color: #464feb; } tr th, tr td { border: 1px solid #e6e6e6; } tr th { background-color: #f5f5f5; } Conclusion HikariCP is extremely efficient when configured appropriately. The goal is not to maximize the number of connections, but rather to maintain a healthy balance between application responsiveness and database resource consumption. As a general rule: Use a reasonable maxLifetime (30–60 minutes) Keep enough idle connections available for traffic spikes Avoid aggressive idleTimeout values Size the pool based on workload characteristics, not guesses Consider fixed-size pools for predictable performance Monitor connection usage and query performance regularly By following these practices, applications connecting to Azure Database for PostgreSQL can achieve improved scalability, lower latency, and more reliable connectivity. References Connection pooling best practices - Azure Database for PostgreSQL Performance best practices for using Azure Database for PostgreSQL – Connection Pooling HikariCP Documentation and Pool Sizing GuidanceLessons Learned #540:Bulk Insert Throughput in Azure SQL Hyperscale with Partitioned Heap Tables
In this lesson learned, I would like to share an interesting scenario working on a service request where our customer was running a high-volume data load process in Azure SQL Database Hyperscale. The workload was based on a common pattern: Recreate a staging table. Load a large number of rows using bulk insert. The bulk insert showed unstable execution times and became the main area to investigate. The process was loading a very large number of rows into an Azure SQL Database Hyperscale database. The process used a staging table that was initially loaded as a heap. The main concern was the inconsistent execution time during the load process. Why Manually Adding Data Files Was Not the Right Direction In Azure SQL Database Hyperscale, the storage architecture is different from a traditional SQL Server deployment. The data layout and storage management are handled internally by the service. Because of this architecture, manually creating or pre-allocating multiple data files is not the same tuning option that we may consider in SQL Server on-premises or SQL Server running on Azure Virtual Machines. For this reason, the troubleshooting focus moved from manual file layout configuration to the actual workload pattern, waits, concurrency, batch size, and staging table design. What We Observed During the bulk insert phase, waits such as PAGELATCH_EX were observed. Since the staging table was loaded as a heap and the clustered primary key was created only after the bulk insert completed, OPTIMIZE_FOR_SEQUENTIAL_KEY was not directly applicable to the bulk insert phase. This changed the direction of the investigation. Instead of focusing on last-page insert contention on an existing clustered index, the analysis moved toward heap insert behavior, allocation contention, concurrency, batch size, and whether a different staging table design could help. First Recommendation: Start with Low-Impact Changes Before changing the table design, the first recommendation was to test the least intrusive changes: Reduce the number of concurrent bulk insert sessions. Increase the batch size, for example from 10,000 rows to 50,000 or 100,000 rows. Test TABLOCK on the dedicated heap staging table. The goal was to avoid assuming that more concurrency would always reduce the total execution time. In some high-volume load scenarios, excessive concurrency may increase contention and make the process less stable. The Interesting Design Option: Partitioned Heap Staging Table One of the most interesting design options was to evaluate a partitioned heap staging table. The idea is simple: instead of loading all rows into a non-partitioned heap staging table, the staging table can be created on the same partition scheme used by the target table, using the same partitioning column. This does not mean that a partitioned heap will always be faster. However, it can be a useful design option when: The bulk load phase is affected by allocation or latch contention. Concurrent load processes can naturally distribute rows across different partition ranges. The staging table is used only as an intermediate structure.Lessons Learned The main lessons from this scenario were: In Azure SQL Database Hyperscale, manually managing multiple data files is not the right tuning direction. PAGELATCH_EX during heap loading may point to concurrency or allocation-related contention. Reducing concurrency can sometimes improve total throughput. Larger batch sizes may provide better results than many small batches. TABLOCK on a dedicated heap staging table is a low-impact test worth evaluating. A partitioned heap staging table can be a valid second-phase design option when the load can be distributed across partition ranges. The best approach is to test small, measurable changes before introducing architectural redesigns. Final Thoughts A partitioned heap staging table can be a powerful option, but only when it is tested carefully and when the workload pattern can benefit from partition distribution.285Views0likes0CommentsDistributing Agents to Microsoft Teams and Microsoft 365 Copilot Part 4/5
This is the fourth post in our series on the Microsoft agent platform. We cover the Distribute in M365 pillar — publishing your agents to Microsoft Teams and Microsoft 365 Copilot so they reach users where they already work. All examples reference the FibreOps repository, demonstrated at Microsoft Build BRK241. The Distribution Story Building a great agent is only half the challenge. The other half is getting it into the hands of users without asking them to learn a new tool, visit a new URL, or change their workflow. Microsoft 365 Copilot and Microsoft Teams are where enterprise users already spend their day, making them the natural distribution surface for agents. With the GA release, publishing an agent to Teams and M365 Copilot is a single command. No separate app registration portal, no manual manifest assembly, no multi-step approval workflow for development and testing. Publishing to Microsoft 365 Copilot (GA) FibreOps ships as a declarative agent + action plugin ready for sideload. A single CLI command produces the complete package: python -m fibreops.demo publish-m365 --out dist/m365 # Output: # ✓ wrote dist/m365/declarativeAgent.json # ✓ wrote dist/m365/fibreops-action.json # ✓ wrote dist/m365/manifest.json # ✓ wrote dist/m365/color.png (192x192) # ✓ wrote dist/m365/outline.png ( 32x32) # ✓ wrote dist/m365/fibreops-copilot.zip What Gets Generated File Purpose declarativeAgent.json Defines the agent's persona, capabilities, and conversation starters for M365 Copilot fibreops-action.json Action plugin that proxies tool calls to the deployed FastAPI backend via OpenAPI manifest.json Teams app manifest with publisher metadata, permissions, and capabilities color.png / outline.png App icons for Teams and M365 surfaces fibreops-copilot.zip Ready-to-upload package for Teams Admin Center Configuration Set the base URL to your deployed FastAPI app before publishing — the action plugin uses this to resolve the OpenAPI runtime: # Set the public HTTPS hostname of the deployed FastAPI app $env:M365_ACTION_BASE_URL = "https://fibreops-demo.azurewebsites.net" # Optional: customise publisher metadata $env:M365_PUBLISHER_NAME = "Contoso Network Operations" $env:M365_PUBLISHER_WEBSITE = "https://contoso.com/noc" # Generate the package python -m fibreops.demo publish-m365 --out dist/m365 Environment Variable Purpose M365_ACTION_BASE_URL Public HTTPS root for the FastAPI /openapi.json (e.g., Container Apps FQDN) M365_APP_ID Override the generated Teams app GUID (default: deterministic per repo) M365_PUBLISHER_NAME Publisher name shown in M365 Admin Center M365_PUBLISHER_WEBSITE Publisher website link Uploading the Package Upload the generated fibreops-copilot.zip through either path: Teams Admin Center → Manage apps → Upload new app M365 Admin Center → Integrated apps → Upload custom apps Once uploaded, the declarative agent: Inherits the publisher metadata you configured Advertises conversation starters from the FibreOps deck (e.g., "What is the current outage status?", "Dispatch an engineer to FN-LDN-001") Proxies tool calls to the deployed FastAPI app via the action plugin Appears in Microsoft 365 Copilot as a specialised agent users can invoke How Declarative Agents Work A declarative agent in Microsoft 365 Copilot is defined by metadata rather than code running in the M365 surface. The intelligence lives in your backend — Copilot handles the conversational UX, tool orchestration schema, and user authentication. The flow: User invokes the agent in Microsoft 365 Copilot or Teams Copilot renders conversation starters and accepts natural language input When the agent needs to act, Copilot calls the action plugin (your OpenAPI endpoint) Your FastAPI backend processes the request using the full agent pipeline Results return to the user in the Copilot/Teams UX This architecture means your agent logic stays in one place — the backend. The M365 surface is purely a distribution and interaction layer. Action Plugins and OpenAPI The action plugin ( fibreops-action.json ) references your FastAPI app's /openapi.json endpoint. FibreOps exposes a JSON API that the action plugin can call: /api/runs — List and query agent runs /api/optimiser — Get optimizer scores and suggestions /sdk/chat — Natural language interaction with the agent system /healthz — Liveness probe Because FastAPI auto-generates OpenAPI schemas from your typed Python endpoints, the action plugin gets accurate parameter descriptions, response schemas, and error codes without any manual specification work. Publishing as Autopilots (Public Preview) Autopilots take distribution one step further — agents that operate autonomously without requiring a user to initiate each interaction. An Autopilot can: React to events (e.g., a critical telemetry signal) without human initiation Take actions within defined guardrails Notify users only when human intervention is needed Operate continuously across Microsoft 365 surfaces For FibreOps, an Autopilot would monitor the Event Hub stream continuously and only surface to the NOC team when an incident exceeds automated resolution capability — a fully autonomous operations agent. Teams Adaptive Cards FibreOps posts rich Adaptive Card notifications to Microsoft Teams throughout the agent pipeline. This is separate from the declarative agent — it is a push notification channel for real-time operational awareness. # The NetOps agent posts an outage notice via Incoming Webhook def post_outage_notice(incident_id, node_id, severity, summary, engineer=None): card = { "type": "AdaptiveCard", "body": [ {"type": "TextBlock", "text": f"🚨 Outage: {node_id}", "weight": "Bolder", "size": "Large"}, {"type": "FactSet", "facts": [ {"title": "Severity", "value": severity.upper()}, {"title": "Incident", "value": incident_id}, {"title": "Summary", "value": summary}, ]}, ], "actions": [ {"type": "Action.OpenUrl", "title": "View in NOC Console", "url": f"{base_url}/runs/{incident_id}"} ] } # POST to Teams webhook or append to outbox for offline mode ... If TEAMS_WEBHOOK_URL is not configured, cards are appended to state/teams_outbox.jsonl for review in the NOC console's Teams panel. End-to-End: From Code to Copilot Here is the complete flow from development to distribution: Build — Develop agents with Microsoft Agent Framework, test locally with python -m fibreops.demo --backend local Publish agents — python -m fibreops.demo publish creates hosted Prompt Agents in Foundry Deploy infrastructure — azd up provisions App Service, ACR, Event Hub, Key Vault, and Application Insights Deploy hosted agent — azd env set FIBREOPS_DEPLOY_HOSTED true && azd up Generate M365 package — python -m fibreops.demo publish-m365 --out dist/m365 Upload to Teams — Upload fibreops-copilot.zip via Teams Admin Center Users interact — The agent is now available in Microsoft 365 Copilot and Teams Security Considerations Managed Identity — The deployed app uses system-assigned managed identity for all Azure service access. No secrets in code. Least privilege — Each role grant is scoped to the minimum required (Event Hubs Data Owner, Key Vault Secrets User, AcrPull, Azure AI Developer). Authentication — The M365 Copilot surface handles user authentication; your backend receives authenticated requests. Guardrails — Autopilots operate within defined boundaries; human-in-the-loop escalation is built into the Routine and agent decision logic. Key Takeaways Publishing to Teams and M365 Copilot is GA — a single command generates the complete package. Declarative agents separate distribution (M365) from intelligence (your backend). Action plugins leverage your existing FastAPI OpenAPI schema — no manual specification needed. Autopilots (Public Preview) enable fully autonomous operation within guardrails. Adaptive Cards provide real-time push notifications alongside the conversational agent surface. The same backend serves the NOC console, the Copilot SDK, and the M365 declarative agent. Next Steps Explore the FibreOps repository — try python -m fibreops.demo publish-m365 Microsoft 365 Copilot extensibility documentation Next in this series: Voice Live and Observability for Production Agent SystemsBuilding HIPAA-Compliant Medical Transcription with Local AI
Building HIPAA-Compliant Medical Transcription with Local AI Introduction Healthcare organizations generate vast amounts of spoken content, patient consultations, research interviews, clinical notes, medical conferences. Transcribing these recordings traditionally requires either manual typing (time-consuming and expensive) or cloud transcription services (creating immediate HIPAA compliance concerns). Every audio file sent to external APIs exposes Protected Health Information (PHI), requires Business Associate Agreements, creates audit trails on third-party servers, and introduces potential breach vectors. This sample solution lies in on-premises voice-to-text systems that process audio entirely locally, never sending PHI beyond organizational boundaries. This article demonstrates building a sample medical transcription application using FLWhisper, ASP.NET Core, C#, and Microsoft Foundry Local with OpenAI Whisper models. You'll learn how to build sample HIPAA-compliant audio processing, integrate Whisper models for medical terminology accuracy, design privacy-first API patterns, and build responsive web UIs for healthcare workflows. Whether you're developing electronic health record (EHR) integrations, building clinical research platforms, or implementing dictation systems for medical practices, this sample could be a great starting point for privacy-first speech recognition. Why Local Transcription Is Critical for Healthcare Healthcare data handling is fundamentally different from general business data due to HIPAA regulations, state privacy laws, and professional ethics obligations. Understanding these requirements explains why cloud transcription services, despite their convenience, create unacceptable risks for medical applications. HIPAA compliance mandates strict controls over PHI. Every system that touches patient data must implement administrative, physical, and technical safeguards. Cloud transcription APIs require Business Associate Agreements (BAAs), but even with paperwork, you're entrusting PHI to external systems. Every API call creates logs on vendor servers, potentially in multiple jurisdictions. Data breaches at transcription vendors expose patient information, creating liability for healthcare organizations. On-premises processing eliminates these third-party risks entirely, PHI never leaves your controlled environment. US State laws increasingly add requirements beyond HIPAA. California's CCPA, New York's SHIELD Act, and similar legislation create additional compliance obligations. International regulations like GDPR prohibit transferring health data outside approved jurisdictions. Local processing simplifies compliance by keeping data within organizational boundaries. Research applications face even stricter requirements. Institutional Review Boards (IRBs) often require explicit consent for data sharing with external parties. Cloud transcription may violate study protocols that promise "no third-party data sharing." Clinical trials in pharmaceutical development handle proprietary information alongside PHI, double jeopardy for data exposure. Local transcription maintains research integrity while enabling audio analysis. Cost considerations favor local deployment at scale. Medical organizations generate substantial audio, thousands of patient encounters monthly. Cloud APIs charge per minute of audio, creating significant recurring costs. Local models have fixed infrastructure costs that scale economically. A modest GPU server can process hundreds of hours monthly at predictable expense. Latency matters for clinical workflows. Doctors and nurses need transcriptions available immediately after patient encounters to review and edit while details are fresh. Cloud APIs introduce network delays, especially problematic in rural health facilities with limited connectivity. Local inference provides <1 second turnaround for typical consultation lengths. Application Architecture: ASP.NET Core with Foundry Local The sample FLWhisper application implements clean separation between audio handling, AI inference, and state management using modern .NET patterns: The ASP.NET Core 10 minimal API provides HTTP endpoints for health checks, audio transcription, and sample file streaming. Minimal APIs reduce boilerplate while maintaining full middleware support for error handling, authentication, and CORS. The API design follows OpenAI's transcription endpoint specification, enabling drop-in replacement for existing integrations. The service layer encapsulates business logic: FoundryModelService manages model loading and lifetime, TranscriptionService handles audio processing and AI inference, and SampleAudioService provides demonstration files for testing. This separation enables easy testing, dependency injection, and service swapping. Foundry Local integration uses the Microsoft.AI.Foundry.Local.WinML SDK. Unlike cloud APIs requiring authentication and network calls, this SDK communicates directly with the local Foundry service via in-process calls. Models load once at startup, remaining resident in memory for sub-second inference on subsequent requests. The static file frontend delivers vanilla HTML/CSS/JavaScript, no framework overhead. This simplicity aids healthcare IT security audits and enables deployment on locked-down hospital networks. The UI provides file upload, sample selection, audio preview, transcription requests, and result display with copy-to-clipboard functionality. Here's the architectural flow for transcription requests: Web UI (Upload Audio File) ↓ POST /v1/audio/transcriptions (Multipart Form Data) ↓ ASP.NET Core API Route ↓ TranscriptionService.TranscribeAudio(audioStream) ↓ Foundry Local Model (Whisper Medium locally) ↓ Text Result + Metadata (language, duration) ↓ Return JSON/Text Response ↓ Display in UI This architecture embodies several healthcare system design principles: Data never leaves the device: All processing occurs on-premises, no external API calls No data persistence by default: Audio and transcripts are session-only, never saved unless explicitly configured Comprehensive health checks: System readiness verification before accepting PHI Audit logging support: Structured logging for compliance documentation Graceful degradation: Clear error messages when models unavailable rather than silent failures Setting Up Foundry Local with Whisper Models Foundry Local supports multiple Whisper model sizes, each with different accuracy/speed tradeoffs. For medical transcription, accuracy is paramount—misheard drug names or dosages create patient safety risks: # Install Foundry Local (Windows) winget install Microsoft.FoundryLocal # Verify installation foundry --version # Download Whisper Medium model (optimal for medical accuracy) foundry model add openai-whisper-medium-generic-cpu:1 # Check model availability foundry model list Whisper Medium (769M parameters) provides the best balance for medical use. Smaller models (Tiny, Base) miss medical terminology frequently. Larger models (Large) offer marginal accuracy gains at 3x inference time. Medium handles medical vocabulary well, drug names, anatomical terms, procedure names, while processing typical consultation audio (5-10 minutes) in under 30 seconds. The application detects and loads the model automatically: // Services/FoundryModelService.cs using Microsoft.AI.Foundry.Local.WinML; public class FoundryModelService { private readonly ILogger _logger; private readonly FoundryOptions _options; private ILocalAIModel? _loadedModel; public FoundryModelService( ILogger logger, IOptions options) { _logger = logger; _options = options.Value; } public async Task InitializeModelAsync() { try { _logger.LogInformation( "Loading Foundry model: {ModelAlias}", _options.ModelAlias ); // Load model from Foundry Local _loadedModel = await FoundryClient.LoadModelAsync( modelAlias: _options.ModelAlias, cancellationToken: CancellationToken.None ); if (_loadedModel == null) { _logger.LogWarning("Model loaded but returned null instance"); return false; } _logger.LogInformation( "Successfully loaded model: {ModelAlias}", _options.ModelAlias ); return true; } catch (Exception ex) { _logger.LogError( ex, "Failed to load Foundry model: {ModelAlias}", _options.ModelAlias ); return false; } } public ILocalAIModel? GetLoadedModel() => _loadedModel; public async Task UnloadModelAsync() { if (_loadedModel != null) { await FoundryClient.UnloadModelAsync(_loadedModel); _loadedModel = null; _logger.LogInformation("Model unloaded"); } } } Configuration lives in appsettings.json , enabling easy customization without code changes: { "Foundry": { "ModelAlias": "whisper-medium", "LogLevel": "Information" }, "Transcription": { "MaxAudioDurationSeconds": 300, "SupportedFormats": ["wav", "mp3", "m4a", "flac"], "DefaultLanguage": "en" } } Implementing Privacy-First Transcription Service The transcription service handles audio processing while maintaining strict privacy controls. No audio or transcript persists beyond the HTTP request lifecycle unless explicitly configured: // Services/TranscriptionService.cs public class TranscriptionService { private readonly FoundryModelService _modelService; private readonly ILogger _logger; public async Task TranscribeAudioAsync( Stream audioStream, string originalFileName, TranscriptionOptions? options = null) { options ??= new TranscriptionOptions(); var startTime = DateTime.UtcNow; try { // Validate audio format ValidateAudioFormat(originalFileName); // Get loaded model var model = _modelService.GetLoadedModel(); if (model == null) { throw new InvalidOperationException("Whisper model not loaded"); } // Create temporary file (automatically deleted after transcription) using var tempFile = new TempAudioFile(audioStream); // Execute transcription _logger.LogInformation( "Starting transcription for file: {FileName}", originalFileName ); var transcription = await model.TranscribeAsync( audioFilePath: tempFile.Path, language: options.Language, cancellationToken: CancellationToken.None ); var duration = (DateTime.UtcNow - startTime).TotalSeconds; _logger.LogInformation( "Transcription completed in {Duration:F2}s", duration ); return new TranscriptionResult { Text = transcription.Text, Language = transcription.Language ?? options.Language, Duration = transcription.AudioDuration, ProcessingTimeSeconds = duration, FileName = originalFileName, Timestamp = DateTime.UtcNow }; } catch (Exception ex) { _logger.LogError( ex, "Transcription failed for file: {FileName}", originalFileName ); throw; } } private void ValidateAudioFormat(string fileName) { var extension = Path.GetExtension(fileName).TrimStart('.'); var supportedFormats = new[] { "wav", "mp3", "m4a", "flac", "ogg" }; if (!supportedFormats.Contains(extension.ToLowerInvariant())) { throw new ArgumentException( $"Unsupported audio format: {extension}. " + $"Supported: {string.Join(", ", supportedFormats)}" ); } } } // Temporary file wrapper that auto-deletes internal class TempAudioFile : IDisposable { public string Path { get; } public TempAudioFile(Stream sourceStream) { Path = System.IO.Path.GetTempFileName(); using var fileStream = File.OpenWrite(Path); sourceStream.CopyTo(fileStream); } public void Dispose() { try { if (File.Exists(Path)) { File.Delete(Path); } } catch { // Ignore deletion errors in temp folder } } } This service demonstrates several privacy-first patterns: Temporary file lifecycle management: Audio written to temp storage, automatically deleted after transcription No implicit persistence: Results returned to caller, not saved by service Format validation: Accept only supported audio formats to prevent processing errors Comprehensive logging: Audit trail for compliance without logging PHI content Error isolation: Exceptions contain diagnostic info but no patient data Building the OpenAI-Compatible REST API The API endpoint mirrors OpenAI's transcription API specification, enabling existing integrations to work without modifications: // Program.cs var builder = WebApplication.CreateBuilder(args); // Configure services builder.Services.Configure( builder.Configuration.GetSection("Foundry") ); builder.Services.AddSingleton(); builder.Services.AddScoped(); builder.Services.AddHealthChecks() .AddCheck("foundry-health"); var app = builder.Build(); // Load model at startup var modelService = app.Services.GetRequiredService(); await modelService.InitializeModelAsync(); app.UseHealthChecks("/health"); app.MapHealthChecks("/api/health/status"); // OpenAI-compatible transcription endpoint app.MapPost("/v1/audio/transcriptions", async ( HttpRequest request, TranscriptionService transcriptionService, ILogger logger) => { if (!request.HasFormContentType) { return Results.BadRequest(new { error = "Content-Type must be multipart/form-data" }); } var form = await request.ReadFormAsync(); // Extract audio file var audioFile = form.Files.GetFile("file"); if (audioFile == null || audioFile.Length == 0) { return Results.BadRequest(new { error = "Audio file required in 'file' field" }); } // Parse options var format = form["format"].ToString() ?? "text"; var language = form["language"].ToString() ?? "en"; try { // Process transcription using var stream = audioFile.OpenReadStream(); var result = await transcriptionService.TranscribeAudioAsync( audioStream: stream, originalFileName: audioFile.FileName, options: new TranscriptionOptions { Language = language } ); // Return in requested format if (format == "json") { return Results.Json(new { text = result.Text, language = result.Language, duration = result.Duration }); } else { // Default: plain text return Results.Text(result.Text); } } catch (Exception ex) { logger.LogError(ex, "Transcription request failed"); return Results.StatusCode(500); } }) .DisableAntiforgery() // File uploads need CSRF exemption .WithName("TranscribeAudio") .WithOpenApi(); app.Run(); Example API usage: # PowerShell $audioFile = Get-Item "consultation-recording.wav" $response = Invoke-RestMethod ` -Uri "http://localhost:5192/v1/audio/transcriptions" ` -Method Post ` -Form @{ file = $audioFile; format = "json" } Write-Output $response.text # cURL curl -X POST http://localhost:5192/v1/audio/transcriptions \ -F "file=@consultation-recording.wav" \ -F "format=json" Building the Interactive Web Frontend The web UI provides a user-friendly interface for non-technical medical staff to transcribe recordings: SarahCare Medical Transcription The JavaScript handles file uploads and API interactions: // wwwroot/app.js let selectedFile = null; async function checkHealth() { try { const response = await fetch('/health'); const statusEl = document.getElementById('status'); if (response.ok) { statusEl.className = 'status-badge online'; statusEl.textContent = '✓ System Ready'; } else { statusEl.className = 'status-badge offline'; statusEl.textContent = '✗ System Unavailable'; } } catch (error) { console.error('Health check failed:', error); } } function handleFileSelect(event) { const file = event.target.files[0]; if (!file) return; selectedFile = file; // Show file info const fileInfo = document.getElementById('fileInfo'); fileInfo.textContent = `Selected: ${file.name} (${formatFileSize(file.size)})`; fileInfo.classList.remove('hidden'); // Enable audio preview const preview = document.getElementById('audioPreview'); preview.src = URL.createObjectURL(file); preview.classList.remove('hidden'); // Enable transcribe button document.getElementById('transcribeBtn').disabled = false; } async function transcribeAudio() { if (!selectedFile) return; const loadingEl = document.getElementById('loadingIndicator'); const resultEl = document.getElementById('resultSection'); const transcribeBtn = document.getElementById('transcribeBtn'); // Show loading state loadingEl.classList.remove('hidden'); resultEl.classList.add('hidden'); transcribeBtn.disabled = true; try { const formData = new FormData(); formData.append('file', selectedFile); formData.append('format', 'json'); const startTime = Date.now(); const response = await fetch('/v1/audio/transcriptions', { method: 'POST', body: formData }); if (!response.ok) { throw new Error(`HTTP ${response.status}: ${response.statusText}`); } const result = await response.json(); const processingTime = ((Date.now() - startTime) / 1000).toFixed(1); // Display results document.getElementById('transcriptionText').value = result.text; document.getElementById('resultDuration').textContent = `Duration: ${result.duration.toFixed(1)}s`; document.getElementById('resultLanguage').textContent = `Language: ${result.language}`; resultEl.classList.remove('hidden'); console.log(`Transcription completed in ${processingTime}s`); } catch (error) { console.error('Transcription failed:', error); alert(`Transcription failed: ${error.message}`); } finally { loadingEl.classList.add('hidden'); transcribeBtn.disabled = false; } } function copyToClipboard() { const text = document.getElementById('transcriptionText').value; navigator.clipboard.writeText(text) .then(() => alert('Copied to clipboard')) .catch(err => console.error('Copy failed:', err)); } // Initialize window.addEventListener('load', () => { checkHealth(); loadSamplesList(); }); Key Takeaways and Production Considerations Building HIPAA-compliant voice-to-text systems requires architectural decisions that prioritize data privacy over convenience. The FLWhisper application demonstrates that you can achieve accurate medical transcription, fast processing times, and intuitive user experiences entirely on-premises. Critical lessons for healthcare AI: Privacy by architecture: Design systems where PHI never exists outside controlled environments, not as a configuration option No persistence by default: Audio and transcripts should be ephemeral unless explicitly saved with proper access controls Model selection matters: Whisper Medium provides medical terminology accuracy that smaller models miss Health checks enable reliability: Systems should verify model availability before accepting PHI Audit logging without content logging: Track operations for compliance without storing sensitive data in logs For production deployment in clinical settings, integrate with EHR systems via HL7/FHIR interfaces. Implement role-based access control with Active Directory integration. Add digital signatures for transcript authentication. Configure automatic PHI redaction using clinical NLP models. Deploy on HIPAA-compliant infrastructure with proper physical security. Implement comprehensive audit logging meeting compliance requirements. The complete implementation with ASP.NET Core API, Foundry Local integration, sample audio files, and comprehensive tests is available at github.com/leestott/FLWhisper. Clone the repository and follow the setup guide to experience privacy-first medical transcription. Resources and Further Reading FLWhisper Repository - Complete C# implementation with .NET 10 Quick Start Guide - Installation and usage instructions Microsoft Foundry Local Documentation - SDK reference and model catalog OpenAI Whisper Documentation - Model architecture and capabilities HIPAA Compliance Guidelines - HHS official guidance Testing Guide - Comprehensive test suite documentation