microsoft fabric
40 Topics
Amplify Healthcare Intelligence: Data, AI, and Agent-Powered Transformation
Join Microsoft for Amplify Healthcare Intelligence, a webinar and in-person workshop series designed for healthcare and life sciences organizations building the foundation for trusted AI. Every session starts from the same premise: you cannot deliver trusted AI without a trusted data foundation. Across the series you will see how leading organizations unify their data estate, ground AI agents in real business context, and turn that foundation into results they can measure. What You Will Learn How to build a unified, AI-ready data foundation across a fragmented healthcare data estate How to ground AI agents in trusted healthcare data and real business context How to modernize analytics while reducing complexity and cost How to accelerate innovation with Microsoft Fabric, Azure AI Foundry, Microsoft IQ, and Copilot technologies How to deliver measurable impact across clinical, operational, research, and business scenarios Whether you are defining your AI strategy, modernizing your analytics platform, or scaling AI across your organization, these sessions offer practical guidance, real-world customer examples, and hands-on learning to help you move from AI ambition to business impact. Webinars & In-Person Workshops 🎥 Webinars One-hour virtual sessions with actionable guidance, live demonstrations, customer stories, and best practices from Microsoft experts. Each webinar shows how leading healthcare organizations are turning data, AI, and enterprise intelligence into measurable business outcomes. All sessions are from 3-4 ET (12-1 PT) and are free to attend. Date Topic Register Oct 7 3-4 ET (12-1 PT) Building an AI-Ready Healthcare Data Foundation Register Oct 14 3-4 ET (12-1 PT) Building Trusted Healthcare AI: Grounding Agents with Enterprise Data and Context Register Oct 21 3-4 ET (12-1 PT) Finance in the Agent Era: AI-Powered Planning, Forecasting, and Insights Register Oct 28 3-4 ET (12-1 PT) Reduce BI Sprawl, Cut Cost and Build an AI-Ready Analytics Foundation Register Cannot join live? Register anyway. We will send you the recording and session materials after the event. Additional sessions will be added through the end of the year, so check back or register for one session to be notified as new dates are announced. 🏢 In-Person Workshops Our two-day workshops combine executive strategy, healthcare-specific use cases, architecture guidance, and hands-on labs designed to help teams identify and accelerate high-value AI opportunities. Attendance is free. Participants are responsible for their own travel and accommodation, and space at each location is limited. Workshops run 9am to 4pm local time on both days. Day 1: From Healthcare Data to Healthcare Intelligence Day 1 focuses on healthcare transformation strategy, customer examples, and the architectural patterns that make trusted AI possible at scale. The day closes with a networking reception and peer exchange. The Frontier Transformation imperative: from AI ambition to measurable impact Microsoft IQ: turning data into enterprise intelligence Building the unified data foundation Building trusted AI: security, governance, privacy, and compliance Healthcare transformation in action: clinical, operational, research, and finance scenarios Activating data with AI data agents and Copilot experiences Day 2: Hands-On Healthcare AI and Analytics Lab Day 2 is a guided, end-to-end lab. Participants build a working healthcare intelligence solution from raw data through to a grounded AI agent, using Microsoft Fabric, Azure AI Foundry, Copilot technologies, and modern data architectures. Build the foundation: data ingestion, lakehouse architecture, and data engineering Create actionable insights: semantic models and dashboards Prepare data for AI: AI-ready data assets and data governance Build and ground AI agents in trusted enterprise data From insight to intelligent action: planning your organization's next steps What to bring: a laptop with a current browser. Lab environments and credentials are provided on site, and no prior Fabric or Foundry experience is assumed. Date City Venue Register October 13-14, 2026 9am - 4pm Boston Microsoft New England One Memorial Drive Cambridge, MA 02142 Register October 27-28, 2026 9am - 4pm Silicon Valley Microsoft Silicon Valley 1045 La Avenida Street Mountain View, CA 94043 Register November 10-11, 2026 9am - 4pm Chicago Microsoft Chicago (AON Center) 200 East Randolph Drive, Suite 200 Chicago, IL 60601 Register December 8-9, 2026 9am - 4pm New York Microsoft Garage 300 Lafayette Street New York, NY 10012 Register Who Should Attend This series is built for the people who own the data estate and the people who depend on it. Sessions are technical enough for practitioners and strategic enough for the leaders who fund the work. Chief data officers and data and analytics leaders Data platform, data engineering, and business intelligence teams Data architects, engineers, and data scientists AI and innovation leaders Healthcare and life sciences executives Clinical, operational, research, and finance transformation leaders No prior Microsoft Fabric experience is required for any session in this series. Questions Wondering whether a session is the right fit, or whether to bring a team rather than an individual? Contact Camille Whicker and we will help you choose the right sessions for your organization.Amplify Healthcare Intelligence In-Person Workshop Series
What You'll Learn How leading organizations are navigating the Frontier Transformation journey Strategies for turning healthcare data, workflows, and expertise into organizational intelligence Best practices for building a unified, AI-ready data foundation Approaches for implementing trusted AI with strong governance and security Real-world healthcare scenarios across clinical, operational, financial, and research domains How AI agents can transform the way people interact with data and make decisions Practical skills for deploying analytics, AI, and agent-powered solutions Day 1: From Healthcare Data to Healthcare Intelligence Explore how leading healthcare organizations are creating a trusted foundation for AI and transforming data into meaningful business outcomes. The Frontier Transformation Imperative The future of healthcare in the age of AI and agents Industry trends, opportunities, and challenges Moving from AI ambition to measurable impact Microsoft IQ: Turning Data into Enterprise Intelligence Connecting data, workflows, and organizational knowledge Building organizational intelligence for AI Establishing the foundation for trusted decision-making Building the Unified Data Foundation Modernizing the healthcare data estate Creating a single source of truth for analytics and AI Leveraging Microsoft Fabric and OneLake as a unified platform Building Trusted AI Security, governance, privacy, and compliance Responsible AI considerations for healthcare and life sciences Preparing data and processes for enterprise AI adoption Healthcare Transformation in Action Clinical transformation scenarios Operational transformation scenarios Research and innovation use cases Finance and performance management opportunities Activating Data with AI Agents AI Data Agents and Copilot experiences From data to decision-making Real-world examples of agent-powered healthcare innovation Networking Reception & Peer Exchange Day 2: Hands-On Healthcare AI & Analytics Lab Gain practical experience building an end-to-end healthcare intelligence solution using Microsoft technologies. Build the Foundation Data ingestion and modernization patterns Lakehouse architecture and data engineering Establishing a scalable healthcare data platform Create Actionable Insights Semantic models and business intelligence Power BI dashboards and reporting Real-time healthcare intelligence Prepare Data for AI Building AI-ready data assets Data governance and trust Optimizing data for intelligent applications Build and Ground AI Agents Creating AI Data Agents Leveraging business context and trusted enterprise data Connecting agents to analytics and operational workflows From Insight to Intelligent Action End-to-end healthcare AI scenario Data → Insights → Agents → Outcomes Planning your organization's next steps Upcoming Workshop Locations Date City Venue Register September 9-10, 2026 9am - 4pm Dallas Microsoft Las Colinas 1 7000 N State Hwy 161 Irving, TX 75039 Register September 29-30, 2026 9am - 4pm Minneapolis Microsoft Edina 3601 West 76th Street, Suite 600 Edina, MN 55435 Register October 13-14, 2026 9am - 4pm Boston Microsoft New England One Memorial Drive Cambridge, MA 02142 Register October 27-28, 2026 9am - 4pm Silicon Valley Microsoft Silicon Valley 1045 La Avenida Street Mountain View, CA 94043 Register November 10-11, 2026 9am - 4pm Chicago Microsoft Chicago (AON Center) 200 East Randolph Drive, Suite 200 Chicago, IL 60601 Register December 8-9, 2026 9am - 4pm New York Microsoft Garage 300 Lafayette Street New York, NY 10012 Register Who Should Attend? Healthcare and Life Sciences Executives CIOs, CTOs, and Chief Data Officers Clinical and Operational Leaders Analytics and Data Platform Teams AI and Innovation Leaders Finance Transformation Teams Architects, Engineers, and Data Professionals What You'll Walk Away With By the end of the workshop, you'll have a clear understanding of how to build a unified data and AI foundation, enable trusted AI and intelligent agents, and create a roadmap for accelerating healthcare transformation within your organization.Fabric Data Agents can choose Query Language based on Context
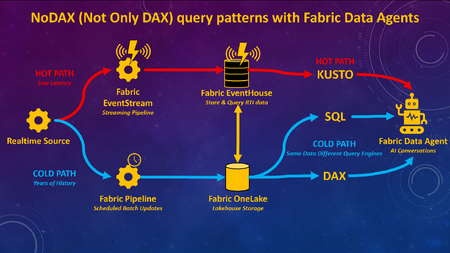
What if you could combine decades of historical analysis with live, real-time data in one seamless AI chat experience? Traditionally, analyzing large volumes of past data (Analytics / Business Intelligence) has been a separate architecture, or has at least required separate toolsets, from monitoring what’s happening right now (real-time, IoT, etc). With Fabric Data Agents, analytics for large volumes of historical data can be accessible with real-time data via a single AI query endpoint. Analytics can be used to gain understanding from historical data, and findings can be put into action for real-time scenarios, all through a single interface for the end users. Figure 1.0 – Fabric Data Agent can use different query languages for optimal performance with a lambda-style RTI architecture on Fabric Many of the demos I’ve seen for Fabric Data Agents will highlight the capability to connect to different types of queries and sources via a single endpoint such as Lakehouses (SQL), Warehouses (SQL), Semantic Models (DAX), Eventhouses (Kusto), and Ontologies. What I have not seen frequently discussed is adding different query engines on the same data for the purpose of optimizing query performance based upon the context of the query and the latency of the data, as per Figure 1.0 above. To be clear, I am not advocating duplication of data for the purpose of query performance. Rather, this architecture would enable Fabric Data Agents to choose the best query language for the context of the query. Hence the acronym I created for this blog article “NoDAX” which stands for “Not Only DAX.” NoSQL “Not Only SQL” is a real term referring to non-relational database systems designed for flexible schemas, horizontal scaling, and high-performance access to large, distributed datasets. NoDAX exists only within this blog post, and represents the availability of multiple query languages within a single Fabric Data Agent. The best query language can be used based on the context of the question and query. Not only DAX but also SQL, Kusto, and Ontologies can be queried to generate the most efficient contextual query. Figure 1.1 – Explaining the NoDAX acronym created for this article Why does this use case matter? The ability to query both the past and the present in one interface isn’t just a novel technical capability. Many analytic solutions can benefit from a pattern of [analysis + action]. Analytics by itself is great at understanding the past. We can look at years of historical data to figure out patterns, drivers of performance, and what went right or wrong. Historical context is incredibly valuable, but understanding the past doesn’t improve outcomes in the future. The real value comes when we connect findings from the past to decisions we make right now and in the future. If you discover historical data patterns that lead to an inventory shortage, a fraud event, or a patient risk score increasing, you can apply that insight to the latest operational data and act on ongoing workflows. Analytics and action have to reinforce each other. Analytics without action doesn’t create value. But action without understanding can easily make things worse. I once had a veteran analytics manager say to me “Without carefully considered and vetted KPIs you are flying blind. But be careful, because a KPI without proper context and understanding will quickly become a blunt object that an empty suit uses to whack somebody over the head.” Figure 1.2 – The purpose of this architecture is to learn from the past to improve the present and future Different Query Languages without data duplication A Fabric real-time architecture can be part of a design pattern that is similar to if not a version of a Lambda architecture. With a Lambda architecture, hot path data is available for real-time alerting and analytics while cold path data is stored for deep and complete historical analytics and data science. Figure 1.3 – NoDAX architecture can query a lambda-style architecture via multiple query endpoints Per the diagram above, real-time data is available in Fabric ASAP and cycled through an Eventhouse. Historical data can either be batched into a Fabric Lakehouse / Warehouse or copied over from the Eventhouse. A Fabric Data Agent can then generate Kusto queries against the Eventhouse, SQL queries against the Lakehouse / Warehouse, or DAX queries against the Warehouse / Lakehouse via the Direct Lake Semantic Model. DAX is often the best query language for data having deep history with complext analytic logic. SQL can be the best query language for retrieving historical row-level information from a robust relational database. Kusto can be used to query what’s happening right now via a real-time Eventhouse. Lambda architectures have been around for years, so why is this architecture a new option? Past lambda architectures would have hot path data available in a streaming toolset such as Azure Eventhub, and then store historical cold path data in a tool such as Azure Data Lake. Hot path alerting and reporting was usually disparate from historical cold path analytics. Per the diagram 3.4 below, with Microsoft Fabric, you can now: implement both the hot and cold path in a single Fabric environment (Eventstream, Eventhouse, Lakehouse / Warehouse). Ontologies are also an option. query the hot and cold path data via a single agentic endpoint using a Fabric Data agent Query either the hot or cold path using the optimal query language for the context of the question (DAX, SQL, Kusto, Ontologies) Figure 1.4 – Fabric not only unifies components of lambda-style architecture, but Data Agent also unites the query endpoints for AI unification Example use case for Healthcare Here’s an example of a Healthcare use case: A user might ask a question “Show me the percentage of patients who had their pain scores checked every hour for gall bladder removals on floor 5 over the last 3 years.” This will ideally filter three years worth of data for patients with specific procedure codes, filtered for specific rooms, and calculate the pain score check compliance for those visits. This query is ideal for the DAX language with a Semantic Model. The user might then want to see details for a specific time period, and ask “Show me the pain score results for patients who had their gall bladder removed on July 3 2024 on floor 5.” A SQL query might be the best option here against the Fabric Warehouse or Lakehouse, since SQL is better than DAX at retrieving row-level information. Then the user might want to know what is happening today. “Show me the pain score checks for inpatients right now who had their gall bladder removed on floor 5.” The Kusto language can retrieve the information that streams into a Fabric Eventhouse via an Eventstream. Based on the findings, the user may take an action. With the example above, a user was able to query deep history with analytic logic, retrieve historical row-level information from a robust relational database, and then view what’s happening right now for those patients. Action can then be taken in the here and now. Here are some additional use cases for Finance, Supply Chain, and Manufacturing in addition to Healthcare: Figure 1.5 – Industry use cases for Fabric Data Agent with multiple endpoints Video Summary Below is my video summary and demo of the Fabric Data Agent NoDAX architecture: Configure Fabric Data Agent for NoDAX query patterns When more than one source is added to a Fabric Data Agent, by default the source used for a specific query will be chosen based on interpreting available metadata. The Data Agents have a field called "Agent instructions" which can be used to provide detailed instructions about choosing the right source for the right question. Here’s a screenshot of the Agent instructions: Figure 1.6 – Agent instructions will guide the Fabric Data Agent to the best query endpoint I would recommend extensive unit testing and iterative improvements to the Agent instructions based upon your own data and use cases. Here’s a few examples that worked for my initial testing. I would recommend much more robust and carefully designed prompts for a production solution, but this is a baseline of an approach I found to work based on the demo in the video above: The KQL database named SeattleFireEventHouse is a live stream of 911 calls to the fire department in the city of Seattle. Whenever someone asks for “most recent” or “newest” or “latest” use SeattleFireEventHouse The lakehouse SeattleFireLakehouse should be queried with a SQL statement when someone asks for a list of incidents before the year 2026. Use SQL to retrieve row level requests for historical data. The semantic model SeattleFireSemantic Model should be queried when questions ask about historical analytic trends such as call volume averages, Year over year changes, and queries that aggregate data for analytic queries.Rayfin | Go from prompt to production backend
Describe the app you want using Rayfin’s open-source SDK with GitHub Copilot, and generate your full backend in code — schemas, relationships, and access policies included. Deploy to Microsoft Fabric with a single CLI command and immediately inherit enterprise data security, identity controls, and audit compliance already in place across your data estate. Connect your app’s live operational data to years of historical records in Fabric from the moment you deploy, no pipelines, no data movement. Query across both datasets using a Fabric data agent you spin up directly on your app’s data. Will Thompson, Microsoft Fabric Principal Product Manager, shares how to take an app from idea to governed production deployment in a single session. Describe the app you want. Rayfin and GitHub Copilot generate your full backend in code- schemas, relationships, and access policies. No manual wiring. See how it works. One CLI command. Fully managed SQL database, APIs, and static hosting in Microsoft Fabric. Rayfin handles provisioning automatically. Take a look. Spend less time configuring. Spend more time creating. Get managed backend services, authentication and authorization, data APIs, built-in analytics, and AI-ready architecture with Rayfin. Check it out. QUICK LINKS: 00:00 — Simplify backend complexity 01:20 — Home delivery service app 01:48 — Data analysis app 02:26 — See the build experience 03:08 — Copilot Generates Full Backend 03:47 — Authorization defined alongside schema 05:06 — One CLI Command Deploys to Fabric 05:21 — Create analytics app & add pages 06:31 — App Data Connects to Fabric Data Estate 06:55 — Conversational Data Agent on App Data 08:13 — Wrap up Link References Get started at https://aka.ms/rayfin Unfamiliar with Microsoft Mechanics? As Microsoft’s official video series for IT, you can watch and share valuable content and demos of current and upcoming tech from the people who build it at Microsoft. Subscribe to our YouTube: https://www.youtube.com/c/MicrosoftMechanicsSeries Talk with other IT Pros, join us on the Microsoft Tech Community: https://techcommunity.microsoft.com/t5/microsoft-mechanics-blog/bg-p/MicrosoftMechanicsBlog Watch or listen from anywhere, subscribe to our podcast: https://microsoftmechanics.libsyn.com/podcast Keep getting this insider knowledge, join us on social: Follow us on Twitter: https://twitter.com/MSFTMechanics Share knowledge on LinkedIn: https://www.linkedin.com/company/microsoft-mechanics/ Enjoy us on Instagram: https://www.instagram.com/msftmechanics/ Loosen up with us on TikTok: https://www.tiktok.com/@msftmechanics Video Transcript: -What if building a real, production-ready enterprise app didn’t take months, but just a few hours? Today, AI can generate app logic and front ends almost instantly. And while everything works great with test data, the moment you try to connect that app to real enterprise data, everything slows down. Because now you have to wire up a database with access control, set up authentication, configure backend services, and make sure everything is secure and scalable. Your quick app turns into a complex backend project with multiple failure points, and that’s where Rayfin comes in. It’s designed to simplify backend definition in code and elevate the developer experience. Our open-source SDK and CLI grounds your agentic coding tools so that when you describe the app that you want to build, it can automatically define your app’s backend in code, including your data schemas, relationships, and access policies. -And then with a single CLI command, you deploy to our unified data and analytics platform, Microsoft Fabric. This spins up a fully managed backend with a SQL database with familiar billing and sharing models, as well as static hosting. APIs are generated automatically to ensure your app can communicate securely to data and services and Fabric’s identity and data security layer ensures that when your app accesses or queries data, it respects existing policies in place across your data estate. -To show how this works in action, I’ll start by showing two apps I built with Rayfin and then walk you through how I created them. My first app is a mobile home delivery service app for a home improvement retailer, with all orders delivered directly to customers’ doors. Drivers must be signed in to access the app, ensuring that every delivery is securely tied to an authenticated user. They can record deliveries, capture photos as proof, and even collect customer signatures to acknowledge receipt. And all this happens in real time. -Next, as a business, we want to learn from the data captured in our delivery app. So I’ve built a second app for data analysis. Because it runs in Fabric, the operational data is already connected to our broader enterprise data estate. It has access to years of customer data in Fabric, modeled and ready to use. And by connecting that data to the live data that our delivery app captures, retail managers now have immediate insight into how the new delivery service is impacting customer satisfaction. Now these apps were built in minutes. They’re not a proof of concept. They have real auth, real data, and real governance, and they work directly with enterprise data already in Fabric. -Let me walk you through the build experience. I’ll open a terminal and run the Rayfin create command, and this will walk me through my entire project setup. I can see that I have various templates that I can use to get started. So let’s go with the blank app template. It’s asking for a name and I’ll name it Delivery App. And you can see it’s creating the project. And under the covers, it’s installing all the necessary dependencies and adding the files I need, including the agent instructions for using the SDK and CLI. Now I can CD into my project and start the development server. Since deploying to Fabric, it prompts for a Fabric workspace name and I’m going to use Zava. And the deployment process is now in full swing with Fabric provisioning my foundational resources. -So now with our Rayfin foundation in place, let’s build the app. Using VS code with GitHub Copilot, I can now describe the app I want and Copilot knows how to build it, including the backend. Let’s try it out, I’ll type a prompt, build a Rayfin delivery app where drivers log deliveries with photos and item conditions and customers confirm receipt. I’m also going to start the Rayfin MCP server and this will help ground Copilot in all the latest best practices for Rayfin. As Copilot is getting to work, we can see it’s using the documentation for the MCP and CLI tool to understand the specifics of Rayfin. And Copilot will run independently using the skills defined by the Rayfin template. That’s going to take a few minutes, so we’re going to jump ahead to the results. -Here’s the app right here in code and there’s lots more to it, in fact, to understand the depth of what was created, let’s take a more detailed look. Inside the Rayfin folder, we can see our whole data schema, customers, deliveries, items, photos, drivers, and more. And if we take a look at how Copilot defined the driver entity, this is where Rayfin shines. The schema lives right in the code, which means instead of keeping the rules about your data in separate places like databases, SQL files, or configs, they’re built right into the code. So things are less likely to break and easier to keep consistent. Each field maps to a column in the database. ID name, email, and optional phone number with types and constraints built in. -And it captures relationships too. It calls out a driver has many deliveries. But here’s the key part, the access policy sits right next to the data. This rule says a user can only ever touch their own driver record. Authorization is defined alongside the schema not bolted on later. And if we open the delivery entity, you can see some of the scale Rayfin is capable of with richer relationships, defined with drivers, customers, and items, and a smarter policy where delivery can be read by an authenticated driver or its customer. And of course I can always customize any of this by hand if I need to. So that was the build experience. -Now let’s look at how we can deploy the app to Microsoft Fabric. I’ll ask Copilot to deploy our app and Copilot is using the Rayfin Up command to deploy everything we’ve defined straight to Fabric. And just like that, our app is deployed and available. Next, directly from Fabric, I’ll show you the steps to create our analytics app. I’ll start in the Fabric portal this time and I’ll call this app Delivery Analysis. This leverages a template that the Microsoft Power BI team built. It’s called a Data App template, and it gives our coding agent what it needs to connect to semantic models and create beautiful interactive visuals. -So I’ll select Data App, and now I can manually follow these steps or just copy the prompt and run it in VS Code to get started scaffolding my project. I’ll move over to VS Code and paste in the prompt and the agent knows exactly how to start up my new Rayfin app. Once it’s finished, you’ll see that the delivery analysis directory has been added. Now we can also add pages to our new app using Copilot. Here I want to add an insights page. So I’ll prompt, Add a customer satisfaction page, which shows historical CSAT scores from our linked semantic model and compare it against a given driver’s delivery ratings. The important detail here, I’m pointing it straight at our Fabric semantic model, so it’s using a preexisting and trusted business model. This process will run for several minutes, creating and executing a plan and querying our semantic model for what it needs. -To save time, I’ll jump back in near its completion. Now the app is ready and I can view it from the provided link. And we can see historical customer satisfaction data trending up since we launched the delivery service with details broken down by driver. Now, data isn’t moved between systems. Everything stays connected from the start. The backend is already connected to your enterprise data estate. And because all of your new data is now also landing in Fabric, there’s lots you can do on top of it. -Now that our app is live and generating data, the next step is making that data actionable through conversation. So instead of building another report or connecting the data to a Fabric notebook, I’m going to go ahead and create a data agent directly on top of this app’s data. I’ll name the agent, Zava Insights Agent, and next I’ll point it at the warehouse I configured earlier. This combines my operational database and historical data as the source. And now I can ask questions against my data just like I would to an analyst. -Let’s start with a simple question. I’ll ask, what is the average customer rating across all our deliveries? The agent understands the data model and returns the answer instantly as 4.56 out of five. But now I’ll go deeper. How does our customer satisfaction compare before and after we launch the new delivery service? It doesn’t just retrieve the data. It reasons across time and trends in the model. And we can see that it’s gone from 3.8 to 4.4 out of five since launching the new service. So instead of navigating dashboards, the business can now ask questions directly against the app and get answers grounded in the same governed data that powers the app. -And just like any Fabric artifact, I can share the app that we created earlier with other people in my organization. So let’s grant Lynne access. They were asking about the delivery analysis and now they can explore the data themselves without waiting on reports. Rayfin helps you go from idea to production faster. By using AI to build and deploying to Fabric, your app inherits existing data security controls, permissions and audit requirements, keeping everything compliant and under control. -To learn more, check out aka.ms/rayfin and keep watching Microsoft Mechanics for the latest tech updates and thanks for watching.469Views0likes0CommentsOperations Context for AI | Ontology in Fabric IQ
Generate a full business ontology from an existing Power BI semantic model, map entities and relationships, and embed real-time operational signals alongside business rules that live inside the ontology with the data and its meaning. From there, trace cascading operational impacts across your business through the relationship graph, stand up Operations Agents in natural language with Teams-based actions, and connect the same ontology as a knowledge source in Copilot Studio or Azure AI Foundry. Chafia Aouissi, Fabric IQ Principal PM Manager, shares how to model your business operations, embed intelligence in your data, and deploy agents that act on it. Logic lives with your data. Embed business rules directly in the Fabric IQ ontology. Define thresholds, trigger notifications, and cascade decisions through connected entities. Watch the demo. Surface cascading impacts with a single query. Filter the Fabric IQ relationship graph by any entity and trace downstream operational impact across your entire business. Check out a built-in ontology graph in Fabric IQ. Build a Fabric IQ Operations agent in natural language. Define monitoring goals, connect your ontology as its knowledge base, configure Teams actions, & deploy. See the full build. QUICK LINKS: 00:00 — Unify models & data with Fabric IQ 01:12 — Generate an ontology 02:27 — Bring in Power BI reports 03:08 — View across multiple data sources 04:23 — Define rules 05:18 — Built-in ontology graph 06:03 — Fabric IQ agents 08:24 — Fabric IQ as Knowledge Source 08:54 — Wrap up Link References Get started at https://aka.ms/FabricIQ Unfamiliar with Microsoft Mechanics? As Microsoft’s official video series for IT, you can watch and share valuable content and demos of current and upcoming tech from the people who build it at Microsoft. Subscribe to our YouTube: https://www.youtube.com/c/MicrosoftMechanicsSeries Talk with other IT Pros, join us on the Microsoft Tech Community: https://techcommunity.microsoft.com/t5/microsoft-mechanics-blog/bg-p/MicrosoftMechanicsBlog Watch or listen from anywhere, subscribe to our podcast: https://microsoftmechanics.libsyn.com/podcast Keep getting this insider knowledge, join us on social: Follow us on Twitter: https://twitter.com/MSFTMechanics Share knowledge on LinkedIn: https://www.linkedin.com/company/microsoft-mechanics/ Enjoy us on Instagram: https://www.instagram.com/msftmechanics/ Loosen up with us on TikTok: https://www.tiktok.com/@msftmechanics Video Transcript: -The agents you build and use need the right operational context of how your business runs to deliver the best outcomes. Today, that context is often fragmented across systems, defined differently by different teams, or buried in dashboards and logic, making outcomes inconsistent and agent behavior hard to predict. That’s where Microsoft Fabric IQ comes in. Fabric IQ introduces a semantic foundation that unifies models and data through an ontology. It defines the shared business entities and their relationships, and connects them to your data. It provides the operational context needed to understand how the business actually runs, without altering any underlying data. Analysts can not only work with the data they already trust, but also model how the business works. And agents can use that same shared context to reason and act more consistently. Today, I’ll show you both sides. -First, how a data analyst leverages Fabric IQ inside a Fabric workspace, using ontology to model the business concepts. Then, how Fabric IQ uses the same context to drive more reliable and predictable insights from agents. I’ll start from the point of view of an analyst looking to create a full fidelity view of how an airline operates, including processes such as ticketing, maintenance, and more. The first thing I need to do is to create a new ontology. I can either build one from scratch, or jumpstart by using an existing Power BI semantic model. As you see here, there’s a new option to generate an ontology from this semantic model. I just need to choose the workspace, give it a name. I’ll choose AirlineOperationsOntology. Then confirm by hitting Create. In just a few clicks, I’m able to see the different entities of our airline business. All data is now linked not only through keys, but also business relationships and semantics. We can see flights, airlines, routes, and more. If I click into airports, because Fabric IQ is semantically aware of the relationships between entities, it shows the routes connected to runways which are in turn connected to airports. -And for any entity, I can choose to add more live operational signals. In this case, I want to add details about the runway conditions using real-time data, including contamination, visual range for visibility, as well as the available cleared width and more. And you can also bring in your Power BI reports for a canonical view of how to monitor and manage these aircrafts. From the ontology, I’ll head over to the Report links tab that opens the OneLake catalog with all of my reports. I’ll search for air and there are three matching reports for gates, ground service, plus safety and runway. So I’ll add them and hit Connect to confirm. -So, in just a few clicks, we’ve expanded our ontology with the live operational view, using real-time signal, geospatial data, and more. Now, as an analyst, I can work immediately with it, and our agents can act on it as well. Let’s fast‑forward and see what I’ve unlocked. You can see that I now have a richer view over my data, which is connected to real‑world operations. We’re no longer optimizing one report or one dataset at a time. We’re looking at our operations across multiple data sources, in the language of our business, with meaning and relationships already understood. -Now let me show you how this makes it easier to turn insights into concrete decisions and actions. First, in the flight entity type overview, I can see how it relates to my other business processes. I see entities like bookings, gates, airlines, and more as a graph. I have links to all of my connected Power BI reports. There is a real-time weather data, including wind knots, as well as geo-spatial insights showing all of my flights. Using Fabric Maps, I have a fleet level view of all my active flights, and I can see live air traffic across the fleet. This, in fact, is a heat map view of three New York City area airports, and we can see that JFK in this case is impacted with lots of runway activity. -I can now understand the system as a whole, across bookings, flights, airports, and real‑time conditions. And I can drill in further to understand what is going on: I have opened the runways entity, and you’ll remember some of these categories from before. Since there’s snow in the area, I can immediately see the runway conditions that affect operations, things like surface friction and contamination levels, so I understand how safe it is for planes to take off and land. -Beyond connecting raw data, I can also define rules directly in the ontology, so this logic lives with the data and its business meaning, instead of being hard coded somewhere else. In this case, I’ll add a rule that says if runway contamination exceeds high threshold value of 25%, notify the passengers proactively of upcoming delays. We’ll also notify the ground crew, so they know that the runways need to be cleared. The rules are now embedded in the ontology, and the value comes from seeing how runway conditions impact the rest of the operations. That’s where the built‑in ontology graph helps. Let’s look at the relationship graph. I’ll expand the graph view. And add a filter for JFK airport Then run the query. No code needed here. And I get a filtered view for JFK. And immediately, I can see a poor condition that’s affecting Runway 25R. -From that insight, it’s easy to see the downstream impact. This runway issue is already affecting related gates and baggage operations that will need to be rescheduled. This is a unified view of our entire operations and how connected events will cascade across related business entities. This is how ontology helps you as an analyst. But remember, the same operational context is also available to AI agents, no matter how you build them. -Let me demonstrate this in the context of one our built-in Fabric IQ agents. From the New Item catalog, you can find the built-in agents by searching for agent. There is a Data agent designed to answer questions, and an Operations agent designed for real-time data and business action recommendations. The Operations agent is a perfect fit for our airline operations scenario, so I’ll choose that one. I want this agent to help with runway-related analysis and actions, so I’ll name it RunwayConditionsAgent, leave the location, and create it. -From there, I can add a bit more information to set up the agent, like adding the business goals for what it should accomplish I want this one to monitor surface conditions for runways and ensure things run smoothly based on logic like we used before. In fact, in the Agent instructions, using natural language, no code, I’ll describe that if surface contamination is reported above 10%, send ground crews to take care of it. Likewise, the clear width should be more than 25 meters, and the agent should send ground crew to visually assess whether planes can safely brake. -Now let’s add some knowledge. And for that, I’ll choose our AirlineOntology. And here’s where I can add actions. I’ll add one to assign ground crew for clearing, along with description for what needs to be done. Then I’ll give it the Runway ID as the one to clear and the Temperature to predict the type of clearing needed. And Create to add that one. Now I’ll add another for requesting visual assessment, and perform similar steps for the parameters. These will send status updates in Microsoft Teams. Now everything is defined and ready. I just need to save this new agent. That takes a moment. And once it’s finished, it creates a nice agent playbook with what it’s designed to do. -Now, with the agent running, the right people will get notified of what to do in Microsoft Teams Here, I’m looking at the Operations agent It’s alerting us that Runway 29L has only 22 meters of clear path. This is under our 25 meter threshold. It recommends to deploy the ground crew for a runway clearance operation. As the human in the loop, I can choose whether or not to proceed with the recommendation. I’ll do that. -Then it asks to confirm a few details. They look good, so I’ll confirm, and the ground crew is on its way. And here is the good news. If you’re building your own agent in Microsoft Copilot Studio or using Microsoft Foundry, Fabric IQ ontology will be an integrated knowledge source that you will be able to choose from. As you choose your knowledge types, you can select Fabric IQ. This will ground agents in the same semantic foundation that already runs your operations. And of course, the agents you build and connect to Fabric IQ will respect the permissions and security policies you already use in Fabric today. -As I have shown, Microsoft Fabric IQ gives agents shared understanding, with entities, relationships, rules, and actions so they can move from insight to decision more reliably. To learn more and get started, check out aka.ms/FabricIQ. Keep watching Microsoft Mechanics for the latest news and deep dives. And thank you for watching.701Views0likes0Comments
Unlock AI-Ready Insights: Empowering Nonprofits with Microsoft Fabric
Disconnected data slows impact—but it doesn’t have to. Nonprofit data solutions in Microsoft Fabric unify your data, accelerate insights, and create an AI-ready foundation for smarter decisions. Imagine moving from raw donor data to actionable insights in weeks, not months. With Fabric, nonprofits gain: Unified fundraising data in one place Instant insights through ready-made dashboards AI-powered possibilities for predictive analytics and smarter strategies This isn’t just technology—it’s a game-changer for fundraising, volunteer management, and program delivery. Built with nonprofit needs in mind, Fabric helps you reduce complexity and unlock mission outcomes faster. Ready to see how? Read the full article on Microsoft for Nonprofits LinkedIn: https://www.linkedin.com/posts/microsoft-for-nonprofits_disconnected-data-slows-impact-but-it-doesn-activity-7402016549773017088-8cH9168Views0likes0CommentsActing on Real-Time data using custom actions with Data Activator
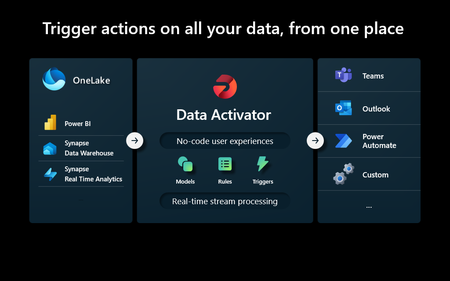
Being able to make data driven decisions and act on real-time data is important to organizations because it enable them to either avert crisis in systems that monitor product health and take other actions based on their requirements. For an example, a shipping company may want to monitor their packages and act in real-time when the temperature of the packages becomes too hot. One way of monitoring and acting on data is to use Data Activator, which is a no-code experience in Microsoft Fabric for automatically taking actions when the condition of the package temperature is detected in the data.1.2KViews0likes1CommentIntegrating remote patient monitoring solutions with healthcare data solutions in Microsoft Fabric
Co-Authors: Kemal Kepenek, Mustafa Al-Durra PhD, Matt Dearing, Jason Foerch, Manoj Kumar Introduction Remote patient monitoring solutions rely on connected devices, wearable technology, and advanced software platforms to collect and transmit patient health data. They facilitate monitoring of vital signs, chronic conditions, and behavioral patterns. Healthcare data solutions in Microsoft Fabric offers a secure, scalable, and interoperable data platform as part of Microsoft for Healthcare. Such a unified data platform is crucial for integrating disparate data sources and generating actionable health insights. This article provides a reference architecture and the steps to integrate remote patient monitoring solutions with healthcare data solutions in Fabric. The integration is aimed at satisfying low data resolution use cases. With low data resolution, we address infrequent (hourly, daily, or less) transfer of aggregated or point-in-time-snapshot device data into healthcare data solutions in Fabric to be used in a batch fashion to generate analytical insights. Integration steps for high data resolution use cases, which necessitate high frequency transfer of highly granular medical device data (for example, data from EKGs or ECGs) to become input to either batch or (near) real-time analytics processing and consumption, is a candidate for a future article. There are several methods, solutions and partners available in the marketplace today that will allow you to integrate a remote patient monitoring solution with the healthcare data solutions in Fabric. In this article, we leveraged the solution from Life365 (a Microsoft partner). The integration approach discussed here is applicable to most remote patient monitoring solutions whose integration logic (code) can be run inside a platform that can programmatically access (for example, through REST API calls) Microsoft Fabric. In our approach, the integration platform chosen is the Function App service within Microsoft Azure. In the subsequent sections of this article, we cover the integration approach in two phases: Interoperability phase, which illustrates how the data from medical devices (used by the remote patient monitoring solution) can be converted into format suitable for transferring into healthcare data solutions in Fabric. Analytical processing and consumption phase, which provides the steps to turn the medical device data into insights that can be easily accessed through Fabric. Integration Approach Interoperability Phase Step 1 of this phase performs the transfer of proprietary device data. As part of this step, datasets are collected from medical devices and transferred (typically, in the form of files) to an integration platform or service. In our reference architecture, the datasets are trans ferred to the Function App (inside an Azure Resource Group) that is responsible for the integration function. It is important for these datasets to contain information about (at least) three concepts or entities: Medical device(s) from which the datasets are collected. Patient(s) to whom the datasets belong. Reading(s) obtained from the medical device(s) throughout the time that the patients utilize these devices. Medical device readings data may be point-in-time data capture, metrics, measures, calculations, collections, or similar data points. Information about the entities listed above will be used in the later step of interoperability phase (discussed below) when we will convert this information into resources to be transferred to the second phase that will perform analytical processing and consumption. In step 2, to maintain mapping between proprietary device data and FHIR® resources, you can use transformation templates, or follow a programmatic approach, to convert datasets received from medical devices into appropriate FHIR® resources. Using the entities mentioned in the previous step, the conversion takes place as follows: Medical device information is converted to Device resource in FHIR® * . Patient information is converted to Patient resource in FHIR®. Device reading information is converted to Observation resource in FHIR®. * Currently, healthcare data solutions in Fabric supports FHIR® Release 4 (R4) standard. Consequently, the FHIR® resources that are created as part of this step should follow the same standard. Transformation and mapping activities are under the purview of each specific remote patient monitoring integration solution and are not reviewed in detail in this article. As an example, we provided below the high-level steps that one of the Microsoft partners (Life365) followed to integrate their remote patient monitoring solution with healthcare data solutions in Fabric: Life365 team developed a cloud-based transformation service that translates internal device data into standardized FHIR® (Fast Healthcare Interoperability Resources) Observations to enable compatibility with healthcare data solutions in Microsoft Fabric and other health data ecosystems. This service is implemented in Microsoft Azure Cloud and designed to ingest structured payloads from Life365-connected medical devices —including blood pressure monitors, weight scales, and pulse oximeters— and convert them into FHIR®-compliant formats in real time. When a reading is received: The service identifies relevant clinical metrics (e.g., systolic/diastolic blood pressure, heart rate, weight, SpO₂). These metrics are mapped to FHIR® Observation resources using industry-standard LOINC codes and units. Each Observation is enriched with references to the associated patient and device, formatted in NDJSON to meet the ingestion requirements in healthcare data solutions in Fabric. The resulting FHIR®-compliant data is securely transmitted to the Fabric instance using token-based authentication. This implementation provides a consistent, standards-aligned pathway for Life365 device data to integrate with downstream FHIR®-based platforms while abstracting the proprietary structure of the original device payloads. For examples from the public domain, you can use the following open-source projects as references: https://github.com/microsoft/fit-on-FHIR® https://github.com/microsoft/healthkit-to-FHIR® https://github.com/microsoft/FitbitOnFHIR® https://github.com/microsoft/FHIR®-Converter Please note that above open-source repositories might not be up to date. While they may not provide a complete (end to end) solution to map medical device data to FHIR®, they may still be helpful as a starting point. If you decide to incorporate them into your remote patient monitoring integration solution, validate their functionality and make necessary changes to meet your solution’s requirements. For the resulting FHIR® resources to be successfully consumed by the analytics processing later (within healthcare data solutions in Fabric), they need to satisfy the requisites listed below. Each FHIR® resource, in its entirety, needs to be saved as a single row into an NDJSON-formatted file. We recommend creating one NDJSON file per FHIR® resource type. That means creating Device.ndjson, Patient.ndjson, and Observation.ndjson files for the three entities we reviewed above. Each FHIR® resource needs to have a meta segment populated with inclusion of lastUpdated value. As an example: "meta":{"lastUpdated":"2025-05-15T15:35:04.218Z", "profile":["http://hl7.org/FHIR®/us/core/StructureDefinition/us-core-documentreference"]} Cross references between Observation and Patient, as well as between Observation and Device FHIR® resources need to be represented correctly, either through formal FHIR® identifiers or logical identifiers. As an example, the subject and device attributes of Observation FHIR® resource need to refer to Patient and Device FHIR® resources, respectively, in this manner: "subject":{"reference":"Patient/d3281621-1584-4631-bc82-edcaf49fda96"} "device":{"reference":"Device/5a934020-c2c4-4e92-a0c5-2116e29e757d"} For Patient FHIR® resource, if MRN is used as the identifier, it is important to represent the MRN value according to the FHIR® standard. Patient identifier is a critical attribute that it is used to establish cross-FHIR®-resource relationships throughout the analytics processing and consumption phase. We will review that phase later in this article. At a minimum, a Patient identifier, which uses MRN coding as its identifier type, needs to have its value, system, type.coding.system, and type.coding.code (with value “MR”) attributes populated correctly. See an example below. You can also refer to a Patient FHIR® resource example from hl7.org. "reference": null, "type": "Patient", "identifier": { "extension": null, "use": null, "value": "4e7e5bf8-2823-8ec1-fe37-eba9c9d69463", "system": "urn:oid: 1.2.36.146.595.217.0.1", "type": { "extension": null, "id": null, "coding": [ { "extension": null, "id": null, "system": "http://terminology.h17.org/CodeSystem/v2-0203", "version": null, "code": "MR", "display": null, "userSelected": null } "text": null }, ... With Step 3, to perform the transfer of FHIR® resource NDJSON files to healthcare data solutions in Fabric: Ensure that the integration platform (Azure Function App, in our case) has permission to transfer (upload) files to the healthcare data solutions in Fabric: Find the managed identity or the service principal that the Azure Function App is running under: Navigate to the Azure portal and find your Function App within your resource group. In the Function App's navigation pane, under "Settings," select "Identity". Identify the Managed Identity (if enabled): If System-assigned managed identity is enabled, you'll see information about the system-assigned managed identity, including its object ID and principal ID. If User-assigned managed identity is linked, the details of that identity will be displayed. You can also add user-assigned identities here if needed. Service Principal (if applicable): If the Function App is configured to use a service principal, you'll need to look for the service principal within the Azure Active Directory (a.k.a. Microsoft Entra ID). You can find this by searching for "Enterprise Applications" within Azure Active Directory and looking for the application associated with the Function App. Grant Azure Function App’s identity access to upload files: Having been logged into Fabric with an administrator account, navigate to the Fabric workspace where your healthcare data solutions instance is deployed. Click on the “Manage Access” button on the top right. Click on “Add People or Groups” Add the managed identity or the service principal, which is associated with your Azure Function App, with Contributor access by selecting “Contributor” from the dropdown list. Using a coding environment, similar to the Python example provided below, you can manage the OneLake content programmatically. This includes the ability to transfer (upload) the NDJSON-formatted files, which have been created earlier, to the destination OneLake folder. from azure.identity import DefaultAzureCredential from azure.storage.filedatalake import DataLakeFileClient, DataLakeFileSystemClient # Replace with your OneLake URI onelake_uri = "https://your-account-name.dfs.core.windows.net" # Replace with the destination path to your file file_path = "/<full path to destination folder (see below)>/<entity name>.ndjson" # Get the credential credential = DefaultAzureCredential() # Create a DataLakeFileClient file_client = DataLakeFileClient( url=f"{onelake_uri}{file_path}", credential=credential ) # Upload the file with open("<entity name>.ndjson", "rb") as f: file_client.upload_data(f, overwrite=True) print(f"File uploaded successfully: {file_path}") The destination OneLake folder to use for the remote patient monitoring solution integration into healthcare data solutions in Fabric is determined as follows: Navigate to the bronze lakehouse created with the healthcare data solutions instance inside the Fabric workspace. The lakehouse is named as “healthcare1_msft_bronze”. “healthcare1” segment in the name of the lakehouse points to the name of the healthcare data solutions instance deployed in the workspace. You might see a different name in your Fabric workspace; however, the rest of the lakehouse name (“_msft_bronze”) remains unchanged. Unified folder structure of healthcare data solutions is located inside the bronze lakehouse. Within that folder structure, create a subfolder named with the name of the remote patient monitoring solution you are integration with. See the screenshot below. This subfolder is referred to as namespace in healthcare data solutions documentation, and is used to uniquely identify the source of incoming (to-be-uploaded) data. NDJSON files, which have been generated during the previous interoperability phase, will be transferred (uploaded) into that subfolder. The full path of the destination OneLake folder to use in your file transfer (upload) code is: healthcare1_msft_bronze.Lakehouse\Files\Ingest\Clinical\FHIR®-NDJSON\<Solution-Name-as-Namespace> Analytics Processing and Consumption Phase Step 1 of this phase connects the interoperability phase discussed earlier with the analytics processing and consumption phase. As part of this step, you can simply verify that the NDJSON files have been uploaded to the remote patient monitoring solution subfolder inside the unified folder structure in bronze lakehouse of healthcare data solutions in Fabric. The path to that subfolder is provided earlier in this article. After the upload of the files has been completed, you are ready to run the data pipeline that will perform data ingestion and transformation so that the device readings data may be used for analytics purposes. In the Fabric workspace, where healthcare data solutions instance is deployed, find and open the data pipeline named “healthcare1_msft_omop_analytics”. As is the case with the bronze lakehouse name, “healthcare1” segment in the name of the data pipeline points to the name of the healthcare data solutions instance deployed in the workspace. You might see a different name in your Fabric workspace depending on your own instance. This data pipeline will execute four activities, first of which will copy the transferred files into another subfolder within unified folder structure so that they can be input to the ingestion step next. Then, the subsequent pipeline activities perform steps 2 through 4 as illustrated in the analytics processing and consumption phase diagram further above. Step 2 ingests the content from the transferred (NDJSON) file(s) to the ClinicalFHIR delta table of the bronze lakehouse. Step 3 transforms the content from the ClinicalFHIR delta table of the bronze lakehouse into flattened FHIR® data model content inside silver lakehouse. Step 4 transforms the flattened FHIR® content of silver lakehouse into OMOP data model content inside gold lakehouse. As part of step 5, you can develop your own gold lakehouse(s) through transforming content from the silver lakehouse into data model(s) best suited for your custom analytics use cases. Device data, once transformed into a gold lakehouse, may be used for analytics or reporting through several ways some of which are discussed briefly below. In step 6, Power BI reports and dashboards can be built inside Fabric that offer a visual and interactive canvas to analyze the data in detail. (Overview of Power BI - Microsoft Fabric | Microsoft Learn) As part of step 7, Fabric data share feature can be used to grant teams within external organizations (that you collaborate with) access to the data (External data sharing in Microsoft Fabric - Microsoft Fabric | Microsoft Learn). Finally, step 8 enables you to utilize the discover and build cohorts capability of healthcare data solutions in Fabric. With this capability, you can submit natural language queries to explore the data and build patient cohorts that fit the criteria that your use cases are aiming for. (Build patient cohorts with generative AI in discover and build cohorts (preview) - Microsoft Cloud for Healthcare | Microsoft Learn) Conclusion When integrated with healthcare data solutions in Fabric, remote patient monitoring solutions can enable transformative potential in enhancing patient outcomes, optimizing care coordination, and streamlining healthcare system operations. If your organization would like to explore the next steps in such a journey, please contact your Microsoft account team.What's new in SQL Server 2025
Add deep AI integration with built-in vector search and DiskANN optimizations, plus native support for large object JSON and new Change Event Streaming for live data updates. Join and analyze data faster with the Lakehouse shortcuts in Microsoft Fabric that unify multiple databases — across different SQL Server versions, clouds, and on-prem — into a single, logical schema without moving data. Build intelligent apps, automate workflows, and unlock rich insights with Copilot and the unified Microsoft data platform, including seamless Microsoft Fabric integration, all while leveraging your existing SQL skills and infrastructure. Bob Ward, lead SQL engineer, joins Jeremy Chapman to share how the latest SQL Server 2025 innovations simplify building complex, high-performance workloads with less effort. Run natural language semantic search directly in SQL Server 2025. Vector search and DiskANN work efficiently on modest hardware — no GPU needed. Get started. Run NoSQL in SQL. Store and manage large JSON documents directly in SQL Server 2025. Insert, update, and query JSON data with native tools. Check it out. Avoid delays. Reduce database locking without code changes to keep your apps running smoothly. See the new Optimized Locking in SQL Server 2025. QUICK LINKS: 00:00 — Updates to SQL Server 2025 00:58 — Search and AI 03:55 — Native JSON Support 06:41 — Real-Time Change Event Streaming 08:40 — Optimized Locking for Better Concurrency 10:33 — Join SQL Server data with Fabric 13:53 — Wrap up Link References Start using SQL Server 2025 at https://aka.ms/GetSQLServer2025 Unfamiliar with Microsoft Mechanics? As Microsoft’s official video series for IT, you can watch and share valuable content and demos of current and upcoming tech from the people who build it at Microsoft. Subscribe to our YouTube: https://www.youtube.com/c/MicrosoftMechanicsSeries Talk with other IT Pros, join us on the Microsoft Tech Community: https://techcommunity.microsoft.com/t5/microsoft-mechanics-blog/bg-p/MicrosoftMechanicsBlog Watch or listen from anywhere, subscribe to our podcast: https://microsoftmechanics.libsyn.com/podcast Keep getting this insider knowledge, join us on social: Follow us on Twitter: https://twitter.com/MSFTMechanics Share knowledge on LinkedIn: https://www.linkedin.com/company/microsoft-mechanics/ Enjoy us on Instagram: https://www.instagram.com/msftmechanics/ Loosen up with us on TikTok: https://www.tiktok.com/@msftmechanics Video Transcript: - Today we’ll look at the AI integration developer updates and performance improvements that make SQL Server 2025 a major upgrade. We’ve got a lot to unpack here, so we’re going to waste no time and get straight into this with lead SQL engineer, Bob Ward. Welcome back to the show. - So great to be back. - So SQL Server 2025, it’s brand new. It’s in public preview right now. So what’s behind the release and what’s new? - There are three major areas of updates that we focus on in this release. First, we have deep AI integration. For example, we now have built-in vector search support for more accurate and efficient data retrieval with some under the hood optimizations using DiskANN. Second, if you’re a developer, this is the most significant release of SQL in the last decade. You know, some of the highlights are native support for JSON files and new change event streaming capabilities for real-time updates. And the third area is improved analytics, where we’re going to make it easy to mirror your SQL Servers into Microsoft Fabric without moving the data. - And all of these are very significant updates. So why don’t we start with what’s new in search and AI? - Great, let’s get going. As I’ve mentioned, we’ve integrated AI directly into the database engine to give you smarter, intelligent searching. With vector search capabilities built-in, you can do semantic search over your data to find matches based on similarity versus keywords. For example, here I have a database with a table called ProductDescription, and I want to search using SQL queries against the Description table for intelligent search. Typically, you’d use full text search for this. Now I’ve built this out, but what about these natural language phrases, Will they work? They don’t. And even when I use like clauses, as you can see here, or contains, or even freetext, none of these methods returns what I’m looking for. Instead, this is where natural language with vector search in SQL Server 2025 shines. As a developer, I can get started even locally on my laptop, no GPU required. I’m using the popular framework, Ollama, to host a free open-source embeddings model from Hugging Face. This will convert our data into vectors, including query prompts, and I declare it using this CREATE EXTERNAL MODEL statement. Then I’m able to go in and build a table using the new built-in vector type to store what’s called embeddings in a binary format. My table has keys pointing back to my description data and then I can use a built-in T-SQL function to generate embeddings based on Ollama and store them. For vector search to work, I need to create a vector index, and it’s also performance optimized using Disk approximate nearest neighbor, or DiskANN, which is a new way to offload what you’d normally want to run completely in memory to point to an index stored on disk. I have a stored procedure to convert the query prompts into embeddings so it can be used to find matching embeddings in the vector index. So now I have everything running locally on my laptop running SQL. Let’s see how it works. I’ll try this natural language prompt, like I showed earlier. And it worked. I get a rich set of results, with matching information based on my search to find products in the database. And I can even use Copilot from here to explore more about SQL data. I’ll prompt it to look for my new table. And you can see, response here, finding our new table. And I can ask it to pull up a few embedding values with product names and descriptions. And as you saw the result using our open source embeddings returned a few languages back. And the good news is that if your data contains multiple languages, it’s easy to use different embedding models. For example, here I’ve wired up Azure OpenAI’s ADA 2 embeddings model optimized for multiple languages without even changing my code. And now I can even search using Mandarin Chinese and get back matching results. - And DiskANN and vector-based search are both massive updates that really go hand in hand to enable better natural language querying on modest hardware. So what about all the developer updates? - With these updates, things get so much more efficient for developers. With JSON file types, you can bring NoSQL into your SQL relational database. Let me show you how. I’ve created a database called Orders and a table called Orders. Notice here the new JSON data type, which can store up to a massive two gigabytes of JSON document in this native data type. Now let’s look at a couple of examples. First, I can easily insert JSON documents in their native format directly into the table, and I’ll show you some of the JSON functions that you can do to process this new JSON type. JSON value will pull a particular value out of a JSON document and bring it back in result set format. And I can just dump out all the JSON values, so each document will appear as a separate row in their native JSON format. But instead of just doing that, I have aggregate functions. This takes all the rows of JSON types in the table and produces a single array with a single JSON document with all the new rows in the native JSON type. Key-value pairs are also popular in JSON, and I can use the new OBJECT AGGREGATE function to take the order ID key and the JSON document and produce a set of key-value pairs. And I can modify the JSON type directly from here too. Notice, for order_id 1, the quantity is also 1. I’ll run this update to modify the value. And when it’s finished, the order_id, quantity has been updated with the value of 2 directly in the JSON. Now that’s a good example of using the JSON type. So let me show you how this works with a JSON index. I’ve got a different database for contacts, along with the table for contacts using a JSON document as one of the properties of the contacts table. I can create a JSON index on top of that JSON document, like this. Now I’ve got some sample data that are JSON documents. And in a second, I’m going to push those into our database. And as I scroll, you’ll that this has nested tags as properties in the JSON document. Now I’ll run the query so I can insert these rows with the names of each tag. Let’s go look at the output. I’m using JSON value for the name, but I’m using JSON query because the tags are nested. Now I’ll show you an example searching with the JSON index. I’m using the new JSON contains function to find tags called fitness that are deep nested in the JSON document. And I can run that and find the right tags and even the execution plan. You can see here that it shows we’re using the new JSON index to help go find that information. - That’s a big deal. And like you said, there’s a lot happening natively in JSON, and now you’ve got the benefits of SQL for joins, and security, and a lot more, - You know, and for developers who use change data capture, things become a lot easier with change event streaming. Here, we’re reducing I/O overhead and sending transaction log changes directly to your application. To get started with change event streaming for our orders database, I’ll run the stored procedure to enable streaming for the database. You can see the table we’re going to use to track changes is a typical type of orders table. Here I’ve created what’s called an event stream group. This is where I’ve configured event streaming to tell it the location of our Azure event hub to stream our data, and I’ve added my credentials. Then I’ve configured the table orders to be part of the event streaming group. I’ve run these procedures to make sure that my configuration is correct. So let’s do something interesting. I’m going to automate a workflow using agents to listen for changes as they come in and try to resolve any issues. First, I’ve created an Azure function app, and using my function app, I have an agent running in the Azure AI service called ContosoShippingAgent. It’s built to take shipment information, analyze it, and decide whether something can be done to help. For example, resolving a shipping delay. I’ve started my Azure function. This function is waiting for events to be sent to Azure Event Hub in order to process them. Now, in SQL, I’ll insert a new order. Going back over to my Azure function, you’ll see how the event is processed. In the code, first, we’re dumping up the raw cloud event that I showed earlier. Notice the operation is an insert. It’s going to dump out some of the different fields we’ve parsed out of the data, the column names, the metadata, and then the row itself. Notice that because the shipment is 75 days greater than our sales date, it will call our agent. The agent then comes back with a response. It looked at the tracking details and determined that it can change the shipping provider to expedite our delayed shipment, and it contacted the customer directly with the updating shipping info. - And everybody likes faster shipping. So speaking of things that are getting faster, it’s kind of a tradition on Mechanics that we cover the speed ups for SQL Server. So what are the speed ups and the performance optimizations for ‘25? - Well, there’s a lot, but my favorite one improves application concurrency. We’ve improved the internals of how locking works without application code changes. And I’ve got an example of this running. I have a lock escalation problem that I need to resolve. I’m going to go update about 2,500 rows in this table just to show what happens, then how we’ve solved for it. So running this query against that Dynamic Management View, or DMV, shows locks that have accumulated, about 2,500 locks here for key-value locks and 111 for page locks. So what happens if I run enough updates against the table that would cause a lock escalation? Here, I’ll update 10,000 rows in the system. But you can see with the locks that this has been escalated to an object lock. It’s not updating the entire table, but it’s going to cause a problem. Because I’ve got a query over here that can update the maximum value in just one row and it’s going to get blocked, but it shouldn’t have to be. You can see here from the blocking query that’s running that it’s blocked on that original session, and I’m not actually updating a row that’s affected by the first one. This is the problem with lock escalation. Now let’s look at a new option called optimized locking in SQL Server 2025. Okay, let’s go back to where I updated 10,000 rows and look at the lock. Notice how in this particular case I have a transaction lock. It’s an intent exclusive lock for the table, but only a transaction lock for that update. If I use this query to update the max, you’ll see that we are not blocked. And by looking at the locks, each item has specific transaction locks, so we’re not blocking each other. And related to this, we’ve also solved another problem where two unrelated updates can get blocked. We call this lock after qualification. - Okay, so it’s pinpointing the exact lock type, so you’ll get less locks in the end. So why don’t we move on though from locks to joins? - Sure. With Microsoft Fabric, it’s amazing. You can pull in multiple databases, multiple data types into a unified data platform. Imagine you have two different SQL Servers in different clouds and on-prem, and you just want to join this data together in an easy way without migrating it. With Fabric, you can. I have a SQL Server 2022 instance with a database, and we’ve already mirrored the product tables from that database into Fabric. I’ll show you the mirroring configuration process for a SQL Server 2025 instance with different, but related tables. These are similar to the steps from mirroring any SQL Server. I’ve created a database connection for SQL Server 2025. Now I’ll pick all the tables in our database and connect. I’ll leave the name as is, AdventureWorks, and we’re ready to mirror our database. You can see now that the replication process has started for all the tables. All the rows have been replicated for all the columns on all the tables in my database and they’ve been mirrored into Fabric. Now let’s query the data using the SQL analytic endpoint. And you can see that the tables that we have previously had in our database and SQL Server are now mirrored into OneLake. Let’s run a query and I’ll use Copilot to do that. Here’s the Copilot code with explanations. Now I’ll run it. And as it completes, there’s our top customers buy sales. Now what if we wanted to do a join across the other SQL server? It’s possible. But normally, there are a lot of manual pieces to do this. Fabric can make that easier using a lakehouse. So let’s create a new lakehouse. I just didn’t to give it a name, AdventureWorks, and confirm. Now notice there are no tables in this lakehouse yet, so let’s add some. And for that, I’ll use a shortcut. A shortcut uses items in OneLake, like the SQL Server databases we just mirrored. So I’ll add the AdventureWorks database. And scrolling down, I’ll pick all the tables I want. Now I’ll create it. And we’re not storing the data separately in the lakehouse. It’s just a shortcut, like an active read link to the source data, which is our mirrored database, and therefore something that already exists in OneLake. And now you can see I’ve got these objects here. This icon means that these are shortcut from another table. So now, let’s get data from another warehouse. The SQL Server 2022 instance, which was ADW_products. Again, here, I’ll pick the tables that I want and Create. That’s it. So I can go and look at product to make sure I’ve got my product data. Now, let’s try to query this as one database and use another analytic endpoint directly against the lakehouse itself. So basically it thinks all the tables are just part of the unified schema now. Let’s open up Copilot and write a prompt to pull my top customers by products and sales. And it will be able to work directly against all of these connected databases because they are in just the same schema. And there you go. I have a list of all the data I need in one logical database. - And this is really great. And I know now that everything’s in OneLake, there’s also a lot more that you can do with that data. - With the lakehouse, the sky’s the limit. You can use Power BI, or any of those services that are in the unified data platform, Microsoft Fabric. - Okay, so now we’ve seen all the updates with SQL Server 2025. To everyone watching, what’s the best thing they can do to get started? - Well, the first thing is to start using it. SQL Server 2025 is ready for you to download and install it on the platform of your choice. You’ll find it at aka.ms/GetSQLServer2025. - So thanks so much for sharing all the updates, Bob, and thank you for joining us today. Be sure to subscribe for more, and we’ll see again soon.994Views0likes0CommentsWhat’s Included with Microsoft’s Granted Offerings for Nonprofits?
Are you a nonprofit looking to boost your impact with cutting-edge technology? Microsoft is here to help! From free software licenses to guided technical documentation and support, this program offers a range of resources designed to empower your organization. In this blog, we’ll dive into the incredible tools and grants available to nonprofits through Microsoft, showing you how to make the most of these generous offerings. Whether you’re managing projects or just trying to simplify your day-to-day tasks, there’s something here for everyone. Let’s explore what’s possible!2.7KViews0likes1Comment