infrastructure
199 Topics
From Prompt to Production: Building Azure Architecture Diagrams with AI
Author: Arturo Quiroga, Senior Partner Solutions Architect — Microsoft Cloud architects spend significant time translating ideas into architecture diagrams. They toggle between Visio, draw.io, pricing calculators, and documentation. According to the 2024 Stack Overflow Developer Survey, 61% of developers spend more than 30 minutes a day searching for answers or solutions, time lost to context-switching rather than design. What if you could describe your architecture in plain English and get a diagram, cost estimate, and deployment guide in minutes? The Challenge: Fragmented Architecture Workflows Designing Azure architectures today typically involves multiple disconnected steps: Sketch the architecture in a diagramming tool Look up official Azure icons and drag them into place Research pricing across regions using the Azure Pricing Calculator Validate the design against the Well-Architected Framework (WAF) Write deployment documentation and Infrastructure as Code templates Compare alternative designs manually Each step lives in a different tool, and keeping them in sync as designs evolve is costly. The Azure Architecture Diagram Builder brings these workflows together in a single browser-based experience. How It Works Describe your architecture in natural language, for example "A HIPAA-compliant healthcare platform with FHIR APIs, event-driven processing, and multi-region disaster recovery", and the AI generates a diagram with grouped services, data flow connections, and logical organization. Figure 1. Enter a natural-language prompt describing your architecture. Curated example prompts help you get started, and you can optionally upload an existing diagram for the AI to analyze. The tool uses Azure OpenAI to power generation across multiple models, enabling you to choose the model that best fits your scenario — from fast iterations to deeper reasoning. Key Features AI-Powered Architecture Generation Describe what you need in plain English, and the AI creates an architecture diagram with: 714 official Azure service icons across 29 categories Smart grouping: services are logically organized (Frontend, Backend, Data, Security) Data flow connections: labeled edges showing how data moves through the system 13 curated example prompts: from simple web apps to complex enterprise scenarios like Zero Trust networks, Industrial IoT with 5,000+ sensors, and global multiplayer gaming backends Figure 2. A generated industrial IoT architecture. Top: the clean diagram view as initially produced. Bottom: the same diagram with per-service monthly cost overlays toggled on, plus a running subscription total in the toolbar. Architecture Image Import Already have an architecture on a whiteboard or in a screenshot? Upload the image and let the AI analyze it, mapping services to official Azure icons and recreating the architecture as an editable, interactive diagram. Figure 3. Upload a photo of a whiteboard sketch (top-right reference panel) and the AI recreates it as an editable diagram with official Azure service icons and labeled data flow connections. ARM Template Import Import existing ARM templates to visualize your current infrastructure. The AI parses resource definitions and dependencies, groups related resources into logical layers, and produces a meaningful diagram of what you actually have deployed — a fast way to document an inherited environment or sanity-check a template before deployment. Figure 4. ARM template import in action. Top: the parser status banner while resources and dependencies are being analyzed. Bottom: the resulting diagram, with resources auto-grouped into logical layers (Web Tier, Data Layer, Container Platform, Observability & Logging) and a Generated from: ARM Template badge linking the diagram back to its source file. Well-Architected Framework Validation Validate your architecture against all five WAF pillars — Security, Reliability, Performance Efficiency, Cost Optimization, and Operational Excellence. The validator provides: An overall WAF score with pillar-level breakdowns Specific findings with severity levels Actionable recommendations you can select and apply Select the recommendations you agree with, and the AI regenerates an improved architecture incorporating those changes. Figure 5. WAF validation results showing the overall score, per-pillar breakdowns, and individual findings with severity badges. Tick the recommendations you want and the AI rebuilds the diagram with those changes applied. Multi-Model Comparison Run the same architecture prompt through multiple AI models side-by-side and compare: Architecture Comparison: service counts, connection counts, groups, token usage, and latency Validation Comparison: WAF scores across models, severity breakdowns, and finding counts Apply Winner: pick the best result and apply it to the canvas with one click Present Critique: a talking avatar narrates the AI-generated ranking with live closed captions Figure 6. Multi-model comparison. Top: select the models and reasoning effort, then enter the prompt. Bottom: side-by-side results across all selected models with service counts, latency, token usage, and Fastest / Cheapest / Most Thorough badges. Multi-Region Cost Estimation Get cost estimates from the Azure Retail Prices API across 8 Azure regions: East US 2, Australia East, Canada Central, Brazil South, Mexico Central, West Europe, Sweden Central, and Southeast Asia. Features include: Color-coded cost legend (green / yellow / red thresholds) SKU and tier information for each service Export options: CSV, JSON, plain-text summary, and an analysis report with top cost drivers, Reserved Instance flags, and a ranked multi-region comparison table Figure 7. The cost legend overlay shows per-service pricing with color-coded thresholds. The region selector in the toolbar lets you re-price the entire architecture in any of eight Azure regions. Deployment Guide Generation with Bicep Generate step-by-step deployment documentation including: Prerequisites and Azure resource requirements Step-by-step deployment instructions Bicep templates for each service (Infrastructure as Code) Post-deployment verification steps Security configuration recommendations Figure 8. Each generated Deployment Guide opens with the architecture name, an estimated deployment time, and a prerequisites checklist covering subscription roles, CLI versions, Microsoft Entra ID permissions, and region requirements, followed by numbered, copy-ready deployment steps. Figure 9. The Infrastructure as Code section produces a main.bicep orchestrator plus a per-service module (Log Analytics, Key Vault, Cosmos DB, SQL Database, Event Hubs, Azure Functions, and more). The Download All Templates button packages everything into a ready-to-deploy folder. Workflow Animation & Avatar Presenter Visualize how data flows through your architecture with step-by-step animations that highlight services on the canvas as each step plays. When the Azure Speech Service is configured, a photorealistic talking avatar can narrate the workflow or present model comparison results, with live word-by-word closed captions in a draggable, resizable panel. Figure 10. A workflow step is highlighted on the canvas as the Avatar Presenter narrates that step. Live word-by-word closed captions appear in a draggable, resizable panel, useful for accessibility and stakeholder demos. Export Options Figure 11. A single-slide PowerPoint export, available in dark or light theme, ready to drop straight into a stakeholder deck. Format Use Case PNG Documentation, presentations SVG Scalable vector graphics PPTX Single PowerPoint slide (dark or light theme) Draw.io Edit in diagrams.net JSON Backup, version control CSV / ZIP Cost analysis with multi-region comparison Highlights The Azure Architecture Diagram Builder unifies the architecture design lifecycle in a single tool: End-to-end workflow: from natural-language description to deployable Bicep templates without tool switching Official Azure icons: 714 icons across 29 categories, mapped directly from the Azure service catalog Live pricing: queries the Azure Retail Prices API at design time rather than relying on static estimates WAF-integrated validation: architectural best practices built into the design loop rather than applied after the fact Multi-model flexibility: choose the AI model that best suits each task, with fast models for iteration and reasoning models for complex designs Open source: the source code is available for customization and contribution One-Command Deploy with Azure Developer CLI The fastest way to get your own instance running is with azd : # Install azd (once) brew tap azure/azd && brew install azd # macOS winget install microsoft.azd # Windows # Clone, configure, and deploy git clone https://github.com/Arturo-Quiroga-MSFT/azure-architecture-diagram-builder cd azure-architecture-diagram-builder azd auth login azd env set AZURE_OPENAI_ENDPOINT "https://your-resource.openai.azure.com/" azd env set AZURE_OPENAI_API_KEY "your-key" azd up # Provisions infrastructure + builds + deploys (~8 min) azd up provisions the following via Bicep: Resource Purpose Azure Container Registry Stores the Docker image Azure Container Apps Runs the app (nginx + token server) Log Analytics + Application Insights Monitoring and telemetry Azure Speech (S0) Avatar Presenter (optional, keyless auth via managed identity) Try It Today The Azure Architecture Diagram Builder is available now: Live demo: https://aka.ms/diagram-builder Source code: GitHub repository Documentation: See the Getting Started Guide for detailed setup instructions We welcome feedback and contributions. Use the GitHub Issues page to report bugs, suggest features, or share your experience. Tags: artificial intelligence · application · apps & devops · well architected · infrastructure5.8KViews3likes4CommentsFrom Features to Flow: How Real-World Adoption Reshaped the Azure Architecture Diagram Builder
In May, I introduced the open-source Azure Architecture Diagram Builder as a way to move from a natural-language prompt to an Azure architecture diagram, cost estimate, Well-Architected assessment, and deployment guidance. In July, I shared how the project had become agent-ready through Model Context Protocol (MCP). Those posts described what the tool could do. The more interesting story came next: what happened when people actually used it. As adoption grew, the central product question changed. It was no longer simply, Can AI generate an Azure architecture? It became: How do we help an architect choose how to begin, improve a result without losing their work, validate it responsibly, and turn it into something another person can use? That question reshaped the Azure Architecture Diagram Builder from a collection of capabilities into a guided workflow: Create → Refine → Validate & Improve → Share or Build This post explains what we learned, what changed in the product, and why the hardest part of AI-assisted architecture is not the first diagram. It is everything that comes after it. TL;DR. Growing adoption created a feedback loop. Aggregate usage showed that people moved beyond generation into validation, recommendations, exports, and deployment guidance. Privacy-safe feedback revealed recurring problems with diagram integrity, preservation of human edits, cost credibility, export quality, and validation continuity. Those signals led to a four-stage architecture journey that keeps human judgment and professional review at the center. The same lesson now shapes agent access and the next product boundary: distinguish logical proposals from evidence-backed physical architecture. Adoption created a product feedback loop As of August 5, 2026, the first two Azure Architecture Blog articles had accumulated approximately 12,100 combined views. A refreshed view of deduplicated application telemetry through August 13 recorded: Activity Aggregate count Architecture generation and refinement events 5,023 Well-Architected validations 960 Recommendations applied 175 Diagram exports 2,020 Deployment guides generated 212 As of August 13, the public repository had reached 45 stars and 14 forks. In GitHub’s current rolling 14-day window, the repository recorded 277 unique visitors and 67 unique cloners. These numbers measure different things and should not be added together. Article views are not unique readers. Application activity uses anonymous telemetry identifiers, not verified people. GitHub traffic is a rolling aggregate window. The signals are useful because of the pattern they reveal, not because they can be combined into one headline user count. Activity also accelerated during the period following the second article. Compared with the May 19–July 9 baseline, daily activity from July 10 through August 13 was approximately 7.0 times higher for architecture generation and refinement, 5.6 times higher for Well-Architected validation, and 5.9 times higher for recommendation application. The timing coincided with publication; it does not prove that the article alone caused the growth. The important product lesson was simpler: people were not stopping after the first diagram. They were testing alternatives, validating designs, applying recommendations, exporting artifacts, and asking how to move toward implementation. Generation was the entry point, not the complete job. The first guided-journey signals reinforce the need for more than one starting path. Through August 13, the new journey instrumentation recorded 880 interactions from 174 anonymous identifiers across 241 sessions. At first start, structured brief/image generation and Guided Chat were selected at almost the same frequency (158 and 156 events), while template and live-Azure import added another 68 selections. These are interaction counts, not unique people or conversion rates, and the window is still too early to claim that the journey improves completion. They are enough to show that architecture work does not begin in one uniform way. In-product Start Here panel showing the four-stage Azure Architecture Diagram Builder journey: Create, Refine, Validate and Improve, and Share or Build. Figure 1. The in-product Start Here panel explains one complete architecture loop. The stages are recommendations, not gates, and direct access to every tool remains available. Stage 1: Create — make the starting choice explicit As capabilities accumulated, the first screen became harder to interpret. Architecture Chat and structured generation were both useful, but they competed for attention. Importing an existing architecture was available, yet easy to miss. The new starting experience makes three paths explicit: Starting path Best suited for Guided Chat Exploring requirements conversationally and refining them over multiple turns Generate Diagram Providing a structured brief or image and producing a first architecture quickly Import Existing Opening an existing architecture or infrastructure artifact for analysis and editing This is not a marketing landing page placed in front of the tool. It is a small decision point inside the authoring experience. Once a path is selected, the user lands on the real canvas. The distinction matters because different architecture tasks begin with different levels of certainty. Sometimes the architect knows the target services. Sometimes the problem needs discovery. Sometimes the architecture already exists and the work is to understand or improve it. The product should acknowledge those differences instead of pretending every design starts with a perfect prompt. Start chooser presenting Guided Chat, Generate Diagram, and Import Existing as three equal entry paths. Figure 2. Three starting paths reflect three different architecture situations: discovery, structured generation, and analysis of an existing design. Stage 2: Refine — preserve human work One of the clearest feedback themes was not about adding another AI capability. It was about preventing AI from casually undoing human effort. An architect might spend time arranging a one-page diagram for a review, resizing groups, moving labels, or emphasizing a specific boundary. A subsequent AI refinement could improve the service selection while disrupting that carefully prepared layout. The design principle that emerged was straightforward: AI acceleration should preserve deliberate human work by default. Refinement now retains existing node positions, group geometry, sizes, and viewport context whenever possible. The model can change the architecture without treating every turn as permission to redraw the entire document. The same principle applies beyond geometry: Preserve the prior validation result when recommendations change the architecture. Preserve the active light or dark theme in exported artifacts. Preserve the distinction between the authoring canvas and the presentation deliverable. Preserve user-configured pricing assumptions rather than replacing them with one fixed estimate. This is a broader lesson for AI-assisted tools. A generated result is not the only source of value. The edits, judgments, and communication choices a person adds afterward are part of the artifact too. Before-and-after AADB canvases showing an AI refinement that adds Azure Front Door and WAF while retaining the positions of eight existing services and the anchors of four existing groups. Figure 3. In this controlled synthetic refinement, all eight existing service positions and four group anchors remained unchanged. The containing Application group expanded to accommodate the new edge tier, so preservation does not imply that every group dimension stays fixed. Quality is structural, not only visual A diagram can look polished while still being architecturally confusing. Early feedback exposed cases where a generated service appeared disconnected because a model referenced a display name instead of the service identifier used by the canvas. The correction was not another prompt instruction alone. The application now resolves connection endpoints across identifiers, normalized service names, and service-type aliases. It repairs valid edges, drops invalid or self-referential edges, detects remaining orphan nodes, and records aggregate integrity signals. That creates a more useful definition of diagram quality: Are the services connected as intended? Were any generated edges repaired or dropped? Are there orphaned nodes? Did refinement preserve the existing layout? Did an architecture change receive a fresh validation? Visual polish still matters, especially when an artifact leaves the editor. But structural integrity gives the product something deterministic to test and monitor. Stage 3: Validate & Improve — treat validation as a lifecycle The Azure Well-Architected Framework is most useful when validation becomes iterative rather than ceremonial. The Diagram Builder can assess a proposed design across the five Well-Architected pillars, surface findings, and apply selected recommendations. But that workflow exposed an important state-management problem: when the architecture changed, the prior validation result disappeared along with the obvious route back to revalidation. The updated experience keeps the previous report, marks it Revalidate Needed, and makes clear that the score describes an earlier state of the architecture. A new validation replaces it only after the updated design has been assessed. This distinction prevents a stale score from looking current. It also clarifies what an architecture-level assessment can and cannot prove. A diagram may show that a WAF, cache, backup service, or secondary region exists. It usually cannot prove that purge protection, diagnostic routing, encryption settings, role assignments, health probes, or failover policies are configured correctly. That is why validation findings need to distinguish between: Pattern-level gaps — missing or misplaced architectural components Configuration-level gaps — required settings that must be verified in Infrastructure as Code or the deployed environment Generated scores and recommendations help architects review a design; they do not replace an Azure Well-Architected Review, security review, deployment validation, or professional judgment. Validation result retained after architecture recommendations are applied, with a Revalidate Needed status and action. Figure 4. Architecture changes make a previous validation historical, not useless. The result remains available while the interface clearly asks for a fresh validation. Stage 4: Share or Build — design for the artifact’s destination The editing canvas and the final deliverable serve different purposes. Canvas dots, handles, navigation controls, and selection states help during authoring. They can make an exported diagram feel unfinished. The Diagram Builder now separates those concerns with Plain, Dots, and Grid export backgrounds while preserving the active light or dark theme. The same AADB architecture shown first on the editing canvas with the export menu open and then as the resulting Plain PNG without authoring controls. Figure 5. Authoring and delivery are different contexts. The upper view shows the editable canvas and its real export controls; the lower view is the Plain PNG produced from that same canvas, without editing chrome. Cost language is deliberately qualified. Azure services often combine fixed, usage-based, and configuration-dependent charges. A baseline that includes six numerically priced services but excludes 20 usage-based items is not the total cost of the architecture. The output identifies those exclusions rather than treating missing values as zero. The final stage also includes deployment guides and Infrastructure as Code. Here, honesty about artifact coverage is essential. A generated Bicep file may be a useful starter while still omitting private endpoints, diagnostic settings, failover configuration, or service-specific resources. The artifact should state what it implements, what remains conceptual, and whether Azure Resource Manager validation passed. AI-generated diagrams, costs, validation results, deployment guides, and Infrastructure as Code should all be reviewed and validated before production use. The same journey now extends to agents The MCP server introduced in the previous article makes the Diagram Builder available to agent experiences such as Microsoft Scout. The four-stage journey provides a useful way to think about agent orchestration too: Import or create one canonical architecture. Refine it without silently changing the intended topology. Validate it, apply supported improvements, and revalidate. Render or generate artifacts with explicit coverage and limitations. The current MCP surface exposes 12 tools, three resources, and three reusable prompts. It can normalize an existing architecture, validate and harden it deterministically, estimate regional costs from a dated pricing snapshot, render presentation/technical/cost views, and generate Bicep, Terraform, and deployment guidance. The calling agent still owns orchestration and reasoning; the MCP server is intended to remain a deterministic architecture capability, not a second hidden agent. The native MCP renderer can project one canonical architecture into three communication profiles: Presentation emphasizes the primary request path, reduces supporting labels, and removes pricing. Technical preserves complete connection detail for engineering inspection. Cost retains the focused composition while adding service-level pricing assumptions, a fixed-priced baseline, and explicit exclusions. These are MCP-generated SVG views, not Blueprint diagrams or screenshots of the editable web canvas. The services, connections, and groups remain the same; only the information treatment changes. The AADB MCP renderer projecting the same canonical architecture into presentation, technical, and cost SVG profiles. Figure 6. Native AADB MCP output from one 8-service, 9-connection, 4-group architecture. Presentation prioritizes the story, Technical exposes connection detail, and Cost foregrounds pricing assumptions and exclusions. Recent work on the MCP renderer added purpose-built presentation, technical, and cost profiles. More importantly, testing agent-generated artifacts reinforced an accountability principle: a polished diagram and a compiled Bicep file do not prove deployability. An agent workflow should report whether topology changed, whether validation improved, which services are represented only conceptually, and whether the generated IaC passed Azure preflight. That is more useful than an unsupported claim that a design is production-ready. Trust also includes the tool boundary itself. The hosted MCP endpoints now require a bearer token for real session operations; missing or incorrect credentials are rejected. A shared token is appropriate for the current controlled integration, but it is not the end state for enterprise multi-user access. Entra ID/OAuth, per-client authorization, rotation, and revocation remain future hardening work. Microsoft Scout response after an authenticated Azure Architecture Diagram Builder MCP workflow, showing the tools used, initial and final validation scores, cost scope, Bicep classification, rendered architecture, artifact links, coverage gaps, and no-deployment warning. Figure 7. The guided lifecycle extends beyond the web application. In this synthetic Scout run with GPT-5.6 Sol, the agent used authenticated AADB MCP tools to validate, harden, cost, render, and generate starter artifacts while explicitly reporting coverage gaps and that nothing was deployed. Learning from adoption without identifying people Product learning does not require reconstructing individual identities. The findings behind this article use aggregate, deduplicated application telemetry, public article counters, public repository totals, and paraphrased feedback themes. They do not correlate Application Insights identifiers, feedback records, GitHub accounts, or email addresses. Written feedback remains submittable without contact information. When someone explicitly opts into follow-up, the email address is stored with the feedback record in Cosmos DB and is not sent to normal product telemetry. The current 180-day expiry field is a retention marker; automated deletion must be implemented and verified before describing that retention period as enforced. Those boundaries matter for both product design and public writing: Aggregate activity rather than profiling individuals. Paraphrase themes rather than publishing comments without permission. Keep optional contact consent separate from telemetry. Avoid presenting anonymous identifiers as confirmed people. Avoid claiming that publication timing proves acquisition causality. This is not a claim of legal compliance. It is a product discipline: collect less, preserve user agency, and make only the claims the evidence supports. What changed The guided journey is the visible result, but the deeper change is how the project now evaluates progress. Earlier question Better question Did the model generate a diagram? Did it generate a connected and understandable architecture? Did the user click Validate? Was the current architecture validated, and was it revalidated after changes? Did export start? Did a professional artifact finish generating successfully? Does the IaC compile? What does it actually implement, and does Azure preflight pass? How many features exist? Can an architect understand the next useful step? The model portfolio continued to evolve as well. The production selector now contains 15 configured entries, including MAI-Thinking-1 (Public Preview). But the more consequential changes in this article are deliberately model-independent: preserve human work, keep state and provenance explicit, qualify generated artifacts, and authenticate the tools agents can call. The goal is not to remove flexibility. Architects can still open any tool directly, rearrange the canvas, reject recommendations, change pricing assumptions, or export at any point. The goal is to make the workflow coherent without pretending architecture itself is linear. The next boundary: logical versus physical architecture Recent feedback points to a harder problem than adding another model or export format. Architects working with private Azure AI landing zones need to distinguish shared platform resources from project-owned resources, preserve VNet and subnet boundaries, and reason about CIDRs, NSGs, route tables, private endpoints, DNS, and managed identities. The current Topology mode can show services and relationships, but it should not imply exact physical fidelity when those facts are absent. A useful logical diagram answers what exists and how it interacts. A physical or low-level design must answer where it is deployed, how it is isolated, and which values came from evidence. That is the next technical direction I am exploring: an evidence-aware Physical Architecture view backed by deterministic reconstruction from Terraform plan/state, ARM, or a live Azure inventory. Exact fields would be labeled as observed or resolved; AI suggestions would remain explicitly proposed; unsupported or missing inputs would be reported instead of silently invented. This capability is not shipped today, and it will require its own schema, validation rules, layout, security review, and evaluation set. That distinction matters. The lesson from adoption is not to put every architecture concern into one crowded canvas. It is to make each artifact’s purpose and evidence boundary clear. Try it, challenge it, help shape what comes next The Azure Architecture Diagram Builder remains open source, and the live experience is available today: Live app: https://aka.ms/diagram-builder Source code: github.com/Arturo-Quiroga-MSFT/azure-architecture-diagram-builder Getting started: Documentation and deployment guidance The next phase is to measure whether the guided journey helps people complete the full loop, especially recommendation-to-revalidation and artifact-generation success. In parallel, I am beginning the narrower physical-architecture investigation described above. Both efforts will use aggregate signals, reviewed fixtures, and sufficiently large cohorts rather than individual journey reconstruction. Try the workflow with a real architecture problem. Tell me where the handoffs are unclear, where the diagram loses intent, or where an artifact claims more than it implements. Those are the gaps worth fixing next. Measurement note: Article views are rounded public counters observed August 5, 2026. Application figures use deduplicated retained telemetry through August 13 and anonymous identifiers. GitHub totals and rolling 14-day traffic were observed August 13. The comparison windows are May 19–July 9 and July 10–August 13. These signals have different populations and must not be added together. Timing comparisons show concurrent activity, not causal attribution.1.1KViews1like2CommentsAzure Incident Retrospective - Please register! Session 2 - Tracking ID: SPCX-S1Z
Join our upcoming live webcast for a transparent discussion about this recent Azure service incident led by our engineering teams. Power issue in Southeast Asia Tracking ID: SPCX-S1Z | Impacted: 25-26 August 2026 Same content presented in both sessions: pick the one that works best for your timezone! What to expect 📚 Understand What happened, how we responded, and what we learned 💬 Ask Live Q&A with our engineering experts throughout the session 🛠 Learn The fixes we've put in place and guidance for workload resiliency Choose your session Same content presented at both times: pick the one that works best for your timezone: Session 1 15:30 UTC Thursday, 24 Sept 2026 Register now → Session 2 03:30 UTC Friday, 25 Sept 2026 Register now → 8:30 AM US Pacific (PDT) 11:30 AM US Eastern (EDT) 4:30 PM London (BST) 11:30 PM Beijing (CST) 1:30 AM +1 Sydney (AEDT) 3:30 AM +1 Auckland (NZDT) 8:30 PM -1 US Pacific (PDT) 11:30 PM -1 US Eastern (EDT) 4:30 AM London (BST) 11:30 AM Beijing (CST) 1:30 PM Sydney (AEDT) 3:30 PM Auckland (NZDT) Our engineering leaders Terry Lo Datacenter Operations Manager Southeast Asia Cloud+AI Engineering LinkedIn ↗ ⚠️ Prepare before the livestream Read the Post Incident Review (PIR) ahead of time so you can ask any follow up questions during the live Q&A Helpful resources 🔔 Azure Service Health Alerts Get alerts for relevant incidents by setting up notifications via email, SMS, or webhook 🎥 Past Retrospective Recordings Watch recordings of previous retrospective livestreams 📄 Azure Post Incident Reviews Learn more about PIRs and the retrospective program203Views0likes0CommentsAzure Incident Retrospective - Please register! Session 1 - Tracking ID: SPCX-S1Z
Join our upcoming live webcast for a transparent discussion about this recent Azure service incident led by our engineering teams. Power issue in Southeast Asia Tracking ID: SPCX-S1Z | Impacted: 25-26 August 2026 Same content presented in both sessions: pick the one that works best for your timezone! What to expect 📚 Understand What happened, how we responded, and what we learned 💬 Ask Live Q&A with our engineering experts throughout the session 🛠 Learn The fixes we've put in place and guidance for workload resiliency Choose your session Same content presented at both times: pick the one that works best for your timezone: Session 1 15:30 UTC Thursday, 24 Sept 2026 Register now → Session 2 03:30 UTC Friday, 25 Sept 2026 Register now → 8:30 AM US Pacific (PDT) 11:30 AM US Eastern (EDT) 4:30 PM London (BST) 11:30 PM Beijing (CST) 1:30 AM +1 Sydney (AEDT) 3:30 AM +1 Auckland (NZDT) 8:30 PM -1 US Pacific (PDT) 11:30 PM -1 US Eastern (EDT) 4:30 AM London (BST) 11:30 AM Beijing (CST) 1:30 PM Sydney (AEDT) 3:30 PM Auckland (NZDT) Our engineering leaders Terry Lo Datacenter Operations Manager Southeast Asia Cloud+AI Engineering LinkedIn ↗ ⚠️ Prepare before the livestream Read the Post Incident Review (PIR) ahead of time so you can ask any follow up questions during the live Q&A Helpful resources 🔔 Azure Service Health Alerts Get alerts for relevant incidents by setting up notifications via email, SMS, or webhook 🎥 Past Retrospective Recordings Watch recordings of previous retrospective livestreams 📄 Azure Post Incident Reviews Learn more about PIRs and the retrospective program192Views0likes0CommentsBring Azure AI to your private workloads on Azure VMware Solution
Overview A global enterprise has migrated thousands of VMware vSphere virtual machines (VMs) to Microsoft Azure as part of their application modernization strategy. Having exited their on-premises data centers and relocated their legacy application VMs to Azure VMware Solution, the next phase of that strategy is no longer about where the workloads run, but about what the organization can do with the data inside them. Those applications hold the enterprise's most valuable data, yet they sit on private networks that Azure AI services cannot reach by default. What should Azure VMware Solution look like when the goal is to make private workloads AI-accessible in place? Azure VMware Solution is a VMware validated first party Azure service from Microsoft that provides private clouds containing VMware vSphere clusters built from dedicated bare-metal Azure infrastructure. It enables customers to leverage their existing investments in VMware skills and tools, allowing them to focus on developing and running their VMware-based workloads on Azure. That is why organizations move their VMware estates to Azure VMware Solution in the first place: they get to modernize on their own terms, lifting and shifting mission-critical applications into Azure exactly as they run today, with no rewrites, no re-platforming, and no big-bang migration. Azure AI Foundry is the Azure platform for building, deploying, and governing AI agents, providing managed model deployments, an agent runtime, tool integration, and end-to-end tracing under Microsoft Entra identity. Agents in Foundry reach external systems through the Model Context Protocol (MCP), an open standard that describes a system to an agent as a small, explicit set of tools. MCP matters here because it turns "connect the agent to a workload" into a contract rather than a custom integration: the agent learns one way to ask, and each workload is fronted by a server that translates it. But the "leave it as it is" strength of Azure VMware Solution has a quiet side effect. The systems holding your most valuable data, such as core databases, file servers, and line-of-business applications, keep running on private networks inside the private cloud. Meanwhile, Azure's AI services live in the Azure control plane and, by default, reach only public endpoints. When the mandate arrives to "add AI everywhere," your Azure VMware Solution workloads are often the one place AI cannot reach. Not because the data isn't valuable, but because it's private by design. In this post, I will introduce the challenge of reaching private workloads with Azure AI, describe the Azure VMware Solution and Azure AI Foundry architectural components that close the gap, and describe the security and design considerations for doing it safely. The pattern is deliberately workload-agnostic: a managed agent in Azure AI Foundry that reaches private Azure VMware Solution systems through small, purpose-built bridges, one per workload type, while your data stays put, read-only, and inside your network. I will prove it with a working SQL example (two private databases behind a single bridge), then show how the same pattern extends to file shares, APIs, and beyond. The full deployment kit is on GitHub, so you can try it in your own environment. In the next section, I will introduce the architectural components of Azure VMware Solution. Architectural Components The diagram below describes the architectural components of the Azure VMware Solution. Figure 1 – Azure VMware Solution Architectural Components Each Azure VMware Solution architectural component has the following function: Azure Subscription: Used to provide controlled access, budget, and quota management for the Azure VMware Solution. Azure Region: Physical locations around the world where we group data centers into Availability Zones (AZs) and then group AZs into regions. Azure Resource Group: Container used to place Azure services and resources into logical groups. Azure VMware Solution Private Cloud: Uses VMware software, including vCenter Server, NSX-T Data Center software-defined networking, vSAN software-defined storage, and Azure bare-metal ESXi hosts to provide compute, networking, and storage resources. Azure NetApp Files, Azure Elastic SAN, and Pure Cloud Block Store are also supported. Azure VMware Solution Resource Cluster: Uses VMware software, including vSAN software-defined storage, and Azure bare-metal ESXi hosts to provide compute, networking, and storage resources for customer workloads by scaling out the Azure VMware Solution private cloud. Azure NetApp Files, Azure Elastic SAN, and Pure Cloud Block Store are also supported. VMware HCX: Provides mobility, migration, and network extension services. VMware Site Recovery: Provides Disaster Recovery automation and storage replication services with VMware vSphere Replication. Third party Disaster Recovery solutions Zerto Disaster Recovery and JetStream Software Disaster Recovery are also supported. Dedicated Microsoft Enterprise Edge (D-MSEE): Router that provides connectivity between Azure cloud and the Azure VMware Solution private cloud instance. Azure Virtual Network (VNet): Private network used to connect Azure services and resources together. Azure Route Server: Enables network appliances to exchange dynamic route information with Azure networks. Azure Virtual Network Gateway: Cross premises gateway for connecting Azure services and resources to other private networks using IPSec VPN, ExpressRoute, and VNet to VNet. Azure ExpressRoute: Provides high-speed private connections between Azure data centers and on-premises or colocation infrastructure. Azure Virtual WAN (vWAN): Aggregates networking, security, and routing functions together into a single unified Wide Area Network (WAN). Those components describe where your workloads run. In the next section, I will introduce the pattern that makes the data inside them reachable by Azure AI, without changing any of it. The idea in one picture One managed agent in Azure AI Foundry talks to your private Azure VMware Solution workloads through a set of small Model Context Protocol (MCP) servers, one bridge per workload type. SQL databases are live today; a file-share bridge or an API bridge is the same shape with different tools. Figure 2: Solution overview A single managed agent in Azure AI Foundry reaches private Azure VMware Solution workloads through per-workload MCP servers running on VNet-integrated Azure Container Apps, connected to the private cloud over ExpressRoute. Three ideas carry the design: MCP is the universal contract. Every workload is exposed through the same small set of tools. For the SQL bridge, that’s list_sources, get_schema, and run_query. The agent learns one way to ask a question; each bridge translates it for its workload. One lightweight bridge per workload type. Each MCP server is a VNet-integrated Azure Container App that can legitimately see both worlds: Azure on one side, the private Azure VMware Solution network over ExpressRoute on the other. Want to make another workload AI-accessible? Add another bridge. The agent doesn’t change. Managed identity end to end. No passwords in code or config. The agent presents a Microsoft Entra token; each bridge pulls the credentials it needs from Azure Key Vault at runtime. One pattern, every workload The power of the design is that it’s workload-agnostic. The agent, the network path, the Entra identity, and the governance model are built once. Each new workload is just a new MCP server that speaks the same tool contract, so you can light up your estate incrementally, highest-value workloads first, without re-architecting anything. Azure VMware Solution workload MCP bridge Example tools What it unlocks SQL databases (SQL Server, PostgreSQL, Oracle, MySQL) SQL MCP server (live in this post) list_sources, get_schema, run_query Natural-language questions and cross-database corroboration File shares (SMB / NFS, document stores) File MCP server list_dirs, search, read_file Q&A and summarization over contracts, drawings, PDFs, logs Line-of-business apps (REST / SOAP) API MCP server list_operations, call_operation Conversational access to ERP, ticketing, claims, orders NoSQL / message systems Connector MCP server list_collections, query, peek Reasoning over document stores and event streams Mainframe / other systems Adapter MCP server workload-specific Bringing legacy systems into modern AI workflows Every bridge is small, independently deployable, and governed the same way: read-only by default, private over ExpressRoute, and locked to your agent’s managed identity. The pattern is the product; the bridges are how you grow it. To make it concrete, here’s the first proof of the pattern: a secure, read-only agent over two private SQL databases in Azure VMware Solution. Reference architecture The reference deployment runs in a single Azure region, with the Azure resources in one resource group alongside the Azure VMware Solution private cloud. Figure 3: Reference architecture A question from the managed agent in Azure AI Foundry crosses into your virtual network, where the MCP server on Azure Container Apps validates the caller's Entra token, reads the database password from Key Vault with its own managed identity, and runs a single read-only SELECT against the SQL Server VMs inside the Azure VMware Solution private cloud. Component Resource Type Azure VMware Solution private cloud avs-private-cloud Microsoft.AVS/privateClouds MCP server avs-mcp-server Microsoft.App/containerApps Container Apps environment avs-mcp-env Microsoft.App/managedEnvironments AI Foundry account avs-sql-foundry Microsoft.CognitiveServices/accounts Foundry project avs-sql-foundry/avs-sql-agent .../accounts/projects Container registry avssqlacr Microsoft.ContainerRegistry/registries Secrets avs-sql-kv-01 Microsoft.KeyVault/vaults Network avs-hub-vnet (10.40.0.0/16) Microsoft.Network/virtualNetworks ExpressRoute gateway avs-ergw virtualNetworkGateways Foundry private endpoint avs-sql-foundry-pe (+ privatelink DNS zones) privateEndpoints Logs avs-sql-logs OperationalInsights/workspaces The data itself lives on VMs inside the Azure VMware Solution private cloud, on a VMware NSX segment (avs-workload-01, 192.168.131.0/24): VM IP Database SQL VM #1 192.168.131.55 SalesDB (Products, Customers, Orders) SQL VM #2 192.168.131.56 InventoryDB (Products, Stock) The bridge works because the Container Apps subnet routes to the Azure VMware Solution private cloud over ExpressRoute, while Foundry is reachable privately through a private endpoint. Figure 4: Network topology The MCP server runs in a delegated aca-subnet and reaches the workload segment over ExpressRoute. Foundry sits behind a private endpoint with privatelink DNS zones, so the portal and jump host reach it privately. The agent’s tool call to the bridge is a single outbound HTTPS request carrying an Entra token. The data bridge: a small, read-only MCP server The first bridge is the SQL MCP server, a small Python service (FastMCP over streamable HTTP) that exposes three read-only tools. It’s engine-agnostic (SQLAlchemy) and pulls its credentials from Key Vault at runtime: @mcp.tool() def list_sources() -> str: """List the databases across the Azure VMware Solution workloads and what each contains.""" @mcp.tool() def get_schema(source: str) -> str: """Return tables and columns for a source (call list_sources first).""" @mcp.tool() def run_query(source: str, query: str) -> str: """Run ONE read-only SELECT and return up to the source's row cap.""" Guardrails are built in. Only SELECT / WITH statements are allowed, one statement at a time; DML and DDL keywords are blocked; and every result set is row-capped. The agent gets to read and reason, but never to mutate. Onboarding a database is configuration, not code. A single sources.yaml catalog describes each source and its governance: sources: sales: type: mssql connection: { host: 192.168.131.55, port: 1433, database: SalesDB } auth: { kind: sql, username: agentreader, secret: sql-agentreader-password } governance: { allow_schemas: [dbo], max_rows: 200 } inventory: type: mssql connection: { host: 192.168.131.56, port: 1433, database: InventoryDB } auth: { kind: sql, username: agentreader, secret: sql-agentreader-password } governance: { allow_schemas: [dbo], max_rows: 200 } The service is containerized (with the ODBC Driver 18 / msodbcsql18), pushed to the container registry, and run on the VNet-integrated Container Apps environment. It has a system-assigned managed identity with Key Vault Secrets User on the vault, so it can fetch the read-only database credential without ever storing it. The managed agent in Azure AI Foundry The agent lives entirely in Azure AI Foundry (avs-sql-foundry, project avs-sql-agent), running on a small, cost-efficient model deployment. It’s configured with: A schema-first workflow. Discover the available sources, read the schema, write a read-only query, then corroborate the results. An MCP tool pointing at the Container App’s /mcp endpoint, authenticated with Microsoft Entra using the project’s managed identity. Generic, source-agnostic instructions. The agent discovers structure at runtime rather than hard-coding any schema, so the same agent works against any workload behind an MCP server, not just these two databases. Figure 5: The agent in Azure AI Foundry The agent is attached as a tool with the private MCP data server and authenticated via managed identity. Once the tool is attached, answering a question is a single, auditable round trip. The agent discovers the available sources, reads only the schema it needs, issues a read-only query, and corroborates the results, all over private connectivity and with managed-identity authentication end to end. Figure 6: How a question becomes an answer. The agent calls list_sources, validates its managed-identity token, reads each schema, and runs read-only SELECTs over ExpressRoute. Key Vault supplies the credentials, and the corroborated answer flows back to the user. Security and governance, by design Because these are your crown-jewel systems, security is the starting point rather than a layer on top: No secrets in code. Database credentials live in Key Vault; the server fetches them through its managed identity (DefaultAzureCredential to SecretClient). Entra managed-identity auth from the agent to the bridge, with no shared keys and automatically rotating tokens. Private connectivity. The bridge reaches Azure VMware Solution over ExpressRoute; the SQL VMs are never exposed to the internet; Foundry sits behind a private endpoint. Read-only guardrails. Only SELECT is allowed; writes and DDL are blocked; result sets are capped. Least-privilege caller lock. The bridge accepts tokens only from the Foundry project’s managed identity. The payoff: answers no single system can give The value here isn’t “query a table.” It’s corroboration, the kind a single database can’t do on its own. Our two databases share a ProductID, so the agent queries both and joins them itself. Ask a plain-language question about stock health, and you get: Widget A: sold 500, stock 40 (below the reorder point of 50), so REORDER NOW Gizmo C: high stock, low sales, so OVERSTOCKED Contraption E: present in Sales, missing from Inventory, flagged as a DISCREPANCY Figure 7: A natural-language question answered from two private Azure VMware Solution databases, with reorder, overstock, and discrepancy flags surfaced directly in the agent’s reply. Figure 8: The run trace Every tool call and query is visible and auditable (list_sources, then get_schema, then run_query on each source), so you can see exactly how the answer was produced. The same shape generalizes far beyond retail: claims versus policy, orders versus fulfillment, and tickets versus assets. Anywhere the truth is split across silos, the agent can bring it back together. Adding the next workload Coverage grows at two levels: within a bridge, and across bridges. Within the SQL bridge (another database), it’s configuration, not code. SQLAlchemy gives one code path for SQL Server, PostgreSQL, MySQL, and Oracle; the source type selects the dialect. Adding a PostgreSQL VM, for example, takes no changes to the server code: add the driver, a source block (type: postgresql, allow_schemas: [public]), and a Key Vault secret, then rebuild. Across workload types (a file share, an API), you add a new bridge that implements the same tool contract with connectors suited to that workload (read_file / search for a document store, call_operation for a REST or SOAP app), then attach it to the same agent. Nothing about the agent, the network, or the identity model changes. Your estate lights up one bridge at a time. Deploy it yourself The entire bridge is packaged as an open, reusable kit on GitHub, Azure VMware Solution AI Data Agent, with a Bicep template (and a compiled ARM equivalent), a parameters file, and a one-command deploy script. # Build and push the MCP image az acr build --registry <your-acr> --image avs-mcp:v4 . # Deploy to the VNet-integrated Container Apps environment az containerapp update -n avs-mcp-server -g avs-sql-rg \ --image "<your-acr>.azurecr.io/avs-mcp:v4" # Store the read-only SQL credential in Key Vault az keyvault secret set --vault-name avs-sql-kv-01 \ --name sql-agentreader-password --value '<password>' The script provisions the delegated subnet, the container registry, Key Vault (with the read-only secret), the VNet-integrated Container Apps environment and MCP server, and the managed-identity role assignments, optionally including the Azure AI Foundry account and model deployment. You point it at the VNet already connected to your Azure VMware Solution private cloud and supply a read-only database credential. All that’s left is creating the read-only login and attaching the MCP tool to your agent in the Foundry portal. What’s next This SQL example is deliberately just the first bridge. A few directions we’re excited about: Meet users where they are. Surface the agent in Microsoft Teams or Microsoft 365 Copilot, so anyone in the organization can ask questions of Azure VMware Solution workloads in natural language. One agent, every workload. Grow from databases to file shares, REST/SOAP apps, NoSQL, and message systems, each a new bridge behind the same agent. A workload catalog. A library of ready-made bridges, so onboarding a new Azure VMware Solution workload becomes a deploy-and-configure step rather than a project. Bringing it together With a managed agent in Azure AI Foundry, lightweight MCP servers on VNet-integrated Azure Container Apps, and private connectivity over ExpressRoute, workloads that used to be “off-limits to AI” become conversational, while staying inside your network, read-only, and credential-less, using the same identity and governance model you already rely on across Azure. The SQL example is just the beginning. Because every workload is reached the same way, enabling AI across your Azure VMware Solution estate becomes a repeatable motion: pick the next workload, add a small bridge, and it’s live, with no data movement, no re-platforming, and no new trust boundary. For organizations on Azure VMware Solution, that reframes what Azure VMware Solution is for. Not just where your VMware workloads run, but where they become AI-accessible, one bridge at a time, securely and in place. Ready to try it? Grab the Azure VMware Solution AI Data Agent kit on GitHub, point it at your Azure VMware Solution-connected VNet, and stand up your first bridge. We’d love to hear what you connect first. Next Steps Start by identifying which Azure VMware Solution workloads hold the highest-value data, typically core databases, document stores, and line-of-business applications, and pick one as your first bridge. Deploy the kit into the virtual network already connected to your Azure VMware Solution private cloud, create a dedicated read-only login for the agent, and validate the full path end to end in a non-production private cloud before going further. With large enterprise solutions for strategic and major customers, an Azure VMware Solution Solutions Architect from Azure, Broadcom, or a trusted VMware Partner should be engaged to review the network path, the identity model, and the data governance boundaries before a production rollout. This should also include a data classification and application dependency assessment, to establish which sources the agent may read, where data gravity lies, and which traffic flows and latency dependencies the ExpressRoute path must support. Beyond the first bridge, a few directions we are excited about: Meet users where they are. Surface the agent in Microsoft Teams or Microsoft 365 Copilot, so anyone in the organization can ask questions of Azure VMware Solution workloads in natural language. One agent, every workload. Grow from databases to file shares, REST/SOAP apps, NoSQL, and message systems, each a new bridge behind the same agent. A workload catalog. A library of ready-made bridges, so onboarding a new Azure VMware Solution workload becomes a deploy-and-configure step rather than a project. Summary In this post, I took a closer look at the challenge of making private Azure VMware Solution workloads reachable by Azure AI, the architectural building blocks that close the gap (a managed agent in Azure AI Foundry, lightweight per-workload MCP servers on VNet-integrated Azure Container Apps, and private connectivity over ExpressRoute), and the security and governance model that keeps your data read-only, credential-less, and inside your network. I also discussed the next steps to continue enabling Azure AI across an Azure VMware Solution estate. The SQL example is just the beginning. Because every workload is reached the same way, enabling AI across your Azure VMware Solution estate becomes a repeatable motion: pick the next workload, add a small bridge, and it's live, with no data movement, no re-platforming, and no new trust boundary. For organizations on Azure VMware Solution, that reframes what the service is for. Not just where your VMware workloads run, but where they become AI-accessible, one bridge at a time, securely and in place. Ready to try it? Grab the Azure VMware Solution AI Data Agent kit on GitHub, point it at your Azure VMware Solution-connected virtual network, and stand up your first bridge. I'd love to hear what you connect first. If you are interested in Azure VMware Solution, please use these resources to learn more about the service and the Azure AI building blocks used in this post: Azure VMware Solution Homepage: Azure VMware Solution Documentation: Azure VMware Solution SLA: SLA for Azure VMware Solution Azure Regions: Azure Products by Region Service Limits: Azure VMware Solution subscription limits and quotas Well-Architected Framework: Azure VMware Solution workloads Cloud Adoption Framework: Introduction to the Azure VMware Solution adoption scenario Enterprise Scale Landing Zone: Enterprise-scale for Microsoft Azure VMware Solution GitHub repository: Azure/azure-vmware-solution Learning Resources: Azure VMware Solution (microsoft.github.io) Networking and connectivity Network connectivity scenarios: Enterprise-scale network topology and connectivity for Azure VMware Solution Network Security: Azure VMware Solution Network Security Internet Connectivity: Internet connectivity design considerations Security and governance Identity & Access Management: Enterprise-scale identity and access management Security Recommendations: Concepts - Security recommendations for Azure VMware Solution Security Baseline: Azure security baseline for Azure VMware Solution WAF: Security considerations for Azure VMware Solution workloads Defender for Cloud: Integrate Microsoft Defender for Cloud with Azure VMware Solution Customer-managed keys: Configure customer-managed key encryption at rest Azure AI and the agent platform Azure AI Foundry: Azure AI Foundry Foundry Agent Service: What is Azure AI Foundry Agent Service? Model Context Protocol: Model Context Protocol specification Azure Container Apps: Azure Container Apps overview VNet integration: Networking in Azure Container Apps environments Managed identities: What are managed identities for Azure resources? Azure Key Vault: About Azure Key Vault Private endpoints: What is Azure Private Endpoint? Deployment kit: Azure VMware Solution AI Data Agent Tooling and automation Azure CLI: Azure Command-Line Interface (CLI) Overview PowerShell module: Az.VMware Module Azure Resource Manager: Microsoft.AVS/privateClouds REST API: Azure VMware Solution REST API Terraform provider: azurerm_vmware_private_cloud Terraform Registry Enterprise Scale GitHub repository: Azure/Enterprise-Scale-for-AVS Author Bio Nivas Narayanasamy is a Senior Software Engineer on the Azure VMware Solution team at Microsoft. He works across the private cloud platform, networking, and automation that customers rely on to run VMware workloads on Azure and is currently focused on secure patterns for bringing Azure AI to private enterprise data.How to Secure Azure Databricks without Public Exposure using WAF + Private Endpoints
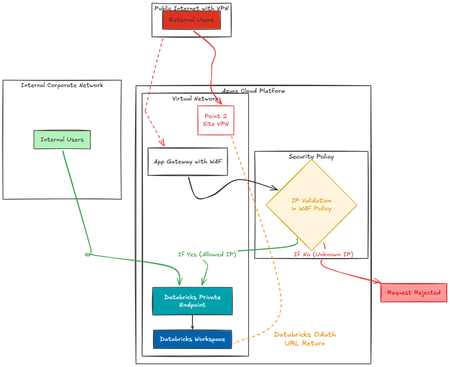
This blog outlines a Zero Trust–aligned architecture for securing Azure Databricks using Application Gateway (WAF) and Private Endpoints within a Hub-Spoke network model. Enables a true Zero Trust model, ensuring: No direct exposure of Databricks Full traffic inspection Compliance-ready secure access for both internal and external users Integration of Azure P2S to cater the Databricks OAuth URL.2.7KViews1like2CommentsAzure Course Blueprints
Each Blueprint serves as a 1:1 visual representation of the official Microsoft instructor‑led course (ILT), ensuring full alignment with the learning path. This helps learners: see exactly how topics fit into the broader Azure landscape, map concepts interactively as they progress, and understand the “why” behind each module, not just the “what.” Formats Available: PDF · Visio · Excel · Video Every icon is clickable and links directly to the related Learn module. Layers and Cross‑Course Comparisons For expert‑level certifications like SC‑100 and AZ‑305, the Visio Template+ includes additional layers for each associate-level course. This allows trainers and students to compare certification paths at a glance: 🔐 Security Path SC‑100 side‑by‑side with SC‑200, SC‑300, SC‑500 🏗️ Infrastructure; Ai & Dev Path AZ‑305 alongside Ai-103, AZ‑104, Ai‑200, AZ‑700, AZ‑140 This helps learners clearly identify: prerequisites, skill gaps, overlapping modules, progression paths toward expert roles. Because associate certifications (e.g., SC‑300 → SC‑100 or AZ‑104 → AZ‑305) are often prerequisites or recommended foundations, this comparison layer makes it easy to understand what additional knowledge is required as learners advance. Benefits for Students 🎯 Defined Goals Learners clearly see the skills and services they are expected to master. 🔍 Focused Learning By spotlighting what truly matters, the Blueprint keeps learners oriented toward core learning objectives. 📈 Progress Tracking Students can easily identify what they’ve already mastered and where more study is needed. 📊 Slide Deck Topic Lists (Excel) A downloadable .xlsx file provides: a topic list for every module, links to Microsoft Learn, prerequisite dependencies. This file helps students build their own study plan while keeping all links organized. Download links Associate Level PDF - Demo Visio Contents AZ-104 Azure Administrator Associate R: 12/14/2023 U: 12/17/2025 Blueprint Demo Video Layer of Visio+ Excel Ai-103 Developing AI Apps and Agents on Azure R: 05/20/2026 Blueprint Inludes Ai-200 Layer of Visio+ Ai-200 Azure Developer Associate R: 11/05/2024 U: 12/17/2025 Blueprint Demo Layer of Visio+ Excel SC-500 Azure Security Engineer Associate R: 01/09/2024 U: 05/20/2026 Blueprint Demo Layer of Visio+ Excel AZ-700 Azure Network Engineer Associate R: 01/25/2024 U: 12/17/2025 Blueprint Demo Layer of Visio+ Excel SC-200 Security Operations Analyst Associate R: 04/03/2025 U:04/09/2025 Blueprint Demo Layer of Visio+ Excel SC-300 Identity and Access Administrator Associate R: 10/10/2024 Blueprint Demo Layer of Visio+ Excel Specialty PDF Visio AZ-140 Azure Virtual Desktop Specialty R: 01/03/2024 U: 12/17/2025 Blueprint Demo Layer of Visio+ Excel Expert level PDF Visio AZ-305 Designing Microsoft Azure Infrastructure Solutions R: 05/07/2024 U: 05/20/2026 Blueprint Demo Visio+ AZ-104 AZ-700 AZ-140 Ai-103 Ai-200 Excel SC-100 Microsoft Cybersecurity Architect R: 10/10/2024 U: 05/20/2026 Blueprint Demo Visio+ SC-500 SC-300 SC-200 Excel Skill based Credentialing PDF AZ-1002 Configure secure access to your workloads using Azure virtual networking R: 05/27/2024 Blueprint Visio Excel AZ-1003 Secure storage for Azure Files and Azure Blob Storage R: 02/07/2024 U: 02/05/2024 Blueprint Excel Subscribe if you want to get notified of any update like new releases or updates. Author: Ilan Nyska, Microsoft Technical Trainer My email ilan.nyska@microsoft.com LinkedIn https://www.linkedin.com/in/ilan-nyska/ I’ve received so many kind messages, thank-you notes, and reshares — and I’m truly grateful. But here’s the reality: 💬 The only thing I can use internally to justify continuing this project is your engagement — through this survey https://lnkd.in/gnZ8v4i8 ___ Benefits for Trainers: Trainers can follow this plan to design a tailored diagram for their course, filled with notes. They can construct this comprehensive diagram during class on a whiteboard and continuously add to it in each session. This evolving visual aid can be shared with students to enhance their grasp of the subject matter. Explore Azure Course Blueprints! | Microsoft Community Hub Visio stencils Azure icons - Azure Architecture Center | Microsoft Learn ___ Are you curious how grounding Copilot in Azure Course Blueprints transforms your study journey into smarter, more visual experience: 🧭 Clickable guides that transform modules into intuitive roadmaps 🌐 Dynamic visual maps revealing how Azure services connect ⚖️ Side-by-side comparisons that clarify roles, services, and security models Whether you're a trainer, a student, or just certification-curious, Copilot becomes your shortcut to clarity, confidence, and mastery. Navigating Azure Certifications with Copilot and Azure Course Blueprints | Microsoft Community Hub Azure Course Blueprints + Demo Deploy Demos are essential for achieving end‑to‑end understanding of Azure. To reduce preparation overhead, we collaborated with Peter De Tender to align each Blueprint with the official Trainer Demo Deploy scenarios. With a single click, trainers can deploy the full environment and guide learners through practical, aligned demonstrations. https://aka.ms/DemoDeployPDF40KViews15likes20CommentsCloud Native Platforms: Run
Audience: SREs (Site Reliability Engineers), platform engineers, engineering managers running production systems Reading time: 8 minutes Series: Cloud Native Platforms. Build, Run, Evolve. This is Part 2 of 3. Most systems are designed thoughtfully. Most operations are inherited reactively. The systems that survive are not the ones built with the most care. They are the ones operated with the most discipline. Production has a way of revealing every shortcut taken during design and every assumption left unverified. This post is about what it takes to operate a platform once the build is done. How they are run, not how they are built Systems are not defined by how they are built. They are defined by how they are run. A well-designed system that is operated reactively will fail in production. A modestly designed system that is operated with discipline will outperform it. Five operational disciplines decide which side of that line a platform lives on. Each one is engineering work, not a checklist for someone else to handle. Figure 1. The incident lifecycle as a state machine. The states are not optional steps. They are the contract between the team and the system. 1. Observability is the backbone of reliability Without observability, every operation becomes a guess. As systems grow, the cost of guessing rises faster than the cost of seeing. Part 1 of this series argued that observability is a design property: instrumentation contracts, request id propagation, structured logging schemas. Production is where those design choices either pay off or do not. Strong observability in production is a contract that lets any engineer answer three questions in minutes: what failed, why it failed, and what the impact was. The shape of that contract matters more than the tool that implements it. (This three-question framing is community-popularised through the SRE community and writers such as Charity Majors. See Honeycomb's What is Observability for the canonical articulation of the three-pillars and question framing; the substance is older than the framing.) Dashboards organised around user journeys, not infrastructure components Service level indicators (SLIs: the specific measurements you care about, e.g., success rate, p99 latency) chosen from the user's perspective, not the database's Alerts that page only on burn-rate against an SLO (Service Level Objective: the target value of an SLI, e.g., 99.9% of requests complete in under 800ms over a rolling month) using a multi-window strategy. A short window catches fast burns; a long window catches slow drifts. This is what makes SLOs operational rather than decorative. Sampling and retention tuned for cost, but never for blind spots The distinction between MTTA (mean time to acknowledge: how fast someone notices) and MTTR (mean time to restore: how fast service returns) tracked separately. Conflating them hides whether the team's bottleneck is detection, response, or fix. In practice The pattern that works: rebuild the operational view around two or three user journeys (sign-in, place order, view history) rather than per-component charts. Tie alerts to error budget burn rather than raw threshold crossings. Track MTTA and MTTR separately so the team's actual bottleneck (detection, response, or fix) is visible. The investment is rethinking what to measure, not buying a new tool. The return is that incidents stop being discovered by customer complaints first. Teams that make this shift typically find their existing telemetry was sufficient; only the questions being asked of it were wrong. If a dashboard cannot answer "what is the user experiencing right now", it is not an observability dashboard. It is decoration. 2. Alerts are signals, not notifications More alerts do not mean better monitoring. In practice, the opposite is true. Once alerts outpace the team's ability to act, important signals start getting missed. Effective alerting works to a small set of rules: Severity that maps to action, not to technical category Ownership baked in, never inferred at runtime Thresholds tied to user impact, not raw metric values Noise treated as a defect, with a regular review cadence Suppression and grouping for known multi-alert patterns In practice The pattern that works: audit every alert against one test, "what action would I take in the next five minutes if this fires now?" Demote alerts with no answer to dashboards. Remove alerts where the answer is the same as another alert's. Group related alerts so one incident produces one page, not twelve. Most teams discover their alert volume drops by an order of magnitude after a thorough audit, and the alerts that remain start getting trusted again. Trust is the precondition for every other operational practice. Without it, on-call rotations decay into noise filtering and the real signals get missed. Figure 2. From raw events to pages, in approximate orders of magnitude. The numbers vary by team and workload; what does not vary is that each stage needs to remove one to two orders of magnitude of noise. Teams that page on raw events end up with on-call rotations nobody trusts. 3. Incident response is a practiced muscle Failures are inevitable. Unstructured response is not. The teams that recover quickly do not improvise during incidents. They follow a structure that has been practiced when nothing was on fire. The structure is intentionally simple, because incident time is the worst time to negotiate roles. Clear roles: incident lead, communications lead, scribe, subject matter expert (the RACI model, Responsible-Accountable-Consulted-Informed, adapted for incident response) Defined escalation paths with clear handoff criteria. Escalation means re-paging to a higher tier or specialist, not returning to detection. The lifecycle diagram in Figure 1 makes the distinction explicit. Runbooks for the top failure modes, kept short enough to actually be read Status communication on a fixed cadence, even when there is nothing new to say. Customer comms and internal comms are tracked separately. Blameless postmortems (focus on the system that allowed the failure, not the person who pushed the button) that produce action items the team actually completes Game days: scheduled exercises that simulate failure modes (region outage, dependency unavailability, traffic spike) under controlled conditions, so gaps in runbooks are found before incidents do In practice The pattern that works: name the incident lead and the comms lead before the first message goes out. Write runbooks short enough to be scannable at 3 AM. Run blameless postmortems with action items that actually get tracked to completion. Schedule game days quarterly so the runbooks are exercised before real incidents. Teams that operate with this structure do not have more engineers; they have engineers who are not single points of failure during recovery. The deepest experts stay the deepest experts, but the platform stops depending on whether they happen to be online. Implementation note A short, well-structured runbook outperforms a long, exhaustive one. The goal during an incident is not to think. It is to act on a procedure that has been thought through in calmer times. # Runbook header pattern (keep it scannable in incident time) title: High latency on order API slo_protected: # this runbook protects two SLOs - order-completion-success - order-completion-latency severity: # derived from burn rate, not declared fast_burn: P1 # 14.4x budget burn over 1 hour => page now slow_burn: P2 # 6x budget burn over 6 hours => investigate owner: payments-team indicators: # triggers for evaluation, not severity - p99 (99th-percentile) latency exceeds the SLO target for 5 min - error rate exceeds the SLO target for 3 min on order-completion first_actions: - Open the order-journey dashboard. Confirm impact in business terms. - Check Service Bus queue depth and dead-letter rate (the most common cause of API latency under load is downstream backpressure) - Verify Cosmos DB RU/s saturation and partition hotspots - Inspect the most recent deployment for behavioural changes escalate_if: - Latency does not recover in 15 min - Error rate exceeds 5% (fast burn against the SLO) - Customer reports arrive before our own signals do rollback_path: - Feature flag "new-order-pipeline" can be disabled per-tenant - Last known good deployment id is in the release tracker note_on_scaling: # CPU is rarely the cause of latency in this service. Scale only after # confirming the bottleneck is compute, not a downstream dependency or # queue depth. Adding capacity to a saturated downstream amplifies the # incident; it does not resolve it. The general principle behind that last note travels beyond this runbook: scale-out is the right remediation for compute saturation, not for downstream saturation. When latency rises because a database, queue, or external dependency is saturated, adding capacity in front of the bottleneck moves more requests into the bottleneck and makes the incident worse. This is one of the most common operational mistakes when the dashboard shows red and the on-call instinct says "add more". 4. Release confidence is engineered Releases get harder as systems grow. The platforms that ship confidently at scale have engineered the path, not learned to fear it. The patterns that change the math: Feature flags that allow change without deploy Canary deployments (releasing the new version to a small slice of traffic first, watching error budget burn before continuing) that surface problems on a small slice Gradual rollouts with automated rollback triggers Database migrations split from application releases Release coordination that scales with services, not with team size In practice The pattern that works: every change ships behind a feature flag, canary deployments take a small slice of traffic first, and rollback is a one-click step in the pipeline rather than a procedure to be invented during an incident. The cost is the discipline of building rollback paths and exercising them. The return is releases that stop being events. Issues that previously triggered full rollbacks get isolated to a slice and rolled back automatically before they reach most users. The willingness to ship smaller, more frequent changes follows directly from the confidence that bad changes can be undone fast. Big releases feel safe because they are rare. They are actually risky because every change rides together. 5. Reliability is continuous, not a milestone Reliability is not achieved through tools alone. It requires continuous refinement, feedback-driven improvement, and a budget that the team can spend on operational work without negotiating each time. The disciplines that keep systems reliable over years are codified well in the SRE-book framing of service level objectives and error budgets (the canonical reference is the Google SRE Book chapter on Service Level Objectives, with the operational follow-up in the SRE Workbook chapter on alerting on SLOs). The names matter less than the practice they enable. SLOs chosen from the user's perspective, with two or three per service rather than ten. More SLOs means none of them shape behaviour. Error budgets: the inverse of the SLO, expressing how much unreliability the team is willing to spend in a window. Used up early in the month means slow down on releases. Healthy means feature work keeps moving. Multi-window burn-rate alerting turns SLOs from dashboards into pages: short window catches catastrophic failures, long window catches slow drift. Without burn-rate alerting, SLOs are observation, not operation. (The pattern is documented in the SRE Workbook.) Reliability work has its own backlog, prioritised against features. Not a wishlist after every incident. Regular game days that exercise failure modes (region failover, dependency outage, traffic spike) before they happen for real Capacity planning informed by data, not by anxiety In practice The pattern that works: define two or three SLOs per service, expressed from the user's perspective. Compute the error budget weekly. When the budget is healthy, ship feature work. When the budget is burning fast, slow down and fix the cause. The conversation about which incidents matter and which can wait becomes possible because there is a shared number to point at. Reliability becomes a quantified property of the platform, not an opinion debated at every retrospective. Teams that adopt this discipline stop having the recurring "how reliable do we need to be?" argument and start having data-grounded trade-off discussions instead. A scenario that ties it together A platform was launching a new region. The build had gone well. Day 1 was clean. Two weeks in, latency started creeping up during peak hours. Alerts fired on raw thresholds, but no one could tell which ones to trust. Incident calls turned into long debugging sessions because three different teams owned overlapping pieces of the request path. The team did not start by buying a new tool. They started by treating operations as engineering work. The dashboard was redesigned around the user journey. Alerts were audited and most were demoted or removed. Roles for incident response were written down. A short runbook covered the top failure modes. Releases were broken into canary slices behind feature flags. None of this was new. It was discipline applied consistently to work that was previously assumed to be someone else's. The next region launch took half the effort, and the team's mean time to restore on the failures that did happen was measurably lower. What teams get wrong The common pattern is treating Day 2 as the cost of Day 1. Teams design beautifully, ship fast, then quietly absorb the operational debt. Dashboards proliferate. Alerts grow louder. Postmortems pile up. The fix is not more dashboards. It is treating operations as engineering work with the same rigour as feature delivery. Operability is a property the system either has or does not. It is not earned by adding monitoring. It is earned by designing for visibility and operating with discipline. Where to start The most concrete starter from this post: an alert audit. List every alert that fires in the next week and apply a single test to each one: "what action would I take in the next five minutes?" Demote the alerts that have no answer. Remove the alerts where the answer is the same as another alert's. The audit takes a morning. The result usually halves alert volume and lifts trust on what remains, which is the precondition for every other operational practice in this post. The shift The most important shift in maturity is not technical. It is in stance. The shift is from shipping software to operating systems: Operations is not a phase that follows engineering. It is engineering. Reliability is not a milestone reached. It is a discipline practiced. Incidents are not interruptions to the work. They are the work. The teams that internalise this shift run platforms that are smaller, calmer, and more trusted. They do not have fewer incidents because their systems are more advanced. They have fewer incidents because their operational discipline is more consistent. Part 3 of this series argues that the same discipline applies again, in a different domain: the practices that make platforms operable are the practices that make AI useful in delivery. Want to discuss? What is the one operational practice your team adopted that changed how you sleep at night? Drop a comment with patterns you have seen in your environment. Every reply gets read. Previously in this series: Building Cloud Native Platforms That Scale: Patterns That Actually Work. The first post covered the design choices that make scale possible. Next in this series: AI-First Platform Engineering: From Copilot to Agentic Delivery. Cloud helped us scale infrastructure. The next post looks at how AI is now changing how we build and run platforms.WAR, Azure Advisor, and Us (Azure Arch Diagram Builder): Three Ways to Score an Azure Architecture
Author: Arturo Quiroga, Azure AI services Engineer - Senior Partner Solutions Architect — Microsoft A few days ago I published From Prompt to Production: Building Azure Architecture Diagrams with AI, introducing the open-source Azure Architecture Diagram Builder. One feature got more follow-up questions than any other: the Well-Architected Framework (WAF) validation. Architects from partners and customers — many of whom already use Azure Advisor and the Well-Architected Review — wanted to know exactly what scoring algorithm we use, how it compares to Microsoft's official tools, and whether they should be using all three. This post is that answer. It's a deep dive into how design-time WAF validation works, how Microsoft's two official WAF assessment algorithms work, and where each fits in the architecture lifecycle. TL;DR. Microsoft ships two WAF assessment vehicles — the Well-Architected Review (questionnaire, scored from human answers) and the Azure Advisor score (healthy-resources-÷-applicable-resources weighted per subcategory, with Defender Secure Score for Security and cost-weighted math for Cost). Both require either a human filling in a form or live Azure telemetry. Our app runs at design time on a diagram, before anything is deployed, using a hybrid pipeline: a deterministic rule pre-scan followed by an LLM refinement pass. Same five WAF pillars, different lifecycle stage. Complementary, not competitive. Why design-time validation matters Every cost overrun, reliability gap, and security incident I've ever debugged was cheaper to fix on a whiteboard than in production. Yet most WAF tooling assumes the architecture already exists — either because there are deployed resources to scan (Advisor) or because someone has built enough of it to answer 60 specific questions about it (WAR). That leaves a gap. Between "rough sketch" and "deployed resource group" there is no algorithmic WAF feedback loop. That's the gap the Diagram Builder fills. Microsoft's two official WAF assessment algorithms Before describing our approach, it's worth being precise about what Microsoft already ships, because the term "WAF assessment algorithm" can mean either of two very different things. 1. Azure Well-Architected Review (WAR) — questionnaire-based The Well-Architected Review is a free self-assessment hosted on Microsoft Learn. Aspect Detail Input Human answers to ~60 questions mapped to the WAF pillar checklists Workload variants Core WAR, plus AI/ML, IoT, SAP on Azure, Azure Stack Hub, SaaS, Mission Critical Scoring Derived from the answers — each "no" or unanswered question subtracts from the pillar score Output Per-pillar maturity score + prioritized recommendations + optional Advisor integration Improvement tracking "Milestones" (point-in-time snapshots) When to use Periodic deep reviews; greenfield design baselining; brownfield audits WAR is human-driven. The algorithm is essentially "how many of the recommended practices have you confirmed you do?" — which is exactly the right algorithm when the assessor is the workload team itself. 2. Azure Advisor Score — telemetry-based The Advisor score is the closest thing Microsoft ships to a real, deterministic WAF algorithm. It runs continuously over your deployed Azure resources. The math: Pillar-specific overrides: Security uses Microsoft Defender for Cloud's Secure Score model. Cost weights by retail $ cost of healthy resources, plus age-of-recommendation weighting; postponed/dismissed items are removed from the denominator. Reliability / Performance / Operational Excellence use the healthy-resources ratio above. Key terms: Healthy resource — a deployed resource with no open Advisor recommendation against it for that pillar. Total applicable — resources Advisor was able to evaluate (excludes dismissed/snoozed). Advisor is the right tool once you're in production. It cannot help you before deployment, because there is nothing to count as "healthy" or "applicable." The missing stage: design time Here's the lifecycle, with each tool's domain shaded: Design / Diagram — Diagram Builder validation runs here. Operate / Observe — Azure Advisor runs here continuously. Periodic Review — WAR runs here, typically quarterly or at major milestones. These three stages are sequential and complementary. Our app does not replace Advisor or WAR — it adds a feedback loop earlier in the lifecycle, where corrections are cheapest. How design-time validation works in the Azure Architecture Diagram Builder The validator is a two-phase hybrid pipeline: deterministic local rules first, then LLM refinement. The full source lives in three files: src/services/architectureValidator.ts — orchestrator and prompt src/services/wafPatternDetector.ts — topology + service rule engine src/data/wafRules.ts — the rule knowledge base Phase 1 — Deterministic rule pre-scan (~1 ms, no LLM) When you click Validate Architecture, the validator runs a fully client-side rule engine against the diagram's services, connections, and groups. There are two kinds of rules: Architecture-pattern rules These fire when a topology anti-pattern is detected: Pattern Detection trigger single-region No global LB (Traffic Manager / Front Door) with ≥3 services single-database Exactly one database service, no replication signal no-cache Compute + database present, no Redis/CDN no-monitoring No Azure Monitor / App Insights / Log Analytics no-identity No Microsoft Entra ID no-waf Public web tier without WAF / Front Door / App Gateway direct-db-access An edge from a frontend service directly into a database no-key-vault 4+ services and no Key Vault no-backup Database present, no Azure Backup / Recovery Services no-api-gateway 2+ compute services and no APIM / App Gateway / Front Door Service-specific rules Every service in the in the generated Azure Architecture diagram is matched against SERVICE_SPECIFIC_RULES by normalized type — App Service, Functions, AKS, Cosmos DB, SQL Database, Storage, Key Vault, and 22 more. The knowledge base at a glance Metric Count Total rules 73 Architecture-pattern rules 10 Service-specific rules 63 Distinct Azure services covered 29 Rules tagged Reliability 18 Rules tagged Security 34 Rules tagged Cost Optimization 5 Rules tagged Operational Excellence 7 Rules tagged Performance Efficiency 9 The preliminary score Each finding has a severity, and severity drives a fixed point deduction from a starting score of 100: Severity Deduction critical −12 high −7 medium −3 low −1 Result is floored at 10 (so even a deliberately bad architecture scores at least 10) and ceilinged at 95 (no findings ≠ perfect — there's always something the model might still catch). This is the deterministic baseline before the LLM ever sees the architecture, and it's what makes the pipeline reproducible. Phase 2 — LLM contextual refinement The pre-scan output, the topology, and the optional natural-language description are folded into a focused prompt sent to one of seven Azure OpenAI models (GPT-5.1 through 5.4, GPT-5.x Codex variants, DeepSeek V3.2 Speciale, Grok 4.1 Fast). The system prompt gives the model explicit scoring guardrails: Score based on what IS present, not what COULD be added. A well-connected architecture with appropriate services should score 60–80. Score below 50 only for critical gaps (no auth, no monitoring, single points of failure). Findings are improvement suggestions, not reasons to penalize the score severely. The model returns strict JSON: { "overallScore": 0-100, "summary": "2–3 sentence assessment", "pillars": [ { "pillar": "Reliability | Security | Cost Optimization | Operational Excellence | Performance Efficiency", "score": 0-100, "findings": [ { "severity": "critical | high | medium | low", "category": "...", "issue": "...", "recommendation": "...", "resources": ["service-name-1", "service-name-2"], "source": "rule-based | ai-analysis" } ] } ], "quickWins": [ /* same shape as findings */ ] } Two things to call out: Every finding is tagged rule-based or ai-analysis . That tag is the credibility lever. You can always see what the deterministic engine produced versus what the model contributed on top. If you don't trust the AI layer, you can ignore it entirely — the rule layer still stands. The LLM is given pattern hints, not the entire rule catalog. The prompt stays small and focused, which is roughly 3–5× faster and cheaper than asking the LLM to do everything from scratch. What the user sees On every run the modal reports: Overall WAF score (0–100) Per-pillar score × 5 (0–100 each) Severity breakdown — counts of critical / high / medium / low across all findings Quick wins — high-impact, low-effort items the model surfaces separately Hybrid metadata — local findings count, patterns detected, KB rules used, preliminary score, local elapsed ms AI metrics — model used, reasoning effort, prompt/completion/total tokens, elapsed time App Insights telemetry — an Architecture_Validated event with model, overall score, finding count, elapsed time Worked example Take this prompt, which I've used in demos with partners: "A multi-region web application: Azure Front Door in front of two App Service instances in West US 2 and East US 2, both reading from an Azure SQL Database with geo-replication, with Application Insights for telemetry. No Entra ID, no Key Vault." After generation, Validate Architecture runs: Phase 1 — pre-scan (deterministic), ~1 ms Patterns detected: no-identity , no-key-vault Findings produced: 8 (1 critical, 1 high, 3 medium, 3 low) Preliminary score: 100 − 12 − 7 − (3×3) − (1×3) = 69 Phase 2 — LLM refinement, ~6–9 s depending on model The model accepts the two pattern hints, validates them in context, and adds three more findings of its own: Finding Source Pillar Severity No Microsoft Entra ID for authentication rule-based Security critical No Key Vault for secret management rule-based Security high App Service slots not used for safe deploys ai-analysis Operational Excellence medium SQL DB geo-replication present but RTO/RPO not documented ai-analysis Reliability medium No CDN for static assets behind Front Door ai-analysis Performance Efficiency low Final scores returned by the model: Pillar Score Reliability 78 Security 52 Cost Optimization 80 Operational Excellence 70 Performance Efficiency 75 Overall 71 The Security score is the lowest because two of the highest-severity findings landed there — exactly what a human reviewer would flag first. Multi-model comparison Because the deterministic floor is identical across runs, the Validation Comparison view becomes a fair shootout of what each LLM adds on top of the same baseline. The same diagram is scored by all seven models, and the UI surfaces: Overall score per model Per-pillar score per model Severity-count deltas Number of ai-analysis findings each model contributed Quick wins each model identified This is genuinely useful for two reasons. First, it shows that LLM scores vary — typically by ±5–10 points on the same architecture — which is exactly why we publish the rule-based vs ai-analysis tag. Second, it lets architects pick the model whose review style matches their own. How we align with Microsoft's algorithms Alignment point What it means Same five pillars Identical names and scope to the official WAF Same source material Rules derived from WAF docs and Azure Architecture Center service guides Severity-graded findings Map conceptually to Advisor's high/medium/low impact recommendations Per-pillar + overall scoring Mirrors WAR/Advisor output shape, so the results feel familiar Where we deliberately differ — and why Concern Microsoft Diagram Builder Why we differ Needs deployed resources Advisor: yes No — works on a diagram We're a design-time tool; the architecture doesn't exist yet Needs human Q&A WAR: yes No — derived from the diagram One-click validation inside the design flow Healthy/Applicable ratio Advisor: yes No No resource-health signal exists pre-deployment Subcategory fixed weights Advisor: yes No explicit weights Severity is the de-facto weight (12/7/3/1) Defender Secure Score for Security Advisor: yes No Defender requires deployed resources Cost-weighted scoring Advisor: yes No (separate Cost Estimation feature) Cost is a separate pipeline in our app AI/LLM refinement Neither Yes Catches context-specific issues a static catalog misses, and explains findings in natural language Multi-model comparison Neither Yes Lets architects see scoring variance across models Honest limitations I'd rather you hear these from me than discover them in production: LLM scores drift. ±5–10 points across models on the same diagram is normal. Treat the score as directional, the findings as actionable. The rule-based tag is your anchor. No live telemetry. We can't know if your App Service is actually using availability zones — only that you have App Service in the diagram. Advisor will tell you the truth post-deployment. Generic ruleset. No specialized workload branches yet (AI/ML, IoT, SAP, SaaS). WAR has those. No milestone tracking. Each validation run is independent. Compare runs manually using the Validation Comparison view. Rule coverage is finite. 29 services and 73 rules is a strong start but not exhaustive — the LLM layer exists in part to compensate for that gap. How to use all three together A lifecycle that actually works: Design — Use the Diagram Builder to sketch the architecture and validate at design time. Iterate until the per-pillar scores look reasonable and the critical/high findings are addressed. Deploy — Generate Bicep from the diagram, deploy, and let Azure Advisor start scoring real resources. Operate — Use Azure Advisor continuously. Use Defender Secure Score for security posture. Periodic review — Run a Core WAR every quarter or at major milestones to capture the things only humans know (business context, tradeoffs, planned debt). None of these three replace the others. They cover different stages of the same loop. What's next A few things on the roadmap I'd love feedback on: Milestone tracking so design-time scores can be compared over time the way WAR milestones work. Workload-specific rulesets mirroring WAR's branches — starting with AI/ML. Direct Advisor handoff — once a diagram is deployed, surface the corresponding Advisor recommendations in the same UI to close the loop. Try it, fork it, tell me where it's wrong Live app: https://aka.ms/diagram-builder Source: github.com/Arturo-Quiroga-MSFT/azure-architecture-diagram-builder Useful references: Azure Well-Architected Framework pillars Azure Well-Architected Review tool Azure Advisor score — calculation Use Azure WAF assessments (Advisor) Complete an Azure Well-Architected Review assessment If you're a partner or customer architect who's already living in Advisor and WAR, I'd genuinely value your reaction — does the design-time stage feel like a real gap to you, or are you already covering it some other way? Open an issue on the repo or reply on LinkedIn. Posted on the Azure Architecture Blog · Comments and issues welcome on the repo.762Views0likes0Comments