genaiops
22 TopicsAutomate Quota Discovery in Azure AI Foundry: A Tale of 3 APIs
Automate the discovery of Azure regions that meet your AI deployment needs using three essential APIs: Models API, Usages API, and Locations API. This process helps reduce decision fatigue and ensures compliance with enterprise-wide model deployment standards. Key learnings: Model Deployment Requirements: Understand the needs of a standard Retrieval-Augmented Generation (RAG) application, which involves deploying multiple models. Automation Benefits: Streamline your deployment process and ensure compliance with enterprise standards. Three Essential APIs: Models API: Query available models for a specific subscription within a chosen location. Usages API: Assess current usages and limits to infer available quotas. Locations API: Obtain a list of all available regions. A comprehensive Jupyter notebook with the implementation steps is available in the accompanying GitHub repository. This resource is invaluable for AI developers looking to streamline their deployment processes and ensure their applications meet all necessary requirements861Views3likes0Comments
Your Agents Need More Than a Place to Run
In architecture reviews with enterprise teams moving their first agentic applications toward production, I often hear the same plan: the team has containerized their agent and intends to run it on the managed Kubernetes cluster the organization already trusts. The reasoning is sensible, since the platform team knows the tooling and security has approved the network model, and for the first use case or two it is often the right call. Having watched this unfold in my years leading AgenticAI customer engineers and forward deployed engineers, and now helping customers reach production on Azure, I want to describe what happens next, before leaders commit rather than after. One thing to note is Azure supports multiple ways to build and operate agents. Foundry Agent Service provides an integrated managed runtime around your agent code. Azure Kubernetes Service supports teams that need Kubernetes-level control or want to extend an established platform, while Azure Container Apps provides managed container hosting. These services can work together. The decision is which capabilities and responsibilities best fit the workload. Where the cluster is the right answer A stateless retrieval application, a document extraction pipeline, or a classification job is a web service that happens to call a model, and a container platform runs web services well. A large retail customer of mine ran an invoice extraction agent on containers for over a year with almost no issues, and I never suggested they move it. The cluster remains the right home for several other situations as well. LLM invocations embedded inside existing microservices, event driven, or batch pipelines fit container platforms naturally. Genuine constraints such as air-gapped or sovereign environment, regions where a managed service is not yet offered are a good reason to run your own stack, and strong engineering team that already operates at that level can be a real asset. Even when the agents themselves move to a managed runtime, the tool servers, business APIs, and data services those agents call, often stay on your cluster, so they are complementary far more often than they are competitors. The problem is that these early wins can make agents seem like just another workload. Where the wheels come off The first failure is the state. A research agent that plans, searches, and synthesizes for ninety minutes is a long-running stateful process, while a Kubernetes pod is a disposable container the scheduler may restart at any time. A financial services team I worked with lost costly research run to a routine node upgrade, and responded as capable engineers do by building checkpointing, a durable store, and a resume mechanism. It worked, but they now owned a piece of infrastructure they had to keep correct as their agent's framework changed beneath it. A managed agent runtime absorbs this. Hosted agents in Foundry Agent Service, as one example, give every session a VM-isolated sandbox with a persistent file system, a durable state store that survives crashes and restarts and can hold checkpoints for frameworks such as LangGraph or Microsoft Agent Framework, and a resilient execution mode that recovers long-running work after a process interruption. The second is the human-in-the-loop. A commercial insurance customer’s claims agent needed sign-off from an adjuster and sometimes a second reviewer, with days between steps. Stopping an agent cleanly at the moment it needs a decision, holding its full session for four days without paying to keep it running, and resuming it correctly when the approval arrives is not something a container orchestrator gives out the box. The team built agent session suspend and resume, a queue, a durable state store, notifications, and an approval interface, and ended up with a small workflow engine nobody had planned to own. In hosted agents, an idle session is deprovisioned with its state persisted and restored onto fresh compute when the same session ID returns, so an agent waiting on an approval cost nothing while it waits, and sessions are retained for up to thirty days of inactivity. The approval experience remains yours to design, which is where your engineers' time should go. The third is multi-turn conversation, which quietly pushes teams into building their own context management system. The first version appends each turn to history, and within few turns the history outgrows the context window while cost and latency climb. So, the team adds truncation, then summarization, then retrieval of earlier turns, then per-user and per-tenant scoping, then expiry and deletion rules for privacy. An industrial customer's safety compliance assistant, with conversations stretching across days, followed exactly this path and ended up with a bespoke thread store and summarization pipeline nobody had budgeted for. Its first serious incident came when a summary silently dropped a compliance-relevant instruction. With the Responses protocol in hosted agents in Foundry, conversation history is a durable, platform-managed record keyed by a conversation ID and reachable from any channel, so the thread store is no longer yours to build, although deciding what to summarize or retrieve remains a design choice for your agent. The fourth is identity. On a cluster, the path of least resistance is a shared service account, and in one review a security architect asked which actions had been taken on behalf of which user, only to learn that the logs could not say. Hosted agents create a dedicated Microsoft Entra agent identity for each agent at deploy time, use on-behalf-of flows to act with the user's delegated permissions in interactive scenarios and the agent's own identity in autonomous ones, and keep the agent identifiable for audit in both cases. The fifth is per-user session isolation, which is the difference between an agent that serves many people and an agent that mixes them up. Agents read files, run code, and hold working data, and on a shared pod the default is that many users share a process, a file system, and often a cache. Giving every user session its own sandboxed environment and storage, so that one person's documents and intermediate results can never surface in another's, means engineering hard isolation boundaries and proving them to your security team. Hosted agents make a VM-isolated sandbox per session the default, and their durable state store can partition items per end user, so one store is safe to share across the users of a multitenant agent. And lastly, Evaluation and optimization are where the gap widens. The largest difference between teams that scale and those that stall is evaluation. Because agents are probabilistic and multi-step, staging tests often miss failures such as a wrong tool choice or a policy violation deep in a task. One customer’s agent passed every offline check but degraded unnoticed for weeks after a model update because evaluation stopped at release. Mature teams continuously evaluate production traces, combine automated judges with sampled human review, and red-team regularly.Once quality is measurable, teams can deliberately balance prompts, models, tools, latency, and cost. One team cut per-task cost by routing simple steps to smaller models after evaluation confirmed quality held. Self-built stacks require teams to assemble and maintain tracing, datasets, judges, and release gates. Hosted agents instead combines default OpenTelemetry traces with continuous evaluation, adversarial testing, and datasets generated from agent instructions. Staged closed-loop optimization uses those traces to improve instructions, tool descriptions, and model selection without extra plumbing. The real cost is the velocity gap Leaders usually expect me to quantify the initial build, and that is the smaller number. A team of four building the first agent often becomes ten or twelve within a year, and a growing share of them are maintaining a runtime for agents rather than building agents that serve the business. The enterprise has quietly created an internal agent infrastructure company in a field where the patterns for memory, tools, evaluation, and safety are rewritten every few months, while hyperscalers put hundreds of engineers on exactly this problem and ship at a cadence no single platform group can match. Foundry Agent Service, for instance, bundle content safety guardrails into the runtime and route outbound traffic through a customer virtual network, capabilities that platform teams otherwise assemble one integration at a time. This plumbing does not differentiate your organization, so the question is whether your scarcest engineers should spend years on it or on the workflows, data, and judgment only your company has. This is also why the technology companies held up as examples are a poor template. Many built their own runtimes because managed options did not yet exist and had large platform organizations to carry the load. Even they tend to invest in a custom runtime for the first handful of use cases and then migrate as managed services mature, because the maintenance burden compounds while the strategic value of owning the plumbing does not. What I would do as the leader I am not arguing against Kubernetes or for moving everything tomorrow. Comparable managed runtimes exist across the hyperscalers, and I use hosted agents as the running example only because it is the one I know best from the inside. Managed agent services are still maturing, some workloads have real data residency or customization needs, and abstraction always constrains something. What I am arguing for is a deliberate choice for each use case, guided by three questions: whether the agent must outlive a single request by running long, waiting on humans, or remembering across sessions whether it must act with its own identity, auditable delegation, and policy enforcement whether your team would be building anything a managed service already provides, and who will still maintain it in two years. Key takeaways Match the runtime to the workload. Containers on your existing cluster suit stateless, short-lived agents, while long-running, human-in-the-loop, and memory-dependent agents need capabilities your platform team was never hired to build. Count the hidden team. The real cost of self-hosting is the growing group of engineers maintaining state, identity, memory, guardrails, and tracing instead of solving business problems. Make evaluation continuous and connected to production traces. Pre-release testing alone will miss the drift and trajectory failures that hurt you, and optimization of quality, cost, and latency depends on that evaluation data. Follow the pattern of the leaders, not their early architecture. Companies that built custom runtimes did so before managed options matured, and most of them move toward managed services as those options improve. A practical place to begin is your roadmap for the next twelve months. Sort each use case into stateless and short-lived or long-running and human-dependent, and for every agent in the second group put a price on the engineers who would maintain the runtime rather than the business logic. I would like to hear how you have drawn this line, and where a managed service was not yet ready for something you needed.466Views2likes0Comments
Ignite 2024: Streamlining AI Development with an Enhanced User Interface, Accessibility, and Learning Experiences in Azure AI Foundry portal
Announcing Azure AI Foundry, a unified platform that simplifies AI development and management. The platform portal (formerly Azure AI Studio) features a revamped user interface, enhanced model catalog, new management center, improved accessibility and learning, making it easier than ever for Developers and IT Admins to design, customize, and manage AI apps and agents efficiently.6.7KViews2likes0CommentsGemma 4 now available in Microsoft Foundry
Experimenting with open-source models has become a core part of how innovative AI teams stay competitive: experimenting with the latest architectures and often fine-tuning on proprietary data to achieve lower latencies and cost. Today, we’re happy to announce that the Gemma 4 family, Google DeepMind’s newest model family, is now available in Microsoft Foundry via the Hugging Face collection. Azure customers can now discover, evaluate, and deploy Gemma 4 inside their Azure environment with the same policies they rely on for every other workload. Foundry is the only hyperscaler platform where developers can access OpenAI, Anthropic, Gemma, and over 11,000+ models under a single control plane. Through our close collaboration with Hugging Face, Gemma 4 joining that collection continues Microsoft’s push to bring customers the widest selection of models from any cloud – and fits in line with our enhanced investments in open-source development. Frontier Intelligence, open-source weights Released by Google DeepMind on April 2, 2026, Gemma 4 is built from the same research foundation as Gemini 3 and packaged as open weights under an Apache 2.0 license. Key capabilities across the Gemma 4 family: Native multimodal: Text + image + video inputs across all sizes; analyze video by processing sequences of frames; audio input on edge models (E2B, E4B) Enhanced reasoning & coding capabilities: Multi-step planning, deep logic, and improvements in math and instruction-following enabling autonomous agents Trained for global deployment: Pretrained on 140+ languages with support for 35+ languages out of the box Long context: Context windows of up to 128K tokens (E2B/E4B) and 256K tokens (26B A4B/31B) allow developers to reason across extensive codebases, lengthy documents, or multi-session histories Why choose Foundry? Foundry is built to give developers breadth -- access to models from major model providers, open and proprietary, under one roof. Stay within Azure to work leading models. When you deploy through Foundry, models run inside your Azure environment and are subject to the same network policies, identity controls, and audit processes your organization already has in place. Managed online endpoints handle serving, scaling, and monitoring without manually setting up and managing the underlying infrastructure. Serverless deployment with Azure Container Apps allows developers to deploy and run containerized applications while reducing infrastructure management and saving costs. Gated model access integrates directly with Hugging Face user tokens, so models that require license acceptance stay compliant can be accessed without manual approvals. Foundry Local lets you run optimized Hugging Face models directly on your own hardware using the same model catalog and SDK patterns as your cloud deployments. Read the documentation here: https://aka.ms/foundrylocal and https://aka.ms/HF/foundrylocal Microsoft’s approach to Responsible AI is grounded in our AI principles of fairness, reliability and safety, privacy and security, inclusiveness, transparency, and accountability. Microsoft Foundry provides governance controls, monitoring, and evaluation capabilities to help organizations deploy new models responsibly in production environments. What are teams building with Gemma 4 in Foundry Gemma 4’s combination of multimodal input, agentic function calling, and long context offers a wide range of production use cases: Document intelligence: Processing PDFs, charts, invoices, and complex tables using native vision capabilities Multilingual enterprise apps: 140+ natively trained languages — ideal for multinational customer support, content platforms as well as language learning tools for grammar correction and writing practice Long-context analytics: Reasoning across entire codebases, legal documents, or multi-session conversation histories Getting started Try Gemma 4 in Microsoft Foundry today. New models from Hugging Face continue to roll out to Foundry on a regular basis through our ongoing collaboration. If there's a model you want to see added, let us know here. Stay connected to our developer community on Discord and stay up to date on what is new in Foundry through the Model Mondays series.4.8KViews1like0CommentsGenerally Available: Evaluations, Monitoring, and Tracing in Microsoft Foundry
If you've shipped an AI agent to production, you've likely run into the same uncomfortable realization: the hard part isn't getting the agent to work - it's keeping it working. Models get updated, prompts get tweaked, retrieval pipelines drift, and user traffic surfaces edge cases that never appeared in your eval suite. Quality isn't something you establish once. It's something you have to continuously measure. Today, we're making that continuous measurement a first-class operational capability. Evaluations, Monitoring, and Tracing in Microsoft Foundry are now generally available through Foundry Control Plane. These aren't standalone tools bolted onto the side of the platform - they're deeply integrated with Azure Monitor, which means AI agent observability now lives in the same operational plane as the rest of your infrastructure. The Problem With Point-in-Time Evaluation Most evaluation workflows are designed around a pre-deployment gate. You build a test dataset, run your evals, review the scores, and ship. That approach has real value - but it has a hard ceiling. In production, agent behavior is a function of many things that change independently of your code: Foundation model updates ship continuously and can shift output style, reasoning patterns, and edge case handling in ways that don't always surface on your benchmark set. Prompt changes can have nonlinear effects downstream, especially in multi-step agentic flows. Retrieval pipeline drift changes what context your agent actually sees at inference time. A document index fresh last month may have stale or subtly different content today. Real-world traffic distribution is never exactly what you sampled for your test set. Production surfaces long-tail inputs that feel obvious in hindsight but were invisible during development. The implication is straightforward: evaluation has to be continuous, not episodic. You need quality signals at development time, at every CI/CD commit, and continuously against live production traffic - all using the same evaluator definitions so results are comparable across environments. That's the core design principle behind Foundry Observability. Continuous Evaluation Across the Full AI Lifecycle Built-In Evaluators Foundry's built-in evaluators cover the most critical quality and safety dimensions for production agent systems: Coherence and Relevance measure whether responses are internally consistent and on-topic relative to the input. These are table-stakes signals for any conversational or task-completion agent. Groundedness is particularly important for RAG-based architectures. It measures whether the model's output is actually supported by the retrieved context - as opposed to plausible-sounding content the model generated from its parametric memory. Groundedness failures are a leading indicator of hallucination risk in production, and they're often invisible to human reviewers at scale. Retrieval Quality evaluates the retrieval step independently from generation. Groundedness failures can originate in two places: the model may be ignoring good context, or the retrieval pipeline may not be surfacing relevant context in the first place. Splitting these signals makes it much easier to pinpoint root cause. Safety and Policy Alignment evaluates whether outputs meet your deployment's policy requirements - content safety, topic restrictions, response format compliance, and similar constraints. These evaluators are designed to run at every stage of the AI lifecycle: Local development - run evals inline as you iterate on prompts, retrieval config, or orchestration logic CI/CD pipelines - gate every commit against your quality baselines; catch regressions before they reach production Production traffic monitoring - continuously evaluate sampled live traffic and surface trends over time Because the evaluators are identical across all three contexts, a score in CI means the same thing as a score in production monitoring. See the Practical Guide to Evaluations and the Built-in Evaluators Reference for a deeper walkthrough. Custom Evaluators - Encoding Your Own Definition of Quality Built-in evaluators cover common signals well, but production agents often need to satisfy criteria specific to a domain, regulatory environment, or internal standard. Foundry supports two types of custom evaluators (currently in public preview): LLM-as-a-Judge evaluators let you configure a prompt and grading rubric, then use a language model to apply that rubric to your agent's outputs. This is the right approach for quality dimensions that require reasoning or contextual judgment - whether a response appropriately acknowledges uncertainty, whether a customer-facing message matches your brand tone, or whether a clinical summary meets documentation standards. You write a judge prompt with a scoring scale (e.g., 1–5 with criteria for each level) that evaluates a given {input} / {response} pair. Foundry runs this at scale and aggregates scores into your dashboards alongside built-in results. Code-based evaluators are Python functions that implement any evaluation logic you can express programmatically - regex matching, schema validation, business rule checks, compliance assertions, or calls to external systems. If your organization has documented policies about what a valid agent response looks like, you can encode those policies directly into your evaluation pipeline. Custom and built-in evaluators compose naturally - running against the same traffic, producing results in the same schema, feeding into the same dashboards and alert rules. Monitoring and Alerting - AI Quality as an Operational Signal All observability data produced by Foundry - evaluation results, traces, latency, token usage, and quality metrics - is published directly to Azure Monitor. This is where the integration pays off for teams already on Azure. What this enables that siloed AI monitoring tools can't: Cross-stack correlation. When your groundedness score drops, is it a model update, a retrieval pipeline issue, or an infrastructure problem affecting latency? With AI quality signals and infrastructure telemetry in the same Azure Monitor Application Insights workspace, you can answer that in minutes rather than hours of manual correlation across disconnected systems. Unified alerting. Configure Azure Monitor alert rules on any evaluation metric - trigger a PagerDuty incident when groundedness drops below threshold, send a Teams notification when safety violations spike, or create automated runbook responses when retrieval quality degrades. These are the same alert mechanisms your SRE team already uses. Enterprise governance by default. Azure Monitor's RBAC, retention policies, diagnostic settings, and audit logging apply automatically to all AI observability data. You inherit the governance framework your organization has already built and approved. Grafana and existing dashboards. If your team uses Azure Managed Grafana, evaluation metrics can flow into existing dashboards alongside your other operational metrics - a single pane of glass for application health, infrastructure performance, and AI agent quality. The Agent Monitoring Dashboard in the Foundry portal provides an AI-native view out of the box - evaluation metric trends, safety threshold status, quality score distributions, and latency breakdowns. Everything in that dashboard is backed by Azure Monitor data, so SRE teams can always drill deeper. End-to-End Tracing: From Quality Signal to Root Cause A groundedness score tells you something is wrong. A trace tells you exactly where the failure occurred and what the agent actually did. Foundry provides OpenTelemetry-based distributed tracing that follows each request through your entire agent system: model calls, tool invocations, retrieval steps, orchestration logic, and cross-agent handoffs. Traces capture the full execution path - inputs, outputs, latency at each step, tool call parameters and responses, and token usage. The key design decision: evaluation results are linked directly to traces. When you see a low groundedness score in your monitoring dashboard, you navigate directly to the specific trace that produced it - no manual timestamp correlation, no separate trace ID lookup. The connection is made automatically. Foundry auto-collects traces across the frameworks your agents are likely already built on: Microsoft Agent Framework Semantic Kernel LangChain and LangGraph OpenAI Agents SDK For custom or less common orchestration frameworks, the Azure Monitor OpenTelemetry Distro provides an instrumentation path. Microsoft is also contributing upstream to the OpenTelemetry project - working with Cisco Outshift, we've contributed semantic conventions for multi-agent trace correlation, standardizing how agent identity, task context, and cross-agent handoffs are represented in OTel spans. Note: Tracing is currently in public preview, with GA shipping by end of March. Prompt Optimizer (Public Preview) One persistent friction point in agent development is the iteration loop between writing prompts and measuring their effect. You make a change, run your evals, look at the delta, try to infer what about the change mattered, and repeat. Prompt Optimizer tightens this loop. It analyzes your existing prompt and applies structured prompt engineering techniques - clarifying ambiguous instructions, improving formatting for model comprehension, restructuring few-shot examples, making implicit constraints explicit - with paragraph-level explanations for every change it makes. The transparency is deliberate. Rather than producing a black-box "optimized" prompt, it shows you exactly what it changed and why. You can add constraints, trigger another optimization pass, and iterate until satisfied. When you're done, apply it with one click. The value compounds alongside continuous evaluation: run your eval suite against the current prompt, optimize, run evals again, see the measured improvement. That feedback loop - optimize, measure, optimize - is the closest thing to a systematic approach to prompt engineering that currently exists. What Makes our Approach to Observability Different There are other evaluation and observability tools in the AI ecosystem. The differentiation in Foundry's approach comes down to specific architectural choices: Unified lifecycle coverage, not just pre-deployment testing. Most existing evaluation tools are designed for offline, pre-deployment use. Foundry's evaluators run in the same form at development time, in CI/CD, and against live production traffic. Your quality metrics are actually comparable across the lifecycle - you can tell whether production quality matches what you saw in testing, rather than operating two separate measurement systems that can't be compared. No separate observability silo. Publishing all observability data to Azure Monitor means you don't operate a separate system for AI quality alongside your existing infrastructure monitoring. AI incidents route through your existing on-call rotations. AI quality data is subject to the same retention and compliance controls as the rest of your telemetry. Framework-agnostic tracing. Auto-instrumentation across Semantic Kernel, LangChain, LangGraph, and the OpenAI Agents SDK means you're not locked into a specific orchestration framework. The OpenTelemetry foundation means trace data is portable to any compatible backend, protecting your investment as the tooling landscape evolves. Composable evaluators. Built-in and custom evaluators run in the same pipeline, against the same traffic, producing results in the same schema, feeding into the same dashboards and alert rules. You don't choose between generic coverage and domain-specific precision - you get both. Evaluation linked to traces. Most systems treat evaluation and tracing as separate concerns. Foundry treats them as two views of the same event - closing the loop between detecting a quality problem and diagnosing it. Getting Started If you're building agents on Microsoft Foundry, or using Semantic Kernel, LangChain, LangGraph, or the OpenAI Agents SDK and want to add production observability, the entry point is Foundry Control Plane. Try it You'll need a Foundry project with an agent and an Azure OpenAI deployment. Enable observability by navigating to Foundry Control Plane and connecting your Azure Monitor workspace. Then walk through the Practical Guide to Evaluations, explore the Built-in Evaluators Reference, and set up end-to-end tracing for your agents.5.2KViews1like0CommentsMicrosoft Foundry: An End-to-End Platform for Building, Governing, and Scaling AI
Microsoft Foundry: What It Is and How to Get Started As organizations accelerate their adoption of AI, one challenge consistently emerges: how to move from experimentation to production at scale in a secure, responsible, and efficient way. Microsoft Foundry exists to address exactly that challenge. What Is Microsoft Foundry? Microsoft Foundry is an end-to-end platform experience that brings together Microsoft’s AI development, deployment, and governance capabilities into a unified environment. It enables developers, data scientists, and enterprises to build, customize, deploy, and operate AI solutions, including generative AI, using Microsoft and partner models, tools, and services. Rather than being a single product, Foundry is a curated and integrated experience that spans model access, tooling, orchestration, evaluation, and enterprise-grade controls. Why Microsoft Foundry Exists AI innovation is moving fast, but enterprise adoption requires more than just access to models. Customers need: A consistent way to work with multiple models, including Microsoft, OpenAI, and open-source models Built-in security, compliance, and responsible AI capabilities Tooling that supports the full AI lifecycle, not just prototyping Seamless integration with existing data platforms, applications, and cloud operations Microsoft Foundry was created to reduce friction between experimentation and real-world deployment while aligning AI development with enterprise standards, governance, and scale. What’s Included in Microsoft Foundry? Microsoft Foundry brings together several key capabilities: 1. Model Choice and Flexibility Access to leading foundation models, including Azure OpenAI models and selected open-source models Ability to evaluate and select models based on performance, cost, and use case 2. AI Development and Orchestration Tools Prompt engineering, fine-tuning, and grounding with enterprise data Tools for building copilots, chat experiences, and AI-powered applications Orchestration across tools, APIs, and workflows 3. Evaluation, Safety, and Responsible AI Built-in evaluation for quality, latency, and cost Content safety, monitoring, and governance controls Alignment with Microsoft’s Responsible AI principles 4. Enterprise-Grade Platform Integration Native integration with Azure, Microsoft Fabric, Power Platform, and developer tools Identity, security, and compliance through Microsoft Entra and Azure controls Observability and lifecycle management for production workloads How to Get Started Getting started with Microsoft Foundry is straightforward: Start in Azure - Use Azure as the control plane to access Foundry experiences and services. Explore models and tools - Experiment with available models, build prompts, and prototype AI workflows. Ground with your data - Connect enterprise data securely to create more relevant and contextual AI experiences. Evaluate and deploy - Use built-in evaluation and safety tools, then deploy AI solutions into production with confidence. Scale responsibly - Apply governance, monitoring, and cost controls as adoption grows. Final Thoughts Microsoft Foundry represents Microsoft’s vision for enterprise AI done right. It offers flexible model choice, strong development tooling, and built-in trust. By unifying AI development and operations into a single experience, Foundry helps organizations move faster while staying secure, compliant, and future-ready. Whether you are just starting with generative AI or scaling existing solutions, Microsoft Foundry provides a practical foundation to build on.1.8KViews1like0CommentsImplementing MCP Remote Servers with Azure Function App and GitHub Copilot Integration
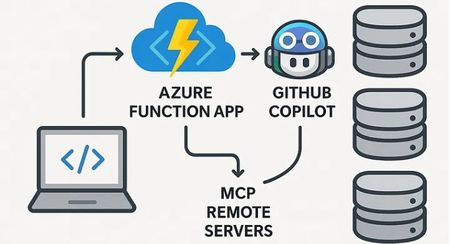
Introduction In the evolving landscape of AI-driven applications, the ability to seamlessly connect large language models (LLMs) with external tools and data sources is becoming a cornerstone of intelligent system design. Model Context Protocol (MCP) — a specification that enables AI agents to discover and invoke tools dynamically, based on context. While MCP is powerful, implementing it from scratch can be daunting !!! That’s where Azure Functions comes in handy. With its event-driven, serverless architecture, Azure Functions now supports a preview extension for MCP, allowing developers to build remote MCP servers that are scalable, secure, and cloud-native. Further, In VS Code, GitHub Copilot Chat in Agent Mode can connect to your deployed Azure Function App acting as an MCP server. This connection allows Copilot to leverage the tools and services exposed by your function app. Why Use Azure Functions for MCP? Serverless Simplicity: Deploy MCP endpoints without managing infrastructure. Secure by Design: Leverage HTTPS, system keys, and OAuth via EasyAuth or API Management. Language Flexibility: Build in .NET, Python, or Node.js using QuickStart templates. AI Integration: Enable GitHub Copilot, VS Code, or other AI agents to invoke your tools via SSE endpoints. Prerequisites Python version 3.11 or higher Azure Functions Core Tools >= 4.0.7030 Azure Developer CLI To use Visual Studio Code to run and debug locally: Visual Studio Code Azure Functions extension An storage emulator is needed when developing azure function app in VScode. you can deploy Azurite extension in VScode to meet this requirement. Press enter or click to view image in full size You can run the Azurite in VS Code as shown below. C:\Program Files\Microsoft Visual Studio\2022\Enterprise\Common7\IDE\Extensions\Microsoft\Azure Storage Emulator> .\azurite.exe Press enter or click to view image in full size alternatively, you can also run Azurite in docker container as shown below. docker run -p 10000:10000 -p 10001:10001 -p 10002:10002 \ mcr.microsoft.com/azure-storage/azurite For more information about setting up Azurite, visit Use Azurite emulator for local Azure Storage development | Microsoft Learn Github Repositories Following Github repos are needed to setup this PoC. Repository for MCP server using Azure Function App https://github.com/mafzal786/mcp-azure-functions-python.git Repository for AI Foundry agent as MCP Client https://github.com/mafzal786/ai-foundry-agent-with-remote-mcp-using-azure-functionapp.git Clone the repository Run the following command to clone the repository to start building your MCP server using Azure function app. git clone https://github.com/mafzal786/mcp-azure-functions-python.git Run the MCP server in VS Code Once cloned. Open the folder in VS Code. Create a virtual environment in VS Code. Change directory to “src” in a new terminal window, install the python dependencies and start the function host locally as shown below. cd src pip install -r requirements.txt func start Note: by default this will use the webhooks route: /runtime/webhooks/mcp/sse. Later we will use this in Azure to set the key on client/host calls: /runtime/webhooks/mcp/sse?code=<system_key> Press enter or click to view image in full size MCP Inspector In a new terminal window, install and run MCP Inspector. npx @modelcontextprotocol/inspector Click to load the MCP inspector. Also provide the generated proxy session token. http://127.0.0.1:6274/#resources In the URL type and click “Connect”: http://localhost:7071/runtime/webhooks/mcp/sse Once connected, click List Tools under Tools and select “hello_mcp” tool and click “Run Tool” for testing as shown below. Press enter or click to view image in full size Select another tool such as get_stockprice and run it as shown below. Press enter or click to view image in full size Deploy Function App to Azure from VS Code For deploying function app to azure from vs code, make sure you have Azure Tools extension enabled in VS Code. To learn more about Azure Tools extension, visit the following Azure Extensions if your VS code environment is not setup for Azure development, follow Configure Visual Studio Code for Azure development with .NET — .NET | Microsoft Learn Once Azure Tools are setup, sign in to Azure account with Azure Tools Press enter or click to view image in full size Once Sign-in is completed, you should be able to see all of your existing resources in the Resources view. These resources can be managed directly in VS Code. Look for Function App in Resource, right click and click “Deploy to Function App”. Press enter or click to view image in full size If you already have it deployed, you will get the following pop-up. Click “Deploy” Press enter or click to view image in full size This will start deploying your function app to Azure. In VS Code, Azure tab will display the following. Press enter or click to view image in full size Once the deployment is completed, you can view the function app and all the tools in Azure portal under function app as shown below. Press enter or click to view image in full size Get the mcp_extension key from Functions → App Keys in Function App. Press enter or click to view image in full size This mcp_extension key would be needed in mcp.json file in VS code, if you would like to test the MCP server using Github Copilot in VS Code. Your entries in mcp.json file will look like as below for example. { "inputs": [ { "type": "promptString", "id": "functions-mcp-extension-system-key", "description": "Azure Functions MCP Extension System Key", "password": true }, { "type": "promptString", "id": "functionapp-name", "description": "Azure Functions App Name" } ], "servers": { "remote-mcp-function": { "type": "sse", "url": "https://${input:functionapp-name}.azurewebsites.net/runtime/webhooks/mcp/sse", "headers": { "x-functions-key": "${input:functions-mcp-extension-system-key}" } }, "local-mcp-function": { "type": "sse", "url": "http://0.0.0.0:7071/runtime/webhooks/mcp/sse" } } } Test Azure Function MCP Server in MCP Inspector Launch MCP Inspector and provide the Azure Function in MCP inspector URL. Provide authentication as shown below. Bearer token is mcp_extension key. Testing an MCP server with GitHub Copilot Testing an MCP server with GitHub Copilot involves configuring and utilizing the server within your development environment to provide enhanced context and capabilities to Copilot Chat. Steps to Test an MCP Server with GitHub Copilot: Ensure Agent Mode is Enabled: Open Copilot Chat in Visual Studio Code and select “Agent” mode. This mode allows Copilot to interact with external tools and services, including MCP servers. Add the MCP Server: Open the Command Palette (Ctrl+Shift+P or Cmd+Shift+P) and run the command MCP: Add Server. Press enter or click to view image in full size Follow the prompts to configure the server. You can choose to add it to your workspace settings (creating a .vscode/mcp.json file) . Select HTTP or Server-Sent events Press enter or click to view image in full size Specify the URL and click Enter Press enter or click to view image in full size Provide a name of your choice Press enter or click to view image in full size Select scope as Global or workspace. I selected Workspace Press enter or click to view image in full size This will generate mcp.json file in .vscode or create a new entry if mcp.json already exists as shown below. Click Start to “start” the server. Also make sure your Azure function app is locally running with func start command. Press enter or click to view image in full size Now Type the prompt as shown below. Press enter or click to view image in full size Try another tool as below. Press enter or click to view image in full size VS code terminal output for reference. Press enter or click to view image in full size Testing an MCP server with Claude Desktop Claude Desktop is a standalone AI application that allows users to interact with Claude AI models directly from their desktop, providing a seamless and efficient experience. you can download Claude desktop at Download Claude In this article, I have added another tool to utilize to test your MCP server running in Azure Function app. Modify claude_desktop_config.json with the following. you can find this file in window environment at C:\Users\<username>\AppData\Roaming\Claude { "mcpServers": { "my mcp": { "command": "npx", "args": [ "mcp-remote", "http://localhost:7071/runtime/webhooks/mcp/sse" ] } } } Note: If claude_desktop_config.json does not exists, click on setting in Claude desktop under user and visit developer tab. You will see you MCP server in Claude Desktop as shown below. Press enter or click to view image in full size Type the prompt such as “What is the stock price of Tesla” . After submitting, you will notice that it is invoking the tool “get_stockprice” from the MCP server running locally and configured in the .json earlier. Click Allow once or Allow always as shown below. Following output will be displayed. Press enter or click to view image in full size Now lets try weather related prompt. As you can see, it has invoked “get_weatheralerts” tool from MCP server. Press enter or click to view image in full size Azure AI Foundry agent as MCP Client Use the following Github repo to set up Azure AI Foundry agent as MCP client. git clone https://github.com/mafzal786/ai-foundry-agent-with-remote-mcp-using-azure-functionapp.git Open the code in VS code and follow the instructions mentioned in README.md file at Github repo. Once you execute the code, following output will show up in VS code. Press enter or click to view image in full size In this code, message is hard coded. Change the content to “what is weather advisory for Florida” and rerun the program. It will call get_weatheralerts tool and output will look like as below. Press enter or click to view image in full size Conclusion The integration of Model Context Protocol (MCP) with Azure Functions marks a pivotal step in democratizing AI agent development. By leveraging Azure’s serverless architecture, developers can now build remote MCP servers that scale automatically, integrate seamlessly with other Azure services, and expose modular tools to intelligent agents like GitHub Copilot. This setup not only simplifies the deployment and management of MCP servers but also enhances the developer experience — allowing tools to be invoked contextually by AI agents in environments like VS Code, GitHub Codespaces, or Copilot Studio[2]. Whether you’re building a tool to query logs, calculate metrics, or manage data, Azure Functions provides the flexibility, security, and scalability needed to bring your AI-powered workflows to life. As the MCP spec continues to evolve, and GitHub Copilot expands its agentic capabilities, this architecture positions you to stay ahead — offering a robust foundation for cloud-native AI tooling that’s both powerful and future-proof.2.2KViews1like1CommentThe Future of AI: Developing Lacuna - an agent for Revealing Quiet Assumptions in Product Design
A conversational agent named Lacuna is helping product teams uncover hidden assumptions embedded in design decisions. Built with Copilot Studio and powered by Azure AI Foundry, Lacuna analyzes product documents to identify speculative beliefs and assess their risk using design analysis lenses: impact, confidence, and reversibility. By surfacing cognitive biases and prompting reflection, Lacuna encourages teams to validate assumptions through lightweight evidence-gathering methods. This experiment in human-AI collaboration explores how agents can foster epistemic humility and transform static documents into dynamic conversations.772Views1like1Comment