devops
433 TopicsAzure DevOps in 2026: Are We Moving Towards Fully AI-Driven DevOps Pipelines?
With AI becoming increasingly integrated into software development and IT operations, I've been thinking about how the role of Azure DevOps might evolve over the next few years. Traditionally, Azure DevOps has helped teams manage repositories, CI/CD pipelines, testing, artifacts, and project delivery. But with the growing adoption of AI agents, automated code reviews, intelligent monitoring, and predictive analytics, could we be approaching a new era of autonomous DevOps? I'm particularly interested in exploring a few questions: 1. AI-powered CI/CD: How far are we from pipelines that can identify issues, recommend fixes, and optimize deployments with minimal human intervention? 2. Azure DevOps vs. GitHub: With GitHub Actions and AI-assisted development becoming increasingly popular, how do you see the long-term positioning of Azure DevOps? 3. Intelligent infrastructure management: Can AI agents eventually manage deployment decisions, infrastructure optimization, and incident response while maintaining appropriate human oversight? 4. Security and governance: How should organizations balance automation with compliance, accountability, and security? 5. The future of DevOps engineers: Will AI primarily assist DevOps professionals, or fundamentally transform their responsibilities? I believe the next major evolution in DevOps won't simply be faster automation, but systems capable of making increasingly intelligent, auditable operational decisions. I'd love to hear from the Microsoft Tech Community: What AI-driven DevOps capabilities are you already implementing, and what do you believe will become mainstream over the next three to five years? Looking forward to learning from your experiences and perspectives.143Views0likes1Comment
Legacy SSRS reports after upgrading Azure DevOps Server 2020 to 2022 or 25H2
We are currently planning an upgrade from Azure DevOps Server 2020 to Azure DevOps Server 2022 or 25H2, and one of our biggest concerns is reporting. We understand that Microsoft’s recommended direction is to move to Power BI based on Analytics / OData. However, for on-prem environments with a large number of existing SSRS reports, rebuilding everything from scratch would require significant time and effort. Since Warehouse and Analysis Services are no longer available in newer versions, we would like to understand how other on-prem teams are handling legacy SSRS reporting during and after the upgrade. Have you rebuilt your reports in Power BI, moved to another reporting approach, or found a practical way to keep existing SSRS reports available during the transition? Any real-world experience, lessons learned, or recommended approaches would be greatly appreciated.527Views0likes4CommentsEnhanced Feature Flags: A New Foundation for Feature Management in Azure App Configuration
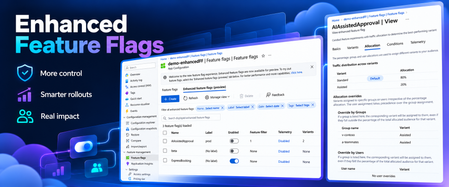
Shipping is no longer just about deploying code. Consider a team introducing a new checkout experience. The code is already in production, but the team wants to expose it to a small audience, gradually increase availability, monitor the results, and retain the ability to turn it off if something goes wrong. Feature flags make that possible without requiring another deployment. As feature flags become increasingly central to how software is released and operated, we saw an opportunity to evolve how they’re represented in Azure App Configuration. Enhanced Feature Flags are available in public preview, with a dedicated resource model designed specifically for feature management. Why rethink the feature flag resource model? Consider a team preparing to launch a new check out experience. The release manager needs to control when the feature becomes available but shouldn’t necessarily have permission to modify payment settings or other application configuration. With traditional feature flags sharing the same key-value resource and permission model as application configuration, separating these responsibilities isn’t possible. Similarly existing SDKS and tooling simplify feature flag management; the underlying APIs still treat flags as specially formatted configuration entries rather than resources with their own defined structure. These are not challenges with feature evaluation itself. They're challenges with how feature flags are represented, managed, and governed. Enhanced Feature Flags address this by introducing a purpose-built resource model, with dedicated APIs and separate access control. What changes with Enhanced Feature Flags? The new model introduces several important improvements. 1. Feature management gets its own security boundary Feature flags often change application behavior in production, and the people responsible for those changes may not be the same people responsible for application configuration. With Enhanced Feature Flags, organizations can grant access to feature flag resources independently of configuration key-values. A team responsible for feature rollout, for example, can manage flags without also receiving permission to modify unrelated application settings. This creates a clearer security boundary for applying least privilege access to feature management. 2. Feature flags get a dedicated API surface Previously, managing feature flags through configuration APIs required clients and automation to understand specific naming conventions, content types, and serialized feature definitions. Enhanced Feature Flags expose dedicated APIs for creating, querying, updating, and deleting flags. The benefit isn't simply another API. Tools and deployment workflows can now work directly with a resource designed for feature management instead of interpreting a feature flag stored as configuration. 3. Validation moves closer to the source Enhanced Feature Flags have a defined resource schema that Azure App Configuration can validate when a flag is created or updated. Malformed definitions can be rejected before they are stored, providing consistent validation across clients and tooling. Existing feature management capabilities continue to work Enhanced Feature Flags build on the feature management capabilities already available in Azure App Configuration, including targeting, variants, allocation, and telemetry. Applications can continue using their existing feature evaluation logic with supported versions of the App Configuration provider libraries. And importantly, existing key-value-based feature flags remain supported. Teams can evaluate the new model alongside their current flags, rather than treating this preview as a mandatory migration. See Enhanced Feature Flags in action Watch this short demo to learn how granular role-based access control enables teams to manage feature releases independently while keeping application configuration protected. A foundation for what comes next Enhanced Feature Flags solve concrete management and governance challenges today, but the opportunity goes further. Giving feature flags their own resource model creates room for feature management to evolve independently from general application configuration, with deeper investments in areas such as automation, governance, targeting, and connecting feature delivery to application outcomes. The longer-term opportunity is to make managing a feature throughout its lifecycle as natural as developing and deploying it. Enhanced Feature Flags are available now in public preview in Azure App Configuration. If you're building a new application or evolving your feature management workflows, explore the new resource model and let us know what you think. We want Enhanced Feature Flags to provide the foundation for the next generation of feature management in Azure App Configuration, and your feedback will help shape where we take it next. Learn about Enhanced Feature Flags Explore the Enhanced Feature Flags REST API Share feedback with the Azure App Configuration team #Azure #AzureAppConfiguration #FeatureFlags #FeatureManagement #DeveloperExperience416Views2likes0CommentsIntroducing AIVANA Decision Intelligence for Azure Boards
A backlog can contain all the right work items and still leave important questions unanswered. Does a user story have acceptance criteria? Who owns a blocked task? Which items have stopped moving? I’m developing AIVANA Decision Intelligence, an extension for Azure Boards that brings these questions into a focused review of backlog quality and delivery signals. The goal is to help teams identify items that need attention and understand the evidence behind each finding. What the current version does AIVANA Decision Intelligence reads work items from an accessible Azure DevOps Services project and applies explainable rules to highlight: Missing descriptions, acceptance criteria or assigned owners. Work items with identical titles that may warrant a duplicate review. Explicitly blocked or stagnant items. Overdue items where a due-date field is available. Each finding includes its source and a suggested next step. Teams can inspect the underlying work item and decide whether the finding matters in their context. An identical title, for example, is a reason to investigate—not proof that two requirements are duplicates. Optional AI-assisted review The extension also includes an optional AI-assisted review of selected work-item text. This requires explicit approval to transmit the selected content and an active organization license. AI suggestions remain subject to review by the team. The extension does not automatically modify work items. The current version focuses on backlog review and explainable findings. It is available as a technical preview, with live installation and commercial release checks still being completed. A practical starting point One way to evaluate AIVANA Decision Intelligence is during backlog refinement: Review the findings for a project. Check the source behind each relevant finding. Agree which items need clarification, ownership or follow-up. Compare the findings with the team’s existing review process. The useful question is whether the extension surfaces issues that deserve attention without creating unnecessary noise. That is something I want to evaluate with real teams. I’d welcome your feedback How does your team currently check backlog quality in Azure Boards? Which checks are useful, and which tend to produce false positives? I’m particularly interested in how teams define stagnation and handle acceptance criteria across different work-item types. Website: https://www.aivana-gmbh.ai Disclosure: I’m involved in developing AIVANA Decision Intelligence.74Views0likes0Comments
Enterprise Adoption Guide for Azure SRE Agent, Part 1: Deploying Your First Azure SRE Agent
We have learned a lot from talking with teams that are bringing Azure SRE Agent into their day-to-day operations. Across those conversations, we have seen a common set of questions emerge as teams move from exploring an initial use case to adopting SRE Agent more broadly. Some teams are starting with a simple question: “Where should we begin?” Others have already seen value in reducing operational toil and improving incident response and are asking what comes next. How do we expand from one successful use case to more workflows? Can multiple teams share the same agent safely? When should we use one SRE Agent versus multiple agents? How should agents collaborate? And how do we deploy and govern them consistently across the enterprise? This two-part guide shares the patterns we have seen and our recommendations for navigating that journey, from the first use case to broader enterprise adoption. Our recommendation is to start with one operational problem your team understands, learn what the agent needs to solve it effectively, and expand from there. The goal is not to design your enterprise topology on day one. It is to make each next decision with better evidence. Part 1: Deploying Your First Azure SRE Agent Which operational problem should we start with? How do I run the first use case? Should I use SRE Agent’s built-in capabilities or customize it? How do we turn a successful first use case into more automated operational workflows? Part 2: From One Team to Enterprise-Wide Adoption How do we share an SRE Agent with more users? How do we expand from one team to multiple teams, and do we need one SRE Agent or multiple? How do we codify, deploy, and govern SRE Agents at enterprise scale? Part 1 focuses on proving and expanding the operational value. Part 2 addresses the questions that appear when more users, teams, and agents become involved. 1. Which operational problem should we start with? A strong first use case is a recurring, bounded problem that the team feels today and understands well enough to judge. Focus on work that affects reliability, consumes engineering time, slows incident response, or creates avoidable cost. Start with the operational pain your team feels most. Choose one well-bounded problem that matters to the team and is familiar enough to judge. If you are unsure where to begin, start by asking SRE Agent to investigate an issue or incident your team is already looking at. Give it the observed symptom or question, let it bring together telemetry, dependencies, source code, and recent changes, and see whether it can identify where the problem is likely occurring. That investigation can include root-cause analysis, deployment correlation, Azure resource health, and dependency analysis. The examples below are some of the use cases we have seen customers implement. Alert investigation: correlate alerts with telemetry, dependencies, source code, and recent changes to explain what happened and identify the next step. Incident auto-triage: collect the initial evidence, identify likely ownership and severity, remove known false positives, and prepare the incident for the responding team. Proactive availability: perform proactive health checks, reliability risks, degraded signals, or unhealthy dependencies before they become customer-facing incidents. Deployment correlation: correlate a failure or degradation with recent deployments, configuration changes, feature releases, and infrastructure updates. Production deployment validation: evaluate post-deployment telemetry, logs, dependencies, and service-health criteria to confirm that a production release is healthy. FinOps proactive cost optimization: identify unexpected cost changes, underused resources, and rightsizing opportunities before spend becomes a larger problem. Certificate expiry monitoring: identify certificates approaching expiration, determine the affected services and owners, and initiate the appropriate follow-up. 2. How do I run the first use case? Should I use SRE Agent’s built-in capabilities or customize it? Once the team has selected the operational pain it wants to address, the next step is to prove that SRE Agent can improve the outcome. Two questions matter at this stage: how should we set up SRE Agent to execute the first use case, and do we need to customize beyond its built-in capabilities? Keep the first use case deliberately small. Connect only the context required to solve the selected problem. For deployment validation, that may be the relevant telemetry source, code repository, deployment history, and runbook, not every repository, monitoring system, or resource the team may eventually use. For more guidance on setting up the first SRE Agent, see Getting the best out of Azure SRE Agent. Begin with diagnostic or read-only access. Use the agent’s managed identity and Azure RBAC as the starting point for Azure resource access. Grant only the resource scopes and permissions required for the use case. As the workflow demonstrates a need to perform write actions, add the narrowest permission at the narrowest practical scope rather than granting broad access up front. Test the agent against a few recent historical incidents the team understands. Use these cases to confirm that the agent can reach the right telemetry, code, deployment history, and operational knowledge, and to expose missing context before a live incident. Then use SRE Agent alongside the team’s normal response process when a real issue occurs. This is where teams begin to build trust: the agent surfaces the relevant evidence, identifies where the problem is likely occurring, connects it to a dependency or recent change, explains its reasoning, and helps responders reach the diagnosis faster. Define the outcomes you want to accomplish. Measure the outcome in the system that already records it, for example, mean time to resolution in the incident platform, alert volume or false-positive rate in monitoring, deployment failure or rollback rate in CI/CD. Choose the measure that matches the pain that justified the use case. Establish a baseline, then use an SRE Agent live report or an existing dashboard to track the result. 2.1 When do I customize SRE Agent, and do I need a skill, custom subagent, or tool? Always start small with SRE Agent’s built-in capabilities. Then add only what the workflow needs. Start with the expert skills and tools that come with SRE Agent. Out of the box, SRE Agent combines Azure-specific product knowledge and built-in operational capabilities for diagnosing issues and finding probable root causes across Azure. This expertise spans all of Azure, including compute, storage, networking, data, monitoring, and management services. Its native integrations connect Azure Monitor, Application Insights, and Log Analytics, GitHub, and Azure DevOps so the agent can correlate infrastructure state, telemetry, deployments, work items, and source code. General-purpose tools, including Azure CLI, Kusto queries, and code analysis, let it gather deeper evidence within its assigned permissions. For example, it can trace network connectivity, troubleshoot gateway and load-balancing paths, query application telemetry and logs, and correlate a degradation with a recent code or deployment change. Add a custom skill when SRE Agent needs to understand how your environment or organization works. Before writing a new skill, browse the plugin marketplace and the public Azure SRE Agent Plugins repository to see whether an existing plugin covers the scenario. A skill can teach the agent how to use and interpret a third-party telemetry source such as Dynatrace, which dashboards or signals matter, how your runbooks and escalation processes work, or how your organization performs a workflow such as pull-request validation, release-risk analysis, or compliance review. Even with a native integration, adding your operating instructions as a skill can help the agent find the right evidence faster. Add a custom tool when part of the workflow must run consistently. Use deterministic code when the agent must perform the same calculation, execute a predefined query, call an external API, or generate a report in an exact format every time. A skill explains when and how your organization performs the task; a tool performs the required action consistently. Prefer an existing built-in or connector tool before adding a custom Python tool, HTTP or Kusto tool, or MCP connector. Use a skill and tool together when the workflow needs both organizational guidance and deterministic execution. For example, a skill can describe how your organization evaluates deployment risk, while a tool calculates the risk score or generates the required report. For most workflows, built-in capabilities plus a custom skill are sufficient. Add a custom tool only when the workflow requires repeatable execution, external-system access, or an exact output. 2.2 When do I need a custom subagent? A custom subagent is a specialist within SRE Agent designed for a focused operational workflow. For most use cases, start with a skill. A skill is enough when the main SRE Agent needs to understand and apply your team’s instructions as part of a broader conversation or investigation. Create a custom subagent when you want to control the scope of that workflow, package a focused set of instructions, skills, and tools, test or invoke it independently, or connect it to a trigger. The use case itself does not determine the choice. The same deployment-validation guidance can remain a skill when an engineer asks the main agent to apply it during an investigation. Package that skill in a deployment-validation agent when the workflow should stay within a defined scope, use selected tools, and run after a deployment through an incident, schedule, HTTP trigger, or another workflow. Start with a skill. Use a custom subagent when the workflow needs tighter scope, focused instructions and tools, independent invocation, or trigger-based automation. 3. How do we turn a successful first use case into more automated operational workflows? Once the first use case proves the value, look at what the team still does manually around it. Where are engineers repeatedly gathering the same evidence, running the same diagnostics, monitoring the same risks, preparing the same updates, or handing off the same follow-up work? Use live reports to bring together incident, service-health, reliability, and cost signals so recurring patterns and remaining operational toil are easier to see. When the team understands the work and the result is repeatable, it is ready to become an automated workflow. Begin with the context already connected to the agent. Reuse the same telemetry, repositories, runbooks, resource access, and team knowledge where they apply. Add another source only when the workflow needs evidence the agent cannot currently reach. There are different ways to start that automation. Use a: Response plan when an incident or alert should start the investigation Scheduled task for recurring health, capacity, compliance, or reporting work HTTP trigger when a pipeline, external monitoring system, or another workflow should invoke the agent Start these workflows in Review mode, where a person can evaluate the agent’s reasoning and proposed actions. Autonomous mode is a good fit for actions the team has already approved its operators to perform without case-by-case review. Start with a human in the loop, build confidence in the workflow, and move approved actions to Autonomous mode when the team is comfortable allowing the agent to perform them on its own. Start automating the work the team now understands. Use the right trigger for each workflow, and use live reports to make the next source of operational toil visible. Continue to Part 2: From One Team to Enterprise-Wide Adoption Every team has operational work it wishes were faster, more consistent, or less manual. What is the recurring operational problem your team would most like to solve with SRE Agent? And what could we build or improve to make it easier to turn that problem into a trusted workflow? In part 1, we explored how your organization can go from zero to one with adoption of Azure SRE Agent to address this operational toil in your organization. We'd love for you to share your experience and ideas in the comments below. Your feedback will help us understand where teams need more guidance, better starting points, or new product capabilities. To continue on to scaling Azure SRE Agent across your enterprise, go on to: Part 2: From One Team to Enterprise-Wide Adoption. Next steps Continue to Part 2: From One Team to Enterprise-Wide Adoption. Open Azure SRE Agent and start your first use case. Create and set up an Azure SRE Agent. Explore the public SRE Agent templates for infrastructure as code, export, verification, and CI/CD examples.1.4KViews0likes0Comments
Send Desk365 Ticket information to Azure DevOps
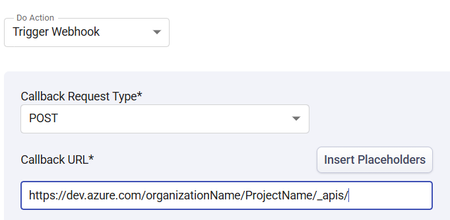
I am trying to send ticket data from Desk365 Helpdesk software to Azure DevOps. I am having trouble with what the Callback URL should be. Any ideas what URL I should be sending the Desk365 data to in order to create a workitem (Feature) in A specific Azure DevOps project? Thank you in advance!359Views0likes4CommentsEngineering an Azure Data Layer for Odoo Analytics Without Changing the ERP
One thing I have learned from working on ERP-driven data projects is that the ERP is rarely the place where you want to solve every analytics problem. We saw this firsthand in a manufacturing engagement where Odoo was being used across finance, inventory, procurement, and manufacturing, but reporting still involved substantial manual extraction and Excel-based consolidation. The interesting engineering question wasn't “How do we replace the ERP?” It was: “How do we build a reliable analytical layer around it without changing the transactional system?” That shaped the architecture. We used Odoo APIs and Azure Data Factory for ingestion, landing the data in Azure Data Lake Storage Gen2. From there, the data was organized into Bronze, Silver, and Gold layers: Bronze: Source-aligned Odoo data was retained with minimal transformation. Silver: Data was cleansed, standardized, and prepared across finance, inventory, procurement, and manufacturing domains. Gold: Analytics-ready data was prepared for downstream reporting and consumption. Azure Databricks with Spark handled transformation and KPI standardization, while Synapse/SQL layers provided structured analytical models for reporting. Power BI datasets consumed the prepared data, with Row-Level Security applied for role-based access. Why did this separation matter for the project? The important architectural boundary was: Odoo → transactional operations Azure data platform → ingestion, storage, transformation, standardization Power BI → analytical consumption That separation meant the reporting layer did not have to repeatedly extract and reshape data directly from the ERP. It also gave us a dedicated place to handle historical data and standardize information across business domains before it reached the reporting layer. What changed? The implementation automated 15+ Odoo-based reports and provided governed Power BI dashboards to 60+ business users. More importantly, teams moved away from repeated ERP extraction and spreadsheet consolidation toward a reusable analytical data layer. For our team, the bigger takeaway was that ERP modernization does not necessarily mean modifying the ERP. For teams building Azure data platforms around ERP systems, how are you drawing the boundary between API ingestion, historical storage, transformation, and analytical modeling?156Views0likes0CommentsBring Your Azure DevOps Repos to Azure SRE Agent Plugins
Plugins package the skills, agents, and connector settings your team wants every SRE Agent to have. A plugin marketplace is a Git repository that lists those plugins so any agent can install them. Until now, that repository had to be on GitHub. If your team keeps its runbooks and tooling in Azure DevOps, you had to mirror them somewhere else. Now you can point your agent at the Azure DevOps repository directly. Your team keeps authoring plugins in the repository it already uses. The agent reads from that repository and installs the plugins you choose, and a pinned version stays put until you change it. Connect a marketplace Azure DevOps marketplaces are rolling out now. You can use them today by turning on the preview feature. Open the Plugins page on your agent and select Connect marketplace . Paste the repository URL, for example https://dev.azure.com/<organization>/<project>/_git/<repository> . Sign in to Azure DevOps if the agent is not connected to that organization yet. Choose your account, a managed identity, or a personal access token. The marketplace is added as soon as the credential is saved. If the organization is already connected under Code access, the dialog uses that connection and skips the sign-in. When the repository finishes cloning, its plugins appear on the Plugins page. Select a plugin to review its skills and install it. The docs below cover each step, including managed identity setup. Use a personal access token or managed identity limited to the repositories you need rather than your own account. Try it Put one procedure your on-call team repeats into a plugin, push it to an Azure DevOps repository, and connect that repository to a test agent. If the skill runs as expected, connect the same marketplace to your other agents. Create or open your Azure SRE Agent to get started. Product documentation: Plugin marketplace overview Add a private marketplace, which now covers Azure DevOps Install a plugin from a marketplace Create a skill if you are not using a marketplace. You can build a custom skill directly in the agent, with no repository involved.574Views0likes0CommentsVirtual nodes on Azure Container Instances: a new compute layer for AKS
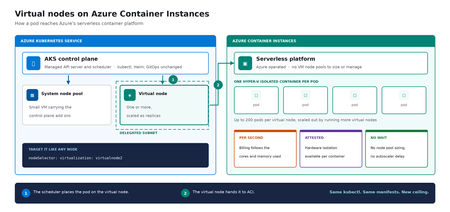
Meet virtual nodes on ACI Azure Kubernetes Service (AKS) gives you managed Kubernetes: the full Kubernetes API without operating the control plane yourself. Virtual nodes on Azure Container Instances go a step further, letting your pods run directly on Azure's serverless container platform, with the elasticity and with no capacity planning and no waiting for machines. Whether you already run AKS or want a managed Kubernetes that bursts without node management, this is for you. In short: virtual nodes on ACI attach Azure's serverless container platform to your cluster as Kubernetes nodes. Pods run as Hyper-V isolated containers, sized per pod rather than packed onto a fixed VM, up to 200 pods per virtual node. Run multiple virtual nodes, scaled as replicas, for more. They behave like any other pod: same kubectl, Helm, and GitOps. Kubernetes has always assumed a fixed set of machines underneath it. That assumption shapes everything above it: you size a node pool for a specific VM type in a specific region, you plan for peak rather than for average, and every workload on a node shares the same kernel and the same security boundary. Virtual nodes on ACI relaxs that assumption, which is what makes both elastic capacity and per container isolation possible without a different Kubernetes. If you've used the original AKS virtual nodes add-on (Virtual Kubelet based), this is not a rebrand. It is a new implementation that integrates far more deeply with Kubernetes, lifts most prior limitations (init containers, persistent volumes, managed identity, richer networking), and adds confidential containers as a first-class capability. The migration guide can be found here. Two capabilities carry the rest of this post: effortless burst capacity, and confidential containers. How virtual nodes on ACI work ACI runs every container as a Hyper-V isolated container, which means each one gets its own lightweight virtual machine boundary rather than sharing a kernel with its neighbors. Azure operates that platform. A virtual node connects it to your cluster. The cluster's control plane, the component that decides where each container runs, sees two kinds of destination: a small pool of virtual machines carrying cluster services, and one or more virtual nodes. From the application manifest's perspective, nothing changes. The pod lands on a virtual node; the virtual node hands it off to ACI. See Microsoft Learn: virtual nodes on ACI for the official capability and current limits. Virtual nodes on ACI in practice The rest of this post is hands on. You do not need to be a Kubernetes expert to follow it. kubectl is the command line tool for talking to a cluster, Helm installs packaged software into one, and a manifest is a text file describing what you want to run. If you have a cluster, everything below runs against it as written. The manifests behind the examples live in a companion demo repo. Setup is documented officially, and you can reproduce this end to end from the ACI virtual nodes documentation and the microsoft/virtualnodesOnAzureContainerInstances Helm repo. One requirement before you start: deploy into a delegated ACI subnet, meaning a subnet in your virtual network set aside for the ACI platform to place containers in. Size it for peak pod count plus headroom, since every pod consumes an address from it for its lifetime. Demo manifest files can be found in this repo, a personal sample repo provided as is and not a supported Microsoft artifact. Enable virtual nodes on ACI The virtual node is deployed via Helm. The Microsoft GitHub repo is itself a Helm repository, so a single helm install is all you strictly need. Cloning first, shown here, just makes it easier to customize values. Running kubectl get nodes afterward confirms the node registered. git clone https://github.com/microsoft/virtualnodesOnAzureContainerInstances.git helm install <yourReleaseName> ./virtualnodesOnAzureContainerInstances/Helm/virtualnode kubectl get nodes The virtual node appears alongside any existing capacity, ready to accept work. A virtual node is a Kubernetes node You target it the same way you would target any node. These few lines in a manifest say "run this on the virtual node": nodeSelector: virtualization: virtualnode2 kubernetes.io/os: linux tolerations: - key: virtual-kubelet.io/provider operator: Exists effect: NoSchedule That is the entire integration surface. No new API to learn, no separate deployment pipeline, no application changes. kubectl describe, kubectl logs, and kubectl exec, the standard commands for inspecting and troubleshooting, all work as they would anywhere else, including opening a shell inside a container running in a Hyper-V isolated boundary. Scaling stays trivial. kubectl scale deployment demo-deployment --replicas=10 lands every replica on the same virtual node, with no VMSS scale event, no provisioning latency, no climbing node-count chart. The same flow scales just as cleanly to hundreds. Cost follows the same shape. Each pod is billed per second against the cores and memory it requests, at ACI rates, and billing stops when the pod stops. Logs and metrics flow through the same path you already use, so existing dashboards and alerts keep working. One annotation makes a pod confidential Turning a regular container into a confidential one takes a single addition to its manifest: a policy that pins exactly which images, commands, environment variables, mounts, and capabilities are permitted inside the Trusted Execution Environment. The format is a base64 encoded Rego document, called a CCE (Container Confidential Enforcement) policy. You do not write that policy by hand. A tool generates it from the manifest you already have: az extension add -n confcom az confcom acipolicygen --virtual-node-yaml ./hello-world-deployment.yaml The tool pulls each image, hashes its layers, builds the allow-list, and injects the annotation back into the manifest. kubectl apply, and you're done. (acipolicygen has prerequisites of its own, including a working Docker installation; see the confcom documentation.) Here is why this is a genuinely new isolation primitive rather than a stronger version of an existing one. Most container security policy is enforced by software in the cluster, which means an attacker who compromises the host can potentially bypass it. This policy is enforced by the guest operating system inside the TEE instead. The underlying hardware, AMD SEV-SNP, also produces an attestation report, retrievable from inside the container, which is a cryptographic proof that the workload running is the workload you specified and nothing tampered with it. That is the guarantee regulated industries have been asking for, and increasingly the one AI workloads running untrusted code need too. The same per pod boundary is also what makes multi-tenancy on a single cluster realistic, though multi-tenancy in production still depends on your network and identity boundaries, which sit outside what the isolation layer itself provides. Background: Microsoft Learn: confidential containers on ACI. Wrapping up Virtual nodes on ACI give containers on Azure two things that were previously hard to deliver cleanly on Kubernetes: Effortless burst capacity on Azure's serverless container platform, billed per second for the cores and memory used, with no capacity planning and no waiting for machines. Confidential containers with hardware attested, per container isolation inside a Trusted Execution Environment. Virtual nodes are additive, not a replacement. Traditional node pools remain the right home for steady state, DaemonSet, and persistent volume workloads, and AKS features such as Node Auto Provisioning and Virtual Machine Node Pools already make that baseline more flexible. Virtual nodes on ACI absorb the spikes, the short-lived jobs, and the specialized isolation work on top. Where to start New to containers on Azure? Start with a small AKS cluster and add a virtual node from day one. You get a managed Kubernetes environment without having to guess your peak capacity in advance, and the elastic layer is there the first time you need it. Already running AKS? Add a virtual node to an existing cluster and move one bursty or short lived workload to it. Nothing else changes, and the comparison is immediate. Evaluating platforms? The capability that is hard to find elsewhere is the confidential containers path: hardware attested isolation per container, reachable through a standard Kubernetes manifest. The result: virtual nodes on ACI expand what AKS can run, with more capacity and stronger isolation, without changing the Kubernetes operating model you already use. Same kubectl, same manifests, same GitOps. New ceiling. For the high-level overview, official documentation, and Helm details, the Microsoft Learn is the source of truth. The companion repo holds the demo manifests used in this post. Acknowledgements I'd like to thank Gurpreet Virdi, Partner Group Engineering Manager, whose guidance shaped this post from the first outline through to publication. Her product leadership ensured this post reflects both the technical depth and the customer value of virtual nodes on ACI. Thanks to Gabriel Fuhrman, Senior Software Engineer, for his detailed technical review. His feedback refined the technical content and significantly improved the accuracy and depth of this post. Christopher Little, Principal CSA, shaped the enterprise adoption perspective, and Adam Sharif, CSA, reviewed the post from the earliest draft. Thanks also to Kirthi Maguluri, Senior Product Manager, and Varun Shandilya, Principal Product Manager, for their review of the blog.792Views1like0Comments
How to recover global admin access to tenant
I have already tried posting this to the general Microsoft Q&A forums and received no response. We are desperate to figure something out so if this is not the correct line of communication, please direct me to where I should go. My company is in a bit of a bind right now, and I am at my wit's end after almost a week of trying to get in contact with anyone who could help. We have multiple directories in Azure that belong to us, but they are all independent of each other. As such, some directories have multiple global admins (and thus are not an issue); others -- and quite frankly, the most important ones -- only have one global admin, and it was our DevOps person, who is no longer employed with us. We have no way of accessing his account, and thus no way of accessing a global admin account for these directories/tenants. Access to these directories is critical to our operations. We were informed last Friday by someone from the data protection team that they could not give us access to these tenants we pay thousands of dollars a month for because: Our former DevOps person registered all other users as guests/external users, and DPT "can't give external users admin permissions", and To reset the MFA of the current global admin account, the owner of the account (who no longer works for our company) would need to contact them and verify their identity What options do we have here? We have blobs full of user-uploaded files in these tenants. Starting over from scratch is a doomsday scenario we are trying everything we can to avoid. Surely there has to be something that can be done?1.1KViews1like6Comments