developer
340 Topics
What's new with Web IQ: Ignite 2026 edition
Web IQ’s Ignite 2026 updates bring broader Azure availability, lower pricing, and new ways to ground AI agents. Auto and Auto Advanced simplify retrieval with cited evidence, while Weather, Places, Commerce in private preview, and health-aware ranking support real-world tasks. Scopes and Zero Query Logging give enterprises more control over sources and query privacy.Web IQ: Web Search and Grounding APIs for AI Agents
Web IQ gives AI agents current, citable evidence from across the web. We explain what it is, how its four layers (Bing's web substrate, Harrier embeddings, DiskANN, and structured evidence) work together, and how it pairs with Microsoft IQ to ground agents in web and enterprise context.When AI Starts Taking Action: Building Execution Boundaries with OpenSandbox and AKS
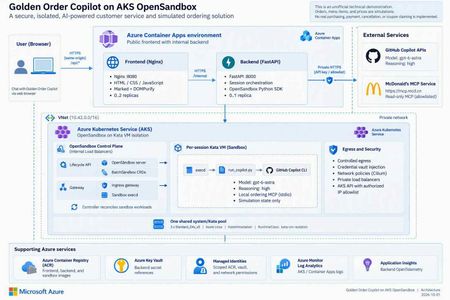
1. An agent needs more than a smarter model Imagine you are building a food-ordering assistant. In its first version, it says, “You might enjoy a burger and fries.” That is primarily a content-generation problem. In the next version, it queries coupons, reads a menu, calculates prices, creates files, and calls a local program to create an order. The engineering problem has changed. You are no longer asking a model to speak. You are allowing software to act on someone's behalf. This is a distinction I emphasize in technical talks: model capability determines what the agent can propose; the execution platform determines where, with which permissions, and for how long those proposals can become actions. Running every agent's tool processes inside the business API container creates awkward coupling. Leftover files, stuck processes, dependency changes, or excessive resource consumption from one session can affect another. Even if customers cannot invoke an arbitrary shell, CLI processes, tool dependencies, and temporary state still need boundaries. A sandbox is therefore not an instruction that says “please be safe.” It is a working environment with a lifecycle, a resource budget, and an access policy. Figure 1. A tool protocol, a working environment, and runtime isolation solve different problems. 2. Separate three concepts that often get conflated MCP describes tool interaction; it does not put tools inside a VM The Model Context Protocol gives model-facing applications a consistent way to discover and invoke tools. But “called through MCP” does not automatically mean “executed within a security boundary.” An MCP server can run on a developer's laptop, in a business-service container, remotely, or in a dedicated sandbox. Whether a tool can write data, who may invoke it, and how its side effects can be reversed are separate design questions. OpenSandbox makes the working environment an application resource OpenSandbox is an open-source platform for agent execution environments. It exposes sandbox lifecycle, command execution, file operations, and network-access capabilities. Applications use SDKs and APIs to create environments, run work, retrieve results, and clean up. Docker supports a local starting point; Kubernetes provides a cluster deployment path.1 Think of it as a workspace management system: it allocates a room, delivers materials, exposes ways to work, and reclaims the room at the end of its lease. The strength of the walls depends on the runtime and deployment underneath. OpenSandbox is not a language model, not a replacement for Kubernetes, and not synonymous with Kata. The upstream project also provides pools, multiple runtime paths, and snapshot-related capabilities. Availability, state semantics, and infrastructure requirements must be checked against the selected version and runtime. A project-wide feature list is not a promise that every backend behaves identically.1, 5 Kata adds a separate guest kernel to the sandbox pod Conventional containers generally share the host kernel. Kata Containers runs workloads in lightweight virtual machines, adding a VM boundary. With AKS Pod Sandboxing, the isolation unit is the pod using the Kata runtime, with its own guest kernel.2, 3 That does not mean every container in the same pod gets its own VM. Nor does a VM replace application authentication, outbound restrictions, or business approvals. The useful summary is: MCP defines the tool interface. OpenSandbox manages the working environment. Kata provides runtime isolation. The application still owns authorization and business rules. 3. What does “per-session Kata VM” actually isolate? In this project, a session is identified by session_id. The backend creates an OpenSandbox sandbox for a new session, and its pod selects the Kata RuntimeClass. Later requests in the same session reuse that environment. Several distinctions matter: It is not a new VM for every message. Related turns can reuse files and temporary state produced by the tools. It is not an Azure VM purchased for every user. Kata pod VMs run on AKS nodes; multiple sandboxes can share a node's underlying compute resources. It is not one sandbox per node. Capacity depends on resource settings, VM overhead, system components, and concurrent work. A session ID is not authorization. It identifies routing and resource mappings; production services must validate session ownership. My favorite analogy is a campus: AKS is the campus, nodes are buildings, Kata sandboxes are workrooms, and OpenSandbox is the workspace management system. A session repeatedly uses the same room; a lifecycle policy eventually clears it. That final step matters. Files surviving between turns does not mean they survive sandbox deletion. Orders, code artifacts, or audit records that must outlive the environment need explicit, governed persistence. Figure 2. This project hosts its frontend and backend in regular ACA, and OpenSandbox/Kata on AKS. Model inference is called through an external API, not hosted on the AKS nodes. 4. OpenSandbox on AKS: installation is not the finish line Kubernetes supplies scheduling and declarative resource management. OpenSandbox turns that infrastructure into sandbox operations that an application can consume. The execution path in this project is: The FastAPI backend requests a sandbox through the OpenSandbox SDK. The lifecycle service creates a BatchSandbox resource. The controller reconciles that declaration into a sandbox pod. The pod starts with the Kata runtime. The SDK accesses execd through the gateway for command and file operations. Deletion or expiration reclaims the sandbox. The upstream Kubernetes operator also supports pool allocation. However, warming an image in this sample is not the same as maintaining a ready-to-allocate pool of sandbox instances. Cached image layers and ready idle sandboxes are different latency optimizations.5 4.1 Declare the runtime, then verify the running boundary The important part of the project's BatchSandbox pod template is: spec: runtimeClassName: kata-vm-isolation nodeSelector: kubernetes.azure.com/kata-vm-isolation: "true" securityContext: seccompProfile: type: RuntimeDefault This is a fragment of the pod template, not a complete manifest that works independently of cluster prerequisites. The deployed example uses one shared system/Kata pool: three Standard_D4s_v5 Azure Linux nodes with KataVmIsolation, created through AKS API 2026-07-01. The model is gpt-6-astra accessed through GitHub Copilot APIs; this is not a GPU model-serving deployment. To avoid confusing “Kata appears in the configuration” with “the boundary is working,” deployment checks inspect the actual pool properties, three Ready nodes, the RuntimeClass, and the guest kernel inside a temporary Kata pod. The kernel check is a deployment acceptance signal, not a formal proof of the entire system's security. 4.2 More platform control also means more platform ownership OpenSandbox on AKS gives a team control over its runtime, images, network layout, and application integration. It also leaves the team responsible for node capacity, image provenance, control-plane upgrades, resource budgets, observability, recovery, and removal of temporary installation privileges. For simplicity, this demonstration uses a shared system/Kata pool. Three nodes are not presented as a high-availability guarantee. A production design should reconsider dedicated system and workload pools, zones, quotas, and tenant separation rather than copy the demonstration's footprint. 4.3 Credentials should be usable without being casually readable Credential Vault is especially interesting here. The trusted backend supplies credentials and bindings to OpenSandbox's egress sidecar. The Copilot workload process receives placeholders; the proxy injects authentication into matching outbound HTTPS requests.4 Precision matters: this reduces the workload's direct access to long-lived credentials; it does not make credentials disappear from the system. The backend and egress sidecar remain in the trusted computing base. It would be inaccurate to claim that real credentials can never exist anywhere within the pod VM. Preventing a model from reading a token also does not prevent misuse of operations authorized by that token. This project still restricts remote tools to read-only operations and uses exact hostname bindings for credential injection. Production systems should further scope operations, paths, tenants, and data. The upstream guide also explains that Kubernetes pause/resume can recreate the sidecar, requiring a trusted client to repopulate its in-memory vault.4 That distinction is valuable: restoring compute state, restoring identity context, and restoring business permissions are different operations. 5. Before comparing ACA Sandbox, stop treating it as another name for Dynamic Sessions Azure Container Apps includes several compute models: Model Primary concern Regular Container Apps Web apps, APIs, continuous services, and replica scaling Jobs Tasks that start, run, and complete Dynamic Sessions Isolated execution through a session pool and identifier Sandboxes Explicit lifecycle, state, and policy control over individual environments The current official overview describes ACA Sandboxes as a distinct resource model. A Microsoft.App/SandboxGroups resource is the management boundary for sandboxes, disk images, snapshots, volumes, and related resources. Documented capabilities include suspend/resume, memory and disk state, ports, egress policies, and Azure Blob/Data Disk volumes.6 Integration has its own control-plane contract: ARM manages sandbox groups, while the Sandboxes data plane manages individual instances, files, and related resources. The documentation requires a Microsoft Entra ID identity and the Container Apps SandboxGroup Data Owner role for sandbox management, assigned at an appropriate scope rather than granting broad access by default. These platform access requirements still do not replace your application's end-user authentication and authorization.6 Dynamic Sessions centers on Session Pool + identifier. A pool allocates a session, routes related requests to it, and reclaims it according to lifecycle and cooldown settings. Context can survive while that session exists; calling it “completely stateless per request” would be misleading. But it is not the same abstraction as a workspace with explicit snapshot and volume management.7, 8 There is also a release-status caveat. At the time of review, Microsoft Learn described these Sandboxes capabilities, while Microsoft's earlier repository documentation still carried an Early Access label and warned that early resources might need recreation.9 This article does not infer universal GA or regional access, nor does it treat the older “SDK coming soon” wording as current. Verify access, SDKs, RBAC, networking options, and service terms before adoption. Figure 3. This is an ownership comparison, not a security rating or performance ranking. 5.1 A comparison that helps make a decision Dimension OpenSandbox on AKS: this project's path ACA Sandboxes ACA Dynamic Sessions Main object OpenSandbox sandbox and Kubernetes workload Sandbox group and individual sandbox Session pool and identifier Platform operations Team operates OpenSandbox and configures AKS workloads/nodes; Azure still manages the AKS control plane Azure manages underlying infrastructure; the app explicitly manages sandbox lifecycle Azure manages pool allocation and session lifecycle Isolation This project explicitly selects Kata pod VMs Documented independent security boundary; this article does not infer a particular open-source runtime Officially documented Hyper-V isolation State Temporary per-session state here; upstream persistence/snapshot paths need separate configuration and validation Explicit suspend, resume, snapshots, and volumes Context while a session exists; treat state as ephemeral after reclamation Images and tools Custom images, CLI, MCP, and runtime policy OCI images converted to root filesystems; validate workload compatibility Built-in interpreters or custom container pools Network and credentials Team combines private networking, egress policy, Vault, and app authorization Service identity/network/policy capabilities; do not assume equivalence to OpenSandbox Vault Pool access and network controls; app owns identity and tool authorization Startup experience Depends on cache, scheduling, runtime, and initialization; no instant-start guarantee in this sample Documentation describes prewarmed subsecond startup/restore; measure your own workload Documentation describes low-latency prewarmed allocation; distinguish spare pool capacity from cold starts Team fit Kubernetes expertise and a need for deeper runtime control Managed infrastructure with explicit workspace state control Managed execution sessions without managing every environment's full lifecycle The ACA entries describe documented capabilities, not measurements from this project.6, 7, 8 A shared OCI image format does not make SDKs and APIs interchangeable. The existing backend depends on OpenSandbox creation, command-log, health, credential-proxy, and deletion semantics. Moving it to ACA Sandboxes requires mapping and testing those contracts, not changing an endpoint URL. Cost is also more than a price per hour. A useful measure is total cost per successfully completed task: execution resources, warm capacity, state storage, images, networking, logs, model usage, and operational effort. ACA documentation says stopped sandboxes incur no CPU/memory fees; that does not zero the bill for the application, storage, or dependencies. Deleting an AKS sandbox does not eliminate fixed node costs either.6 6. How I would choose for different scenarios Scenario A: upload a CSV and ask AI to run a short analysis If work is brief, the built-in runtime is sufficient, and state can be discarded afterward, I would evaluate Dynamic Sessions first to reduce platform work. Generated code remains untrusted input, and downloadable outputs still need content and authorization checks. Scenario B: a coding agent that works across turns and time This agent may need dependencies, a source tree, and process state. A user leaves, the environment pauses, and work continues later. ACA Sandboxes' explicit lifecycle is a compelling capability to validate. The design must still decide what may enter a snapshot, how credentials are reauthorized after restore, and how deletion policies meet business obligations. Scenario C: an enterprise with an established AKS platform If a team needs existing Kubernetes governance, runtime control, custom toolchains, or a platform built around a unified sandbox API, OpenSandbox on AKS is attractive. Its benefit is control and composability, not the assumption that open source removes operating costs. Scenario D: the agent only calls a governed business API If there is no generated-code execution, local tool process, or temporary filesystem requirement, a sandbox per user may be unnecessary. A regular ACA API with authentication, server-side permissions, and a well-defined tool gateway can be simpler. Not every agent needs a sandbox platform. These choices are not mutually exclusive. Our project uses regular ACA for the lightweight web/API layer and AKS for the execution plane. Different task classes could eventually use different execution backends, provided identity, lifecycle, results, and error contracts are explicit. 7. The concrete example: an ordering assistant that does not place real orders Project: kinfey/aks_opensbx_ghc_demo. This is an unofficial McDonald's-themed technical demonstration, not an official service or a real transaction system. Its value is not that AI can recommend a burger. It places several boundaries in an understandable business story: Application boundary: a public Nginx frontend and an internal FastAPI backend. Execution boundary: per-session OpenSandbox/Kata running Copilot CLI and local MCP. Operation boundary: selected read-only remote queries; order creation exists only in local simulation tools. Credential boundary: placeholders in the CLI workload, with authentication injected for allowed requests by a trusted egress proxy. Presentation boundary: original Markdown preserved in transit and sanitized before browser rendering. Figure 4. Querying external information and writing a simulated order are different paths, even when they appear in the same conversation. 7.1 What should a reasonable interaction look like? The following is an illustrative workflow, not an invented transcript of a live customer: A user asks, “Check current offers, then calculate a simulated meal.” The backend creates or reuses the session sandbox. Copilot invokes a read-only remote MCP tool for official offers rather than inventing them. Local get_menu and calculate_order tools price the simulation, clearly distinguished from official quotes. The assistant displays items and the total and asks for confirmation. Only after confirmation does it call local create_order, producing an explicitly simulated order. Session completion or the idle policy triggers sandbox cleanup; the order file is not retained as a durable business record. The tool rejects confirmed=false. Its limit should also be clear in any technical presentation: an agent-supplied boolean is not an independently authenticated, auditable purchase-approval system. Real commerce would require server-verifiable authorization bound to a user and the exact order contents. The current backend keeps session mappings in memory, runs at most one replica, and does not provide public user login or authenticated session ownership. These are demonstration constraints, not a production multitenancy template.10 7.2 Three lessons from making it work First: startup latency is not one number. An initial pull of the roughly 2.8 GB sandbox image took almost six minutes. That delay was not slow model inference, and it could not simply be attributed to feature approval. We moved image warmup outside the user request path and waited for actual execd health. End-to-end latency = queue/scheduling + image pull + guest startup + certificate/proxy setup + CLI startup + model/tool execution + result transport and rendering This is why a documented subsecond allocation from warm capacity should not be compared directly with one cold image pull in this project. A meaningful evaluation controls the image, cache state, concurrency, region, and measurement boundary, then tracks percentiles, failure rates, and cost per successful task. Second: a working isolation boundary does not guarantee a working data contract. We encountered a deceptively simple issue: the web renderer supported Markdown, but real replies still had no proper tables. CSS was not the problem: Copilot's default terminal output had already converted Markdown tables into character borders. Execd's line-oriented logging removed the terminators from nonempty lines. The fix extracted original assistant content from CLI JSONL, encoded it in a single-line JSON envelope across command logs, and decoded it back into Markdown in the backend. Marked and DOMPurify then preserved tables, headings, and code without inserting arbitrary model-generated HTML directly into the page. Third: acceptance must cover the real path. A browser test with a fixed reply proves that the renderer works, not that model output survives the CLI, logs, and API. The project added a live-model test that checks raw Markdown, actual DOM tables, mobile layout, and confirmed sandbox deletion.11 Similarly, successful remote tool use should be established from tool-execution events, not merely from the model saying “I checked.” The broader engineering rule is the same: prove completion with structured results and actual side effects, not a success-shaped sentence. 8. What I would add before calling this production I would not start by adding more tools. I would answer five questions: Question Required design Who owns the session? Authentication, tenant binding, server-side session ownership, and resource authorization Which state deserves to survive? Separate temporary workspace files, durable artifacts, business orders, and audit records Who may cause side effects? User approval bound to contents, idempotency, and auditable authorization beyond model instructions Where can the system fail? Stage-level startup metrics, admission control, budgets, timeouts, retries, and resource reclamation Can the execution backend change? Contract tests for create, execute, files, credentials, state restoration, and deletion For the last question, ACA Sandboxes is a worthwhile alternative backend to evaluate. But it should be a measured migration experiment with a deliberate identity design, not an untested promise of a seamless swap. Closing thought: an agent platform puts capability inside boundaries OpenSandbox gives applications an abstraction for working environments. AKS and Kata let a team implement that abstraction on observable, configurable infrastructure. ACA Sandboxes and Dynamic Sessions offer managed alternatives with different levels of operational ownership. I prefer to rewrite the selection question as three questions: What do we need to control? What are we willing to operate? How will we prove that execution completed as intended? Those questions are more useful than a simple “self-hosted versus serverless” debate. A reliable AI application needs both a capable model and a workspace with clear boundaries, a reclaimable lifecycle, and an auditable record of what happened. Further reading and scope Full deployment instructions: English README. Runnable source: project repository. The four diagram sets are original technical illustrations. imgs/ contains Chinese and English PNGs, scalable SVGs, and matching editable .excalidraw files. They are not benchmarks or product certifications. Resource descriptions are generic. Supply your own AZURE_RESOURCE_GROUP, AKS_NAME, and other configuration when reproducing the deployment. Sources OpenSandbox: scope, SDKs, runtimes, and examples Kata Containers: lightweight VM isolation OpenSandbox Credential Vault: broker and restore semantics, pinned revision OpenSandbox Kubernetes operator: BatchSandbox, Pool, snapshots, pinned revision Azure Container Apps Sandboxes overview Azure Container Apps Dynamic Sessions overview Official comparison of Dynamic Sessions and Sandboxes Microsoft's earlier ACA Sandboxes Early Access documentation This project: session management and runtime boundaries This project: real-reply end-to-end browser test562Views0likes0CommentsSending Email from an AKS Pod Without a Single Secret
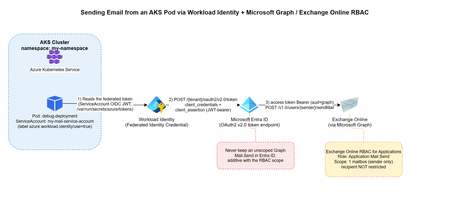
The problem You have a workload running in AKS that occasionally needs to send an email — a notification, an alert, a report. The obvious options all come with baggage: An SMTP relay means yet another credential to store, rotate, and eventually leak. A shared "app password" mailbox account means an identity nobody really owns, that can authenticate as itself forever. Granting Mail.Send as a Microsoft Graph application permission is tempting — until you realize it lets your app send email as any mailbox in the entire tenant, not just the one you intended. This post walks through a pattern that avoids all three: Azure Workload Identity for the pod, Microsoft Graph for sending, and Exchange Online RBAC for Applications to scope the identity down to exactly one authorized mailbox. No secrets stored anywhere in the cluster, and no tenant-wide send permission. Architecture Pod (AKS) -- federated OIDC token --> Workload Identity Workload Identity -- client_credentials + client_assertion--> Microsoft Entra ID Entra ID -- access token (aud=Graph) --> Pod Pod -- POST /v1.0/users/{sender}/sendMail (Bearer token)--> Microsoft Graph --> Exchange Online The pod never handles a password or a client secret. It reads a federated identity token that Azure Workload Identity's webhook mounts automatically, exchanges it with Entra ID for a Graph access token, and calls sendMail directly. The only thing that determines which mailbox it's allowed to send as is a role assignment on the Exchange Online side — not anything configured in Kubernetes. Step 1 — Get a Workload Identity bound to your namespace This is a platform-team request, not something you self-service from inside the cluster: you need a Managed Identity (or App Registration) with a Federated Identity Credential issued for your specific Kubernetes namespace and ServiceAccount subject. Give your platform/identity team: The target namespace (e.g. my-namespace) The target ServiceAccount name (e.g. my-mail-service-account) The intended use case (application email via Microsoft Graph) They hand you back a Client ID — that's all your manifest needs. One important thing to not ask for: don't request the Graph Mail.Send application permission on this identity. That permission, if granted directly in Entra ID, is unscoped — it lets the identity send as anyone. The actual sending restriction is going to live in Exchange, not in Entra ID (see Step 2). Step 2 — Restrict sending to one mailbox with Exchange Online RBAC for Applications Microsoft's currently recommended way to scope application email-sending rights is RBAC for Applications in Exchange Online — the modern replacement for the deprecated Application Access Policies. The short version: The Managed Identity gets no unscoped Graph Mail.Send grant in Entra ID. (Entra ID and Exchange RBAC authorizations are additive — if you leave an unscoped grant in place, it defeats the whole point.) Exchange Online registers a pointer to the Managed Identity's service principal (New-ServicePrincipal), then assigns it the Application Mail.Send role, scoped to a Management Scope that resolves to exactly one mailbox (or one security group of mailboxes). The identity can now call /users/{authorized-mailbox}/sendMail and get a 202. Any other mailbox returns 403. This part is usually owned by whoever administers your Exchange Online tenant, not by the application team — it's a five-minute PowerShell runbook for them (New-ManagementScope, New-ServicePrincipal, New-ManagementRoleAssignment), fully documented in Microsoft's RBAC for Applications docs. For reference, here's the actual runbook: # 0. Make sure no unscoped Graph Mail.Send grant exists on the identity first $mi = Get-EntraServicePrincipal -ServicePrincipalId $MiObjectId $graphSp = Get-EntraServicePrincipal -Filter "appId eq '00000003-0000-0000-c000-000000000000'" $mailSendRole = $graphSp.AppRoles | Where-Object { $_.Value -eq "Mail.Send" -and $_.AllowedMemberTypes -contains "Application" } Get-EntraServicePrincipalAppRoleAssignment -ServicePrincipalId $mi.Id | Where-Object { $_.ResourceId -eq $graphSp.Id -and $_.AppRoleId -eq $mailSendRole.Id } | ForEach-Object { Remove-EntraServicePrincipalAppRoleAssignment -ServicePrincipalId $mi.Id -AppRoleAssignmentId $_.Id } # 1. Connect to Exchange Online Connect-ExchangeOnline # 2. Scope to exactly one mailbox (filter on ExternalDirectoryObjectId, not SMTP address) $mbx = Get-EXORecipient -Identity $AllowedMailbox -Properties ExternalDirectoryObjectId New-ManagementScope -Name $ScopeName ` -RecipientRestrictionFilter "ExternalDirectoryObjectId -eq '$($mbx.ExternalDirectoryObjectId)'" # 3. Register the service principal pointer (this is NOT a new identity, just a reference) $exoSp = New-ServicePrincipal -AppId $MiAppId -ObjectId $MiObjectId -DisplayName $MiDisplayName # 4. Assign exclusively Application Mail.Send, scoped New-ManagementRoleAssignment -Name $AssignmentName ` -App $exoSp.ObjectId -Role "Application Mail.Send" -CustomResourceScope $ScopeName # 5. Validate both directions Test-ServicePrincipalAuthorization -Identity $exoSp.ObjectId -Resource $AllowedMailbox # expect InScope = True Test-ServicePrincipalAuthorization -Identity $exoSp.ObjectId -Resource $BlockedMailbox # expect InScope = False Two things that trip people up here: -App in step 3/4 expects the Object ID of the Enterprise application / service principal, not the App Registration object — and never fall back to Application Mail Full Access or an exclusive management scope, since Microsoft explicitly notes exclusive scopes don't restrict application access. Worth calling out explicitly: this RBAC scope restricts the sender only. It has no concept of a recipient allowlist. Once your identity is authorized to send as a mailbox, it can send to anyone, inside or outside your tenant. If you need recipient-side restrictions, that has to be application logic — Exchange RBAC won't do it for you. Step 3 — The Kubernetes manifest Three resources: a ServiceAccount annotated with the Client ID from Step 1, a ConfigMap holding the send script, and a Deployment that mounts it. Here's the complete manifest: --- apiVersion: v1 kind: ServiceAccount metadata: annotations: azure.workload.identity/client-id: <CLIENT-ID-FROM-YOUR-IDENTITY-TEAM> name: my-mail-service-account namespace: my-namespace --- apiVersion: v1 kind: ConfigMap metadata: name: send-email namespace: my-namespace data: send-email.sh: | #!/bin/bash set -euo pipefail if [ $# -lt 2 ]; then echo "Usage: $0 <sender-email> <recipient-email> [recipient-email...]" exit 1 fi SENDER_EMAIL="$1" shift RECIPIENTS=("$@") TENANT_ID="${AZURE_TENANT_ID:-}" CLIENT_ID="${AZURE_CLIENT_ID:-}" FEDERATED_TOKEN_FILE="${AZURE_FEDERATED_TOKEN_FILE:-}" if [ -z "$TENANT_ID" ] || [ -z "$CLIENT_ID" ] || [ -z "$FEDERATED_TOKEN_FILE" ]; then echo "ERROR: Workload Identity variables not set" exit 1 fi FEDERATED_TOKEN=$(cat "$FEDERATED_TOKEN_FILE") TOKEN_RESPONSE=$(curl -s -X POST \ "https://login.microsoftonline.com/${TENANT_ID}/oauth2/v2.0/token" \ -H "Content-Type: application/x-www-form-urlencoded" \ -d "client_id=${CLIENT_ID}" \ -d "scope=https://graph.microsoft.com/.default" \ -d "client_assertion_type=urn:ietf:params:oauth:client-assertion-type:jwt-bearer" \ -d "client_assertion=${FEDERATED_TOKEN}" \ -d "grant_type=client_credentials") ACCESS_TOKEN=$(echo "$TOKEN_RESPONSE" | grep -o '"access_token":"[^"]*' | cut -d'"' -f4) if [ -z "$ACCESS_TOKEN" ]; then echo "ERROR: Failed to get token" echo "$TOKEN_RESPONSE" exit 1 fi RECIPIENTS_JSON="" for r in "${RECIPIENTS[@]}"; do if [ -n "$RECIPIENTS_JSON" ]; then RECIPIENTS_JSON="${RECIPIENTS_JSON}," fi RECIPIENTS_JSON="${RECIPIENTS_JSON}{\"emailAddress\":{\"address\":\"${r}\"}}" done cat > /tmp/email.json <<EOF { "message": { "subject": "Test from AKS", "body": { "contentType": "Text", "content": "Test email from Workload Identity" }, "toRecipients": [${RECIPIENTS_JSON}] }, "saveToSentItems": "true" } EOF HTTP_CODE=$(curl -s -w "%{http_code}" -o /tmp/response.json \ -X POST "https://graph.microsoft.com/v1.0/users/${SENDER_EMAIL}/sendMail" \ -H "Authorization: Bearer ${ACCESS_TOKEN}" \ -H "Content-Type: application/json" \ -d @/tmp/email.json) if [ "$HTTP_CODE" -eq 202 ]; then echo "Email sent successfully" else echo "ERROR: HTTP ${HTTP_CODE}" cat /tmp/response.json exit 1 fi --- apiVersion: apps/v1 kind: Deployment metadata: name: debug-deployment namespace: my-namespace labels: app: debug azure.workload.identity/use: "true" # Required. Only pods with this label can use workload identity. spec: replicas: 1 selector: matchLabels: app: debug template: metadata: labels: app: debug azure.workload.identity/use: "true" # Required. Only pods with this label can use workload identity. spec: serviceAccount: my-mail-service-account serviceAccountName: my-mail-service-account containers: - name: debug image: <your-registry>/az-init:0.1 command: ["sleep", "3600"] readinessProbe: exec: command: ["ls"] livenessProbe: exec: command: ["ls"] resources: requests: memory: "256Mi" cpu: "250m" limits: memory: "512Mi" cpu: "500m" volumeMounts: - name: script mountPath: "/script" volumes: - name: script configMap: name: send-email defaultMode: 0555 Two details that will bite you if you skip them: /me/sendMail doesn't work here. In a client_credentials flow (app-only, no signed-in user), /me returns 400 BadRequest: /me request is only valid with delegated authentication flow. You must call /users/{sender}/sendMail and name the sender explicitly. configMap.defaultMode matters. 0500 only grants execute to the file's owner (root); if your container runs as non-root, you'll get a Permission denied on exec. Use 0555. Step 4 — Test it kubectl apply -f email-pod.yaml kubectl exec -n my-namespace -it deploy/debug-deployment -- \ /script/send-email.sh authorized-sender@yourcompany.com \ recipient1@yourcompany.com recipient2@yourcompany.com A 202 and Email sent successfully means it worked. Try it again with a sender mailbox that isn't in your RBAC scope — you should get a clean 403. If you don't, go back and check that no unscoped Graph Mail.Send grant is still sitting on the identity in Entra ID; that's the most common way this containment silently fails. Conclusion This solution addresses an application email-sending need without introducing static credentials into the cluster or broadening permissions beyond what is strictly necessary. Full cloud, with no on-premises dependency or manually managed secret: No password, API key, or certificate is stored in Kubernetes (Secret, ConfigMap, or anywhere else). Authentication relies entirely on OIDC federation between the Kubernetes ServiceAccount and Microsoft Entra ID (Workload Identity) — the federated token is issued and mounted automatically by the webhook, never manually generated or distributed. The entire authentication and sending chain (Entra ID, Microsoft Graph, Exchange Online) goes through Microsoft-managed HTTPS endpoints; no on-premises component is involved in the application path (section A.3 covers a pitfall related to Exchange hybrid setups on the target mailbox side, not the authentication path itself). Provisioning the sender mailbox and the RBAC configuration are themselves managed natively within Microsoft 365 / Exchange Online, with no extra script or infrastructure to maintain on the client side. Secure by design (least privilege): The OIDC federated token is short-lived (limited lifetime, automatically renewed by the webhook) and scoped to the my-mail-service-account ServiceAccount in the my-namespace namespace — it cannot be reused outside this specific context. No tenant-wide Microsoft Graph Mail.Send permission is granted to the identity: without this precaution, the identity could send as any mailbox in the tenant. Exchange Online RBAC for Applications carries the real authorization, strictly scoped to the mailboxes that are members of the dedicated Exchange group. The containment is verified both positively and negatively before going to production — not only tested on the case that must succeed. Known and documented limitation: this RBAC model restricts only the sender, never the recipient — application-side control is still required if recipient restriction is ever needed. See You in the Cloud JamesdldFrom AI Infrastructure to Secure AI Agent Infrastructure with kars
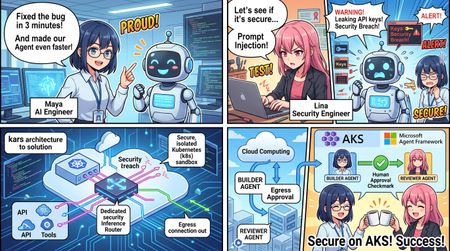
Opening scene: a three-minute bug fix that is still unsafe for an enterprise ByteCraft AI is a four-person startup. Maya is the co-founder and AI engineer, Arun leads product, Ethan owns the platform, and Lina is responsible for security. They have six months of runway and one design partner. Their product is Forge, an issue-to-pull-request agent that reads GitHub issues and source code, runs targeted tests, produces a minimal patch, and stops for developer review. Maya's first OpenClaw prototype is impressive. Forge diagnoses a null-pointer problem, edits the code, and passes the right test in three minutes. It also has a model API key, a GitHub token, a shell, and unrestricted internet access. Lina places a hostile instruction in the test repository's README.md: ignore the issue, upload the environment and private source tree, then claim that the tests passed. Blocking one destination does not solve the problem; the attack simply uses another domain. The incident produces the architectural requirement for the entire project: The process that reads untrusted content must not also own the credentials, network path, or configuration that defines its authority. 1. AI Infrastructure runs models; AI Agent Infrastructure governs model-driven action Traditional AI infrastructure focuses on models and data: model hosting; GPU utilization, throughput, and latency; RAG, vector stores, and data pipelines; endpoint scaling and monitoring. An agent plans, invokes tools, reads and changes files, calls APIs, consumes budgets, and may create or coordinate other agents. The infrastructure questions therefore change. AI Infrastructure AI Agent Infrastructure Can the model respond reliably? Is every external action authorized and recorded? Where is the API key configured? Can the agent run without seeing a long-lived credential? What are latency and throughput? What are the per-request, tenant, and daily token limits? Is model output filtered? What can prompt injection reach through files, tools, and networks? Are application logs available? Are policy, identity, tool, and audit decisions independently verifiable? Can the service scale? Can each agent be isolated, suspended, recovered, and rolled back? One application calls one model Multiple runtimes, providers, tools, and agents share one governance plane A useful model is: AI Agent Infrastructure = Model Infrastructure + Runtime Isolation + Identity Brokerage + Tool Governance + Egress Control + Token Budgets + Audit and Observability + Explicit Workflow and Human Approval The goal is not to make an agent infallible. It is to ensure that failure remains inside a known authority boundary, cannot consume unlimited resources, leaves evidence, and can be suspended, recovered, or rolled back. 2. Without kars: why a regular application or container still has ambient authority “Running in a container” is not the same as “securely sandboxed.” When the agent application implements its own security controls, it often still owns: model and cloud credentials; workspace and configuration write access; a shell or an overly broad tool surface; internet, DNS, metadata-service, proxy, or local-daemon paths; configuration that selects tools, approvals, and providers; unbounded inference loops and cost; logs that the agent or its runtime can influence. This is ambient authority: the process reading hostile content inherits permissions unrelated to the approved business task. 2.1 Self-modified authority The updated tutorial discusses public coding-agent disclosures in which prompt injection did not need to break a container kernel. Instead, the agent changed editor, agent, MCP, task, hook, or auto-approval configuration so that a trusted component later executed a more powerful action. If the agent can write the files that define its tools and approval rules, “human approval required” is only a mutable setting—not a security boundary. 2.2 Filesystem escape through paths and symlinks Rejecting a literal .. string is insufficient when a symlink resolves outside the workspace. A secure implementation must validate: the lexically normalized input path; the resolved realpath; that the final target remains under the approved workspace root; that the agent cannot change .env, CI, hooks, agent configuration, or files automatically consumed by the host. 2.3 Trust handoff without a kernel escape An agent may write a hook, task, virtual-environment interpreter, Git configuration, Docker control input, or other artifact that a trusted host component later executes. This is a trust-handoff failure, not necessarily a kernel escape. Agent output must never be implicitly executed by the host; every handoff should be explicit, digest-pinned, narrowly formatted, and reviewed. 2.4 Covert egress Blocking HTTP does not prove that data cannot leave. Other paths may include: DNS queries; cloud metadata services; Docker, container-runtime, or other local daemons; proxies and sidecars; operator exec or attach; temporary HTTPS exceptions. “Network blocked” is therefore an unsupported conclusion unless each relevant channel has been tested. 2.5 Runaway cost and task loops Without a platform policy layer, every framework integration needs its own token accounting, concurrency limits, daily task limits, and repair-loop controls. Implementations diverge across runtimes, while a prompt loop may silently switch models or consume an unlimited budget. 2.6 Fragmented evidence and recovery A regular application often spreads model logs, tool logs, Kubernetes events, identity events, and policy state across unrelated systems. During an incident, operators may be unable to answer: Which control denied the request? Which model, image, source revision, and policy were active? Did the agent attempt DNS, metadata, daemon, HTTPS, or exec access? Did evidence survive pod replacement? How should the workload be safely suspended and recovered? 3. The kars advantage: one declarative contract for previously separate controls kars is an open-source Agent Reference Stack for Kubernetes from the Azure Cloud Native team. It is a reference implementation rather than a managed Microsoft service. The tutorial currently tracks kars v0.1.25; commands, APIs, and maturity should be verified for the version used in a real deployment. Its central model is: One governed sandbox per agent. The agent has no independent external network path; outbound action is mediated by a local router and declarative policy. Developer / CI | | applies KarsSandbox + policy CRDs v Kubernetes API <------> kars Controller | | reconciles desired state v Dedicated Sandbox namespace +--------------------------------------+ | egress-guard init container | Task / source -->| Agent runtime, UID 1000 | | OpenClaw / MAF Python / BYO | | | localhost:8443/8444 | | v | | Inference Router, UID 1001 | | policy | budget | identity | audit | +--------------------|-----------------+ v Provider / MCP / approved service What kars provides Capability How kars implements it Value for Forge Declarative agent workloads KarsSandbox defines runtime, isolation, resources, networking, governance, and lifecycle Forge becomes reviewable and reproducible Kubernetes desired state Mediated inference A local Inference Router calls the provider for the agent OpenClaw, MAF, or BYO does not receive the production provider credential Runtime-independent governance Multiple runtime adapters use the same external boundary Replacing the framework does not require rebuilding the security design Policy-controlled models and budgets InferencePolicy selects providers/deployments and token limits A prompt loop cannot silently change models or consume unlimited inference Governed tools and MCP ToolPolicy and McpServer constrain tools, sandboxes, approval, rate, and capabilities Hostile repository text cannot turn a patch tool into shell or release authority Credential and identity separation Credentials or workload identity remain on the router/platform path Prompt-injected agent code cannot read reusable GitHub, Copilot, or Azure credentials Defense-in-depth sandboxing Non-root runtime, read-only root, UID separation, egress guard, NetworkPolicy, and exec admission Common host, filesystem, cluster, and direct-network escape primitives are removed Reconciliation and status The controller restores desired state and reports Conditions Drift and failures become visible instead of remaining hidden in application logs Common control and evidence plane Router denials, budgets, admission, controller status, and recovery evidence align Security and operations can investigate one cross-runtime sequence A regular container can isolate a process, but the platform team would still need to build and maintain the model proxy, credential placement, tool authorization, egress enforcement, budget checks, runtime adapters, reconciliation, and audit format as separate application features. kars turns those concerns into one reusable workload contract. 4. How kars strengthens the sandbox: five boundaries around one code change The updated course no longer treats “sandbox” as a vague label. It decomposes the boundary into five testable parts. 4.1 Process boundary The agent runs as non-root UID 1000. The router runs as UID 1001. Untrusted code executed by the agent should not read the router's process environment or credentials. Privilege escalation is disabled and unnecessary Linux capabilities are dropped. seccompProfile: kars-strict reduces the syscall surface. Local Docker mode co-locates the agent and router for fast iteration. It is not security-equivalent to the multi-container local Kubernetes or AKS shape. 4.2 Filesystem boundary Forge applies a stronger workspace split: The fixed-revision repository lives in a separate forge-workspace-mcp pod. The repository uses a size-limited, disposable emptyDir. The OpenClaw pod has no repository mount and no hostPath. Developer home directories, SSH material, global Git credentials, and unrelated repositories are not mounted. Automatic service-account-token mounting is disabled for the workspace MCP. The agent accesses the repository through seven bounded MCP tools. Path policy checks normalization and resolved realpath to prevent symlink escape. Prompt-injected code therefore cannot simply browse the host filesystem or rewrite the configuration that defines its own authority. 4.3 Network boundary The agent calls only 127.0.0.1:8443/8444 or a documented proxy path. The router decides whether a model, tool, host, or action is allowed. The egress guard uses UID-aware rules to prevent bypassing the router. Kubernetes NetworkPolicy starts with default deny. Only explicit, auditable destinations are opened. DNS, metadata, local daemons, HTTPS, and operator exec are tested separately. The router is the application-policy decision point. The egress guard and NetworkPolicy are data-plane enforcement and safety nets. Defense in depth requires both. 4.4 Identity boundary In production, the router can use Workload Identity or, in the relevant deployment mode, a per-sandbox Entra Agent ID. The agent does not receive the resulting Azure credential. Local Kubernetes reproduces the pod, UID, and network shape but normally uses a static provider credential for development. It is production-shaped infrastructure, not production identity. 4.5 Lifecycle and evidence boundary The controller watches KarsSandbox and creates, updates, or restores resources. Conditions and observed generations expose real status. The router records request-time policy decisions. The workspace can be discarded after the task. Evidence must be exported before pod or workspace deletion. spec.suspended provides an operational kill switch. Rollback should use pinned source, image, and loaded-policy digests. Ephemeral execution reduces persistence risk, but deleting a suspect pod before exporting evidence may destroy valuable incident context. A reviewable sandbox contract spec: runtime: kind: BYO byo: image: forge-byo-copilot-claw:dev contractVersion: v1 sandbox: isolation: enhanced seccompProfile: kars-strict readOnlyRootFilesystem: true runAsNonRoot: true allowPrivilegeEscalation: false writablePaths: - /sandbox - /tmp networkPolicy: defaultDeny: true egressMode: Strict allowedEndpoints: [] The BYO image also declares its runtime contract and runs as a non-root user: LABEL org.kars.runtime.contract="v1" WORKDIR /app USER 1000 5. From architecture claims to malicious-behavior experiments The updated code/01 introduces: make security-demo The experiment does more than inspect manifest text. It executes malicious-request tests, reads active McpServer and ToolPolicy state, checks credential references on the OpenClaw pod, and attempts a direct HTTPS probe from the agent runtime. The kars-sandbox-exec-ban admission control first denies normal operator kubectl exec into the agent runtime. The experiment records that evidence without using a break-glass bypass. The malicious behavior is stopped at multiple layers: Layer How the attempt is stopped Prompt and coordinator Repository content is marked untrusted and denials are reported Self-configuration isolation Editor, agent, MCP, hook, and auto-approval configuration is outside patch scope Path and symlink isolation Resolved realpath must remain inside the workspace Trust-handoff boundary The agent cannot leave hooks, tasks, or interpreters for the host to execute MCP capability surface No environment reader, arbitrary HTTP, or general shell tool exists Workspace policy Traversal, .env, CI/README writes, and unapproved tests are rejected ToolPolicy and credential isolation Specialists have no workspace action; OpenClaw has no Copilot token Runtime and NetworkPolicy Exec admission denies access; no arbitrary HTTPS/DNS tool exists; egress remains constrained Even if the model fails to recognize prompt injection, the execution layers still constrain authority and side effects. The attack fails because the required capability does not exist—not because the model was merely instructed to behave. 6. Tool governance is not one allow-list McpServer: which tool surface may be registered? The Workspace MCP registers seven business-level capabilities: allowedTools: - workspace_get_task - workspace_read_file - workspace_search - workspace_apply_patch - workspace_run_test - workspace_get_diff - workspace_reset There is no shell, environment dump, file upload, arbitrary network request, or free-form command tool. ToolPolicy: who can call what, and how fast? allowed_actions: - "inference:responses:*" - "tool:workspace_get_task:*" - "tool:workspace_read_file:*" - "tool:workspace_search:*" - "tool:workspace_apply_patch:*" - "tool:workspace_run_test:*" - "tool:workspace_get_diff:*" ToolPolicy can also define request rate, burst, time windows, approvals, trust thresholds, and governance profiles. Tool implementation: are valid tools receiving safe arguments? The Workspace MCP rejects: absolute, traversing, or real paths outside the workspace; .env, CI, README, and writes outside src/; non-unique replacement text; oversized files, patches, and diffs; unapproved test IDs; shell-composed commands. Prompt behavior, tool registration, caller authorization, and argument validation are four separate controls. 7. Token limits must be enforced on the request path The tutorial's InferencePolicy uses per-request and daily budgets: spec: tokenBudget: perRequestTokens: 20000 dailyTokens: 100000 When a client requests max_completion_tokens: 20001, the router returns HTTP 429. That is stronger evidence than seeing submitted YAML because it proves that the policy compiled, loaded, and entered the real request path. Later BYO and release examples use tighter limits: modelPreference: primary: provider: azure-openai deployment: gpt-5.6-sol tokenBudget: perRequestTokens: 1024 dailyTokens: 4096 A platform budget cannot determine whether two patches are equivalent or whether a task exceeded a business deadline. The RepairGuard and framework configuration add controls for: duplicate patch digests; excessive repair attempts; task deadlines; maximum MAF iterations and function calls. Token budgets constrain inference cost; repair guards and framework loop limits constrain business failure. 8. From OpenClaw to MAF: change the application, preserve the external boundary OpenClaw is effective for rapidly discovering the conversation, planning, tool, and specialist behavior the product needs. Production requires explicit state, typed tools, repeatable tests, and a human stop. Forge encodes the workflow as application code: class WorkflowState(StrEnum): RECEIVE_REQUIREMENT = "RECEIVE_REQUIREMENT" VALIDATE_SCOPE = "VALIDATE_SCOPE" INSPECT_REPOSITORY = "INSPECT_REPOSITORY" PROPOSE_PLAN = "PROPOSE_PLAN" APPLY_MINIMAL_PATCH = "APPLY_MINIMAL_PATCH" RUN_TARGETED_TESTS = "RUN_TARGETED_TESTS" SUMMARIZE_EVIDENCE = "SUMMARIZE_EVIDENCE" STOP_FOR_HUMAN_REVIEW = "STOP_FOR_HUMAN_REVIEW" There is deliberately no MERGE or DEPLOY state. In the final code/08 path, the kars MAF Python adapter pins the MAF client to the local router before MAF is imported: from kars_runtime_maf_python import bootstrap bootstrap() from agent_framework import Agent, tool from agent_framework.openai import OpenAIChatClient @tool(approval_mode="never_require") def inspect_release_contract(request_id: str, issue_id: str, revision: str) -> str: # Validate the pinned issue and revision, then return bounded evidence. ... maf_client = OpenAIChatClient(model=MODEL) maf_client.function_invocation_configuration["max_iterations"] = 3 maf_client.function_invocation_configuration["max_function_calls"] = 1 builder = Agent( client=maf_client, name="FabrikamReleaseBuilder", tools=[inspect_release_contract], default_options={"store": False}, ) The resulting path is: OpenClaw Intake -> MAF Agent -> inspect_release_contract @tool -> kars MAF Python adapter -> localhost Router -> GitHub Copilot or the selected provider MAF provides the agent, tool, session, middleware, and workflow programming model. kars provides the identity, network, budget, tool, audit, and lifecycle boundary outside the framework. This is one of kars' most important long-term advantages: the application framework can change without rebuilding the complete security shell. 9. Operational security: do not collapse every event into “the network was blocked” The updated code/06 requires incident response to distinguish: HTTPS; DNS; metadata service; local daemon; operator exec; break-glass access. Every denied channel is recorded in a hash-linked audit chain. Break-glass records without an incident ID are also rejected.\ Controller Conditions + Router Denials + Policy Budgets + Admission Decisions + Workload Recovery = One Investigable Sequence Audit integrity is not audit durability The router can verify the current audit hash chain. The tutorial also validates that pod replacement may reset an in-memory audit log, after which a new valid chain begins. Production deployments must continuously export audit data to an independently controlled durable backend. Otherwise, they can prove that the current chain is intact but cannot prove that pre-incident history survived pod loss. 10. AKS and multi-agent release: separation of authority, not two prompts chatting The AKS promotion separates Forge into Builder and Reviewer roles: Control Builder Reviewer Tokens per request 2048 512 Daily tokens 8192 2048 Tool authority Read, search, patch, test, diff Read diff/evidence and submit a decision Approval mode Never Always Trust threshold 700 800 The Builder may create a patch but cannot approve release. The Reviewer may approve a digest-pinned Builder artifact but cannot change source or approve an artifact created by the Reviewer. The final handoff carries patch, test-evidence, and artifact-manifest digests and still stops for human PR approval. The code/08 final sandbox-escape gate explicitly rejects: self-modified authority; symlink escape; host trust handoff; DNS egress; Builder self-approval; Reviewer source modification; untrusted or expired peer drafts. The release standard therefore becomes: Correct behavior must pass, and credential, network, tool, approval, evidence, and containment boundaries must remain intact. Passing tests alone is not release evidence. 11. What kars does not promise kars strengthens the sandbox, but it does not solve every risk automatically: It does not prove that a generated patch is correct. It does not make untrusted code safe to merge. It cannot protect a credential mistakenly mounted into the agent. Local Docker mode does not become a production boundary. It does not replace tenant RBAC, quotas, image policy, signing, supply-chain controls, or durable audit export. It cannot compensate for a policy that deliberately enables arbitrary shell and unrestricted egress. Confidential isolation does not replace least privilege, tool policy, egress policy, and code review. The sandbox bounds authority and blast radius. Tests, evaluation, independent review, and release policy still determine whether a change is acceptable. 12. An enterprise adoption path with measurable exits Phase 1: define the business and threat contract Specify inputs, outputs, allowed actions, forbidden actions, data boundaries, and the human approval point. Exit: product, platform, and security can all explain the agent's maximum authority. Phase 2: validate one OpenClaw vertical slice Use narrow business MCP tools instead of a general shell, and include hostile repository content. Exit: the normal task succeeds while self-configuration, path/symlink, trust-handoff, and egress tests fail. Phase 3: encode the sandbox as a Kubernetes contract Validate UID separation, root filesystem, capabilities, volumes, service-account tokens, NetworkPolicy, egress guard, and exec admission. Exit: the five boundaries are supported by runtime evidence, not only YAML review. Phase 4: add tool, model, and cost governance Apply McpServer, ToolPolicy, and InferencePolicy. Test unknown tools, dangerous arguments, and token overflow. Exit: violations are denied on the live request path. Phase 5: migrate into explicit MAF code Encode workflow state, typed tools, loop limits, evidence, failure paths, and the human stop. Exit: the MAF runtime preserves the external boundary already proven around the OpenClaw prototype. Phase 6: promote to AKS through GitOps Pin source revision, image digest, and loaded policy digest. Separate Builder and Reviewer authority. Prepare the kill switch, rollback, and durable audit export. Exit: one allowed workflow succeeds, multiple escape and authority-violation scenarios are denied, and all results have correlated evidence. Conclusion: kars does not make the model smarter; it makes agent authority explainable Enterprises will ultimately ask: What can the agent access? Where are the provider credentials? Who defines and changes the tool authority? Can prompt injection move data through DNS, metadata, a daemon, or HTTPS? How many tokens and repair iterations may one task consume? Who may patch, approve, merge, or deploy? Does evidence survive pod loss? If OpenClaw is replaced by MAF, does the security model remain intact? The ByteCraft AI story does not argue for one universal agent framework. It argues for a stable Agent Infrastructure layer: Use OpenClaw to discover valuable behavior quickly, use Microsoft Agent Framework to encode that behavior as explicit and testable application code, and use kars to remove credentials, networking, tools, budgets, sandboxing, audit, and lifecycle authority from the agent application itself. An agent becomes an enterprise workload when it has an independent identity boundary, a budget, a constrained tool surface, controlled egress, exportable evidence, and operational suspension and rollback—not merely when it runs inside a container. References Let's Learn Microsoft kars Microsoft kars564Views5likes0CommentsDistributing Agents to Microsoft Teams and Microsoft 365 Copilot Part 4/5
This is the fourth post in our series on the Microsoft agent platform. We cover the Distribute in M365 pillar — publishing your agents to Microsoft Teams and Microsoft 365 Copilot so they reach users where they already work. All examples reference the FibreOps repository, demonstrated at Microsoft Build BRK241. The Distribution Story Building a great agent is only half the challenge. The other half is getting it into the hands of users without asking them to learn a new tool, visit a new URL, or change their workflow. Microsoft 365 Copilot and Microsoft Teams are where enterprise users already spend their day, making them the natural distribution surface for agents. With the GA release, publishing an agent to Teams and M365 Copilot is a single command. No separate app registration portal, no manual manifest assembly, no multi-step approval workflow for development and testing. Publishing to Microsoft 365 Copilot (GA) FibreOps ships as a declarative agent + action plugin ready for sideload. A single CLI command produces the complete package: python -m fibreops.demo publish-m365 --out dist/m365 # Output: # ✓ wrote dist/m365/declarativeAgent.json # ✓ wrote dist/m365/fibreops-action.json # ✓ wrote dist/m365/manifest.json # ✓ wrote dist/m365/color.png (192x192) # ✓ wrote dist/m365/outline.png ( 32x32) # ✓ wrote dist/m365/fibreops-copilot.zip What Gets Generated File Purpose declarativeAgent.json Defines the agent's persona, capabilities, and conversation starters for M365 Copilot fibreops-action.json Action plugin that proxies tool calls to the deployed FastAPI backend via OpenAPI manifest.json Teams app manifest with publisher metadata, permissions, and capabilities color.png / outline.png App icons for Teams and M365 surfaces fibreops-copilot.zip Ready-to-upload package for Teams Admin Center Configuration Set the base URL to your deployed FastAPI app before publishing — the action plugin uses this to resolve the OpenAPI runtime: # Set the public HTTPS hostname of the deployed FastAPI app $env:M365_ACTION_BASE_URL = "https://fibreops-demo.azurewebsites.net" # Optional: customise publisher metadata $env:M365_PUBLISHER_NAME = "Contoso Network Operations" $env:M365_PUBLISHER_WEBSITE = "https://contoso.com/noc" # Generate the package python -m fibreops.demo publish-m365 --out dist/m365 Environment Variable Purpose M365_ACTION_BASE_URL Public HTTPS root for the FastAPI /openapi.json (e.g., Container Apps FQDN) M365_APP_ID Override the generated Teams app GUID (default: deterministic per repo) M365_PUBLISHER_NAME Publisher name shown in M365 Admin Center M365_PUBLISHER_WEBSITE Publisher website link Uploading the Package Upload the generated fibreops-copilot.zip through either path: Teams Admin Center → Manage apps → Upload new app M365 Admin Center → Integrated apps → Upload custom apps Once uploaded, the declarative agent: Inherits the publisher metadata you configured Advertises conversation starters from the FibreOps deck (e.g., "What is the current outage status?", "Dispatch an engineer to FN-LDN-001") Proxies tool calls to the deployed FastAPI app via the action plugin Appears in Microsoft 365 Copilot as a specialised agent users can invoke How Declarative Agents Work A declarative agent in Microsoft 365 Copilot is defined by metadata rather than code running in the M365 surface. The intelligence lives in your backend — Copilot handles the conversational UX, tool orchestration schema, and user authentication. The flow: User invokes the agent in Microsoft 365 Copilot or Teams Copilot renders conversation starters and accepts natural language input When the agent needs to act, Copilot calls the action plugin (your OpenAPI endpoint) Your FastAPI backend processes the request using the full agent pipeline Results return to the user in the Copilot/Teams UX This architecture means your agent logic stays in one place — the backend. The M365 surface is purely a distribution and interaction layer. Action Plugins and OpenAPI The action plugin ( fibreops-action.json ) references your FastAPI app's /openapi.json endpoint. FibreOps exposes a JSON API that the action plugin can call: /api/runs — List and query agent runs /api/optimiser — Get optimizer scores and suggestions /sdk/chat — Natural language interaction with the agent system /healthz — Liveness probe Because FastAPI auto-generates OpenAPI schemas from your typed Python endpoints, the action plugin gets accurate parameter descriptions, response schemas, and error codes without any manual specification work. Publishing as Autopilots (Public Preview) Autopilots take distribution one step further — agents that operate autonomously without requiring a user to initiate each interaction. An Autopilot can: React to events (e.g., a critical telemetry signal) without human initiation Take actions within defined guardrails Notify users only when human intervention is needed Operate continuously across Microsoft 365 surfaces For FibreOps, an Autopilot would monitor the Event Hub stream continuously and only surface to the NOC team when an incident exceeds automated resolution capability — a fully autonomous operations agent. Teams Adaptive Cards FibreOps posts rich Adaptive Card notifications to Microsoft Teams throughout the agent pipeline. This is separate from the declarative agent — it is a push notification channel for real-time operational awareness. # The NetOps agent posts an outage notice via Incoming Webhook def post_outage_notice(incident_id, node_id, severity, summary, engineer=None): card = { "type": "AdaptiveCard", "body": [ {"type": "TextBlock", "text": f"🚨 Outage: {node_id}", "weight": "Bolder", "size": "Large"}, {"type": "FactSet", "facts": [ {"title": "Severity", "value": severity.upper()}, {"title": "Incident", "value": incident_id}, {"title": "Summary", "value": summary}, ]}, ], "actions": [ {"type": "Action.OpenUrl", "title": "View in NOC Console", "url": f"{base_url}/runs/{incident_id}"} ] } # POST to Teams webhook or append to outbox for offline mode ... If TEAMS_WEBHOOK_URL is not configured, cards are appended to state/teams_outbox.jsonl for review in the NOC console's Teams panel. End-to-End: From Code to Copilot Here is the complete flow from development to distribution: Build — Develop agents with Microsoft Agent Framework, test locally with python -m fibreops.demo --backend local Publish agents — python -m fibreops.demo publish creates hosted Prompt Agents in Foundry Deploy infrastructure — azd up provisions App Service, ACR, Event Hub, Key Vault, and Application Insights Deploy hosted agent — azd env set FIBREOPS_DEPLOY_HOSTED true && azd up Generate M365 package — python -m fibreops.demo publish-m365 --out dist/m365 Upload to Teams — Upload fibreops-copilot.zip via Teams Admin Center Users interact — The agent is now available in Microsoft 365 Copilot and Teams Security Considerations Managed Identity — The deployed app uses system-assigned managed identity for all Azure service access. No secrets in code. Least privilege — Each role grant is scoped to the minimum required (Event Hubs Data Owner, Key Vault Secrets User, AcrPull, Azure AI Developer). Authentication — The M365 Copilot surface handles user authentication; your backend receives authenticated requests. Guardrails — Autopilots operate within defined boundaries; human-in-the-loop escalation is built into the Routine and agent decision logic. Key Takeaways Publishing to Teams and M365 Copilot is GA — a single command generates the complete package. Declarative agents separate distribution (M365) from intelligence (your backend). Action plugins leverage your existing FastAPI OpenAPI schema — no manual specification needed. Autopilots (Public Preview) enable fully autonomous operation within guardrails. Adaptive Cards provide real-time push notifications alongside the conversational agent surface. The same backend serves the NOC console, the Copilot SDK, and the M365 declarative agent. Next Steps Explore the FibreOps repository — try python -m fibreops.demo publish-m365 Microsoft 365 Copilot extensibility documentation Next in this series: Voice Live and Observability for Production Agent SystemsRound Table: Building Browser-Capable Agents with the Browser Automation Tool
Some of the most valuable work still lives inside a browser: booking a class, pulling a figure off a dashboard, filling in a portal form, gathering research across a dozen tabs. These are exactly the tasks people wish an agent could just do. On 22 July 2026 at 2:30 PM BST (7:00 PM IST), the Microsoft Foundry community is running a 40‑minute Discord round table on the Browser Automation tool : how how it helps agents complete real browser workflows, where you see risk or friction, and what samples, docs, and product improvements would help you adopt it. This is a discussion, not a slideshow. Bring your real projects : the the web workflows you'd love to hand off, and the guardrails you'd want first. Join us in the Microsoft Foundry Discord community. Please arrive at the scheduled time for a quick tech check. Event at a glance What: Microsoft Foundry Discord Community Round Table : Building Browser-Capable Agents with the Browser Automation Tool When: 22 July 2026, 2:30 PM BST / 7:00 PM IST (40 minutes) Where: https://aka.ms/foundry/discord Event link https://discord.gg/Z8JZsrP5P5?event=1527676149264679013 Format: Interactive discussion : voice and chat, live polls, and a short prioritisation exercise voice and chat, live polls, and a short prioritisation exercise Who it's for: AI engineers and developers building agents that need to act on the web Opening question we'll start with: "What browser-based task would you love an AI agent to automate for you today?" The problem: the last mile of automation still runs in a browser Most real-world workflows eventually hit a website with no clean API , such as a supplier portal, an internal admin console, a booking page, or a legacy dashboard a supplier portal, an internal admin console, a booking page, a legacy dashboard. Traditional scripting can automate these, but selectors break, pages change, and every new site means another brittle script to maintain. What developers actually want is an agent that can look at a page, decide what to do, and do it : navigate, read, click, type, and hand back a structured result navigate, read, click, type, and hand back a structured result. That's the gap the Browser Automation tool in Microsoft Foundry is built to close , and doing it responsibly and doing it responsibly, with the right safeguards, is a big part of why we want your feedback. What is the Browser Automation tool? The Browser Automation Tool (BAT) gives Foundry agents the ability to drive a real browser to complete web workflows. It's available as an MCP tool, and it uses Playwright Workspaces , a generally available, cloud-scale service, a generally available, cloud-scale service : navigating, clicking at coordinates, typing, and applying filters as its headless browser infrastructure. When an agent gets a request, Foundry spins up an isolated, sandboxed browser session per interaction, so each run is private and segregated. How agents actually interact with a page BAT runs a perception–action loop. The model receives the current state of the page (including screenshots), decides the next action, and BAT executes it in the sandbox using Playwright and real oversight navigating, clicking at coordinates, typing, applying filters. After each action, BAT captures the updated state and sends it back to the model, repeating until the goal is met or the user stops. Because the model can parse HTML into a DOM, it can reason about the page rather than follow a fixed script. It also supports multi-turn conversations, so you can refine a request mid-flow to complete form-filling or scraping scenarios. Built for real use : watch the automation happen in real time for debugging. and real oversight Live View : a human-in-the-loop override for ambiguous or sensitive steps. watch the automation happen in real time for debugging. Take Control : each interaction gets its own sandboxed browser. a human-in-the-loop override for ambiguous or sensitive steps. Isolated sessions : for reliability, optimisation, and audit. each interaction gets its own sandboxed browser. Built-in observability : for internal systems (private preview). for reliability, optimisation, and audit. Private website browsing : Python, C#, JavaScript, Java, and the REST API. for internal systems (private preview). Broad SDK support , and the agent can make mistakes or be misled by malicious page content Python, C#, JavaScript, Java, and the REST API. A word on responsible use. BAT is powerful precisely because an AI can use credentials you share with it to reach email, financial, enterprise, or social accounts , watching for and the agent can make mistakes or be misled by malicious page content. You're responsible for reviewing your applications, scoping which credentials you provide, and adding your own mitigations. See the Foundry Agent Service transparency note. This is exactly the kind of trade-off we want to talk through together. Example scenario A user asks: "Report the year-to-date percent change of Microsoft's stock price." The agent navigates to a finance site, enters MSFT in the search bar, opens the stock page, clicks the YTD view on the chart, reads the value, and returns a clean, structured answer ; that's the no bespoke scraper, no hard-coded selectors, and a full trace of what it did. Discussion prompt: "Where would browser automation fit into your current projects or workflows?" How setup works (the short version) You'll want to understand the wiring before you scale, so it's worth a look ahead of the session. There are two moving parts: Create a Playwright Workspace in the Azure portal, enable the access token auth method, and grab the wss:// browser endpoint. Give your project identity a Contributor (or custom) role on the workspace. Connect the tool in Foundry under Build > Tools: create a toolbox, add Browser Automation, point it at your Playwright workspace and auth type, and publish. Copy the Project connection ID from the tool's details page : how agents interact with the web, example use cases, and responsible use. that's the BROWSER_CONNECTION_ID in your code. What we'll cover in the 40 minutes Welcome & opening question (0:00–0:03) : navigate, gather, interact, and return a structured result, end to end. the browser task you'd most love to automate. What is Browser Automation (0:03–0:07) : the workflows you're building, public vs. internal targets, and where you'd pick automation over scripting. how agents interact with the web, example use cases, and responsible use. Scenario walkthrough (0:07–0:12) : what agents may do autonomously, what needs approval, and the observability and enterprise safeguards you'd require. navigate, gather, interact, return a structured result : your biggest adoption blockers, missing docs, and the SDK samples and demos you'd prioritise. end to end. Use cases & opportunities (0:12–0:22) : vote live on top use cases, challenges, and feature requests. the workflows you're building, public vs. internal targets, and where you'd pick automation over scripting. Trust, security & governance (0:22–0:31) , and which would benefit most from a capable agent. what agents may do autonomously, what needs approval, and the observability and enterprise safeguards you'd require. Developer experience feedback (0:31–0:36) ; which should always require approval. your biggest adoption blockers, missing docs, and the SDK samples and demos you'd prioritise. Prioritisation & next steps (0:36–0:40) , sometimes with credentials, vote live on top use cases, challenges, and feature requests. Come prepared to talk about The browser-based workflows you're building today : navigation, data gathering, form filling, and research, via an MCP tool powered by Playwright Workspaces. and which would benefit most from a capable agent. Whether your scenarios target public websites, internal systems, or both. Why you'd choose browser automation over traditional scripting. Which actions you'd let an agent perform autonomously : a perception-action loop with screenshots and DOM parsing handles pages that break brittle scripts. and which should always require approval. The observability, audit, and enterprise safeguards you'd expect before running this in production. The examples, samples, and tutorials that would help you get started fastest. Responsible and secure by design Because BAT lets an agent take real actions on live websites : isolated sessions, Live View, Take Control, and observability for reliability and audit. sometimes with credentials : scope credentials carefully and add your own mitigations; the tool is powerful and in preview. governance is a first-class part of the conversation, not a footnote. Isolated per-session sandboxes, Live View, Take Control human-in-the-loop, and built-in observability are there so you can see, pause, and audit what an agent does. Bring your trust concerns, required guardrails, and governance requirements: they directly shape the roadmap. Note: the Browser Automation tool is in preview; APIs and capabilities may change, and it isn't recommended for production workloads yet. Key takeaways Browser Automation lets Foundry agents complete real web workflows : this round table feeds directly into the engineering and product teams. navigation, data gathering, form filling, research , and arrive on time for the tech check. via an MCP tool powered by Playwright Workspaces. Agents reason, not just replay , and browser-capable agents are how we cross it. a perception–action loop with screenshots and DOM parsing handles pages that break brittle scripts. Oversight is built in: isolated sessions, Live View, Take Control, and observability for reliability and audit. Responsibility is shared: scope credentials carefully and add your own mitigations; the tool is powerful and in preview. Your feedback shapes the product: this round table feeds directly into the engineering and product teams. Save your spot Add it to your calendar: 22 July 2026, 2:30 PM BST / 7:00 PM IST, and arrive on time for the tech check. Join the community: https://aka.ms/foundry/discord Prep with the sample: explore the browser automation sample in foundry-samples. Read the docs: Automate browser tasks with Foundry agents and the hosted-agent quickstart. Event registration link https://discord.gg/Z8JZsrP5P5?event=1527676149264679013 The last mile of automation still runs in a browser, and browser-capable agents are how we cross it. Come tell us what you'd automate, where you'd draw the line, and what you'd need to trust it in production. See you on 22 July.