azure
8203 TopicsError: The provided client secret keys are expired
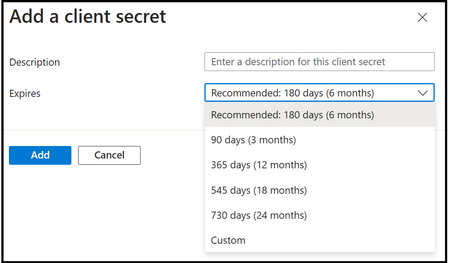
If you have been using Microsoft Graph Data Connect for a while, you might have configured a recurring pipeline that has been running for several months. In that case, you might run into this error: Operation on target task_name failed: ErrorCode=UserErrorOffice365SinkValidationError, 'Type=Microsoft.DataTransfer.Common.Shared.HybridDeliveryException, Message=Office365 data loading job failed to validate the sink data store. Possible causes are the name of the data store or its folder path is invalid, or the provided credentials do not have enough permission to access the folder. Detailed error: ADLS Gen2 operation failed for: Failed to get access token by using service principal. Error: invalid_client, Error Message: A configuration issue is preventing authentication – check the error message from the server for details. You can modify the configuration in the application registration portal. See https://aka.ms/msal-net-invalid-client for details. Original exception: AADSTS7000222: The provided client secret keys for app 'xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx' are expired. Visit the Azure portal to create new keys for your app: https://aka.ms/NewClientSecret, or consider using certificate credentials for added security: https://aka.ms/certCreds. Trace ID: xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx Correlation ID: xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx Timestamp: 2024-11-26 18:35:23Z. Account: 'account_name'. FileSystem: 'container_name'. Path: 'folder_name'., Source=Microsoft.DataTransfer.ClientLibrary,' The main error is really "The provided client secret keys for app 'x' are expired." The solution is simple. Go back to Azure Entra ID to configure a new secret for the App Registration. You can follow the instructions at step 1b in our Synapse step-by-step instructions to add a new secret. Finally, be sure to add the new secret to the link services of the pipeline (you need to update both the source (Source/MGDC) and the destination (Sink/Storage). You avoid this issue completely by keeping track of the secret expiration date and creating a new one (and updating the pipeline) ahead of time. You can have multiple secrets in place, allowing for this secret rotation to be done proactively.MGDC for SharePoint FAQ: How to use Excel for analytics
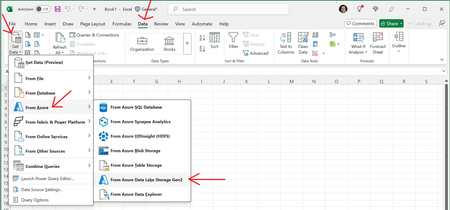
MGDC for SharePoint – Dataset types and features In this post, we’ll discuss how to use Microsoft Excel to consume the data from Microsoft Graph Data Connect (MGDC) for SharePoint. If you’re new to MGDC, get an overview at https://aka.ms/SharePointData. 1. Introduction In most examples on how to analyze the data from MGDC for SharePoint, we use Azure Synapse in combination with Power BI Desktop, which is a very capable tool that can turn your data into coherent, visually immersive, and interactive insights. But keep in mind that, when pulling datasets from MGDC with Azure Synapse, the data becomes available in an Azure storage account as a set of JSON files. From there, you can use many different tools beyond Power BI. In this article, we will focus on how to read and analyze that data using Microsoft Excel. 2. Get the data into Azure storage The first step in the process is to get your data from MGDC. I have a blog post that describes that process at Step-by-step: (Synapse) Gather a detailed dataset on SharePoint Sites using MGDC. Section 1 if that blog shows how to setup the Microsoft Graph Data Connect and section 2 describes how to run an Azure Synapse pipeline to pull the data. If you complete these first two sections, you will end up with your SharePoint Sites data in Azure. You can skip section 3 of that blog, that describes how to get the data into a Power BI dashboard. You will replace that section with the information in this article, which takes the data to Microsoft Excel instead. 3. Bring the data from Azure storage to Excel Next, you need to bring the data in the JSON files from the Azure storage account to your Excel spreadsheet. Fortunately, Excel has the perfect set of tools to bring in that data. You should start with a blank spreadsheet. Select the “Data” tab in the ribbon and use the option to “Get Data”. Then select the option “from Azure” and choose “From Azure Data Lake Storage Gen2”. This will make sure that you’re getting the data in your ADLS Gen2 storage account. > Get Data --> From Azure --> From Azure Data Lake Storage Gen2 Next, you will need to provide the URL to the ADLS Gen2 storage. Provide the full path, with the container and folder in the format: https://account.dfs.core.windows.net/container/folder. The account name is in step 1d of the at step-by-step guide mentioned before. The container and folder names are in step 1f of the guide. You can also find the URL in the Azure Portal, under the Settings/Endpoints section of the storage account. Once you provide the URL and click OK, you will need to authenticate. Select the option to use the storage account key and type in the key you saved in step 1d of the at step-by-step guide. You can find the key in the Azure Portal, under the “Security + Networking” / “Access Keys” section of the storage account. Once you have typed the account key, click “Connect”. At this point, you want to click on the “Transform Data” button to filter for the specific files you want. This will open the “Power Query Editor” window, where you can apply specific steps to filter the data coming in. The easiest way to filter out the metadata files is to scroll right until you find the “Folder Path” column and filter that column for paths that do not contain the word “metadata”. > down arrow --> Text filters --> Does not contain... After that, you can scroll left to the “Content” column and click on the button to “Combine files”. After that, the query will pull in the content of the files and expand all the columns from the JSON. > Content --> Combine files Finally, you can click on the “Close & Load” button to bring the data into a sheet. & Load With that, you can play with the data in Excel. 4. Create PivotTables Once the data is imported into your Excel spreadsheet, you will be able to create data visualizations from it. The most interesting way to do this is to use Excel PivotTables. For instance, here’s a pivot table with storage (Storage Used) by site type (RootWeb.WebTemplate) on the different dates you pulled data (SnapShotDate). See the sample PivotTable below after some adjustments and formatting. 5. Tips Here are a few additional comments. Distinct types of authentication: As you might have noticed, there are multiple ways to authenticate to get access to the Azure storage account. In addition to using a key to the entire storage account as shown here, you could use Azure to grant specific permissions to a user and log in as that user. This will help restrict access to specific folders and grant limited permissions (like read-only). Create custom columns: To help with your data analysis, you might want to add a few custom or calculated columns. You can in many ways, including transformations in Power Query, formulas in the Excel sheet or in the pivot table itself. You can read more about it at How to create custom columns in Power BI (this says Power BI but applies to Excel as well). More than one million rows: If you’re using this to visualize data from the SharePoint Sites dataset, you are likely to have fewer than one million rows, which is the Microsoft Excel limit. If you’re one of the few tenants that will have more than one million sites or if you’re analyzing a larger dataset like Permissions or Files, you can only pull the first one million rows into a sheet. To overcome this, you can load the data into a model and use that to drive your pivot tables. You can read more about it at Loading CSV/text files with more than a million rows into Excel (this says text files but applies to JSON as well). 6. Conclusion I hope this post helped you understand how to use Microsoft Excel to pull JSON data from an Azure storage account used by MGDC for SharePoint. For more information, visit https://aka.ms/SharePointData.