azure sql
747 TopicsStop defragmenting and start living: auto index compaction is now generally available
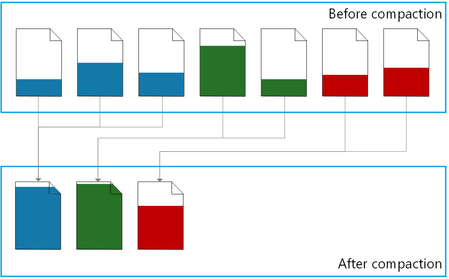
Executive summary Automatic index compaction is a built-in MSSQL database engine feature that compacts indexes in background and with minimal overhead. Now you can: Stop using scheduled index maintenance jobs. Reduce storage space consumption and save costs. Improve performance by reducing CPU, memory, and disk I/O consumption. Automatic index compaction is now generally available in Azure SQL Database, Azure SQL Managed Instance with the always-up-to-date update policy, and SQL database in Fabric. Index maintenance without maintenance jobs Enable automatic index compaction for a database with a single T-SQL command: ALTER DATABASE [database-name] SET AUTOMATIC_INDEX_COMPACTION = ON; Once enabled, you no longer need to set up, maintain, and monitor resource intensive index maintenance jobs, a time-consuming operational task for many DBA teams today. As the data in the database changes, a background process consolidates rows from partially filled data pages into a smaller number of filled up pages, and then removes the empty pages. Index bloat is eliminated – the same amount of data now uses a minimal amount of storage space. Resource consumption is reduced because the database engine needs fewer disk IOs and less CPU and memory to process the same amount of data. By design, the background compaction process acts on the recently modified pages only. This means that its own resource consumption is much lower compared to the traditional index maintenance operations (index rebuild and reorganize), which process all pages in an index or its partition. For a detailed description of how the feature works, a comparison between automatic index compaction and the traditional index maintenance operations, and the ways to monitor the compaction process, see automatic index compaction in documentation. Let the numbers speak As auto index compaction becomes generally available, it is already enabled in more than 6 million databases worldwide, most of them from Microsoft internal customers who helped validate the feature during preview. Hundreds of external customers also enabled auto compaction during preview and have been enjoying the benefits, with zero issues reported. Looking at our worldwide telemetry data for a 28-day window, automatic index compaction freed up approximately 14.3 petabytes of space in data files by consolidating 547.5 trillion rows on fewer pages, saving resources and improving query performance. Looking at the space freed up per database, the benefits range from a few megabytes per day for databases with already dense pages, to more than 500 gigabytes per day for databases that have gone through one-time extensive data modifications. Compaction in action To see the effects of automatic index compaction, we wrote a stored procedure that simulates a write-intensive OLTP workload. Each execution of the procedure inserts, updates, deletes, or selects a random number of rows, from 1 to 100, in a 50,000-row table with a clustered index. We executed this stored procedure using a popular SQLQueryStress tool, with 30 threads and 400 iterations on each thread. We measured the page density, the number pages in the leaf level of the table’s clustered index, and the number of logical reads (pages) used by a test query reading 1,000 rows, at three points in time: After initially inserting the data and before running the workload. Once the workload stopped running. Several minutes later, once the background process completed index compaction. Here are the results: Before workload After workload After compaction Logical reads 25 🟢 1,610 🔴⬆️ 35 🟢⬇️ Page density 99.51% 🟢 52.71% 🔴⬇️ 96.11% 🟢⬆️ Pages 962 🟢 4,394 🔴⬆️ 1,065 🟢⬇️ Before the workload starts, page density is high because nearly all pages are full. The number of logical reads required by the test query is minimal, and so is its resource consumption. The workload leaves a lot of empty space on pages and increases the number of pages because of row updates and deletions, and because of page splits. As a result, immediately after workload completion, the number of logical reads required for the same test query increases more than 60 times, which translates into a higher CPU and memory usage. But then within a few minutes, automatic index compaction removes the empty space from the index, increasing page density back to nearly 100%, reducing logical reads by about 98% and getting the index very close to its initial compact state. Less logical reads means that the query is faster and uses less CPU. All of this without any user action. With continuous workloads, index compaction is continuous as well, maintaining higher average page density and reducing resource usage by the workload over time. The T-SQL code we used in this demo is available in the Appendix. Conclusion Automatic index compaction delegates a routine database maintenance operation to the database engine itself, letting administrators and engineers focus on more important work without worrying about index maintenance. Making this feature generally available doesn’t mean that we stop working on it. Your feedback during preview helped us find new opportunities to fine-tune the compaction process. We thank you for that feedback and look forward to announcing new improvements in auto index compaction in the future. Appendix Here is the T-SQL code we used to demonstrate automatic index compaction. The type of executed statements and the number of affected rows is randomized to better represent an OLTP workload. While the results demonstrate the effectiveness of automatic index compaction, exact measurements may vary from one execution to the next. /* Enable automatic index compaction */ ALTER DATABASE CURRENT SET AUTOMATIC_INDEX_COMPACTION = ON; /* Reset to the initial state */ DROP TABLE IF EXISTS dbo.t; DROP SEQUENCE IF EXISTS dbo.s_id; DROP PROCEDURE IF EXISTS dbo.churn; /* Create a sequence to generate clustered index keys */ CREATE SEQUENCE dbo.s_id AS int START WITH 1 INCREMENT BY 1; /* Create a test table */ CREATE TABLE dbo.t ( id int NOT NULL CONSTRAINT df_t_id DEFAULT (NEXT VALUE FOR dbo.s_id), dt datetime2 NOT NULL CONSTRAINT df_t_dt DEFAULT (SYSDATETIME()), u uniqueidentifier NOT NULL CONSTRAINT df_t_uid DEFAULT (NEWID()), s nvarchar(100) NOT NULL CONSTRAINT df_t_s DEFAULT (REPLICATE('c', 1 + 100 * RAND())), CONSTRAINT pk_t PRIMARY KEY (id) ); /* Insert 50,000 rows */ INSERT INTO dbo.t (s) SELECT REPLICATE('c', 50) AS s FROM GENERATE_SERIES(1, 50000); GO /* Create a stored procedure that simulates a write-intensive OLTP workload. */ CREATE OR ALTER PROCEDURE dbo.churn AS SET NOCOUNT, XACT_ABORT ON; DECLARE @r float = RAND(CAST(CAST(NEWID() AS varbinary(4)) AS int)); /* Get the type of statement to execute */ DECLARE @StatementType char(6) = CASE WHEN @r <= 0.15 THEN 'insert' WHEN @r <= 0.30 THEN 'delete' WHEN @r <= 0.65 THEN 'update' WHEN @r <= 1 THEN 'select' ELSE NULL END; /* Get the maximum key value for the clustered index */ DECLARE @MaxKey int = ( SELECT CAST(current_value AS int) FROM sys.sequences WHERE name = 's_id' AND SCHEMA_NAME(schema_id) = 'dbo' ); /* Get a random key value within the key range */ DECLARE @StartKey int = 1 + RAND() * @MaxKey; /* Get a random number of rows, between 1 and 100, to modify or read */ DECLARE @RowCount int = 1 + RAND() * 99; /* Execute a statement */ IF @StatementType = 'insert' INSERT INTO dbo.t (id) SELECT NEXT VALUE FOR dbo.s_id FROM GENERATE_SERIES(1, @RowCount); IF @StatementType = 'delete' DELETE TOP (@RowCount) dbo.t WHERE id >= @StartKey; IF @StatementType = 'update' UPDATE TOP (@RowCount) dbo.t SET dt = DEFAULT, u = DEFAULT, s = DEFAULT WHERE id >= @StartKey; IF @StatementType = 'select' SELECT TOP (@RowCount) id, dt, u, s FROM dbo.t WHERE id >= @StartKey; GO /* The remainder of this script is executed three times: 1. Before running the workload using SQLQueryStress. 2. Immediately after the workload stops running. 3. Once automatic index compaction completes several minutes later. */ /* Monitor page density and the number of pages and records in the leaf level of the clustered index. */ SELECT avg_page_space_used_in_percent AS page_density, page_count, record_count FROM sys.dm_db_index_physical_stats(DB_ID(), OBJECT_ID('dbo.t'), 1, 1, 'DETAILED') WHERE index_level = 0; /* Run a test query and measure its logical reads. */ DROP TABLE IF EXISTS #t; SET STATISTICS IO ON; SELECT TOP (1000) id, dt, u, s INTO #t FROM dbo.t WHERE id >= 10000 SET STATISTICS IO OFF;7.3KViews3likes7CommentsWhat Really Happens When You Scale Azure SQL Database? How to Monitor Long-Running Scale Operations
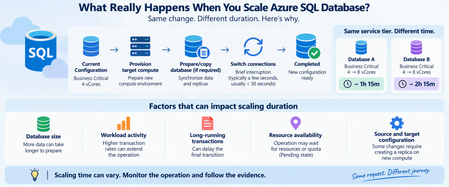
One of the advantages of Azure SQL Database is the ability to scale compute resources without managing the underlying infrastructure. Changing from 4 vCores to 8 vCores can be only a few clicks or a single command. But there is a question I frequently see when troubleshooting scaling operations: "Why is my Azure SQL Database scaling operation taking so long?" An even more interesting question appears when two databases undergo what looks like the same change: Database A Business Critical → Business Critical Scaling duration: ~1 hour 15 minutes Database B Business Critical → Business Critical Scaling duration: ~2 hours 15 minutes Same service tier. Similar scaling request. Very different completion time. At first glance, that might look unusual. However, a scale operation isn't simply Azure changing a configuration value from one number of vCores to another. Depending on the source and target configuration, Azure SQL Database can need to provision target compute, prepare or copy database data, transition connections to the target compute, and clean up the original environment. Microsoft specifically notes that creating a database replica on the new compute instance for some scaling combinations can strongly influence the overall latency. Let's look at what happens and, more importantly, how to monitor it. Scaling Is More Than Changing vCores When you submit a scaling request such as: Business Critical 4 vCores ↓ Business Critical 8 vCores it's tempting to imagine something like: CPU allocation: 4 → 8 Done. That isn't necessarily what happens. At a high level, Microsoft documents a scaling workflow involving two important stages: Create a new compute instance with the requested service tier and compute size Switch routing from the original compute instance to the new one For some combinations of service-tier and compute-size changes, Azure SQL Database must also create a replica on the new compute instance, involving data copying. A simplified view is: Scaling request ↓ Prepare target compute ↓ Prepare/copy database if required ↓ Bring target environment ready ↓ Switch connections ↓ Scaling complete The important takeaway is: A scale operation can involve moving database execution to a new compute environment, not simply increasing CPU on the existing environment. Why Can Two Similar Databases Take Different Amounts of Time? This is where troubleshooting becomes interesting. Imagine two databases: Database A 4 vCores → 8 vCores Completed in 75 minutes Database B 4 vCores → 8 vCores Completed in 135 minutes The natural question is: "If the source and destination configurations are the same, shouldn't the duration also be the same?" Not necessarily. The requested configuration tells us where the database needs to end up. It does not mean the work required to reach that state is identical. Several factors can affect the operation. 1. Database Size and Data Movement One of the most important factors can be the amount of data that must be prepared on the target compute. Microsoft's scaling documentation explicitly states that for some source/target combinations, a replica must be created on the new compute instance. That involves copying data and can significantly affect the overall scaling latency. Conceptually: Small database Provision ████ Data preparation ██████ Switch █ versus: Large database Provision ████ Data preparation ████████████████████████ Switch █ Database size alone doesn't provide a precise prediction of completion time, but it can influence the amount of work required during applicable scaling paths. 2. Workload Activity Matters A database also doesn't necessarily stop processing application traffic while Azure prepares the target environment. Microsoft states that during target compute creation, the database remains online and connections continue to the original compute instance. That creates an interesting challenge: Target environment preparing + Application still generating workload A highly active transactional database and a relatively idle database can therefore present different operational conditions during scaling. The practical lesson is: Two databases with the same service objective aren't necessarily in the same workload state when scaling begins. When investigating a slow scale operation, look at the activity around the scaling window, including: transaction volume; write activity; long-running transactions; workload peaks; batch operations; maintenance activity. 3. Long-Running Transactions Can Affect Switchover Toward the end of scaling, connections need to transition to the target compute instance. Microsoft documents that existing connections to the original compute are dropped and new connections are established to the target compute. The switch generally results in a short interruption, often only a few seconds and generally less than 30 seconds. However, there's an important exception. Microsoft notes that: If long-running transactions are active when connections are dropped, the switch can take longer because aborted transactions need to recover. Conceptually: Normal transition Target ready ↓ Switch ↓ Reconnect ↓ Done With a long-running transaction: Target ready ↓ Connection transition ↓ Transaction interruption ↓ Recovery work ↓ Reconnect ↓ Done This is one reason application workload should be considered when evaluating scaling duration. 4. Resource Availability Can Matter Another clue comes from Azure SQL's operation-status metadata. The sys.dm_operation_status DMV exposes several states for database operations, including: PENDING IN_PROGRESS COMPLETED FAILED CANCEL_IN_PROGRESS CANCELLED Importantly, Microsoft defines PENDING as an operation waiting for resource or quota availability. That means some of the elapsed time around an operation may occur before active processing progresses as expected. This is why comparing scale operations purely by database size or vCore count can be misleading. How Can I Monitor a Scaling Operation? Rather than repeatedly refreshing the Azure portal, there are several useful methods for inspecting progress. Method 1: Azure PowerShell with Get-AzSqlDatabaseActivity Azure PowerShell provides: Get-AzSqlDatabaseActivity Microsoft documents this cmdlet specifically for retrieving the status of operations against Azure SQL databases. For example: Get-AzSqlDatabaseActivity ` -ResourceGroupName "MyResourceGroup" ` -ServerName "myserver" ` -DatabaseName "mydatabase" This can help identify database operations associated with the selected database. For clearer output: Get-AzSqlDatabaseActivity ` -ResourceGroupName "MyResourceGroup" ` -ServerName "myserver" ` -DatabaseName "mydatabase" | Select-Object ` Operation, OperationId, DatabaseName, State, PercentComplete, StartTime, ErrorCode, ErrorMessage The specific fields returned can vary with module/API behavior, so always interpret them in the context of the operation being monitored. The important point is that you're no longer asking only: "Is scaling still happening?" You can inspect the operation itself. Method 2: Check Current and Requested Service Objectives Another useful PowerShell command is: Get-AzSqlDatabase Microsoft documents this cmdlet for retrieving Azure SQL Database properties. Its output includes service-objective information such as CurrentServiceObjectiveName and RequestedServiceObjectiveName. For example: Get-AzSqlDatabase ` -ResourceGroupName "MyResourceGroup" ` -ServerName "myserver" ` -DatabaseName "mydatabase" | Select-Object ` DatabaseName, Status, Edition, CurrentServiceObjectiveName, RequestedServiceObjectiveName During a change, comparing these fields can help establish the current and requested configuration. Think of it as: CurrentServiceObjectiveName ↓ Where am I now? RequestedServiceObjectiveName ↓ Where am I trying to go? Once the operation completes successfully, the current configuration should reflect the requested target. Method 3: Use sys.dm_operation_status For SQL-side monitoring, sys.dm_operation_status provides information about database operations such as CREATE and ALTER. For example: SELECT major_resource_id, operation, state_desc, percent_complete, start_time, last_modify_time, error_code, error_desc FROM sys.dm_operation_status ORDER BY start_time DESC; Useful columns include: operation state_desc percent_complete start_time last_modify_time error_code error_desc Microsoft defines the operation states as including PENDING, IN_PROGRESS, COMPLETED, and FAILED. Be Careful With PercentComplete This is an important detail. It is tempting to interpret: PercentComplete = 50 as: "Half of the work is finished, so half of the remaining time is left." That isn't necessarily correct. For sys.dm_operation_status, Microsoft documents percent_complete for most operations as: 0 = Operation not started 50 = Operation in progress 100 = Operation complete Restore operations are an important exception, where values between 1 and 99 can indicate more granular progress. So for a normal ALTER/scale operation: 50% should generally be interpreted as: The operation is in progress rather than: Exactly half the work remains. This distinction is very useful when communicating with application teams during long-running operations. A Practical Monitoring Script For PowerShell users, I like combining the configuration and operation views. First check the database: $db = Get-AzSqlDatabase ` -ResourceGroupName "MyResourceGroup" ` -ServerName "myserver" ` -DatabaseName "mydatabase" $db | Select-Object ` DatabaseName, Status, Edition, CurrentServiceObjectiveName, RequestedServiceObjectiveName Then check database operations: Get-AzSqlDatabaseActivity ` -ResourceGroupName "MyResourceGroup" ` -ServerName "myserver" ` -DatabaseName "mydatabase" This gives you two complementary perspectives: DATABASE STATE + OPERATION STATE ↓ Better understanding of scaling progress What About Application Availability During Scaling? One of the biggest concerns is: "Does the database remain available while scaling?" For Azure SQL Database, Microsoft states that the database remains online while the new compute environment is being prepared. Connections continue to the original compute during that stage. The important availability event occurs during the transition. At switchover: Existing connections ↓ Dropped ↓ Routing switches ↓ New connections ↓ Target compute Microsoft says the switch generally causes an interruption of less than 30 seconds and often only a few seconds. Applications should therefore implement appropriate transient-error handling and retry logic. Microsoft explicitly recommends retry logic for applications and components using the database while the service tier is being changed. Don't Immediately Cancel a "Slow" Scaling Operation A scale operation taking longer than expected does not automatically mean: Scaling is stuck. It could still be legitimately working through: Resource availability ↓ Target compute preparation ↓ Data/replica preparation ↓ Synchronization / workload handling ↓ Switchover Before assuming failure, gather evidence. Check: Operation state Current service objective Requested service objective Start time Last modification time Error details Workload activity Long-running transactions Then determine whether the operation is: Pending Actively progressing Completed or: Failed Troubleshooting Two Databases With Different Scaling Durations Suppose you're investigating: Database A Scale duration: 1h15 Database B Scale duration: 2h15 Here is the approach I recommend. 1. Verify that the changes truly match Compare: Source service tier Target service tier Source vCores Target vCores Compute tier Storage configuration Do not assume both operations were identical simply because both ended at, for example, Business Critical 8 vCores. 2. Compare database characteristics Look at: Database size Workload level Write activity Transaction volume Long-running transactions 3. Compare operation timing Retrieve: Start time State Last modification time Completion time sys.dm_operation_status exposes this operation metadata for Azure SQL database operations. 4. Determine whether either operation spent time pending Remember: PENDING can mean the operation is waiting for resource or quota availability. That represents a very different explanation from: "The database took longer to copy." 5. Check workload around the transition Look for: Large transactions Bulk writes ETL operations Maintenance High transaction rates Long-running transactions particularly around the switchover period. Scaling Duration Is Not an SLA Stopwatch This leads to perhaps the most important takeaway. If: Database A took 75 minutes you should not assume: Database B must take approximately 75 minutes. Even apparently similar scale operations can encounter different database and platform conditions. A better operational expectation is: Treat each scaling operation as an asynchronous platform operation whose duration depends on the work required to safely reach the requested configuration. Monitor the operation rather than predicting its completion from a previous database. Recommended Checklist Before scaling a production Azure SQL Database: Before Review workload activity. Identify long-running transactions or batch processes. Confirm the requested service objective. Ensure application retry logic is implemented. Record the UTC start time. Understand dependent application connection behavior. During Monitor: Get-AzSqlDatabaseActivity Get-AzSqlDatabase sys.dm_operation_status and watch: State CurrentServiceObjectiveName RequestedServiceObjectiveName StartTime LastModifyTime Error information After Confirm: Current service objective = requested target Database status = Online Application connectivity = Healthy Workload performance = Expected Also validate that applications successfully reconnected after the transition. Final Thoughts When Azure SQL Database scaling takes longer than expected, it's easy to think: "Something must be wrong." And when two similar databases take very different amounts of time, it's equally tempting to expect the durations to match. But a scale operation can involve substantially more than changing a vCore number. At a high level: Request scaling ↓ Provision target compute ↓ Prepare/copy database when required ↓ Transition connections ↓ Complete Microsoft's documentation confirms that data copying for applicable scale paths can strongly influence latency, that the switchover can take longer in the presence of long-running transactions, and that a pending operation might be waiting for resource or quota availability. So when someone asks: "Why is Azure SQL scaling taking so long?" my recommendation is not to start by guessing how many minutes it should take. Instead ask: "What state is the operation currently in, and what evidence do we have about its progress?" With Get-AzSqlDatabaseActivity, Get-AzSqlDatabase, and sys.dm_operation_status, you can turn an opaque waiting period into a much more structured investigation. References Scale single database resources in Azure SQL Database Scale resources in Azure SQL Database sys.dm_operation_status Get-AzSqlDatabaseActivity Get-AzSqlDatabaseAzure SQL Performance Troubleshooting: When High Latency Is Not High CPU
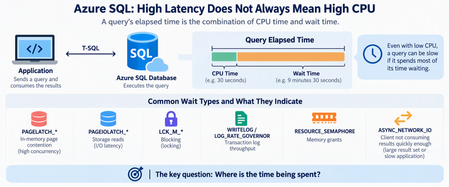
When an application connected to Azure SQL Database becomes slow or starts timing out, one of the first questions is usually: Is the database running out of CPU? It's a reasonable starting point, but CPU is only one part of the performance story. Some Azure SQL performance problems occur while CPU, Data IO, and worker utilization appear healthy. The database may have plenty of compute capacity while queries spend most of their time waiting rather than executing. The key troubleshooting question is therefore not simply: "How much CPU is Azure SQL using?" Instead, ask: "Where is the elapsed time being spent?" Start With Resources, But Don't Stop There Resource utilization should still be the first checkpoint. A simple query using sys.dm_db_resource_stats can help identify whether Azure SQL is approaching CPU, Data IO, Log IO, memory, or worker limits: SELECT DB_NAME() AS database_name, AVG(avg_cpu_percent) AS avg_cpu_percent, MAX(avg_cpu_percent) AS max_cpu_percent, MAX(avg_data_io_percent) AS max_data_io_percent, MAX(avg_log_write_percent) AS max_log_write_percent, MAX(avg_memory_usage_percent) AS max_memory_percent, MAX(max_worker_percent) AS max_worker_percent FROM sys.dm_db_resource_stats; If CPU is consistently near 100%, investigate CPU consumption. If Log IO reaches its limit, investigate transaction-log generation. If workers are exhausted, investigate concurrency. But if none of these resources is saturated, don't conclude that Azure SQL is healthy. Move to wait analysis. Follow the Waits A useful simplified model is: Query elapsed time = CPU execution If a query runs for 10 minutes but uses only 30 seconds of CPU, most of its elapsed time occurred somewhere else. Common wait patterns can point the investigation in different directions: Wait Area to investigate PAGELATCH_* In-memory page contention PAGEIOLATCH_* Storage reads LCK_M_* Blocking WRITELOG Transaction log LOG_RATE_GOVERNOR Log throughput RESOURCE_SEMAPHORE Memory grants ASYNC_NETWORK_IO Client/result consumption The wait type is not automatically the root cause. Think of it as a sign telling you: Look in this direction next. PAGELATCH Does Not Mean Slow Storage One important distinction is: PAGELATCH versus: PAGEIOLATCH Despite their similar names, they represent different problems. PAGEIOLATCH is associated with waiting for data pages involved in physical I/O. PAGELATCH, however, is synchronization around pages that are already in memory. Consider a highly concurrent workload: Hundreds of sessions ↓ Same memory page ↓ Latch contention ↓ Sessions wait ↓ Application CPU may still have available capacity. This is why increasing vCores doesn't necessarily eliminate latch contention. Additional compute provides more workload headroom, but it doesn't automatically remove a serialization point around a hot page. Microsoft's I/O troubleshooting guidance also distinguishes PAGEIOLATCH and other I/O-related waits when diagnosing storage-performance problems. Microsoft Learn: Troubleshoot SQL Server I/O performance Query Frequency Matters Too Another common mistake is focusing only on individually expensive queries. Imagine a query that takes only 20 milliseconds but executes hundreds of thousands of times, often concurrently. Its impact is better thought of as: Workload Impact = Cost per execution × Execution frequency × A small metadata lookup or initialization query can become significant when hundreds of application instances execute it simultaneously. This is where Query Store becomes particularly useful. Query Store preserves query, execution-plan, and runtime history, allowing you to compare executions, duration, CPU, plans, and other performance characteristics over time. Microsoft Learn: Monitor performance using Query Store Instead of asking only: "What's my most expensive query?" also ask: "What changed in the workload?" When Nine Hours of Duration Is Only One Minute of CPU Now consider the opposite problem. Suppose Query Store shows something like: Elapsed time 9 hours SQL CPU time 1 minute Returned rows 750,000+ Dominant wait ASYNC_NETWORK_IO Would adding CPU solve this? Probably not. CPU represents only a tiny fraction of the elapsed time. ASYNC_NETWORK_IO commonly occurs when SQL Server has results available but the client application is not consuming them quickly enough. Microsoft documents several possible causes, including: large result sets; slow application processing; applications fetching rows slowly; network-related delays. Microsoft Learn: Troubleshoot ASYNC_NETWORK_IO Importantly: ASYNC_NETWORK_IO does not automatically mean the network is slow. The bottleneck might actually be the application. Measure Time to First Row A useful troubleshooting technique is to separate database response time from result-consumption time. Instead of measuring only: Query start → Application finished measure: T0 = Query submitted T1 = First row received T2 = Last row received T3 = Application processing completed You can then separate: Database response = T1 - T0 Result consumption = T2 - T1 Application For example: First row received: 2 seconds Last row received: 2 hours Processing completed: 2.5 hours Calling this a "2.5-hour SQL query" would be misleading. SQL started returning results after two seconds. Most of the time was spent transferring or processing them. Don't Forget Blocking Low CPU can also be caused by blocking. If many sessions are waiting behind a transaction, increasing CPU isn't going to solve the problem. During an active incident, check requests and their waits: SELECT r.session_id, r.blocking_session_id, r.status, r.wait_type, r.wait_time, r.wait_resource, r.cpu_time, r.total_elapsed_time, st.text FROM sys.dm_exec_requests AS r CROSS APPLY sys.dm_exec_sql_text(r.sql_handle) AS st WHERE r.blocking_session_id <> 0 ORDER BY r.wait_time DESC; This helps determine whether the application is experiencing a resource problem or simply waiting behind another transaction. Why Scaling Can Be Misleading Imagine this sequence: Application slow ↓ Scale database ↓ Performance improves It's tempting to conclude: "We needed more CPU." But scaling can change more than CPU availability. Depending on the operation and environment, it can alter resource availability or execution conditions. Therefore: A successful mitigation does not automatically prove the root cause. Always distinguish between: What made the symptoms disappear? and: What originally caused the symptoms? A Practical Troubleshooting Workflow When investigating Azure SQL performance, I use the following approach: 1. Define the exact incident window Preferably using UTC timestamps. 2. Check core resources Look at: CPU Data IO Log IO memory workers 3. Compare CPU time with elapsed time If: Elapsed ≈ CPU investigate computational workload. If: Elapsed >>> CPU investigate waits. 4. Identify dominant waits Ask what prevented SQL from continuing execution. 5. Check blocking Determine whether requests are waiting behind other transactions. 6. Use Query Store Compare healthy and problematic periods for: execution count; CPU; duration; logical reads; plans; wait behavior. Microsoft provides Query Store examples specifically for workload and performance investigation. Microsoft Learn: Tune performance with Query Store 7. Inspect the execution plan Look for inefficient access patterns, cardinality problems, excessive reads, repeated lookups, spills, scans, or plan changes. 8. Investigate the application Especially when SQL CPU is low but result-transfer waits are high. Look at: rows returned; fetch size; batch size; application processing; concurrency; downstream dependencies. 9. Compare healthy vs unhealthy periods Don't analyze an incident in isolation. Ask: What changed? Common Misdiagnoses "CPU isn't 100%, so SQL is healthy." Not necessarily. Queries might simply be waiting. "ASYNC_NETWORK_IO means we have a network problem." Not necessarily. The client may be consuming results slowly. "PAGELATCH means storage is slow." No. Don't confuse PAGELATCH with PAGEIOLATCH. "Scaling fixed the problem, so CPU was the root cause." Not necessarily. Mitigation and root cause are different concepts. "The slowest query must be the problem." Not always. A small query executed extremely frequently can generate larger cumulative impact. Final Thought: Follow the Time When Azure SQL becomes slow, avoid jumping directly from: Slow database → Add more vCores Instead, work through: High latency ↓ Resource utilization ↓ CPU vs elapsed time ↓ Wait statistics ↓ Query Store ↓ Execution plan ↓ Application behavior ↓ Root cause ↓ Targeted optimization Performance troubleshooting becomes much easier once you stop asking only: "How busy is Azure SQL?" and start asking: "Where did the time go?" Because sometimes the database isn't busy at all. It's waiting. References Monitor Performance by Using the Query Store Tune performance with the Query Store Troubleshoot slow queries resulting from ASYNC_NETWORK_IO Troubleshoot slow SQL Server performance caused by I/O issuesIntroducing Simplified Regional Limits for Azure SQL Managed Instance
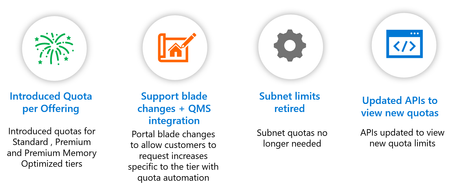
We are pleased to announce improvements to regional subscription limits for Azure SQL Managed Instance. These changes simplify subnet management and provide more granular control over vCore capacity across hardware generations. What’s changing? Two changes are now generally available: Regional subnet limits are removed Azure SQL Managed Instance no longer applies service-specific regional subnet limits. Instead, deployments are governed by the applicable Azure Resource Manager virtual networking limits. This simplifies resource planning and removes the need to monitor or request increases for Azure SQL Managed Instance regional subnet limits. Regional vCore limits are now hardware-generation specific Regional vCore limits are now managed separately for each supported hardware generation: • Standard Series • Premium Series • Premium Series Memory Optimized Previously, a single regional vCore limit applied across hardware generations. With hardware-generation-specific limits, customers can request additional capacity only for the hardware generation required by their workloads. For example, if you need additional Premium Series capacity in a region, you can request an increase for Premium Series without changing the limits for Standard Series or Premium Series Memory Optimized. Check vCore quota limit and usage with PowerShell Use the Subscription Usages - Get REST API to retrieve the current vCore quota limit and consumption for Azure SQL Managed Instance in a subscription and region. Query each hardware generation separately by specifying its usage name: Hardware generation Usage name Standard-series (Gen5) SubscriptionSQLManagedInstanceStandardSeriesVCoreQuota Premium-series SubscriptionSQLManagedInstancePremiumSeriesVCoreQuota Memory optimized premium-series SubscriptionSQLManagedInstancePremiumSeriesMemoryOptimizedVCoreQuota Run the following script in a PowerShell session with the Az module installed, or in Azure Cloud Shell using PowerShell. Your account needs permission to read subscription usage, such as the Reader role assigned at subscription scope. Replace <subscription-id> with your subscription ID, set $location to the Azure region name (for example, eastus), and set $usageName to one of the values in the table. If you're already signed in through Cloud Shell, omit Connect-AzAccount. $subscriptionId = "<subscription-id>" $location = "eastus" $usageName = "SubscriptionSQLManagedInstanceStandardSeriesVCoreQuota" Connect-AzAccount -ErrorAction Stop | Out-Null Set-AzContext -SubscriptionId $subscriptionId -ErrorAction Stop | Out-Null $path = "/subscriptions/$subscriptionId/providers/Microsoft.Sql/locations/$location/usages/${usageName}?api-version=2025-01-01" $response = Invoke-AzRestMethod -Method GET -Path $path -ErrorAction Stop if ($response.StatusCode -ne 200) { throw "Unable to retrieve quota usage. HTTP $($response.StatusCode): $($response.Content)" } $response.Content | ConvertFrom-Json -ErrorAction Stop | ConvertTo-Json -Depth 10 Example output (excerpt; values are illustrative): { "name": "SubscriptionSQLManagedInstanceStandardSeriesVCoreQuota", "properties": { "currentValue": 80, "limit": 320, "unit": "SubscriptionSQLManagedInstanceStandardSeriesVCoreQuota" } } In this example, `properties.currentValue` is the current quota consumption: 80 vCore units. `properties.limit` is the current quota limit: 320 vCore units. The remaining quota is `limit - currentValue`, or 240 vCore units, for standard-series hardware in the specified subscription and region. The previously used VCoreQuota usage name, which represented a single regional quota shared across all hardware generations, is being deprecated in favor of hardware-generation-specific quotas. Use the usage names listed in the table above to retrieve the quota limit and consumption for each hardware generation. What does this mean for existing customers? Existing regional vCore limits will be automatically converted to hardware-generation-specific limits. No customer action is required. Your new limits can be viewed and managed through the Azure portal. If the default limit for a hardware generation is insufficient for a planned deployment, you can request an increase for that specific hardware generation. New hardware generation specific vCore limits apply to both single-zone and multi-zone (Zone Redundant) Managed Instance deployments. Benefits These improvements provide: • Simpler quota management through the removal of service-specific regional subnet limits. • Better granularity with separate vCore limits for each hardware generation. • Greater flexibility to request capacity only where it is needed. • A seamless transition with automatic conversion of existing limits. To learn more about Azure SQL Managed Instance resource limits and how to request an increase, see Request quota increases for Azure SQL Database and SQL Managed Instance. We hope these changes make planning and scaling your Azure SQL Managed Instance deployments simpler and more flexible.558Views1like0CommentsManaged Instance link – connecting SQL Server to Azure reimagined
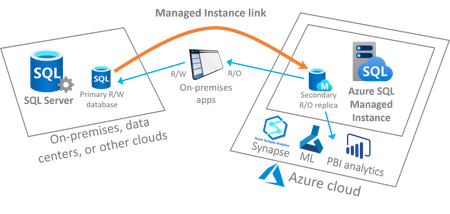
Link feature for Managed Instance is a new feature reimagining the connection between SQL Server hosted anywhere and the fully managed PaaS service Azure SQL Managed Instance, providing unprecedented hybrid flexibility and database mobility. With an approach that uses near real-time data replication to Azure, you can offload workloads to read-only secondaries on Azure to take advantage of a fully managed database platform, performance, and scale. The link can be operated for as long as you need it – months and years at a time, empowering you to get all the modern benefits of Azure today without migrating to the cloud. On your modernization journey, when and if you are ready to migrate to the cloud, the link de-risks your migration experience allowing you to validate your workloads in Azure prior to migrating with a seamless and instant experience, and at your own pace. This article provides deeper insights into this new feature.26KViews4likes9CommentsAzure SQL Database is retiring Always Encrypted with Intel SGX enclaves
On October 31, 2027, Azure SQL Database will retire Intel Software Guard Extensions (SGX) enclave functionality for Always Encrypted. Workloads that still depend on Intel SGX enclaves after that date will no longer work as configured. The path forward is Virtualization-Based Security (VBS) enclaves, a hardware-independent option that does not require attestation. To retain secure-enclave capabilities, move databases from DC-series compute to a supported standard-series, non-DC tier and update affected applications for VBS enclave mode. What is changing? Intel SGX enclaves are tied to DC-series compute. After October 31, 2027, databases on these tiers must move to supported compute to retain enclave-enabled capabilities. Applications configured for Intel SGX enclaves may also need driver and connection-string updates. For workloads that do not require isolation from the host operating system, VBS enclaves offer a straightforward migration within Azure SQL Database. If your threat model requires Intel SGX-equivalent host isolation, evaluate SQL Server on Azure Confidential VMs instead. Choose the right migration path Use the migration guide to identify databases and elastic pools on DC-series compute, choose the target architecture that matches your threat model, update application connectivity and attestation settings, and validate the workload before production cutover. Move to VBS enclaves in Azure SQL Database Choose VBS enclaves when you need to protect sensitive data from unauthorized users or malicious insiders but do not require isolation from the host operating system. VBS enclaves run on supported non-DC compute tiers and eliminate attestation requirements. Consider SQL Server on Azure Confidential VMs If your threat model requires stronger isolation from the host operating system, assess SQL Server on Azure Confidential VMs. Compare architecture, operations, compatibility, and cost with the Azure SQL Database option. Start planning early Start now. Discovery, compute-tier changes, application updates, security review, and production validation all take time. Complete the migration before October 31, 2027, to keep enclave-enabled workloads running without interruption. Help and support Have questions? Ask community experts in Microsoft Q&A. If you have an Azure support plan and need technical help, create a support request. Review service retirements that may affect your resources in the Azure Retirement Workbook. For more ways to find impacted resources, see the retirement guidance. Retirement information may take up to two weeks to appear.198Views1like1CommentDatabase Hub in Fabric: Now in Public Preview -Turn Database Signals into Guided Action
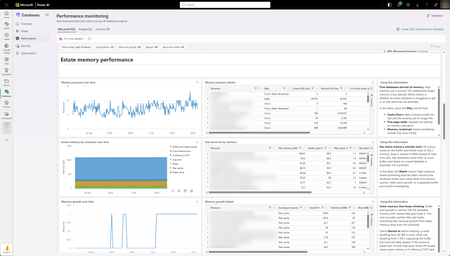
As applications grow, so does the database estate behind them. What starts with a handful of databases can become hundreds or thousands of resources spread across services, subscriptions, and environments. For the teams responsible for keeping them healthy, the challenge is no longer just collecting signals. It is knowing what needs attention, why it matters, and what to do next. Now in public preview, Database Hub in Microsoft Fabric brings inventory, health, performance, security, and optimization insights into one connected experience. It helps administrators and developers see the bigger picture, identify affected resources, and move from estate-wide visibility to focused investigation, without losing the context that brought them there. The preview brings together supported resources across Azure SQL Database, SQL Server enabled by Azure Arc, Azure Database for PostgreSQL, Azure Cosmos DB, and SQL database in Fabric. Available capabilities and signals vary by service and preview configuration. Database Hub Overview brings together estate-wide findings and cross-engine performance trends to help you prioritize what needs attention. Start with what needs your attention When you manage a large database estate, another dashboard is only useful if it helps you decide where to spend your time. The Overview page provides that starting point, bringing together findings across security, performance, and optimization. It distinguishes Issues, which require timely attention, from Suggestions, which highlight opportunities to improve your estate over time. You might begin with a security configuration that needs review or a performance signal that warrants investigation. Selecting a finding opens Estate with the relevant filters already applied, so you can see the affected resources rather than search for them again. The result is a more direct path from “something needs attention” to “these are the resources I should investigate.” Overview highlights issues across Security, Performance, and Optimization, with affected-resource counts and direct links to investigate further. Bring your estate into one view, and make it relevant to you The Estate experience brings supported resources into a unified inventory, scoped to your existing permissions. Search and filters help you narrow that inventory to the service, subscription, or resource group you manage. This is especially useful when your responsibilities span database engines. You can begin with a broader view, then focus on Azure SQL databases, Arc-enabled SQL Server resources, or Azure Database for PostgreSQL flexible servers without rebuilding the resource list in separate portals. Each resource brings its associated Issues and Suggestions into context. Open a finding to review the affected resource, supporting information, and recommended next step. The inventory also respects the resource model of each service. For example, the PostgreSQL view represents flexible server instances, rather than every database hosted within them. A unified view does not mean moving your databases. Your Azure resources remain in their existing subscriptions, and on-premises SQL Server instances remain on-premises, connected through Azure Arc. Database Hub brings operational context together; it does not require relocating or mirroring your application data into Fabric. Estate brings resource inventory, Issues, and Suggestions into one view, with quick actions to continue investigation in the Azure portal, VS Code, or SSMS. Understand security posture and performance in context Database Hub helps you identify configurations worth reviewing and resources that need a closer look. For security, supported signals can include Microsoft Entra authentication, customer-managed keys, and auditing coverage, depending on the database service. These findings provide a starting point for investigation, not a blanket judgment that every flagged resource is insecure or noncompliant. For example, a suggestion to review customer-managed keys should be evaluated against your organization’s requirements. A resource using service-managed keys is still encrypted at rest. For performance, built-in dashboards bring supported utilization and activity signals into view, including CPU, memory, storage, I/O, and connections. Review trends across your estate, then narrow the scope and time range to investigate individual resources. Metric availability varies by engine and monitoring configuration; missing data should not be interpreted as good health. For supported SQL monitoring scenarios, you can also create a custom monitoring dashboard from a template and tailor its charts and layout to the resources your team follows regularly. Together, these experiences help answer two practical questions: Where is pressure building, and where is there an opportunity to improve? Performance summaries highlight recent capacity signals and trends across Microsoft SQL, PostgreSQL, and Cosmos DB. The Security dashboard summarizes Microsoft Entra authentication, audit logging, and customer-managed key coverage, helping you identify configurations that warrant review across your estate. The Performance monitoring dashboard combines memory-pressure trends, resource-level details, and interpretation guidance to help focus your investigation. Move from a finding to an informed next step Estate-wide visibility is the beginning of an investigation, not a replacement for database expertise. When a finding needs deeper analysis, Database Hub helps you review the evidence and continue in the appropriate native experience, such as the Azure portal or SQL Server Management Studio (SSMS). Engine-specific diagnostics and configuration changes remain in the tools designed for that work. Consider a performance issue that occurred before an administrator could inspect it. In supported agent-assisted scenarios, captured incident evidence can help establish what happened, when it happened, and which queries or sessions were involved. That context gives the administrator a more informed starting point for investigation. The operator remains in control: review the evidence, evaluate the recommendation, and apply authorized changes through the appropriate service tools. The preview investigation workflow does not automatically remediate issues, and existing permissions and approval requirements continue to apply. Bring database expertise into agent-assisted workflows We are also making database operational intelligence available through agent skills: reusable capabilities that agents can call to support observability, monitoring, diagnostics, optimization, and other database operations. Database Hub provides estate context; skills provide a way to bring database expertise into an agent-assisted investigation. This creates a foundation for helping teams move from identifying an affected resource to understanding its signals and evaluating the next step. We’re building toward making this expertise available in the AI companions and development tools teams already use, with recommendations grounded in evidence, the specific database, and your organization’s operational controls. If we take a step back, our broader vision brings together a free, extensible Database Hub experience, agentic observability, and OneLake integration, all within Microsoft Fabric. It’s a foundation for connecting database operations with analytics and AI and helping teams turn signals into informed action. Get started with Database Hub Start with the Database Hub documentation to review preview availability, supported services, and setup requirements. Ask your Fabric administrator to enable the preview where required, confirm that you have the appropriate resource permissions, and complete any service-specific monitoring prerequisites. Then open Microsoft Fabric, select Databases in the left navigation, and begin with Overview. Choose a finding, explore the affected resources in Estate, and follow the evidence into your next investigation. For more details on supported services and getting set up, the Database Hub documentation is also available on Microsoft Learn. Learn more What is Database Hub in Fabric? Enable performance monitoring for Microsoft SQL Performance Monitoring for Azure SQL in Database Hub753Views5likes1CommentMI link support for multiple databases in an Always On availability group for SQL Server (Preview)
A simpler way to extend availability groups to Azure We are pleased to announce the preview of multi-database mode for Managed Instance link. The new mode lets you replicate multiple databases from an existing Always On availability group through a single link between SQL Server and Azure SQL Managed Instance. Managed Instance link uses distributed availability group technology to provide near-real-time replication between SQL Server and Azure SQL Managed Instance. It supports hybrid architectures, online migration, disaster recovery, and read-only workload offload. The link can be configured and managed through SQL Server Management Studio (SSMS), PowerShell, Azure CLI, and Azure APIs. Previously, each link supported one database. Customers with multi-database availability groups therefore had to split databases into separate availability groups and create a link for each database. Multi-database mode removes that limitation for supported SQL Server versions and editions, while the existing single-database mode remains available for earlier versions and other supported configurations. What you can do with multi-database link mode Migrate multiple databases to Azure SQL Managed Instance with minimal cutover downtime. Offload read-only workloads, including reporting and analytics, to the secondary replica. Use Azure SQL Managed Instance as a disaster recovery target for supported SQL Server versions. Start replication in either direction when the SQL Server version and Azure SQL Managed Instance update policy support that direction. Reverse primary and secondary roles through a planned failover. Build hybrid and multicloud topologies that place database groups where they are most useful. One link for an existing multi-database availability group If you already use an Always On availability group, multi-database link mode lets you extend the complete database group to Azure SQL Managed Instance without creating a separate availability group for every database. All databases in the link move together as one managed group. Databases on the primary are read-write, while their copies on the secondary are read-only. Use of your existing Always On AG listener endpoint is supported with multi-database mode MI link, allowing the link to remain operational after a local AG failover. Image 1: A multi-database Always On availability group replicated to Azure SQL Managed Instance through one Managed Instance link. The diagram illustrates the availability group relationship rather than a specific Azure SQL Managed Instance service-tier replica count. Managed Instance link is supported across all Azure SQL Managed Instance service tiers. Run multiple links in different directions A single SQL Server instance can participate in multiple links. Each link can carry a different availability group, and supported links can replicate in different directions at the same time. In the following example, AG1 (containing DB1, DB2, and DB3) replicates from SQL Server to Azure SQL Managed Instance through MI link 1. AG2 (containing DB4, DB5, and DB6) replicates from Azure SQL Managed Instance to SQL Server through MI link 2. Both links can operate at the same time between the two instances. Image 2: Two multi-database availability groups using separate links with opposite replication directions. Important: Database names must be unique in this configuration. A database cannot be renamed on the secondary while it is participating in replication to resolve a naming conflict. Replicate one availability group to multiple managed instances Multi-database mode also supports fan-out topologies. You can replicate multiple availability groups to one managed instance, or replicate the same availability group to different managed instances. For example, separate links can target managed instances in different Azure regions. Image 3: One multi-database availability group replicated through separate links to two Azure SQL managed instances. Preview requirements Requirement Details SQL Server SQL Server 2022 with CU27 or SQL Server 2025 with CU9 and above. Edition Enterprise or Developer edition. Standard edition supports basic availability groups with one database and is not supported for multi-database mode. Azure SQL Managed Instance Use a compatible update policy (2022 or 2025) matching your SQL Server version. SSMS SSMS 22.10.2 or later for the multi-database link capability. Automation Az module 16.3.0 or later and Az.Sql 7.1.0 or later, or the corresponding Azure APIs. Get started To evaluate multi-database mode during preview: Confirm that the SQL Server version, edition, servicing level, and Azure SQL Managed Instance update policy meet the preview requirements. Upgrade to SSMS 22.10.2 or later, or use a supported automation interface. Enable multi-database mode before creating a multi-database link. Create the link from the existing Always On availability group and validate synchronization for every database. Review the Azure documentation for multi-database Managed Instance link configuration, limitations, monitoring, failover, and cleanup guidance. Share your feedback We would love to hear about your experience with multi-database mode. Please share questions, feedback, and feature suggestions through the Managed Instance link feedback form.367Views0likes0CommentsSQLCon is Back: 5 Reasons to Attend the European Microsoft Fabric + SQL Community Conference
5 Reasons to Attend the European Microsoft Fabric + SQL Community Conference This year the SQL community joins Fabric in Europe for the first time at the Microsoft Fabric + SQL Community Conference happening September 28th - October 1st in Barcelona, Spain. Hear the latest announcements and roadmap directly from Microsoft leaders. With a full week of deep technical sessions and workshops covering the topics you care about most across and see how we’re helping solve your most pressing data challenges, from strengthening data sovereignty to powering agentic AI and unlocking trusted, actionable intelligence. And while there’s no shortage of topics, here are a couple of things we’re the most excited about heading to Barcelona: Unify your data (conference) experience With one registration, this event doubles your opportunity to sharpen your skillset with 130+ expert led sessions, workshops, and keynotes coming together in one high- impact week. Mix and match sessions to best meet your learning goals while you move seamlessly across tracks, visit the shared expo, and connect with peers in the community hub, all under one roof. The ultimate SQL experience, like only Microsoft can deliver With more than 25 dedicated SQL sessions, whether you’re a DBA or, a developer building AI apps, you can create your custom agenda with the topics you care about most. Pre-day programming is for the builders; bring your laptop and start your week with any of our full- day SQL workshops for the demos, practical guidance, and repeatable patterns you can start using immediately. Tuesday kicks off the official event with our opening keynote, three corenotes, and general sessions focused on SQL Server 2025, Azure SQL, and SQL in Fabric. Learn the latest in performance, tuning and tools like SSMS and VS Code delivered directly from SQL experts, MVPs, and community leaders. Ready to start building your agenda? Try our new session planner to curate your schedule based on your interests. The backdrop: Barcelona This year’s conference takes place in the historic, vibrant city of Barcelona, set along the Mediterranean Sea, the ideal setting for the first European SQLCon. When you’re ready for a break, you’re only a 15-minute ride away from the city center, perfect for exploring Gaudí’s iconic architecture or enjoying some local bites. Don’t miss the wrap- up celebration taking place in Barcelona’s exclusive Sutton Club. Community Connection SQLCon is more than just sessions; we’re bringing together more than 4,000 of the most dedicated Microsoft community members together for a week of endless connection opportunities. The Community Hub will bring some of our most popular experiences to life, from in-person meetups and user group connections to hands-on learning and certification opportunities all designed to help you grow your skills and expand your network. Launching Soon: SQLCon TV Enjoyed catching all the behind-the-scenes action on FabCon TV? In Barcelona we’ll bring SQLCon TV to the stage, with the content, demos, and interviews every SQL fan will want to see. Save your spot today. The earlier you register, the more opportunities you have to take advantage of early pricing specials. See you in Barcelona!416Views0likes2Comments
Public Preview: Performance monitoring for Azure SQL in Database Hub
We're excited to announce the public preview of performance monitoring for Azure SQL in Database Hub in Fabric. Performance monitoring brings the health and performance of your SQL estate into Database Hub. You see every supported database in one place and quickly spot the ones that need attention. It works across: Azure SQL Database Azure SQL Managed Instance (coming soon) SQL Server on Azure Virtual Machines SQL Server enabled by Azure Arc Microsoft collects performance-related telemetry, runs the pipeline, and stores the data for you. There's nothing you need to deploy and nothing to operate. Turn it on, and your SQL resources show up on the Performance page in Database Hub, which is free. This post is a deep dive on the performance part of Database Hub. For the full tour, including the Overview, Estate, and Security pages, read Database Hub in Fabric: Now in Public Preview. Get started in three steps Open Database Hub in Fabric. During the preview, a Fabric administrator needs to turn on the Database Hub tenant setting. See the prerequisites. Turn on performance monitoring for your SQL resources. See Enable performance monitoring for Microsoft SQL. Go to the Performance page to see which databases need your attention. See your entire database estate in Database Hub Performance monitoring powers the Performance page in Database Hub. Database Hub is built for when you need to look across all your databases, not just one at a time. It brings your database estate across Azure, on-premises, and other clouds into one place, including: Azure SQL and SQL Server enabled by Azure Arc Azure Database for PostgreSQL Azure Cosmos DB The Performance page comes with prebuilt dashboards, so you can see performance at a glance without building anything yourself. The dashboards are designed to quickly answer two questions: Are my databases healthy? Which ones need my attention? From there, you can drill into resource usage, waits, and session activity to understand what's driving a change in performance. With Database Hub, you can: Get estate-wide visibility into health and performance across database types Investigate the root cause of performance issues across many databases Use AI-assisted analysis to find and explain issues faster To learn more, see What is Database Hub in Fabric? Why we built this Monitoring SQL performance at scale often meant building and running your own monitoring stack. Before you could effectively answer, "Which of my databases need attention right now?" you typically had to: Deploy and configure a collection resource, such as a watcher or an agent Build a telemetry pipeline to move the data Provision a data store, and then pay for it, secure it, and keep it running Build dashboards on top of all of it Repeat for every new server, database, or region That's a lot of work before you see your first chart. And every step is another thing that can break, drift, or quietly stop collecting data. Customers are also turning to AI to make sense of their database estate. They want an AI agent that can spot a performance problem, explain what's causing it, and recommend a fix. But an AI agent is only as good as the data it can reach. It operates best with one consistent source of performance data across every database, not a patchwork of tools and data stores. We heard this feedback loud and clear from customers. You told us you love having at-scale dashboards and ownership of your performance data. You also told us that setting up a telemetry stack was time-consuming, scale limits got in the way, and running the data store added operational burden and cost overhead. One customer put it simply: they wanted to spend less time managing their telemetry infrastructure and more time managing and improving their databases. Performance monitoring keeps the parts you valued and removes the infrastructure you had to manage. That's why it feeds Database Hub directly. You get one place to see your whole estate, and your AI agents get one consistent source of performance data. No infrastructure to manage (or pay for) With performance monitoring, there's no monitoring infrastructure for you to deploy, size, or run. It's all managed by Microsoft, with no scale limits on how many targets you can monitor. Telemetry is collected close to the database engine and sent to a Microsoft-managed telemetry pipeline and data store. Access to that data is governed by Azure role-based access control (RBAC), so people only see telemetry for the resources they already have access to. Consistent telemetry across your SQL estate Performance monitoring collects the same core set of performance data across every supported SQL deployment, whether it runs in Azure, on-premises, or in another cloud. That means one mental model and one set of dashboards in Database Hub, instead of a different tool for every flavor of SQL. The preview collects performance-related telemetry, including: CPU and memory utilization Wait statistics Active sessions Storage I/O and database storage utilization Performance counters Client connections Database properties Availability group, replica, and database replica health Go beyond Database Hub with KQL Database Hub covers the most common performance questions. When you need a view that Database Hub doesn't show, you can query the same telemetry directly with Kusto Query Language (KQL). The telemetry is available through a Microsoft-managed, RBAC-governed endpoint, so you don't need to create or pay for your own Azure Data Explorer cluster. Use it to: Build your own Real-Time Dashboards and reports Connect tools you already use, such as Grafana or Power BI Give an AI agent access to investigate performance across your estate To get started, see Query performance monitoring telemetry. It includes the schema, connection steps, and ready-to-run starter queries. Turn on performance monitoring How you turn on performance monitoring depends on the resource type. For all of the steps in one place, see Enable performance monitoring for Microsoft SQL. Resource type How monitoring is enabled in preview Step-by-step guidance Azure SQL Database Add an extended property to each database you want to monitor. You can also select Enable Performance Monitoring in Database Hub. Azure SQL Database Azure SQL Managed Instance (coming soon) Coming soon Coming soon SQL Server on Azure VMs Turn on a feature flag in the SQL IaaS Agent extension. SQL Server on Azure VMs SQL Server enabled by Azure Arc On by default once the server is connected to Azure Arc. SQL Server enabled by Azure Arc To view performance monitoring data, you need: The Reader role, or a role with higher privileges, on each subscription that contains the resources you want to view. The Microsoft.AzureArcData resource provider registered on each subscription. For steps, see Register the Azure resource provider. Availability Performance monitoring is available in public preview in select Azure regions. For the current list of supported regions, see Regional availability and data handling. Learn more Database Hub in Fabric: Now in Public Preview What is Database Hub in Fabric? Enable performance monitoring for Microsoft SQL Query performance monitoring telemetry Supplemental Terms of Use for Microsoft Azure Previews1.8KViews2likes5Comments