azure sql
749 Topics
Make Estate yours: Focus on the databases and issues you own in Database Hub
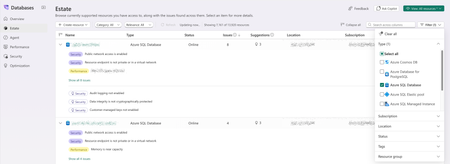
Database Hub in Microsoft Fabric is now in public preview. Estate experience brings every supported database you can access into one inventory, with the issues and suggestions found across them. In a large organization, that can mean thousands of resources. But most people own only part of the estate: a set of production databases, a few subscriptions, one resource group. This post shows how to shape Estate around your part, save it as a custom view, and use it to triage and bring in help. The examples use Azure SQL Database; the same steps work for PostgreSQL and Azure Cosmos DB. Which resources are mine? While in Estate view select Filter to narrow the list by Type, Subscription, Location, Status, Tags, or Resource group. The grid and the resource count update as you select values; Filter (1) shows how many dimensions are active, and Clear all resets them. Looking for one resource? Search across columns matches names, locations, subscriptions, and more. Which issues should I focus on? Each row shows its Issues and Suggestions counts and opens expanded, so findings are readable at a glance: issues with a filled Security or Performance tag, suggestions marked with a lightbulb. Open Category and select Security, Performance, Optimization, or a combination. Use Relevance to keep only resources with Issues or Suggestions. The grid is sorted by issue count, so the resources that need the most attention come first. How do I get back here tomorrow? Once Estate shows what you want, save it. An asterisk after the view name (View: All resources *) means your filters have unsaved changes. Select View > Save. Choose Save as new custom view and give it a name that describes the scope, such as sqlDB-sec-perf-issues. Select Apply. The view now appears under Custom views in the View menu. It saves filters, not results, so you always see the current state of those resources. What's wrong, and what should I do about it? Select an issue to open its detail page. Here, the top database reports Public network access is enabled. The Summary explains why it matters: public reachability increases exposure to credential attacks, scanning, and firewall mistakes. The Recommended action gives the fix and its precondition: Disable public network access after confirming that all clients can connect through approved private connectivity. Resolve in Azure portal opens the resource. Database Hub doesn't change the resource for you; you make the change in the tool that owns it, under your existing permissions. Back returns you to Estate with your view intact. Who can help me fix it? That precondition is often the hard part: confirming every client can connect privately may take your networking or application team. Bring them into the same view. Select View > Share, then Copy link. The link carries your current filters, so a colleague starts from the same scope. Each person still sees only the resources they already have access to; sharing never grants access. Need the list for a change ticket? Select Export view (as .csv). CSV files don't carry sensitivity labels, so handle the file according to your organization's data policies. What needs attention in my part of the estate? Your view isn't limited to Estate. Open Overview, select the same view from the View menu, and every card and chart rescopes to it: the Estate issues summary, the Security, Performance, and Optimization cards with their top issues, and the performance trends. Overview now summarizes your backlog instead of the whole estate. Views are managed in Estate; Manage views (Estate) takes you there. o the resources you own. More in Estate Look up a resource without leaving the list Select a resource name to open its details next to the list: subscription, resource group, and logical server (each linking to the Azure portal), status, location, pricing tier, max storage, and tags. Connection strings for ADO.NET, JDBC, ODBC, PHP, and Go use Microsoft Entra authentication, and Open in Azure portal, Open in VS Code, and Open in SSMS are at the top. The … menu on each row adds quick actions Copy connection string, Open in editor, Enable performance monitoring, Create monitor from template and Set alert from template. Create a database where you work Create resource starts a new database from Estate, grouped by engine: SQL database in Fabric, Azure SQL Database, SQL Server instance, Azure Database for PostgreSQL, and Azure Cosmos DB for NoSQL. Get started Open Estate, filter to the resources you own, focus on the categories you triage, and save the result as a view. Then select it on Overview and start with what needs attention. Database Hub is in public preview; capabilities vary by service and preview configuration. See the Database Hub documentation for supported services and setup, and use Feedback in Database Hub to tell us what you'd like next.94Views0likes0Comments
Free SQL Managed Instance offer is now generally available
We are thrilled to announce the General Availability of the free offer for Azure SQL Managed Instance – making it easier than ever to explore the power of a fully managed, cloud-native SQL Server experience. With the GA release, you can now utilize a General Purpose or Next-Gen General Purpose (preview) Azure SQL Managed Instance at no cost for up to 12 months. With support for up to 500 databases, you can: Build applications with functionalities such as cross-database queries, Evaluate strategies to migrate your SQL Server applications to Azure, Explore some of the state-of-the-art PaaS capabilities like automated backups, availability, and more [1] . What’s included in the free offer The free SQL Managed Instance Offer includes: One General Purpose or Next-Gen General Purpose (preview) SQL managed instance per subscription. 720 vCore hours every month (renews every month, unused credits are lost). 64 GB of data storage. SQL license for the instance. Automatically backed up databases retained for up to 7 days. Default workday start/stop schedule from 9-5 to ensure frugal utilization of your free credits. Creation of up to 500 databases [1] The instance is automatically stopped when you reach the monthly vCore limit. If the start/stop schedule is set on the instance the next scheduled start succeeds when credits are available gain. Review vCore hours spending You can review your current available free credit on the Overview page of the Azure SQL Managed Instance in the Azure Portal. Simply open your free SQL managed instance resource page and observe the remaining credits, as illustrated in the following image: Upgrade If you want to upgrade your free SQL managed instance to production-ready instance with SLA, navigate to the Compute + Storage pane for you free instance, choose the Paid offer and click apply to save your changes. Disclaimer: These costs are estimates only. Actual charges may vary depending on region and configuration. Get started Have you already tried the free Azure SQL Managed Instance? If yes, feel free to share your feedback with the product team – aka.ms/sqlmi-free-feedback. If you still haven’t, follow these simple steps to get started in less than 5 minutes: Create Azure SQL Managed Instance Apply Free Offer – look for the “Want to try SQL MI for free?” banner and select “Apply” Select an existing resource group, or create a new one. Select “Review and create” to finish creating the instance. You’re now ready to explore the capabilities of Azure SQL Managed Instance! 😊 Don't miss out on this fantastic opportunity to experience Azure SQL Managed Instance for free! Learn more about the offer and get started today – aka.ms/freesqlmi [1] – Limitations might apply. Learn more about free offer limits.3.6KViews3likes4CommentsManaged Instance link with failover groups (limited preview)
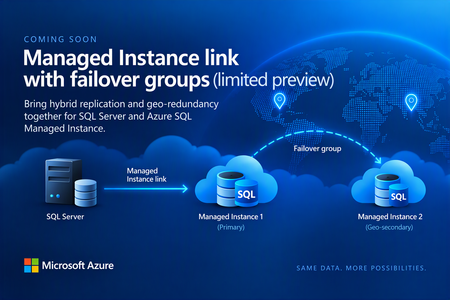
Before we kick off the preview, we’d like to hear from customers interested in trying it. The new capability will let you replicate data from SQL Server to a managed instance that’s part of a failover group, combining hybrid replication with geo-redundancy in Azure. The preview isn’t starting just yet. We expect to begin onboarding customers in the coming weeks, and capacity will be very limited. If this is something you’d like to try, let us know by filling out the sign-up form. Register your interest in the upcoming limited preview: https://aka.ms/milink-fog-signup What are the Managed Instance link and failover groups? The Managed Instance link enables near real-time data replication between SQL Server and Azure SQL Managed Instance. Built on distributed availability groups, it replicates user databases in near real time from SQL Server hosted anywhere to Azure SQL Managed Instance, or from Azure SQL Managed Instance to SQL Server 2022 or later. Customers use the Managed Instance link for: Offloading read-only workloads to Azure, or from Azure back to on-premises. Online migration from on-premises to Azure, or from Azure back to on-premises, with minimal downtime. Bidirectional disaster recovery between SQL Server and Azure. Failover groups, also known as geo-replication, manage the replication and failover of user databases from one managed instance to another managed instance in a different Azure region. They provide read-write and read-only listener endpoints that remain unchanged after a geo-failover, so applications don’t need connection-string changes. The geo-secondary can also take on read-only workloads. Until now, you couldn’t combine the two scenarios. Establishing a two-hop replication path from SQL Server to Managed Instance 1 and then to Managed Instance 2 presents a technical challenge and isn’t supported today. As a result, you’ve had to choose between using the MI link with a single managed instance or using failover groups without the MI link. The capability we’re getting ready to preview removes that trade-off. SQL Server replicates to MI-1 through the Managed Instance link, while the failover group keeps MI-2 in sync in a second Azure region, as shown in the figure below. Figure 1: SQL Server replicating to a primary managed instance through the Managed Instance link, with the failover group geo-replicating to a secondary managed instance in another region. Replication in both directions In this configuration, the link works bidirectionally. You can replicate from SQL Server to Azure and back from Azure to SQL Server. In practice, that means you can fail over to Azure and, when you’re ready, fail back to SQL Server. Version requirements follow the existing MI link documentation. Two-way replication and failback require SQL Server 2022 or SQL Server 2025, with the managed instance on the matching SQL Server 2022 or SQL Server 2025 update policy. SQL Server 2016 through 2019 support only one-way replication to Azure. What this unlocks Hybrid disaster recovery with regional resilience in Azure: Keep SQL Server as your primary, protected by Managed Instance in one Azure region and a geo-secondary Managed Instance in another Azure region. Migration to Azure with minimal downtime: Land directly in a geo-redundant configuration without having to re-seed or re-architect after cutover. Reverse migration: Move from a geo-redundant Azure configuration back to on-premises SQL Server. Read scale-out: Offload read-only workloads to a geo-redundant Azure SQL Managed Instance configuration. Reverse data replication: Replicate data from a geo-redundant Managed Instance configuration back to on-premises SQL Server. Who should apply and how the limited preview works If you run SQL Server workloads that could benefit from both hybrid replication and geo redundancy on Azure SQL Managed Instance, we’d love to hear from you. A few things to know The limited preview hasn’t started yet. Right now, we’re collecting interest from customers who would like to participate. We expect onboarding to begin in the coming weeks. Capacity will be limited, and the product team will contact selected participants directly. The preview isn’t intended for production workloads unless agreed with the product team. We’ll be looking for feedback from participating customers to help us shape the capability as it evolves. Interested? Let us know If combining the Managed Instance link with failover groups could simplify your hybrid, disaster recovery, or migration architecture, register your interest today. We’re looking forward to hearing about your scenarios and working with some of you as we get the preview underway. Register your interest in the upcoming limited preview: https://aka.ms/milink-fog-signup Learn more • Overview of the Managed Instance link • Overview of Failover groups for Azure SQL Managed Instance101Views1like0CommentsStop defragmenting and start living: auto index compaction is now generally available
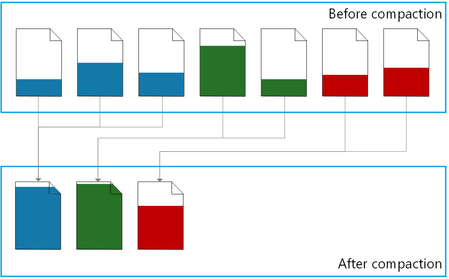
Executive summary Automatic index compaction is a built-in MSSQL database engine feature that compacts indexes in background and with minimal overhead. Now you can: Stop using scheduled index maintenance jobs. Reduce storage space consumption and save costs. Improve performance by reducing CPU, memory, and disk I/O consumption. Automatic index compaction is now generally available in Azure SQL Database, Azure SQL Managed Instance with the always-up-to-date update policy, and SQL database in Fabric. Index maintenance without maintenance jobs Enable automatic index compaction for a database with a single T-SQL command: ALTER DATABASE [database-name] SET AUTOMATIC_INDEX_COMPACTION = ON; Once enabled, you no longer need to set up, maintain, and monitor resource intensive index maintenance jobs, a time-consuming operational task for many DBA teams today. As the data in the database changes, a background process consolidates rows from partially filled data pages into a smaller number of filled up pages, and then removes the empty pages. Index bloat is eliminated – the same amount of data now uses a minimal amount of storage space. Resource consumption is reduced because the database engine needs fewer disk IOs and less CPU and memory to process the same amount of data. By design, the background compaction process acts on the recently modified pages only. This means that its own resource consumption is much lower compared to the traditional index maintenance operations (index rebuild and reorganize), which process all pages in an index or its partition. For a detailed description of how the feature works, a comparison between automatic index compaction and the traditional index maintenance operations, and the ways to monitor the compaction process, see automatic index compaction in documentation. Let the numbers speak As auto index compaction becomes generally available, it is already enabled in more than 6 million databases worldwide, most of them from Microsoft internal customers who helped validate the feature during preview. Hundreds of external customers also enabled auto compaction during preview and have been enjoying the benefits, with zero issues reported. Looking at our worldwide telemetry data for a 28-day window, automatic index compaction freed up approximately 14.3 petabytes of space in data files by consolidating 547.5 trillion rows on fewer pages, saving resources and improving query performance. Looking at the space freed up per database, the benefits range from a few megabytes per day for databases with already dense pages, to more than 500 gigabytes per day for databases that have gone through one-time extensive data modifications. Compaction in action To see the effects of automatic index compaction, we wrote a stored procedure that simulates a write-intensive OLTP workload. Each execution of the procedure inserts, updates, deletes, or selects a random number of rows, from 1 to 100, in a 50,000-row table with a clustered index. We executed this stored procedure using a popular SQLQueryStress tool, with 30 threads and 400 iterations on each thread. We measured the page density, the number pages in the leaf level of the table’s clustered index, and the number of logical reads (pages) used by a test query reading 1,000 rows, at three points in time: After initially inserting the data and before running the workload. Once the workload stopped running. Several minutes later, once the background process completed index compaction. Here are the results: Before workload After workload After compaction Logical reads 25 🟢 1,610 🔴⬆️ 35 🟢⬇️ Page density 99.51% 🟢 52.71% 🔴⬇️ 96.11% 🟢⬆️ Pages 962 🟢 4,394 🔴⬆️ 1,065 🟢⬇️ Before the workload starts, page density is high because nearly all pages are full. The number of logical reads required by the test query is minimal, and so is its resource consumption. The workload leaves a lot of empty space on pages and increases the number of pages because of row updates and deletions, and because of page splits. As a result, immediately after workload completion, the number of logical reads required for the same test query increases more than 60 times, which translates into a higher CPU and memory usage. But then within a few minutes, automatic index compaction removes the empty space from the index, increasing page density back to nearly 100%, reducing logical reads by about 98% and getting the index very close to its initial compact state. Less logical reads means that the query is faster and uses less CPU. All of this without any user action. With continuous workloads, index compaction is continuous as well, maintaining higher average page density and reducing resource usage by the workload over time. The T-SQL code we used in this demo is available in the Appendix. Conclusion Automatic index compaction delegates a routine database maintenance operation to the database engine itself, letting administrators and engineers focus on more important work without worrying about index maintenance. Making this feature generally available doesn’t mean that we stop working on it. Your feedback during preview helped us find new opportunities to fine-tune the compaction process. We thank you for that feedback and look forward to announcing new improvements in auto index compaction in the future. Appendix Here is the T-SQL code we used to demonstrate automatic index compaction. The type of executed statements and the number of affected rows is randomized to better represent an OLTP workload. While the results demonstrate the effectiveness of automatic index compaction, exact measurements may vary from one execution to the next. /* Enable automatic index compaction */ ALTER DATABASE CURRENT SET AUTOMATIC_INDEX_COMPACTION = ON; /* Reset to the initial state */ DROP TABLE IF EXISTS dbo.t; DROP SEQUENCE IF EXISTS dbo.s_id; DROP PROCEDURE IF EXISTS dbo.churn; /* Create a sequence to generate clustered index keys */ CREATE SEQUENCE dbo.s_id AS int START WITH 1 INCREMENT BY 1; /* Create a test table */ CREATE TABLE dbo.t ( id int NOT NULL CONSTRAINT df_t_id DEFAULT (NEXT VALUE FOR dbo.s_id), dt datetime2 NOT NULL CONSTRAINT df_t_dt DEFAULT (SYSDATETIME()), u uniqueidentifier NOT NULL CONSTRAINT df_t_uid DEFAULT (NEWID()), s nvarchar(100) NOT NULL CONSTRAINT df_t_s DEFAULT (REPLICATE('c', 1 + 100 * RAND())), CONSTRAINT pk_t PRIMARY KEY (id) ); /* Insert 50,000 rows */ INSERT INTO dbo.t (s) SELECT REPLICATE('c', 50) AS s FROM GENERATE_SERIES(1, 50000); GO /* Create a stored procedure that simulates a write-intensive OLTP workload. */ CREATE OR ALTER PROCEDURE dbo.churn AS SET NOCOUNT, XACT_ABORT ON; DECLARE @r float = RAND(CAST(CAST(NEWID() AS varbinary(4)) AS int)); /* Get the type of statement to execute */ DECLARE @StatementType char(6) = CASE WHEN @r <= 0.15 THEN 'insert' WHEN @r <= 0.30 THEN 'delete' WHEN @r <= 0.65 THEN 'update' WHEN @r <= 1 THEN 'select' ELSE NULL END; /* Get the maximum key value for the clustered index */ DECLARE @MaxKey int = ( SELECT CAST(current_value AS int) FROM sys.sequences WHERE name = 's_id' AND SCHEMA_NAME(schema_id) = 'dbo' ); /* Get a random key value within the key range */ DECLARE @StartKey int = 1 + RAND() * @MaxKey; /* Get a random number of rows, between 1 and 100, to modify or read */ DECLARE @RowCount int = 1 + RAND() * 99; /* Execute a statement */ IF @StatementType = 'insert' INSERT INTO dbo.t (id) SELECT NEXT VALUE FOR dbo.s_id FROM GENERATE_SERIES(1, @RowCount); IF @StatementType = 'delete' DELETE TOP (@RowCount) dbo.t WHERE id >= @StartKey; IF @StatementType = 'update' UPDATE TOP (@RowCount) dbo.t SET dt = DEFAULT, u = DEFAULT, s = DEFAULT WHERE id >= @StartKey; IF @StatementType = 'select' SELECT TOP (@RowCount) id, dt, u, s FROM dbo.t WHERE id >= @StartKey; GO /* The remainder of this script is executed three times: 1. Before running the workload using SQLQueryStress. 2. Immediately after the workload stops running. 3. Once automatic index compaction completes several minutes later. */ /* Monitor page density and the number of pages and records in the leaf level of the clustered index. */ SELECT avg_page_space_used_in_percent AS page_density, page_count, record_count FROM sys.dm_db_index_physical_stats(DB_ID(), OBJECT_ID('dbo.t'), 1, 1, 'DETAILED') WHERE index_level = 0; /* Run a test query and measure its logical reads. */ DROP TABLE IF EXISTS #t; SET STATISTICS IO ON; SELECT TOP (1000) id, dt, u, s INTO #t FROM dbo.t WHERE id >= 10000 SET STATISTICS IO OFF;7.4KViews3likes7CommentsWhat Really Happens When You Scale Azure SQL Database? How to Monitor Long-Running Scale Operations
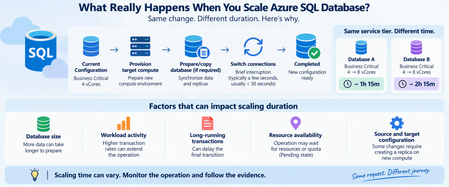
One of the advantages of Azure SQL Database is the ability to scale compute resources without managing the underlying infrastructure. Changing from 4 vCores to 8 vCores can be only a few clicks or a single command. But there is a question I frequently see when troubleshooting scaling operations: "Why is my Azure SQL Database scaling operation taking so long?" An even more interesting question appears when two databases undergo what looks like the same change: Database A Business Critical → Business Critical Scaling duration: ~1 hour 15 minutes Database B Business Critical → Business Critical Scaling duration: ~2 hours 15 minutes Same service tier. Similar scaling request. Very different completion time. At first glance, that might look unusual. However, a scale operation isn't simply Azure changing a configuration value from one number of vCores to another. Depending on the source and target configuration, Azure SQL Database can need to provision target compute, prepare or copy database data, transition connections to the target compute, and clean up the original environment. Microsoft specifically notes that creating a database replica on the new compute instance for some scaling combinations can strongly influence the overall latency. Let's look at what happens and, more importantly, how to monitor it. Scaling Is More Than Changing vCores When you submit a scaling request such as: Business Critical 4 vCores ↓ Business Critical 8 vCores it's tempting to imagine something like: CPU allocation: 4 → 8 Done. That isn't necessarily what happens. At a high level, Microsoft documents a scaling workflow involving two important stages: Create a new compute instance with the requested service tier and compute size Switch routing from the original compute instance to the new one For some combinations of service-tier and compute-size changes, Azure SQL Database must also create a replica on the new compute instance, involving data copying. A simplified view is: Scaling request ↓ Prepare target compute ↓ Prepare/copy database if required ↓ Bring target environment ready ↓ Switch connections ↓ Scaling complete The important takeaway is: A scale operation can involve moving database execution to a new compute environment, not simply increasing CPU on the existing environment. Why Can Two Similar Databases Take Different Amounts of Time? This is where troubleshooting becomes interesting. Imagine two databases: Database A 4 vCores → 8 vCores Completed in 75 minutes Database B 4 vCores → 8 vCores Completed in 135 minutes The natural question is: "If the source and destination configurations are the same, shouldn't the duration also be the same?" Not necessarily. The requested configuration tells us where the database needs to end up. It does not mean the work required to reach that state is identical. Several factors can affect the operation. 1. Database Size and Data Movement One of the most important factors can be the amount of data that must be prepared on the target compute. Microsoft's scaling documentation explicitly states that for some source/target combinations, a replica must be created on the new compute instance. That involves copying data and can significantly affect the overall scaling latency. Conceptually: Small database Provision ████ Data preparation ██████ Switch █ versus: Large database Provision ████ Data preparation ████████████████████████ Switch █ Database size alone doesn't provide a precise prediction of completion time, but it can influence the amount of work required during applicable scaling paths. 2. Workload Activity Matters A database also doesn't necessarily stop processing application traffic while Azure prepares the target environment. Microsoft states that during target compute creation, the database remains online and connections continue to the original compute instance. That creates an interesting challenge: Target environment preparing + Application still generating workload A highly active transactional database and a relatively idle database can therefore present different operational conditions during scaling. The practical lesson is: Two databases with the same service objective aren't necessarily in the same workload state when scaling begins. When investigating a slow scale operation, look at the activity around the scaling window, including: transaction volume; write activity; long-running transactions; workload peaks; batch operations; maintenance activity. 3. Long-Running Transactions Can Affect Switchover Toward the end of scaling, connections need to transition to the target compute instance. Microsoft documents that existing connections to the original compute are dropped and new connections are established to the target compute. The switch generally results in a short interruption, often only a few seconds and generally less than 30 seconds. However, there's an important exception. Microsoft notes that: If long-running transactions are active when connections are dropped, the switch can take longer because aborted transactions need to recover. Conceptually: Normal transition Target ready ↓ Switch ↓ Reconnect ↓ Done With a long-running transaction: Target ready ↓ Connection transition ↓ Transaction interruption ↓ Recovery work ↓ Reconnect ↓ Done This is one reason application workload should be considered when evaluating scaling duration. 4. Resource Availability Can Matter Another clue comes from Azure SQL's operation-status metadata. The sys.dm_operation_status DMV exposes several states for database operations, including: PENDING IN_PROGRESS COMPLETED FAILED CANCEL_IN_PROGRESS CANCELLED Importantly, Microsoft defines PENDING as an operation waiting for resource or quota availability. That means some of the elapsed time around an operation may occur before active processing progresses as expected. This is why comparing scale operations purely by database size or vCore count can be misleading. How Can I Monitor a Scaling Operation? Rather than repeatedly refreshing the Azure portal, there are several useful methods for inspecting progress. Method 1: Azure PowerShell with Get-AzSqlDatabaseActivity Azure PowerShell provides: Get-AzSqlDatabaseActivity Microsoft documents this cmdlet specifically for retrieving the status of operations against Azure SQL databases. For example: Get-AzSqlDatabaseActivity ` -ResourceGroupName "MyResourceGroup" ` -ServerName "myserver" ` -DatabaseName "mydatabase" This can help identify database operations associated with the selected database. For clearer output: Get-AzSqlDatabaseActivity ` -ResourceGroupName "MyResourceGroup" ` -ServerName "myserver" ` -DatabaseName "mydatabase" | Select-Object ` Operation, OperationId, DatabaseName, State, PercentComplete, StartTime, ErrorCode, ErrorMessage The specific fields returned can vary with module/API behavior, so always interpret them in the context of the operation being monitored. The important point is that you're no longer asking only: "Is scaling still happening?" You can inspect the operation itself. Method 2: Check Current and Requested Service Objectives Another useful PowerShell command is: Get-AzSqlDatabase Microsoft documents this cmdlet for retrieving Azure SQL Database properties. Its output includes service-objective information such as CurrentServiceObjectiveName and RequestedServiceObjectiveName. For example: Get-AzSqlDatabase ` -ResourceGroupName "MyResourceGroup" ` -ServerName "myserver" ` -DatabaseName "mydatabase" | Select-Object ` DatabaseName, Status, Edition, CurrentServiceObjectiveName, RequestedServiceObjectiveName During a change, comparing these fields can help establish the current and requested configuration. Think of it as: CurrentServiceObjectiveName ↓ Where am I now? RequestedServiceObjectiveName ↓ Where am I trying to go? Once the operation completes successfully, the current configuration should reflect the requested target. Method 3: Use sys.dm_operation_status For SQL-side monitoring, sys.dm_operation_status provides information about database operations such as CREATE and ALTER. For example: SELECT major_resource_id, operation, state_desc, percent_complete, start_time, last_modify_time, error_code, error_desc FROM sys.dm_operation_status ORDER BY start_time DESC; Useful columns include: operation state_desc percent_complete start_time last_modify_time error_code error_desc Microsoft defines the operation states as including PENDING, IN_PROGRESS, COMPLETED, and FAILED. Be Careful With PercentComplete This is an important detail. It is tempting to interpret: PercentComplete = 50 as: "Half of the work is finished, so half of the remaining time is left." That isn't necessarily correct. For sys.dm_operation_status, Microsoft documents percent_complete for most operations as: 0 = Operation not started 50 = Operation in progress 100 = Operation complete Restore operations are an important exception, where values between 1 and 99 can indicate more granular progress. So for a normal ALTER/scale operation: 50% should generally be interpreted as: The operation is in progress rather than: Exactly half the work remains. This distinction is very useful when communicating with application teams during long-running operations. A Practical Monitoring Script For PowerShell users, I like combining the configuration and operation views. First check the database: $db = Get-AzSqlDatabase ` -ResourceGroupName "MyResourceGroup" ` -ServerName "myserver" ` -DatabaseName "mydatabase" $db | Select-Object ` DatabaseName, Status, Edition, CurrentServiceObjectiveName, RequestedServiceObjectiveName Then check database operations: Get-AzSqlDatabaseActivity ` -ResourceGroupName "MyResourceGroup" ` -ServerName "myserver" ` -DatabaseName "mydatabase" This gives you two complementary perspectives: DATABASE STATE + OPERATION STATE ↓ Better understanding of scaling progress What About Application Availability During Scaling? One of the biggest concerns is: "Does the database remain available while scaling?" For Azure SQL Database, Microsoft states that the database remains online while the new compute environment is being prepared. Connections continue to the original compute during that stage. The important availability event occurs during the transition. At switchover: Existing connections ↓ Dropped ↓ Routing switches ↓ New connections ↓ Target compute Microsoft says the switch generally causes an interruption of less than 30 seconds and often only a few seconds. Applications should therefore implement appropriate transient-error handling and retry logic. Microsoft explicitly recommends retry logic for applications and components using the database while the service tier is being changed. Don't Immediately Cancel a "Slow" Scaling Operation A scale operation taking longer than expected does not automatically mean: Scaling is stuck. It could still be legitimately working through: Resource availability ↓ Target compute preparation ↓ Data/replica preparation ↓ Synchronization / workload handling ↓ Switchover Before assuming failure, gather evidence. Check: Operation state Current service objective Requested service objective Start time Last modification time Error details Workload activity Long-running transactions Then determine whether the operation is: Pending Actively progressing Completed or: Failed Troubleshooting Two Databases With Different Scaling Durations Suppose you're investigating: Database A Scale duration: 1h15 Database B Scale duration: 2h15 Here is the approach I recommend. 1. Verify that the changes truly match Compare: Source service tier Target service tier Source vCores Target vCores Compute tier Storage configuration Do not assume both operations were identical simply because both ended at, for example, Business Critical 8 vCores. 2. Compare database characteristics Look at: Database size Workload level Write activity Transaction volume Long-running transactions 3. Compare operation timing Retrieve: Start time State Last modification time Completion time sys.dm_operation_status exposes this operation metadata for Azure SQL database operations. 4. Determine whether either operation spent time pending Remember: PENDING can mean the operation is waiting for resource or quota availability. That represents a very different explanation from: "The database took longer to copy." 5. Check workload around the transition Look for: Large transactions Bulk writes ETL operations Maintenance High transaction rates Long-running transactions particularly around the switchover period. Scaling Duration Is Not an SLA Stopwatch This leads to perhaps the most important takeaway. If: Database A took 75 minutes you should not assume: Database B must take approximately 75 minutes. Even apparently similar scale operations can encounter different database and platform conditions. A better operational expectation is: Treat each scaling operation as an asynchronous platform operation whose duration depends on the work required to safely reach the requested configuration. Monitor the operation rather than predicting its completion from a previous database. Recommended Checklist Before scaling a production Azure SQL Database: Before Review workload activity. Identify long-running transactions or batch processes. Confirm the requested service objective. Ensure application retry logic is implemented. Record the UTC start time. Understand dependent application connection behavior. During Monitor: Get-AzSqlDatabaseActivity Get-AzSqlDatabase sys.dm_operation_status and watch: State CurrentServiceObjectiveName RequestedServiceObjectiveName StartTime LastModifyTime Error information After Confirm: Current service objective = requested target Database status = Online Application connectivity = Healthy Workload performance = Expected Also validate that applications successfully reconnected after the transition. Final Thoughts When Azure SQL Database scaling takes longer than expected, it's easy to think: "Something must be wrong." And when two similar databases take very different amounts of time, it's equally tempting to expect the durations to match. But a scale operation can involve substantially more than changing a vCore number. At a high level: Request scaling ↓ Provision target compute ↓ Prepare/copy database when required ↓ Transition connections ↓ Complete Microsoft's documentation confirms that data copying for applicable scale paths can strongly influence latency, that the switchover can take longer in the presence of long-running transactions, and that a pending operation might be waiting for resource or quota availability. So when someone asks: "Why is Azure SQL scaling taking so long?" my recommendation is not to start by guessing how many minutes it should take. Instead ask: "What state is the operation currently in, and what evidence do we have about its progress?" With Get-AzSqlDatabaseActivity, Get-AzSqlDatabase, and sys.dm_operation_status, you can turn an opaque waiting period into a much more structured investigation. References Scale single database resources in Azure SQL Database Scale resources in Azure SQL Database sys.dm_operation_status Get-AzSqlDatabaseActivity Get-AzSqlDatabase129Views0likes0CommentsAzure SQL Performance Troubleshooting: When High Latency Is Not High CPU
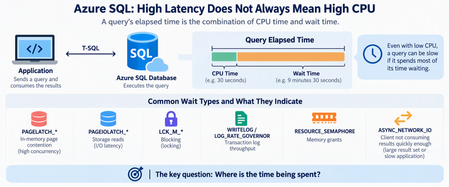
When an application connected to Azure SQL Database becomes slow or starts timing out, one of the first questions is usually: Is the database running out of CPU? It's a reasonable starting point, but CPU is only one part of the performance story. Some Azure SQL performance problems occur while CPU, Data IO, and worker utilization appear healthy. The database may have plenty of compute capacity while queries spend most of their time waiting rather than executing. The key troubleshooting question is therefore not simply: "How much CPU is Azure SQL using?" Instead, ask: "Where is the elapsed time being spent?" Start With Resources, But Don't Stop There Resource utilization should still be the first checkpoint. A simple query using sys.dm_db_resource_stats can help identify whether Azure SQL is approaching CPU, Data IO, Log IO, memory, or worker limits: SELECT DB_NAME() AS database_name, AVG(avg_cpu_percent) AS avg_cpu_percent, MAX(avg_cpu_percent) AS max_cpu_percent, MAX(avg_data_io_percent) AS max_data_io_percent, MAX(avg_log_write_percent) AS max_log_write_percent, MAX(avg_memory_usage_percent) AS max_memory_percent, MAX(max_worker_percent) AS max_worker_percent FROM sys.dm_db_resource_stats; If CPU is consistently near 100%, investigate CPU consumption. If Log IO reaches its limit, investigate transaction-log generation. If workers are exhausted, investigate concurrency. But if none of these resources is saturated, don't conclude that Azure SQL is healthy. Move to wait analysis. Follow the Waits A useful simplified model is: Query elapsed time = CPU execution If a query runs for 10 minutes but uses only 30 seconds of CPU, most of its elapsed time occurred somewhere else. Common wait patterns can point the investigation in different directions: Wait Area to investigate PAGELATCH_* In-memory page contention PAGEIOLATCH_* Storage reads LCK_M_* Blocking WRITELOG Transaction log LOG_RATE_GOVERNOR Log throughput RESOURCE_SEMAPHORE Memory grants ASYNC_NETWORK_IO Client/result consumption The wait type is not automatically the root cause. Think of it as a sign telling you: Look in this direction next. PAGELATCH Does Not Mean Slow Storage One important distinction is: PAGELATCH versus: PAGEIOLATCH Despite their similar names, they represent different problems. PAGEIOLATCH is associated with waiting for data pages involved in physical I/O. PAGELATCH, however, is synchronization around pages that are already in memory. Consider a highly concurrent workload: Hundreds of sessions ↓ Same memory page ↓ Latch contention ↓ Sessions wait ↓ Application CPU may still have available capacity. This is why increasing vCores doesn't necessarily eliminate latch contention. Additional compute provides more workload headroom, but it doesn't automatically remove a serialization point around a hot page. Microsoft's I/O troubleshooting guidance also distinguishes PAGEIOLATCH and other I/O-related waits when diagnosing storage-performance problems. Microsoft Learn: Troubleshoot SQL Server I/O performance Query Frequency Matters Too Another common mistake is focusing only on individually expensive queries. Imagine a query that takes only 20 milliseconds but executes hundreds of thousands of times, often concurrently. Its impact is better thought of as: Workload Impact = Cost per execution × Execution frequency × A small metadata lookup or initialization query can become significant when hundreds of application instances execute it simultaneously. This is where Query Store becomes particularly useful. Query Store preserves query, execution-plan, and runtime history, allowing you to compare executions, duration, CPU, plans, and other performance characteristics over time. Microsoft Learn: Monitor performance using Query Store Instead of asking only: "What's my most expensive query?" also ask: "What changed in the workload?" When Nine Hours of Duration Is Only One Minute of CPU Now consider the opposite problem. Suppose Query Store shows something like: Elapsed time 9 hours SQL CPU time 1 minute Returned rows 750,000+ Dominant wait ASYNC_NETWORK_IO Would adding CPU solve this? Probably not. CPU represents only a tiny fraction of the elapsed time. ASYNC_NETWORK_IO commonly occurs when SQL Server has results available but the client application is not consuming them quickly enough. Microsoft documents several possible causes, including: large result sets; slow application processing; applications fetching rows slowly; network-related delays. Microsoft Learn: Troubleshoot ASYNC_NETWORK_IO Importantly: ASYNC_NETWORK_IO does not automatically mean the network is slow. The bottleneck might actually be the application. Measure Time to First Row A useful troubleshooting technique is to separate database response time from result-consumption time. Instead of measuring only: Query start → Application finished measure: T0 = Query submitted T1 = First row received T2 = Last row received T3 = Application processing completed You can then separate: Database response = T1 - T0 Result consumption = T2 - T1 Application For example: First row received: 2 seconds Last row received: 2 hours Processing completed: 2.5 hours Calling this a "2.5-hour SQL query" would be misleading. SQL started returning results after two seconds. Most of the time was spent transferring or processing them. Don't Forget Blocking Low CPU can also be caused by blocking. If many sessions are waiting behind a transaction, increasing CPU isn't going to solve the problem. During an active incident, check requests and their waits: SELECT r.session_id, r.blocking_session_id, r.status, r.wait_type, r.wait_time, r.wait_resource, r.cpu_time, r.total_elapsed_time, st.text FROM sys.dm_exec_requests AS r CROSS APPLY sys.dm_exec_sql_text(r.sql_handle) AS st WHERE r.blocking_session_id <> 0 ORDER BY r.wait_time DESC; This helps determine whether the application is experiencing a resource problem or simply waiting behind another transaction. Why Scaling Can Be Misleading Imagine this sequence: Application slow ↓ Scale database ↓ Performance improves It's tempting to conclude: "We needed more CPU." But scaling can change more than CPU availability. Depending on the operation and environment, it can alter resource availability or execution conditions. Therefore: A successful mitigation does not automatically prove the root cause. Always distinguish between: What made the symptoms disappear? and: What originally caused the symptoms? A Practical Troubleshooting Workflow When investigating Azure SQL performance, I use the following approach: 1. Define the exact incident window Preferably using UTC timestamps. 2. Check core resources Look at: CPU Data IO Log IO memory workers 3. Compare CPU time with elapsed time If: Elapsed ≈ CPU investigate computational workload. If: Elapsed >>> CPU investigate waits. 4. Identify dominant waits Ask what prevented SQL from continuing execution. 5. Check blocking Determine whether requests are waiting behind other transactions. 6. Use Query Store Compare healthy and problematic periods for: execution count; CPU; duration; logical reads; plans; wait behavior. Microsoft provides Query Store examples specifically for workload and performance investigation. Microsoft Learn: Tune performance with Query Store 7. Inspect the execution plan Look for inefficient access patterns, cardinality problems, excessive reads, repeated lookups, spills, scans, or plan changes. 8. Investigate the application Especially when SQL CPU is low but result-transfer waits are high. Look at: rows returned; fetch size; batch size; application processing; concurrency; downstream dependencies. 9. Compare healthy vs unhealthy periods Don't analyze an incident in isolation. Ask: What changed? Common Misdiagnoses "CPU isn't 100%, so SQL is healthy." Not necessarily. Queries might simply be waiting. "ASYNC_NETWORK_IO means we have a network problem." Not necessarily. The client may be consuming results slowly. "PAGELATCH means storage is slow." No. Don't confuse PAGELATCH with PAGEIOLATCH. "Scaling fixed the problem, so CPU was the root cause." Not necessarily. Mitigation and root cause are different concepts. "The slowest query must be the problem." Not always. A small query executed extremely frequently can generate larger cumulative impact. Final Thought: Follow the Time When Azure SQL becomes slow, avoid jumping directly from: Slow database → Add more vCores Instead, work through: High latency ↓ Resource utilization ↓ CPU vs elapsed time ↓ Wait statistics ↓ Query Store ↓ Execution plan ↓ Application behavior ↓ Root cause ↓ Targeted optimization Performance troubleshooting becomes much easier once you stop asking only: "How busy is Azure SQL?" and start asking: "Where did the time go?" Because sometimes the database isn't busy at all. It's waiting. References Monitor Performance by Using the Query Store Tune performance with the Query Store Troubleshoot slow queries resulting from ASYNC_NETWORK_IO Troubleshoot slow SQL Server performance caused by I/O issues168Views0likes0CommentsIntroducing Simplified Regional Limits for Azure SQL Managed Instance
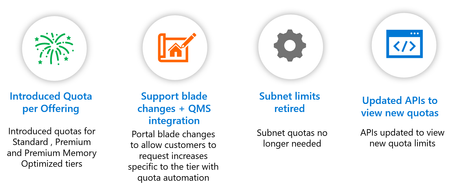
We are pleased to announce improvements to regional subscription limits for Azure SQL Managed Instance. These changes simplify subnet management and provide more granular control over vCore capacity across hardware generations. What’s changing? Two changes are now generally available: Regional subnet limits are removed Azure SQL Managed Instance no longer applies service-specific regional subnet limits. Instead, deployments are governed by the applicable Azure Resource Manager virtual networking limits. This simplifies resource planning and removes the need to monitor or request increases for Azure SQL Managed Instance regional subnet limits. Regional vCore limits are now hardware-generation specific Regional vCore limits are now managed separately for each supported hardware generation: • Standard Series • Premium Series • Premium Series Memory Optimized Previously, a single regional vCore limit applied across hardware generations. With hardware-generation-specific limits, customers can request additional capacity only for the hardware generation required by their workloads. For example, if you need additional Premium Series capacity in a region, you can request an increase for Premium Series without changing the limits for Standard Series or Premium Series Memory Optimized. Check vCore quota limit and usage with PowerShell Use the Subscription Usages - Get REST API to retrieve the current vCore quota limit and consumption for Azure SQL Managed Instance in a subscription and region. Query each hardware generation separately by specifying its usage name: Hardware generation Usage name Standard-series (Gen5) SubscriptionSQLManagedInstanceStandardSeriesVCoreQuota Premium-series SubscriptionSQLManagedInstancePremiumSeriesVCoreQuota Memory optimized premium-series SubscriptionSQLManagedInstancePremiumSeriesMemoryOptimizedVCoreQuota Run the following script in a PowerShell session with the Az module installed, or in Azure Cloud Shell using PowerShell. Your account needs permission to read subscription usage, such as the Reader role assigned at subscription scope. Replace <subscription-id> with your subscription ID, set $location to the Azure region name (for example, eastus), and set $usageName to one of the values in the table. If you're already signed in through Cloud Shell, omit Connect-AzAccount. $subscriptionId = "<subscription-id>" $location = "eastus" $usageName = "SubscriptionSQLManagedInstanceStandardSeriesVCoreQuota" Connect-AzAccount -ErrorAction Stop | Out-Null Set-AzContext -SubscriptionId $subscriptionId -ErrorAction Stop | Out-Null $path = "/subscriptions/$subscriptionId/providers/Microsoft.Sql/locations/$location/usages/${usageName}?api-version=2025-01-01" $response = Invoke-AzRestMethod -Method GET -Path $path -ErrorAction Stop if ($response.StatusCode -ne 200) { throw "Unable to retrieve quota usage. HTTP $($response.StatusCode): $($response.Content)" } $response.Content | ConvertFrom-Json -ErrorAction Stop | ConvertTo-Json -Depth 10 Example output (excerpt; values are illustrative): { "name": "SubscriptionSQLManagedInstanceStandardSeriesVCoreQuota", "properties": { "currentValue": 80, "limit": 320, "unit": "SubscriptionSQLManagedInstanceStandardSeriesVCoreQuota" } } In this example, `properties.currentValue` is the current quota consumption: 80 vCore units. `properties.limit` is the current quota limit: 320 vCore units. The remaining quota is `limit - currentValue`, or 240 vCore units, for standard-series hardware in the specified subscription and region. The previously used VCoreQuota usage name, which represented a single regional quota shared across all hardware generations, is being deprecated in favor of hardware-generation-specific quotas. Use the usage names listed in the table above to retrieve the quota limit and consumption for each hardware generation. What does this mean for existing customers? Existing regional vCore limits will be automatically converted to hardware-generation-specific limits. No customer action is required. Your new limits can be viewed and managed through the Azure portal. If the default limit for a hardware generation is insufficient for a planned deployment, you can request an increase for that specific hardware generation. New hardware generation specific vCore limits apply to both single-zone and multi-zone (Zone Redundant) Managed Instance deployments. Benefits These improvements provide: • Simpler quota management through the removal of service-specific regional subnet limits. • Better granularity with separate vCore limits for each hardware generation. • Greater flexibility to request capacity only where it is needed. • A seamless transition with automatic conversion of existing limits. To learn more about Azure SQL Managed Instance resource limits and how to request an increase, see Request quota increases for Azure SQL Database and SQL Managed Instance. We hope these changes make planning and scaling your Azure SQL Managed Instance deployments simpler and more flexible.576Views1like0CommentsManaged Instance link – connecting SQL Server to Azure reimagined
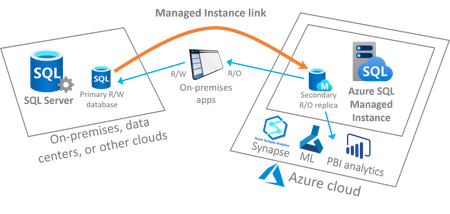
Link feature for Managed Instance is a new feature reimagining the connection between SQL Server hosted anywhere and the fully managed PaaS service Azure SQL Managed Instance, providing unprecedented hybrid flexibility and database mobility. With an approach that uses near real-time data replication to Azure, you can offload workloads to read-only secondaries on Azure to take advantage of a fully managed database platform, performance, and scale. The link can be operated for as long as you need it – months and years at a time, empowering you to get all the modern benefits of Azure today without migrating to the cloud. On your modernization journey, when and if you are ready to migrate to the cloud, the link de-risks your migration experience allowing you to validate your workloads in Azure prior to migrating with a seamless and instant experience, and at your own pace. This article provides deeper insights into this new feature.27KViews4likes9CommentsAzure SQL Database is retiring Always Encrypted with Intel SGX enclaves
On October 31, 2027, Azure SQL Database will retire Intel Software Guard Extensions (SGX) enclave functionality for Always Encrypted. Workloads that still depend on Intel SGX enclaves after that date will no longer work as configured. The path forward is Virtualization-Based Security (VBS) enclaves, a hardware-independent option that does not require attestation. To retain secure-enclave capabilities, move databases from DC-series compute to a supported standard-series, non-DC tier and update affected applications for VBS enclave mode. What is changing? Intel SGX enclaves are tied to DC-series compute. After October 31, 2027, databases on these tiers must move to supported compute to retain enclave-enabled capabilities. Applications configured for Intel SGX enclaves may also need driver and connection-string updates. For workloads that do not require isolation from the host operating system, VBS enclaves offer a straightforward migration within Azure SQL Database. If your threat model requires Intel SGX-equivalent host isolation, evaluate SQL Server on Azure Confidential VMs instead. Choose the right migration path Use the migration guide to identify databases and elastic pools on DC-series compute, choose the target architecture that matches your threat model, update application connectivity and attestation settings, and validate the workload before production cutover. Move to VBS enclaves in Azure SQL Database Choose VBS enclaves when you need to protect sensitive data from unauthorized users or malicious insiders but do not require isolation from the host operating system. VBS enclaves run on supported non-DC compute tiers and eliminate attestation requirements. Consider SQL Server on Azure Confidential VMs If your threat model requires stronger isolation from the host operating system, assess SQL Server on Azure Confidential VMs. Compare architecture, operations, compatibility, and cost with the Azure SQL Database option. Start planning early Start now. Discovery, compute-tier changes, application updates, security review, and production validation all take time. Complete the migration before October 31, 2027, to keep enclave-enabled workloads running without interruption. Help and support Have questions? Ask community experts in Microsoft Q&A. If you have an Azure support plan and need technical help, create a support request. Review service retirements that may affect your resources in the Azure Retirement Workbook. For more ways to find impacted resources, see the retirement guidance. Retirement information may take up to two weeks to appear.253Views1like1CommentDatabase Hub in Fabric: Now in Public Preview -Turn Database Signals into Guided Action
As applications grow, so does the database estate behind them. What starts with a handful of databases can become hundreds or thousands of resources spread across services, subscriptions, and environments. For the teams responsible for keeping them healthy, the challenge is no longer just collecting signals. It is knowing what needs attention, why it matters, and what to do next. Now in public preview, Database Hub in Microsoft Fabric brings inventory, health, performance, security, and optimization insights into one connected experience. It helps administrators and developers see the bigger picture, identify affected resources, and move from estate-wide visibility to focused investigation, without losing the context that brought them there. The preview brings together supported resources across Azure SQL Database, SQL Server enabled by Azure Arc, Azure Database for PostgreSQL, Azure Cosmos DB, and SQL database in Fabric. Available capabilities and signals vary by service and preview configuration. Database Hub Overview brings together estate-wide findings and cross-engine performance trends to help you prioritize what needs attention. Start with what needs your attention When you manage a large database estate, another dashboard is only useful if it helps you decide where to spend your time. The Overview page provides that starting point, bringing together findings across security, performance, and optimization. It distinguishes Issues, which require timely attention, from Suggestions, which highlight opportunities to improve your estate over time. You might begin with a security configuration that needs review or a performance signal that warrants investigation. Selecting a finding opens Estate with the relevant filters already applied, so you can see the affected resources rather than search for them again. The result is a more direct path from “something needs attention” to “these are the resources I should investigate.” Overview highlights issues across Security, Performance, and Optimization, with affected-resource counts and direct links to investigate further. Bring your estate into one view, and make it relevant to you The Estate experience brings supported resources into a unified inventory, scoped to your existing permissions. Search and filters help you narrow that inventory to the service, subscription, or resource group you manage. This is especially useful when your responsibilities span database engines. You can begin with a broader view, then focus on Azure SQL databases, Arc-enabled SQL Server resources, or Azure Database for PostgreSQL flexible servers without rebuilding the resource list in separate portals. Each resource brings its associated Issues and Suggestions into context. Open a finding to review the affected resource, supporting information, and recommended next step. The inventory also respects the resource model of each service. For example, the PostgreSQL view represents flexible server instances, rather than every database hosted within them. A unified view does not mean moving your databases. Your Azure resources remain in their existing subscriptions, and on-premises SQL Server instances remain on-premises, connected through Azure Arc. Database Hub brings operational context together; it does not require relocating or mirroring your application data into Fabric. Estate brings resource inventory, Issues, and Suggestions into one view, with quick actions to continue investigation in the Azure portal, VS Code, or SSMS. Understand security posture and performance in context Database Hub helps you identify configurations worth reviewing and resources that need a closer look. For security, supported signals can include Microsoft Entra authentication, customer-managed keys, and auditing coverage, depending on the database service. These findings provide a starting point for investigation, not a blanket judgment that every flagged resource is insecure or noncompliant. For example, a suggestion to review customer-managed keys should be evaluated against your organization’s requirements. A resource using service-managed keys is still encrypted at rest. For performance, built-in dashboards bring supported utilization and activity signals into view, including CPU, memory, storage, I/O, and connections. Review trends across your estate, then narrow the scope and time range to investigate individual resources. Metric availability varies by engine and monitoring configuration; missing data should not be interpreted as good health. For supported SQL monitoring scenarios, you can also create a custom monitoring dashboard from a template and tailor its charts and layout to the resources your team follows regularly. Together, these experiences help answer two practical questions: Where is pressure building, and where is there an opportunity to improve? Performance summaries highlight recent capacity signals and trends across Microsoft SQL, PostgreSQL, and Cosmos DB. The Security dashboard summarizes Microsoft Entra authentication, audit logging, and customer-managed key coverage, helping you identify configurations that warrant review across your estate. The Performance monitoring dashboard combines memory-pressure trends, resource-level details, and interpretation guidance to help focus your investigation. Move from a finding to an informed next step Estate-wide visibility is the beginning of an investigation, not a replacement for database expertise. When a finding needs deeper analysis, Database Hub helps you review the evidence and continue in the appropriate native experience, such as the Azure portal or SQL Server Management Studio (SSMS). Engine-specific diagnostics and configuration changes remain in the tools designed for that work. Consider a performance issue that occurred before an administrator could inspect it. In supported agent-assisted scenarios, captured incident evidence can help establish what happened, when it happened, and which queries or sessions were involved. That context gives the administrator a more informed starting point for investigation. The operator remains in control: review the evidence, evaluate the recommendation, and apply authorized changes through the appropriate service tools. The preview investigation workflow does not automatically remediate issues, and existing permissions and approval requirements continue to apply. Bring database expertise into agent-assisted workflows We are also making database operational intelligence available through agent skills: reusable capabilities that agents can call to support observability, monitoring, diagnostics, optimization, and other database operations. Database Hub provides estate context; skills provide a way to bring database expertise into an agent-assisted investigation. This creates a foundation for helping teams move from identifying an affected resource to understanding its signals and evaluating the next step. We’re building toward making this expertise available in the AI companions and development tools teams already use, with recommendations grounded in evidence, the specific database, and your organization’s operational controls. If we take a step back, our broader vision brings together a free, extensible Database Hub experience, agentic observability, and OneLake integration, all within Microsoft Fabric. It’s a foundation for connecting database operations with analytics and AI and helping teams turn signals into informed action. Get started with Database Hub Start with the Database Hub documentation to review preview availability, supported services, and setup requirements. Ask your Fabric administrator to enable the preview where required, confirm that you have the appropriate resource permissions, and complete any service-specific monitoring prerequisites. Then open Microsoft Fabric, select Databases in the left navigation, and begin with Overview. Choose a finding, explore the affected resources in Estate, and follow the evidence into your next investigation. For more details on supported services and getting set up, the Database Hub documentation is also available on Microsoft Learn. Learn more What is Database Hub in Fabric? Enable performance monitoring for Microsoft SQL Performance Monitoring for Azure SQL in Database Hub854Views5likes1Comment