azure monitor
1366 TopicsSee the Patterns, Then the Trace: Distributed Tracing at Scale with Azure Monitor
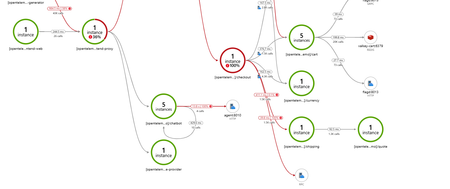
Analyze distributed traces at scale We are excited to announce the public preview of Azure Monitor traces. You can now analyze application transactions at-scale using end-to-end traces and their derived metrics to identify patterns in usage, performance, and failures. Trace-based metrics automatically generates metrics from transaction traces that can power service-level indicators, dashboards, alerts and long-term trend analysis. Trace Analytics brings distributed operations from multiple services together and lets you define matching criteria to isolate the business-relevant or service-specific transactions that matter most to you. From that result set, you can compare behavior across traces, understand which services and dependencies shape end-to-end latency or result in failures, and drill into individual transactions when deeper diagnosis is required. Move from broad signals to the traces that explain it Distributed systems and AI-powered applications can generate millions of spans across many services, dependencies, and customer journeys. The challenge is rarely finding a single slow or failed trace. It is understanding whether the issue represents a pattern, which business transactions are affected, and which components and dependencies are contributing most to the outcomes at-scale. Figure 1: Trace-derived metrics in Application Insights Traces blade With the new trace experiences, you can use trace-based metrics and Trace analytics to analyze high-volume telemetry and focus on the transactions most relevant to customer journeys, agent interactions or specific services and performance thresholds. These workflows support both wide trend analysis and pattern recognition plus detailed investigations of individual end-to-end transactions. Figure 2: Critical Path Analysis in Application Insights Traces • Trend application behavior and SLIs over time with trace-based metrics • Find and analyze business transactions that are not meeting SLOs • Use critical path analysis to identify services and dependencies driving end-to-end transaction time • Perform agent-based troubleshooting using Azure Monitor traces MCP • Compare span attributes across healthy and unhealthy traces • Find failing components responsible for broken customer journeys • Drill down to individual trace details Unified tracing Available to every Application Insights user. Benefit from the new tracing experience regardless of your current instrumentation or application architecture by linking your Application Insights resources to a centralized trace store in an Azure Monitor workspace. OpenTelemetry-compatible by design. Azure Monitor preserves OpenTelemetry attributes, naming conventions, and schema when traces are ingested, enabling search and analysis using native OpenTelemetry semantics across cloud-native and open-source observability stacks. Get started Existing Application Insights users can opt-in to the new tracing features with a few selections in the Azure portal. Organizations managing multiple Application Insights resources can enable the experience programmatically by using the provided Azure Resource Manager template. Try the public preview and share your feedback with the Azure Monitor team as we continue to expand the distributed tracing experience. Reach us at TraceAnalyticsFeedback@microsoft.com33Views0likes0CommentsTroubleshoot with OpenTelemetry in Azure Monitor – Now Generally Available
OpenTelemetry is fast becoming the industry standard for modern telemetry pipelines. Now Azure Monitor speaks it natively. With OpenTelemetry Protocol (OTLP) support generally available, you can ship logs, metrics, and traces from wherever your workloads run to analyze and act on it in one place. Direct OTLP ingestion into Azure Monitor has been generally available since May 2026. Now, we are expanding the scope to include automated onboarding for Azure Kubernetes Service (AKS) and using the Azure Monitor Agent (AMA) to receive and forward OTLP. OTLP Support in Azure Monitor Ingest OTLP signals directly into Azure Monitor logs, metrics, and traces. Automatically onboard AKS workloads. Receive and forward OTLP with (AMA) on Linux Azure VMs and VM Scale sets. Use Application Insights on OTLP for distributed tracing, performance and troubleshooting experiences. Visualize signals in Grafana with Azure-supported and community dashboards. Store and query OTLP metrics using PromQL Use OTLP semantic conventions for logs and traces, so your data lands in a familiar standards-based schema. Choose your OTLP path VMs/VM Scale Sets (and Azure Arc-enabled compute): Use the Azure Monitor Agent to receive OTLP from your apps and export it to Azure Monitor. Get started AKS: Auto-instrument Java, Node.js, Python and .NET workloads using the Azure Monitor OpenTelemetry distro, or auto-configure any OpenTelemetry SDK-instrumented workload to export OTLP to Azure Monitor. Get started Any environment: Use the OpenTelemetry Collector to receive OTLP signals and export directly to Azure Monitor cloud ingestion endpoints. Get started Where your telemetry lands Metrics: Stored in an Azure Monitor Workspace, a Prometheus metrics store. Logs + traces: Stored in a Log Analytics workspace using an OpenTelemetry semantic conventions–based schema. Troubleshooting: Application Insights lights up distributed tracing and end-to-end performance investigations, backed by Azure Monitor. OTLP traces: Also, now available in Azure Monitor traces with Trace Analytics Why it matters Standardize once: Instrument with OpenTelemetry and keep your telemetry portable and reusable. Reduce overhead: Fewer vendor-specific components and pipelines to maintain. Debug faster: Correlate metrics, logs, and traces using consistent labels to get from notifications to root cause faster. Observe with confidence: Use pre-built dashboards and tracing views and enable agent-assisted workflows through Azure Monitor MCPs and APIs. Next step: Onboard using direct ingestion, AKS or AMA, then validate end-to-end signal flow with Application Insights and Grafana dashboards. Learn More50Views0likes0Comments
Public preview: Auto scaling of ingestion limits in Azure Monitor workspace
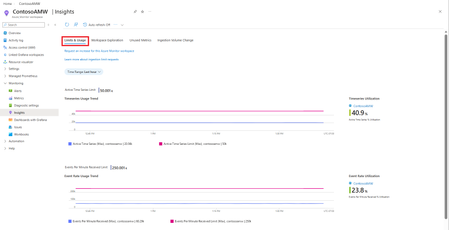
If you run Azure Monitor Workspace at scale, you've probably had to request a higher ingestion limit at some point. A new service rolls out, a cluster scales out, or cardinality creeps up, and suddenly usage is close to your limit. Until now, the fix was a manual request, and you were at risk of throttling until the new limit was applied. Today we're announcing the public preview of Auto-scale for ingestion limits in Azure Monitor workspace (AMW). When you turn on Auto-scale, Azure Monitor adjusts your workspace's ingestion limits automatically based on your actual usage. Limits go up as your metrics volume grows and come back down when usage stays low for a sustained period of time. Why Auto-scale? Static ingestion limits create problems in both directions: Throttling risk: When usage grows faster than your limit, metrics can be dropped. You lose visibility right when your environment is changing. Manual work: Raising a limit means opening a support request and waiting for it to be applied. Over-provisioning: To avoid repeat requests, teams often ask for far more headroom than they need. Auto-scale removes this balancing act. Your limits track your real usage, so you can spend less time managing quotas and more time using your observability data. Key capabilities Turn on Auto-scale for your workspace During public preview, Auto-scale is an opt-in setting for each workspace. When it's on, the system keeps your ingestion limit at a healthy level compared with your usage: Scale up: When ingestion approaches the upper utilization threshold, your limit is raised to help prevent throttling. Scale down: When utilization stays low for a sustained period, unused capacity is reclaimed. Ingestion isn't affected. You can turn on Auto-scale in the with an ARM API update or in the Azure portal. Azure CLI: $resourceId = "/subscriptions/<subscriptionId>/resourceGroups/<resourceGroupName>/providers/Microsoft.Monitor/accounts/<azureMonitorWorkspaceName>/metricsContainers/default" az resource update --ids $resourceId --api-version 2026-09-03-preview --set properties.limits.enableAutoScale=true --force-string To turn Auto-scale off, set enableAutoScale=false. Your limits then stay fixed and you manage them manually, the same as today. [Coming soon] Azure portal: In the Azure portal, navigate to the Azure Monitor Workspace -> Limits and Usage to enable Auto-scale. Note: Azure portal support for this feature is being deployed in phases and is expected to be available in all regions in the coming weeks. See every scale change in the Activity Log When Auto-scale is enabled, any change in the ingestion limits is recorded in the workspace's Activity Log. You get a clear history of when your limits changed and in which direction. Set up alerts on limits, usage and scale events You can create Azure Monitor alerts on: Ingestion usage compared with your current limits, such as events per minute ingested and active time series. See set up recommended alerts for Azure Monitor Workspace to learn more. Dropped events or time series. See Monitor ingestion health to learn more. Any scale event triggered by Auto-scale. See Create an activity log alert rule to learn more. Once you set up these alerts, you will be notified whenever limits change, or when usage trends need a closer look. What about billing? Auto-scale doesn't change what you pay. It only adjusts your ingestion limit (the quota ceiling). Billing is still based on what you actually ingest. When should you use Auto-scale? Turn on Auto-scale if Keep Auto-scale off if Your metrics volume grows over time or varies with deployments You need a hard, fixed ingestion cap to control volume You want to avoid throttling without filing limit requests You prefer to manage limits manually through existing processes You want limits that match your real usage instead of padded headroom If you don't turn on Auto-scale, nothing changes. Your workspace behaves exactly as it does today. Get started Open your Azure Monitor workspace in the Azure portal or use the ARM command above. Turn on Auto-scale for ingestion limits. Check the Activity Log for scale events and set up alerts on usage and scale changes. Set up recommended alerts for your Azure Monitor Workspace to monitor your ingestion limits and utilization. Learn more. We want your feedback This is a public preview, and your input will shape general availability. Tell us how Auto-scale works for your workloads at AMW Auto-scale feedback form.136Views0likes0CommentsScale Data Collection Endpoint private connectivity with IP Endpoint Compression - Preview
Scale Azure Monitor Private Link with data collection endpoint IP compression As organizations expand their Azure Monitor deployments, private networking needs to scale with them. For enterprises running large, distributed environments, that can create an increasingly important challenge: how do you grow private monitoring without consuming private IP address space at the same rate? Azure Monitor is introducing private IP endpoint compression for data collection endpoints (DCEs) connected through Azure Monitor Private Link Scope (AMPLS). This capability is designed to reduce the private IP footprint by ~90%-95% associated with DCEs while preserving the Azure Monitor Private Link architecture and the security controls customers already use. The challenge: private monitoring at enterprise scale Organizations often centralize Azure Monitor connectivity through carefully governed hub-and-spoke networks. As these environments grow, they can include monitored resources, data collection rules (DCRs), DCEs, and Log Analytics workspaces distributed across multiple regions. When private connectivity is required, DCEs are connected through AMPLS. The associated private endpoint uses addresses from a customer-managed subnet. As more DCEs are added, this can increase the private IP footprint required for Azure Monitor connectivity and create challenges such as: Increased subnet-capacity planning Additional network-governance reviews Delays when onboarding workloads or regions Provisioning challenges when available subnet capacity becomes constrained More operational complexity in centralized DNS and hub-and-spoke environments As customers onboard more Azure resources to send telemetry over private networks, they need a scalable way to preserve valuable private IP address space without increasing the operational complexity of their network-isolated monitoring environment. Introducing DCE private IP endpoint compression DCE private IP endpoint compression changes how DCE service endpoints are represented behind an AMPLS private endpoint. Instead of having the private IP footprint scale directly with every DCE, the compressed architecture groups compatible DCE service endpoints regionally and allows them to use a smaller, bounded set of private IP configurations. Requests continue to be routed to the intended DCE based on the requested endpoint and the existing Azure Monitor authorization context. The result is a more scalable private-network architecture without introducing a new data collection model. What does this mean for customers? Large enterprises have limited, tightly managed, often fragmented private IPv4 spaces. Private endpoints require IP addresses from customers' private IPv4 subnets. With private IP endpoint compression, all DCEs in a region share 3 regional private IPs. For example, 20 DCEs drop from 60 private IPs to 3, which is 95% fewer. Private IP address use stops growing with every DCE you add. There are no changes to how DCEs, DCRs, AMPLS, Azure Monitor Agent or Log Analytics work. Use private address space more efficiently A smaller, bounded private IP footprint can preserve valuable subnet capacity for additional workloads and Azure services. This can be particularly useful for enterprises operating with constrained private IP address space or centralized network-allocation processes. Make network planning more predictable Instead of treating each additional DCE as a proportional increase in private IP requirements, network teams can plan capacity around the regional architecture. This approach makes the network planning more predictable for enterprise customers. Scale monitoring across more workloads and regions Reducing pressure on private IP address space can make it easier to expand monitoring across applications, subscriptions, and regions without repeatedly redesigning private endpoint subnets. Reduce operational friction A more compact endpoint representation can reduce the networking work associated with subnet capacity reviews, expansion planning, and Private Link onboarding. What stays the same? One of the goals of this design is to improve network scalability while preserving the Azure Monitor model customers already use. DCE private IP endpoint compression doesn't change: The role of AMPLS as the private Azure Monitor network boundary The role of the private endpoint connecting a virtual network to AMPLS AMPLS Open and Private Only access modes DCR collection, transformation, and routing logic Azure Monitor Agent configuration semantics Log Analytics tables, retention, or KQL query behavior The amount of telemetry ingested into Azure Monitor Application Insights data collection, which doesn't use DCEs Azure Monitor ingestion charges Azure Private Link data-processing charges based on data volume Customers should continue following their existing DNS, routing, network security, public network access, and AMPLS configuration requirements. Preparing for the controlled preview DCE private IP endpoint compression is currently intended for subscriptions participating in a controlled preview. For customers participating in the preview, we recommend starting with a nonproduction or limited deployment. Before expanding the deployment: Map your topology. Understand the virtual networks, peering, AMPLS resources, private endpoints, DCEs, DCRs, workspaces, DNS zones, and supporting subnets involved. Review DNS ownership. Pay particular attention to networks sharing Azure Monitor private DNS zones and use a deliberate AMPLS topology. Establish a baseline. Record your existing private endpoint IP configurations and DCE DNS responses. Confirm regional alignment. Review the relationship between monitored resources, DCE configuration access, ingestion endpoints, and destination workspaces. Review access modes. Confirm the appropriate use of AMPLS Open or Private Only access modes for your security requirements. Validate end to end. Verify DNS resolution, Azure Monitor Agent configuration access, DCR health, ingestion, transformation, and query behavior before expanding the deployment. Looking ahead Bottom line: DCE private IP endpoint compression is designed to make private Azure Monitor deployments easier to scale by reducing the relationship between DCE growth and private IP consumption, while preserving the Azure Monitor and AMPLS architecture customers use today. Customers interested in participating in the controlled preview can contact the author via email with their subscription need to be allowlisted for the preview. This preview is available only to allowlisted subscriptions. To request access, submit your Azure subscription ID through the DCE IP Endpoint Compression preview onboarding form. Wait for Microsoft to confirm that your subscription is preview-enabled before you create the test DCEs. IP compression applies automatically to newly created DCEs in preview-enabled subscriptions. There's no additional setting to enable when you create a DCE or associate it with AMPLS. We look forward to helping customers scale private Azure Monitor deployments while making more efficient use of their network address space. Resources Learn more about designing and configuring private connectivity for Azure Monitor: Scale Data Collection Endpoint (DCE) private connectivity with IP Endpoint Compression (Preview) - Azure Monitor | Microsoft Learn Use Azure Private Link to connect networks to Azure Monitor Learn how Azure Monitor Private Link Scope (AMPLS), private endpoints, and Azure Monitor resources work together to provide private connectivity. Design your Azure Monitor Private Link configuration Review network topology, DNS, AMPLS limits, hub-and-spoke architectures, and other considerations when planning Azure Monitor Private Link. Configure Azure Monitor Private Link Follow the configuration guidance for creating an AMPLS, connecting Azure Monitor resources such as Data Collection Endpoints (DCEs), and connecting the AMPLS to a private endpoint. Prevent IPv4 Exhaustion in Azure - Azure Architecture Center | Microsoft Learn262Views0likes0CommentsGeneral Availability: Advanced platform metrics in Azure Monitor
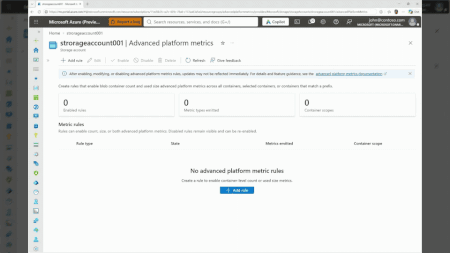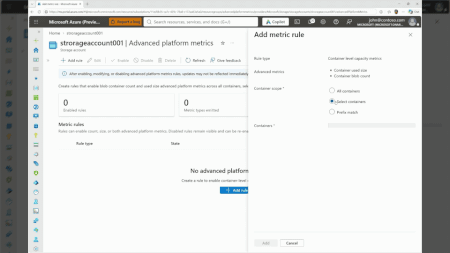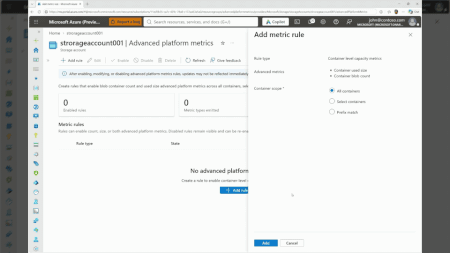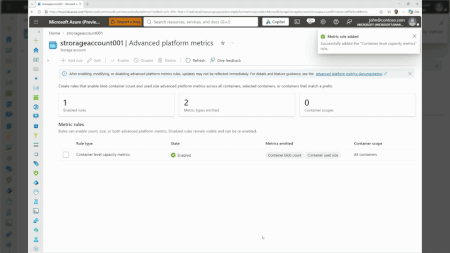
We are excited to announce the general availability (GA) of advanced platform metrics for Azure Monitor, delivering more granular telemetry to help customers monitor and optimize their workloads more effectively. This new capability builds on Azure Monitor platform metrics, which continue to provide broad insight into the health, activity, and consumption of Azure resources. These additional signals help customers pinpoint changes and trends within resources more quickly and accurately. Azure Storage is the first Azure resource to provide advanced platform metrics to customers. Today, Azure Storage users rely on platform metrics to understand overall storage account trends, but this account-level telemetry does not always show what is driving change. For example, a storage account may show steady capacity growth without revealing which specific container is responsible. That growth could be coming from one container used for backups, another storing application logs, or a staging container used by a data pipeline. Advanced platform metrics for Azure Monitor address this scenario by providing container-level visibility, helping customers quickly identify where growth is occurring, investigate unexpected consumption increases, and make more informed cost and capacity planning decisions. What is available at GA? Today, the following advanced platform metrics are available for Azure Storage: Container Blob Capacity: The amount of storage used by one or more specific containers in a storage account. Container Blob Count: The number of blob objects in one or more specific containers in a storage account. For GA, availability of advanced platform metrics will expand to Fairfax and Mooncake clouds, in addition to all Azure public regions that were supported during the public preview. Advanced platform metrics can also now be discovered, enabled, and exported directly from the Azure portal, making it easier for customers to use the feature and monitor their workloads in greater depth. Getting Started Advanced platform metrics can be enabled and configured for each storage account through the Azure portal, Azure CLI, or PowerShell. In the Azure portal, advanced platform metrics can be enabled by navigating to the Advanced platform metrics tab under the Monitoring blade within a storage account. For detailed instructions on enabling, managing, and viewing Azure Storage advanced platform metrics, see Azure Platform Metrics for Azure Blob Storage. After advanced platform metrics are enabled for a storage account, they can be queried, visualized, and used for alerts through the same existing platform metrics experiences. Container Blob Capacity and Container Blob Count will appear in the Metric dropdown menu in Metrics Explorer, alongside all existing Azure Storage platform metrics. Users can then select Apply splitting and choose Container name to view container-level data for individual containers. Azure Storage scenarios enabled by advanced platform metrics Advanced platform metrics are already helping customers gain deeper insight into their Azure Storage environments. Customers are using container-level visibility to understand which applications and workloads are driving consumption in shared storage accounts, support internal cost attribution, plan for future capacity needs, and investigate unexpected increases in capacity or object count. Instead of relying on custom reporting pipelines to understand container-level usage, teams can use these metrics to more quickly identify where changes are occurring and focus on their investigation. Pricing and billing Advanced platform metrics for Azure Monitor are offered as a paid capability. For the latest pricing details, see Azure Monitor pricing. What's next? The GA of advanced platform metrics is just the beginning of bringing higher-cardinality metrics to Azure customers. Looking ahead, our roadmap includes the following expansions: Azure Storage plans to broaden support for advanced platform metrics, including increased capacity and additional transaction scenarios. Additional Azure resource providers will onboard over time, with newly supported metrics documented on the Azure Monitor supported metrics by resource type page. Azure Service Bus and Event Hubs are working to release select subscription and partition-level advanced platform metrics. Expansion of feature availability to all supported Azure clouds. Continue to follow the Azure Observability Blog for the latest updates. Feedback We would love to hear your feedback on advanced platform metrics, including how your teams are using the feature to optimize workloads and which additional advanced platform metrics that you would like to see onboarded to Azure Monitor. Please fill out this Azure Monitor advanced platform metrics feedback form, or email advancedplatformmetrics@microsoft.com.433Views0likes0Comments
General Availability: Metrics usage insights for Azure Monitor workspace
As your application and hosting environment grows, so do your observability needs and the volume of metrics you collect. But understanding what is driving that usage, how it is changing over time, and where there may be opportunities to optimize can be challenging. We’re excited to announce the general availability of Metrics usage insights for Azure Monitor workspace, an end-to-end insights solution that brings together detailed metrics usage data to give you greater visibility into your metrics footprint and help you better understand, manage, and optimize your usage. Since public preview, we’ve expanded Metrics usage insights to all public regions where Azure Monitor workspace is generally available and refreshed the dashboard experiences. As part of GA, we’re also introducing the Ingestion Volume Change dashboard to help you investigate how your metrics usage changes over time. What customers are saying Customers who have adopted Metrics usage insights have told us that one of the biggest challenges in operating large-scale metrics environments is understanding what's consuming their workspace capacity. “We have been using this feature for more than a year now on our AMW fleet and it has been really awesome with no apparent issues. The insights around which metrics are the highest consumers of the AMW quota (time series and events) have been super helpful.” — Microsoft HLS Frontier AI Metrics usage insights is also helping teams establish stronger operational practices for large Azure Monitor deployments. "Metric Insights is must-have observability in AKS [Azure Kubernetes Service], everyone needs it." — Microsoft Observability Common infrastructure (OCI) This feedback reinforced the importance of making metrics investigations simpler and more actionable and helped shape the continued evolution of the Metrics usage insights experience. Understand your metrics usage Metrics usage insights provides a centralized view into the metrics being ingested into your Azure Monitor workspace. With built-in insights, you can: Understand workspace utilization by viewing live active timeseries and event ingestion rates against workspace limits. Explore metrics usage to understand timeseries counts, ingestion volume growth, daily trends on a per metric basis. Identify unused metrics that haven’t been queried recently and evaluate opportunities to reduce unnecessary ingestion and recuperate costs. This helps you move beyond simply knowing how much data you’re ingesting to understanding what is contributing to that usage and where you may want to take a closer look. New since public preview: Investigate changes in ingestion volume When you see a significant increase or decrease in workspace usage, one of the first questions is often: What changed? The new Ingestion Volume Change dashboard helps answer that question by letting you compare metrics ingestion between two points in time and identify the metrics contributing to changes across your workspace. For each metric, you can see changes in: Event ingestion rate Active time series Change in time series or event rates Percentage increases or decreases This makes it easier to identify metrics experiencing significant growth or decline and focus your investigation on the metrics contributing to those changes. Get started Metrics usage insights is available directly from your Azure Monitor workspace. You can enable it when creating a new workspace or configure it for an existing workspace using diagnostic settings. Learn more: Metrics usage insights in Azure Monitor | Microsoft Learn413Views1like0CommentsAction required: PromQL regex matching in Azure Monitor Workspace is becoming spec-compliant
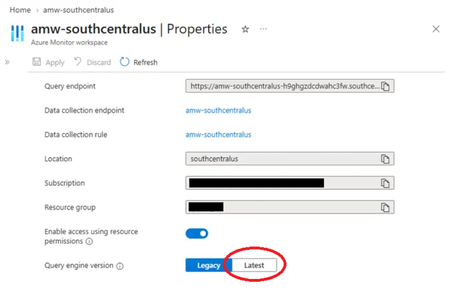
TL;DR: Bare regex matchers like pod=~"foo" will soon return only exact matches, not substring matches. If you rely on =~ for "starts with" or "contains" semantics, update your queries to add .* before the change lands. What is changing AMW's Prometheus Query Service is moving to fully-anchored regex matching, aligning with the upstream Prometheus specification. After the change, every =~ and !~ matcher is wrapped with ^…$ before evaluation. This matches the behavior of self-hosted Prometheus, Grafana Cloud Metrics, and Amazon Managed Prometheus. "Regex matches are fully anchored. A match of env=~"foo" is treated as env=~"^foo$"." Reference: Prometheus querying basics — Instant vector selectors Behavior delta Given these timeseries: kube_pod_container_status_ready{pod="grafana-otel-collector-97b6c55f4-abc12"} kube_pod_container_status_ready{pod="grafana-otel-collector-97b6c55f4-def34"} kube_pod_container_status_ready{pod="grafana-otel-collector-97b6c55f4"} Query: kube_pod_container_status_ready{pod=~"grafana-otel-collector-97b6c55f4"} Environment Effective regex Series returned AMW PQS — current grafana-otel-collector-97b6c55f4 (unanchored) 3 (all matching pods) AMW PQS — after change ^grafana-otel-collector-97b6c55f4$ 1 (exact name only) Self-hosted Prometheus, Grafana Cloud, AMP ^grafana-otel-collector-97b6c55f4$ 1 (exact name only) If your query depends on the first row, it will return fewer — often zero — series after the change. What to do Audit any query, alert rule, recording rule, or dashboard variable that uses =~ or !~. Map each to the table below. Intent Update to Exact match No change necessary; both label="value" and label=~"value" should return exact matches after updating query engine version for fully anchored regex support. Starts with label=~"value.*" Ends with label=~".*value" Contains label=~".*value.*" Set of prefixes label=~"(a\|b\|c).*" Recommendation: Where the intent is exact match, switch from =~ to = It is clearer to readers and skips per-series regex evaluation. When ready, update AMW configuration to use the latest Query engine version. This can be done via the Azure Portal UI, Azure CLI, or PowerShell. Configuring AMW to use the latest Prometheus query engine version Azure Portal In the Azure portal, open your Azure Monitor workspace. Under Settings, select Properties. Select the Latest segment of the Query engine version for the AMW. Azure CLI Run the following command to update to the latest (2.0) metrics query engine version for the AMW: Az monitor account metrics-container update --subscription <subscriptionId> -g <resourcegroupName> -w <azmonWorkspaceName> -n default --version 2.0 Azure PowerShell Run the following command to use the latest Query engine version for the AMW: $resourceId = “/subscriptions/<subscriptionId>/resourceGroups/<resourcegroupName>/providers/Microsoft.Monitor/accounts/<azureMonitorWorkspaceName>/metricsContainers/default” Az resource update --ids $resourceId --api-version 2025-10-03 --set properties.version=2.0 --force-string To confirm: Az resource show --ids $resourceId --api-version 2025-10-03 --query properties.version --output tsv Expected output: 2.0 Common pitfalls Alternation anchors the whole expression. pod=~"foo|bar" becomes ^(?:foo|bar)$, not ^foo|bar$. Add .* and parentheses for prefix sets. . matches any character, including -. pod=~"my-pod.*" will match my-pod-xyz, my-podxyz, and my-pod9xyz. Use character classes like [-] for tighter matches. Empty-label matching is unchanged. label=~"" still matches series without that label. Timeline Public Preview rollout: September 2026 In Public Preview, newly created AMWs will default to the latest metrics query version (“2.0”) which features fully anchored regex matching. AMWs created prior to September 2026 will continue using version (“1.0”) unless users take action to update. This provides users with the opportunity to verify their query intent and update accordingly prior to cutover to the latest AMW metrics query engine version. General Availability: March 2027 In General Availability, all AMWs regardless of creation date will be updated to version “2.0” for cross-workspace compatibility. Action window: Audit and update queries before the General Availability date.398Views0likes0CommentsUsage stats for Log Analytics?
Is there a way to view usage statistics for Log Analytics? Specifically, is there a way to view "when/what/who" queries have been executed in Log Analytics? I'd like to be able to generate some usage reports so that we can make sure that the service is being properly utilized by our users.1KViews0likes1CommentAzure VMs host (platform) metrics (not guest metrics) to the log analytics workspace ?
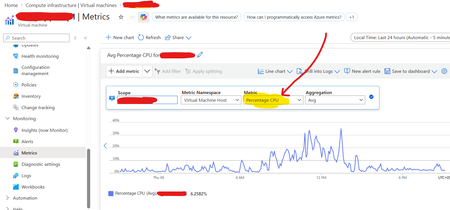
Hi Team, Can some one help me how to send Azure VMs host (platform) metrics (not guest metrics) to the log analytics workspace ? Earlier some years ago I used to do it, by clicking on “Diagnostic Settings”, but now if I go to “Diagnostic Settings” tab its asking me to enable guest level monitoring (guest level metrics I don’t want) and pointing to a Storage Account. I don’t see the option to send the these metrics to Log analytics workspace. I have around 500 azure VMs whose host (platform) metrics (not guest metrics) I want to send it to the log analytics workspace.533Views0likes3Comments