azure databricks
128 TopicsThe Partition Count You Picked on Day 1 Doesn't Have to Follow You Forever
Every stateful Structured Streaming query carries a decision that used to feel permanent: the shuffle partition count chosen on the day its checkpoint was created. Get that number wrong, usually because the real production volume only shows up months after the default value of 200 got accepted without much thought, and the historical choice was binary: live with the wrong partition count indefinitely, or abandon the entire checkpoint (and the state accumulated in it) to recreate the query from scratch with the right value. For a job that has already processed months of user sessions or aggregation windows, "abandon the checkpoint" was never a real option. On-demand state repartitioning, now in Public Preview on Databricks Runtime 18, exists precisely to close that gap: change the partition count of a stateful query without losing what has already been accumulated. The mechanism: why this was never trivial The state of a stateful query in Structured Streaming isn't a loose configuration number, it's physical data, stored in RocksDB instances inside the checkpoint, one per partition. Every key in your aggregation is distributed across partitions via hashing, so the partition count isn't just config metadata, it literally defines where each key physically lives on disk. Changing spark.sql.shuffle.partitions after the checkpoint already exists had no effect at all, because the engine kept reading the partition count recorded during the first run, and changing that number without redistributing the physical data first would break the relationship between key and partition. On-demand state repartitioning solves this with a single, explicit operation: the query finishes the pending micro-batch, runs a redistribution that rehashes every key to the new partition count, and only then resumes normal processing. It's a controlled pause, not a background migration, and its duration is auditable in the StreamingQueryProgress event, under the durationMs.controlBatch.REPARTITION field. My take: the detail that stands out here isn't the feature itself, it's how much it exposes a silent technical debt that probably exists in production right now. A lot of teams accept the default of 200 for spark.sql.shuffle.partitions without questioning it, because when the stateful query is first written nobody yet knows what the real volume will look like six months later. Before this feature, that day-1 decision effectively became permanent. It's worth mapping which of your oldest stateful queries have never had their partition count revisited since creation, that's your list of candidates for a free win. Hands-on: scaling a query already in production The requirement is Databricks Runtime 18 LTS or higher, with the RocksDB state store provider (already the default since DBR 17.3). The change itself is done by stopping the query, adjusting the configuration, and restarting with the same checkpoint: # Original query, created with the default of 200 partitions query = (df .withWatermark("event_time", "10 minutes") .groupBy(window("event_time", "5 minutes"), "id") .count() .writeStream .format("delta") .option("checkpointLocation", "/checkpoint/path") .outputMode("append") .start() ) # Volume grew, 200 partitions is no longer enough: scaling to 600 query.stop() spark.conf.set("spark.sql.streaming.stateStore.partitions", "600") query = (df .withWatermark("event_time", "10 minutes") .groupBy(window("event_time", "5 minutes"), "id") .count() .writeStream .format("delta") .option("checkpointLocation", "/checkpoint/path") # same checkpoint .outputMode("append") .start() ) The detail that matters here is that spark.sql.streaming.stateStore.partitions takes precedence over spark.sql.shuffle.partitions for that specific query, so there's no need to rewrite the aggregation logic or touch any other parameter, just restart with the checkpoint intact. In Lakeflow Pipelines, the same adjustment goes through spark_conf on the flow or table decorator, with no manual restart needed outside the pipeline's normal deploy cycle: DP.append_flow( target="session_table", name="session_aggregation", spark_conf={"spark.sql.streaming.stateStore.partitions": "600"} ) def session_aggregation(): return (spark.readStream.format("cloudFiles") .option("cloudFiles.format", "json") .load(source_path) .withWatermark("timestamp", "10 minutes") .groupBy(window("timestamp", "5 minutes"), "id") .count()) The documented payoff: it's not just speed, it's the storage bill The case Databricks itself published comes from Coveo, which reported a 40% reduction in Amazon S3 API call costs after being able to adjust state partitioning without migrating the entire checkpoint. That's an important clue about where the gain actually shows up: poorly sized state partitioning isn't just a processing-latency problem, it's also unnecessary read and write call volume against the object storage behind the checkpoint. Too few partitions concentrate too many calls on a single RocksDB instance; too many partitions spread coordination overhead without need. Both extremes cost money in a way that only really shows up on the storage bill, not on the latency dashboard. How to know which number to pick (and how to confirm it worked) Before triggering a repartition, it's worth measuring two numbers: the current state size per partition (visible in the stateOperators metric inside the StreamingQueryProgress event, the numRowsTotal field per operator) and the load distribution across partitions, since a key with much higher cardinality than the others concentrates disproportionate volume on a single RocksDB partition regardless of how many partitions exist in total. If the problem is total volume growing uniformly, increasing the partition count solves it. If the problem is one specific key dominating the volume (a hot key), increasing partitions alone won't help much, the bottleneck is in the key distribution, not the partition count. After running the repartition, the same StreamingQueryProgress event that recorded the operation's duration in durationMs.controlBatch.REPARTITION goes back to reporting normal processing metrics on the next micro-batch. Comparing average micro-batch time before and after the change, together with storage read metrics if available in your observability setup, is the most direct way to confirm the adjustment had the expected effect, instead of assuming "more partitions is always better" and moving on without measuring. What this doesn't solve On-demand state repartitioning requires stopping the query to run, it isn't a live, real-time adjustment, so there's still a pause window proportional to the size of the accumulated state, larger state takes longer to redistribute. The feature also requires RocksDB as the state store provider, anyone still on the older in-memory provider (the legacy HDFS state store) needs to migrate before even considering this. And the feature is in Public Preview on Databricks Runtime 18, so before applying it to a critical production query, it's worth testing the repartition time against a checkpoint of comparable size in a non-production environment, the pause duration itself isn't documented as predictable in advance, we only know that "bigger state means longer." Is it worth revisiting your configuration? If your oldest stateful query has never had its partition count reviewed since creation, and data volume has grown since then (the common case), it's worth the exercise of measuring current state size and comparing it against the partition count inherited from day 1. The gain Coveo documented suggests that this kind of late adjustment, which used to require rebuilding the entire checkpoint (and for that reason almost never happened in practice), now has low enough operational cost to become a routine periodic review, not just an emergency measure. References Databricks Docs, "On-demand state repartitioning for stateful streaming queries": https://docs.databricks.com/aws/en/structured-streaming/state-repartitioning Microsoft Learn, "On-demand state repartitioning for stateful streaming queries - Azure Databricks": https://learn.microsoft.com/en-us/azure/databricks/structured-streaming/state-repartitioning Databricks Blog, "Announcing On-Demand State Repartitioning for Apache Spark Structured Streaming on Databricks": https://www.databricks.com/blog/announcing-demand-state-repartitioning-apache-sparktm-structured-streaming-databricks58Views0likes0CommentsThe Complete Guide to Azure Databricks Cost Optimization
Co-Authored by: Aladdin Alchalabi AladdinAlchalabi, Sanjeev Nair Sanjeev Nair and Rafia Aqil Rafia_Aqil This guide walks through a proven approach to Azure Databricks cost optimization, structured in three phases: 1. Discovery, 2. Cluster/Data/Code Best Practices, and 3. Team Alignment & Next Steps. Phase 1: Discovery Assessing Your Current State The following questions are designed to guide your initial assessment and help you identify areas for improvement. Documenting answers to each will provide a baseline for optimization and inform the next phases of your cost management strategy. Environment & Organization Cluster Management Cost Optimization Data Management Performance Monitoring Future Planning What is the current scale of your Databricks environment? How many workspaces do you have? How are your workspaces organized (e.g., by environment type, region, use case)? How many clusters are deployed? How many users are active? What are the primary use cases for Databricks in your organization? Data engineering Data science Machine learning Business intelligence How are clusters currently managed? Manual configuration Automated scripts Databricks REST API Cluster policies What is the average cluster uptime? Hours per day Days per week What is the average cluster utilization rate? CPU usage Memory usage What is the current monthly spend on Databricks? Total cost Breakdown by workspace Breakdown by cluster What cost management tools are currently in use? Azure Cost Management Third-party tools Are there any existing cost optimization strategies in place? Reserved instances Spot instances Cluster auto-scaling What is the current data storage strategy? Data lake Data warehouse Hybrid What is the average data ingestion rate? GB per day Number of files What is the average data processing time? ETL jobs Machine learning models What types of data formats are used in your environment? Delta Lake Parquet JSON CSV Other formats relevant to your workloads What performance monitoring tools are currently in use? Databricks Ganglia Azure Monitor Third-party tools What are the key performance metrics tracked? Job execution time Cluster performance Data processing speed Are there any planned expansions or changes to the Databricks environment? New use cases Increased data volume Additional users What are the long-term goals for Databricks cost optimization? Reducing overall spend Improving resource utilization & cost attribution Enhancing performance Understanding Databricks Cost Structure Total Cost = Cloud Cost + DBU Cost Cloud Cost: Compute (VMs, networking, IP addresses), storage (ADLS, MLflow artifacts), other services (firewalls), cluster type (serverless compute, classic compute) DBU Cost: Workload size, cluster/warehouse size, photon acceleration, compute runtime, workspace tier, SKU type (Jobs, Delta Live Tables, All Purpose Clusters, Serverless), model serving, queries per second, model execution time Diagnose Cost and Issues Effectively diagnosing cost and performance issues in Databricks requires a structured approach. Use the following steps and metrics to gain visibility into your environment and uncover actionable insights. 1. Identify Costly Workloads Account Console Usage Reports: Review usage reports to identify usage breakdowns by product, SKU name, and custom tags. Usage Breakdown by Product and SKU: Helps you understand which services and compute types (clusters, SQL warehouses, serverless options) are consuming the most resources. Custom Tags for Attribution: Tags allow you to attribute costs to teams, projects, or departments, making it easier to identify high-cost areas. Workflow and Job Analysis: By correlating usage data with workflows and jobs, you can pinpoint long-running or resource-heavy workloads that drive costs. Focus on Long-Running Workloads: Examine workloads with extended runtimes or high resource utilization. Key Question: Which pipelines or workloads are driving the majority of your costs? Governance Hub: is a centralized, account-level UI for monitoring and managing governance across Databricks. Note this is a beta feature, we will update this article as we get more information and use-cases on this feature. Now That You’ve Identified Long-Running Workloads, Review These Key Areas: 2. Review Cluster Metrics CPU Utilization: Track guest, iowait, idle, irq, nice, softirq, steal, system, and user times to understand how compute resources are being used. Memory Utilization: Monitor used, free, buffer, and cached memory to identify over- or under-utilization. Key Question: Is your cluster over- or under-utilized? Are resources being wasted or stretched too thin? 3. Review SQL Warehouse Metrics Live Statistics: Monitor warehouse status, running/queued queries, and current cluster count. Time Scale Filter: Analyze query and cluster activity over different time frames (8 hours, 24 hours, 7 days, 14 days). Peak Query Count Chart: Identify periods of high concurrency. Completed Query Count Chart: Track throughput and query success/failure rates. Running Clusters Chart: Observe cluster allocation and recycling events. Query History Table: Filter and analyze queries by user, duration, status, and statement type. Key Question: Is your SQL Warehouse over- or under-utilized? Are resources being wasted or stretched too thin? 4. Review Spark UI Stages Tab: Look for skewed data, high input/output, and shuffle times. Uneven task durations may indicate data skew or inefficient data handling. Jobs Timeline: Identify long-running jobs or stages that consume excessive resources. Stage Analysis: Determine if stages are I/O bound or suffering from data skew/spill. Executor Metrics: Monitor memory usage, CPU utilization, and disk I/O. Frequent garbage collection or high memory usage may signal the need for better resource allocation. 4.1. Spark UI: Storage & Jobs Tab Storage Level: Check if data is stored in memory, on disk, or both. Size: Assess the size of cached data. Job Analysis: Investigate jobs that dominate the timeline or have unusually long durations. Look for gaps caused by complex execution plans, non-Spark code, driver overload, or cluster malfunction. 4.2. Spark UI: Executor Tab Storage Memory: Compare used vs. available memory. Task Time (Garbage Collection): Review long tasks and garbage collection times. Shuffle Read/Write: Measure data transferred between stages. 5. Additional Diagnostic Methods System Tables in Unity Catalog: Query system tables for cost attribution and resource usage trends. Cost Observability Queries Tagging Analysis: Use tags to identify which teams or projects consume the most resources. Dashboards & Alerts: Set up cost dashboards and budget alerts for proactive monitoring. Phase 2: Cluster/Code/Data Best Practices Alignment Cluster UI Configuration and Cost Attribution Effectively configuring clusters/workloads in Databricks is essential for balancing performance, scalability, and cost. Tunning settings and features when used strategically can help organizations maximize resource efficiency and minimize unnecessary spending. Key Configuration Strategies 1. Reduce Idle Time: Clusters to incur costs even when not actively processing workloads. To avoid paying for unused resources: Enable Auto-Terminate: Set clusters automatically shut down after a period of inactivity. This simple setting can significantly reduce wasted spending. Enable Autoscaling: Workloads fluctuate in size and complexity. Autoscaling allows clusters to dynamically adjust the number of nodes based on demand: Automatic Resource Adjustment: Scale up for heavy jobs and scale down for lighter loads, ensuring you only pay for what you use. It significantly enhances cost efficiency and overall performance. For serverless and streaming, using Delta Live Tables with autoscaling is recommended. This approach leads to better resource management and reliability. Use Spot Instances: For batch processing and non-critical workloads, spot instances offer substantial cost savings: Lower VM Costs: Spot instances are typically much cheaper than standard VMs. However, they are not recommended for jobs requiring constant uptime due to potential interruptions. Considerations: Azure Spot VMs are intended for non-critical, fault-tolerant tasks. They can be evicted without notice, risking production stability. No SLA guarantees mean potential downtime for critical applications. Using Spot VMs could lead to reliability issues in production environments. Leverage Photon Engine: Photon is Databricks’ high-performance, vectorized query engine: Accelerate Large Workloads: Photon can dramatically reduce runtime for compute-intensive tasks, improving both speed and cost efficiency. Keep Runtimes Up to Date: Using the latest Databricks runtime ensures optimal performance and security: Benefit from Improvements: Regular updates include performance enhancements, bug fixes, and new features. Apply Cluster Policies: Cluster policies help standardize configurations and enforce cost controls across teams: Governance and Consistency: Policies can restrict certain settings, enforce tagging, and ensure clusters are created with cost-effective defaults. Optimize Storage: type impacts both performance and cost: Switch from HDDs to SSDs: SSDs provide faster caching and shuffle operations, which can improve job efficiency and reduce runtime. Tag Clusters for Cost Attribution: Tagging clusters enables granular tracking and reporting: Visibility and Accountability: Use tags to attribute costs to specific teams, projects, or environments, supporting better budgeting and chargeback processes. Select the Right Cluster Type: Different workloads require different cluster types, see table below for Serverless vs Classic Compute: Feature Classic Compute Serverless Compute Control Full control over config & network Minimal control, fully managed by Databricks Startup Time Slower (unless pre-warmed) Instant Cost Model Hourly, supports reservations Pay-per-use, elastic scaling Security VNet injection, private endpoints NCC-based private connectivity Best For Heavy ETL, ML, compliance workloads Interactive queries, unpredictable demand Job Clusters: Ideal for scheduled jobs and Delta Live Tables. All-Purpose Clusters: Suited for ad-hoc analysis and collaborative work. Single-Node Clusters: Efficient for simple exploratory data analysis or pure Python tasks. Serverless Compute: Scalable, managed workloads with automatic resource management. 11. Monitor and Adjust Regularly: review cluster metrics and query history: Continuous Optimization: Use built-in dashboards to monitor usage, identify bottlenecks, and adjust cluster size or configuration as needed. Code Best Practices Avoid Reprocessing Large Tables Use a CDC (Change Data Capture) architecture with Delta Live Tables (DLT) to process only new or changed data, minimizing unnecessary computation. Ensure Code Parallelizes Well Write Spark code that leverages parallel processing. Avoid loops, deeply nested structures, and inefficient user-defined functions (UDFs) that can hinder scalability. Reduce Memory Consumption Tweak Spark configurations to minimize memory overhead. Clean out legacy or unnecessary settings that may have carried over from previous Spark versions. Prefer SQL Over Complex Python Use SQL (declarative language) for Spark jobs whenever possible. SQL queries are typically more efficient and easier to optimize than complex Python logic. Modularize Notebooks Use %run to split large notebooks into smaller, reusable modules. This improves maintainability. Use LIMIT in Exploratory Queries When exploring data, always use the LIMIT clause to avoid scanning large datasets unnecessarily. Monitor Job Performance Regularly review Spark UI to detect inefficiencies such as high shuffle, input, or output. Review the below table for optimization opportunities: Spark stage high I/O - Azure Databricks | Microsoft Learn Databricks Code Performance Enhancements & Data Engineering Best Practices By enabling the below features and applying best practices, you can significantly lower costs, accelerate job execution, and build Databricks pipelines that are both scalable and highly reliable. For more guidance review: Comprehensive Guide to Optimize Data Workloads | Databricks. Feature / Technique Purpose / Benefit How to Use / Enable / Key Notes Disk Caching Accelerates repeated reads of Parquet files Set spark.databricks.io.cache.enabled = true Dynamic File Pruning (DFP) Skips irrelevant data files during queries, improves query performance Enabled by default in Databricks Low Shuffle Merge Reduces data rewriting during MERGE operations, less need to recalculate ZORDER Use Databricks runtime with feature enabled Adaptive Query Execution (AQE) Dynamically optimizes query plans based on runtime statistics Available in Spark 3.0+, enabled by default Deletion Vectors Efficient row removal/change without rewriting entire Parquet file Enable in workspace settings, use with Delta Lake Materialized Views Faster BI queries, reduced compute for frequently accessed data Create in Databricks SQL Optimize Compacts Delta Lake files, improves query performance Run regularly, combine with ZORDER on high-cardinality columns ZORDER Physically sorts/co-locates data by chosen columns for faster queries Use with OPTIMIZE, select columns frequently used in filters/joins Auto Optimize Automatically compacts small files during writes Enable optimizeWrite and autoCompact table properties Liquid Clustering Simplifies data layout, replaces partitioning/ZORDER, flexible clustering keys Recommended for new Delta tables, enables easy redefinition of clustering keys File Size Tuning Achieve optimal file size for performance and cost Set delta.targetFileSize table property Broadcast Hash Join Optimizes joins by broadcasting smaller tables Adjust spark.sql.autoBroadcastJoinThreshold and spark.databricks.adaptive.autoBroadcastJoinThreshold Shuffle Hash Join Faster join alternative to sort-merge join Prefer over sort-merge join when broadcasting isn’t possible, Photon engine can help Cost-Based Optimizer (CBO) Improves query plans for complex joins Enabled by default, collect column/table statistics with ANALYZE TABLE Data Spilling & Skew Handles uneven data distribution and excessive shuffle Use AQE, set spark.sql.shuffle.partitions=auto, optimize partitioning Data Explosion Management Controls partition sizes after transformations (e.g., explode, join) Adjust spark.sql.files.maxPartitionBytes, use repartition() after reads Delta Merge Efficient upserts and CDC (Change Data Capture) Use MERGE operation in Delta Lake, combine with CDC architecture Data Purging (Vacuum) Removes stale data files, maintains storage efficiency Run VACUUM regularly based on transaction frequency Phase 3: Team Alignment and Next Steps Implementing Cost Observability and Taking Action Effective cost management in Databricks goes beyond configuration and code—it requires robust observability, granular tracking, and proactive measures. Below outlines how your teams can achieve this using system tables, tagging, dashboards, and actionable scripts. Cost Observability with System Tables Databricks Unity Catalog provides system tables that store operational data for your account. These tables enable historical cost observability and empower FinOps teams to analyze spend independently. System Tables Location: Found inside the Unity Catalog under the “system” schema. Key Benefits: Structured data for querying, historical analysis, and cost attribution. Action: Assign permissions to FinOps teams so they can access and analyze dedicated cost tables. Enable Tags for Granular Tracking Tagging is a powerful feature for tracking, reporting, and budgeting at a granular level. Classic Compute: Manually add key/value pairs when creating clusters, jobs, SQL Warehouses, or Model Serving endpoints. Use cluster policies to enforce custom tags. Serverless Compute: Create budget policies and assign permissions to teams or members for serverless workloads. Action: Tag all compute resources to enable detailed cost attribution and reporting. Track Costs with Dashboards and Alerts Databricks offers prebuilt dashboards and queries for cost forecasting and usage analysis. Dashboards: Visualize spend, usage trends, and forecast future costs. Prebuilt Queries: Use top queries with system tables to answer meaningful cost questions. Budget Alerts: Set up alerts in the Account Console (Usage > Budget) to receive notifications when spend approaches defined thresholds. Build Culture of Efficiency To go beyond technical fixes and build a culture of efficiency, by focusing on the below strategic actions: Collaborate with Internal Engineers: Spend time with engineering teams to understand workload patterns and optimization opportunities. Peer Reviews and Code Audits: Conduct regular code review sessions and peer reviews to ensure best practices are followed for Spark jobs, data pipelines, and cluster configurations. Create Internal Best Practice Documentation: Develop clear guidelines for writing optimized code, managing data, and maintaining clusters. Make these resources easily accessible for all teams. Implement Observability Dashboards: Use Databricks’ built-in features to create dashboards that track spend, monitor resource utilization, and highlight anomalies. Set Alerts and Budgets: Configure alerts for long-running workloads and establish budgets using prebuilt Databricks capabilities to prevent cost overruns. 5. Azure Reservations and Azure Savings Plan When optimizing Databricks costs on Azure, it’s important to understand the two main commitment-based savings options: Azure Reservations and Azure Savings Plans. Both can help you reduce compute costs, but they differ in flexibility and how savings are applied. Which Should You Choose? Reservations are ideal if you have stable, predictable Databricks workloads and want maximum savings. Savings Plans are better if you expect your compute needs to change, or if you want a simpler, more flexible way to save across multiple services. Pro Tip: You can combine both options—use Reservations for your baseline, always-on Databricks clusters, and Savings Plans for bursty, variable, or new workloads. Summary Table: Action Steps It’s critical to monitor costs continuously and align your teams with established best practices, while scheduling regular code review sessions to ensure efficiency and consistency. Area Best Practice / Action System Tables Use for historical cost analysis and attribution Tagging Apply to all compute resources for granular tracking Dashboards Visualize spend, usage, and forecasts Alerts Set budget alerts for proactive cost management Scripts/Queries Build custom analysis tools for deep insights Cluster/Data/Code Review & Align Regularly review best practices, share findings, and align teams on optimization Save on your Usage Consider Azure Reservations and Azure Savings Plan635Views2likes0CommentsLearn What to Do When You Hit Capacity in Azure Databricks!
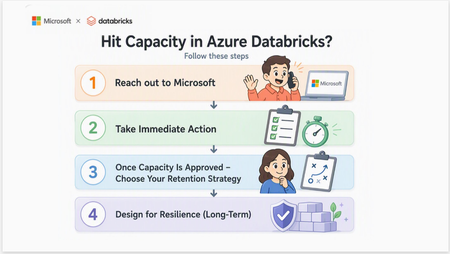
Microsoft's Cloud Architects: Manu Mehta manumehta, Chris Walk cwalk, Eduardo Dos Santos eduardomdossantos, Maria Hito mariahito, Kiran Raja Ch KiranRaja, Paul Singh PaulSingh, Aladdin Alchalabi AladdinAlchalabi and Rafia Aqil Rafia_Aqil Start Here: Engage Microsoft Capacity constraints in Azure Databricks are not an Azure Databricks product issue. Azure Databricks does not own or reserve compute, it dynamically provisions VMs from Azure when clusters are created or scaled. This means cluster creation, autoscaling, or job execution can stall when the underlying VM SKUs are constrained at the regional level. The fastest path to resolution is a structured conversation with your Microsoft account team, who can engage the Azure capacity intake process on your behalf. Create a Quota Support Ticket via Microsoft Support and bring the following to your account team with your Support Ticket Number. Each field maps directly to what capacity intake teams will ask for: missing fields slow the request. What to Prepare Before You Reach Out Your Account Team Field What Capacity Intake Needs Example Subscription IDs The exact Azure subscriptions that will host the workspaces and clusters 7ebee83d-7923-426c-8449-59fd4dff25ab Region(s) Primary region, plus any acceptable alternates East US 2 VM family / SKU Specific series and version requested Eadsv5, ESv4, DSv4, DSv2 Core count / new limit Total vCPU or core count per SKU 10,000 cores for Eadsv5 Workload characteristic CPU-bound vs. memory/shuffle-heavy vs. IO-heavy; batch vs. streaming vs. SQL “Memory-intensive ETL with large joins and shuffles” Scale and timing When you need it, ramp profile, peak vs. steady state “Need by month-end; ramp from 2,000 to 9,650 cores over Q3” Business context Business use case “Migration off AWS” What “Capacity” Really Means: A Layered Mental Model Before diving into fixes, it is important to understand what is actually happening behind the scenes. Capacity constraints can occur at three distinct layers, and solving them requires addressing each one. Layer 1: Azure Infrastructure This is the layer most teams underestimate. Capacity here is governed by: VM SKU availability in the region. D-series and E-series: the two most common Databricks worker families: have repeatedly hit capacity constraints across multiple Azure regions, causing cluster creation failures, autoscale stalls, and provisioning delays. Regional supply constraints, which are dynamic and shared across all Azure tenants. vCPU quotas and limits per subscription, which are separate from regional supply. Quota is your subscription’s limit to deploy resources (like a credit card limit); regional capacity is the underlying infrastructure available. Both must be sufficient. Mechanism Guarantees Capacity Costs Money when idle Discount vCPU quota No No N/A Instance pool Best effort Yes (VM only, no DBU) No Reserved Instance No N/A Yes Savings Plan No N/A Yes CRG Yes, within SLA Yes No, but RI/SP can apply Serverless Platform-Managed No N/A Layer 2: Azure Databricks Platform The Azure Databricks control plane has its own published ceilings that your architecture must proactively respect. Key limits from the official Azure Databricks resource limits documentation: Resource Limit Scope Jobs created per hour 10,000 Workspace Tasks running simultaneously 2,000 Workspace (Run Job and For Each parent tasks excluded) Parent tasks running simultaneously (Run Job / For Each) 750 Workspace SQL warehouses 1,000 Workspace Attached notebooks or execution contexts 145 Cluster Virtual machines 25,000 Per subscription per region Note: For limits marked as non-fixed in the official documentation, you can request an increase through your Azure Databricks account team. Reference: https://learn.microsoft.com/en-us/azure/databricks/resources/limits Layer 3: Workload (Spark Execution) Even when both lower layers cooperate, Spark’s own execution model can produce capacity-like symptoms: Parallelism and task distribution, which dictate how many cores a job can usefully consume. Memory pressure from joins, shuffles, and skewed keys. IO demand and caching behavior, including Delta cache effectiveness and Spark cache misuse. Understanding these layers is critical. Retries sometimes succeed because capacity is dynamic: as other workloads complete, nodes are released back to Azure and briefly become available. Recognizing When You’ve Hit Capacity Capacity issues rarely present as a single clean error. Instead, they appear as inconsistent behaviors: Clusters stuck in Pending state Autoscaling fails or never reaches the desired size Jobs intermittently fail to start Retry attempts sometimes succeed These inconsistencies occur because capacity is shared across Azure tenants and fluctuates throughout the day. Running workloads outside peak business hours in the impacted region’s time zone is one of the most effective short-term mitigations. Inconsistent symptoms are not the same as unknowable ones. Before escalating, confirm what you are actually looking at. Several very different problems produce the symptoms above, and only one of them is a regional capacity shortage. 1. Where to look first Start with the cluster's termination reason and event log in the Azure Databricks workspace. Then cross-check the Azure Activity Log for the workspace's managed resource group over the same time window, which shows the VM allocation attempt and its result. 2. Match signal to the clause What you observe Points to Review What to do Cluster-provider launch or stockout failure Regional capacity for that VM size Immediate Actions, below Quota, core, or vCPU limit referenced Subscription quota, not capacity Request a quota increase — capacity may be fine VM size unavailable in the region or zone Availability restriction, not a transient shortage Switch VM SKU or Family below, retrying will not help Pool returns INSTANCE_POOL_MAX_CAPACITY_FAILURE A Databricks pool ceiling you configured Raise the pool's maximum capacity Cluster starts normally but jobs run slowly, spill, or OOM Workload design, not capacity Why Adding more Nodes is Not Always the Answer, below Only the first row is a genuine Azure capacity constraint. The others are resolved without any capacity conversations 3. Check quota before you conclude capacity Quota and capacity fail in similar ways but are resolved through entirely different paths. Compare current usage against the limit for the VM series and region in question. If usage is below the limit and allocation still fails, the constraint is regional capacity. If usage it at the limit, it is quota and an increase may resolve it outright. Immediate Actions: How to Unblock Your Workloads When you are actively hitting capacity constraints, speed matters. Please reach out to your Microsoft Account team and try these mitigations that are ordered from quickest to most involved. Retry and Run During Off-Peak Hours Capacity availability changes throughout the day as workloads complete and release VMs. Running outside peak business hours for the impacted region significantly improves success rates. Retrying is bounded, not unlimited. As a rule of thumb, retry two or three times across different hours, including at least one off-peak window in the impacted region's time zone. If the same VM size and region fall consistently across a full business day, stop treating it as transient; open a support ticket, engage your account team, and evaluate VM families in parallel. If the workload is production critical with a fixed deadline, or if failures are blocking a migration or cutover already in flight, escalate immediately without waiting for the retry window. Switch VM SKU or Family If a specific VM SKU is constrained, switching to another can immediately unblock provisioning. Move within the same family (for example, DSv4 → DSv5) Or switch families entirely (for example, D-series → F-series or L-series) Choosing the Right VM Family Most Databricks environments default to D-series (general purpose) and E-series (memory optimized). These are also the most heavily used and most capacity-constrained VM families. Consider alternatives based on your workload: VM Family Best For When to Use Trade-off D-series General workloads Default choice Often constrained in high-demand regions E-series Memory-heavy Spark jobs Joins, shuffles, analytics High demand; higher cost F-series CPU-intensive jobs Parsing, transformations Lower memory per core L-series IO-heavy workloads Delta caching, large datasets Higher cost; large local NVMe Practical decision framework: Memory-bound workloads (joins, shuffles): Move from E-series to L-series. Similar memory per core, plus large local NVMe for Delta caching. CPU-bound workloads: Move from D-series to F-series. Higher CPU performance at lower cost. IO-heavy or cache-sensitive workloads: L-series can significantly improve performance and reduce shuffle pressure. Implement Regional Diversity in your Databricks workload As Azure capacity constraints are region and SKU-specific, it is important to build architectural flexibility into your Databricks deployments. For critical or large-scale workloads, consider deploying multiple Databricks workspaces across different Azure regions to reduce dependency on any single region’s capacity. This approach enables: improved resilience to regional capacity constraints greater flexibility in workload placement Important: Multi-region deployment requires deliberate architecture, including deploying separate workspaces and replicating data and configurations across regions; it is not automatic. Why Adding More Nodes Is Not Always the Answer When jobs slow down, the instinct is to scale compute. With Spark, more nodes do not always solve the problem. Common workload issues that masquerade as capacity problems: Data skew Excessive shuffle operations Inefficient partitioning Overuse of UDFs In some workloads, shuffle operations can grow significantly larger than the original input data, placing substantial pressure on compute, memory, disk I/O, and network resources. Because shuffle workloads are distributed across the cluster, adding nodes can improve performance by increasing parallelism. However, that benefit reaches a limit when the bottleneck is caused by data skew, oversized shuffle partitions, network-intensive data movement, or data explosion from joins and aggregations. In these scenarios, the workload becomes constrained by the shuffle pattern itself, and simply adding more nodes does not address the root cause. Instead, the shuffle strategy, partitioning approach, or query design should be optimized. Smarter optimization strategies: Reduce shuffle through repartitioning and query optimization Enable Photon for faster execution Optimize Delta tables using Z-ordering and compaction Leverage caching strategically (not just Spark cache: use the Delta/disk cache) These optimizations can reduce your dependency on scarce VM capacity altogether. Review optimization strategies: The Complete Guide to Azure Databricks Cost Optimization | Microsoft Community Hub. What to Do When Your Capacity Is Approved Once Azure approves your capacity request, retaining it requires active steps. Because Azure capacity is dynamic and shared, approved capacity is held only while compute remains actively deployed and running. This is especially important in highly constrained regions. Microsoft recommends the following: Configure an Instance Pool For workloads that cannot yet use serverless compute, configure an Azure Databricks Instance Pool with a minimum number of idle nodes aligned to your production requirements. An instance pool pre-allocates and maintains a set of idle, ready-to-use VM instances. When a cluster is created from the pool, it draws from these warm nodes: eliminating the need to request new VMs from the regional Azure capacity pool between job runs. Key behaviors: The pool holds a minimum number of nodes continuously, keeping them warm and immediately available. Clusters attached to the pool pull from warm nodes, avoiding re-acquisition from Azure between runs. No DBU charges apply while nodes are idle in the pool. Azure VM infrastructure costs do apply for all minimum idle instances. Size the pool conservatively: aligned to production need only: to balance capacity retention against ongoing cost. Important: Instance pools hold idle nodes on a best-effort basis. Periodic platform events can recycle pool nodes, briefly causing the pool to fall below its configured minimum idle count while Azure re-acquires replacement nodes. Pools significantly improve availability and startup latency, but they do not change the fact that the underlying VMs are still requested from Azure on demand. They are not a hard reservation. Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/pools You can launch a pool's instances against an Azure capacity reservation group by setting the capacity_reservation_group field in the pool's azure_attributes to the group's resource ID. Configure it through the Instance Pools API or the Azure Databricks SDKs. The same requirements apply as for clusters: on-demand instances only, and only workspaces that use VNet injection. Designing for Resilience: Long-Term Best Practices To avoid repeated capacity issues, your architecture needs to evolve beyond reactive mitigations. Plan Ahead with Azure Capacity Reservation Groups For organizations running mission-critical Azure Databricks workloads, Azure Capacity Reservation Groups (CRGs) can provide additional predictability by reserving VM capacity in advance for your Databricks compute resources. Rather than competing for available regional capacity during periods of high demand, reserved capacity helps ensure that the required VM families are available when clusters need to scale or start, Reference: Databricks Clusters API documentation. Note: Before you commit to a reservation, know three things: Auto-termination stops saving VM costs. When a cluster terminates, its reserved capacity returns to an unused state and continues billing at the full VM rate. A pool backed by a reservation is not billed twice. If a team already pays for minimum idle pool nodes in a constrained region, a reservation at comparable spend converts best-effort capacity into SLA-backed capacity. Confirm that the cluster is actually using the reservation. Creating the reservation proves Azure set capacity aside, but it does not prove Databricks is drawing on it. Start a cluster, then check that allocated instances on the reservation rose by the expected node count. If it stays at zero, the usual causes are a VM size mismatch, availability not set to ON_DEMAND_AZURE, a workspace on the Databricks-managed VNet, or the RBAC actions never granted. Note also that omitting capacity_reservation_group when editing an instance pool silently clears it. Step-by-Step Instructions: Attaching a CRG to Databricks is done only through the Clusters/Instance Pools API or the Databricks SDKs, it is not available in the compute UI. Prerequisites VNet-injected workspace only. The workspace must be deployed into your own VNet. Workspaces on the default Databricks-managed VNet cannot use a CRG. On-demand instances only. The cluster/pool must use ON_DEMAND_AZURE availability. Spot and serverless are not eligible. Same region. Create the CRG in the same Azure region as the workspace. Matching VM size. Reserve the exact VM SKU(s) your cluster uses (driver and workers). Sufficient subscription quota for that SKU and core count. Go to the CRG resource -> Access Control -> Add role assignment and add the below roles to the workspace (i.e. databricks-login-prod) Enterprise Application: Microsoft.Compute/capacityReservationGroups/read Microsoft.Compute/capacityReservationGroups/deploy/action Microsoft.Compute/capacityReservationGroups/capacityReservations/read Microsoft.Compute/capacityReservationGroups/capacityReservations/deploy/action Step 1: Create the CRG and reservation in Azure az group create -l eastus -g myResourceGroup az capacity reservation group create \ -n myCapacityReservationGroup -l eastus -g myResourceGroup --zones 1 2 3 az capacity reservation create \ -c myCapacityReservationGroup -n myCapacityReservation \ -l eastus -g myResourceGroup --sku Standard_D2s_v3 --capacity 5 --zone 1 Note: If you want to create the CRG from the Azure Portal you can do the following: Set Subscription, Resource group, Name, and Region (use the same region as your Databricks workspace). Optionally pick Availability zones. Add one or more reservations: Reservation name, Instances (quantity), and VM size (match your cluster's driver/worker SKU). Example here: reservation-eadsv5, 5 × Standard_D4s_v3. Confirm the summary (price, basics, reservations), then click Create. Step 2 Attach the CRG to the cluster (Clusters API or SDK) This would be the Azure Databricks compute cluster, the Spark cluster you create inside your Azure Databricks workspace (Compute → Create compute, or a job cluster). You add an azure_attributes block to the cluster definition. The snippet below is a fragment that goes inside the cluster's JSON, alongside the normal cluster fields. You provide the CRG resource ID; Azure picks a matching reservation within the group. databricks clusters edit --json '{ "cluster_id": "<existing-cluster-id>", "spark_version": "15.4.x-scala2.12", "node_type_id": "Standard_D4s_v3", "num_workers": 4, "azure_attributes": { "availability": "ON_DEMAND_AZURE", "capacity_reservation_group": "/subscriptions/<subscription-id>/resourceGroups/<resource-group>/providers/Microsoft.Compute/capacityReservationGroups/<crg-name>" } }' The cluster's node_type_id (VM SKU) has to be the same VM size you reserved in the CRG (Step 1). If the reservation is Standard_D4s_v3, the cluster's node type must also be Standard_D4s_v3, or it won't draw from the reservation. For instance pools, set the same capacity_reservation_group field via the Instance Pools API or SDK (If you omit the field when editing a pool, Databricks clears any CRG already configured on it). Plan for Capacity Early Understand VM quotas and limits before you need them: not after a constraint occurs. Avoid designing a single SKU. Build flexibility into cluster configurations so you can switch families without re-engineering jobs. Standardize Compute Configurations Consistent, policy-driven environments make it easier to adapt when capacity constraints occur. Use Databricks Cluster Policies to constrain cluster creation to approved, available VM families: this prevents teams from inadvertently requesting constrained SKUs. Also, consider enforcing the CRG setting through a Databricks compute policy, so teams launch only against approved, reserved capacity. Move Toward Serverless Where Possible Serverless compute abstracts capacity management away from the customer. As the Databricks platform expands serverless support, migrating eligible workloads is the most durable long-term strategy. Azure continues to expand infrastructure capacity, but there are no guaranteed timelines for relief in constrained regions. Note: If your workload supports serverless compute, Databricks recommends using serverless compute instead of pools or classic VM-backed clusters. Serverless removes dependency on specific VM SKUs and regional capacity: scaling is managed by the platform with significantly improved availability. Reference: https://learn.microsoft.com/en-us/azure/databricks/serverless-compute. For eligible workloads: including Databricks Jobs (automated workflows), Databricks SQL Warehouses, and Delta Live Tables: serverless compute eliminates VM SKU dependency entirely. Configuration guidance is available in the Azure Databricks deployment guide, Development Section, Step 9. Multi-Region Strategy for Critical Workloads For the most critical workloads, evaluate a multi-region deployment as part of your business's continuity planning. This is a significant architectural investment: see the FAQ for the full scope: but it is the only approach that provides true regional redundancy. Coordinate this with your Microsoft account team. Reference: Azure Databricks & Microsoft Fabric Disaster Recovery: The Complete Better‑Together Strategy for Cloud Architects Know the Difference: Azure Capacity Reservations vs. Reserved Instances vs. Savings Plans When planning Azure infrastructure, it is important to separate capacity assurance from cost optimization. Although these options are sometimes discussed together, they solve different problems. On-Demand Capacity Reservations (ODCR) are designed to reserve compute capacity for workloads that need to run now. They are useful when an organization needs capacity for an eligible VM size in a specific region or availability zone. ODCRs generally offer flexibility because they do not require a long-term commitment and can be canceled when no longer needed. Future Capacity Reservations (FCR) support planned capacity requirements for a future need-by date. They are useful for migrations, major launches, seasonal events, and other predictable workload ramps that require advance capacity planning. In comparison, Azure Reserved VM Instances and Azure Savings Plans for Compute are primarily commercial constructs. Reserved Instances provide discounts for predictable, consistently running workloads through a one-year or three-year commitment. Savings Plans offer broader flexibility by applying discounts to eligible compute usage in exchange for an hourly spending commitment. The key takeaway is simple: capacity reservations address infrastructure availability, while Reserved Instances and Savings Plans address pricing. Organizations can use them together, pairing a capacity reservation with an applicable pricing benefit to improve both workload readiness and cost efficiency. Final Takeaways Capacity issues are infrastructure-level constraints, not Databricks product failures VM family selection is critical: do not rely solely on D-series and E-series Workload optimization can reduce dependency on scarce resources before requesting more capacity Serverless compute is Microsoft’s preferred long-term recommendation for eligible workloads Architectural flexibility: multi-SKU, multi-region awareness is your best defense against future constraints FAQ Why do retries work? Capacity in Azure regions is shared across all tenants and fluctuates throughout the day as workloads complete and release VMs. A retry succeeds when capacity temporarily frees up. Retrying during off-peak hours improves success rates significantly. Why does capacity fluctuate during the day? Capacity is a function of regional supply and concurrent demand. As workloads complete, nodes are released back to Azure. Peak business hours in the impacted region’s time zone tend to be the tightest windows. Why are instance pools not a hard reservation? Pools hold a minimum number of nodes on a best-effort basis. Periodic platform events recycle pool nodes, so a pool can briefly fall below its configured minimum idle count while Azure re-acquires replacement nodes. Setting minimum idle to 0 avoids paying for idle VMs at the cost of slower acquisition time. Pools significantly improve availability and startup latency but do not guarantee capacity at the Azure infrastructure level. Why does serverless behave differently from classic clusters? Serverless compute removes customer control over individual VM SKUs. Databricks manages the underlying capacity across a shared pool. SKU-swap and pool-based mitigations do not apply. Customer-side levers reduce to retry and off-peak scheduling. The trade-off is that serverless is the simplest and most reliable option when the workload supports it. Why is changing regions a last resort? Region changes require redeployment of the Azure Databricks workspace and migration of all dependent artifacts: jobs, clusters, libraries, networking (private endpoints, VNet injection), Unity Catalog assignments, identities, and source data. The destination region must be validated for the same SKU and zonal configuration. For these reasons, region change should always be coordinated with the Microsoft account team and attempted only after preferred mitigations have been exhausted. Why does VM family selection matter so much for capacity? Different VM families have different supply curves. D-series and E-series are the most requested Databricks worker families and the ones most frequently constrained. Choosing a SKU based on whether the workload is memory/shuffle-heavy, CPU-bound, or IO-heavy improves both performance and the probability that capacity is available. The capacity team often steers customers toward newer-generation alternatives when supply differs by generation version. What does the Microsoft account team actually do? They route the request into the Azure capacity intake process, advise alternate SKUs and regions, surface zonal vs. regional considerations, and provide forward visibility into known constraints. The customer’s job is to bring a complete, accurate workload profile so the account team can advocate effectively. It is also recommended to open an Azure Support ticket. This will save time later, as the capacity planning teams would like to track issues and requests via a support ticket. Once an Azure Support ticket is opened, the ticket number should be shared to the Microsoft Account Team, at a minimum to the Customer Success Account Manager (CSAM), if one is assigned to your organization.514Views1like0CommentsAn Azure Databricks data agent that never gets re-evaluated is a production model with no monitoring
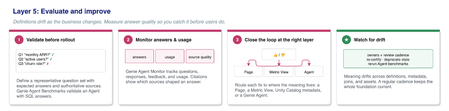
Every ML team has learned, usually the hard way, that a model left unevaluated after deployment will silently degrade: the data distribution shifts, the original assumption stops holding, and nobody notices until the wrong output has already done damage. What's strange is that the same discipline rarely shows up when the "model" in production is a conversational data agent. The team validates the Genie Agent with a handful of demo questions, approves it, ships it, and from that point on its accuracy becomes an article of faith instead of a tracked metric. Genie Ontology, the layered architecture Azure Databricks documented to give business context to data agents, has a final layer that exists precisely to close this gap: continuous evaluation and improvement, backed by a concrete mechanism called Genie Agent Benchmarks. It's worth understanding how it works, because it's the piece most likely to get skipped when a deadline is tight, and the most expensive one to be missing once the agent is already in production, quietly getting things wrong. The mechanism: two ways to measure "correct," depending on the question type A Genie Agent can hold up to 500 benchmark questions, each one running as an isolated conversation, with no thread context carried over, exactly as if a new user were asking for the first time. There are two evaluation modes, and the choice between them depends on the type of question: Chat mode: compares the SQL the agent generated (or its result) against a "ground truth" answer supplied by whoever wrote the benchmark. The rule is objective: identical SQL is "Good," an identical result set in a different sort order is also "Good," a number that matches to 4 significant digits also counts. An empty result, an extra column, or a diverging single-cell value is "Bad." The comparison covers up to 5,000 rows, so any question whose plausible result exceeds that needs an explicit ORDER BY on both sides to avoid a false negative caused by truncation. Agent mode: used when the response isn't a simple tabular result to compare, but a multi-step, text-based reasoning report instead. Here an LLM judge grades the response against an optional "evaluation note" that whoever wrote the benchmark provided, describing what the correct answer needs to contain. The mode is chosen at run time, not when the question is registered, so the same question set can be re-evaluated either way depending on the kind of response the agent is currently producing. My take: the detail I find most sensible about this design is that Chat mode rewards legitimate variation (different sort order, numeric precision) without rewarding structural error (an extra column, an empty result). A naive benchmark that demands byte-for-byte equality generates too much noise, flags a correct answer as wrong just because the agent sorted differently, and teams end up distrusting and ignoring their own benchmark over time. Calibrating the bar to separate "cosmetic difference" from "actual error" is what makes a team trust the number enough to act when it drops. Hands-on: registering benchmarks with phrasing variation A best practice the documentation calls out explicitly, and one that's easy to skip when benchmarks get registered in a hurry: the same business question rarely reaches the agent phrased the same way twice. A real user asks "what was last quarter's revenue" and "how much did we bill in Q3" about the same underlying data, and an agent that gets one phrasing right and the other wrong isn't actually reliable, even if a naive benchmark with only one phrasing reports 100% accuracy. The registration flow, done directly from the Benchmarks tab of the Genie Agent: Question 1: "What was total revenue for the last closed quarter?" Question 2: "How much did we bill in Q3?" Question 3: "Last quarter's revenue, what was it?" SQL Answer (same for all 3): SELECT SUM(order_amount) AS total_revenue FROM sales.orders WHERE fiscal_quarter = ( SELECT MAX(fiscal_quarter) FROM sales.orders WHERE closed_date IS NOT NULL ) The official recommendation is two to four phrasing variations per real business question. Running this set after any change to a Metric View or to an underlying term definition quickly shows whether the change broke one specific phrasing without breaking the others, a signal that would normally go unnoticed until a real user runs into it. The loop that closes itself: from benchmark back to agent context The real payoff isn't the isolated accuracy number, it's what happens after a benchmark run. Reviewing question by question doesn't scale, so the recommended flow uses Genie Code itself to analyze the entire run at once: it reviews what was expected, what the agent actually generated, and the agent's current context, then proposes instruction or context adjustments for each gap found, for whoever manages the agent to accept or reject individually. That same "batch review via Genie Code" pattern also applies to real usage, not just formal benchmarking: the agent's Monitor tab brings a weekly digest of message volume, active users, and positive/negative feedback rate, and the "Analyze Agent Usage" button launches Genie Code to comb through six months of real messages looking for recurring topics and repeated problems, with citations linking straight back to the original conversation. In practice, this means the signal for "where the agent is getting it wrong" comes from two complementary sources: the controlled benchmark, designed to cover what the team already knows matters, and real usage, which reveals what nobody thought to test. What this doesn't solve User feedback alone doesn't change agent behavior automatically, the documentation is explicit about this: someone with manage permission needs to review the feedback and decide whether it becomes a context adjustment or not, so a benchmark without periodic human review is still a mechanism gathering dust. Chat mode also depends entirely on the quality of the registered ground-truth SQL, a question with no SQL Answer falls into mandatory manual review, and a wrong ground-truth SQL silently teaches the agent to be wrong the "right" way. And the detailed result of an individual evaluation run stays visible for only one week, so anyone wanting to track an accuracy trend over months needs to export or log the number somewhere external, the tool doesn't keep long-term history on its own. Is it worth investing in this from day one? Registering benchmarks before the agent even reaches production can feel like redundant work when the initial demo already convinced everyone, but it's actually the opposite: the benchmark only earns its value later, when the Metric View changes, when a business term gets redefined, when the agent gains a new data source. Without an already-registered set of questions with known-correct answers, each of those changes demands manual validation from scratch. With it, the same question asked last time reruns in seconds, and the answer to "did this break anything" becomes a number instead of a guess. References Azure Databricks Blog (Databricks), "Operationalizing Genie Ontology in Your Data Stack": https://www.databricks.com/blog/operationalizing-genie-ontology-your-data-stack Microsoft Learn, "Test and monitor a Genie Agent - Azure Databricks": https://learn.microsoft.com/en-us/azure/databricks/genie-agents/monitor77Views0likes0CommentsThe Gap Between Applications and Analytics, and "How Lakebase Solves It"
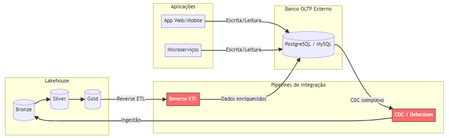
The Problem Nobody Likes to Admit. Imagine this scenario: your data team has built a flawless lakehouse. Ingest pipelines, bronze/silver/gold tiers, gleaming dashboards. Everything is working perfectly. Until someone asks: "And the production app? Where does it store the transactional data?" That's where the headache begins. You need a separate OLTP database (Postgres, MySQL, DynamoDB...), CDC pipelines to bring data into the lakehouse, reverse ETL to return enriched data to the app, and an infrastructure team to keep it all running. The result? Data silos, synchronization latency, operational complexity, and ever-increasing costs. Traditional Architecture (and Its Pain Points) Here's how most companies operate today: Pain points in this architecture: Multiple tools and suppliers for managing Significant latency between writing on OLTP and availability on Lakehouse. Fragmented governance — Unity Catalog doesn't see the external bank. High operational costs associated with synchronization pipelines. What is Lakebase? Lakebase is a fully managed Postgres database natively integrated with the Databricks Data Intelligence Platform. It is designed to bridge the gap between transactional (OLTP) and analytical (OLAP) workloads, unifying everything into a single ecosystem . In simple terms: it's like having a high-performance Postgres server living inside your lakehouse , with unified governance via Unity Catalog, native bidirectional synchronization, and modern capabilities such as autoscaling, scale-to-zero, and database branching. The New Architecture with Lakebase: What changes? Zero external database infrastructure Native bidirectional synchronization (no Debezium, no Airflow, no pain) Unified governance through the Unity Catalog A single control plane for OLTP + OLAP The Architectural Innovations of Lakebase Lakebase is not "just another managed Postgres." It brings modern data engineering concepts to the transactional world. 1. Separation of Compute and Storage Unlike traditional data banks where CPU and disk are coupled, Lakebase completely separates computing resources from storage. This means you scale each independently, paying only for what you use. 2. Copy-on-Write Storage The storage system uses a copy-on-write approach. In practice, when you create a branch of the database, there is no data duplication —only the changes are stored separately. This makes operations like branching and restoring virtually instantaneous. 3. Autoscaling and Scale-to-Zero The compute system automatically adjusts its capacity based on demand. During periods of inactivity, the database scales to zero , eliminating costs. When a request arrives, it "wakes up" in seconds. Database Branching: Git for Your Data This is probably the most innovative feature. Just as developers create branches in Git to work on isolated features, Lakebase allows you to create branches for the entire database . Powerful use cases: Development : each developer has their own branch of the database, without interfering with production. Migration testing : test schema changes in an isolated branch before applying them to production. Instant Restore : Restore the database to any point in time (configurable window from 0 to 30 days) by creating a branch from that point. Two-Way Synchronization: The End of Reverse ETL One of the biggest advantages is the native synchronization between Lakehouse and Lakebase: Synced Tables (Lakehouse → Lakebase) Unity Catalog tables are automatically synchronized to Lakebase, allowing applications to query rich analytical data with low latency. Supports Snapshot, Triggered, and Continuous modes. Lakehouse Sync (Lakebase → Lakehouse) Transactional data from Lakebase is continuously replicated to Delta tables in the Unity Catalog using Change Data Capture (CDC). The destination tables follow the SCD Type 2 standard , maintaining a complete history of changes. This completely eliminates the need for: External CDC tools (Debezium, Fivetran) Reverse ETL pipelines (Census, Hightouch) Custom synchronization jobs in Airflow/Prefect Three Strategic Use Cases Feature Serving for Real-Time ML Lakebase functions as an online store for Databricks' Feature Store. Features computed in the lakehouse are synchronized via Synced Tables to Lakebase, from where ML models query them with millisecond latency. State of AI Agents AI agents need to persist state between requests — conversation context, action history, workflow data. Lakebase provides a native transactional database to store this state with ACID consistency. Transactional Data for Applications Databricks Apps (or any external application) can use Lakebase as their primary database. The integration is native: simply add the Lakebase project as a resource in your app. Additionally, the Data API offers a PostgREST-compatible REST interface for direct HTTP access. Comparison: Before and After Availability Lakebase Autoscaling is available in the following AWS regions: us-east-1, us-east-2,us-west-2 ca-central-1, sa-east-1 eu-central-1, eu-west-1,eu-west-2 ap-south-1, ap-southeast-1,ap-southeast-2 The presence in sa-east-1 is particularly relevant for us in the Brazilian community, ensuring low latency for applications hosted in Brazil. Conclusion Lakebase represents a paradigm shift: instead of treating OLTP and OLAP as separate worlds that need complex "bridges," it unifies them into a single platform. For Brazilian data teams, this means: Fewer tools to manage and integrate. Fewer pipelines that silently break down at 3 a.m. More time focused on generating value with data. Real governance across the entire data lifecycle — from transactional writing to the executive dashboard. Lakehouse finally has its native transactional database. And it speaks Postgres. This post was inspired by concepts from the official Databricks documentation. For more technical details, please refer to the Lakebase documentation . Wiliam Rosa Data Engineer | Machine Learning Engineer linkedin.com/in/wiliamrosa Blog: https://wiliamrosa.github.io325Views1like3CommentsSystem Table Retention Is Now Your Choice, Not a Fixed Number
Long-term auditing based on system tables has always faced the same challenge: sometimes, the data simply wasn't available for as long as organizations needed it. Azure Databricks has introduced, in Beta, configurable retention for supported system tables, giving account administrators greater control over how long historical system data is retained. Instead of relying only on the platform's default retention period, administrators can now configure retention from 30 to 3,650 days — up to approximately 10 years. This is particularly relevant for organizations using system tables for FinOps, auditing, governance, security investigations, usage analysis, and long-term operational analytics. Official documentation: https://learn.microsoft.com/en-us/azure/databricks/admin/system-tables/ What changes with configurable retention? When configurable retention is enabled, supported system tables can use an account-level retention configuration. The main characteristics are: Retention can be configured from 30 to 3,650 days. The configuration is managed at the Databricks account level. An account administrator is required to manage the setting. The configuration applies only to system tables that support configurable retention. During the Beta period, configurable retention is available without additional retention storage charges. When the feature is enabled, supported system tables receive 395 days of retention by default. This gives organizations considerably more flexibility when designing long-term governance and observability strategies around system tables. Configuring retention using the API In addition to managing retention through the Databricks Account Console, account administrators can configure it programmatically using the Databricks Account Settings API. The setting responsible for system table retention is called: st_retention Administrators can then change the retention period using a PATCH request. For example, the following configuration sets the retention period to 400 days: curl --request PATCH \ --header "Content-Type: application/json" \ --header "Authorization: Bearer $token" \ --data '{ "integer_val": { "value": 400 }, "name": "st_retention" }' \ "<account-console-url>/api/2.1/accounts/<account-id>/settings/st_retention" This is particularly useful for organizations that manage their Databricks environments using automation and Infrastructure as Code practices, since retention policies can become part of a broader governance process. Official documentation: https://learn.microsoft.com/en-us/azure/databricks/admin/system-tables/ Increasing and decreasing retention behave differently Azure Databricks also includes an important protection mechanism when changing retention settings. When administrators increase the retention period, the new configuration takes effect immediately. However, when administrators decrease the retention period, Azure Databricks provides a seven-day grace period before applying the reduction. This provides an opportunity to correct an accidental configuration change before historical data is permanently removed. For example: Current retention: 1,000 days New retention: 365 days Grace period: 7 days During this grace period, an administrator can reconsider or correct the configuration before the shorter retention policy takes effect. Records that exceed the configured retention period are generally removed within approximately one week after becoming eligible for deletion. Increasing retention does not restore deleted data There is another important behavior to understand. Increasing the retention period does not restore historical records that have already expired or been removed. For example, imagine that an organization previously retained system table information for 365 days. Later, the administrator changes the configuration to: 3,650 days This does not cause Azure Databricks to recreate or backfill data from previous years. The new retention period applies to data that is still available and to data generated going forward. Therefore, organizations that require long-term auditing should define their retention strategy before historical information becomes unavailable. Not every system table supports configurable retention Configurable retention does not currently apply to every system table. According to the current documentation, tables in the following schemas are excluded: system.data_classification system.data_quality_monitoring These system tables continue to follow their own retention policies. Because this capability is currently in Beta, supported tables and behavior may evolve as the feature moves toward General Availability. Always check the latest documentation before defining production retention policies: https://learn.microsoft.com/en-us/azure/databricks/admin/system-tables/ What about cost? During the Beta period, configurable system table retention is available without additional retention storage charges. However, Databricks states that when the feature becomes Generally Available (GA), data retained beyond 395 days will be subject to storage charges. This turns retention into more than just a technical configuration. It becomes a FinOps and governance decision. For example, configuring: Retention = 3,650 days means maintaining approximately 10 years of system table history. That could be extremely valuable for regulatory auditing, historical usage analysis, security investigations, or long-term FinOps analysis. But organizations should evaluate whether that historical depth provides enough business value to justify the associated storage cost once the capability becomes generally available. Why does this matter? System tables provide operational information about the Databricks environment and can support use cases such as: Cost and usage analysis FinOps dashboards Audit analysis Security investigations Governance monitoring Query history analysis Compute monitoring Marketplace activity Data sharing activity Operational observability For many organizations, 395 days may be enough. For others — especially organizations operating in highly regulated environments — retaining several years of historical information can be an important compliance requirement. The possibility of configuring up to 3,650 days allows the retention strategy to better reflect the organization's actual governance requirements. A governance decision, not just a configuration The most interesting aspect of this feature is that system table retention is becoming an explicit architectural decision. Instead of simply accepting a predefined retention period, Data Platform teams can ask: How much history do we actually need? Which system tables are important for auditing? What are our regulatory requirements? How much historical data is useful for FinOps? What will be the storage impact? Who should be allowed to change the retention policy? These questions move system table retention from a platform limitation into the organization's Data Governance and FinOps strategy. A reasonable approach is to define retention according to the purpose of the data rather than automatically selecting the maximum available value. Final thoughts Configurable system table retention may look like a relatively small platform feature, but it solves a very practical problem. Teams often build dashboards, audit processes, FinOps reports, and operational analytics on top of system tables only to discover later that the historical information they need is no longer available. With configurable retention, Azure Databricks provides organizations with much more control over this lifecycle. The possibility of retaining system table information for anywhere between 30 days and 3,650 days makes it possible to align historical availability with business, regulatory, security, and operational requirements. At the same time, the maximum value should not automatically become the default. Retention is now a choice — and that choice should be part of your Data Governance strategy. References Azure Databricks — System tables: https://learn.microsoft.com/en-us/azure/databricks/admin/system-tables/ Azure Databricks documentation: https://learn.microsoft.com/en-us/azure/databricks/ Databricks System Tables documentation: https://docs.databricks.com/aws/en/admin/system-tables Databricks September 2026 product release notes: https://docs.databricks.com/aws/en/release-notes/product/2026/september105Views0likes0CommentsGenie's answer in Slack now ships with the actual chart, not just text
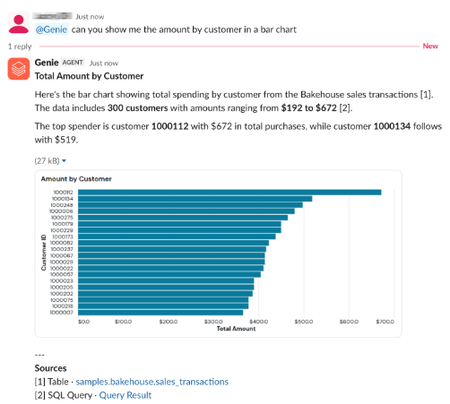
Asking Genie a question in Slack and getting a text-only table where a chart should be always left the answer half finished. Azure Databricks now renders Genie's visualizations directly as images inside the Slack conversation, in public preview. Before this, whenever Genie's answer included a chart, the visual content was limited to whatever could be represented as plain text inside the thread. Now the chart actually shows up as an image alongside the answer, complete with a View in Genie button that opens the full conversation in Azure Databricks for more context. Anyone who had already installed the Genie app for Slack before this release needs to reinstall the app to enable the new behavior. The specific reason is a permission gap: rendering a chart as an attached image requires the files:write Slack permission, which the app didn't originally request, so the existing installation simply can't attach image files until it's reinstalled and re-authorized. One detail worth knowing before you go looking for a missing chart: visualizations never show up when message visibility is set to private, since a private reply is only visible to the person who asked. So if a chart seems to be missing, check the visibility setting before assuming the reinstall didn't work. Technical points: Genie's chart output now renders as an image in the Slack thread, not just as text The feature is in public preview A previous installation of the Genie app for Slack needs to be redone specifically to grant the files:write permission Visualizations are suppressed entirely when message visibility is set to private, regardless of install state For teams that want to track how much of this traffic is coming through Slack in the first place, Azure Databricks logs every Genie request with its origin in the audit system table. This query pulls Slack-originated requests from the last five days: SELECT event_time, user_identity.email AS user_email, request_params.conversation_id AS conversation_id FROM system.access.audit WHERE service_name = 'genieChat' AND action_name = 'createGenieChatResponse' AND request_params.source = 'slack' AND event_date >= date_add(current_date(), -5) ORDER BY event_time DESC My take: it's a small adjustment, but it fixes a real friction point for anyone who uses Genie through Slack as their main channel for querying data, instead of opening the workspace every time they need to check a number. The thing to watch is operational, not technical: since the change requires manually reinstalling the app for a permission it never had, teams that don't follow release notes closely will keep getting chart-less answers until someone notices, and the audit log query above is a decent way to check who's actually using the Slack integration before you go chasing that reinstall. Source: https://learn.microsoft.com/en-us/azure/databricks/genie-one/genie-slack78Views0likes0CommentsDetecting corrupted data in under 1ms: what changes when Spark stops waiting for the micro-batch
Streaming anomaly detection almost always runs into the same wall: the micro-batch. Traditional Structured Streaming processes data in one-to-two-second windows, which is fast enough for most use cases, but terrible when the very act of waiting for the batch to close is already too late. Fraud, sensitive payload validation, corrupted data entering a critical pipeline, these scenarios can't tolerate even a second of structural delay. Apache Spark's Real-time mode exists to attack exactly that gap, and Databricks published an experiment that uses a concrete use case to prove the point: analyzing Ethereum transactions in real time. For Azure Databricks practitioners, this experiment is particularly relevant because it explores improvements at the Apache Spark execution layer that could benefit real-time data engineering workloads. More broadly, it points toward lower-latency streaming scenarios while preserving the Spark ecosystem already familiar to teams building batch and streaming pipelines on Azure Databricks. What structurally changes in Real-time mode Unlike the micro-batch trigger, Real-time mode processes data as it arrives, without waiting for a window to close. That's possible through three combined architectural changes: a continuous flow of data between stages (instead of materializing an intermediate result on every batch), scheduling all stages of the query simultaneously (instead of scheduling stage by stage), and an in-memory streaming shuffle between stages, eliminating the cost of writing and reading shuffle files on every round. In practice, this brings Spark Structured Streaming closer to a continuous processing model, something historically associated with engines like Flink, but within the same runtime that already runs the rest of your organization's batch and streaming pipeline. The experiment: Ethereum transactions as a stress test The Databricks team built a pipeline that ingests blocks and transactions from the Ethereum network and classifies each event as ALLOW or QUARANTINE, based on two checks: Protocol invariant validation: a block where gas_used is greater than gas_limit is logically impossible under the Ethereum protocol's own rules, so it becomes an automatic signal of corrupted or malformed data. Payload hygiene: the block's extra_data field is scanned for patterns that shouldn't be there, such as a fragment of PII, a JWT token, or an AWS access key leaked by accident. The cluster used was Databricks Runtime 16.4 LTS, four i3.xlarge workers, a dedicated (single-user) cluster, with Photon deliberately disabled to isolate the effect of Real-time mode itself. The numbers behind the promise Sustained input rate of approximately 65,592 rows per second. Sustained processing rate of approximately 69,713 rows per second (the engine was able to absorb the input without building up backlog). More than 23.2 million messages processed over the course of the experiment. P95 latency under 0.5 millisecond. P99 latency of 1 millisecond. For context: a traditional 1-2 second micro-batch represents a three-order-of-magnitude difference in detection latency. If the goal is to stop a suspicious transaction before it propagates, that difference isn't cosmetic. Hands-on: a skeleton for real-time classification The "classify and route" pattern described in the experiment can be reproduced on any structured event schema. Here's a simplified example using transformWithState, the operator that gives you access to custom stateful logic inside Structured Streaming: from pyspark.sql.streaming import StatefulProcessor, StatefulProcessorHandle from pyspark.sql.types import StructType, StructField, StringType, LongType class BlockValidator(StatefulProcessor): def init(self, handle: StatefulProcessorHandle): self.handle = handle def handleInputRows(self, key, rows, timer_values): for row in rows: status = "ALLOW" if row["gas_used"] > row["gas_limit"]: status = "QUARANTINE" elif self._contains_sensitive_pattern(row["extra_data"]): status = "QUARANTINE" yield {"block_id": row["block_id"], "status": status} def _contains_sensitive_pattern(self, payload: str) -> bool: markers = ["AKIA", "eyJhbGciOi", "-----BEGIN"] return any(m in (payload or "") for m in markers) query = ( spark.readStream.table("bronze.eth_blocks") .groupBy("block_id") .transformWithState( statefulProcessor=BlockValidator(), outputStructType=StructType([ StructField("block_id", LongType()), StructField("status", StringType()), ]), ) .writeStream .trigger(availableNow=False) # real-time trigger is configured at the cluster/runtime level .toTable("silver.eth_blocks_classified") ) Worth reinforcing: enabling Real-time mode itself depends on runtime- and cluster-level configuration, it's not just a matter of swapping the trigger in the API, so the official reference documentation should be consulted before running this in production. In practice: I'd test this kind of pipeline under real load spikes, not just a constant rate, before blindly trusting the p99 number. Real Ethereum network traffic has much more irregular transaction bursts than a synthetic constant-throughput test, and it's under bursts that any low-latency system tends to reveal its real queueing behavior. Why Ethereum was a smart benchmark choice It's worth pausing for a moment on why Ethereum was chosen as the test scenario, because it isn't obvious at first glance. Ethereum transactions have two properties that make them an honest stress test for an anomaly detection system: first, the volume is public and replicable, anyone can audit the dataset used, which reduces the chance of an artificially favorable benchmark. Second, and more important, the protocol's invariant rules (like gas_used never being allowed to exceed gas_limit) are known and deterministically verifiable, so there's no ambiguity about what counts as a real anomaly versus a false positive. That removes a confounding variable common in anomaly-detection benchmarks, where the very definition of "anomaly" is already subjective. Applied to a corporate scenario, the equivalent would be having clear, auditable business rules (credit limit, expected value range, field format) before trying to apply this kind of real-time classification; without that, the technical pipeline works fine, but classification quality collapses. What this doesn't solve Real-time mode drastically reduces processing latency, but it doesn't replace the need for a good response strategy for suspicious data. Classifying something as QUARANTINE in one millisecond is pointless if the human or automated process that handles that alert still takes minutes or hours to act. It's also important to note the documented limitations of transformWithState in real-time mode: transformWithStateInPandas isn't supported in this mode, and state management (timers, TTL) has its own rules that differ from the traditional micro-batch mode, which requires extra care when migrating an existing pipeline. Wrapping up The Ethereum experiment works as a proof of concept for something broader: once Spark Structured Streaming itself can operate in the millisecond range, scenarios that used to require leaving the Spark ecosystem (fraud, critical validation, immediate operational alerting) start to fit inside the same runtime that already processes the rest of your data pipeline. It's worth testing, but with a realistic expectation of what still depends on human decision-making and response after detection. References Ultra-fast anomaly detection using Apache Spark Real-Time Mode (https://www.databricks.com/blog/ultra-fast-anomaly-detection-using-apache-spark-real-time-mode) (official Databricks blog) Apache Spark Structured Streaming Real-Time Mode: concepts (https://docs.databricks.com/aws/en/structured-streaming/real-time/concepts) (official documentation) Real-time mode concepts (https://learn.microsoft.com/en-us/azure/databricks/structured-streaming/real-time/concepts) (Microsoft Learn) Stateful applications with transformWithState (https://docs.databricks.com/aws/en/stateful-applications/) (official documentation) Build a custom stateful application with transformWithState (https://learn.microsoft.com/en-us/azure/databricks/stateful-applications/) (Microsoft Learn)199Views0likes0CommentsBefore Opening Grafana: How Azure Databricks Uses an AI Agent to Investigate Its Own Incidents
Any on-call engineer who has ever been woken up by an alert in the middle of the night knows the routine: open the dashboard, correlate logs from three different services, check whether there was a recent deployment, review metrics from upstream dependencies, and only after spending twenty minutes putting all that context together actually start investigating the root cause. Azure Databricks measured this internally and found an uncomfortable number: 60% to 80% of incident investigation time is not spent finding the root cause, it is spent gathering the context required to start looking for it. AI SRE, an internal agent recently documented by Azure Databricks, targets exactly this inefficiency. The core idea is not to replace engineering judgment. Instead, it eliminates the mechanical work of gathering context before that judgment can happen, running in parallel and within seconds what would otherwise take a human several minutes to assemble manually. The Mechanism: Three Parallel Tracks, Evidence Before Conclusions When an incident is triggered, AI SRE does not wait for an engineer to request information. It immediately starts three investigations in parallel. Platform health checks: It verifies cloud infrastructure, networking, and upstream dependencies, quickly ruling out causes outside the team's code, such as an availability zone experiencing issues or an external provider being unavailable. Service-level analysis: It examines logs, metrics, traces, recent deployments, and configuration changes related to the specific service involved in the alert. Runbook execution: It runs workflows that the team has already documented as "what an expert would check for this type of failure," converted into agentic runbooks. The design principle connecting these three tracks is explicitly stated by the team: "Structured checks before open-ended reasoning." This means AI SRE first performs deterministic platform checks and runbook steps, and only then passes the raw results to the LLM layer for synthesis and explanation, never the other way around. Data collection is not left to the model's judgment. It happens first, following a predefined process. Every final recommendation is tied to the evidence supporting it and can be traced back to the specific check that generated it, rather than being a loose model inference about what "probably" happened. My take is that this is the kind of architectural decision that becomes obvious only after someone has experienced the opposite approach. An agent that immediately starts "open-ended reasoning" over logs and metrics without deterministic checks first can sound convincing even when it is wrong. And during an incident, a convincing but incorrect root-cause hypothesis can delay the actual resolution. Making "data first, interpretation second" an architectural rule rather than an optional best practice is what makes this type of agent reliable enough to operate without constant supervision. Hands-On: Turning an On-Call Checklist into an Agentic Runbook One of the most reusable ideas outside Azure Databricks' internal environment is the runbook mechanism itself. It is built on top of Genie Code's public skills system (.assistant/skills/), the same mechanism used to teach business logic to data agents. Any team using Azure Databricks can apply the same approach to its own incident-response process by converting an informal checklist into a skill: Workspace/.assistant/skills/incidente-fila-kafka-atrasada/ └── SKILL.md --- name: incidente-fila-kafka-atrasada description: Runbook para lag alto no consumer group de streaming. Use quando o alerta mencionar consumer lag, offset atrasado ou fila de eventos acumulando. --- Checagem, na ordem: 1. Consultar `lag_by_partition` no painel de métricas do consumer group; lag acima de 500 mil mensagens em qualquer partição é o limiar de atenção. 2. Verificar se houve deploy do consumer nas últimas 2 horas (causa mais comum: handler novo mais lento que o anterior). 3. Se não houve deploy, checar throughput do broker de origem; partição com lag isolado numa única partição indica hot partition, não problema de consumer. 4. Mitigação padrão: escalar réplica do consumer group primeiro, nunca aumentar partição em produção sem aprovação, isso reembaralha o particionamento existente. Once documented this way, the knowledge no longer lives only in the head of the engineer who has solved that incident before. It becomes executable automatically the next time the alert fires. That is exactly the effect of the agentic runbook approach used internally by AI SRE, but the underlying pattern can already be applied by other teams without waiting for access to Azure Databricks' internal tooling. The Work Nobody Sees: Giving the Agent Access Without Creating a Security Risk The least glamorous part of the project, and the one the Azure Databricks team says required more engineering effort than designing the agent itself, was rebuilding the API layer that gives the agent access to the company's observability systems. The reason is straightforward. An agent that can freely query logs, metrics, and traces can also, if poorly configured, generate enough query volume to overload the very observability infrastructure supporting critical production alerts. There would be a certain irony in a reliability agent becoming the cause of a reliability incident. The team therefore had to implement rate limits, permission scopes, and sufficient guardrails to keep the agent fast without allowing it to become a source of incidents itself. This lesson extends far beyond AI SRE. Any agent project with broad access to production systems carries the same second-order risk, and designing the necessary guardrails often requires more engineering effort than implementing the agent behavior they are meant to protect. Underestimating this part is one of the most common reasons internal agent projects get stuck during the security phase after already working well as proofs of concept. What This Does Not Solve AI SRE does not eliminate the need for well-written runbooks. It simply executes more quickly what the team already knows how to do. If nobody has documented the checklist for a new type of incident, there is no runbook to execute. The agent then falls back to generic platform and service-level checks without the shortcut provided by the team's specific operational knowledge. The architecture also assumes broad access to the company's observability layer. According to the Azure Databricks team, redesigning the API to provide this access with sufficient guardrails to avoid impacting critical monitoring infrastructure required more engineering effort than building the agent itself. It is also important to remember that AI SRE is an internal Azure Databricks tool. There is currently no equivalent public product that can simply be installed and enabled. What teams can replicate today is the architectural pattern: structured checks before reasoning, and runbooks implemented as version-controlled skills. Final Thoughts The real improvement here does not come from having a smarter model interpret an incident. It comes from eliminating the time engineers spend assembling context before they can even begin interpreting what happened. For any platform team that already maintains a wiki full of "how to solve X" procedures, often known only by the people who have encountered that incident before, the natural next step is similar to what Azure Databricks describes internally: turn that knowledge into version-controlled, executable runbooks and let deterministic checks run before any open-ended reasoning layer enters the process. References Databricks Blog - How Databricks Uses AI to Accelerate Incident Investigation Databricks Documentation - Extend Genie Code with agent skills123Views0likes0CommentsHow to Secure Azure Databricks without Public Exposure using WAF + Private Endpoints
This blog outlines a Zero Trust–aligned architecture for securing Azure Databricks using Application Gateway (WAF) and Private Endpoints within a Hub-Spoke network model. Enables a true Zero Trust model, ensuring: No direct exposure of Databricks Full traffic inspection Compliance-ready secure access for both internal and external users Integration of Azure P2S to cater the Databricks OAuth URL.2.6KViews1like2Comments