azure blob
67 TopicsAzure Native Commvault Cloud is now generally available
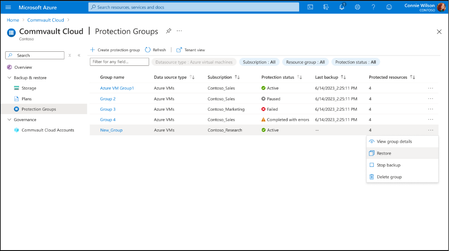
As you modernize critical applications and adopt AI, protecting and recovering data becomes essential to innovation. New AI-powered experiences depend on the availability and integrity of the systems and data behind them. Protection needs to fit how teams operate in Azure, with clear policies and practical recovery options when disruption occurs. Azure Native Commvault Cloud is now generally available as an Azure Native ISV service. The service brings Commvault backup and recovery for Azure virtual machines into the Azure portal, with data-protection resources managed as Azure resources and applicable Commvault charges included on your Azure bill. This gives you another option for protecting business-critical workloads in Azure, combining Commvault's data-protection capabilities with a familiar Azure management experience. A familiar Azure experience for protecting virtual machines Built jointly by Microsoft and Commvault, this integration goes beyond Marketplace purchase and deployment. From Azure, you can configure backup storage, define protection policies, and run supported backup and recovery operations. After setting up identity and access, create a Commvault Cloud account to connect your Azure subscription and Commvault tenant, then configure storage, backup plans, and protection groups. In the Azure portal, you can view protection groups, check protection status and backup details, and take group-level actions. Azure Native Commvault Cloud protection groups in the Azure portal, showing protection status, backup information, and group-level actions. With this integration, you can protect and recover Azure VMs directly from Azure: Apply consistent protection policies. Backup plans specify where backup data is stored, how often full or incremental backups run, and how long backups are retained. Protection groups associate selected virtual machines with those plans. Policy-based protection helps keep recovery readiness continuous as Azure environments change. Discover and protect VMs as your environment grows. During protection-group configuration, you can discover virtual machines and select them manually or define rules to include or exclude resources. You can preview the results before applying a rule to check that the intended VMs are included. Each time the protection group runs, it automatically brings newly matching VMs under the group’s protection plan, helping you maintain coverage as your Azure environment expands. Recover at the scope the situation requires. Individual or multiple VMs can be recovered from a protection group. From an available recovery point, you can restore to a disk attached to an existing VM or recover a full virtual machine, either in place or to a new VM. You can also start an on-demand backup without waiting for the next scheduled run. Strengthen cyber resilience. Immutable, air-gapped backup protection helps safeguard recovery data from ransomware, accidental deletion, and malicious modification. The integration uses a managed identity for supported workload-protection operations and maps Microsoft Entra groups to Commvault roles. Supported backup and recovery actions are available in the Azure portal, while Commvault Command Center provides detailed job information and troubleshooting. A team responsible for protecting a group of Azure VMs, can manage the protection policy, resource selection, and recovery action through a consistent and familiar Azure workflow rather than as disconnected administrative tasks. Extending our investment in partner-led resilience Microsoft and Commvault have worked together for more than 25 years. In our 2026 Azure Storage outlook, we described our investment in co-engineered partner solutions, including Commvault, that go beyond Marketplace availability to deliver more deeply integrated services. This launch puts that strategy into practice for backup and recovery. Commvault brings its experience in data protection and cyber resilience; Azure brings the platform and resource-management experience you already use. Together, we are giving you more choice in how you protect critical workloads, so resilience can evolve alongside your investments in cloud and AI. “Azure Native Commvault Cloud reflects how customers want to consume enterprise recovery today: through the cloud platforms they already trust and operate every day. By bringing Commvault's recovery, resilience, and cyber protection capabilities directly into Azure, we're helping organizations simplify protection, strengthen recovery readiness, and give teams greater confidence as they modernize critical workloads, data platforms, and AI-powered applications,” said Rajiv Kottomtharayil, Chief Product Officer, Commvault. Get started with Azure Native Commvault Cloud Explore Azure Native Commvault Cloud on Microsoft Learn and follow the getting-started guidance to prepare identity and access, connect your Azure subscription, and configure protection for Azure virtual machines.90Views0likes0CommentsFaster, Secure Reads for AI Workloads: Session-Based Authentication Now in Preview for Azure Blob
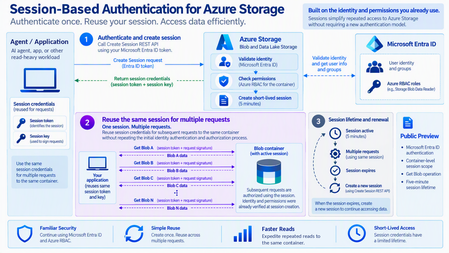
Data continues to grow exponentially on Azure Blob and Azure Data Lake Storage for a wide range of workloads: AI training and inference, agentic AI, analytics, high-performance computing, and backup and recovery. Azure Blob and Azure Data Lake Storage are the foundations of these exabyte-scale data estates, and agentic AI is now fundamentally changing how that data is accessed and used. Azure Storage has always offered granular access control and strong auditing for access to the data. Every request can be authenticated with a Microsoft Entra ID identity, authorized with Azure role-based access control (RBAC) and attribute-based access control (ABAC) conditions, and recorded in Azure Storage diagnostic logs. The same controls apply to AI agents. What is changing is scale. AI and agentic workloads issue large volumes of read requests, often across many objects in the same container, resulting in increased latency for authentication and authorization. To meet those demands, we are introducing a new authentication method that reduces per-request latency while preserving the security controls organizations already rely on. Today, we are excited to announce that session-based authentication is now in public preview for Azure Blob and Azure Data Lake Storage, in all public Azure regions. With session-based authentication, an agent or application authenticates once with Microsoft Entra ID, establishes a short-lived session for a container, and uses that session for subsequent reads. It brings three benefits: Improved performance. Identity and permissions are verified once when the session is created. Subsequent read requests to the container use that session which reduces per-request authentication and authorization latency. The same least privileged access, now short-lived. Sessions use your organization’s existing permission model for least privileged access, Azure RBAC and Azure ABAC. Each session is also scoped to one container, expires after five minutes, is bound to the client that created it, and requires every request to be signed. Full traceability. Azure Storage diagnostic logs currently record the Microsoft Entra ID identity behind each request, and the same is true with sessions. With sessions, every request remains tied to the Microsoft Entra ID identity that created the session, so security teams keep visibility into which identity, human or agent, accessed what data, and when. With the Azure Storage SDK, enabling session-based authentication is a simple client configuration option, with no changes to your application logic. Whether you are grounding AI in your company’s knowledge, giving agents access to your data, or feeding a training pipeline, session-based authentication helps you read data faster while preserving security. Read on to learn how sessions work, which workloads benefit most, and how to get started. How session-based authentication works When you call the Create Session REST API, Azure Storage verifies your Microsoft Entra ID identity, checks RBAC permissions and ABAC conditions, starts a five-minute session, and returns session credentials. The session credentials consist of two parts: A session token, which identifies the session. A session key, which your client uses to sign each request made within the session. For subsequent requests to the same container, your client sends the session token together with a signature computed with the session key, instead of a Microsoft Entra ID token. Because identity and permissions were already verified when the session was created, per-request authentication and authorization latency is reduced. Sessions are also bound to the network context of the client that created them, which helps prevent a captured token from being replayed by another client and every request is logged to the diagnostic logs. For this preview, session tokens are supported only for the Get Blob operation; all other operations require a Microsoft Entra ID access token. The Azure Storage SDKs handle this automatically. To learn more, see the Session Based Authentication documentation. Workloads that benefit from using session-based authentication Session-based authentication is a good fit for read-heavy, latency-sensitive workloads that make many requests to the same container using the same identity. These workloads benefit from higher throughput and transaction rates, with lower latency. Examples include: AI training and inference: Training pipelines repeatedly read dataset shards, images, and other inputs, while inference services load model artifacts and supporting data. Inferencing agent: Accelerates data insights to support faster business decisions. AI ops log-investigation agent: Quickly detects anomalies and raises alerts to speed remediation. Analytics: Query engines and processing jobs read many files or portions of files in parallel to filter, aggregate, and transform data. High-performance computing: Simulations and scientific applications read shared input datasets across many workers, creating concentrated demand for fast data access. Sessions and agent delegation In an agentic workflow, a user asks an agent to complete a task, and the agent reads data on that user's behalf. Session-based authentication keeps that delegation tightly bounded: Access is inherited, never expanded. The agent creates the session with the user's Microsoft Entra ID identity or with its own agent identity. Azure Storage checks RBAC and ABAC before it creates a session. The agent can read only what that identity is already allowed to read, even if a prompt injection tries to steer it toward other data. Access is short-lived and scoped to the task. Sessions expire after five minutes and are scoped to one container. Reaching another container requires creating a new session and a new authorization check. Access can't be handed off or replayed. Sessions are bound to the network context of the client that created them, and every request is signed with the session key. A token captured from an agent can't be reused by another client. Access stays traceable. Every read in the session is logged against the Entra ID identity that created the session. Turbo tier – Better Together To further improve performance for read-heavy AI and data intensive workloads, use Azure Blob Storage Turbo tier which is now in public preview. Turbo tier leverages session-based authentication and other improvements to deliver high throughput and low latency for applications that need higher storage performance. Less performance-sensitive data can stay on cost-efficient HDD-backed access tiers. Smart placement automatically moves eligible data as workload access patterns change, while customers keep a single storage account, namespace, and Blob API surface. To learn more about Turbo tier and the performance benefits, see the Azure Blob Storage Turbo tier blog. Pricing and Availability Creating a session is billed as a write transaction. Read requests made with a session are billed at the standard transaction rates for your storage account type. To learn more, please see Azure Blob Storage pricing. Session-based authentication is in public preview in all public regions. This preview release supports session-based authentication with Microsoft Entra ID at the Blob container level and applies to the Get Blob operation, and is available via REST API and SDKs. Getting Started To get started, you need to register for the preview by running the following Azure PowerShell commands: Connect-AzAccount -SubscriptionId <ID> Register-AzProviderFeature -FeatureName SessionRequest -ProviderNamespace Microsoft.Storage To check your registration state, run the following Azure PowerShell commands: Connect-AzAccount -SubscriptionId <ID> Get-AzProviderFeature -FeatureName SessionRequest -ProviderNamespace Microsoft.Storage Once your registration is approved, the RegistrationState will show as Registered. You can also use Azure CLI to register for the preview. To learn more, see the Session Based Authentication documentation. Using sessions with the Azure Storage SDK The Azure Storage SDK offers the simplest way to use session-based authentication. Enable session mode when you initialize your Azure Blob client; the rest of your application logic stays unchanged. Python SDK sample The only change is enabling session-based authentication with use_session=True. with DefaultAzureCredential() as credential: with BlobServiceClient( account_url=account_url, credential=credential, use_session=True, ) For SDK examples, see the Session Based Authentication documentation. When session mode is enabled, the SDK manages the full session lifecycle automatically: Creates a session and caches its credentials. Automatically signs every request with the session key. Uses the session token for Get Blob operations and Microsoft Entra ID access token for other operations. Renews the session before expiration without affecting data access, so your app never needs to track session lifetimes. Your existing code continues to read blobs with the same methods, Microsoft Entra ID credentials, and RBAC role assignments, while benefiting from lower-latency reads. More Information To learn more, see the Session Based Authentication documentation. Help and Support If you have questions or feedback, please reach out to us at blobsessionauth@microsoft.com. If you need technical help, get answers from community experts in Microsoft Q&A or create a support request: For Service type, select Blob Storage. For Problem type, select Authentication and Authorization. For Problem subtype, select Issues with Session-based authentication.138Views0likes0Comments
Blob Storage Turbo Tier: High performance with object storage scale and economics
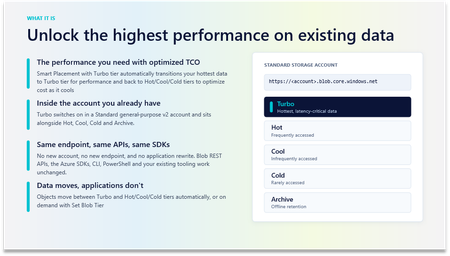
At Microsoft Ignite, we are introducing the preview of Turbo tier for Azure Blob Storage, built for AI and other data-intensive workloads that increasingly put storage on the critical path of compute. Training pipelines need to continuously feed data to GPUs. Inference services need fast access to models and application data as they start and scale. Analytics and HPC pipelines need high throughput across large datasets. Meeting those performance demands can require customers to choose between SSD-backed performance at high TCO and the scale and economics of HDD-backed object storage or incur operational overhead across separate storage systems to get both. Customers no longer need to choose between high-performance storage and cost-efficient, scalable object storage. Turbo tier removes that tradeoff by combining higher performance for performance-demanding data with cost optimization for the rest, within one Blob Storage account. Applications continue using the same account, namespace, and Blob APIs. Turbo tier combines these product capabilities: Higher throughput, transactions/second, and lower latency. Turbo tier accelerates demanding I/O patterns, including highly concurrent reads and large transfers. One Blob Storage account and namespace across performance tiers. Use Turbo alongside Hot, Cool, and Cold tiers without managing a separate high-performance storage account or moving objects between storage accounts. Automated placement across tiers. Smart placement helps place performance-sensitive data in SSD-based Turbo tier as access patterns change, while less-active data can tier down to HDD-based Hot, Cool and Cold tiers. Same API surface. Continue using the same Blob APIs, SDKs, and tooling your applications use today as eligible data moves between performance tiers. The result is a different approach to object storage performance: bring high performance to the subset of data inside your Blob Storage account that requires it rather than moving an entire dataset into a separate SSD storage architecture. One storage account, multiple performance tiers. Traditionally, cloud object storage has required customers to choose upfront between performance-optimized storage and cost-optimized storage. That choice becomes limiting as application needs and access patterns change. Azure Blob Storage Turbo tier removes that friction. Customers can apply higher performance to the data that needs it while retaining cost-efficient storage for the rest, all within one account, namespace, and Blob API surface. Your storage architecture stays familiar. The performance class of your data can change as workload demands change. An AI training pipeline might repeatedly access a subset of images or model data across many epochs. Analytics pipelines may repeatedly process recent partitions of a much larger data lake. Inference applications can require fast access to active models and application data. In each case, only part of the overall dataset may need SSD-backed performance at any given time. Turbo tier brings SSD-backed performance directly into a standard Azure Storage account. Applications continue to address blobs through the same account endpoints and namespace as data changes tiers. Existing Blob APIs remain the application interface. Turbo is an access tier within the storage account, rather than a cache or a separately managed high-performance storage account. Smart placement: Performance follows workload demand Smart placement removes the burden of continuously identifying, promoting, and cooling individual objects as access patterns change. Instead, you configure the size of your high-performance working set while Smart placement manages eligible data movement between Turbo and HDD-backed tiers. You configure a Turbo capacity target directly on your storage account through the Azure Portal, Azure CLI, Azure PowerShell, or the management plane REST APIs. The capacity target helps govern how Smart placement manages your high-performance working set. With Turbo tier, the data lifecycle becomes: Land fast. When configured for Turbo tier, new data in your storage account will land directly in Turbo so performance-sensitive processing starts against SSD-backed storage. Cool as demand changes. When Turbo performance is no longer needed, Smart placement moves eligible data back to HDD-backed access tiers, helping maintain the configured Turbo working set and reducing SSD-backed capacity spend. Accelerate when workloads demand it. As workload access patterns change, Smart placement promotes eligible data from HDD-backed access tiers into Turbo tier. If you know exactly which data requires Turbo, you can skip smart placement and directly orchestrate movement through explicit Blob tiering operations. Performance across the I/O patterns of demanding workloads Modern AI and data workloads stress storage in different ways, sometimes within the same pipeline. Small, concurrent reads. Training workers, inference services, and analytics systems can generate large numbers of concurrent requests. Low latency and high transaction rates help keep storage from becoming the pacing layer. Large transfers. Model loading, dataset movement, and checkpointing depend on sustained bandwidth, making storage throughput critical to how quickly data reaches compute. Bursty demand. Worker startup, model loading, and checkpoints can rapidly increase storage demand, requiring storage performance to scale with concurrency. We tested a synthetic 4 KiB random-read workload against the same dataset, using 72 Standard D96s v6 worker VMs for Standard Blob with HDD-backed tiers and 256 for Turbo tier. The Standard Blob configuration used fewer workers to stay within the HDD-backed storage account limits. In this benchmark, Turbo tier delivered 16.8× the transaction rate, reaching 10.1 million transactions per second compared with 601,000 for Standard Blob. Results are specific to this test configuration. Performance varies by workload, object size, concurrency, network conditions, and account configuration. Read bandwidth is another critical dimension of storage performance. During checkpoint recovery, large GPU clusters must reload model weights ranging from several GiB to tens of TiB. High read throughput helps reduce GPU idle time after a job interruption. It also helps reduce data-loading delays in analytics workloads and when scaling out inference endpoints. In this separate read-bandwidth benchmark, Turbo tier sustained more than 20 Tbps: Where Turbo tier fits: Turning storage performance into workload performance Higher storage performance can help reduce data-loading delays and checkpoint pauses when storage is a bottleneck. The benchmarks above measure storage performance, not end-to-end workload speedups. Turbo tier is designed for workloads in which storage latency, throughput, or transaction rates directly affect application performance and compute efficiency. AI training and fine-tuning. Feed large training clusters with active datasets while supporting high-bandwidth checkpoint and intermediate-state writes. AI inference. Provide fast access to models and other latency-sensitive application data as inference services start, scale, and serve requests. Analytics and HPC pipelines. Accelerate repeated processing against the active portion of large datasets and data lakes. High throughput reads, writes, and checkpoints. Sustain large output and checkpoint reads and writes so compute resources can return to productive work sooner. Across these scenarios, the objective is the same: apply higher storage performance where it creates workload value without requiring every object in your dataset to carry the cost of SSD-backed storage. Align storage spend and workload economics with performance demand The benchmarks above demonstrate storage performance. Turbo also changes the economics of high-performance Blob Storage: You pay for SSD-backed capacity only for the data that needs it, rather than for the entire dataset. In the customer workloads we have analyzed across diverse use cases, only a fraction of the overall dataset typically requires the highest level of performance. As an illustration, consider a 1 PiB dataset with an approximately 20% active, high-performance working set. Rounded to whole TiB, the example places: 205 TiB of active data in Turbo tier 819 TiB of remaining data in Hot tier Data placement Illustrative monthly capacity cost (in USD) 1 PiB all-SSD baseline $115,343 20% Turbo tier + 80% Hot tier $37,500 Illustrative capacity-cost reduction 67% * The example is based on East US 2 and assumes a full month at the stated placement. The illustrated savings apply to capacity costs in this scenario and do not represent total workload-cost savings or a pricing or savings guarantee. In this illustrative scenario, the mixed Turbo and Hot configuration results in approximately 67% lower capacity cost than the all-SSD configuration used for this comparison (1 PiB x $0.11 per GiB = $115,343). This example highlights the core economic model behind Turbo: align SSD capacity spend with the part of the dataset where performance creates value, while continuing to use cost-efficient HDD-backed access tiers for the rest. The capacity comparison captures only one part of the economic value. At the workload level, Turbo may also reduce costs associated with idle compute, delayed processing, data movement, and operating separate storage architectures. (Actual workload TCO depends on each application’s compute, transaction, networking, and operational profile.) High performance where it matters, Blob economics for the rest. AI and data systems increasingly need high storage performance for data actively feeding compute, while retaining much larger datasets economically over time. Turbo tier brings those requirements together in Azure Blob Storage. SSD-backed performance accelerates performance-demanding data, Smart placement adapts placement to changing access patterns and workload needs, and Blob Storage tiering keeps less performance-sensitive data on cost-efficient HDD-backed access tiers. For supported configurations, Turbo runs within an eligible Standard Storage account, using the same namespace and Blob APIs your applications already use. During the preview, eligibility is limited to GPv2 accounts that use locally redundant storage (LRS) in selected regions, subject to regional capacity. Request access to the Turbo tier preview today and evaluate Turbo tier with your own workload to see how much of your data needs SSD-backed performance.317Views1like0Comments
Azure Storage
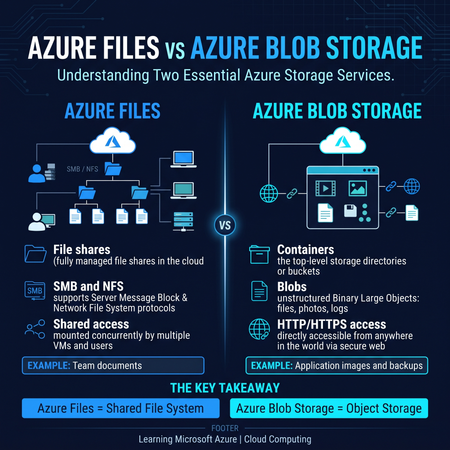
Azure Files vs Azure Blob Storage: When Should We Use Each? Hello everyone! I've been exploring Microsoft Azure Storage services through hands-on labs and recently worked on a project involving Azure Files and Azure Blob Storage. While learning these services, I realized that beginners often get confused about when to use Azure Files and when to use Blob Storage. So, let's discuss the difference! 1. Azure Files Azure Files provides managed file shares in the cloud. Some important features: Supports SMB and NFS protocols. Organizes data using files and folders. Can provide shared file-system access to multiple clients. Example: Imagine a company where multiple servers need access to the same shared folder containing documents and configuration files. 2. Azure Blob Storage Azure Blob Storage is designed for storing large amounts of unstructured data. Some important features: Stores data as blobs inside containers. Supports images, videos, PDFs, backups, and other files. Provides access through HTTP/HTTPS and APIs. Example: An e-commerce application storing thousands of product images and videos. Key Difference Azure Files = Shared file-system storage. Azure Blob Storage = Object storage. My Question to the Community Suppose we are developing a university management system. Where would you store shared departmental documents? Where would you store student profile pictures and uploaded assignment PDFs? Would you use Azure Files, Azure Blob Storage, or a combination of both? I'd love to learn from your experiences and hear how you approach storage architecture in real-world projects. Official Microsoft Documentation https://learn.microsoft.com/en-us/azure/storage/common/storage-introduction?wt.mc_id=studentamb_618702 #Azure #AzureStorage #AzureFiles #AzureBlobStorage #CloudArchitecture15Views0likes0Comments
Discover and assess on-premises Network Attached Storage (NAS) shares using Azure Migrate
Network-attached storage (NAS) holds much of an enterprise’s data; home directories, project shares, media libraries, application data, and analytics datasets, often spanning tens or hundreds of terabytes across protocols and administrative boundaries. Moving this estate to Azure starts not with copying data, but with understanding what you have, where each share should go, and what it will cost. Building on the file share assessment capability we announced in May, today we’re announcing the public preview of NAS share discovery and assessment in Azure Migrate. It connects directly to Dell PowerScale/Isilon and NetApp ONTAP clusters, inventories every SMB, NFS, and S3 share, and assesses each against Azure Files, Azure Blob Storage, and Azure NetApp Files—providing readiness, right-sized configurations, cost estimates, and migration tooling guidance. Your NAS assets now join servers, applications, and databases in the same Azure Migrate project, inventory, and business case. Why does this matter NAS planning has historically been done with spreadsheets, vendor-specific tools, and a lot of manual reconciliation. Storage ends up being assessed separately from the servers and applications that depend on it, which makes it hard to sequence a migration or defend a budget. This capability is designed to help you: Replace manual inventory with automated discoveries across Dell and NetApp platforms, so you can go from "we think we have a few thousand shares" to a verified, per-share inventory. Effectively plan your NAS shares alongside everything else. NAS clusters and their shares appear in the same Azure Migrate inventory as your VMware, Hyper-V, and physical servers, databases, and web apps. Make your informed decision before you migrate. Each share gets a readiness verdict, a recommended Azure service and SKU, and a monthly cost estimate. What's available in public preview Add Dell or NetApp NAS clusters: Discover Dell PowerScale / Isilon (OneFS) and NetApp ONTAP AFF / FAS clusters, and inventory every SMB, NFS, and S3 shares they host — including shares exposed through more than one protocol. Explore and review on-prem shares and workloads: Review cluster and share details in the portal: model, nodes, total and used capacity, protocol versions, volume, and estimated size. Group and filter shares by tag — by business unit, cost center, or application — so related workloads can be planned together. Suitable Azure storage targets: Assess each share against Azure Files, Azure Blob Storage, and Azure NetApp Files, with control over target region, sizing criteria, comfort factor, redundancy, media type, access frequency, and workload type. Alternative migration paths: Compare various migration paths side by side — a recommended mixed path that sends each share to its best-fit service, alongside single-service alternatives — with readiness, monthly cost, and estimated emissions for each. Business case: Build a business case for a NAS-only estate or for a mixed estate of VMs and NAS, comparing a modernization approach against lift-and-shift. End-to-end experience The experience follows the same guided workflow you already know from Azure Migrate. 1. Enable the feature Install the latest Azure Migrate appliance or turn on auto-update, so your existing appliance picks up the new capability. Unlike file shares hosted on Windows and Linux servers, NAS clusters need to be added explicitly: in the appliance configuration manager, add a credential of source type NAS Server, then add a discovery source of type NAS Server with your cluster's FQDN and port. The account needs read-only permission at cluster level — Azure Migrate only reads metadata and never writes to your storage. 2. Discover your NAS estate Create an Azure Migrate project, deploy the appliance on VMware, Hyper-V, or a physical server, and point it at your clusters. The appliance connects to each cluster's management endpoint and collects system and share metadata, vendor, product and model, operating system version, cluster nodes, total and used capacity, share and bucket paths, protocols and protocol versions; followed by performance signals such as IOPS and throughput. Discovered clusters and their shares appear as first-class inventory objects, listed alongside the Windows and Linux file servers the appliance already finds. Filter by type, search, tag, and export the inventory at whatever scale your estate demands. Discovery runs a daily cycle and updates existing items as new metadata arrives, so the picture improves over time rather than being a one-shot snapshot. 3. Create an assessment Select the shares you care about — individually, by tag, or a whole cluster at a time — and create an assessment. The share is the unit of assessment, so every SMB, NFS, or S3 share receives its own verdict rather than inheriting one from its host. Assessment settings let you shape the recommendation to your environment: choose the target Azure region, pick as-is or performance-based sizing, set a comfort factor for headroom, and configure redundancy, Azure Files media preferences, and Azure Blob access frequency. A workload type setting from general purpose file shares through to AI/ML and mission-critical, helps Azure Migrate recommend an appropriate performance level. Azure NetApp Files is added to the evaluation automatically when the source share is detected on NetApp NAS. Settings can be changed, and the assessment recalculated at any time. 4. Review results and build the business case Results are organized as migration paths. The recommended path routes each share to its best-fit Azure service and is shown next to single-service alternatives, so you can compare readiness and cost on the same basis. Key insights include: Readiness for every share — Ready, Ready with conditions, or Not ready — with the warnings that need attention before you move. A recommended Azure configuration per share. For example, a multi-protocol NetApp volume is recommended for Azure NetApp Files, while a general-purpose SMB share is recommended for Azure Files with a specific media type and redundancy. Provisioned size, IOPS, and throughput behind the recommendation, plus the reasoning Azure Migrate used to select the SKU and access tier. Monthly cost estimates per share and per path, an on-premises versus Azure TCO comparison, and estimated carbon savings. Next, you can generate a wave plan to sequence the migration or build a business case that helps you with cost modernizing Azure storage services. Assessment results showing the recommended path, source-to-target mappings, estimated Azure TCO, and carbon savings. Note: All screenshots in this post are from a sample environment. Cluster and share names, capacity values, readiness distributions, cost and TCO estimates, and emissions figures are illustrative and shown for reference and indicative purposes only. They are not a price quote. Your own results depend on your discovered environment, the assessment settings you choose, your target Azure region, and the pricing and offers that apply to your subscription. Prepare for migration with the right tool Assessment tells you where each share should go; Azure Migrate then points you at the tool to get it there. Azure Storage Mover is the recommended path for moving shares to Azure Files and Azure Blob Storage. For ONTAP volumes heading to Azure NetApp Files, the Azure NetApp Files migration assistant is recommended, and Azure File Sync remains the option for active sync and hybrid scenarios with Windows file servers. To learn more about our recommendations for unstructured data migration, visit https://aka.ms/migratemydata. Get started Update your Azure Migrate appliance, add your first NAS cluster, and let a discovery cycle run. Within a few hours you'll start to see a per-share picture of your NAS estate; you can then create an assessment to view the right target service to migrate to Azure. Learn more in our documentation. Connect and discover your NAS appliance Review discovered NAS resources Create a fileshare assessment of NAS shares Review NAS File share assessment recommendations Write to us at azurestoragemigrations@microsoft.com with questions or feedback, or to suggest additional NAS systems you’d like this capability to support. We look forward to hearing from you!310Views1like1CommentAzure Storage Discovery now offers advanced capacity insights
Azure Storage Discovery is introducing advanced capacity insights to help customers gain deeper visibility into their data estate, identify inactive or inefficiently stored data, understand storage composition and retention considerations, and pinpoint resources for further investigation and optimization.874Views0likes1CommentAccelerated AI & Analytics workload on Azure Blob Storage: Up to 25x faster List Blobs operations
Today Azure Storage introduces in preview a new List Blobs optimization that accelerates listing operations by up to 25x with up to 15x lower client-side CPU utilization allowing customers to return millions of objects per second in List Blobs results. The list results are now returned in Apache Arrow format, a highly optimized and compact columnar response format that allows more efficient parsing and reduced client-side CPU utilization. Clients can now parallelize object list operations efficiently across multiple concurrent requests, while maintaining the same strong consistency of listing results that applications require. This increased performance and lower client CPU utilization is delivered within the existing List Blobs API via just a simple header change and is automatically invoked when using the updated Azure Blob Storage SDK’s. Why we built this Object storage was originally designed to provide low-cost, resilient data access through simple REST APIs. Early systems contained only a few million objects and were listed infrequently, so listing performance was not a priority. Cloud, big data, mobile, and cloud-native computing steadily increased data volumes and access demands. Since 2020, foundation models, LLMs, and large GPU fleets have pushed object storage to trillions of objects, making it an active data layer for AI. Modern AI and analytics workloads operates at the scale of trillions of objects. These workloads must repeatedly discover and inventory vast datasets for pre-training, analytics, fine-tuning, and inference, making frequent listing operations a significant source of storage-system pressure and client-side CPU consumption. Downstream AI training and data analytics jobs are gated by the time required to enumerate immense datasets, while parsing the results consumes client-side CPU that could otherwise run the workload. To meet these rapidly growing demands of AI workloads, we’ve built the next generation of Azure Blob Storage listing capabilities that deliver the performance required at this massive scale. Next, we will dive deeper into the details of how List Blobs performance and scalability have been accelerated and how simple it is for customers to take advantage of this new level of performance. Faster, more efficient, listing results with lower client CPU utilization The Apache Arrow format was selected as the most efficient new way to deliver the performance and scalability gains required for efficiently listing millions of objects per second. Apache Arrow is an open-source, compact columnar format that returns List Blobs results in an optimized response roughly one third the size of the XML format used by most cloud object-storage listing APIs, making parsing faster and easier. The new format is enabled with a simple request-header change. The List Blobs API then packages and accelerates results automatically while preserving strong consistency, so newly written objects remain immediately visible. Because Apache Arrow is compact and efficient to parse, client-side CPU utilization per object listed decreased by up to 15x, freeing compute resources for the workload itself. Submitting multiple List Blobs requests concurrently further improves performance, delivering up to a 25x increase in enumeration speed with a single request-header change, while preserving schema consistency and compatibility with existing XML responses. This new List Blobs performance enhancement via Apache Arrow remains an additive, opt-in extension of the existing List Blobs API, not a replacement. The existing XML-based List Blobs API remains unchanged, and current clients not adopting the new header continue to work with no breaking changes, but without the performance and lower CPU-utilization benefits. The next figure shows the comparison of a parallelized listing operation using Apache Arrow format compared with the XML baseline on 16 clients and 48 threads per client. rclone accelerates listing of 100K objects from 24 seconds to 1.1 seconds rclone is a popular command-line program to manage, copy, move and replicate files on and between cloud storage destinations. rclone is a widely used open-source tool for moving and syncing data across almost all types of cloud storage. Listing is a critical part of rclone’s synchronization workflow. To perform these data management operations at scale for large numbers of objects, rclone must enumerate the objects that are intended to be copied, moved, or replicated. For example, before and after syncing Azure Blob Storage containers, rclone performs a large-scale listing to compare the source and target states. After updating rclone to incorporate the simple header change for the enhanced Apache Arrow-based List Blobs API calls, rclone was able to reduce their List Blobs time-to-completion by 21.7x from 24 seconds to 1.1 seconds on 100K object datasets. The chart below shows rclone's measured wall clock time for listing a single container with 100,000 entries (columns, left axis) alongside the resulting speedup versus the classic XML path (line, right axis). Two things stand out in the results: Apache Arrow is an immediate win on its own: With no parallelism at all, sequential Arrow listing is 3.5× faster than the current XML-based List Blobs results, reducing listing operation time to completion from 23.9 seconds to 6.9 seconds . Parallel enumeration compounds the gains: Throughput climbs steadily with concurrency, reaching a 21.7× speedup at a parallelism of 30 and completing the same listing of 100,000 entries in just 1.1 seconds. The accelerated List Blobs results are returned with the same consistency using the same List Blobs API but now returned much faster with no breaking changes for existing clients. That is exactly the outcome we set out to deliver with this new capability. In rclone's own words about these results: " rclone has to list containers before it can sync them; with Apache Arrow and parallelism enabled this will make a sync of a directory with millions of files get going 20x faster. The Azure Storage team has been very responsive to our feedback during the preview which made the integration straightforward. The new Go SDK works very well and required very few code changes. Our Azure Blob Storage users are going to love this!" Nick Craig-Wood, rclone Lead Developer To get started, you can download rclone from the official rclone website. If you are running rclone v1.74.0 or later you can enable the Apache Arrow listing with the --azureblob-use-arrow-list flag and enable listing parallelism with --azureblob-list-parallelism. As described in the testing, if you set “--azureblob-list-parallelism 30” this will get you the most performance listing from Azure with Arrow listing also enabled. A sincere thank you to the rclone community for adopting List Blobs with Apache Arrow early and sharing such clear, quantified results. Feedback like that is invaluable as we advance toward general availability. Happy listing rcloners! How to get started At the REST layer, the Arrow response is negotiated with the Accept: application/vnd.apache.arrow.stream header on a minimal x-ms-version of 2026-06-06 or later. This will return a response content that will be an Apache Arrow IPC stream that can be decoded and used to instantiate a RecordBatchStreamReader using Apache Arrow SDKs in any language. An example of decoding from Rest API response is provided below using Apache Arrow Python SDK for decoding: table = pa.ipc.open_stream(resp.content).read_all() print(table.schema) print("\nrows:", table.num_rows, " columns:", table.num_columns) Name: string not null Creation-Time: timestamp[s] Last-Modified: timestamp[s] BlobType: string ResourceType: string not null Etag: string Content-Length: uint64 Content-Type: string Content-MD5: string AccessTier: string AccessTierInferred: bool LeaseState: string LeaseStatus: string ServerEncrypted: bool -- schema metadata -- NumberOfRecords: '100' NextMarker: '' rows: 100 columns: 14 import pandas as pd df = table.to_pandas() df[["Name", "BlobType", "Content-Length", "size_mb", "AccessTier"]].head(6) Name BlobType Content-Length AccessTier 0 train_chunk10_shard1.jsonl.zst BlockBlob 215 Hot 1 train_chunk10_shard10.jsonl.zst BlockBlob 216 Hot 2 train_chunk10_shard2.jsonl.zst BlockBlob 215 Hot 3 train_chunk10_shard3.jsonl.zst BlockBlob 215 Hot 4 train_chunk10_shard4.jsonl.zst BlockBlob 215 Hot 5 train_chunk10_shard5.jsonl.zst BlockBlob 217 Hot This new accelerated performance for List Blobs listing via Apache Arrow can be transparently enabled on Python, Java, .NET, C++ and Go SDKs with a simple option in the container listing function. Enabling via Azure Blob SDKs allows the performance benefits to be achieved without changing the listing interface and returned object formats in the Azure Storage SDK. This new accelerated performance for List Blobs is available in public preview across the Azure Storage client libraries listed below. To evaluate the capability, use the corresponding minimum preview version for your preferred language. SDK Minimum version (preview) .NET 12.30.0-beta.1 Python 12.31.0b1 Java 12.36.0-beta.1 Go v1.8.1-beta.1 C++ 12.19.0-beta.1 JavaScript 12.34.0-beta.1 To get started, update to a preview enabled SDK for your language and start testing the new feature with our samples, or add the new listing options to your existing REST calls Parallelizing listing operations unlocks the double-digit performance gains described in this article. The optimal strategy depends on the namespace layout and distributes listing requests across multiple threads. The two most common approaches are: Use delimiter parameter to recursively fan out additional threads for each BlobPrefix, walking the namespace. Partition the namespace with startFrom and endBefore, then process the ranges across multiple threads. This is the approach used by rclone. The best approach depends on the specific namespace layout and can be optimized by tuning both the algorithm and the level of parallelism. Limitations This new Apache Arrow-powered performance optimization for List Blobs is today supported on flat namespace (FNS) Azure Blob Storage accounts. In scenarios where the account is Hierarchical Namespace (HNS) enabled, if the List Blobs REST API is called with the new header, it will return a 409 (Conflict) error code. This error code can be used to fallback on the client application to standard XML listing. Public preview is where your input shapes the product. Try it on your largest containers, tell us what you measure, and let us know what would make it even better through this form. References List Blobs (REST API) - Azure Storage | Microsoft Learn List Blobs with Apache Arrow Samples976Views1like0CommentsUnlocking Storage Optimizations: Smart Tiering for Blobs and ADLS in Azure Storage
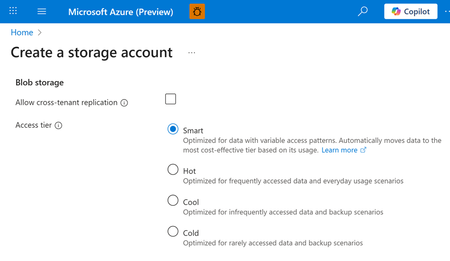
We are excited to introduce the public preview of smart tier for Azure Blob and Azure Data Lake Storage. Smart tier is a fully managed, automated data tiering solution that takes the guesswork and manual effort out of optimizing your storage costs. Smart tier continuously analyzes your data’s access patterns and automatically moves objects between the hot, cool, and cold tiers. Smart tier will keep regularly accessed objects on the hot capacity tier to optimize transaction costs and moves inactive objects after 30 days to the cool tier capacity tier and after an additional 60 days of inactivity to the cold capacity tier. If you access an object in cool or cold tiers again, it’s instantly promoted back to the hot tier, restarting the cycle. This ensures your data is always in the most cost-effective tier with zero manual intervention, making it the ideal online tier for datasets with mixed or unknown access patterns. Getting started Using smart tier is quick and easy: Enabling smart tier is simple: Just select smart tier as the default access tier through the storage account configuration for any storage account with zonal redundancy. Smart tier is available in all zonal public cloud regions, supporting both flat and hierarchical namespaces. Billing is straightforward: You will pay the regular hot, cool, and cold capacity rates, with no extra charges for tier transitions, early deletion, or data retrieval. Even moving existing objects into smart tier does not incur tier change fees. There’s just a small monitoring fee for the orchestration. Smart tier is configured at the account level. It can be configured via API or the Azure portal as the default access tier setting for new and existing storage accounts. Existing objects following the default access tier setting from the account will be moved to smart tier automatically. Objects that are explicitly tiered, i.e. to the hot tier, will remain in the same account and will not be moved to other capacity tiers. Smart tier will always keep small objects that are below 128 KiB in size in the hot capacity tier for efficiency and those objects will not incur a monitoring charge. If objects below 128 KiB increase in size, the smart tiering patterns apply for those objects as well. The automatic down tiering of inactive data, paired with the billing model simplifications of Smart tier can lead to large cost savings over time. In the metrics view of the storage account you can see the distribution across the capacity tiers for smart tiered objects by both object count and capacity. This account shows smart tier in action, moving inactive objects to the cool and cold capacity tier, thereby drastically reducing the capacity charges without any manual intervention. "2 years ago, Qumulo partnered with Microsoft to deliver the first truly elastic, unlimited capacity, fully managed file system, Azure Native Qumulo, which was built on Azure Blob," said Brandon Whitelaw SVP of Product at Qumulo. "Qumulo shared feedback with Microsoft on our ideal solution for data tiering and Microsoft clearly delivered, meeting all expectations. With today's smart tier announcement, Qumulo will immediately enhance our offerings with these new capabilities, delivering greater functionality and control over data lifecycle management. We are thrilled with the feature set Azure is delivering at launch” Note that smart tier is not supported with append and page blobs. Smart tier is the ideal tier to choose when you are looking to store your data on standard online tiers but are not fully aware of the data access patterns or do not want to manage data transitions across online tiers. Objects managed by smart tier are not subject to lifecycle management policies, ensuring that automated tiering decisions are based solely on access patterns. Smart tier for block blobs is now available in public preview for both Azure Blob Storage and Azure Data Lake Storage for storage accounts with zonal redundancies, including ZRS, GZRS and RA-GZRS. Unlock cost savings by adding smart tier to your blob storage accounts in one easy step: https://aka.ms/BlobSmarttier. Please reach out to us for any feedback or questions, we would love to hear from you: smartblob@microsoft.com3.1KViews3likes6CommentsEnterprise Identity Meets Secure File Transfer: Entra ID Public Preview on Azure Blob Storage SFTP
Updated on June 23 2026: Microsoft Entra ID-based access for Azure Blob Storage SFTP is now Generally Available. GA enhancements: Improved ABAC by resolving inconsistencies with the Storage Blob Data Owner role (eliminating timeout issues) while adding support for sub-operations to enable more granular access control. Learn more here. We are excited to announce the public preview of Entra ID-based access for Azure Blob Storage SFTP. This new capability enables you to use Microsoft Entra ID (formerly Azure Active Directory) identities (including guest users via Entra External Identities) to securely connect to Azure Blob Storage via SFTP without needing local users. This feature eliminates the operational overhead of managing local SFTP users and passwords by introducing enterprise-grade identity management powered by Microsoft Entra ID. For IT administrators and security teams, this means no more creating, tracking, rotating, or decommissioning local SFTP credentials. For developers and architects, it means seamless integration with your existing identity infrastructure. For business users, it means faster, more secure access to the data they need, all while maintaining compliance with enterprise security policies. Azure Blob Storage SFTP Azure Blob Storage SFTP natively enables secure file access and management without third-party solutions. This simplifies operations for customers and removes the need for complex, custom SFTP solutions. Until this Public Preview, Azure Blob Storage SFTP utilized a form of identity management called local users as the only authorization mechanism. Local users must use either a password or a Secure Shell (SSH) private key credential for authentication. Learn more about local users here. The Challenge: SFTP Local User Management Organizations currently face challenges when managing SFTP access at scale with Azure Storage SFTP Local Users. Local User based SFTP access require IT teams to: Manually create and provision local user accounts for each SFTP user Generate, distribute, and securely store SSH keys or passwords Implement custom workflows for lifecycle management Manage offboarding processes to ensure departed users lose access immediately Audit and track access across disconnected identity silos Handle external partner and vendor access through ad-hoc, often insecure methods The Solution: Enterprise Identity Meets Secure File Transfer With Entra ID-based access for Azure Blob Storage SFTP, you can now leverage your organization's centralized identity platform to authenticate and authorize SFTP users. This integration brings the full power of Microsoft Entra ID to your file transfer workflows, delivering the following benefits: 1. Eliminate Local User Management Simplify SFTP management by assigning access with Entra ID—no separate SFTP accounts needed. No local credential generation or distribution—users authenticate with their existing corporate credentials No orphaned accounts when users change roles or leave the organization Reduced attack surface by eliminating static, long-lived local credentials Centralized user lifecycle management through your existing identity platform 2. Enterprise-Grade Identity and Security Leverage the full security capabilities of Microsoft Entra ID for your SFTP infrastructure: Multi-Factor Authentication (MFA): Require additional verification factors beyond passwords, significantly reducing the risk of account compromise Conditional Access: Define policies that grant or block access based on user location, device compliance, sign-in risk, and other conditions Identity Protection: Benefit from Microsoft threat intelligence and risk detection to identify and respond to compromised accounts Privileged Identity Management (PIM): Provide just-in-time elevated access for administrative operations 3. Native Azure RBAC, ABAC, and ACL Integration Your SFTP access control seamlessly integrates with Azure comprehensive authorization framework: Role-Based Access Control (RBAC): Assign built-in or custom roles at the storage account, container, or even blob level Attribute-Based Access Control (ABAC): Create sophisticated access policies based on resource tags, user attributes, and environmental conditions Access Control Lists (ACLs): Apply fine-grained permissions at the directory and file level for hierarchical namespace-enabled accounts Unified Permission Model: SFTP access respects the same permissions as REST API, Azure CLI, and other access methods—no separate permission system to manage 4. Faster SFTP Onboarding and Time-to-Value Onboard new SFTP users or partners in minutes instead of hours or days, saving significant time and boosting business agility. 5. Secure External Collaboration with Entra External Identities Seamlessly enable secure external SFTP access by allowing partners to authenticate with their own credentials using Entra External Identities (Azure AD B2B). External users authenticate with credentials they already manage Full audit trail of external user activity Ability to apply Conditional Access policies to external users Automatic access revocation when B2B relationships end Real World Scenarios Financial Services: A bank receives daily transaction files from merchants via SFTP. Merchants authenticate with their own Entra ID credentials (B2B collaboration), MFA is enforced, and access is restricted to assigned directories. Access is instantly revoked when a merchant is removed from the B2B directory. Healthcare: A hospital exchanges patient data with insurers and labs. Entra ID authentication ensures only authorized staff access sensitive PII, with full audit logs for HIPAA compliance. Conditional Access restricts connections to approved locations and devices. Media & Entertainment: A production company enables freelance editors and agencies to transfer large media files. Entra External Identities provide time-limited access and automatic revocation when projects end—no need for local SFTP accounts. Manufacturing: A manufacturer receives CAD files and orders from suppliers using SFTP. With Entra ID, suppliers use unified credentials and access policies across all systems, streamlining supply chain management. How It Works Entra ID simplifies SFTP access to Azure Blob Storage by authenticating users with their corporate credentials. After authentication, users receive a short-lived Open SSH certificate to connect. The service verifies certificate validity and user permissions, enabling secure file operations and automatic access revocation in line with current identity policies. Learn more here. Getting started with the Public Preview We encourage you to try Entra ID-based access for Azure Blob Storage SFTP in your non-production environments today. Learn more about how to register for the preview and get started with the detailed ms docs learn guide here. This preview gives you an opportunity to shape the feature development by providing feedback on what works well and what could be improved. Note: Local user accounts for SFTP access are still supported, but we strongly recommend switching to Entra ID-based access for greater security, simpler management, and automatic access control. Questions or feedback? We would love to hear from you! Reach out to our team at blobsftp@microsoft.com We are excited to bring enterprise-grade identity management to Azure Blob Storage SFTP, and we cannot wait to see how you use this capability to simplify operations, enhance security, and enable new collaboration scenarios. Happy transferring!2.3KViews0likes0CommentsAHEAD helps us launch the Strategic Azure Storage Services Partner Program
AHEAD becomes the first Azure Storage Strategic Channel Partner by demonstrating their expertise in helping customers select the ideal Azure Storage, or Azure Storage ISV, Service to offer the ideal price / performance solution for their application and helping customers to migrate to Azure quickly and safely.895Views0likes0Comments