azure ai
317 TopicsWhen the Answer Isn’t in the Document: Metadata-Aware Agentic RAG with Foundry IQ
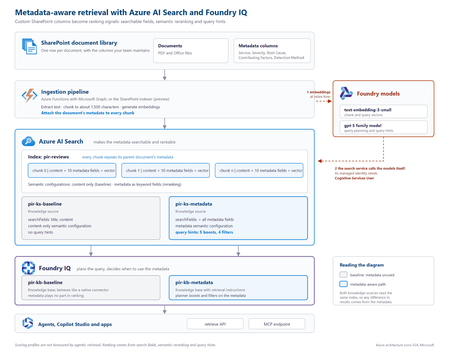
The problem SharePoint libraries often contain years of carefully curated metadata, including root cause, severity, business unit, document type, owner and classification. If that metadata never reaches the retrieval pipeline, however, a RAG system cannot use it. This creates a common blind spot: the information that explains what a document is about may exist in its metadata rather than its text. Consider an incident review containing this statement: “Investigation found that a DNS record was repointed during a migration while the old target was still serving writes.” The associated Root Cause Category is Configuration change, but those words do not appear in the document. Another review might mention that a configuration change was suspected and ruled out. Text-only retrieval can therefore favour the wrong document. In the sample dataset used for this project, none of the 19 reviews classified as configuration-change incidents contained the word “configuration”, while six reviews with other root causes did. Metadata does not improve every search. It helps when the information that determines what a document is lives outside the document text. Why tuning alone cannot fix it With a native SharePoint knowledge source, document text is extracted, chunked and embedded, while standard properties are retained. Custom SharePoint columns are not part of that ingestion path. Fields such as Root Cause Category, Contributing Factors, Detection Method and Severity therefore never become structured fields available to retrieval. If the metadata is absent from the index, search tuning cannot make it count. Flattening all metadata into a single text string is also problematic: Notification Service | Sev2 | Configuration change | Missing runbook This preserves the words but loses their meaning. A root cause, severity and contributing factor represent different concepts and should remain separate fields. Bring a custom Azure AI Search index The approach is to create and control a custom Azure AI Search index, then expose it to Foundry IQ as a searchIndex knowledge source. This combines metadata control with agentic query planning and a governed retrieval surface. Approach Metadata control Agentic planning Native SharePoint knowledge source No Yes Custom index queried directly Yes No Custom index as a knowledge source Yes Yes Architecture The key design principle is simple: every chunk carries its parent document's metadata. Figure 1. Metadata-aware retrieval architecture with Azure AI Search and Foundry IQ. The ingestion pipeline extracts a document, creates chunks, attaches document-level metadata to every chunk, generates embeddings and writes the records to Azure AI Search. Foundry IQ then uses the index as a knowledge source. Azure AI Search holds the metadata. Foundry IQ decides when to use it. Figure 2. Detailed implementation view, including the baseline and metadata-aware retrieval paths. At query time, the search service calls the configured models for vectorisation and query planning. Where key authentication is disabled, the search service's managed identity needs the required access. In the tested implementation, the Cognitive Services User role resolved HTTP 401 responses from retrieve requests. Put metadata on every chunk A chunk can only be retrieved and ranked using information available on that chunk. Each metadata property should therefore remain in its own field: { "id": "doc1035-000", "parentId": "doc1035", "title": "Notification Service: failed sign-ins", "content": "<extracted review text>", "rootCauseCategory": "Configuration change", "contributingFactors": "Missing runbook; Change outside window", "detectionMethod": "Customer report", "severity": "Sev2" } A separate metadata index does not solve the same problem because a match against metadata in one index cannot raise the ranking of a content chunk in another. What influences retrieval Four areas matter in this design: Search fields: searchFields determine which fields generated subqueries search. Semantic configuration: prioritised fields give the semantic reranker access to important metadata. Query hints: hints help the planner connect natural-language requests to known metadata values. Filters: a baseFilter or request-level filterAddOn can enforce constraints. Boost hints influence ranking without excluding documents. Filter hints can narrow the result set when the planner determines that a filter is appropriate. "queryHints": { "boosts": [{ "kind": "fieldValue", "field": "rootCauseCategory", "fieldValues": ["Configuration change", "Capacity", "Software defect", "Dependency failure", "Certificate expiry"], "boost": 3.0, "boostInstructions": "Boost when the user describes what caused an incident." }] } Hints are best effort. Hard requirements should use a base filter or document-level access control rather than relying on the planner to select a hint. The tested configuration used the 2026-08-01-preview API. Current documentation should be checked for supported models, limits and behaviour before implementation. Why can't vector search or semantic ranking solve this? This is probably the most obvious question: if embeddings understand meaning, and semantic ranking understands context, why do we need metadata at all? The answer is that vector search and semantic ranking solve a different problem. This approach complements them rather than replacing them. Vector search finds similarity, not recorded facts In a typical RAG pipeline, document chunks are converted into embeddings, numerical representations of their meaning. The user's question is embedded as well, and vector search finds chunks that are close to it in vector space. For example, a passage saying: “The gateway routing rule was updated shortly before the incident.” might rank highly for: “Find incidents caused by configuration changes.” That's useful. But it doesn't necessarily mean Configuration change was the confirmed root cause. The passage could describe an investigation path, a contributing factor, or even something that was later ruled out. Vector similarity is essentially asking: “Does this content mean something similar to what the user is asking about?” Metadata lets us ask a different question: “What was this incident actually classified as?” If the incident review already contains a curated rootCauseCategory = Configuration change field, we should not require an embedding model to rediscover that fact from the prose every time somebody searches. What about semantic ranking? Semantic ranking helps, but at a different stage. In Azure AI Search, semantic ranker applies secondary ranking to an initial result set, using language understanding to promote results that are more semantically relevant to the query. That can help distinguish between: a configuration change that caused an incident a configuration change that was merely investigated a configuration change that was explicitly ruled out But semantic ranking still works with the information supplied to the retrieval pipeline. It cannot make use of a classification stored in a separate metadata field if that field was never supplied to retrieval or ranking in the first place. The difference becomes clearer with a real query Consider: “Show me configuration change incidents that customers reported.” A content-first approach primarily asks: “Does this passage sound relevant to configuration changes and customer reports?” A metadata-aware approach can additionally ask: “Is the recorded root cause Configuration change , and is the recorded detection method Customer report ?” Those signals can influence retrieval in different ways: Boost: favour incidents with those metadata values while still allowing other relevant results. Filter: restrict the candidate set when those classifications represent hard constraints. Retrieval layer Typical content-first RAG Metadata-aware approach Vector search Finds chunks with similar meaning using content embeddings Keeps content embeddings for narrative similarity Searchable fields Primarily searches document content and other configured fields Makes classifications such as root cause and detection method explicit searchable or filterable fields Semantic ranking Reranks the supplied candidate content for relevance Can also benefit from curated text fields when those fields are included and prioritised in the semantic configuration Query planning Translates the question into retrieval over content, optionally with application-defined filters Uses the metadata taxonomy to generate field-specific boosts or filters where appropriate There is an important nuance here: traditional RAG can absolutely use metadata filters and hybrid search. So the contribution here isn't a new embedding algorithm, nor is metadata an alternative to vector search. It is about making structured knowledge a first-class retrieval signal, and wiring that information into candidate retrieval, ranking and Foundry IQ's agentic query planning rather than asking the system to infer every classification from document text. And importantly, in the comparison below, both approaches use the same Azure AI Search index. So the comparison isn't: vector search vs. metadata. It's: content-first retrieval vs. retrieval that can also use the structured information the organisation already knows. Measuring the impact Two knowledge bases were created over the same Azure AI Search index. The baseline searched title and content. The metadata-aware configuration used the same content plus structured metadata, semantic configuration and query hints. Ten questions were run through both configurations. Correctness was determined directly from the metadata attached to returned reviews, rather than by asking an LLM whether a result appeared relevant. For the question “What can be learned from outages caused by configuration changes?”, the planner generated: rootCauseCategory eq 'Configuration change' Matching reports in top 5 Score Baseline 0 Metadata-aware 3 Best possible 5 Across ten questions and four runs using gpt-5.4-mini for query planning, the baseline returned 26 matching reviews in the top five. The metadata-aware configuration returned 39 to 41, against a best possible score of 50. The gains appeared where metadata carried the missing meaning: Configuration changes: 0 → 3 Configuration changes reported by customers: 0 → 3 Capacity in production: 1 → 5 Alert fatigue: 3 → 5 Queries whose important terms already appeared in the document text scored 5/5 in both configurations. The result is therefore more specific than “metadata improves search”: metadata closes a retrieval gap when document text does not fully describe what the document represents. A failure mode worth handling Because query planning uses an LLM, the planner can occasionally generate a filter that the search index rejects. Two invalid examples observed during testing were: severity eq Sev1 changeRelated eq true The first omitted quotes around a string. The second treated an Edm.String field containing Yes and No as a Boolean. The latter caused the retrieve request to fail with HTTP 502. The fix was to make the schema and allowed values explicit: This is a text field, not a Boolean. The only valid values are 'Yes' and 'No'. Never compare the field with true or false. Application code should also handle retrieval failures rather than assuming every generated filter will be valid. Production considerations A custom index provides control, but the solution now owns ingestion. Options include the SharePoint indexer with custom columns, an Azure Function using Microsoft Graph, or an existing pipeline built with Logic Apps, Azure Data Factory or Microsoft Fabric. A custom Azure AI Search index does not automatically inherit the SharePoint permissions model. Where users have different document permissions, ACLs must be carried into ingestion and retrieval. Query hints should also be regenerated when taxonomy values change. Key takeaways Confirm that the required metadata reaches the index. Keep metadata structured rather than flattening it into one text field. Attach parent-document metadata to every chunk. Use search fields, semantic configuration, query hints and filters deliberately. Describe field types and valid values clearly in filter instructions. Evaluate against a baseline using objective correctness rules. Metadata-aware retrieval is not about making every search better. It gives the retrieval system access to context that does not exist in the document text. Try the proof of concept The complete proof of concept, synthetic dataset, index scripts, knowledge-base configurations and A/B evaluation harness are available in the GitHub - shikha-msft/foundryiq-metadata-agentic-rag. References Create a search index knowledge source Create a knowledge base Query a knowledge base via API or MCP What is Foundry IQ?449Views0likes0Comments
Amplify Healthcare Intelligence: Data, AI, and Agent-Powered Transformation
Join Microsoft for Amplify Healthcare Intelligence, a webinar and in-person workshop series designed for healthcare and life sciences organizations building the foundation for trusted AI. Every session starts from the same premise: you cannot deliver trusted AI without a trusted data foundation. Across the series you will see how leading organizations unify their data estate, ground AI agents in real business context, and turn that foundation into results they can measure. What You Will Learn How to build a unified, AI-ready data foundation across a fragmented healthcare data estate How to ground AI agents in trusted healthcare data and real business context How to modernize analytics while reducing complexity and cost How to accelerate innovation with Microsoft Fabric, Azure AI Foundry, Microsoft IQ, and Copilot technologies How to deliver measurable impact across clinical, operational, research, and business scenarios Whether you are defining your AI strategy, modernizing your analytics platform, or scaling AI across your organization, these sessions offer practical guidance, real-world customer examples, and hands-on learning to help you move from AI ambition to business impact. Webinars & In-Person Workshops 🎥 Webinars One-hour virtual sessions with actionable guidance, live demonstrations, customer stories, and best practices from Microsoft experts. Each webinar shows how leading healthcare organizations are turning data, AI, and enterprise intelligence into measurable business outcomes. All sessions are from 3-4 ET (12-1 PT) and are free to attend. Date Topic Register Oct 28 3-4 ET (12-1 PT) Reduce BI Sprawl, Cut Cost and Build an AI-Ready Analytics Foundation Register Nov 11 3-4 ET (12-1 PT) Connecting Microsoft Fabric with ExpressRoute: Enterprise Network Architecture Register Nov 18 3-4 ET (12-1 PT) From Question to Visuals: Data Insights with Fabric, Rayfin & GitHub Copilot Register Dec 2 3-4 ET (12-1 PT) The Intelligent Healthcare Enterprise: Microsoft IQ in Action Register Dec 9 3-4 ET (12-1 PT) From Trusted Data to Action: Microsoft Fabric + Copilot Cowork for Healthcare & Life Sciences Register Cannot join live? Register anyway. We will send you the recording and session materials after the event. Additional sessions will be added through the end of the year, so check back or register for one session to be notified as new dates are announced. 🏢 In-Person Workshops Our two-day workshops combine executive strategy, healthcare-specific use cases, architecture guidance, and hands-on labs designed to help teams identify and accelerate high-value AI opportunities. Attendance is free. Participants are responsible for their own travel and accommodation, and space at each location is limited. Workshops run 9am to 4pm local time on both days. Day 1: From Healthcare Data to Healthcare Intelligence Day 1 focuses on healthcare transformation strategy, customer examples, and the architectural patterns that make trusted AI possible at scale. The day closes with a networking reception and peer exchange. The Frontier Transformation imperative: from AI ambition to measurable impact Microsoft IQ: turning data into enterprise intelligence Building the unified data foundation Building trusted AI: security, governance, privacy, and compliance Healthcare transformation in action: clinical, operational, research, and finance scenarios Activating data with AI data agents and Copilot experiences Day 2: Hands-On Healthcare AI and Analytics Lab Day 2 is a guided, end-to-end lab. Participants build a working healthcare intelligence solution from raw data through to a grounded AI agent, using Microsoft Fabric, Azure AI Foundry, Copilot technologies, and modern data architectures. Build the foundation: data ingestion, lakehouse architecture, and data engineering Create actionable insights: semantic models and dashboards Prepare data for AI: AI-ready data assets and data governance Build and ground AI agents in trusted enterprise data From insight to intelligent action: planning your organization's next steps What to bring: a laptop with a current browser. Lab environments and credentials are provided on site, and no prior Fabric or Foundry experience is assumed. Date City Venue Register November 10-11, 2026 9am - 4pm Chicago Microsoft Chicago (AON Center) 200 East Randolph Drive, Suite 200 Chicago, IL 60601 Register December 8-9, 2026 9am - 4pm New York Microsoft Garage 300 Lafayette Street New York, NY 10012 Register Who Should Attend This series is built for the people who own the data estate and the people who depend on it. Sessions are technical enough for practitioners and strategic enough for the leaders who prioritize the work. Data & analytics leaders Data platform, data engineering, and business intelligence teams Data architects, engineers, and data scientists AI and innovation leaders Healthcare and life sciences executives Clinical, operational, research, and finance transformation leaders No prior Microsoft Fabric or AI experience is required for any session in this series. Questions Contact Camille Whicker if you have any questions about our upcoming events.Azure OpenAI Decisions API: Now generally available in Microsoft Foundry
AI applications and agents do more than generate content. They constantly make decisions about what should happen next. Which model should handle this request? Is a customer issue urgent? Did an agent’s output meet the required criteria? Should a workflow continue, try another approach, or involve a person? As agents become more sophisticated, these decisions can happen hundreds or even thousands of times across a workflow, and not every one of them requires a full generative response. On October 22, we brought the OpenAI Decisions API to Microsoft Foundry, giving developers a purpose-built way to make fast, focused decisions across AI applications and agentic workflows. The Decisions API evaluates text, images, and structured inputs and turns them into actionable choices, probabilities, and scores. It brings intelligence directly into the control flow of an application, helping developers determine what should happen next without relying on traditional generative inference for every step. This represents an important evolution in how models can be used within AI systems. Sometimes you need a model to create. Sometimes you need it to reason deeply across a complex problem. And sometimes, the most valuable thing a model can do is make a focused decision that helps the rest of the system move forward. Decision-making is becoming a core part of agentic applications Consider an AI customer service agent handling an incoming request. Before it generates a response, the application may need to understand what the customer is asking about, determine how urgent the issue is, identify which model or tool is best suited to handle it, and decide whether specialized expertise is required. Once a response has been generated, the application may need to evaluate it again, determining whether it adequately addressed the customer's issue, met the application's requirements, or should be escalated for human review. For an agentic workflow, that distinction can be significant. Before work begins, an application can evaluate an incoming request and route it to the right model or tool. During execution, an agent can assess possible actions and choose the appropriate next step. After another model completes a task, the application can evaluate the output against defined criteria and decide whether to continue, retry, take a different path, or bring a person into the workflow. Before work begins: Evaluate an incoming request and route it to the right model or tool. During execution: Assess possible actions and choose the appropriate next step. After a task completes: Evaluate the output against defined criteria and decide whether to continue, retry, take a different path, or bring a person into the workflow. These decisions may be small individually, but collectively they shape how an agent behaves. Giving developers a model designed specifically for these moments creates an opportunity to build systems that can make these choices efficiently while reserving more computationally intensive reasoning and generation for the parts of the experience that need them. Turn inputs into decisions your application can use The Decisions API gives developers a dedicated endpoint for evaluating inputs against questions they define. Each question supports one of three focused outcomes: a probability, a choice from a predefined set of options, or a score against a defined rubric. Instead of parsing generated text to determine what a model meant, application code can work with defined values designed to inform what happens next. Probability: Determine whether a condition is true and return a confidence value. Multiple choice: Select from a predefined set of options. Rubric scoring: Score an input against defined criteria. Instead of parsing generated text to determine what a model meant, application code can work with defined values designed to inform what happens next. Use the right model for the right moment What makes this especially powerful is the impact on real-world agentic applications. As agents become more sophisticated, they make hundreds or even thousands of decisions across workflows. The latency and cost of each decision can quickly compound. With the Decisions API, developers can bring intelligence directly into these critical decision points, from dynamically routing requests and prioritizing customer issues to evaluating agent outputs and deciding when human intervention is needed. This is an important shift from using AI primarily to generate content toward using AI to drive responsive, efficient, and intelligent systems. For developers, the opportunity isn't simply to build agents capable of doing more. It's to make those agents faster, more cost-efficient, and practical to operate at enterprise scale. That could mean routing a request to the appropriate model rather than automatically using a larger model, prioritizing customer issues before an agent begins working on them, or evaluating an agent's output before deciding whether a workflow can continue autonomously. In each of these cases, the model isn't responsible for producing the final experience. It's helping the application intelligently decide how that experience should unfold. Building AI systems that can decide what comes next The broader shift here is from thinking about AI primarily as something that generates an answer to thinking about intelligence as something that can be embedded throughout an application. Generative models remain essential for creating, reasoning, and interacting with users, but increasingly sophisticated agents also need intelligence between those moments to continuously determine what to do next. Developers can use it alongside other models to create workflows where reasoning, generation, evaluation, routing, and decision-making each happen where they make the most sense. As those workflows become longer and more autonomous, having a focused way to make the many smaller decisions along the way can become just as important as the models performing the largest tasks. Get started with the Decisions API For developers, the Decisions API is available through a dedicated /openai/v1/decisions endpoint on an Azure OpenAI resource and is available with GPT-6 Luna. Developers can call the endpoint using OpenAI SDKs or REST, pass their GPT-6 Luna deployment name in the model field, and authenticate using an API key or Microsoft Entra ID. Learn more about the Decisions API → Learn how it works here. Try the Decisions API in Microsoft Foundry → https://ai.azure.com As we continue expanding the models and capabilities available through Microsoft Foundry, I'm particularly excited about what this unlocks for developers building the next generation of AI applications. The opportunity isn't simply to give agents access to increasingly capable models. It's to build systems that can apply the right intelligence at the right moment, from the complex reasoning and generation that users see to the many decisions happening behind the scenes. The next generation of AI applications won't just be defined by how well they generate. They'll also be defined by how intelligently and efficiently they decide what to do next. Pricing (per 1M tokens) Decision API supported model Input Output Cached input 30-minute cached write GPT-6 Luna $0.10 N/A $0.01 $0.125 Start building with the Azure OpenAI Decisions API in Microsoft Foundry today to bring reliable, structured decision-making to your apps and agents.2.1KViews2likes0CommentsFoundry Fine-Tuning: open-source model expansion, MAI-Code, and shared multi-LoRA deployments
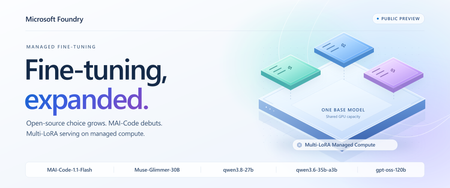
Today, Microsoft Foundry Managed Fine-Tuning expands its collection with four new open-source models and brings MAI-Code-1.1-Flash to Foundry resources, all in public preview. Alongside them, Multi-LoRA Managed Compute deployments enter public preview, letting compatible adapters share base-model weights and GPU capacity instead of each needing a separate serving allocation. More open-source choice for your next custom model Muse-Glimmer-30B, qwen3.8-27b, qwen3.6-35b-a3b and gpt-oss-120b join Foundry's managed open-source model collection, with supervised fine-tuning (SFT) support across all four. You can now bring your example-driven customization workflow to more backbones, choosing for tool-use reliability, coding efficiency, extended planning or reasoning capacity. Here's what each option brings: Model Why put it on your shortlist? Muse-Glimmer-30B Resilient tool orchestration: precise tool calls, interpreting unexpected results and recovering when a workflow goes off-script. qwen3.8-27b Extended research and planning: a dense backbone for sustained autonomous work that adapts to feedback from its environment. qwen3.6-35b-a3b Repository and frontend coding: a sparse mixture-of-experts backbone for navigating codebases and making coordinated changes. gpt-oss-120b Reasoning headroom: a higher-capacity alternative to the existing gpt-oss-20b option for difficult analytical and problem-solving tasks. Use SFT to tailor these models to your application's needs: Coding conventions: organization-specific library usage and preferred implementation patterns. Structured outputs: JSON schemas and extraction responses used by downstream applications. Domain workflows: product terminology, support tone, and classification or triage decisions. Distillation: use teacher-generated example responses to specialize a smaller model for your task. All four also support reinforcement fine-tuning (RFT) if your workflow calls for more advanced, reward-based optimization. MAI makes its fine-tuning debut in Foundry In addition to the open-source models above, we're introducing MAI-Code-1.1-Flash, the first Microsoft model available for Managed Fine-Tuning on Foundry resources. With the base model already available in GitHub Copilot, this compact, coding-focused model brings particular strengths in software development tasks. Its emphasis on responsiveness and token efficiency makes it a compelling backbone for repeated edit-build-test loops, where inspecting code, proposing edits and responding to compiler or test feedback all contribute to the task's latency and token budget. MAI-Code-1.1-Flash supports RFT only in this preview. Use it to target outcomes you can verify: a change that passes task-specific tests, correctly uses an internal software library, or satisfies your repository's acceptance checks. Build rewards around correctness and the required scope of the change, rather than whether an answer reproduces a reference patch. That leaves room for different valid solutions while keeping the customization anchored to your engineering requirements. Share hardware across adapters to reduce serving costs Previously, Foundry's managed fine-tuning outputs went to serverless pay-as-you-go deployments: input/output token charges plus hosting fees for each fine-tuned deployment. More traffic increased usage charges; more deployed variants added hosting costs. With Multi-LoRA adapter deployment on Managed Compute, compatible adapters share LoRA-enabled base-model deployment and GPU capacity. You pay an hourly rate for that hardware, rather than per-token inference charges, so multiple customizations can use one serving allocation instead of funding separate GPU footprints. Three task-specific qwen3.8-27b adapters, for example, can share a LoRA-enabled base deployment while remaining separately addressable. When their combined traffic fits, adding an adapter doesn't mean another hardware bill. You avoid duplicating base-model serving capacity and can improve utilization by pooling requests across variants, instead of paying separate serverless hosting fees for each one. The tradeoff is utilization: running hardware is billed even when idle, so size for aggregate concurrency and context lengths. More traffic can require additional capacity, while serverless remains an option for intermittent workloads on eligible models. The managed compute deployment path supports Muse-Glimmer-30B, both new Qwen models and gpt-oss-120b. Adapters must match the same base model and version; the base deployment needs a compatible LoRA-enabled template. Accelerator quota is required. Put the new models to work in your agents The expanded model collection helps you pick a backbone suited to your tasks; Multi-LoRA lets compatible customizations share serving capacity. These choices come together in agent applications, where different roles can need different model behavior. A coding assistant and a code-review agent, for example, can use separate adapters on the same supported OSS base model while sharing the hardware that serves them. Fine-tuning customizes model behavior, but the goal is to improve the agent application that uses it. Connect your tuned models to your agent applications in Foundry and evaluate them alongside the instructions, tools and workflows they'll use in production. That keeps customization focused on better application outcomes, not just better training results. Put these new capabilities behind your agent's next iteration. Get started with Foundry Fine-Tuning today.468Views2likes0CommentsAzure Incident Retrospective - Please register! Session 2 - Tracking ID: 7QL5-Z50
Join our upcoming live webcast for a transparent discussion about this recent Azure service incident led by our engineering teams. AOAI/Foundry – Intermittent failures in Sweden Central Tracking ID: 7QL5-Z50 | Impacted: 29 September 2026 Same content presented in both sessions: pick the one that works best for your timezone! What to expect 📚 Understand What happened, how we responded, and what we learned 💬 Ask Live Q&A with our engineering experts throughout the session 🛠 Learn The fixes we've put in place and guidance for workload resiliency Choose your session Same content presented at both times: pick the one that works best for your timezone: Session 1 17:30 UTC Thursday, 22 Oct 2026 Register now → Session 2 05:30 UTC Friday, 23 Oct 2026 Register now → 10:30 AM US Pacific (PDT) 1:30 PM US Eastern (EDT) 6:30 PM London (BST) 1:30 AM Beijing (CST) 4:30 AM +1 Sydney (AEDT) 6:30 AM +1 Auckland (NZDT) 10:30 PM -1 US Pacific (PDT) 1:30 AM -1 US Eastern (EDT) 6:30 AM London (BST) 1:30 PM Beijing (CST) 4:30 PM Sydney (AEDT) 6:30 PM Auckland (NZDT) Our engineering leader Bhuwan Sahni Partner, Software Engineer CoreAI Engineering LinkedIn ↗ ⚠️ Prepare before the livestream Read the Post Incident Review (PIR) ahead of time so you can ask any follow up questions during the live Q&A Helpful resources 🔔 Azure Service Health Alerts Get alerts for relevant incidents by setting up notifications via email, SMS, or webhook 🎥 Past Retrospective Recordings Watch recordings of previous retrospective livestreams 📄 Azure Post Incident Reviews Learn more about PIRs and the retrospective program116Views0likes0CommentsAzure Incident Retrospective - Please register! Session 1 - Tracking ID: 7QL5-Z50
Join our upcoming live webcast for a transparent discussion about this recent Azure service incident led by our engineering teams. AOAI/Foundry – Intermittent failures in Sweden Central Tracking ID: 7QL5-Z50 | Impacted: 29 September 2026 Same content presented in both sessions: pick the one that works best for your timezone! What to expect 📚 Understand What happened, how we responded, and what we learned 💬 Ask Live Q&A with our engineering experts throughout the session 🛠 Learn The fixes we've put in place and guidance for workload resiliency Choose your session Same content presented at both times: pick the one that works best for your timezone: Session 1 17:30 UTC Thursday, 22 Oct 2026 Register now → Session 2 05:30 UTC Friday, 23 Oct 2026 Register now → 10:30 AM US Pacific (PDT) 1:30 PM US Eastern (EDT) 6:30 PM London (BST) 1:30 AM Beijing (CST) 4:30 AM +1 Sydney (AEDT) 6:30 AM +1 Auckland (NZDT) 10:30 PM -1 US Pacific (PDT) 1:30 AM -1 US Eastern (EDT) 6:30 AM London (BST) 1:30 PM Beijing (CST) 4:30 PM Sydney (AEDT) 6:30 PM Auckland (NZDT) Our engineering leader Bhuwan Sahni Partner, Software Engineer CoreAI Engineering LinkedIn ↗ ⚠️ Prepare before the livestream Read the Post Incident Review (PIR) ahead of time so you can ask any follow up questions during the live Q&A Helpful resources 🔔 Azure Service Health Alerts Get alerts for relevant incidents by setting up notifications via email, SMS, or webhook 🎥 Past Retrospective Recordings Watch recordings of previous retrospective livestreams 📄 Azure Post Incident Reviews Learn more about PIRs and the retrospective program129Views0likes0Comments
Introducing Dragon HD Omni: Azure Speech New Voice Type Now in Preview via Microsoft Foundry
Dragon HD Omni is Microsoft Azure Speech’s newest text‑to‑speech generation, delivering over 700 high‑quality voices with enhanced expressiveness, multi‑lingual fluency, and multi‑style control — all through a unified model built in Microsoft Foundry. It removes common developer pain points such as unnatural voice prosody, limited language coverage, and heavy SSML tuning effort. The result is a powerful value proposition: faster integration, richer user experiences, and production‑ready voice output with minimal effort. Azure speech offers a broad range of unique voices for applications like virtual agents, audiobooks, podcasts, and speech-to-speech tasks. Demo video 700+ prebuilt voices Dragon HD Omni offers a range of prebuilt voices with distinct personas and emotions, supporting diverse use cases from agent-based applications to content creation. These voices unlock endless possibilities, empowering users to enhance end-to-end applications. Full update for previous generation voices Dragon HD Omni merges a wide range of prebuilt voices into one, improving contextual adaptation, prosody, expression, and keeping each voice's unique character. This technology delivers more accurate, flexible, and lifelike speech for a variety of uses. Dragon HD Omni raises the standard for natural AI voices across customer service, accessibility, and creative projects, advancing human-computer interaction. You can explore some voices from voice list, such as: "en-US-Ava:DragonHDOmniLatestNeural" "en-US-Andrew:DragonHDOmniLatestNeural" "en-US-Dana:DragonHDOmniLatestNeural" "en-US-Caleb:DragonHDOmniLatestNeural" "zh-CN-Xiaoyue:DragonHDOmniLatestNeural" "zh-CN-Yunqi:DragonHDOmniLatestNeural" "en-US-Phoebe:DragonHDOmniLatestNeural" "en-US-Lewis:DragonHDOmniLatestNeural" They will be available to try directly via Speech Playground - Microsoft Foundry Or, you can use this voice name format by adding the suffix `:DragonHDOmniLatestNeural` to try the Omni version of the given voice via direct SSML call. For example: Previous neural voice Omni version voice name de-DE-ConradNeural de-DE-Conrad:DragonHDOmniLatestNeural AI-Generated Voices Dragon HD Omni now features nearly 300 brand‑new AI‑generated voices, carefully designed to deliver an unprecedented range of vocal diversity. These voices aren’t just more of the same — they’re built to give you choice, flexibility, and creative control. With variations across: Gender – male, female, and non‑binary options Age – youthful, mature, and senior tones Pitch & tone – from warm and friendly to authoritative and professional This expanded library means you can: Personalize experiences for different audiences, whether you’re building an educational app, a customer support bot, or a storytelling platform. Strengthen brand identity by selecting voices that reflect your company’s personality and values. Increase inclusivity with diverse vocal styles that resonate across cultures and communities. Unlock creativity by experimenting with unique voice personalities for podcasts, games, or immersive experiences. Speaker name – Description Sample en-us-graphiterhodium - A bold and dramatic male voice en-us-olivepoivre - An adult female voice that is calm and soothing. Check the full Dragon HD Omni voice list at here. Styles control Standard Azure voices have limited styles due to extensive tuning requirements. The Dragon HD Omni introduces automatic style prediction using natural language descriptions, enabling advanced customization, broader style support, reduced cost, and improved expressiveness. In the initial release, styles will launch for en-US-Ava and en-US-Andrew. Supported styles angry, chill surfer, confused, curious, determined, disgusted, embarrassed, emo teenager, empathetic, encouraging, excited, fearful, friendly, grateful, joyful, mad scientist, meditative, narration, neutral, new yorker, news, reflective, regretful, relieved, sad, santa, shy, soft voice, surprised Note that style result will be strongly influenced by the input content. SSML example <speak version="1.0" xmlns="http://www.w3.org/2001/10/synthesis" xmlns:mstts="http://www.w3.org/2001/mstts" xml:lang="en-US"> <voice name="en-us-ava:DragonHDOmniLatestNeural"> <mstts:express-as style="cheerful"> Wow! What an amazing day! I feel so full of energy, and everything around me seems brighter. My voice is bubbling with excitement, and I can’t stop smiling. I’m ready to take on anything that comes my way—let’s celebrate this wonderful moment together! </mstts:express-as> </voice> </speak> Multilingual and Accents All Dragon HD Omni voices support multiple languages, with the capability that can automatically predicting and generating output based on the input text. Additionally, you may utilize the tag to adjust speaking languages and accents, such as fr-FR for French, de-DE for German, etc. For a comprehensive list of supported languages and their associated syntax and attributes, please refer to the lang element. SSML example <speak version="1.0" xmlns="http://www.w3.org/2001/10/synthesis" xmlns:mstts="http://www.w3.org/2001/mstts" xml:lang="en-US"><voice name="en-us-ava:Dragon HD OmniLatestNeural"><lang xml:lang="fr-FR"> Bonjour ! Ce matin, j’ai pris un café au jardin du Luxembourg. Il faisait frais, mais très agréable. Ensuite, j’ai acheté une baguette et quelques macarons. Paris est vraiment charmant.</lang> </voice> </speak> Word Boundary Event Support Dragon HD Omni supports the word boundary event, which allows developers to track the precise timing of each word as it is spoken. This feature is essential for applications requiring word-level synchronization, such as karaoke, real-time captioning, or interactive voice experiences. When the event fires, it provides: Text: The word spoken AudioOffset: The time offset in the audio stream (milliseconds) TextOffset: The position of the word in the input text Example: Python Sample Using Wordboundary Event in Azure Speech SDK import azure.cognitiveservices.speech as speechsdk def word_boundary_cb(evt): print(f"Word: '{evt.text}', AudioOffset: {evt.audio_offset / 10000}ms, TextOffset: {evt.text_offset}") speech_config = speechsdk.SpeechConfig(subscription="YourSubscriptionKey", region="YourServiceRegion") synthesizer = speechsdk.SpeechSynthesizer(speech_config=speech_config) synthesizer.synthesis_word_boundary.connect(word_boundary_cb) ssml = """ <speak version="1.0" xmlns="http://www.w3.org/2001/10/synthesis" xmlns:mstts="http://www.w3.org/2001/mstts" xml:lang="en-US"> <voice name="en-us-ava:DragonHDOmniLatestNeural"> Hello Azure, welcome to Dragon HD Omni! </voice> </speak> """ result = synthesizer.speak_ssml_async(ssml).get() Sample Output: Word: 'Hello', AudioOffset: 110.0ms, TextOffset: 182 Word: 'Azure', AudioOffset: 590.0ms, TextOffset: 188 Word: ',', AudioOffset: 1110.0ms, TextOffset: 193 Word: 'welcome', AudioOffset: 1270.0ms, TextOffset: 195 Word: 'to', AudioOffset: 1750.0ms, TextOffset: 203 Word: 'Dragon HD Omni', AudioOffset: 1910.0ms, TextOffset: 206 Word: '!', AudioOffset: 2750.0ms, TextOffset: 216 Parameters Dragon HD Omni supports advanced parameter tuning to help you customize voice output for different scenarios. This guide explains each parameter in simple terms and provides recommendations for adjusting them based on your goals. Overview Parameter Default Range Purpose temperature 0.7 0.3 – 1.0 Controls creativity vs. stability top_p 0.7 0.3 – 1.0 Filters output for diversity top_k 22 1 – 50 Limits number of options considered cfg_scale 1.4 1.0 – 2.0 Adjusts relevance and speech speed Tuning for Expressiveness vs. Stability Higher values for temperature, top_p, and top_k result in more expressive, emotionally varied speech. Lower values produce more stable and predictable output. Recommendation: To increase expressiveness, raise all three parameters together. Keep top_p equal to temperature for best results. Tuning for Speed and Contextual Relevance cfg_scale affects how quickly the voice speaks and how well it aligns with the context. Higher values (e.g., 1.8–2.0): faster speech, stronger contextual relevance. Lower values (e.g., 1.0–1.2): slower speech, less contextual alignment. Suggested Tuning Strategies Goal Suggested Adjustment More expressive Increase temperature, top_p, and top_k together More stable Lower temperature first, then adjust top_p if needed Faster & relevant Increase cfg_scale Slower & neutral Decrease cfg_scale The following table describes the usage of the parameters above: Single parameter: <speak version="1.0" xmlns="http://www.w3.org/2001/10/synthesis" xmlns:mstts="http://www.w3.org/2001/mstts" xml:lang="en-US"> <voice name="en-us-ava:Dragon HD OmniLatestNeural" parameters="top_p=0.8"> Hello Azure! </voice> </speak> Multiple parameters: <speak version="1.0" xmlns="http://www.w3.org/2001/10/synthesis" xmlns:mstts="http://www.w3.org/2001/mstts" xml:lang="en-US"> <voice name="en-us-ava:Dragon HD OmniLatestNeural" parameters="top_p=0.8;top_k=22;temperature=0.7;cfg_scale=1.2"> Hello Azure! Hello Azure! </voice> </speak> Get Started In our ongoing journey to enhance multilingual capabilities in text to speech (TTS) technology, we strive to deliver the best voices to empower your applications. Our voices are designed to be incredibly adaptive, seamlessly switching between languages based on the text input. They deliver natural-sounding speech with precise pronunciation and prosody, making them invaluable for applications like language learning, travel guidance, and international business communication. Microsoft offers an extensive portfolio of over 600 neural voices, covering more than 150 languages and locales. These TTS voices can quickly add read-aloud functionality for a more accessible app design or provide a voice to chatbots, elevating the conversational experience for users. With the Custom Neural Voice capability, businesses can also create unique and distinctive brand voices effortlessly. With these advancements, we continue to push the boundaries of what’s possible in TTS technology, ensuring that our users have access to the most versatile, high-quality voices for their needs. For more information Try our demo to listen to existing neural voices Add Text to speech to your apps today Apply for access to Custom Neural Voice Join Discord to collaborate and share feedback Contact us ttsvoicefeedback@microsoft.com4.9KViews0likes1CommentClosing the AI Agent Governance Gap with Microsoft Foundry
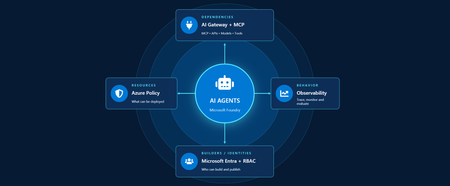
Developers are shipping agents faster than security teams can catalog them. As organizations move beyond pilots and begin operating dozens or hundreds of agents, one question keeps coming up: how do we actually get visibility into our AI agents across our environment? In this article, we'll walk through how Azure services can help establish visibility, guardrails, and cost accountability across your AI estate. Governance for AI happens across four layers: Resources – who can create new AI resources Builders – who can develop and publish agents in a certain scope Behavior – how agent outputs are evaluated, monitored, and governed Dependencies – what models, tools, APIs, and MCP servers agents can interact with Most organizations already have governance controls for identities, networking, and compliance. The challenge isn't creating new controls. It's connecting existing controls into an operating model that works for AI agents. Below we walk through each area and go a bit deeper on how to close the gap. Setting up boundaries with Azure Policy First, let's start in the Azure portal with Azure Policy. Azure Policy lets you set guardrails on what can be deployed in your environment and flags or blocks anything that doesn't comply. For AI workloads, the built-in definitions range from limiting models that people in your organization can deploy to locking down the network through enabling private endpoints. Some policies you get started with: Foundry model deployments should only use approved models: Restricts deployments to models or publishers your organization has explicitly approved Foundry model deployments should meet eligibility requirements (preview): Applies rules based on model attributes like preview vs. GA status and distribution source Azure AI Services resources should have key access disabled: Makes Microsoft Entra ID the only entry point The full list of policies related to Azure AI Services are available here: List of built-in policy definitions - Azure Policy | Microsoft Learn Why this comes first: Policy checks resources before they are created, so it proactively keeps your environment aligned with your standards. Implementing role-based access control (RBAC) Once these boundaries are in place, the next step is RBAC. Setting RBAC up early ensures that people and identities building agents have the right scope for what they actually need to do. Foundry roles only apply when you authenticate using Microsoft Entra ID. If you're using key-based authentication instead, the key grants full access with without role restrictions. API keys are convenient for quick development usage but when moving towards production, Microsoft Entra ID is the preferred method. Roles can be assigned at three scopes: the Foundry resource, a Foundry project, or an individual agent itself. Below is an example of how different personas within organization can map to a certain scope for creating and building agents with Foundry. Here's how each role in the diagram compares, from least to most privileged: Role Privilege Level What it does in Microsoft Foundry Foundry Agent Consumer Least Interact with agent endpoints in a project. This is your least-privilege role for people who only need to use agents. Foundry User Low Grants reader access to the Foundry project, the Foundry resource, and data actions for your Foundry project. Least-privilege access role for developers building and testing agents. Foundry Project Manager Medium This role lets you perform management actions on Foundry projects, build and develop with projects, and conditionally assign the Foundry User role to other user principals. Foundry Account Owner Higher Grants full access to manage Foundry projects and resources, and lets you assign the Foundry User role to other user principals. Foundry Owner Highest Grants full access to manage Foundry projects and resources to build and develop with projects. This role can also assign the Foundry User, ACR, and monitoring roles to users in the environment. Source: Role-based access control for Microsoft Foundry - Microsoft Foundry | Microsoft Learn For the agent resources themselves, assign managed identities rather than API keys since it lowers the risk of having compromised credentials. Note if you're scripting RBAC permissions: these roles were recently renamed from Azure AI User, Azure AI Owner, Azure AI Account Owner, and Azure AI Project Manager. The role IDs and permissions didn't change, so use the role definition GUID in your code to avoid issues while the rename rolls out. Observability in Microsoft Foundry Governance requires more than access control. Organizations also need evidence of how agents are being used. Observability provides the audit trail needed to investigate incidents, understand usage patterns, and track costs. The Foundry Control Plane brings these observability and governance tools together in one place, alongside services like Azure Monitor, Microsoft Entra, Microsoft Purview, and Azure Policy. In the Foundry portal, tracing is a good starting point. Once you connect an Application Insights resource to your project, Foundry turns on tracing automatically so every run, including the ones you test in the playground, is logged. After it is completed, you can search by Response ID or Trace ID to see the conversation history, token usage, run steps, tool calls, and inputs and outputs between the user and the agent. For more granular queries, you can write KQL to dive into individual agent runs or use the prebuilt Grafana dashboards in Azure Monitor. With client-side tracing, you can also export traces to observability tools you may already use, such as Datadog or Jaeger. Note: Permissions required for viewing this telemetry requires the Log Analytics Reader role on the connected Application Insights resource, and Privileged Monitoring Data Reader on top of that if the underlying Log Analytics tables are protected. Alongside all of these monitoring features, every agent comes with content safety guardrails and evaluations let you test and optimize performance before and after you publish your agents. When agents get published to Microsoft Teams and Microsoft 365 Copilot, Microsoft 365 admins can approve usage requests. These requests can be further scoped to a limited group for pilot testing/department usage or the full organization. Adding an AI gateway Observability tells you what your agents are doing, but how do you actually control them? This is where Azure API Management comes in. Once you have more than one agent, model deployment, or multiple teams consuming them, you need a single enforcement point between the agents and the resources they call. Adding Azure API Management in front of Microsoft Foundry gives you: Rate limiting and load balancing across regions and model deployments Consistent authentication and quota policies for model and tool traffic Usage tracking per team or cost center so you can accurately charge back to different departments Governed access to your custom and remote MCP servers Note: When choosing MCP servers, start with trusted, enterprise supported sources (GitHub, Microsoft, internally developed servers, etc.) that have documented security controls, enterprise authentication, clear ownership, and least-privilege permissions. Treat community MCP servers as untrusted until they have undergone a formal security review and are verified by organizations. Adding an AI gateway completes the governance picture. Azure Policy governs what can be deployed. RBAC governs who can build and manage agents. Observability provides evidence of how agents behave in production. The AI gateway extends governance into runtime, controlling how agents interact with models, tools, and external systems. Combined, these layers help organizations move beyond simply building agents to operating them responsibly at scale. Extend governance across the wider estate A few directions to take this further: MCP registry in Azure API Center – As MCP usage grows, you can create an approved inventory of MCP servers and APIs that can be used across an organization. Microsoft Agent 365 – Microsoft's enterprise control plane for AI agents. It gives every agent its own Microsoft Entra Agent ID and published Foundry agents sync to its registry automatically. This gives your IT team one place to run access reviews, lifecycle policies, and owner attestation across every agent in the tenant, including shadow agents discovered outside Foundry. Copilot Studio – when you add an MCP tool, you can point it at the API Management URL instead of the direct remote endpoint to gain additional observability through the gateway. GitHub Copilot – you can apply the same AI gateway-fronted MCP registry, applied to the developer side. Microsoft Purview – data classification, DLP, audit, and AI interaction governance across the wider estate. Where to go next Looking for a quick start? Turn on the three Azure Policy definitions above in audit mode against a non-production subscription and see what gets flagged that is out of compliance. Ready to design the end-to-end pattern? Take a look at this Cloud Adoption Framework guidance on AI governance and governing Azure platform services for AI. Want to go deeper on agent observability? Start with these articles around Application Insights integrations with Foundry: Use Insights in Microsoft Foundry and Monitor AI Agents with Application Insights Governing AI agents doesn't require starting from scratch. The identity, policy, monitoring, and cost controls you already use for the rest of your Azure estate can extend to AI workloads. Start with one layer, connect the next, and build a governance foundation that grows with your AI adoption.730Views3likes0CommentsResource Guide: Making Physical AI Practical for Real‑World Industrial Operations
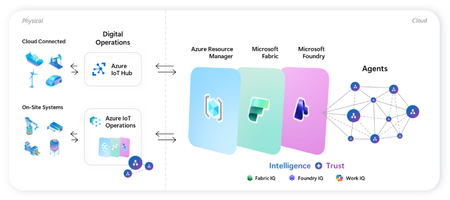
Microsoft's adaptive cloud approach brings cloud, edge, data, and AI together to help organizations turn operational technology (OT) data into intelligent action, without requiring everything to live in the cloud. At the center of this approach are key technologies that connect physical operations to cloud-scale data, analytics, and AI: Key Purpose Offering Direct-to-cloud device management + telemetry ingestion Azure IoT Hub Industrial connectivity + edge data plane Azure IoT Operations Unified analytics + real-time intelligence Microsoft Fabric On-device AI inferencing runtime Microsoft Foundry Industry recognition Microsoft named a Leader in the 2026 Gartner® Magic Quadrant™ for Global Industrial AIoT Platforms Read the announcement See it all come together Before diving into each component, watch this end-to-end demo showing how Azure IoT Operations, Azure IoT Hub, Microsoft Fabric, and Foundry Local work as one stack across the edge-to-cloud lifecycle - Making industrial AI practical for real-world operations with adaptive cloud. How these components work together Azure IoT Operations and Azure IoT Hub collect real-time data from operational assets and send semantically-ready, modeled data to Microsoft Fabric, where it's contextualized with enterprise data for downstream analytics. Microsoft Foundry extends to the edge through Foundry Local, so the same tooling used to deploy and manage AI models in the cloud applies to edge use cases. All of it integrates into Azure Resource Manager, bringing OT devices, assets, and edge AI models into the same management and security paradigm as every other Azure-managed resource. This blog walks through where to get started with each product capability: 1. Manage Cloud-Connected Devices and Telemetry with Azure IoT Hub Azure IoT Hub is a fully managed cloud service that enables secure bidirectional communication, device-to-cloud telemetry ingestion, cloud-to-device command execution, per-device authentication, remote management and more. Telemetry from IoT Hub can also be routed downstream into analytics platforms like Microsoft Fabric for visualization or AI modeling. Recommended Usage: Devices that utilize IoT Hub are distributed, stand-alone devices with fixed-functions. These devices typically do not require cloud-managed containerized workloads or cloud-managed proximal industrial protocol connectivity. Examples of appropriate device-to-cloud IoT Hub endpoint devices include water monitoring stations, vehicle telematics, distributed fluid level sensors, etc. Resources Current in-market services overview: IoT Hub: What is Azure IoT Hub? - Azure IoT Hub DPS: Overview of Azure IoT Hub Device Provisioning Service - Azure IoT Hub Device Provisioning Service ADU: Introduction to Device Update for Azure IoT Hub Building scalable solutions with Azure IoT platform: Best practices for large-scale IoT deployments - Azure IoT Hub Device Provisioning Service Scale Out an Azure IoT Hub-based Solution to Support Millions of Devices - Azure Architecture Center Azure IoT Hub scaling Try out our preview of new IoT Hub capabilities (integration with Azure Device Registry and Certificate Management) Learn more about these capabilities on our blog post: Azure IoT Hub + Azure Device Registry (Preview Refresh): Device Trust and Management at Fleet Scale… Integration with Azure Device Registry (preview): Integration with Azure Device Registry (preview) - Azure IoT Hub Microsoft-backed X.509 certificate management (preview): What is Microsoft-backed X.509 Certificate Management (Preview)? - Azure IoT Hub How to start with the preview: Deploy IoT Hub with ADR integration and certificate management (Preview) - Azure IoT Hub 2. Connect Industrial Assets with Azure IoT Operations Azure IoT Operations provides a unified data plane for the edge that runs on Azure Arc–enabled Kubernetes clusters and supports open industrial standards. It allows organizations to connect and capture equipment telemetry, normalize OT data locally, route hot-path signals to real-time analytics, securely manage layered industrial networks, and more. Edge‑processed data can then be sent upstream to Microsoft Fabric for AI‑driven analysis. Recommended Usage: Azure IoT Operations is intended to be the data plane for an adaptive cloud deployment extending the management, data, and AI capabilities of the Microsoft cloud to an on-prem device. This device binds to these cloud planes providing a platform for local data processing and intermittent connectivity. The target for these devices range from a small-gateway-style PC to a full data center. Azure IoT Operations endpoints enable cloud-managed containerized workloads and cloud-managed proximal industrial protocol connectivity. Examples of appropriate adaptive cloud and Azure IoT Operations endpoints include, on-robot computers, industrial machine controllers, retail store sensor/vision processing, and top-of-factory site infrastructure for line of business applications. Resources Azure IoT Operations Overview Azure IoT Operations Documentation Hub Releases · Azure/azure-iot-operations Quickstart: explore-iot-operations/quickstart at main · Azure-Samples/explore-iot-operations Latest release update: Open-source framework for scaling robotics from simulation to production on Azure + NVIDIA: microsoft/physical-ai-toolchain Demo video showcasing this in action: Making industrial AI practical for real-world operations with adaptive cloud How we built the demo: explore-iot-operations/quickstart at main · Azure-Samples/explore-iot-operations Edge-AI: microsoft/edge-ai: Production-ready Infrastructure as Code, applications, pluggable components, and… Latest Announcements & Blogs Making Physical AI Practical for Real-World Industrial Operations: Part 1 | Microsoft Community Hub Making Physical AI Practical for Real-World Industrial Operations: Part 2 | Microsoft Community Hub Introducing small form factor infrastructure: embed intelligence into physical systems Unlock Industrial Intelligence | Microsoft Hannover Messe 2026 From pilots to production: How Microsoft and partners are accelerating intelligent operations Partner Solutions How Mesh Systems Builds on Azure IoT Hub and Azure IoT Operations to Accelerate Industrial AI | Microsoft Community Hub Unlocking the Human Telemetry Layer for Safer Industrial Operations | Microsoft Community Hub Unlocking Smart Manufacturing: Siemens Industrial Edge Meets Azure IoT Operations Solving the Data Challenge for Manufacturers with Sight Machine & Azure IoT Operations | Microsoft Community Hub Microsoft and Rockwell Automation: Transforming Industrial AI Together | Microsoft Community Hub 3. Advanced Analytics with Microsoft Fabric Microsoft Fabric delivers a unified, end‑to‑end analytics platform that transforms streaming OT telemetry into real‑time insights and live dashboards. Fabric Operations Agents monitor industrial signals to recommend targeted actions, while Fabric IQ provides a shared semantic foundation that enables AI agents to reason over enterprise data with business context. Together, Fabric turns live industrial data into AI‑powered operational intelligence. Resources Get Started with Microsoft Fabric Learning Path Fabric Real-Time Intelligence documentation - Microsoft Fabric | Microsoft Learn Create and Configure Operations Agents - Microsoft Fabric | Microsoft Learn Fabric IQ documentation - Microsoft Fabric | Microsoft Learn 4.Run AI Models On‑Device with Foundry Local Foundry Local extends on‑device AI to Arc‑enabled Kubernetes edge clusters, providing a Microsoft‑validated inferencing layer for running AI models in industrial, disconnected or sovereign environments. Resources Foundry Local on Azure Local Documentation Participate in Foundry Local on Azure Local preview form Foundry Local on Azure Local: HELM deployment Demo Customer Stories Chevron: Chevron plans facilities of the future with Azure IoT Operations Husqvarna: Husqvarna Group Boosts Operational Efficiency with Azure Adaptive Cloud Ecopetrol: Azure IoT Operations and Azure IoT for energy help Ecopetrol optimize energy distribution while lowering operational costs P&G: Procter & Gamble cuts model deployment time up to 90% with Azure IoT Operations Toyota: Toyota Industries innovates its paint shop processes with Azure industrial AI and Azure IoT Hub1.5KViews3likes0Comments
Your Agents Need More Than a Place to Run
In architecture reviews with enterprise teams moving their first agentic applications toward production, I often hear the same plan: the team has containerized their agent and intends to run it on the managed Kubernetes cluster the organization already trusts. The reasoning is sensible, since the platform team knows the tooling and security has approved the network model, and for the first use case or two it is often the right call. Having watched this unfold in my years leading AgenticAI customer engineers and forward deployed engineers, and now helping customers reach production on Azure, I want to describe what happens next, before leaders commit rather than after. One thing to note is Azure supports multiple ways to build and operate agents. Foundry Agent Service provides an integrated managed runtime around your agent code. Azure Kubernetes Service supports teams that need Kubernetes-level control or want to extend an established platform, while Azure Container Apps provides managed container hosting. These services can work together. The decision is which capabilities and responsibilities best fit the workload. Where the cluster is the right answer A stateless retrieval application, a document extraction pipeline, or a classification job is a web service that happens to call a model, and a container platform runs web services well. A large retail customer of mine ran an invoice extraction agent on containers for over a year with almost no issues, and I never suggested they move it. The cluster remains the right home for several other situations as well. LLM invocations embedded inside existing microservices, event driven, or batch pipelines fit container platforms naturally. Genuine constraints such as air-gapped or sovereign environment, regions where a managed service is not yet offered are a good reason to run your own stack, and strong engineering team that already operates at that level can be a real asset. Even when the agents themselves move to a managed runtime, the tool servers, business APIs, and data services those agents call, often stay on your cluster, so they are complementary far more often than they are competitors. The problem is that these early wins can make agents seem like just another workload. Where the wheels come off The first failure is the state. A research agent that plans, searches, and synthesizes for ninety minutes is a long-running stateful process, while a Kubernetes pod is a disposable container the scheduler may restart at any time. A financial services team I worked with lost costly research run to a routine node upgrade, and responded as capable engineers do by building checkpointing, a durable store, and a resume mechanism. It worked, but they now owned a piece of infrastructure they had to keep correct as their agent's framework changed beneath it. A managed agent runtime absorbs this. Hosted agents in Foundry Agent Service, as one example, give every session a VM-isolated sandbox with a persistent file system, a durable state store that survives crashes and restarts and can hold checkpoints for frameworks such as LangGraph or Microsoft Agent Framework, and a resilient execution mode that recovers long-running work after a process interruption. The second is the human-in-the-loop. A commercial insurance customer’s claims agent needed sign-off from an adjuster and sometimes a second reviewer, with days between steps. Stopping an agent cleanly at the moment it needs a decision, holding its full session for four days without paying to keep it running, and resuming it correctly when the approval arrives is not something a container orchestrator gives out the box. The team built agent session suspend and resume, a queue, a durable state store, notifications, and an approval interface, and ended up with a small workflow engine nobody had planned to own. In hosted agents, an idle session is deprovisioned with its state persisted and restored onto fresh compute when the same session ID returns, so an agent waiting on an approval cost nothing while it waits, and sessions are retained for up to thirty days of inactivity. The approval experience remains yours to design, which is where your engineers' time should go. The third is multi-turn conversation, which quietly pushes teams into building their own context management system. The first version appends each turn to history, and within few turns the history outgrows the context window while cost and latency climb. So, the team adds truncation, then summarization, then retrieval of earlier turns, then per-user and per-tenant scoping, then expiry and deletion rules for privacy. An industrial customer's safety compliance assistant, with conversations stretching across days, followed exactly this path and ended up with a bespoke thread store and summarization pipeline nobody had budgeted for. Its first serious incident came when a summary silently dropped a compliance-relevant instruction. With the Responses protocol in hosted agents in Foundry, conversation history is a durable, platform-managed record keyed by a conversation ID and reachable from any channel, so the thread store is no longer yours to build, although deciding what to summarize or retrieve remains a design choice for your agent. The fourth is identity. On a cluster, the path of least resistance is a shared service account, and in one review a security architect asked which actions had been taken on behalf of which user, only to learn that the logs could not say. Hosted agents create a dedicated Microsoft Entra agent identity for each agent at deploy time, use on-behalf-of flows to act with the user's delegated permissions in interactive scenarios and the agent's own identity in autonomous ones, and keep the agent identifiable for audit in both cases. The fifth is per-user session isolation, which is the difference between an agent that serves many people and an agent that mixes them up. Agents read files, run code, and hold working data, and on a shared pod the default is that many users share a process, a file system, and often a cache. Giving every user session its own sandboxed environment and storage, so that one person's documents and intermediate results can never surface in another's, means engineering hard isolation boundaries and proving them to your security team. Hosted agents make a VM-isolated sandbox per session the default, and their durable state store can partition items per end user, so one store is safe to share across the users of a multitenant agent. And lastly, Evaluation and optimization are where the gap widens. The largest difference between teams that scale and those that stall is evaluation. Because agents are probabilistic and multi-step, staging tests often miss failures such as a wrong tool choice or a policy violation deep in a task. One customer’s agent passed every offline check but degraded unnoticed for weeks after a model update because evaluation stopped at release. Mature teams continuously evaluate production traces, combine automated judges with sampled human review, and red-team regularly.Once quality is measurable, teams can deliberately balance prompts, models, tools, latency, and cost. One team cut per-task cost by routing simple steps to smaller models after evaluation confirmed quality held. Self-built stacks require teams to assemble and maintain tracing, datasets, judges, and release gates. Hosted agents instead combines default OpenTelemetry traces with continuous evaluation, adversarial testing, and datasets generated from agent instructions. Staged closed-loop optimization uses those traces to improve instructions, tool descriptions, and model selection without extra plumbing. The real cost is the velocity gap Leaders usually expect me to quantify the initial build, and that is the smaller number. A team of four building the first agent often becomes ten or twelve within a year, and a growing share of them are maintaining a runtime for agents rather than building agents that serve the business. The enterprise has quietly created an internal agent infrastructure company in a field where the patterns for memory, tools, evaluation, and safety are rewritten every few months, while hyperscalers put hundreds of engineers on exactly this problem and ship at a cadence no single platform group can match. Foundry Agent Service, for instance, bundle content safety guardrails into the runtime and route outbound traffic through a customer virtual network, capabilities that platform teams otherwise assemble one integration at a time. This plumbing does not differentiate your organization, so the question is whether your scarcest engineers should spend years on it or on the workflows, data, and judgment only your company has. This is also why the technology companies held up as examples are a poor template. Many built their own runtimes because managed options did not yet exist and had large platform organizations to carry the load. Even they tend to invest in a custom runtime for the first handful of use cases and then migrate as managed services mature, because the maintenance burden compounds while the strategic value of owning the plumbing does not. What I would do as the leader I am not arguing against Kubernetes or for moving everything tomorrow. Comparable managed runtimes exist across the hyperscalers, and I use hosted agents as the running example only because it is the one I know best from the inside. Managed agent services are still maturing, some workloads have real data residency or customization needs, and abstraction always constrains something. What I am arguing for is a deliberate choice for each use case, guided by three questions: whether the agent must outlive a single request by running long, waiting on humans, or remembering across sessions whether it must act with its own identity, auditable delegation, and policy enforcement whether your team would be building anything a managed service already provides, and who will still maintain it in two years. Key takeaways Match the runtime to the workload. Containers on your existing cluster suit stateless, short-lived agents, while long-running, human-in-the-loop, and memory-dependent agents need capabilities your platform team was never hired to build. Count the hidden team. The real cost of self-hosting is the growing group of engineers maintaining state, identity, memory, guardrails, and tracing instead of solving business problems. Make evaluation continuous and connected to production traces. Pre-release testing alone will miss the drift and trajectory failures that hurt you, and optimization of quality, cost, and latency depends on that evaluation data. Follow the pattern of the leaders, not their early architecture. Companies that built custom runtimes did so before managed options matured, and most of them move toward managed services as those options improve. A practical place to begin is your roadmap for the next twelve months. Sort each use case into stateless and short-lived or long-running and human-dependent, and for every agent in the second group put a price on the engineers who would maintain the runtime rather than the business logic. I would like to hear how you have drawn this line, and where a managed service was not yet ready for something you needed.875Views2likes0Comments