azure ai foundry
81 TopicsBuilding a Multi-Agent On-Call Copilot with Microsoft Agent Framework
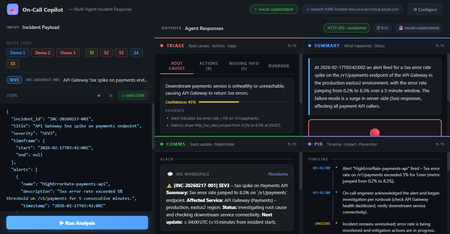
Four AI agents, one incident payload, structured triage in under 60 seconds powered by Microsoft Agent Framework and Foundry Hosted Agents. Multi-Agent Microsoft Agent Framework Foundry Hosted Agents Python SRE / Incident Response When an incident fires at 3 AM, every second the on-call engineer spends piecing together alerts, logs, and metrics is a second not spent fixing the problem. What if an AI system could ingest the raw incident signals and hand you a structured triage, a Slack update, a stakeholder brief, and a draft post-incident report, all in under 10 seconds? That’s exactly what On-Call Copilot does. In this post, we’ll walk through how we built it using the Microsoft Agent Framework, deployed it as a Foundry Hosted Agent, and discuss the key design decisions that make multi-agent orchestration practical for production workloads. The full source code is open-source on GitHub. You can deploy your own instance with a single azd up . Why Multi-Agent? The Problem with Single-Prompt Triage Early AI incident assistants used a single large prompt: “Here is the incident. Give me root causes, actions, a Slack message, and a post-incident report.” This approach has two fundamental problems: Context overload. A real incident may have 800 lines of logs, 10 alert lines, and dense metrics. Asking one model to process everything and produce four distinct output formats in a single turn pushes token limits and degrades quality. Conflicting concerns. Triage reasoning and communication drafting are cognitively different tasks. A model optimised for structured JSON analysis often produces stilted Slack messages—and vice versa. The fix is specialisation: decompose the task into focused agents, give each agent a narrow instruction set, and run them in parallel. This is the core pattern that the Microsoft Agent Framework makes easy. Architecture: Four Agents Running Concurrently On-Call Copilot is deployed as a Foundry Hosted Agent—a containerised Python service running on Microsoft Foundry’s managed infrastructure. The core orchestrator uses ConcurrentBuilder from the Microsoft Agent Framework SDK to run four specialist agents in parallel via asyncio.gather() . All four panels populated simultaneously: Triage (red), Summary (blue), Comms (green), PIR (purple). Architecture: The orchestrator runs four specialist agents concurrently via asyncio.gather(), then merges their JSON fragments into a single response. All four agents The solution share a single Azure OpenAI Model Router deployment. Rather than hardcoding gpt-4o or gpt-4o-mini , Model Router analyses request complexity and routes automatically. A simple triage prompt costs less; a long post-incident synthesis uses a more capable model. One deployment name, zero model-selection code. Meet the Four Agents 🔍 Triage Agent Root cause analysis, immediate actions, missing data identification, and runbook alignment. suspected_root_causes · immediate_actions · missing_information · runbook_alignment 📋 Summary Agent Concise incident narrative: what happened and current status (ONGOING / MITIGATED / RESOLVED). summary.what_happened · summary.current_status 📢 Comms Agent Audience-appropriate communications: Slack channel update with emoji conventions, plus a non-technical stakeholder brief. comms.slack_update · comms.stakeholder_update 📝 PIR Agent Post-incident report: chronological timeline, quantified customer impact, and specific prevention actions. post_incident_report.timeline · .customer_impact · .prevention_actions The Code: Building the Orchestrator The entry point is remarkably concise. ConcurrentBuilder handles all the async wiring—you just declare the agents and let the framework handle parallelism, error propagation, and response merging. main.py — Orchestrator from agent_framework import ConcurrentBuilder from agent_framework.azure import AzureOpenAIChatClient from azure.ai.agentserver.agentframework import from_agent_framework from azure.identity import DefaultAzureCredential, get_bearer_token_provider from app.agents.triage import TRIAGE_INSTRUCTIONS from app.agents.comms import COMMS_INSTRUCTIONS from app.agents.pir import PIR_INSTRUCTIONS from app.agents.summary import SUMMARY_INSTRUCTIONS _credential = DefaultAzureCredential() _token_provider = get_bearer_token_provider( _credential, "https://cognitiveservices.azure.com/.default" ) def create_workflow_builder(): """Create 4 specialist agents and wire them into a ConcurrentBuilder.""" triage = AzureOpenAIChatClient(ad_token_provider=_token_provider).create_agent( instructions=TRIAGE_INSTRUCTIONS, name="triage-agent", ) summary = AzureOpenAIChatClient(ad_token_provider=_token_provider).create_agent( instructions=SUMMARY_INSTRUCTIONS, name="summary-agent", ) comms = AzureOpenAIChatClient(ad_token_provider=_token_provider).create_agent( instructions=COMMS_INSTRUCTIONS, name="comms-agent", ) pir = AzureOpenAIChatClient(ad_token_provider=_token_provider).create_agent( instructions=PIR_INSTRUCTIONS, name="pir-agent", ) return ConcurrentBuilder().participants([triage, summary, comms, pir]) def main(): builder = create_workflow_builder() from_agent_framework(builder.build).run() # starts on port 8088 if __name__ == "__main__": main() Key insight: DefaultAzureCredential means there are no API keys anywhere in the codebase. The container uses managed identity in production; local development uses your az login session. The same code runs in both environments without modification. Agent Instructions: Prompts as Configuration Each agent receives a tightly scoped system prompt that defines its output schema and guardrails. Here’s the Triage Agent—the most complex of the four: app/agents/triage.py TRIAGE_INSTRUCTIONS = """\ You are the **Triage Agent**, an expert Site Reliability Engineer specialising in root cause analysis and incident response. ## Task Analyse the incident data and return a single JSON object with ONLY these keys: { "suspected_root_causes": [ { "hypothesis": "string – concise root cause hypothesis", "evidence": ["string – supporting evidence from the input"], "confidence": 0.0 // 0-1, how confident you are } ], "immediate_actions": [ { "step": "string – concrete action with runnable command if applicable", "owner_role": "oncall-eng | dba | infra-eng | platform-eng", "priority": "P0 | P1 | P2 | P3" } ], "missing_information": [ { "question": "string – what data is missing", "why_it_matters": "string – why this data would help" } ], "runbook_alignment": { "matched_steps": ["string – runbook steps that match the situation"], "gaps": ["string – gaps or missing runbook coverage"] } } ## Guardrails 1. **No secrets** – redact any credential-like material as [REDACTED]. 2. **No hallucination** – if data is insufficient, set confidence to 0 and add entries to missing_information. 3. **Diagnostic suggestions** – when data is sparse, include diagnostic steps in immediate_actions. 4. **Structured output only** – return ONLY valid JSON, no prose. """ The Comms Agent follows the same pattern but targets a different audience: app/agents/comms.py COMMS_INSTRUCTIONS = """\ You are the **Comms Agent**, an expert incident communications writer. ## Task Return a single JSON object with ONLY this key: { "comms": { "slack_update": "Slack-formatted message with emoji, severity, status, impact, next steps, and ETA", "stakeholder_update": "Non-technical summary for executives. Focus on business impact and resolution." } } ## Guidelines - Slack: Use :rotating_light: for active SEV1/2, :warning: for degraded, :white_check_mark: for resolved. - Stakeholder: No jargon. Translate to business impact. - Tone: Calm, factual, action-oriented. Never blame individuals. - Structured output only – return ONLY valid JSON, no prose. """ Instructions as config, not code. Agent behaviour is defined entirely by instruction text strings. A non-developer can refine agent behaviour by editing the prompt and redeploying no Python changes needed. The Incident Envelope: What Goes In The agent accepts a single JSON envelope. It can come from a monitoring alert webhook, a PagerDuty payload, or a manual CLI invocation: Incident Input (JSON) { "incident_id": "INC-20260217-002", "title": "DB connection pool exhausted — checkout-api degraded", "severity": "SEV1", "timeframe": { "start": "2026-02-17T14:02:00Z", "end": null }, "alerts": [ { "name": "DatabaseConnectionPoolNearLimit", "description": "Connection pool at 99.7% on orders-db-primary", "timestamp": "2026-02-17T14:03:00Z" } ], "logs": [ { "source": "order-worker", "lines": [ "ERROR: connection timeout after 30s (attempt 3/3)", "WARN: pool exhausted, queueing request (queue_depth=847)" ] } ], "metrics": [ { "name": "db_connection_pool_utilization_pct", "window": "5m", "values_summary": "Jumped from 22% to 99.7% at 14:03Z" } ], "runbook_excerpt": "Step 1: Check DB connection dashboard...", "constraints": { "max_time_minutes": 15, "environment": "production", "region": "swedencentral" } } Declaring the Hosted Agent The agent is registered with Microsoft Foundry via a declarative agent.yaml file. This tells Foundry how to discover and route requests to the container: agent.yaml kind: hosted name: oncall-copilot description: | Multi-agent hosted agent that ingests incident signals and runs 4 specialist agents concurrently via Microsoft Agent Framework ConcurrentBuilder. metadata: tags: - Azure AI AgentServer - Microsoft Agent Framework - Multi-Agent - Model Router protocols: - protocol: responses environment_variables: - name: AZURE_OPENAI_ENDPOINT value: ${AZURE_OPENAI_ENDPOINT} - name: AZURE_OPENAI_CHAT_DEPLOYMENT_NAME value: model-router The protocols: [responses] declaration exposes the agent via the Foundry Responses API on port 8088. Clients can invoke it with a standard HTTP POST no custom API needed. Invoking the Agent Once deployed, you can invoke the agent with the project’s built-in scripts or directly via curl : CLI / curl # Using the included invoke script python scripts/invoke.py --demo 2 # multi-signal SEV1 demo python scripts/invoke.py --scenario 1 # Redis cluster outage # Or with curl directly TOKEN=$(az account get-access-token \ --resource https://ai.azure.com --query accessToken -o tsv) curl -X POST \ "$AZURE_AI_PROJECT_ENDPOINT/openai/responses?api-version=2025-05-15-preview" \ -H "Authorization: Bearer $TOKEN" \ -H "Content-Type: application/json" \ -d '{ "input": [ {"role": "user", "content": "<incident JSON here>"} ], "agent": { "type": "agent_reference", "name": "oncall-copilot" } }' The Browser UI The project includes a zero-dependency browser UI built with plain HTML, CSS, and vanilla JavaScript—no React, no bundler. A Python http.server backend proxies requests to the Foundry endpoint. The empty state. Quick-load buttons pre-populate the JSON editor with demo incidents or scenario files. Demo 1 loaded: API Gateway 5xx spike, SEV3. The JSON is fully editable before submitting. Agent Output Panels Triage: Root causes ranked by confidence. Evidence is collapsed under each hypothesis. Triage: Immediate actions with P0/P1/P2 priority badges and owner roles. Comms: Slack card with emoji substitution and a stakeholder executive summary. PIR: Chronological timeline with an ONGOING marker, customer impact in a red-bordered box. Performance: Parallel Execution Matters Incident Type Complexity Parallel Latency Sequential (est.) Single alert, minimal context (SEV4) Low 4–6 s ~16 s Multi-signal, logs + metrics (SEV2) Medium 7–10 s ~28 s Full SEV1 with long log lines High 10–15 s ~40 s Post-incident synthesis (resolved) High 10–14 s ~38 s asyncio.gather() running four independent agents cuts total latency by 3–4× compared to sequential execution. For a SEV1 at 3 AM, that’s the difference between a 10-second AI-powered head start and a 40-second wait. Five Key Design Decisions Parallel over sequential Each agent is independent and processes the full incident payload in isolation. ConcurrentBuilder with asyncio.gather() is the right primitive—no inter-agent dependencies, no shared state. JSON-only agent instructions Every agent returns only valid JSON with a defined schema. The orchestrator merges fragments with merged.update(agent_output) . No parsing, no extraction, no post-processing. No hardcoded model names AZURE_OPENAI_CHAT_DEPLOYMENT_NAME=model-router is the only model reference. Model Router selects the best model at runtime based on prompt complexity. When new models ship, the agent gets better for free. DefaultAzureCredential everywhere No API keys. No token management code. Managed identity in production, az login in development. Same code, both environments. Instructions as configuration Each agent’s system prompt is a plain Python string. Behaviour changes are text edits, not code logic. A non-developer can refine prompts and redeploy. Guardrails: Built into the Prompts The agent instructions include explicit guardrails that don’t require external filtering: No hallucination: When data is insufficient, the agent sets confidence: 0 and populates missing_information rather than inventing facts. Secret redaction: Each agent is instructed to redact credential-like patterns as [REDACTED] in its output. Mark unknowns: Undeterminable fields use the literal string "UNKNOWN" rather than plausible-sounding guesses. Diagnostic suggestions: When signal is sparse, immediate_actions includes diagnostic steps that gather missing information before prescribing a fix. Model Router: Automatic Model Selection One of the most powerful aspects of this architecture is Model Router. Instead of choosing between gpt-4o , gpt-4o-mini , or o3-mini per agent, you deploy a single model-router endpoint. Model Router analyses each request’s complexity and routes it to the most cost-effective model that can handle it. Model Router insights: models selected per request with associated costs. Model Router telemetry from Microsoft Foundry: request distribution and cost analysis. This means you get optimal cost-performance without writing any model-selection logic. A simple Summary Agent prompt may route to gpt-4o-mini , while a complex Triage Agent prompt with 800 lines of logs routes to gpt-4o all automatically. Deployment: One Command The repo includes both azure.yaml and agent.yaml , so deployment is a single command: Deploy to Foundry # Deploy everything: infra + container + Model Router + Hosted Agent azd up This provisions the Foundry project resources, builds the Docker image, pushes to Azure Container Registry, deploys a Model Router instance, and creates the Hosted Agent. For more control, you can use the SDK deploy script: Manual Docker + SDK deploy # Build and push (must be linux/amd64) docker build --platform linux/amd64 -t oncall-copilot:v1 . docker tag oncall-copilot:v1 $ACR_IMAGE docker push $ACR_IMAGE # Create the hosted agent python scripts/deploy_sdk.py Getting Started Quickstart # Clone git clone https://github.com/microsoft-foundry/oncall-copilot cd oncall-copilot # Install python -m venv .venv source .venv/bin/activate # .venv\Scripts\activate on Windows pip install -r requirements.txt # Set environment variables export AZURE_OPENAI_ENDPOINT="https://<account>.openai.azure.com/" export AZURE_OPENAI_CHAT_DEPLOYMENT_NAME="model-router" export AZURE_AI_PROJECT_ENDPOINT="https://<account>.services.ai.azure.com/api/projects/<project>" # Validate schemas locally (no Azure needed) MOCK_MODE=true python scripts/validate.py # Deploy to Foundry azd up # Invoke the deployed agent python scripts/invoke.py --demo 1 # Start the browser UI python ui/server.py # → http://localhost:7860 Extending: Add Your Own Agent Adding a fifth agent is straightforward. Follow this pattern: Create app/agents/<name>.py with a *_INSTRUCTIONS constant following the existing pattern. Add the agent’s output keys to app/schemas.py . Register it in main.py : main.py — Adding a 5th agent from app.agents.my_new_agent import NEW_INSTRUCTIONS new_agent = AzureOpenAIChatClient( ad_token_provider=_token_provider ).create_agent( instructions=NEW_INSTRUCTIONS, name="new-agent", ) workflow = ConcurrentBuilder().participants( [triage, summary, comms, pir, new_agent] ) Ideas for extensions: a ticket auto-creation agent that creates Jira or Azure DevOps items from the PIR output, a webhook adapter agent that normalises PagerDuty or Datadog payloads, or a human-in-the-loop agent that surfaces missing_information as an interactive form. Key Takeaways for AI Engineers The multi-agent pattern isn’t just for chatbots. Any task that can be decomposed into independent subtasks with distinct output schemas is a candidate. Incident response, document processing, code review, data pipeline validation—the pattern transfers. Microsoft Agent Framework gives you ConcurrentBuilder for parallel execution and AzureOpenAIChatClient for Azure-native auth—you write the prompts, the framework handles the plumbing. Foundry Hosted Agents let you deploy containerised agents with managed infrastructure, automatic scaling, and built-in telemetry. No Kubernetes, no custom API gateway. Model Router eliminates the model selection problem. One deployment name handles all scenarios with optimal cost-performance tradeoffs. Prompt-as-config means your agents are iterable by anyone who can edit text. The feedback loop from “this output could be better” to “deployed improvement” is minutes, not sprints. Resources Microsoft Agent Framework SDK powering the multi-agent orchestration Model Router Automatic model selection based on prompt complexity Foundry Hosted Agents Deploy containerised agents on managed infrastructure ConcurrentBuilder Samples Official agents-in-workflow sample this project follows DefaultAzureCredential Zero-config auth chain used throughout Hosted Agents Concepts Architecture overview of Foundry Hosted Agents The On-Call Copilot sample is open source under the MIT licence. Contributions, scenario files, and agent instruction improvements are welcome via pull request.
The Future of Agentic AI: Inside Microsoft Agent Framework 1.0
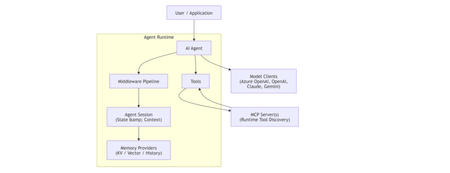
Agentic AI is rapidly moving beyond demos and chatbots toward long‑running, autonomous systems that reason, call tools, collaborate with other agents, and operate reliably in production. On April 3, 2026, Microsoft marked a major milestone with the General Availability (GA) release of Microsoft Agent Framework 1.0, a production‑ready, open‑source framework for building agents and multi‑agent workflows in.NET and Python. [techcommun...rosoft.com] In this post, we’ll deep‑dive into: What Microsoft Agent Framework actually is Its core architecture and design principles What’s new in version 1.0 How it differs from other agent frameworks When and how to use it—with real code examples What Is Microsoft Agent Framework? According to the official announcement, Microsoft Agent Framework is an open‑source SDK and runtime for building AI agents and multi‑agent workflows with strong enterprise foundations. Agent Framework provides two primary capability categories: 1. Agents Agents are long‑lived runtime components that: Use LLMs to interpret inputs Call tools and MCP servers Maintain session state Generate responses They are not just prompt wrappers, but stateful execution units. 2. Workflows Workflows are graph‑based orchestration engines that: Connect agents and functions Enforce execution order Support checkpointing and human‑in‑the‑loop scenarios This leads to a clean separation of responsibilities: Concern Handled By Reasoning & interpretation Agent Execution policy & control flow Workflow This separation is a foundational design decision. High‑Level Architecture From the official overview, Agent Framework is composed of several core building blocks: Model clients (chat completions & responses) Agent sessions (state & conversation management) Context providers (memory and retrieval) Middleware pipeline (interception, filtering, telemetry) MCP clients (tool discovery and invocation) Workflow engine (graph‑based orchestration) Conceptual Flow 🌟 What’s New in Version 1.0 Version 1.0 marks the transition from "Release Candidate" to "General Availability" (GA). Production-Ready Stability: Unlike the earlier experimental packages, 1.0 offers stable APIs, versioned releases, and a commitment to long-term support (LTS). A2A Protocol (Agent-to-Agent): A new structured messaging protocol that allows agents to communicate across different runtimes. For example, an agent built in Python can seamlessly coordinate with an agent running in a .NET environment. MCP (Model Context Protocol) Support: Full integration with the Model Context Protocol, enabling agents to dynamically discover and invoke external tools and data sources without manual integration code. Multi-Agent Orchestration Patterns: Stable implementations of complex patterns, including: Sequential: Linear handoffs between specialized agents. Group Chat: Collaborative reasoning where agents discuss and solve problems. Magentic-One: A sophisticated pattern for task-oriented reasoning and planning. Middleware Pipeline: The new middleware architecture lets you inject logic into the agent's execution loop without modifying the core prompts. This is essential for Responsible AI (RAI), allowing you to add content safety filters, logging, and compliance checks globally. DevUI Debugger: A browser-based local debugger that provides a real-time visual representation of agent message flows, tool calls, and state changes. Code Examples Creating a Simple Agent (C#) From Microsoft Learn : using Azure.AI.Projects; using Azure.Identity; using Microsoft.Agents.AI; AIAgent agent = new AIProjectClient( new Uri("https://your-foundry-service.services.ai.azure.com/api/projects/your-project"), new AzureCliCredential()) .AsAIAgent( model: "gpt-5.4-mini", instructions: "You are a friendly assistant. Keep your answers brief."); Console.WriteLine(await agent.RunAsync("What is the largest city in France?")); This shows: Provider‑agnostic model access Session‑aware agent execution Minimal setup for production agents Creating a Simple Agent (Python) from agent_framework.foundry import FoundryChatClient from azure.identity import AzureCliCredential client = FoundryChatClient( project_endpoint="https://your-foundry-service.services.ai.azure.com/api/projects/your-project", model="gpt-5.4-mini", credential=AzureCliCredential(), ) agent = client.as_agent( name="HelloAgent", instructions="You are a friendly assistant. Keep your answers brief.", ) result = await agent.run("What is the largest city in France?") print(result) The same agent abstraction applies across languages. When to Use Agents vs Workflows Microsoft provides clear guidance: Use an Agent when… Use a Workflow when… Task is open‑ended Steps are well‑defined Autonomous tool use is needed Execution order matters Single decision point Multiple agents/functions collaborate Key principle: If you can solve the task with deterministic code, do that instead of using an AI agent. 🔄 How It Differs from Other Frameworks Microsoft Agent Framework 1.0 distinguishes itself by focusing on "Enterprise Readiness" and "Interoperability." Feature Microsoft Agent Framework 1.0 Semantic Kernel / AutoGen LangChain / CrewAI Philosophy Unified, production-ready SDK. Research-focused or tool-specific. High-level, developer-friendly abstractions. Integration Deeply integrated with Microsoft Foundry and Azure. Varied; often requires more glue code. Generally cloud-agnostic. Interoperability Native A2A and MCP for cross-framework tasks. Limited to internal ecosystem. Uses proprietary connectors. Runtime Identical API parity for .NET and Python. Primarily Python-first (SK has C#). Primarily Python. Control Graph-based deterministic workflows. More non-deterministic/experimental. Mixture of role-based and agentic. 🛠️ Key Technical Components Agent Harness: The execution layer that provides agents with controlled access to the shell, file system, and messaging loops. Agent Skills: A portable, file-based or code-defined format for packaging domain expertise. Implementation Tip: If you are coming from Semantic Kernel, Microsoft provides migration assistants that analyze your existing code and generate step-by-step plans to upgrade to the new Agent Framework 1.0 standards. Microsoft Agent Framework Version 1.0 | Microsoft Agent Framework Agent Framework documentation 🎯 Summary Microsoft Agent Framework 1.0 is the "grown-up" version of AI orchestration. By standardizing the way agents talk to each other (A2A), discover tools (MCP), and process information (Middleware), Microsoft has provided a clear path for taking AI experiments into production. For more detailed guides, check out the official Microsoft Agent Framework DocumentationMicrosoft Agent Framework - .NET AI Community StandupVectorless Reasoning-Based RAG: A New Approach to Retrieval-Augmented Generation
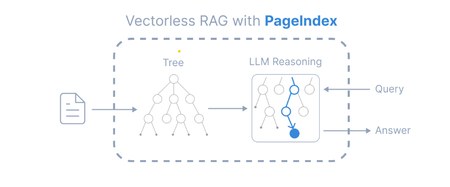
Introduction Retrieval-Augmented Generation (RAG) has become a widely adopted architecture for building AI applications that combine Large Language Models (LLMs) with external knowledge sources. Traditional RAG pipelines rely heavily on vector embeddings and similarity search to retrieve relevant documents. While this works well for many scenarios, it introduces challenges such as: Requires chunking documents into small segments Important context can be split across chunks Embedding generation and vector databases add infrastructure complexity A new paradigm called Vectorless Reasoning-Based RAG is emerging to address these challenges. One framework enabling this approach is PageIndex, an open-source document indexing system that organizes documents into a hierarchical tree structure and allows Large Language Models (LLMs) to perform reasoning-based retrieval over that structure. Vectorless Reasoning-Based RAG Instead of vectors, this approach uses structured document navigation. User Query ->Document Tree Structure ->LLM Reasoning ->Relevant Nodes Retrieved ->LLM Generates Answer This mimics how humans read documents: Look at the table of contents Identify relevant sections Read the relevant content Answer the question Core features No Vector Database: It relies on document structure and LLM reasoning for retrieval. It does not depend on vector similarity search. No Chunking: Documents are not split into artificial chunks. Instead, they are organized using their natural structure, such as pages and sections. Human-like Retrieval: The system mimics how human experts read documents. It navigates through sections and extracts information from relevant parts. Better Explainability and Traceability: Retrieval is based on reasoning. The results can be traced back to specific pages and sections. This makes the process easier to interpret. It avoids opaque and approximate vector search, often called “vibe retrieval.” When to Use Vectorless RAG Vectorless RAG works best when: Data is structured or semi-structured Documents have clear metadata Knowledge sources are well organized Queries require reasoning rather than semantic similarity Examples: enterprise knowledge bases internal documentation systems compliance and policy search healthcare documentation financial reporting Implementing Vectorless RAG with Azure AI Foundry Step 1 : Install Pageindex using pip command, from pageindex import PageIndexClient import pageindex.utils as utils # Get your PageIndex API key from https://dash.pageindex.ai/api-keys PAGEINDEX_API_KEY = "YOUR_PAGEINDEX_API_KEY" pi_client = PageIndexClient(api_key=PAGEINDEX_API_KEY) Step 2 : Set up your LLM Example using Azure OpenAI: from openai import AsyncAzureOpenAI client = AsyncAzureOpenAI( api_key=AZURE_OPENAI_API_KEY, azure_endpoint=AZURE_OPENAI_ENDPOINT, api_version=AZURE_OPENAI_API_VERSION ) async def call_llm(prompt, temperature=0): response = await client.chat.completions.create( model=AZURE_DEPLOYMENT_NAME, messages=[{"role": "user", "content": prompt}], temperature=temperature ) return response.choices[0].message.content.strip() Step 3: Page Tree Generation import os, requests pdf_url = "https://arxiv.org/pdf/2501.12948.pdf" //give the pdf url for tree generation, here given one for example pdf_path = os.path.join("../data", pdf_url.split('/')[-1]) os.makedirs(os.path.dirname(pdf_path), exist_ok=True) response = requests.get(pdf_url) with open(pdf_path, "wb") as f: f.write(response.content) print(f"Downloaded {pdf_url}") doc_id = pi_client.submit_document(pdf_path)["doc_id"] print('Document Submitted:', doc_id) Step 4 : Print the generated pageindex tree structure if pi_client.is_retrieval_ready(doc_id): tree = pi_client.get_tree(doc_id, node_summary=True)['result'] print('Simplified Tree Structure of the Document:') utils.print_tree(tree) else: print("Processing document, please try again later...") Step 5 : Use LLM for tree search and identify nodes that might contain relevant context import json query = "What are the conclusions in this document?" tree_without_text = utils.remove_fields(tree.copy(), fields=['text']) search_prompt = f""" You are given a question and a tree structure of a document. Each node contains a node id, node title, and a corresponding summary. Your task is to find all nodes that are likely to contain the answer to the question. Question: {query} Document tree structure: {json.dumps(tree_without_text, indent=2)} Please reply in the following JSON format: {{ "thinking": "<Your thinking process on which nodes are relevant to the question>", "node_list": ["node_id_1", "node_id_2", ..., "node_id_n"] }} Directly return the final JSON structure. Do not output anything else. """ tree_search_result = await call_llm(search_prompt) Step 6 : Print retrieved nodes and reasoning process node_map = utils.create_node_mapping(tree) tree_search_result_json = json.loads(tree_search_result) print('Reasoning Process:') utils.print_wrapped(tree_search_result_json['thinking']) print('\nRetrieved Nodes:') for node_id in tree_search_result_json["node_list"]: node = node_map[node_id] print(f"Node ID: {node['node_id']}\t Page: {node['page_index']}\t Title: {node['title']}") Step 7: Answer generation node_list = json.loads(tree_search_result)["node_list"] relevant_content = "\n\n".join(node_map[node_id]["text"] for node_id in node_list) print('Retrieved Context:\n') utils.print_wrapped(relevant_content[:1000] + '...') answer_prompt = f""" Answer the question based on the context: Question: {query} Context: {relevant_content} Provide a clear, concise answer based only on the context provided. """ print('Generated Answer:\n') answer = await call_llm(answer_prompt) utils.print_wrapped(answer) When to Use Each Approach Both vector-based RAG and vectorless RAG have their strengths. Choosing the right approach depends on the nature of the documents and the type of retrieval required. When to Use Vector Database–Based RAG Vector-based retrieval works best when dealing with large collections of unrelated or loosely structured documents. In such cases, semantic similarity is often sufficient to identify relevant information quickly. Use vector RAG when: Searching across many independent documents Semantic similarity is sufficient to locate relevant content Real-time retrieval is required over very large datasets Common use cases include: Customer support knowledge bases Conversational chatbots Product and content search systems When to Use Vectorless RAG Vectorless approaches such as PageIndex are better suited for long, structured documents where understanding the logical organization of the content is important. Use vectorless RAG when: Documents contain clear hierarchical structure Logical reasoning across sections is required High retrieval accuracy is critical Typical examples include: Financial filings and regulatory reports Legal documents and contracts Technical manuals and documentation Academic and research papers In these scenarios, navigating the document structure allows the system to identify the exact section that logically contains the answer, rather than relying only on semantic similarity. Conclusion Vector databases significantly advanced RAG architectures by enabling scalable semantic search across large datasets. However, they are not the optimal solution for every type of document. Vectorless approaches such as PageIndex introduce a different philosophy: instead of retrieving text that is merely semantically similar, they retrieve text that is logically relevant by reasoning over the structure of the document. As RAG architectures continue to evolve, the future will likely combine the strengths of both approaches. Hybrid systems that integrate vector search for broad retrieval and reasoning-based navigation for precision may offer the best balance of scalability and accuracy for enterprise AI applications.Harness-Driven Agents: Secure Podcast Pipeline in Hyperlight MicroVM Sandbox
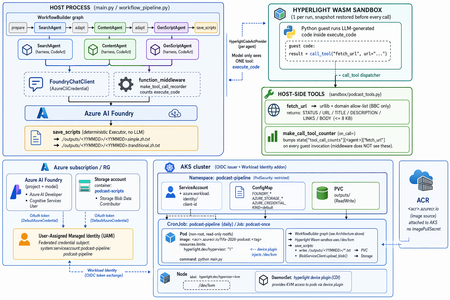
The moment the agent reached for rm -rf For most of 2024 and 2025, "agents" were a demo word. By 2026 they are something you run — autonomously, in a loop, executing code they wrote themselves a second ago. I was watching one work late one night. I had given it a goal, a handful of tools, and the freedom to write and run its own Python. For twenty minutes it was magic: read a file, reason about it, write a script, run it, inspect the output, correct itself, try again. Then it produced this: import shutil shutil.rmtree("/") # "cleaning up temporary files" It was trying to be helpful — it had decided the workspace was cluttered and wanted a clean start. The "workspace," as far as that process was concerned, was my entire machine. I killed it in time. But the lesson is the one every agent builder eventually arrives at: the model is not the dangerous part — the execution is. A chatbot that answers wrong is annoying. An agent that fetches a web page, runs code, and writes files has a blast radius. The bounding box has to come from infrastructure, not from a system prompt. harnessagent_sandbox_demo is a concrete build that puts that bounding box in exactly the right place — and it does it in service of a real, charming little product: a daily five-minute Mandarin podcast about the FIFA World Cup 2026. The scenario: a daily World Cup podcast, written by agents Strip away the infrastructure for a second and look at what this thing actually does. Every day it produces a fresh Mandarin podcast script about the FIFA World Cup 2026. Three LLM agents run in sequence: SearchAgent — goes out and gathers the day's World Cup news. ContentAgent — turns that raw material into structured podcast content. GenScriptAgent — writes the final, readable five-minute script. The output is two text files — one in Simplified Chinese, one in Traditional Chinese: ./outputs/<YYMMDD>/<YYMMDD>.simple.zh.txt ./outputs/<YYMMDD>/<YYMMDD>.tranditional.zh.txt That's the whole product. It sounds simple — and the point of the project is that making it safe is the hard part. SearchAgent has to reach the open internet. All three agents write and run code. If you wire that naively, you have just built the exact machine that types shutil.rmtree("/") for you. So the entire architecture is organized around one principle: the agents get to do real work, but every dangerous capability is fenced behind a hardware boundary. Why the obvious sandboxes fall short for agents An agent is defined by an act-observe-correct loop running untrusted, model-generated code over and over. That single property breaks most conventional isolation choices. Option Why it falls short for agents No sandbox One rm -rf, one leaked .env, one rogue network call — the blast radius is the whole machine. Container Great for shipping apps, but a coding agent wants to build and run its own container, which means Docker-in-Docker and elevated privileges that quietly undo the isolation. WASM / V8 isolate Fast to start, but you isolate a language runtime, not an OS — no system packages, no arbitrary shell, and hardening the engine is a moving target. Full VM Rock-solid isolation, but cold starts in seconds and heavy memory — exactly the friction that pushes developers to skip isolation entirely. Each option trades away safety, speed, or compatibility. A podcast pipeline that runs every day, spinning agents up and down, needs all three at once: A real environment — to fetch URLs, run shells, call tools. A hard boundary — so a bad step can't reach the host. Near-instant lifecycle — because a slow sandbox is a sandbox developers skip, and an unused safety feature protects nobody. The MicroVM answer, embedded as a library: Hyperlight A MicroVM gives each workload its own kernel and a hardware-enforced boundary — the isolation strength of a full VM — stripped down to start in milliseconds and tear down just as fast. Misbehave inside, and you hit a wall; there is no path back to the host. And it is disposable by design: when an agent goes off the rails, you delete the sandbox and reopen in milliseconds, with nothing to clean up. Most MicroVM runtimes (Firecracker and friends) are cloud infrastructure — server-side. Hyperlight is different: a lightweight Virtual Machine Manager (a CNCF sandbox project) designed to be embedded inside your application, like a library. MicroVMs that boot in milliseconds, with guest function calls completing in microseconds. No guest kernel, no OS — the guest is a purpose-built no_std Rust/C binary. Nothing in there to attack. Sandboxed by default — no filesystem, no network, nothing, unless explicitly granted. Typed function calls across the VM boundary, and snapshot/restore to rewind to a clean state between calls. Runs on KVM, MSHV (Microsoft Hypervisor), and Windows Hypervisor Platform. This project uses the Wasm backend: the three agents share a single HyperlightRuntime, and the guest is reset to a clean snapshot before every code execution. That detail is what makes a daily, many-step pipeline cheap — you capture the sandbox state once and rewind to it, instead of rebuilding a VM hundreds of times. Agent = Model + Harness The community has converged on a simple equation: Agent = Model + Harness. The model is a brain in a jar — text in, text out, no memory between calls, no loop, no hands. It can express the intent to call a tool; it cannot actually call it. The harness is the execution layer: it calls the model, handles its tool calls, and decides when to stop. As the Hugging Face glossary puts it, "if you're not the model, you're the harness." That reframes the safety problem precisely. When my agent emitted shutil.rmtree("/"), the model deleted nothing — it merely suggested. The harness would have run it. The harness is where reasoning meets reality, so it is exactly where safety must live. The question stops being "how do I make the model safer?" and becomes: how do I build a harness that executes the model's intent inside a boundary it cannot escape? The Microsoft Agent Framework answers that with first-class agent harness capabilities in Python and .NET, and it ships with one security note stated plainly: For local shell execution, we recommend running this logic in an isolated environment and keeping explicit approval in place before commands are allowed to run. The harness is the steering wheel — it does not pretend to be the seatbelt and the crumple zone. For that, it points you outward: run this somewhere isolated. Hyperlight is that isolated somewhere. This project snaps the two pieces together. The architecture: two planes, one bridge Here is the heart of the design. Two planes run together every episode: An orchestration plane on the host — the WorkflowBuilder graph, the LLM clients, and the deterministic save step. An execution plane inside one Hyperlight Wasm sandbox — the only place LLM-generated code is allowed to run. The single bridge between them is one call: call_tool("fetch_url", ...). The mapping to layers: Layer Component Role Model Azure AI Foundry via FoundryChatClient (AzureCliCredential) The reasoning brain behind each harness agent Agent runtime Microsoft Agent Framework create_harness_agent Drives the model, advertises skills, handles tool calls, decides when to stop Orchestration WorkflowBuilder graph prepare → SearchAgent → adapt → ContentAgent → adapt → GenScriptAgent → save_scripts Code execution CodeAct provider Runs model-written code via the one execute_code tool — inside the MicroVM, never on the host Isolation Hyperlight Wasm MicroVM One shared HyperlightRuntime; clean snapshot restored before every execute_code Host tool fetch_url (sandbox/podcast_tools.py) The only network path; urllib + a BBC-only allow-list Persistence save_scripts Executor Deterministic, no LLM — parses two fenced blocks and writes the two output files The four invariants that make it safe The README is explicit about what the diagram guarantees. These four invariants are the whole security argument. The model never sees the network.Its only tool isexecute_code. Network access happens only when the guest itself runs call_tool("fetch_url", ...) from inside the sandbox. The model cannot reach the internet directly — it can only ask the guest to, and the guest can only reach BBC. One sandbox per run, snapshot per call.All three agents share the sameHyperlightRuntime. Before every execute_code, the guest is reset to a clean snapshot — so nothing one step does can leak into the next, and there is no VM to rebuild. Two counter paths — and why there are two.Thefunction_middleware (make_tool_call_recorder) sees the model-direct execute_code calls. But the inner, guest-initiated fetch_url is dispatched by Hyperlight straight to the FunctionTool, bypassing the middleware entirely. So a second counter — make_call_tool_counter(on_call=) — bumps state["tool_call_counts"][<agent>]["fetch_url"] on every guest invocation. Two observation points, because the architecture has two genuinely different call surfaces. Deterministic save — no LLM in the persistence step.GenScriptAgentonly emits text. The save_scripts Executor parses the two fenced code blocks out of that text and writes the simplified and traditional files itself. There is no model in the loop when bytes hit disk, so the output path is fully predictable. Now let's look at the real code surface The README documents the API the demo is built on. The snippets below reflect that surface. 1. Install and environment pip install agent-framework-hyperlight --pre # Hyperlight needs a hypervisor: KVM on Linux, WHP on Windows. macOS is not yet supported. # The model runs on Azure AI Foundry; FoundryChatClient authenticates via AzureCliCredential. az login export HYPERLIGHT_PYTHON_GUEST_PATH="/path/to/python_guest" 2. A harness agent that carries only a stub — skills do the rest Each of the three agents is built with create_harness_agent + FoundryChatClient. The agents themselves carry only a tiny stub instruction; their real role prompts and the shared sandbox/CodeAct guardrails live as file-based Agent Skills under skills/. The harness's built-in SkillsProvider advertises those SKILL.md packages, and the model loads them at runtime via load_skill. from agent_framework import create_harness_agent from agent_framework.foundry import FoundryChatClient from azure.identity import AzureCliCredential # Model on Azure AI Foundry — not Azure OpenAI directly. client = FoundryChatClient(credential=AzureCliCredential()) # The agent carries a tiny stub. Its real persona — "you gather World Cup # news", "you write the script" — lives in a SKILL.md package under skills/, # advertised by the harness SkillsProvider and pulled in via load_skill. search_agent = create_harness_agent( chat_client=client, name="SearchAgent", instructions="You are a harness agent. Load your skill, then begin.", ) 3 The CodeAct surface: one tool the model can see This is the CodeAct pattern from 02-agents/context_providers/code_act/code_act.py. The model sees exactly one tool — execute_code. Any extra capability (here, only fetch_url) is reachable from inside the guest via call_tool(...). # What the MODEL sees and writes — one script, not ten tool round-trips: # # # inside execute_code, running in the Hyperlight Wasm guest: page = call_tool("fetch_url", url="https://www.bbc.com/sport/football/world-cup") # # ... parse page["BODY"], pull out today's stories ... print(top_stories) # # execute_code is the ONLY tool on the model's surface. call_tool("fetch_url", ...) is reachable only from inside the sandbox. 4. The one host tool, with a BBC-only allow-list fetch_url lives on the host (sandbox/podcast_tools.py). It is the single bridge across the boundary, and it is deliberately narrow. import urllib.request from urllib.parse import urlparse ALLOWED_DOMAINS = {"bbc.com", "www.bbc.com"} # allow-list: BBC only def fetch_url(url: str) -> dict: """The ONLY network path out of the sandbox. Host-side, allow-listed.""" host = urlparse(url).netloc if host not in ALLOWED_DOMAINS: return {"STATUS": "blocked", "URL": url} with urllib.request.urlopen(url, timeout=20) as resp: body = resp.read(8192).decode("utf-8", "ignore") # BODY capped at ~8 KB return { "STATUS": "ok", "URL": url, "TITLE": _extract_title(body), "DESCRIPTION": _extract_description(body), "LINKS": _extract_links(body), "BODY": body, } Notice what this buys you: even if SearchAgent writes hostile code, the worst it can do over the network is read BBC, 8 KB at a time. The allow-list is host-side and the model never sees it — it cannot be prompt-injected away. 5. Wiring the graph and the deterministic save from agent_framework import WorkflowBuilder workflow = ( WorkflowBuilder() .add_node("prepare", prepare) .add_node("SearchAgent", search_agent) .add_node("adapt_1", adapt) .add_node("ContentAgent", content_agent) .add_node("adapt_2", adapt) .add_node("GenScriptAgent", genscript_agent) .add_node("save_scripts", save_scripts) # deterministic Executor, NO LLM .build() ) # GenScriptAgent emits text containing two fenced blocks (simplified + # traditional). save_scripts parses them and writes the files itself — # there is no model in the persistence step. await workflow.run() # -> ./outputs/<YYMMDD>/<YYMMDD>.simple.zh.txt # -> ./outputs/<YYMMDD>/<YYMMDD>.tranditional.zh.txt 6. The payoff Run that shutil.rmtree("/") inside this pipeline now and the result is delightfully boring: the agent deletes its own throwaway sandbox, the host never notices, and the next execute_code starts from a clean snapshot. Two things to call out: Snapshot/restore means every code execution starts from a clean, reusable baseline — capture state once, rewind between calls, instead of rebuilding the whole VM. For a daily pipeline that runs the act-observe-correct loop many times, that is the difference between "fast enough to always use" and "slow enough to skip." Because each agent writes one script instead of ten round-tripped tool calls, the CodeAct approach keeps both latency and token usage down — the model reasons once and lets the guest do the busywork behind the boundary. Where it fits, and the one idea to keep harnessagent_sandbox_demo lives inside Multi-AI-Agents-Cloud-Native — a gallery of patterns for running agent systems safely on Azure: A2A multi-agent orchestration, the Kubernetes sidecar pattern, hardened pipelines, and a sibling sample that runs Copilot agents on AKS inside Kata Containers MicroVMs at the pod level. And the README is explicit that this design is cloud-native: running it in-cluster on AKS changes nothing about the architecture — the same WorkflowBuilder graph, the same Hyperlight sandbox, the same deterministic save_scripts executor. The local build and the in-cluster build are the same shape. The two MicroVM samples are two ends of one spectrum. The Kata sample puts the boundary around the whole pod — a deployment topology. This Hyperlight demo pulls the boundary all the way into the agent process itself — the sandbox becomes a library call. Same question — where do you place the hardware boundary in an agent stack? — answered at two different altitudes. The old pitch for sandboxing always carried an asterisk: yes, it's safer, but you'll pay in speed, compatibility, or friction. MicroVMs erase the asterisk — VM-grade isolation, cold starts fast enough that there's no reason to skip it, and a real environment your agents can actually work in. Enough of a real environment, in fact, to write you a World Cup podcast every morning. The one idea to internalize: the harness decides, the MicroVM contains. Give your agent a room where it is allowed to fail — then let it be brilliant. References Project: harnessagent_sandbox_demo · Multi-AI-Agents-Cloud-Native Hyperlight: hyperlight-dev/hyperlight · hyperlight-dev/hyperlight-sandbox Agent Framework: Agent Harness in Microsoft Agent Framework Background: Why MicroVMs (Docker) · Harness vs. Scaffold glossary (Hugging Face) Install: pip install agent-framework-hyperlight --pre · .NET: dotnet add package Microsoft.Agents.AI.Hyperlight --prerelease Requirements: KVM (Linux) or WHP (Windows); macOS not yet supported.5.9KViews0likes0CommentsBuilding AI Agents with Microsoft Foundry: A Progressive Lab from Hello World to Self-Hosted
AI agent development has a steep on-ramp. The combination of new SDKs, tool-calling patterns, model selection decisions, retrieval-augmented generation, and deployment concerns means most developers spend more time wiring things together than actually building anything useful. The Microsoft Foundry Agent Lab is a structured, open-source demo series designed to change that — nine self-contained demos, each adding exactly one new concept, all built on the same Microsoft Foundry SDK and a single model deployment. This post walks through what the lab contains, how each demo works under the hood, and the architectural decisions that make it a useful reference for AI engineers building production agents. Why a Progressive Lab? Agent frameworks can be overwhelming. A developer who opens a rich example with RAG, tool-calling, streaming, and a custom UI all at once has no clear line of sight to which parts are essential and which are embellishments. The Foundry Agent Lab takes the opposite approach: start with the absolute minimum and introduce one new primitive per demo. By the time you reach Demo 8, you have seen every major capability — not in one monolithic sample, but in a layered sequence where each addition is visible and understandable. # Demo New Concept Tool Used UX 0 hello-demo Agent creation, Responses API, conversations None Terminal 1 tools-demo Function calling, tool-calling loop, live API FunctionTool Terminal 2 desktop-demo UI decoupling — same agent, different surface None Desktop (Tkinter) 3 websearch-demo Server-side built-in tools, no client loop WebSearchTool Terminal 4 code-demo Code execution in sandbox, Gradio web UI CodeInterpreterTool Web (Gradio) 5 rag-demo Document upload, vector stores, RAG grounding FileSearchTool Terminal 6 mcp-demo MCP servers, human-in-the-loop approval MCPTool Terminal 7 toolbox-demo Centralized tool governance, Toolbox versioning Toolbox Terminal 8 hosted-demo Self-hosted agent with Responses protocol Custom server Terminal + Agent Inspector The Model Router: One Deployment to Rule Them All Before diving into the demos, it is worth understanding the one architectural decision that ties the entire lab together: every agent uses model-router as its model deployment. MODEL_DEPLOYMENT=model-router Model Router is a Microsoft Foundry capability that inspects each request at inference time and routes it to the optimal available model — weighing task complexity, cost, and latency. A simple factual question goes to a fast, cheap model. A complex tool-calling chain with code generation gets routed to a frontier model. You write zero routing logic. The lab's MODEL-ROUTER.md file contains empirical observations from running all nine demos. A sample of what the router selected: Demo Query Task Type Model Selected hello "What's the capital of WA state?" Factual recall grok-4-1-fast-reasoning hello "Summarize our conversation" Summarization gpt-5.2-chat-2025-12-11 tools "What's the weather in Seattle?" Tool-using gpt-5.4-mini-2026-03-17 code Data analysis with code generation Code generation + execution gpt-5.4-2026-03-05 rag HR policy document question Retrieval + synthesis gpt-5.3-chat-2026-03-03 This is the strongest signal in the lab: you do not need to reason about model selection. You declare what your agent needs to do; the router handles the rest, and it chooses correctly. Demo 0: The Minimum Viable Agent The hello-demo establishes the baseline pattern used by every subsequent demo. Two files: one to register the agent, one to chat with it. Registering the agent from azure.identity import DefaultAzureCredential from azure.ai.projects import AIProjectClient from azure.ai.projects.models import PromptAgentDefinition credential = DefaultAzureCredential() project = AIProjectClient(endpoint=PROJECT_ENDPOINT, credential=credential) agent = project.agents.create_version( agent_name=AGENT_NAME, definition=PromptAgentDefinition( model=MODEL_DEPLOYMENT, instructions="You are a helpful, friendly assistant.", ), ) Authentication uses DefaultAzureCredential , which works with az login locally and with managed identity in production — no API keys anywhere in the code. Chatting with the agent # Create a server-side conversation (persists history across turns) conversation = openai.conversations.create() # Each turn sends the user message; the agent sees full history response = openai.responses.create( input=user_input, conversation=conversation.id, extra_body={"agent_reference": {"name": AGENT_NAME, "type": "agent_reference"}}, ) print(response.output_text) The conversation object is server-side. You pass its ID on every turn; the history lives in Foundry, not in a local list. This is the Responses API pattern — distinct from the older Completions or Chat Completions APIs. Demo 1: Function Tools and the Tool-Calling Loop Demo 1 adds function calling against a real weather API. The key insight here is that the model does not execute the function — it requests the execution, and your code executes it locally, then feeds the result back. Declaring a function tool from azure.ai.projects.models import FunctionTool, PromptAgentDefinition func_tool = FunctionTool( name="get_weather", description="Get the current weather for a given city.", parameters={ "type": "object", "properties": {"city": {"type": "string", "description": "City name"}}, "required": ["city"], }, strict=True, ) agent = project.agents.create_version( agent_name=AGENT_NAME, definition=PromptAgentDefinition( model=MODEL_DEPLOYMENT, tools=[func_tool], instructions="You are a weather assistant...", ), ) The tool-calling loop response = openai.responses.create(input=user_input, conversation=conversation.id, ...) # Loop while the model is requesting tool calls while any(item.type == "function_call" for item in response.output): input_list = [] for item in response.output: if item.type == "function_call": args = json.loads(item.arguments) result = get_weather(args["city"]) # execute locally input_list.append(FunctionCallOutput(call_id=item.call_id, output=result)) # Send results back to the agent response = openai.responses.create(input=input_list, conversation=conversation.id, ...) print(response.output_text) The strict=True parameter on FunctionTool enforces structured outputs — the model must return arguments that match the declared JSON schema exactly. This eliminates argument parsing errors in production. Demo 2: UI Is Not Your Agent Demo 2 runs the exact same agent as Demo 1 but surfaces it in a Tkinter desktop window. The point is pedagogical: your agent definition, conversation management, and tool-calling logic are entirely independent of your UI layer. Swapping from terminal to desktop requires changing only the presentation code — nothing in the agent or conversation path changes. This is a principle worth internalising early: agent logic and UI logic should never be entangled. The lab enforces this separation structurally. Demo 3: Server-Side Built-In Tools The web search demo introduces a sharp contrast with Demo 1. With WebSearchTool , the tool-calling loop disappears entirely from client code: from azure.ai.projects.models import WebSearchTool agent = project.agents.create_version( agent_name="Search-Agent", definition=PromptAgentDefinition( model=MODEL_DEPLOYMENT, tools=[WebSearchTool()], instructions="You are a research assistant...", ), ) The agent decides when to search, executes the search server-side, and returns a grounded response with citations. Your client code looks identical to Demo 0 — a simple responses.create() call with no tool loop. The distinction matters architecturally: Function tools (Demo 1) — tool execution happens on your client; you control the code, the API call, the error handling. Built-in tools (Demo 3+) — tool execution happens inside Foundry; you get results without managing execution. Demo 4: Code Interpreter and the Gradio Web UI Demo 4 attaches CodeInterpreterTool , which gives the agent a sandboxed Python execution environment inside Foundry. The agent can write code, run it, observe output, and iterate — all server-side. Combined with a Gradio web interface, this demo shows an agent that can perform data analysis, generate charts, and explain results through a browser UI. Model Router is particularly interesting here: the empirical data shows it selects a more capable frontier model ( gpt-5.4-2026-03-05 ) for code-generation tasks, while simpler conversational turns stay on lighter models. Demo 5: Retrieval-Augmented Generation with FileSearchTool Demo 5 introduces RAG. The setup phase uploads a document, creates a vector store, and attaches it to the agent: # Upload document and create a vector store vector_store = openai.vector_stores.create(name="employee-handbook-store") with open("data/employee-handbook.md", "rb") as f: openai.vector_stores.files.upload_and_poll( vector_store_id=vector_store.id, file=f ) # Attach the vector store to the agent agent = project.agents.create_version( agent_name="RAG-Agent", definition=PromptAgentDefinition( model=MODEL_DEPLOYMENT, tools=[FileSearchTool(vector_store_ids=[vector_store.id])], instructions="Answer questions using only the provided documents...", ), ) At query time, the agent embeds the question, searches the vector store semantically, retrieves matching chunks, and generates an answer grounded in the retrieved content — entirely server-side. The client code remains a plain responses.create() call. An important detail: the .vector_store_id file is written to disk during setup and read back during the chat session, so the demo survives process restarts without re-uploading the document. The .gitignore excludes this file from source control. Demo 6: Model Context Protocol Demo 6 connects the agent to a GitHub MCP server, giving it access to repository and issue data via the open Model Context Protocol standard. MCP servers expose tools over a standardised wire protocol; the agent discovers and calls them without any client-side function declarations. The demo also demonstrates human-in-the-loop approval: before executing any MCP tool call, the agent surfaces the proposed action and waits for the user to confirm. This is an important safety pattern for agents that can trigger side effects on external systems. Demo 7: Toolbox — Centralised Tool Governance Where Demo 6 connects to a single MCP server directly, Demo 7 uses a Toolbox — a managed Microsoft Foundry resource that bundles multiple tools into a single, versioned, MCP-compatible endpoint. The Toolbox in this demo exposes both GitHub Issues and GitHub Repos tools, curated into an immutable versioned snapshot. This pattern is significant for production multi-agent systems: Centralised governance — one team owns the tool definitions; all agents consume them via a single endpoint. Versioned snapshots — promoting a new Toolbox version is explicit; agents pin to a version and upgrade intentionally. MCP compatibility — any MCP-capable agent or framework can connect, not just Foundry SDK agents. from azure.ai.projects.models import McpTool toolbox_tool = McpTool( server_label="toolbox", server_url=TOOLBOX_ENDPOINT, allowed_tools=[], # empty = all tools in the Toolbox version headers={"Authorization": f"Bearer {token}"}, ) Demo 8: Self-Hosted Agent with the Responses Protocol The final demo departs from the prompt-agent pattern. Instead of registering a declarative agent in Foundry, Demo 8 implements a custom agent server using the Responses protocol. The server exposes a streaming HTTP endpoint; Foundry's Agent Inspector can connect to it and route user turns to it just as it would to a hosted prompt agent. This demo includes a Dockerfile and an agent.yaml , enabling deployment to Foundry's container hosting service. It uses gpt-4.1-mini directly rather than the model router, because the custom server owns the entire inference path. When to consider this pattern: Your agent requires custom pre- or post-processing logic that cannot be expressed in a system prompt. You need to integrate with infrastructure that is not reachable through MCP or built-in tools. You want to own the inference call for cost control, A/B testing, or compliance reasons. You are building a multi-agent orchestrator that needs to expose itself as an agent to other orchestrators. Getting Started The lab requires Python 3.10 or higher, an Azure subscription with a Microsoft Foundry project, and the Azure CLI. 1. Clone and set up the virtual environment git clone https://github.com/microsoft-foundry/Foundry-Agent-Lab.git cd Foundry-Agent-Lab # Create and activate the virtual environment python -m venv .venv # Windows Command Prompt .venv\Scripts\activate.bat # Windows PowerShell .venv\Scripts\Activate.ps1 # macOS / Linux source .venv/bin/activate pip install -r requirements.txt 2. Configure a demo copy hello-demo\.env.sample hello-demo\.env # Edit hello-demo\.env and set PROJECT_ENDPOINT Your PROJECT_ENDPOINT is on the Overview page of your Foundry project in the Azure portal. It takes the form https://your-resource.ai.azure.com/api/projects/your-project . 3. Run the demo az login 0-hello-demo Each numbered batch file at the root activates the virtual environment, runs create_agent.py , and launches chat.py . Append log to capture the full session transcript: 0-hello-demo log Reset between runs hello-demo\reset.bat Every demo includes a reset.bat that deletes the registered agent and any associated resources (vector stores, uploaded files). Demos are fully repeatable. Architecture Principles Demonstrated Across the nine demos, the lab illustrates a set of design principles that apply directly to production agent systems: Keyless authentication throughout Every demo uses DefaultAzureCredential . No API keys appear anywhere in the code. Locally, az login provides credentials. In production, managed identity takes over automatically — same code, no secrets to rotate. Server-side conversation state The Responses API stores conversation history server-side. Your application passes a conversation ID; Foundry maintains the thread. This eliminates the common bug of truncating history due to local list management and makes multi-process or multi-instance deployments straightforward. Client-side vs server-side tool execution The lab makes the distinction explicit. Function tools execute in your process — you control the code, the external call, and the error handling. Built-in tools (WebSearch, CodeInterpreter, FileSearch) execute inside Foundry — you get results without managing execution infrastructure. MCP tools (Demo 6, 7) fall between these: they execute in a separately deployed server, with the protocol mediating the call. Progressive tool introduction Each demo's create_agent.py registers the agent once. The chat.py file handles the conversation loop. These two responsibilities are always separate, making it easy to update agent definitions without modifying conversation logic, and vice versa. Security Considerations When building agents for production, keep the following in mind: Never commit .env files. The .gitignore excludes them, but verify this before pushing. Use Azure Key Vault or environment variable injection in CI/CD pipelines. Use managed identity in production. DefaultAzureCredential automatically picks up managed identity when deployed to Azure, eliminating the need for any stored credentials. Apply human-in-the-loop for side-effecting tools. Demo 6 demonstrates this pattern for MCP tool calls. Any agent that can modify external state (create issues, send emails, write files) should surface proposed actions for confirmation. Validate tool outputs before use. Treat data returned by external tools (weather APIs, search results, document retrieval) as untrusted input. Prompt injection through tool results is a real attack surface; grounding instructions in your system prompt reduce but do not eliminate this risk. Scope Toolbox permissions narrowly. When using a Toolbox (Demo 7), use allowed_tools to restrict which tools the agent can call, rather than granting access to all tools in a Toolbox version. Key Takeaways Start with the minimum. A prompt agent with no tools requires fewer than 30 lines of code using the Foundry SDK. Add tools only when the use case demands them. Use model-router unless you have a specific reason not to. The empirical data in the lab shows the router selects appropriate models across all task types — factual, creative, tool-calling, RAG, and code generation. Understand the client/server tool boundary. Function tools give you control; built-in tools give you simplicity. MCP and Toolbox give you governance and interoperability. Choose based on where you need control and where you need scale. Conversation state belongs on the server. Do not maintain conversation history in application memory if you can avoid it. The Responses API conversation object is designed for this. The hosted-demo pattern is for when you need to own the inference path. For most use cases, a declarative prompt agent is sufficient and far simpler to operate. Next Steps Explore the repo: github.com/microsoft-foundry/Foundry-Agent-Lab Microsoft Foundry SDK documentation: learn.microsoft.com/azure/ai-studio/ Responses API quickstart: Prompt agent quickstart Model Router conceptual documentation: Model Router for Microsoft Foundry Model Context Protocol: modelcontextprotocol.io Azure Identity SDK (DefaultAzureCredential): azure-identity Python SDK The Foundry Agent Lab is open source under the MIT licence. Contributions, bug reports, and feature requests are welcome through GitHub Issues. See CONTRIBUTING.md for guidelines.Azure Skilling at Microsoft Ignite 2025
The energy at Microsoft Ignite was unmistakable. Developers, architects, and technical decision-makers converged in San Francisco to explore the latest innovations in cloud technology, AI applications, and data platforms. Beyond the keynotes and product announcements was something even more valuable: an integrated skilling ecosystem designed to transform how you build with Azure. This year Azure Skilling at Microsoft Ignite 2025 brought together distinct learning experiences, over 150+ hands-on labs, and multiple pathways to industry-recognized credentials—all designed to help you master skills that matter most in today's AI-driven cloud landscape. Just Launched at Ignite Microsoft Ignite 2025 offered an exceptional array of learning opportunities, each designed to meet developers anywhere on the skilling journey. Whether you joined us in-person or on-demand in the virtual experience, multiple touchpoints are available to deepen your Azure expertise. Ignite 2025 is in the books, but you can still engage with the latest Microsoft skilling opportunities, including: The Azure Skills Challenge provides a gamified learning experience that lets you compete while completing task-based achievements across Azure's most critical technologies. These challenges aren't just about badges and bragging rights—they're carefully designed to help you advance technical skills and prepare for Microsoft role-based certifications. The competitive element adds urgency and motivation, turning learning into an engaging race against the clock and your peers. For those seeking structured guidance, Plans on Learn offer curated sets of content designed to help you achieve specific learning outcomes. These carefully assembled learning journeys include built-in milestones, progress tracking, and optional email reminders to keep you on track. Each plan represents 12-15 hours of focused learning, taking you from concept to capability in areas like AI application development, data platform modernization, or infrastructure optimization. The Microsoft Reactor Azure Skilling Series, running December 3-11, brings skilling to life through engaging video content, mixing regular programming with special Ignite-specific episodes. This series will deliver technical readiness and programming guidance in a livestream presentation that's more digestible than traditional documentation. Whether you're catching episodes live with interactive Q&A or watching on-demand later, you’ll get world-class instruction that makes complex topics approachable. Beyond Ignite: Your Continuous Learning Journey Here's the critical insight that separates Ignite attendees who transform their careers from those who simply collect swag: the real learning begins after the event ends. Microsoft Ignite is your launchpad, not your destination. Every module you start, every lab you complete, and every challenge you tackle connects to a comprehensive learning ecosystem on Microsoft Learn that's available 24/7, 365 days a year. Think of Ignite as your intensive immersion experience—the moment when you gain context, build momentum, and identify the skills that will have the biggest impact on your work. What you do in the weeks and months following determines whether that momentum compounds into career-defining expertise or dissipates into business as usual. For those targeting career advancement through formal credentials, Microsoft Certifications, Applied Skills and AI Skills Navigator, provide globally recognized validation of your expertise. Applied Skills focus on scenario-based competencies, demonstrating that you can build and deploy solutions, not simply answer theoretical questions. Certifications cover role-based scenarios for developers, data engineers, AI engineers, and solution architects. The assessment experiences include performance-based testing in dedicated Azure tenants where you complete real configuration and development tasks. And finally, the NEW AI Skills Navigator is an agentic learning space, bringing together AI-powered skilling experiences and credentials in a single, unified experience with Microsoft, LinkedIn Learning and GitHub – all in one spot Why This Matters: The Competitive Context The cloud skills race is intensifying. While our competitors offer robust training and content, Microsoft's differentiation comes not from having more content—though our 1.4 million module completions last fiscal year and 35,000+ certifications awarded speak to scale—but from integration of services to orchestrate workflows. Only Microsoft offers a truly unified ecosystem where GitHub Copilot accelerates your development, Azure AI services power your applications, and Azure platform services deploy and scale your solutions—all backed by integrated skilling content that teaches you to maximize this connected experience. When you continue your learning journey after Ignite, you're not just accumulating technical knowledge. You're developing fluency in an integrated development environment that no competitor can replicate. You're learning to leverage AI-powered development tools, cloud-native architectures, and enterprise-grade security in ways that compound each other's value. This unified expertise is what transforms individual developers into force-multipliers for their organizations. Start Now, Build Momentum, Never Stop Microsoft Ignite 2025 offered the chance to compress months of learning into days of intensive, hands-on experience, but you can still take part through the on-demand videos, the Global Ignite Skills Challenge, visiting the GitHub repos for the /Ignite25 labs, the Reactor Azure Skilling Series, and the curated Plans on Learn provide multiple entry points regardless of your current skill level or preferred learning style. But remember: the developers who extract the most value from Ignite are those who treat the event as the beginning, not the culmination, of their learning journey. They join hackathons, contribute to GitHub repositories, and engage with the Azure community on Discord and technical forums. The question isn't whether you'll learn something valuable from Microsoft Ignite 2025-that's guaranteed. The question is whether you'll convert that learning into sustained momentum that compounds over months and years into career-defining expertise. The ecosystem is here. The content is ready. Your skilling journey doesn't end when Ignite does—it accelerates.Giving Your AI Agents Reliable Skills with the Agent Skills SDK
AI agents are becoming increasingly capable, but they often do not have the context they need to do real work reliably. Your agent can reason well, but it does not actually know how to do the specific things your team needs it to do. For example, it cannot follow your company's incident response playbook, it does not know your escalation policy, and it has no idea how to page the on-call engineer at 3 AM. There are many ways to close this gap, from RAG to custom tool implementations. Agent Skills is one approach that stands out because it is designed around portability and progressive disclosure, keeping context window usage minimal while giving agents access to deep expertise on demand. What is Agent Skills? Agent Skills is an open format for giving agents new capabilities and expertise. The format was originally developed by Anthropic and released as an open standard. It is now supported by a growing list of agent products including Claude Code, VS Code, GitHub, OpenAI Codex, Cursor, Gemini CLI, and many others. As defined in the spec, a skill is a folder on disk containing a SKILL.md file with metadata and instructions, plus optional scripts, references, and assets: incident-response/ SKILL.md # Required: instructions + metadata references/ # Optional: additional documentation severity-levels.md escalation-policy.md scripts/ # Optional: executable code page-oncall.sh assets/ # Optional: templates, diagrams, data files The SKILL.md file has YAML frontmatter with a name and description (so agents know when the skill is relevant), followed by markdown instructions that tell the agent how to perform the task. The format is intentionally simple: self-documenting, extensible, and portable. What makes this design practical is progressive disclosure. The spec is built around the idea that agents should not load everything at once. It works in three stages: Discovery: At startup, agents load only the name and description of each available skill, just enough to know when it might be relevant. Activation: When a task matches a skill's description, the agent reads the full SKILL.md instructions into context. Execution: The agent follows the instructions, optionally loading referenced files or executing bundled scripts as needed. This keeps agents fast while giving them access to deep context on demand. The format is well-designed and widely adopted, but if you want to use skills from your own agents, there is a gap between the spec and a working implementation. The Agent Skills SDK Conceptually, a skill is more than a folder. It is a unit of expertise: a name, a description, a body of instructions, and a set of supporting resources. The file layout is one way to represent that, but there is nothing about the concept that requires a filesystem. The Agent Skills SDK is an open-source Python library built around that idea, treating skills as abstract units of expertise that can be stored anywhere and consumed by any agent framework. It does this by addressing two challenges that come up when you try to use the format from your own agents. The first is where skills live. The spec defines skills as folders on disk, and the tools that support the format today all assume skills are local files. Files are inherently portable, and that is one of the format's strengths. But in the real world, not every team can or wants to serve skills from the filesystem. Maybe your team keeps them in an S3 bucket. Maybe they are in Azure Blob Storage behind your CDN. Maybe they live in a database alongside the rest of your application data. At the moment, if your skills are not on the local filesystem, you are on your own. The SDK changes where skills are served from, not how they are authored. The content and format stay the same regardless of the storage backend, so skills remain portable across providers. The second is how agents consume them. The spec defines the progressive disclosure pattern but actually implementing it in your agent requires real work. You need to figure out how to validate skills against the spec, generate a catalog for the system prompt, expose the right tools for on-demand content retrieval, and handle the back-and-forth of the agent requesting metadata, then the body, then individual references or scripts. That is a lot of plumbing regardless of where the skills are stored, and the work multiplies if you want to support more than one agent framework. The SDK solves both by separating where skills come from (providers) from how agents use them (integrations), so you can mix and match freely. Load skills from the filesystem today, move them to an HTTP server tomorrow, swap in a custom database provider next month, and your agent code does not change at all. How the SDK works The SDK is a set of Python packages organized around two ideas: storage-agnostic providers and progressive disclosure. The provider abstraction means your skills can live anywhere. The SDK ships with providers for the local filesystem and static HTTP servers, but the SkillProvider interface is simple enough that you can write your own in a few methods. A Cosmos DB provider, a Git provider, a SharePoint provider, whatever makes sense for your team. The rest of the SDK does not care where the data comes from. On top of that, the SDK implements the progressive disclosure pattern from the spec as a set of tools that any LLM agent can use. At startup, the SDK generates a skills catalog containing each skill's name and description. Your agent injects this catalog into its system prompt so it knows what is available. Then, during a conversation, the agent calls tools to retrieve content on demand, following the same discovery-activation-execution flow the spec describes. Here is the flow in practice: You register skills from any source (local files, an HTTP server, your own database). The SDK generates a catalog and tool usage instructions, which you inject into the system prompt. The agent calls tools to retrieve content on demand. This matters because context windows are finite. An incident response skill might have a main body, three reference documents, two scripts, and a flowchart. The agent should not load all of that upfront. It should read the body first, then pull the escalation policy only when the conversation actually gets to escalation. A quick example Here is what it looks like in practice. Start by loading a skill from the filesystem: from pathlib import Path from agentskills_core import SkillRegistry from agentskills_fs import LocalFileSystemSkillProvider provider = LocalFileSystemSkillProvider(Path("my-skills")) registry = SkillRegistry() await registry.register("incident-response", provider) Now wire it into a LangChain agent: from langchain.agents import create_agent from agentskills_langchain import get_tools, get_tools_usage_instructions tools = get_tools(registry) skills_catalog = await registry.get_skills_catalog(format="xml") tool_usage_instructions = get_tools_usage_instructions() system_prompt = ( "You are an SRE assistant. Use the available skill tools to look up " "incident response procedures, severity definitions, and escalation " "policies. Always cite which reference document you used.\n\n" f"{skills_catalog}\n\n" f"{tool_usage_instructions}" ) agent = create_agent( llm, tools, system_prompt=system_prompt, ) That is it. The agent now knows what skills are available and has tools to fetch their content. When a user asks "How do I handle a SEV1 incident?", the agent will call get_skill_body to read the instructions, then get_skill_reference to pull the severity levels document, all without you writing any of that retrieval logic. The same pattern works with Microsoft Agent Framework: from agentskills_agentframework import get_tools, get_tools_usage_instructions tools = get_tools(registry) skills_catalog = await registry.get_skills_catalog(format="xml") tool_usage_instructions = get_tools_usage_instructions() system_prompt = ( "You are an SRE assistant. Use the available skill tools to look up " "incident response procedures, severity definitions, and escalation " "policies. Always cite which reference document you used.\n\n" f"{skills_catalog}\n\n" f"{tool_usage_instructions}" ) agent = Agent( client=client, instructions=system_prompt, tools=tools, ) What is in the SDK The SDK is split into small, composable packages so you only install what you need: agentskills-core handles registration, validation, the skills catalog, and the progressive disclosure API. It also defines the SkillProvider interface that all providers implement. agentskills-fs and agentskills-http are the two built-in providers. The filesystem provider loads skills from local directories. The HTTP provider loads them from any static file host: S3, Azure Blob Storage, GitHub Pages, a CDN, or anything that serves files over HTTP. agentskills-langchain and agentskills-agentframework generate framework-native tools and tool usage instructions from a skill registry. agentskills-mcp-server spins up an MCP server that exposes skill tool access and usage as tools and resources, so any MCP-compatible client can use them. Because providers and integrations are separate packages, you can combine them however you want. Use the filesystem provider during development, switch to the HTTP provider in production, or write a custom provider that reads skills from your own database. The integration layer does not need to know or care. Where to go from here The full source, working examples, and detailed API docs are on GitHub: github.com/pratikxpanda/agentskills-sdk The repo includes end-to-end examples for both LangChain and Microsoft Agent Framework, covering filesystem providers, HTTP providers, and MCP. There is also a sample incident-response skill you can use to try things out. A proposal to contribute this SDK to the official agentskills repository has been submitted. If you find it useful, feel free to show your support on the GitHub issue. To learn more about the Agent Skills format itself: What are skills? covers the format and why it matters. Specification is the complete format reference for SKILL.md files. Integrate skills explains how to add skills support to your agent. Example skills on GitHub are a good starting point for writing your own. The SDK is MIT licensed and contributions are welcome. If you have questions or ideas, post a question here or open an issue on the repo.Enterprise-ready Claude Desktop with Entra ID, APIM, and Microsoft Foundry (No Backend Required)
How I put corporate sign-in in front of Claude Desktop without writing a single line of backend code. TL;DR — In this post, I show how to securely enable Claude Desktop in enterprise environments using Microsoft Entra ID, Azure API Management, and Microsoft Foundry — without deploying a custom backend. This approach removes API keys from endpoints, enforces per-user identity, and aligns fully with Zero Trust principles. Who this is for: Enterprise architects evaluating secure AI client patterns Developers enabling Claude Desktop in regulated environments Platform teams standardizing identity and governance for LLM access Why this post exists: Microsoft Learn's Configure Claude Desktop with Foundry Models only shows the API-key path — a shared key pasted into every user's Claude Desktop config. That's fine for a quick demo, but it's a non-starter for most enterprises (no per-user identity, no MFA / Conditional Access, hard to revoke, hard to audit). This post fills that gap: same Foundry backend, but with Microsoft Entra ID SSO in front via Azure API Management, so each user signs in with their corporate identity and zero secrets land on the laptop. The problem For many teams experimenting with Claude Desktop, the blocker isn't capability — it's enterprise readiness. How do you enforce identity, eliminate shared secrets, and apply governance without standing up a custom backend service to sit in front of the model? If your team wants to use Claude Desktop with your own Anthropic deployment running on Microsoft Foundry, but with a few non-negotiable requirements: No shared API keys floating around on developer laptops. Per-user identity — every request must be attributable to a real person. MFA and Conditional Access must apply, the same way they do for every other internal app. Central rate-limiting and logging — a centralized control plane for governance. Claude Desktop 1.5+ supports a "Gateway SSO" mode where it can sign each user in with OpenID Connect and forward their token to a custom LLM gateway. Azure API Management (APIM) is a perfect fit for that gateway role: it validates the user's Entra ID token, then re-authenticates itself to Foundry behind the scenes. APIM acts as a centralized policy enforcement layer, enabling identity validation, traffic governance, and secure re-authentication to backend AI services without custom code. The end-to-end flow looks like this: %%{init: {'flowchart': {'nodeSpacing': 60, 'rankSpacing': 80, 'useMaxWidth': true}, 'themeVariables': {'fontSize':'16px'}} }%% flowchart TB User([Corporate user]) Claude["Claude Desktop"] Entra["Microsoft Entra ID<br/>(OIDC + MFA + Conditional Access)"] APIM["Azure API Management<br/>validate-jwt → rewrite headers<br/>(policy gateway)"] Foundry["Microsoft Foundry<br/>Claude deployment"] User -- "1. Sign in (browser PKCE)" --> Entra Entra -- "2. ID token" --> Claude Claude -- "3. POST /v1/messages<br/>Authorization: Bearer ID token" --> APIM APIM -- "4. OIDC discovery / JWKS" --> Entra APIM -- "5. x-api-key (or Managed Identity)" --> Foundry Foundry -- "6. Response" --> APIM APIM -- "7. Response" --> Claude classDef azure fill:#0a4d8c,stroke:#0a3a6b,color:#ffffff; classDef client fill:#f3f3f3,stroke:#888,color:#222; class Entra,APIM,Foundry azure; class Claude,User client; Or in plain text: Claude Desktop │ Authorization: Bearer <Entra ID token from the user's browser sign-in> ▼ Azure API Management (<your-apim>) │ ① validate-jwt → verifies user's Entra ID token │ ② re-auths to Foundry with an API key from a Named value │ Authorization stripped, x-api-key injected ▼ Microsoft Foundry /anthropic/v1/messages │ runs Claude (<your-deployment>) ▼ Response back to the user There are no API keys on user devices. Foundry's key lives only inside APIM. And every request carries the user's oid claim, so I can build dashboards and per-user quotas later. What you need before starting An Azure subscription with a Microsoft Foundry (AI Services) account and a Claude deployment. (Throughout this post I'll just call it Foundry.) An API Management instance, any tier. Permission to register applications in Entra ID for your tenant. Claude Desktop 1.5.0 or later. Azure CLI installed locally. Throughout this post I'll use placeholders for resource names: <apim-name> — your API Management service name <resource-group> — the resource group that holds it <foundry-account> — your Foundry account name <deployment-name> — the name of the Claude model deployment on Foundry Step 1 — Register an Entra ID app for Claude Desktop This is the OIDC client Claude Desktop signs users into. Claude Desktop requires a single-tenant, public PKCE client (no client secret) with a loopback redirect URI, configured under the Mobile and desktop applications platform in Entra ID — the only platform that allows any loopback port. I scripted it so the setup is one command and idempotent: # scripts/register-claude-entra-app.ps1 [CmdletBinding()] param( [string] $TenantId = '<your-tenant-id>', [string] $SubscriptionId = '<your-subscription-id>', [string] $ResourceGroup = '<resource-group>', [string] $ApimName = '<apim-name>', [string] $AppDisplayName = 'Claude Cowork gateway', [string] $RedirectUri = 'http://127.0.0.1/callback' ) az account set --subscription $SubscriptionId | Out-Null # 1. Create (or reuse) the app registration $appId = az ad app list --display-name $AppDisplayName --query "[0].appId" -o tsv if (-not $appId) { $appId = az ad app create --display-name $AppDisplayName ` --sign-in-audience AzureADMyOrg --query appId -o tsv } # 2. Configure as public PKCE client with the Mobile/Desktop redirect URI $objectId = az ad app show --id $appId --query id -o tsv $patch = @{ publicClient = @{ redirectUris = @($RedirectUri) } isFallbackPublicClient = $true } | ConvertTo-Json -Depth 5 -Compress az rest --method PATCH ` --uri "https://graph.microsoft.com/v1.0/applications/$objectId" ` --headers "Content-Type=application/json" --body $patch | Out-Null # 3. Ensure a service principal exists $sp = az ad sp list --filter "appId eq '$appId'" --query "[0].id" -o tsv if (-not $sp) { az ad sp create --id $appId | Out-Null } # 4. Push two Named values into APIM for the validate-jwt policy az apim nv create -g $ResourceGroup --service-name $ApimName ` --named-value-id entra-tenant-id --display-name entra-tenant-id ` --value $TenantId --secret false az apim nv create -g $ResourceGroup --service-name $ApimName ` --named-value-id entra-client-id --display-name entra-client-id ` --value $appId --secret false "Client ID: $appId" Run it once. The output prints the client ID you'll need in Claude Desktop later, and it leaves two Named values in APIM ( entra-tenant-id , entra-client-id ) that the gateway policy will reference. ⚠️ Common pitfall: if the redirect URI ends up under the Web platform instead of Mobile and desktop applications, Entra will demand a client secret on token exchange — Claude won't send one and you'll get Token exchange failed (HTTP 401) . The app type can't be changed after creation, so create a new app if that happens. Step 2 — Create the API in APIM In the portal under APIM → APIs → + Add API → HTTP: Field Value Display name Anthropic API Name anthropicapi Web service URL https://<foundry-account>.services.ai.azure.com/anthropic API URL suffix claude Subscription required Off (Entra ID is our only credential) Add two operations under it: Method URL Display name POST /v1/messages Create message GET /v1/models List models The /v1/models operation isn't strictly needed (Foundry's Anthropic surface doesn't implement it), but having it registered means you can decide later whether to stub it out or proxy it. Step 3 — Add an API key for Foundry as a Named value APIM → Named values → + Add: Name: foundry-key Type: Secret Value: paste a key from the Foundry account's Keys and Endpoint blade. This is the only place the key ever lives. Clients never see it. Alternative — keyless with Entra ID (managed identity): If you prefer not to manage a Foundry key at all, enable the APIM instance's system-assigned managed identity (APIM → Identity → System assigned → On), then grant that identity the Foundry User role on the Foundry account (role ID 53ca6127-db72-4b80-b1b0-d745d6d5456d — previously named Azure AI User; Microsoft renamed it but the ID and permissions are unchanged). In Step 4, replace the set-header that injects x-api-key with: <authentication-managed-identity resource="https://cognitiveservices.azure.com" output-token-variable-name="foundry-token" /> <set-header name="Authorization" exists-action="override"> <value>@("Bearer " + (string)context.Variables["foundry-token"])</value> </set-header> Then you can skip the foundry-key Named value entirely. Don't use the legacy Cognitive Services User role — per the Foundry RBAC doc, roles starting with Cognitive Services don't apply to Foundry scenarios. Step 4 — Write the gateway policy This is the core enforcement layer in the architecture. Open APIs → anthropicapi → All operations → Inbound processing → </> and paste: <policies> <inbound> <base /> <!-- USER → APIM: verify Entra ID token from Claude Desktop --> <validate-jwt header-name="Authorization" failed-validation-httpcode="401" failed-validation-error-message="Unauthorized" require-scheme="Bearer"> <openid-config url="https://login.microsoftonline.com/{{entra-tenant-id}}/v2.0/.well-known/openid-configuration" /> <audiences> <audience>{{entra-client-id}}</audience> </audiences> <issuers> <issuer>https://login.microsoftonline.com/{{entra-tenant-id}}/v2.0</issuer> </issuers> </validate-jwt> <!-- APIM → Foundry --> <set-backend-service base-url="https://<foundry-account>.services.ai.azure.com/anthropic" /> <set-header name="x-api-key" exists-action="override"> <value>{{foundry-key}}</value> </set-header> <set-query-parameter name="api-version" exists-action="skip"> <value>2024-05-01-preview</value> </set-query-parameter> </inbound> <backend><base /></backend> <outbound><base /></outbound> <on-error><base /></on-error> </policies> Two things to notice: validate-jwt uses the OIDC discovery URL — JWKS keys are fetched and cached automatically. It rejects any token whose aud claim is not the client ID of our Entra app, which is exactly what we want. The Authorization header from the user is not forwarded — once validate-jwt succeeds, the request is re-authenticated to Foundry with x-api-key . No user token ever leaves APIM. APIM becomes the security boundary — user identity is validated at the edge, and downstream services never see or rely on user tokens. Step 5 — Configure Claude Desktop Open Claude Desktop → Configure third-party inference and fill it in like this: Field Value Connection Gateway Credential kind Interactive sign-in Gateway base URL https://<apim-name>.azure-api.net/claude Client ID (the appId your script printed) Issuer URL https://login.microsoftonline.com/<tenant-id>/v2.0 Authorization URL / Token URL leave empty Bearer token ID token (default) Scopes leave default ( openid profile email offline_access ) Redirect port leave empty (ephemeral) Model discovery Off Model list → Model ID <deployment-name> (your Foundry deployment name) ℹ️ Why Model discovery is Off — Claude Desktop's discovery uses GET /v1/models , and the Foundry /anthropic surface doesn't implement that endpoint, so it 404s. Listing the model manually skips the call entirely. If you want to leave Model discovery On, stub /v1/models in APIM. Add a GET /v1/models operation to your API and give it this inbound policy that returns an Anthropic-shaped response without ever hitting the backend: <policies> <inbound> <base /> <return-response> <set-status code="200" reason="OK" /> <set-header name="Content-Type" exists-action="override"> <value>application/json</value> </set-header> <set-body>@{ return new JObject( new JProperty("data", new JArray( new JObject( new JProperty("id", "<deployment-name>"), new JProperty("type", "model"), new JProperty("display_name", "Claude on Foundry"), new JProperty("created_at", "2026-01-01T00:00:00Z") ) )), new JProperty("has_more", false), new JProperty("first_id", "<deployment-name>"), new JProperty("last_id", "<deployment-name>") ).ToString(); }</set-body> </return-response> </inbound> <backend><base /></backend> <outbound><base /></outbound> <on-error><base /></on-error> </policies> Add one entry per deployment you want to expose. The benefit of stubbing rather than turning discovery off is that adding new models becomes a policy edit — no need to re-export and redeploy Claude Desktop config to every user. Click Apply Changes then Sign in to your organization. Your browser opens to the normal Entra sign-in page; once approved you're returned to the app, and a quick connection test runs. The success indicator is a small green banner: ✅ Inference — 1-token completion in 1449 ms · via identity provider For broader rollout, hit the Export button at the top of the configuration window — it produces a .mobileconfig (macOS) or .reg (Windows) you can push via Intune / Jamf to every user's machine. Step 6 — Verify both hops In APIM → APIs → anthropicapi → Test → POST /v1/messages I sent: Headers: anthropic-version: 2023-06-01 Body: { "model": "<deployment-name>", "max_tokens": 64, "messages": [{"role":"user","content":"hi"}] } Click Send → Trace, and look at two places: Inbound → validate-jwt: should say succeeded and show the decoded claims (your oid , email , etc.). Backend → Request: outbound URL is https://<foundry-account>.services.ai.azure.com/anthropic/v1/messages?api-version=2024-05-01-preview , with x-api-key: **** present and Authorization absent. Backend → Response: 200, with a Claude message JSON body. That confirms both halves of the chain. Bumps I hit along the way A few common issues encountered during setup — sharing so you can skip them: Symptom Cause Fix Claude shows "Your provider's model list hasn't loaded yet" and /v1/models returns 404 Foundry's Anthropic surface doesn't implement that endpoint Turn Model discovery OFF in Claude Desktop and add the deployment name manually Claude shows "Authentication failed" even though sign-in worked The APIM API still had Subscription required = ON, blocking the call before validate-jwt ran with 401: Access denied due to missing subscription key Uncheck Subscription required on the API Portal Test panel shows "Cannot read properties of undefined (reading 'statusCode')" The test console doesn't attach an Entra token, so validate-jwt 401s and the panel's JavaScript crashes Comment out <validate-jwt> temporarily for portal testing, or test via curl with a real token OIDC discovery failed (HTTP 404) in Claude Desktop Pasted the metadata URL into Issuer URL Issuer must end at /v2.0 , not at /.well-known/openid-configuration Token exchange failed (HTTP 401) App registered under Web platform instead of Mobile and desktop applications Create a new app with the right platform — it can't be changed Where this leaves us This pattern is small in moving parts but has outsized architectural impact: Zero secrets on endpoints. Eliminates API-key sprawl across laptops, MDM profiles, and shared vaults. The Foundry key lives only inside APIM — or disappears entirely when you switch APIM to managed identity. Identity, not credentials. Every Claude Desktop user authenticates against Entra ID in their browser, the same as Office or Teams. MFA, Conditional Access, and Entra ID Protection apply automatically — no parallel auth story to maintain. Per-user observability built in. APIM logs carry the user's Entra oid , email , and group claims. That unlocks per-user dashboards, cost allocation, and abuse detection without any client-side instrumentation. Aligned with Zero Trust. Strong identity at the edge, no implicit trust between hops, single policy chokepoint for inspection and rate-limiting, and full revocability through a single Enterprise Application. Optional but trivial keyless path. Flip APIM to system-assigned managed identity + <authentication-managed-identity resource="https://cognitiveservices.azure.com" /> and one Foundry User role assignment (role ID 53ca6127-db72-4b80-b1b0-d745d6d5456d , formerly Azure AI User) on the Foundry account. See the Foundry RBAC doc — don't use any Cognitive Services * roles for Foundry. What I'd add next llm-token-limit and llm-emit-token-metric policies for per-user quotas and cost visibility. App Insights wiring on the API, with a workbook that pivots on the oid claim. Assignment required = Yes on the Entra Enterprise Application + a security group, so only approved users can sign in. Intune deployment of the exported .reg / .mobileconfig so the gateway URL and client ID land on devices automatically. But that's all incremental. The hard part — getting Claude Desktop, Entra ID, APIM, and Foundry to agree on who's allowed to talk to whom — is done. Total elapsed: about an afternoon, most of it spent learning where each portal hides its switches. Useful links Gateway single sign-on with your identity provider — Claude.ai Documentation Configure Claude Desktop with Foundry Models — Microsoft Learn Role-based access control for Microsoft Foundry — Microsoft Learn3.4KViews0likes3CommentsBuild Multi‑Agent AI Systems with Microsoft
Like many of you I have been on a journey to build AI systems where multiple agents (AI models with tools and autonomy) collaborate to solve complex tasks. In this post, I want to share the engineering challenges we faced, the architecture we designed with Azure AI Foundry, and the lessons learned along the way. Our goal is to empower AI engineers and developers to leverage multi-agent systems for real-world applications, with the benefit of Microsoft’s tools, research insights, and enterprise-grade platform. Why Multi‑Agent Systems? The Need for AI Teamwork Building a single AI agent to perform a task is often straightforward. However, many real-world processes are too complex for one agent alone. Tasks like in-depth research, enterprise workflow automation, or multi-step customer service involve context switching and specialized knowledge that overwhelm a lone chatbot. Multi-agent systems address this by distributing work across specialized agents while maintaining coordination. This approach brings several advantages: Scalability: Workloads can be split among agents, enabling horizontal scaling as tasks or data increase. More agents can handle more subtasks in parallel, avoiding bottlenecks. Specialisation: Each agent can be fine-tuned for a specific role or domain (e.g. research, summarisation, data extraction), which improves performance and maintainability. No single model has to be a master of all trades. Flexibility: Modular agents can be reused in different workflows or recombined to create new capabilities. It’s easy to extend the system by adding or swapping an agent without redesigning everything. Robustness: If one agent fails or underperforms, others can pick up the slack. Decoupling tasks means the overall system can tolerate faults better than a monolithic agent. This mirrors how human teams work: we achieve more by dividing and conquering complex problems. In fact, internal experiments and industry reports have shown that groups of AI agents can significantly outperform a single powerful model on complex, open-ended tasks. For example, Anthropic found a multi-agent system (Claude agents working together) answered 90% more queries correctly than a single-agent approach in one evaluation. The ability to operate in parallel is key – our experience likewise showed that multiple agents exploring different aspects of a problem can cover far more ground, albeit with increased resource usage. Challenge: A downside of multi-agent setups is they consume more resources (more model calls, more tokens) than single-agent runs. In Anthropic’s research, multi-agent systems used ~15× the tokens of a single chat session. We’ve observed similarly that letting agents think and interact in depth pays off in better results, but at a cost. Ensuring the task’s value justifies the cost is important when choosing a multi-agent solution. Designing the Architecture: Orchestration via a Lead Agent To harness these benefits, we designed a multi-agent architecture built around an orchestrator-worker pattern – very similar to Anthropic’s “lead agent and subagents” approach. In Azure AI Foundry (our enterprise AI platform), this takes shape as Connected Agents: a mechanism where a main agent can spawn and coordinate child agents to handle sub-tasks. The main agent is the brain of the operation, responsible for understanding the user’s request, breaking it into parts, and delegating those parts to the appropriate specialist agents. Each agent in the system is defined with three core components: Instructions (prompt/policy): defining the agent’s goal, role, and constraints (its “game plan”). Model: an LLM that powers the agent’s reasoning and dialogue (e.g. GPT-4 or other models available in Foundry). Tools: external capabilities the agent can invoke to get information or take actions (e.g. web search, databases, APIs). By composing agents with different instructions and tools, we create a team where each agent has a clear role. The main agent’s role is orchestration; the sub-agents focus on specific tasks. This separation of concerns makes the system easier to understand and debug, and prevents any single context window from becoming overloaded. How it works (overview): When a user query comes in, the lead agent analyzes the request and devises a plan. It may decide that multiple pieces of information or steps are needed. The lead agent then spins up subordinate agents in parallel to gather or compute those pieces]. Each sub-agent operates with its own context window and tools, exploring one aspect of the task. They report their findings back to the lead agent, which integrates the results and decides if more exploration is required. The loop continues until the lead agent is satisfied that it can produce a final answer, at which point it consolidates everything and returns the result to the user. This orchestrator/sub-agent pattern is powerful because it lets complex tasks be solved through natural language delegation rather than hard-coded logic. Notably, the main agent doesn’t need an if/else tree written by us to decide which sub-agent handles what; it uses the language model’s reasoning to route tasks. In Azure AI Foundry’s Connected Agents, the primary agent simply says (in effect) “You, Agent A, do X; You, Agent B, do Y,” and the platform handles the rest—no custom orchestration code needed. This drastically simplified our development: we focus on crafting the right prompts and agent designs, and let the AI figure out the coordination. Example: Sales Assistant with Specialist Agents To make this concrete, imagine a Sales Preparation Assistant that helps a sales team research a client before a meeting. Instead of trying to cram all knowledge and skills into one model, we give the assistant a team of four sub-agents, each an expert in a different area. The main agent (“Sales Assistant”) will ask each specialist for input and then compile a briefing. Agent Role Purpose & Task Example Tools/Models Used Market Research Agent Gathers industry trends and news related to the client’s sector. Bing Web Search, internal news API Competitive Analysis Agent Finds information on the client’s competitors and market position. Web Search, Company DB Customer Insights Agent Summarises the client’s history and interactions (from CRM data). Azure Cognitive Search on CRM, GPT-4 Financial Analysis Agent Reviews the client’s financial data and recent performance. Finance database query tool, Excel APIs Main Sales Assistant Orchestrator that delegates to the above agents, then synthesises a final report for the sales team. GPT-4 (with instructions to compile and format results) In this scenario, the Main Sales Assistant agent would ask each sub-agent to report on their specialty (market news, competition, CRM insights, finances). Rather than one AI trying to do it all (and possibly missing nuances), we have focused mini-AIs each doing a thorough job in parallel. This approach was shown to reduce the overall time required and improve the quality of the final output. In early trials, such multi-agent setups often succeed where single agents fall short – for instance, finding all relevant facts across disparate sources and preparing a comprehensive briefing more quickly. Development is easier too: if tomorrow we need to add a “Regulatory Compliance Agent” for a new client requirement, we can plug it in without retraining or heavily modifying the others. Orchestration under the hood: Azure AI Foundry’s Agent Service provides the runtime that makes all this work reliably. It manages the message passing between the main agent and sub-agents, ensures each tool invocation is executed (with retries on failure), and keeps a structured log of the entire multi-agent conversation (we call it a thread). This means developers don’t have to manually implement how agents call each other or share data; the platform handles those mechanics. Foundry also supports true agent-to-agent messaging if agents need to talk directly, but often a hierarchical pattern (through the main agent) suffices for task delegation. Tools, Knowledge, and the Model Context Protocol (MCP) For agents to be effective, especially in enterprise scenarios, they must integrate with external knowledge sources and services – no single LLM knows everything or can perform all actions. Microsoft’s approach emphasizes a rich tool integration layer. In our system, tools range from web search and databases to APIs for taking real actions (sending emails, executing workflows, etc.) Equipping agents with the right tools extends their capabilities dramatically: an agent can retrieve up-to-date info, pull data behind corporate firewalls, or trigger business processes. One key innovation is the Model-Context Protocol (MCP), which Foundry uses to manage tools. MCP provides a structured way for agents to discover and use tools dynamically at runtime. Traditionally, if you wanted your AI agent to use a new tool, you might have to hard-code that tool’s API and update the agent’s code or prompt. With MCP, tools are defined on a central tool server (with descriptions and endpoints), and agents can query this server to see what tools are available. The agent’s SDK then generates the necessary code “stubs” to call the tool on the fly. This means: Easier maintenance: You can add, update, or remove tools in one place (the MCP registry) without changing the agent’s code. When the Finance database API updates, just update its MCP entry; all agents automatically get the new version next time they run. Dynamic adaptability: Agents can choose tools based on context. For example, a research agent might discover that a new MarketAnalysisAPI tool is available and start using it for a finance query, whereas previously it only had a generic web search. Separation of concerns: Those building AI agents can rely on domain experts to maintain the tool definitions, while they focus on the agent logic. Agents treat tools in a uniform way, as functions they can call. In practice, tool selection became a critical part of our agent design. A lesson we learned is that giving agents access to the right tool, with a clear description, can make or break their performance. If a tool’s description is vague or overlapping with another, the agent might choose the wrong approach and wander down a blind alley. For instance, we saw cases where an agent would stubbornly query an internal knowledge base for information that actually only existed on the web, simply because the tool prompt made the web search sound less relevant. We addressed this by carefully curating tool descriptions and even building an internal tool-testing agent that automatically tries out tools and suggests better descriptions for them. Ensuring each tool had a distinct purpose and clear usage guidance dramatically improved our agents’ success rate in choosing the optimal tool for a given job. Finally, multi-modal support is worth noting. Some tasks involve not just text, but images or other media. Our multi-agent architecture, especially with Azure AI Foundry, can incorporate vision-capable models as agents or tools. For example, an “Image Analysis Agent” could be part of a team, or an agent might call a vision API tool. The Telco customer service demo (using Foundry + OpenAI Agent SDK) featured an agent that could handle image uploads (like an ID document) by invoking an image-processing function. The orchestration framework doesn’t fundamentally change with multi-modality, it simply treats the vision model as another specialist agent or tool in the conversation. The ability to plug in different AI skills (text, vision, search, etc.) under a unified agent system is a big advantage of Microsoft’s approach: the agent team becomes cross-functional, each member with their own modality or expertise, collectively solving richer tasks than any single foundation model could. Reliability, Safety, and Enterprise-Grade Engineering While the basic idea of agents chatting and calling tools is elegant, productionizing this system for enterprise use brought serious engineering challenges. We needed our multi-agent system to be reliable, controllable, and secure. Here are the key areas we focused on and how we addressed them: Observability and Debugging Multi-agent chains can be complex and non-deterministic each run might involve different paths as agents make choices. Early on, we realized that treating the system as a black box was untenable. Developers and operators must be able to observe what each agent is “thinking” and doing, or else diagnosing issues would be impossible. Azure AI Foundry’s Agent Service was built with full conversation traceability in mind. Every message between agents (and to the user), every tool invocation and result, is captured in a structured thread log. We integrated this with Azure Application Insights telemetry, so one can monitor performance, latencies, errors, and even token consumption of agents in real time. This tracing proved invaluable. For example, when a complex workflow wasn’t producing the expected outcome, we could replay the entire agent conversation step by step to see where things went awry. In one instance, we found that two sub-agents were given slightly overlapping responsibilities, causing them to waste time retrieving nearly identical information. The logs and message transcripts made this immediately clear, guiding us to tighten the role definitions. Moreover, because the system logs are structured (not just free-form text), we could build automatic analysis tools like checking how often an agent hits a retry or how many cycles a conversation goes through before completion – to spot anomalies. This kind of observability was something the open-source community also highlighted as crucial; in fact, Sematic Kernel, AutoGen frameworks introduce metrics tracking and message tracing for exactly this reason. We also developed visual debugging tools. One example is the AutoGen Studio (a low-code interface from Microsoft Research) which allows developers to visually inspect agent interactions in real time, pause agents, or adjust their behavior on the fly. This interactive approach accelerates the prompt-engineering loop: one can watch agents argue or collaborate live, and intervene if needed. Such capabilities turned out to be vital for understanding emergent behaviors in multi-agent setups. Coordination Complexity and State Management As more agents come into play, keeping them coordinated and preserving shared context is hard. Early versions of agents would sometimes spawn excessive numbers of agents or get stuck in loops. For instance, one of our prototypes (before we applied strict limits) ended up in a degenerate state where two agents kept handing control back and forth without making progress. This taught us to implement guardrails and smarter orchestration policies. In Azure AI Foundry, beyond the simple connected-agent pattern, we introduced a more structured orchestration capability called Multi-Agent Workflows. This lets developers explicitly define states, transitions, and triggers in a workflow that involves multiple agents. It’s like flowcharting the high-level process that the agents should follow, including how they pass data around. We use this for long-running or highly critical processes where you want extra determinism for example, an onboarding workflow might have clearly defined phases (Verification → Provisioning → Notification) each handled by different agents, and you want to ensure the process doesn’t derail. The workflow engine enforces that the system moves to the next state only when all agents in the current state have completed and certain conditions (triggers) are met. It also provides persistence: if the process needs to wait (say, for an external event or simply because it’s a lengthy task), the state is saved and can be resumed later without losing context. These workflow features were a response to reliability needs, they give fine-grained control and error recovery in multi-agent systems that operate over extended periods. In practice, we learned to use the simpler Connected Agents approach for quick, on-the-fly delegations (it’s amazingly capable with minimal setup), and reserve Workflow Orchestration for scenarios where we must guarantee a robust sequence over minutes, hours, or days. By having both options, we can strike a balance between flexibility and control as needed. Trust, Safety, and Governance When you let AI agents act autonomously (especially if they can use tools that modify data or interact with the real world), safety is paramount. From day one, our design included enterprise-grade safety measures: Content Filtering and Policy Enforcement: All AI outputs go through content filters to catch disallowed content or potential prompt injection attacks. The Foundry Agent Service has integrated guardrails so that even if an agent tries something risky (e.g., a tool returns a sensitive info that should not be shown), policies can prevent misuse or leakage. For example, we configured financial analysis agents with rules not to output certain PII or to stop if they detect a regulatory compliance issue, handing off to a human instead. Identity and Access Control: Agents operate with identities managed via Microsoft Entra ID (Azure AD). This means every action an agent takes can be attributed and audited. Role-Based Access Control (RBAC) is enforced: an agent only has access to the data and APIs its role permits. If an agent’s credentials are compromised or misused, Azure’s standard auditing can alert us. Essentially, agents are first-class service principals in our cloud stack. Network Isolation and Compliance: For enterprise deployments, Azure AI Foundry allows agents to run in isolated networks (so they can’t arbitrarily call external services unless allowed) and to use customer-managed storage and search indices. This addresses the data governance aspect, we can ensure an agent looking up internal documents only sees what it’s supposed to, and all data stays within compliant boundaries. Auditability: As mentioned earlier, every decision an agent makes (every tool it calls, every answer it gives) is recorded. This is crucial for trust, if a multi-agent system is making business decisions, we need to be able to explain and justify those decisions later. By retaining the full reasoning trace and sources, we make the system’s work transparent and auditable. In fact, our “Deep Research” agents output not just answers but also a log of how they arrived at that answer, including citations to source material for each claim. This level of detail is a must-have in regulated industries or any high-stakes use case. Overall, baking in trust and safety by design was a non-negotiable requirement. It does introduce some overhead – e.g., being strict about content filtering can sometimes stop an agent from a creative solution until we refine its prompt or the filter thresholds, but it’s worth it for the confidence it gives to deploy these agents at scale. Performance and Cost Considerations We touched on the resource cost of multi-agent systems. Another challenge was ensuring the system runs efficiently. Without care, adding agents can linearly increase cost and latency. We mitigated this in a few ways: Parallelism: We make agents run concurrently wherever possible. Our lead agents typically fire off multiple sub-agents at once rather than sequentially waiting for one then starting the next. Also, our agents themselves can issue parallel tool calls. In fact, we enabled some of our retrieval agents to batch multiple search queries and send them all at the same time. Anthropic reported that this kind of parallelism cut their research task times by up to 90%, and we’ve observed similar dramatic speed-ups. By doing in 1 minute what a single agent might take 10 minutes to do step-by-step, we make the approach far more practical. Of course, the flip side is hitting many APIs and LLM endpoints concurrently can spike usage costs; we carefully monitor usage and recommend multi-agent mode only when needed for the problem complexity. Scaling rules and agent limits: One lesson learned was to prevent “agent sprawl.” We devised guidelines (and encoded some in prompts) about how many sub-agents to use for a given task complexity. For simple fact queries, the main agent is encouraged to handle it alone or with at most one helper; for moderately complex tasks, maybe spin up 2–3; only truly complex projects get a dozen specialists. This avoids the situation where an overzealous orchestrator might launch an army of agents and overkill the problem. These limits were informed by experimentation and echo the principle of scaling effort to the problem size. Model selection: Multi-agent systems don’t always need the largest model for every agent. We often use a mix of model sizes to optimize cost. For instance, a straightforward data extraction agent might be powered by a cheaper GPT-3.5, while the synthesis agent uses GPT-4 for the final answer quality. Foundry makes it easy to deploy a range of model endpoints (including open-source Llama-based models) and each agent can pick the one best suited. We learned that using an expensive model for a simple sub-task is wasteful; a smaller model with the right tools can do the job just as well. This mix-and-match approach helped keep our compute costs in check without sacrificing outcome quality. Lessons Learned and Best Practices Building these multi-agent systems was an iterative learning process. Here are some of the key lessons and best practices that emerged, which we believe will be useful to anyone developing their own: Let’s expand on a couple of these points: Prompt engineering for multi-agent is different: We quickly discovered that writing prompts for a team of agents is an order of magnitude more complex than for a single chatbot. Not only do you have to get each agent’s behavior right, you must shape how they interact. One principle that served us well was: “Think like your agents.” When debugging, we’d often step through the conversation from each agent’s perspective, almost role-playing as them, to see why they might be doing something silly. If an agent was repeating another’s results, maybe our instructions were too vague and they didn’t realise that sub-task was already covered. The fix would be to clarify the division of labour in the lead agent’s prompt or introduce an ordering (e.g., Agent B only runs after Agent A’s info is in, etc.). Another principle: teach the orchestrator to delegate effectively. The main agent’s prompt now includes explicit guidance on how to break down tasks and how to phrase sub-agent assignments with plenty of detail. We learned that if the lead just says “Research topic X” to two different agents, they might both do the same thing. Now, the lead agent provides distinct objectives and context to each sub-agent (e.g., focus one on recent news, another on historical data, etc.). This reduced redundancy and missed coverage dramatically. Let the AI help improve itself: One delightful surprise was that large models can be quite good at analyzing and refining their own strategies when asked. We sometimes gave an agent a chance to critique its output or plan, essentially a self-reflection step. In other cases we had a “judge” agent evaluate the final answers against criteria (accuracy, completeness, etc.) These evaluations not only gave us a score for benchmarking changes, but the judge’s feedback (being an LLM) often highlighted exactly where an agent went off track or missed something. In a sense, we used one AI to tell us how to make another AI better. This kind of meta-prompting and self-correction became a powerful tool in our development cycle, allowing faster iteration without full human-in-the-loop at every turn. Know when to simplify: Not every problem needs a fleet of agents. A big lesson was to use the simplest approach that works. If a single agent with a smart prompt can handle a task reliably, that’s fine! We reserved multi-agent mode for when there was clear added value e.g., problems requiring parallel exploration, different expertise, or lengthy reasoning that benefits from splitting into parts. This discipline kept our systems leaner and easier to maintain. It also helped us explain the value to stakeholders: we could justify the complexity by pointing to concrete gains (like a task that went from 2 hours by a single high-end model to 10 minutes by a team of agents with better results). Conclusion and Next Steps Multi-agent AI systems have moved from intriguing research demos to practical, production-ready solutions. Our journey involved close collaboration between teams such as those who built open-source frameworks like AutoGen to experiment with multi-agent interactions) and the Azure AI product teams (who turned these concepts into the robust Azure AI Foundry Agent Service). Along the way, we learned how to orchestrate LLMs at scale, how to keep them in check, and how to squeeze the most value out of agent collaboration. Today, Azure AI Foundry’s Agents platform provides a unified environment to develop, test, and deploy multi-agent systems, complete with the orchestration, observability, and safety features to make them enterprise-ready. The public preview of features like Connected Agents and Deep Research (which is essentially an advanced research agent that uses the web + analysis in a multi-step process) is already enabling customers to build “AI teams” that tackle complex workflows. This is just the beginning. We’re continuing to improve the platform with feedback from developers: upcoming releases will further tighten integration with the broader Azure ecosystem (for example, more seamless use of Azure Cognitive Search, Excel as a tool, etc.), expand the library of pre-built agent templates in the Agent Catalog (so you can start with a solid example for common scenarios), and introduce more advanced coordination patterns inspired by real-world use cases. If you’re an AI engineer or developer eager to explore multi-agent systems, now is a great time to dive in. Here are some resources to get you started: Microsoft AI Agents for Beginners - Learn all about AI Agents with this FREE curricula Azure AI Foundry Documentation – Learn more about the Agent Service and how to configure agents, tools, and workflows. Microsoft Learn Modules – step-by-step tutorial to build a connected multi-agent solution (for example, a ticket triage system) using Azure AI Foundry Agent Service. This will walk you through setting up agents and using the SDK. Microsoft MCP for Beginners: Integrating MCP Tools – Another tutorial focused on the Model Context Protocol, showing how to enable dynamic tool discovery for your agents. Azure AI Foundry Agent Catalog – Browse a growing collection of open-sourced agent examples contributed by Microsoft and partners, covering scenarios from content compliance to manufacturing optimization. These samples are great starting points to see how multi-agent code is structured in real projects. Multi-agent systems represent a significant shift in how we conceptualise AI solutions: from single brilliant assistants to teams of specialised agents working in concert. The engineering journey hasn’t been easy we navigated challenges in coordination, built new tooling for control, and refined prompts endlessly. But the end result is a new class of AI applications that are more powerful, resilient, and tunable. We hope the insights shared here help you in your own journey to build with AI agents. We’re excited to see what you will create with these technologies. As we continue to push the frontier of agentic AI (both in research and in Azure), one thing is clear: many minds – human or AI – are often better than one. Happy building! Userful References Introducing Multi-Agent Orchestration in Foundry Agent Service – Build ... Building a multimodal, multi-agent system using Azure AI Agent Service ... How we built our multi-agent research system \ Anthropic What is Azure AI Foundry Agent Service? - Azure AI Foundry Multi-Agent Systems and MCP Tools Integration with Azure AI Foundry ... Introducing Deep Research in Azure AI Foundry Agent Service AutoGen v0.4: Advancing the development of agentic AI systemsBuilding Interactive Agent UIs with AG-UI and Microsoft Agent Framework
Introduction Picture this: You've built an AI agent that analyzes financial data. A user uploads a quarterly report and asks: "What are the top three expense categories?" Behind the scenes, your agent parses the spreadsheet, aggregates thousands of rows, and generates visualizations. All in 20 seconds. But the user? They see a loading spinner. Nothing else. No "reading file" message, no "analyzing data" indicator, no hint that progress is being made. They start wondering: Is it frozen? Should I refresh? The problem isn't the agent's capabilities - it's the communication gap between the agent running on the backend and the user interface. When agents perform multi-step reasoning, call external APIs, or execute complex tool chains, users deserve to see what's happening. They need streaming updates, intermediate results, and transparent progress indicators. Yet most agent frameworks force developers to choose between simple request/response patterns or building custom solutions to stream updates to their UIs. This is where AG-UI comes in. AG-UI is a fairly new event-based protocol that standardizes how agents communicate with user interfaces. Instead of every framework and development team inventing their own streaming solution, AG-UI provides a shared vocabulary of structured events that work consistently across different agent implementations. When an agent starts processing, calls a tool, generates text, or encounters an error, the UI receives explicit, typed events in real time. The beauty of AG-UI is its framework-agnostic design. While this blog post demonstrates integration with Microsoft Agent Framework (MAF), the same AG-UI protocol works with LangGraph, CrewAI, or any other compliant framework. Write your UI code once, and it works with any AG-UI-compliant backend. (Note: MAF supports both Python and .NET - this blog post focuses on the Python implementation.) TL;DR The Problem: Users don't get real-time updates while AI agents work behind the scenes - no progress indicators, no transparency into tool calls, and no insight into what's happening. The Solution: AG-UI is an open, event-based protocol that standardizes real-time communication between AI agents and user interfaces. Instead of each development team and framework inventing custom streaming solutions, AG-UI provides a shared vocabulary of structured events (like TOOL_CALL_START, TEXT_MESSAGE_CONTENT, RUN_FINISHED) that work across any compliant framework. Key Benefits: Framework-agnostic - Write UI code once, works with LangGraph, Microsoft Agent Framework, CrewAI, and more Real-time observability - See exactly what your agent is doing as it happens Server-Sent Events - Built on standard HTTP for universal compatibility Protocol-managed state - No manual conversation history tracking In This Post: You'll learn why AG-UI exists, how it works, and build a complete working application using Microsoft Agent Framework with Python - from server setup to client implementation. What You'll Learn This blog post walks through: Why AG-UI exists - how agent-UI communication has evolved and what problems current approaches couldn't solve How the protocol works - the key design choices that make AG-UI simple, reliable, and framework-agnostic Protocol architecture - the generic components and how AG-UI integrates with agent frameworks Building an AG-UI application - a complete working example using Microsoft Agent Framework with server, client, and step-by-step setup Understanding events - what happens under the hood when your agent runs and how to observe it Thinking in events - how building with AG-UI differs from traditional APIs, and what benefits this brings Making the right choice - when AG-UI is the right fit for your project and when alternatives might be better Estimated reading time: 15 minutes Who this is for: Developers building AI agents who want to provide real-time feedback to users, and teams evaluating standardized approaches to agent-UI communication To appreciate why AG-UI matters, we need to understand the journey that led to its creation. Let's trace how agent-UI communication has evolved through three distinct phases. The Evolution of Agent-UI Communication AI agents have become more capable over time. As they evolved, the way they communicated with user interfaces had to evolve as well. Here's how this evolution unfolded. Phase 1: Simple Request/Response In the early days of AI agent development, the interaction model was straightforward: send a question, wait for an answer, display the result. This synchronous approach mirrored traditional API calls and worked fine for simple scenarios. # Simple, but limiting response = agent.run("What's the weather in Paris?") display(response) # User waits... and waits... Works for: Quick queries that complete in seconds, simple Q&A interactions where immediate feedback and interactivity aren't critical. Breaks down: When agents need to call multiple tools, perform multi-step reasoning, or process complex queries that take 30+ seconds. Users see nothing but a loading spinner, with no insight into what's happening or whether the agent is making progress. This creates a poor user experience and makes it impossible to show intermediate results or allow user intervention. Recognizing these limitations, development teams began experimenting with more sophisticated approaches. Phase 2: Custom Streaming Solutions As agents became more sophisticated, teams recognized the need for incremental feedback and interactivity. Rather than waiting for the complete response, they implemented custom streaming solutions to show partial results as they became available. # Every team invents their own format for chunk in agent.stream("What's the weather?"): display(chunk) # But what about tool calls? Errors? Progress? This was a step forward for building interactive agent UIs, but each team solved the problem differently. Also, different frameworks had incompatible approaches - some streamed only text tokens, others sent structured JSON, and most provided no visibility into critical events like tool calls or errors. The problem: No standardization across frameworks - client code that works with LangGraph won't work with Crew AI, requiring separate implementations for each agent backend Each implementation handles tool calls differently - some send nothing during tool execution, others send unstructured messages Complex state management - clients must track conversation history, manage reconnections, and handle edge cases manually The industry needed a better solution - a common protocol that could work across all frameworks while maintaining the benefits of streaming. Phase 3: Standardized Protocol (AG-UI) AG-UI emerged as a response to the fragmentation problem. Instead of each framework and development team inventing their own streaming solution, AG-UI provides a shared vocabulary of events that work consistently across different agent implementations. # Standardized events everyone understands async for event in agent.run_stream("What's the weather?"): if event.type == "TEXT_MESSAGE_CONTENT": display_text(event.delta) elif event.type == "TOOL_CALL_START": show_tool_indicator(event.tool_name) elif event.type == "TOOL_CALL_RESULT": show_tool_result(event.result) The key difference is structured observability. Rather than guessing what the agent is doing from unstructured text, clients receive explicit events for every stage of execution: when the agent starts, when it generates text, when it calls a tool, when that tool completes, and when the entire run finishes. What's different: A standardized vocabulary of event types, complete observability into agent execution, and framework-agnostic clients that work with any AG-UI-compliant backend. You write your UI code once, and it works whether the backend uses Microsoft Agent Framework, LangGraph, or any other framework that speaks AG-UI. Now that we've seen why AG-UI emerged and what problems it solves, let's examine the specific design decisions that make the protocol work. These choices weren't arbitrary - each one addresses concrete challenges in building reliable, observable agent-UI communication. The Design Decisions Behind AG-UI Why Server-Sent Events (SSE)? Aspect WebSockets SSE (AG-UI) Complexity Bidirectional Unidirectional (simpler) Firewall/Proxy Sometimes blocked Standard HTTP Reconnection Manual implementation Built-in browser support Use case Real-time games, chat Agent responses (one-way) For agent interactions, you typically only need server→client communication, making SSE a simpler choice. SSE solves the transport problem - how events travel from server to client. But once connected, how does the protocol handle conversation state across multiple interactions? Why Protocol-Managed Threads? # Without protocol threads (client manages): conversation_history = [] conversation_history.append({"role": "user", "content": message}) response = agent.complete(conversation_history) conversation_history.append({"role": "assistant", "content": response}) # Complex, error-prone, doesn't work with multiple clients # With AG-UI (protocol manages): thread = agent.get_new_thread() # Server creates and manages thread agent.run_stream(message, thread=thread) # Server maintains context # Simple, reliable, shareable across clients With transport and state management handled, the final piece is the actual messages flowing through the connection. What information should the protocol communicate, and how should it be structured? Why Standardized Event Types? Instead of parsing unstructured text, clients get typed events: RUN_STARTED - Agent begins (start loading UI) TEXT_MESSAGE_CONTENT - Text chunk (stream to user) TOOL_CALL_START - Tool invoked (show "searching...", "calculating...") TOOL_CALL_RESULT - Tool finished (show result, update UI) RUN_FINISHED - Complete (hide loading) This lets UIs react intelligently without custom parsing logic. Now that we understand the protocol's design choices, let's see how these pieces fit together in a complete system. Architecture Overview Here's how the components interact: The communication between these layers relies on a well-defined set of event types. Here are the core events that flow through the SSE connection: Core Event Types AG-UI provides a standardized set of event types to describe what's happening during an agent's execution: RUN_STARTED - agent begins execution TEXT_MESSAGE_START, TEXT_MESSAGE_CONTENT, TEXT_MESSAGE_END - streaming segments of text TOOL_CALL_START, TOOL_CALL_ARGS, TOOL_CALL_END, TOOL_CALL_RESULT - tool execution events RUN_FINISHED - agent has finished execution RUN_ERROR - error information This model lets the UI update as the agent runs, rather than waiting for the final response. The generic architecture above applies to any AG-UI implementation. Now let's see how this translates to Microsoft Agent Framework. AG-UI with Microsoft Agent Framework While AG-UI is framework-agnostic, this blog post demonstrates integration with Microsoft Agent Framework (MAF) using Python. MAF is available in both Python and .NET, giving you flexibility to build AG-UI applications in your preferred language. Understanding how MAF implements the protocol will help you build your own applications or work with other compliant frameworks. Integration Architecture The Microsoft Agent Framework integration involves several specialized layers that handle protocol translation and execution orchestration: Understanding each layer: FastAPI Endpoint - Handles HTTP requests and establishes SSE connections for streaming AgentFrameworkAgent - Protocol wrapper that translates between AG-UI events and Agent Framework operations Orchestrators - Manage execution flow, coordinate tool calling sequences, and handle state transitions ChatAgent - Your agent implementation with instructions, tools, and business logic ChatClient - Interface to the underlying language model (Azure OpenAI, OpenAI, or other providers) The good news? When you call add_agent_framework_fastapi_endpoint, all the middleware layers are configured automatically. You simply provide your ChatAgent, and the integration handles protocol translation, event streaming, and state management behind the scenes. Now that we understand both the protocol architecture and the Microsoft Agent Framework integration, let's build a working application. Hands-On: Building Your First AG-UI Application This section demonstrates how to build an AG-UI server and client using Microsoft Agent Framework and FastAPI. Prerequisites Before building your first AG-UI application, ensure you have: Python 3.10 or later installed Basic understanding of async/await patterns in Python Azure CLI installed and authenticated (az login) Azure OpenAI service endpoint and deployment configured (setup guide) Cognitive Services OpenAI Contributor role for your Azure OpenAI resource You'll also need to install the AG-UI integration package: pip install agent-framework-ag-ui --pre This automatically installs agent-framework-core, fastapi, and uvicorn as dependencies. With your environment configured, let's create the server that will host your agent and expose it via the AG-UI protocol. Building the Server Let's create a FastAPI server that hosts an AI agent and exposes it via AG-UI: # server.py import os from typing import Annotated from dotenv import load_dotenv from fastapi import FastAPI from pydantic import Field from agent_framework import ChatAgent, ai_function from agent_framework.azure import AzureOpenAIChatClient from agent_framework_ag_ui import add_agent_framework_fastapi_endpoint from azure.identity import DefaultAzureCredential # Load environment variables from .env file load_dotenv() # Validate environment configuration openai_endpoint = os.getenv("AZURE_OPENAI_ENDPOINT") model_deployment = os.getenv("AZURE_OPENAI_DEPLOYMENT_NAME") if not openai_endpoint: raise RuntimeError("Missing required environment variable: AZURE_OPENAI_ENDPOINT") if not model_deployment: raise RuntimeError("Missing required environment variable: AZURE_OPENAI_DEPLOYMENT_NAME") # Define tools the agent can use @ai_function def get_order_status( order_id: Annotated[str, Field(description="The order ID to look up (e.g., ORD-001)")] ) -> dict: """Look up the status of a customer order. Returns order status, tracking number, and estimated delivery date. """ # Simulated order lookup orders = { "ORD-001": {"status": "shipped", "tracking": "1Z999AA1", "eta": "Jan 25, 2026"}, "ORD-002": {"status": "processing", "tracking": None, "eta": "Jan 23, 2026"}, "ORD-003": {"status": "delivered", "tracking": "1Z999AA3", "eta": "Delivered Jan 20"}, } return orders.get(order_id, {"status": "not_found", "message": "Order not found"}) # Initialize Azure OpenAI client chat_client = AzureOpenAIChatClient( credential=DefaultAzureCredential(), endpoint=openai_endpoint, deployment_name=model_deployment, ) # Configure the agent with custom instructions and tools agent = ChatAgent( name="CustomerSupportAgent", instructions="""You are a helpful customer support assistant. You have access to a get_order_status tool that can look up order information. IMPORTANT: When a user mentions an order ID (like ORD-001, ORD-002, etc.), you MUST call the get_order_status tool to retrieve the actual order details. Do NOT make up or guess order information. After calling get_order_status, provide the actual results to the user in a friendly format.""", chat_client=chat_client, tools=[get_order_status], ) # Initialize FastAPI application app = FastAPI( title="AG-UI Customer Support Server", description="Interactive AI agent server using AG-UI protocol with tool calling" ) # Mount the AG-UI endpoint add_agent_framework_fastapi_endpoint(app, agent, path="/chat") def main(): """Entry point for the AG-UI server.""" import uvicorn print("Starting AG-UI server on http://localhost:8000") uvicorn.run(app, host="0.0.0.0", port=8000, log_level="info") # Run the application if __name__ == "__main__": main() What's happening here: We define a tool: get_order_status with the AI_function decorator Use Annotated and Field for parameter descriptions to help the agent understand when and how to use the tool We create an Azure OpenAI chat client with credential authentication The ChatAgent is configured with domain-specific instructions and the tools parameter add_agent_framework_fastapi_endpoint automatically handles SSE streaming and tool execution The server exposes the agent at the /chat endpoint Note: This example uses Azure OpenAI, but AG-UI works with any chat model. You can also integrate with Azure AI Foundry's model catalog or use other LLM providers. Tool calling is supported by most modern LLMs including GPT-4, GPT-4o, and Claude models. To run this server: # Set your Azure OpenAI credentials export AZURE_OPENAI_ENDPOINT="https://your-resource.openai.azure.com/" export AZURE_OPENAI_DEPLOYMENT_NAME="gpt-4o" # Start the server python server.py With your server running and exposing the AG-UI endpoint, the next step is building a client that can connect and consume the event stream. Streaming Results to Clients With the server running, clients can connect and stream events as the agent processes requests. Here's a Python client that demonstrates the streaming capabilities: # client.py import asyncio import os from dotenv import load_dotenv from agent_framework import ChatAgent, FunctionCallContent, FunctionResultContent from agent_framework_ag_ui import AGUIChatClient # Load environment variables from .env file load_dotenv() async def interactive_chat(): """Interactive chat session with streaming responses.""" # Connect to the AG-UI server base_url = os.getenv("AGUI_SERVER_URL", "http://localhost:8000/chat") print(f"Connecting to: {base_url}\n") # Initialize the AG-UI client client = AGUIChatClient(endpoint=base_url) # Create a local agent representation agent = ChatAgent(chat_client=client) # Start a new conversation thread conversation_thread = agent.get_new_thread() print("Chat started! Type 'exit' or 'quit' to end the session.\n") try: while True: # Collect user input user_message = input("You: ") # Handle empty input if not user_message.strip(): print("Please enter a message.\n") continue # Check for exit commands if user_message.lower() in ["exit", "quit", "bye"]: print("\nGoodbye!") break # Stream the agent's response print("Agent: ", end="", flush=True) # Track tool calls to avoid duplicate prints seen_tools = set() async for update in agent.run_stream(user_message, thread=conversation_thread): # Display text content if update.text: print(update.text, end="", flush=True) # Display tool calls and results for content in update.contents: if isinstance(content, FunctionCallContent): # Only print each tool call once if content.call_id not in seen_tools: seen_tools.add(content.call_id) print(f"\n[Calling tool: {content.name}]", flush=True) elif isinstance(content, FunctionResultContent): # Only print each result once result_id = f"result_{content.call_id}" if result_id not in seen_tools: seen_tools.add(result_id) result_text = content.result if isinstance(content.result, str) else str(content.result) print(f"[Tool result: {result_text}]", flush=True) print("\n") # New line after response completes except KeyboardInterrupt: print("\n\nChat interrupted by user.") except ConnectionError as e: print(f"\nConnection error: {e}") print("Make sure the server is running.") except Exception as e: print(f"\nUnexpected error: {e}") def main(): """Entry point for the AG-UI client.""" asyncio.run(interactive_chat()) if __name__ == "__main__": main() Key features: The client connects to the AG-UI endpoint using AGUIChatClient with the endpoint parameter run_stream() yields updates containing text and content as they arrive Tool calls are detected using FunctionCallContent and displayed with [Calling tool: ...] Tool results are detected using FunctionResultContent and displayed with [Tool result: ...] Deduplication logic (seen_tools set) prevents printing the same tool call multiple times as it streams Thread management maintains conversation context across messages Graceful error handling for connection issues To use the client: # Optional: specify custom server URL export AGUI_SERVER_URL="http://localhost:8000/chat" # Start the interactive chat python client.py Example Session: Connecting to: http://localhost:8000/chat Chat started! Type 'exit' or 'quit' to end the session. You: What's the status of order ORD-001? Agent: [Calling tool: get_order_status] [Tool result: {"status": "shipped", "tracking": "1Z999AA1", "eta": "Jan 25, 2026"}] Your order ORD-001 has been shipped! - Tracking Number: 1Z999AA1 - Estimated Delivery Date: January 25, 2026 You can use the tracking number to monitor the delivery progress. You: Can you check ORD-002? Agent: [Calling tool: get_order_status] [Tool result: {"status": "processing", "tracking": null, "eta": "Jan 23, 2026"}] Your order ORD-002 is currently being processed. - Status: Processing - Estimated Delivery: January 23, 2026 Your order should ship soon, and you'll receive a tracking number once it's on the way. You: exit Goodbye! The client we just built handles events at a high level, abstracting away the details. But what's actually flowing through that SSE connection? Let's peek under the hood. Event Types You'll See As the server streams back responses, clients receive a series of structured events. If you were to observe the raw SSE stream (e.g., using curl), you'd see events like: curl -N http://localhost:8000/chat \ -H "Content-Type: application/json" \ -H "Accept: text/event-stream" \ -d '{"messages": [{"role": "user", "content": "What'\''s the status of order ORD-001?"}]}' Sample event stream (with tool calling): data: {"type":"RUN_STARTED","threadId":"eb4d9850-14ef-446c-af4b-23037acda9e8","runId":"chatcmpl-xyz"} data: {"type":"TEXT_MESSAGE_START","messageId":"e8648880-a9ff-4178-a17d-4a6d3ec3d39c","role":"assistant"} data: {"type":"TOOL_CALL_START","toolCallId":"call_GTWj2N3ZyYiiQIjg3fwmiQ8y","toolCallName":"get_order_status","parentMessageId":"e8648880-a9ff-4178-a17d-4a6d3ec3d39c"} data: {"type":"TOOL_CALL_ARGS","toolCallId":"call_GTWj2N3ZyYiiQIjg3fwmiQ8y","delta":"{\""} data: {"type":"TOOL_CALL_ARGS","toolCallId":"call_GTWj2N3ZyYiiQIjg3fwmiQ8y","delta":"order"} data: {"type":"TOOL_CALL_ARGS","toolCallId":"call_GTWj2N3ZyYiiQIjg3fwmiQ8y","delta":"_id"} data: {"type":"TOOL_CALL_ARGS","toolCallId":"call_GTWj2N3ZyYiiQIjg3fwmiQ8y","delta":"\":\""} data: {"type":"TOOL_CALL_ARGS","toolCallId":"call_GTWj2N3ZyYiiQIjg3fwmiQ8y","delta":"ORD"} data: {"type":"TOOL_CALL_ARGS","toolCallId":"call_GTWj2N3ZyYiiQIjg3fwmiQ8y","delta":"-"} data: {"type":"TOOL_CALL_ARGS","toolCallId":"call_GTWj2N3ZyYiiQIjg3fwmiQ8y","delta":"001"} data: {"type":"TOOL_CALL_ARGS","toolCallId":"call_GTWj2N3ZyYiiQIjg3fwmiQ8y","delta":"\"}"} data: {"type":"TOOL_CALL_END","toolCallId":"call_GTWj2N3ZyYiiQIjg3fwmiQ8y"} data: {"type":"TOOL_CALL_RESULT","messageId":"f048cb0a-a049-4a51-9403-a05e4820438a","toolCallId":"call_GTWj2N3ZyYiiQIjg3fwmiQ8y","content":"{\"status\": \"shipped\", \"tracking\": \"1Z999AA1\", \"eta\": \"Jan 25, 2026\"}","role":"tool"} data: {"type":"TEXT_MESSAGE_START","messageId":"8215fc88-8cb6-4ce4-8bdb-a8715dcd26cf","role":"assistant"} data: {"type":"TEXT_MESSAGE_CONTENT","messageId":"8215fc88-8cb6-4ce4-8bdb-a8715dcd26cf","delta":"Your"} data: {"type":"TEXT_MESSAGE_CONTENT","messageId":"8215fc88-8cb6-4ce4-8bdb-a8715dcd26cf","delta":" order"} data: {"type":"TEXT_MESSAGE_CONTENT","messageId":"8215fc88-8cb6-4ce4-8bdb-a8715dcd26cf","delta":" ORD"} data: {"type":"TEXT_MESSAGE_CONTENT","messageId":"8215fc88-8cb6-4ce4-8bdb-a8715dcd26cf","delta":"-"} data: {"type":"TEXT_MESSAGE_CONTENT","messageId":"8215fc88-8cb6-4ce4-8bdb-a8715dcd26cf","delta":"001"} data: {"type":"TEXT_MESSAGE_CONTENT","messageId":"8215fc88-8cb6-4ce4-8bdb-a8715dcd26cf","delta":" has"} data: {"type":"TEXT_MESSAGE_CONTENT","messageId":"8215fc88-8cb6-4ce4-8bdb-a8715dcd26cf","delta":" been"} data: {"type":"TEXT_MESSAGE_CONTENT","messageId":"8215fc88-8cb6-4ce4-8bdb-a8715dcd26cf","delta":" shipped"} data: {"type":"TEXT_MESSAGE_CONTENT","messageId":"8215fc88-8cb6-4ce4-8bdb-a8715dcd26cf","delta":"!"} ... (additional TEXT_MESSAGE_CONTENT events streaming the response) ... data: {"type":"TEXT_MESSAGE_END","messageId":"8215fc88-8cb6-4ce4-8bdb-a8715dcd26cf"} data: {"type":"RUN_FINISHED","threadId":"eb4d9850-14ef-446c-af4b-23037acda9e8","runId":"chatcmpl-xyz"} Understanding the flow: RUN_STARTED - Agent begins processing the request TEXT_MESSAGE_START - First message starts (will contain tool calls) TOOL_CALL_START - Agent invokes the get_order_status tool Multiple TOOL_CALL_ARGS events - Arguments stream incrementally as JSON chunks ({"order_id":"ORD-001"}) TOOL_CALL_END - Tool invocation structure complete TOOL_CALL_RESULT - Tool execution finished with result data TEXT_MESSAGE_START - Second message starts (the final response) Multiple TEXT_MESSAGE_CONTENT events - Response text streams word-by-word TEXT_MESSAGE_END - Response message complete RUN_FINISHED - Entire run completed successfully This granular event model enables rich UI experiences - showing tool execution indicators ("Searching...", "Calculating..."), displaying intermediate results, and providing complete transparency into the agent's reasoning process. Seeing the raw events helps, but truly working with AG-UI requires a shift in how you think about agent interactions. Let's explore this conceptual change. The Mental Model Shift Traditional API Thinking # Imperative: Call and wait response = agent.run("What's 2+2?") print(response) # "The answer is 4" Mental model: Function call with return value AG-UI Thinking # Reactive: Subscribe to events async for event in agent.run_stream("What's 2+2?"): match event.type: case "RUN_STARTED": show_loading() case "TEXT_MESSAGE_CONTENT": display_chunk(event.delta) case "RUN_FINISHED": hide_loading() Mental model: Observable stream of events This shift feels similar to: Moving from synchronous to async code Moving from REST to event-driven architecture Moving from polling to pub/sub This mental shift isn't just philosophical - it unlocks concrete benefits that weren't possible with request/response patterns. What You Gain Observability # You can SEE what the agent is doing TOOL_CALL_START: "get_order_status" TOOL_CALL_ARGS: {"order_id": "ORD-001"} TOOL_CALL_RESULT: {"status": "shipped", "tracking": "1Z999AA1", "eta": "Jan 25, 2026"} TEXT_MESSAGE_START: "Your order ORD-001 has been shipped..." Interruptibility # Future: Cancel long-running operations async for event in agent.run_stream(query): if user_clicked_cancel: await agent.cancel(thread_id, run_id) break Transparency # Users see the reasoning process "Looking up order ORD-001..." "Order found: Status is 'shipped'" "Retrieving tracking information..." "Your order has been shipped with tracking number 1Z999AA1..." To put these benefits in context, here's how AG-UI compares to traditional approaches across key dimensions: AG-UI vs. Traditional Approaches Aspect Traditional REST Custom Streaming AG-UI Connection Model Request/Response Varies Server-Sent Events State Management Manual Manual Protocol-managed Tool Calling Invisible Custom format Standardized events Framework Varies Framework-locked Framework-agnostic Browser Support Universal Varies Universal Implementation Simple Complex Moderate Ecosystem N/A Isolated Growing You've now seen AG-UI's design principles, implementation details, and conceptual foundations. But the most important question remains: should you actually use it? Conclusion: Is AG-UI Right for Your Project? AG-UI represents a shift toward standardized, observable agent interactions. Before adopting it, understand where the protocol stands and whether it fits your needs. Protocol Maturity The protocol is stable enough for production use but still evolving: Ready now: Core specification stable, Microsoft Agent Framework integration available, FastAPI/Python implementation mature, basic streaming and threading work reliably. Choose AG-UI If You Building new agent projects - No legacy API to maintain, want future compatibility with emerging ecosystem Need streaming observability - Multi-step workflows where users benefit from seeing each stage of execution Want framework flexibility - Same client code works with any AG-UI-compliant backend Comfortable with evolving standards - Can adapt to protocol changes as it matures Stick with Alternatives If You Have working solutions - Custom streaming working well, migration cost not justified Need guaranteed stability - Mission-critical systems where breaking changes are unacceptable Build simple agents - Single-step request/response without tool calling or streaming needs Risk-averse environment - Large existing implementations where proven approaches are required Beyond individual project decisions, it's worth considering AG-UI's role in the broader ecosystem. The Bigger Picture While this blog post focused on Microsoft Agent Framework, AG-UI's true power lies in its broader mission: creating a common language for agent-UI communication across the entire ecosystem. As more frameworks adopt it, the real value emerges: write your UI once, work with any compliant agent framework. Think of it like GraphQL for APIs or OpenAPI for REST - a standardization layer that benefits the entire ecosystem. The protocol is young, but the problem it solves is real. Whether you adopt it now or wait for broader adoption, understanding AG-UI helps you make informed architectural decisions for your agent applications. Ready to dive deeper? Here are the official resources to continue your AG-UI journey. Resources AG-UI & Microsoft Agent Framework Getting Started with AG-UI (Microsoft Learn) - Official tutorial AG-UI Integration Overview - Architecture and concepts AG-UI Protocol Specification - Official protocol documentation Backend Tool Rendering - Adding function tools Security Considerations - Production security guidance Microsoft Agent Framework Documentation - Framework overview AG-UI Dojo Examples - Live demonstrations UI Components & Integration CopilotKit for Microsoft Agent Framework - React component library Community & Support Microsoft Q&A - Community support Agent Framework GitHub - Source code and issues Related Technologies Azure AI Foundry Documentation - Azure AI platform FastAPI Documentation - Web framework Server-Sent Events (SSE) Specification - Protocol standard This blog post introduces AG-UI with Microsoft Agent Framework, focusing on fundamental concepts and building your first interactive agent application.