azure ai foundry
233 Topics
Microsoft-Decision-1 scores changed on the same deployment / version 1 – anyone else?
We use Microsoft-Decision-1 in Foundry (DataZoneStandard, model version 1, Sweden Central) as a yes/no gate with `noul` questions and a fixed probability threshold. Between Oct 23 (~15:00 UTC) and Oct 24 (~22:00 UTC) the scores changed for our calibration requests: Same deployment, same API key, no changes in the activity log. We had this running for pretty much since the announcement and probabilities for the same requests where near identical. Now: Repeated calls of the same query can vary a lot (0.915 vs 0.932 seconds apart). Re-scoring 10,000 stored requests: Results are all over the place. Most low scores barely move, but clear positives dropped (0.99 -> 0.78) and some negatives rose (0.00 -> 0.90). Pinning the deployment (versionUpgradeOption = NoAutoUpgrade) changed nothing. The model now seems to read the instructions much more literally: removing one qualifying word from our context note moved a clear positive from 0.92 to 0.996. Did anyone else see Decision-1 probabilities shift around Oct 23/24? Has Microsoft said whether updates (e.g. the announced rebase onto MAI/OpenAI base models) can happen behind "version 1"?88Views0likes2CommentsFrom Writing Scripts to Running a Newsroom: A 24-Hour News Station with Microsoft Copilot Harness
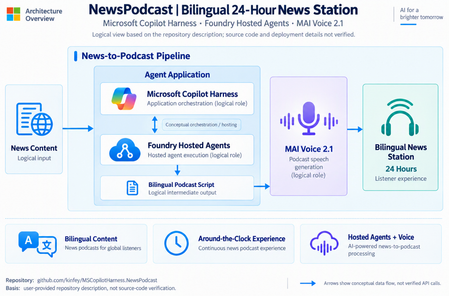
Picture an evening commute. You open a page on your phone and hear two anchors delivering a coherent news bulletin. Headlines and timestamps move across the bottom of the screen. Tap a headline and the audio jumps to that story. Tap its source and the original report opens separately. Switch to English and you hear the same underlying facts—not an unrelated second news selection. That is the idea behind Meridian 24: a half-hourly China and world news podcast, with Chinese and English audio and a single HTML, JavaScript and CSS3 page. At first, it sounds like a simple recipe: search for news, ask a model to write a script, and turn the script into speech. Once we started building, the real challenge became clear. Getting AI to speak was relatively easy. Keeping a small newsroom working responsibly was not. 1. Why Introduce Microsoft Copilot Harness? The first script needed a better process, not prettier sentences Give a model a pile of headlines and it can produce a pile of summaries. The stories may not connect. Some search results contain too little detail, inviting the model to fill space with commentary. One agency may dominate simply because its reporting is easier to retrieve. Another instruction to “sound more professional” does not solve that problem. We needed an editorial method: collect public reporting, consolidate related events, identify missing details, research those gaps, prepare evidence-backed facts, and only then write a coherent two-anchor programme. A model can be a capable editor. A newsroom still needs a workbench, a filing system, task assignments and handovers. Microsoft Copilot Harness supplies a managed execution foundation for that work. Microsoft Foundry operates the agent loop and sandbox, coordinates model and tool steps, and supports native subagents, file operations and reusable skills, among other capabilities.[1][2] Developers can spend less time constructing the newsroom's office equipment and more time teaching it how to do useful work. A 22:30 production job should not lose its progress A bulletin involves retrieval, editorial requests, speech synthesis and audio encoding. If the service stops after ten speech segments have already been synthesized, starting everything again wastes time and money. Two capabilities matter here, and they should not be confused. Microsoft Copilot Harness operates the managed editorial runtime. Long-running resilience for Hosted Agents provides a foundation for restarting interrupted work. The application still decides what progress to save, how to resume and how to prevent duplicate publication.[1] We therefore did not put the entire station into one prompt. Nor did we interpret “managed” as “nothing left to engineer.” 2. How Do We Build the Application with Microsoft Copilot Harness? A managed editor, with a separate audio production room The existing Hosted service already knew how to call WebIQ, invoke speech synthesis, run FFmpeg and write to Blob. Instead of replacing it, we kept those deterministic responsibilities there and created a separate Prompt Agent using Microsoft Copilot Harness for research and editing. Figure 1: The purple boundary contains managed editorial execution. WebIQ and audio production run in external Hosted services. Important results are stored in Blob, not entrusted to a permanently available sandbox. Microsoft Copilot Harness owns the editorial execution: researching, organizing, delegating and drafting. Hosted code owns external API execution, validation, synthesis and publication. That boundary is also a practical preview requirement. You cannot switch an existing agent to a different harness during the initial public preview. We created a new editor and retained the original Hosted Agent's type and responsibilities.[2] Here is an abbreviated excerpt from the project's definition, omitting the full instructions and custom news tools: kind: prompt name: newsradio24-editor model: gpt-6.1-sol harness: type: microsoft_copilot_preview tools: - type: microsoft_copilot_toolset_preview defaultConfig: enabled: false configs: - name: filesystem_read enabled: true - name: filesystem_write enabled: true - name: shell enabled: true - name: subagents enabled: true gpt-6.1-sol is the model deployment name used in this project, not a promise that it is available in every project. Use a supported model already deployed in your own project region. See the full newsroom.yaml, and check official documentation for current preview fields and supported tools. Subagents are backstage editors, not extra presenters The audience still hears just two anchors. Behind the scenes, the work has three logical roles: Subtask role Input Output China research China reporting and evidence IDs Consolidated events, facts and research gaps World research International reporting and agency coverage Topic order, citations and expansion needs Fact verification Expanded evidence, briefs or scripts Citation checks, conflicts and bilingual consistency issues The parent editor delegates bounded tasks and merges their results. This project allows at most three subtasks per editorial request. These are not three separately deployed, permanently running services, nor an identical fixed trio instantiated in every phase. The sandbox acts as an editor's workbench: shell and file tools help organize JSON and inspect evidence IDs and topic order. Each conversation has a separate workspace, but that workspace is not a durable archive. Important outputs belong in durable storage.[2] The station currently describes its method through version-controlled instructions and request-level procedures. It has not published those procedures as separate Foundry Skills. Reusable skills are a supported extension opportunity, not something we should claim this implementation already uses. Let tools bring evidence, not credentials The editor requests discovery and expansion through collect_news and expand_news. Both accept an empty object. The server binds the news window and context, and the WebIQ key remains in the Hosted service. When an external function call arrives, Hosted code executes the search and returns a function_call_output with the matching call_id in the same conversation. The editor can continue without receiving credentials. This excerpt shows only the editorial request entry point—not the full tool-execution loop. payload carries the phase's procedure, evidence and output contract: import json import os from azure.ai.projects.aio import AIProjectClient from azure.identity.aio import DefaultAzureCredential async def request_editor(payload): async with ( DefaultAzureCredential() as credential, AIProjectClient( endpoint=os.environ["FOUNDRY_PROJECT_ENDPOINT"], credential=credential, allow_preview=True, ) as project, project.get_openai_client( agent_name="newsradio24-editor", timeout=900, max_retries=2, ) as client, ): conversation = await client.conversations.create() return await client.responses.create( conversation=conversation.id, input=json.dumps(payload, ensure_ascii=False), ) The project uses azure-ai-projects 2.9.0. Read your own project endpoint from a server-side environment. Never put keys, real resource-group names or complete environment files into an article, browser code or sandbox. The complete adapter is in harness.py. 3. Where does it offer an advantage over a typical self-built agent harness? As a technical evangelist, I prefer describing the responsibility it removes rather than implying that nobody else can implement these capabilities. Open-source frameworks and custom systems can also support tools, delegation, state management and sandboxes. The distinction is that Microsoft Copilot Harness delegates part of that execution infrastructure to Foundry and connects it with the platform's agent definitions, identity and tool configuration. Question Typical self-built approach Microsoft Copilot Harness Who maintains the internal model/tool loop? Your team builds it or operates a framework runtime Foundry operates that runtime How are files, commands and subtasks integrated? Your team assembles execution and delegation mechanisms Use supported native capabilities How are agent definitions delivered? Establish your own configuration and release conventions Version declarative definitions alongside application code How is tool access governed? Depends on your framework and integrations Connect with Foundry roles, agent identity and connections How much runtime control is available? Greater control, with greater maintenance responsibility Less runtime operation, within supported capabilities and preview limits For a news station, that trade-off leaves more engineering time for evidence quality, editorial coherence and listening experience. It does not make reporting automatically true, remove permission configuration or support arbitrary models and tools. If you need to control the framework, dependencies, process model or specialized middleware, a Hosted Agent remains a sensible choice.[1][2] Costs do not disappear either. Inference, speech, retrieval, storage, traffic and runtime usage require a budget. Consult current regional service pricing and your agreement. The advantage is not “all engineering done for you.” It is a clearer opportunity to spend engineering effort on what makes your application different. 4. What Techniques Matter Most When Building a 24-Hour News Station? Turn reporting into facts before turning facts into sound Our production flow does not send raw search results directly to speech synthesis. It produces explicit intermediate deliverables: Figure 2: Each blue node has an inspectable data shape. Research gaps trigger an expansion loop. Editorial execution and audio production have separate validation gates. WebIQ searches public reporting from Xinhua, AP, AFP and Bloomberg. We check sources and dates. Homepages, advisories and headline-only results are discovery leads, not sufficient factual evidence. Related reports become topics. Missing details become targeted searches. If expansion still does not find enough evidence, shorten or omit the story rather than fill the silence with opinions. A section without sufficient facts should prevent publication. “Trending” also needs an honest definition: this implementation selects using relevance, recency and cross-source coverage. It does not possess a measured audience-popularity leaderboard. Agency balance must come from evidence, not relabeling Early programmes leaned toward Xinhua because more usable reporting was available. The answer was not to label those stories “AP.” We reserved candidate space for underrepresented agencies and added bounded expansion searches. Final selection keeps at most two China topics and four world topics. When at least two reliable non-Xinhua topics are selected, Xinhua is capped at half the programme. Sparse evidence may still produce an uneven mix. The page reports actual sources rather than inventing four-agency coverage. Neutrality is not achieved by asking the male and female anchors to exchange opposing opinions. They complement each other with cited facts and background, finish one story before moving on, and use transitions without manufacturing debate. Two languages should share one factual foundation If Chinese and English select stories independently, they can become different programmes. We prepare an ordered factual brief, draft the Chinese body, and adapt the English version from the same brief and Chinese content. Deterministic code adds introductions, AI-voice disclosure, greetings and polite sign-offs rather than hoping the model remembers every time. The Chinese anchors use MAI Voice 2.1's Wei and Mei; English uses Grant and Harper. The station has no sports section or third anchor.[3] “The voice is too slow” turned out to be a timing problem too Wei's Chinese delivery needed more pace. Instead of accelerating the entire programme in the browser, we applied pitch-preserving 1.25x tempo to Wei's synthesized tracks on the server. Mei and both English anchors remain at 1.0x. That decision requires measuring the processed tracks again before calculating story starts, assembling audio and encoding it. Otherwise, a “jump to story two” button may land in the wrong sentence. WAVs are working files. The final MP4 contains real AAC audio; it is not an MP3 with a different extension. The complete bulletin and every section must remain within 1,200 seconds, measured from actual audio. Oversized output is rejected, not cut in the middle of a sentence. Inspect the handover sheet, not the AI's claim of completion The station stores records for collection, topic organization, expansion, final briefs, Chinese scripts and English scripts. All four editorial phases must actually execute native subtasks and shell operations. A response saying “I checked it” is not sufficient. Here is an abbreviated illustration of two gates. Production checks runtime records per phase and duration after audio production: observed = harness.native_tools(response_outputs) if not {"task", "shell"} <= observed: raise RuntimeError("Missing native editorial execution") audio.check_duration(chapters, total_seconds) Native subtasks and shell operations run through the platform. They must not be mistaken for unresolved external functions that Hosted code still needs to execute. The implementation uses actual response events and call_id pairing, not the model's self-assessment. In one completed end-to-end run, Chinese audio measured 268.1 seconds and English 271.0 seconds. Verification covered all six phase records and story starts derived from actual WAVs. Those are results for one particular edition—not guarantees of future latency, quality or availability. Passing these gates establishes structural, citation and execution conditions. It is not proof of truth or semantic neutrality. Human editorial review still matters. Put recovery into the data and publication into a handover Completed evidence, scripts, WAVs and status live in private Blob storage. A resumed task reads checkpoints and reuses synthesized tracks rather than repeating every completed action. Only after Chinese and English are complete does a publication lease protect the catalogue update. One write reveals both outputs. Scheduled editions and manual extras have separate catalogues, so a manual success cannot be passed off as proof of a successful scheduled run. We also encountered a very practical deployment hurdle: the Hosted service's instance identity lacked project permission to create managed editorial conversations. Assigning Foundry User at the project scope to the correct calling identity, then allowing propagation, resolved it. Your user account having permission does not imply that the running agent has it.[2] Midnight is a real handover, not another replay “Keep one day” requires a shared definition of the day. We use the current Asia/Shanghai calendar date—not a rolling 24 hours, and not each visitor's local day for deleting shared Blob content. A separate task runs at Beijing midnight to prune expired catalogues, public/private audio, evidence, scripts, WAVs and runtime records, including snapshots and stored versions. Each production also sweeps to catch missed cleanup. Dated writes and cleanup share the publication lease, so an old job cannot recreate yesterday's files after deletion. The browser stops expired audio at rollover even if catalogue refresh fails. If today's first programme is not ready, it waits. Repeating the latest completed programme is allowed only within the current station day. Cleanup does not silently disable account-wide Azure soft-delete protection. If enabled, recoverable copies remain subject to that policy. Previously downloaded files cannot be recalled. The final details live on a phone screen The frontend needs no elaborate framework: a lightweight single page can offer a persistent player, headline ticker, source links, language switching and current-day listening on demand. A headline seeks the audio; a source link opens the report. Keeping those actions separate avoids an ambiguous click. Display all times in the listener's browser timezone while retaining Beijing time for paths and cleanup. Refresh catalogues every 45 seconds. Expect browser autoplay restrictions to require an initial tap. A desktop demonstration is not enough: exercise mobile playback, scrolling, seeking and timezone conversion. Closing Thought: A Useful Agent Is More than a Beautiful Answer The takeaway is not simply that AI can generate a podcast. It is that we gave the station understandable responsibilities, durable data and inspectable handovers. Microsoft Copilot Harness gives the managed editor tools, a workbench and delegation. Application code protects evidence, permissions, duration, publication and lifecycle boundaries. That is the agent story I want to tell as a technical evangelist: bring intelligence into a real workflow, rather than hide the workflow inside a prompt. Explore the current programme and interactive data-node diagram on the Meridian 24 page. The page retains only the current station day's content; it is not a permanent episode archive. Source Code Repo - https://github.com/kinfey/MSCopilotHarness.NewsPodcast References Microsoft announcement: Microsoft Copilot Harness and Hosted Agent long-running resilience Microsoft Learn: Microsoft Copilot Harness, including identity, workspaces and preview limitations Microsoft Learn: MAI Voice 2.1 and MAI Voice 2.1 Flash Project implementation and documentation Source Code Repo279Views0likes0CommentsIs Microsoft Foundry the Future of Enterprise AI?
After reviewing several recent Microsoft Foundry presentations, one theme stood out: The future of AI isn't about having the best model. It's about connecting models to business context, systems, governance, and observability. The slides consistently highlight the challenges organizations face: Choosing and managing models Connecting AI to enterprise knowledge Integrating with business systems Governing agents at scale Microsoft's answer appears to be Foundry, an AI app and agent factory that brings together models, knowledge, tools, orchestration, security, and lifecycle management into a single platform. What I found most interesting is the emphasis on Foundry IQ and business context. The message seems to be that AI becomes truly valuable when it understands not just language, but how your organization operates. As AI evolves from chatbots → copilots → agents, governance and context may become more important than raw model intelligence.291Views0likes2Comments
Making Azure AI Foundry Agents Explainable — Knowledge Graphs + Source Attribution
90% of Azure AI demos work on stage — most never ship. The gap is architecture, not the model. I wrote up a field guide on taking Azure AI Foundry agents from POC to production, with knowledge graphs (GraphRAG) doing the grounding and source attribution. What the post covers Grounding with a knowledge graph — multi-hop retrieval + inline citations so every answer is traceable to a source (critical for regulated/medical use cases). Externalized state — keeping agent memory and session state outside the model. Identity at the boundary — Entra ID / RBAC instead of trusting the prompt. Observability & compliance — tracing, evaluation, and auditability. The stack — Azure AI Foundry + Model Context Protocol (MCP) + Azure Functions (Flex Consumption) + Azure OpenAI, from a real build (VeritasGraph medical MCP server). 📖 Full write-up: https://bibinprathap.com/blog/azure-ai-proof-of-concept-to-production ▶️ 6-min walkthrough: https://youtu.be/z-CPS5WUvyw?si=fmpo1RN28Bh9KbIb Questions for the community How are you grounding Foundry agents today — vector RAG, GraphRAG, or hybrid? Anyone combining knowledge graphs with MCP tools in Foundry? What worked / broke? For regulated domains, how are you handling source attribution and audit trails? Curious to compare notes — happy to share more detail on the GraphRAG retrieval design if useful.407Views0likes0Comments
Azure AI Foundry Agent Unable to Use Credentials Stored in Key Vault Through Playwright MCP Tool
Hello everyone, I am trying to understand how Azure AI Foundry agents interact with Azure Key Vault when using custom MCP tools, and I would appreciate any guidance from the community. My Setup - Created an Azure AI Foundry agent. - Created an Azure Key Vault and configured all permissions according to Microsoft's official documentation. - Stored the required website credentials (username and password) in the Key Vault. - Deployed the official Playwright MCP Docker image. - Exposed the MCP server using ngrok and verified that the endpoint is accessible. - Connected the MCP endpoint as a Custom MCP Tool in Azure AI Foundry. - Performed all configuration through the Azure portal, Foundry UI, and Playground only (no SDK or custom application code involved). The Issue The agent can access and use the Playwright MCP tool. However, when I ask it to log in to a website using credentials that are already stored in Key Vault, it does not populate the username and password fields. My expectation was that the agent would be able to retrieve the secrets from Key Vault and provide them to the Playwright tool during execution. Questions Is there currently a supported mechanism for Azure AI Foundry agents to automatically retrieve Key Vault secrets and pass them to a Custom MCP tool? Does the Playwright MCP Docker image have any built-in integration with Azure Key Vault? When using only the Foundry UI (without SDK code), can a Foundry agent securely inject Key Vault secrets into MCP tool calls? Are additional configurations required beyond Key Vault permissions and agent connections? Has anyone successfully implemented a similar setup where a Foundry agent uses credentials stored in Key Vault to perform browser automation through Playwright MCP? Any clarification on the expected architecture and whether this scenario is currently supported in Azure AI Foundry would be greatly appreciated. Thank you.790Views0likes3CommentsLearn how to use the four IQs: Web IQ, Work IQ, Fabric IQ, Foundry IQ
We just concluded Microsoft IQ Deep Dive with Python, a three-part livestream series all about Microsoft IQ. We showed how to use the four IQs to ground your AI applications and agents: Work IQ: user-specific retrieval of M365 data, like Teams chats, emails, and calendar events. Fabric IQ: retrieval of data stored in OneLake, via Fabric ontologies, graphs, and data agents. Web IQ: real-time web results with super low latency Foundry IQ: multi-source agentic retrieval on search indexes plus remote sources (including Web IQ, Work IQ, and Fabric IQ) The four IQs are all exposed as MCP endpoints, so you can easily integrate into your own agents, or add to your Foundry agents via the Foundry Toolbox. Check out our code samples for Python notebooks and agents that use each of the MCP servers and APIs. All of the materials from our series are available for you to keep learning from, and linked below: Video recordings of each stream PowerPoint slides that you can use for reviewing or even teaching the material to your own community An annotated write-up of each presentation, so you can quickly read through 🙋🏽♂️ Have follow up questions? Join the weekly Python+AI office hours on Foundry Discord. Microsoft IQ Deep Dive with Python: Foundry IQ 📺 Watch YouTube recording In the first session, we dived into Foundry IQ (Azure AI Search), exploring how it helps agents and applications work with curated knowledge and organizational context. We built knowledge bases in Python and connected them to multiple knowledge sources, including file knowledge sources, search indexes built from ingested data, and the Web IQ MCP server. Then we performed multi-source agentic retrieval on those knowledge bases, which executes queries in parallel and merges the results with state-of-the-art ranking models. Finally, we built agents in Python using Microsoft Agent Framework and grounded their responses in Foundry IQ results three different ways: a custom tool calling the knowledge base API, the knowledge base MCP endpoint, and a Foundry Toolbox. We deployed those agents to Foundry Agent Service as hosted agents and published one to Teams. 🖼️ Slides for this session 📝 Write-up for this session 💻 Code repository with examples: iqdeepdive Microsoft IQ Deep Dive with Python: Work IQ 📺 Watch YouTube recording In the second session, we focused on Work IQ and how it brings workplace context into AI-powered experiences. We compared Work IQ to Microsoft Graph, then explored all three protocols it speaks — A2A, MCP, and REST — with runnable Python notebooks for each. We walked through the 10 generic tools that Work IQ exposes over MCP, including ask, which calls Microsoft 365 Copilot directly, and do_action, the only write path. We also connected Work IQ to a Foundry IQ knowledge base as a knowledge source, so a single query returns a blended answer across indexed HR documents and live work context. Then we wired Work IQ into a Microsoft Agent Framework agent as an MCP tool, and finished with Agent 365 autopilots — agents that get their own Microsoft 365 identity, mailbox, and place in the org chart, and act as themselves rather than on behalf of you. A live demo showed the Work Mate autopilot reading its own mailbox in Teams and emailing a customer directly. 🖼️ Slides for this session 📝 Write-up for this session 💻 Code repository with examples: iqdeepdive Microsoft IQ Deep Dive with Python: Fabric IQ 📺 Watch YouTube recording In the final session, we explored Fabric IQ and how it connects AI experiences to structured business data stored in Microsoft Fabric's OneLake. We introduced the key components of Fabric IQ — ontologies, graphs, semantic models, and data agents — and showed how each one helps describe, organize, and reason over operational data. Ontologies provide a shared business vocabulary that maps entity types, properties, and relationships to actual OneLake data. Graphs offer dedicated graph database capabilities for queries requiring extensive relationship traversal. Semantic models expose Power BI analytics through DAX measures on star-schema tables. Data agents combine all of these behind a single conversational interface that selects the right source and query language automatically. For each component, we demonstrated the Ontology MCP server and Data Agent MCP server for agent integration, and showed how to add each as a knowledge source to Foundry IQ knowledge bases for multi-source retrieval. 🖼️ Slides for this session 📝 Write-up for this session 💻 Code repository with examples: iqdeepdive2.3KViews2likes0Comments
Data Visualisation / Charting in Azure Foundry
Hi Foundry community, We are working on an agent that can query internal data sources, and are looking for ways that we can visualise data (think pie charts, bar charts, etc.). This would be consumed by end users through Copilot/Teams. However we are unable to find a way to do so, which is surprising given that you easily can create charts through M365 Copilot Chat and through Copilot Studio. We have tried using the 'Code Interpreter' tool, but the Teams/Copilot client UIs just do not render the results inline, either interactive or as an embedded image. They also do not give any option to download them. Has anyone tackled this before? How have you been able generate charts? Many thanks!575Views0likes2CommentsStaying in the flow: SleekFlow and Azure turn customer conversations into conversions
A customer adds three items to their cart but never checks out. Another asks about shipping, gets stuck waiting eight minutes, only to drop the call. A lead responds to an offer but is never followed up with in time. Each of these moments represents lost revenue, and they happen to businesses every day. SleekFlow was founded in 2019 to help companies turn those almost-lost-customer moments into connection, retention, and growth. Today we serve more than 2,000 mid-market and enterprise organizations across industries including retail and e-commerce, financial services, healthcare, travel and hospitality, telecommunications, real estate, and professional services. In total, those customers rely on SleekFlow to orchestrate more than 600,000 daily customer interactions across WhatsApp, Instagram, web chat, email, and more. Our name reflects what makes us different. Sleek is about unified, polished experiences—consolidating conversations into one intelligent, enterprise-ready platform. Flow is about orchestration—AI and human agents working together to move each conversation forward, from first inquiry to purchase to renewal. The drive for enterprise-ready agentic AI Enterprises today expect always-on, intelligent conversations—but delivering that at scale proved daunting. When we set out to build AgentFlow, our agentic AI platform, we quickly ran into familiar roadblocks: downtime that disrupted peak-hour interactions, vector search delays that hurt accuracy, and costs that ballooned under multi-tenant workloads. Development slowed from limited compatibility with other technologies, while customer onboarding stalled without clear compliance assurances. To move past these barriers, we needed a foundation that could deliver the performance, trust, and global scale enterprises demand. The platform behind the flow: How Azure powers AgentFlow We chose Azure because building AgentFlow required more than raw compute power. Chatbots built on a single-agent model often stall out. They struggle to retrieve the right context, they miss critical handoffs, and they return answers too slowly to keep a customer engaged. To fix that, we needed an ecosystem capable of supporting a team of specialized AI agents working together at enterprise scale. Azure Cosmos DB provides the backbone for memory and context, managing short-term interactions, long-term histories, and vector embeddings in containers that respond in 15–20 milliseconds. Powered by Azure AI Foundry, our agents use Azure OpenAI models within Azure AI Foundry to understand and generate responses natively in multiple languages. Whether in English, Chinese, or Portuguese, the responses feel natural and aligned with the brand. Semantic Kernel acts as the conductor, orchestrating multiple agents, each of which retrieves the necessary knowledge and context, including chat histories, transactional data, and vector embeddings, directly from Azure Cosmos DB. For example, one agent could be retrieving pricing data, another summarizing it, and a third preparing it for a human handoff. The result is not just responsiveness but accuracy. A telecom provider can resolve a billing question while surfacing an upsell opportunity in the same dialogue. A financial advisor can walk into a call with a complete dossier prepared in seconds rather than hours. A retailer can save a purchase by offering an in-stock substitute before the shopper abandons the cart. Each of these conversations is different, yet the foundation is consistent on AgentFlow. Fast, fluent, and focused: Azure keeps conversations moving Speed is the heartbeat of a good conversation. A delayed answer feels like a dropped call, and an irrelevant one breaks trust. For AgentFlow to keep customers engaged, every operation behind the scenes has to happen in milliseconds. A single interaction can involve dozens of steps. One agent pulls product information from embeddings, another checks it against structured policy data, and a third generates a concise, brand-aligned response. If any of these steps lag, the dialogue falters. On Azure, they don’t. Azure Cosmos DB manages conversational memory and agent state across dedicated containers for short-term exchanges, long-term history, and vector search. Sharded DiskANN indexing powers semantic lookups that resolve in the 15–20 millisecond range—fast enough that the customer never feels a pause. Microsoft Phi’s model Phi-4 as well as Azure OpenAI in Foundry Models like o3-mini and o4-mini, provide the reasoning, and Azure Container Apps scale elastically, so performance holds steady during event-driven bursts, such as campaign broadcasts that can push the platform from a few to thousands of conversations per minute, and during daily peak-hour surges. To support that level of responsiveness, we run Azure Container Apps on the Pay-As-You-Go consumption plan, using KEDA-based autoscaling to expand from five idle containers to more than 160 within seconds. Meanwhile, Microsoft Orleans coordinates lightweight in-memory clustering to keep conversations sleek and flowing. The results are tangible. Retrieval-augmented generation recall improved from 50 to 70 percent. Execution speed is about 50 percent faster. For SleekFlow’s customers, that means carts are recovered before they’re abandoned, leads are qualified in real time, and support inquiries move forward instead of stalling out. With Azure handling the complexity under the hood, conversations flow naturally on the surface—and that’s what keeps customers engaged. Secure enough for enterprises, human enough for customers AgentFlow was built with security-by-design as a first principle, giving businesses confidence that every interaction is private, compliant, and reliable. On Azure, every AI agent operates inside guardrails enterprises can depend on. Azure Cosmos DB enforces strict per-tenant isolation through logical partitioning, encryption, and role-based access control, ensuring chat histories, knowledge bases, and embeddings remain auditable and contained. Models deployed through Azure AI Foundry, including Azure OpenAI and Microsoft Phi, process data entirely within SleekFlow’s Azure environment and guarantees it is never used to train public models, with activity logged for transparency. And Azure’s certifications—including ISO 27001, SOC 2, and GDPR—are backed by continuous monitoring and regional data residency options, proving compliance at a global scale. But trust is more than a checklist of certifications. AgentFlow brings human-like fluency and empathy to every interaction, powered by Azure OpenAI running with high token-per-second throughput so responses feel natural in real time. Quality control isn’t left to chance. Human override workflows are orchestrated through Azure Container Apps and Azure App Service, ensuring AI agents can carry conversations confidently until they’re ready for human agents. Enterprises gain the confidence to let AI handle revenue-critical moments, knowing Azure provides the foundation and SleekFlow provides the human-centered design. Shaping the next era of conversational AI on Azure The benefits of Azure show up not only in customer conversations but also in the way our own teams work. Faster processing speeds and high token-per-second throughput reduce latency, so we spend less time debugging and more time building. Stable infrastructure minimizes downtime and troubleshooting, lowering operational costs. That same reliability and scalability have transformed the way we engineer AgentFlow. AgentFlow started as part of our monolithic system. Shipping new features used to take about a month of development and another week of heavy testing to make sure everything held together. After moving AgentFlow to a microservices architecture on Azure Container Apps, we can now deploy updates almost daily with no down time or customer impact. And this is all thanks to native support for rolling updates and blue-green deployments. This agility is what excites us most about what's ahead. With Azure as our foundation, SleekFlow is not simply keeping pace with the evolution of conversational AI—we are shaping what comes next. Every interaction we refine, every second we save, and every workflow we streamline brings us closer to our mission: keeping conversations sleek, flowing, and valuable for enterprises everywhere.917Views3likes0Comments
o3-deep-research is failed with the status incomplete with the reason as content filter
I working on an to do an deep research on internal data. I'm using currently the Azure OpenAI Responses API with MCP Tool. The underlying MCP server deployed into ACA with search and fetch tool with signatures in complaint with the specification (https://developers.openai.com/apps-sdk/build/mcp-server#company-knowledge-compatibility). OpenAI client created with 03-deep-research model with MCP tool, in a loop response status being checked. (https://learn.microsoft.com/en-us/azure/foundry/openai/how-to/deep-research#remote-mcp-server-with-deep-research) Deep Research is being carried out for sometime, I could see in the log that handshake has been made, ListTools invoked, search tool is called post that fetch is called for the queries framed by the model.. But intermittently, the response status is becoming "incomplete" with incomplete reason as "content_filter". Otherwise the deep research is working fine. Not able identify the root cause as there is seems to be no way to identify what caused the content filtration whether its the prompt or completion. How to debug and check the root cause and rectify this ? Or is there known issue with the o3-deep-research model's intermediate reasoning completions Or search and fetch tool results are causing this ? I had uploaded a file made it available to MCP server, the search and fetch tool uses an Azure OpenAI agent to search the data using File Search and fetch tool gets the content of the file based on the id passed. For same file and same research topic the issue is not occurring always but intermittently.548Views0likes1Comment