azure ai
313 TopicsWhen the Answer Isn’t in the Document: Metadata-Aware Agentic RAG with Foundry IQ
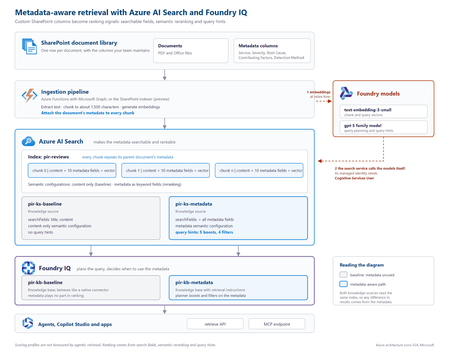
The problem SharePoint libraries often contain years of carefully curated metadata, including root cause, severity, business unit, document type, owner and classification. If that metadata never reaches the retrieval pipeline, however, a RAG system cannot use it. This creates a common blind spot: the information that explains what a document is about may exist in its metadata rather than its text. Consider an incident review containing this statement: “Investigation found that a DNS record was repointed during a migration while the old target was still serving writes.” The associated Root Cause Category is Configuration change, but those words do not appear in the document. Another review might mention that a configuration change was suspected and ruled out. Text-only retrieval can therefore favour the wrong document. In the sample dataset used for this project, none of the 19 reviews classified as configuration-change incidents contained the word “configuration”, while six reviews with other root causes did. Metadata does not improve every search. It helps when the information that determines what a document is lives outside the document text. Why tuning alone cannot fix it With a native SharePoint knowledge source, document text is extracted, chunked and embedded, while standard properties are retained. Custom SharePoint columns are not part of that ingestion path. Fields such as Root Cause Category, Contributing Factors, Detection Method and Severity therefore never become structured fields available to retrieval. If the metadata is absent from the index, search tuning cannot make it count. Flattening all metadata into a single text string is also problematic: Notification Service | Sev2 | Configuration change | Missing runbook This preserves the words but loses their meaning. A root cause, severity and contributing factor represent different concepts and should remain separate fields. Bring a custom Azure AI Search index The approach is to create and control a custom Azure AI Search index, then expose it to Foundry IQ as a searchIndex knowledge source. This combines metadata control with agentic query planning and a governed retrieval surface. Approach Metadata control Agentic planning Native SharePoint knowledge source No Yes Custom index queried directly Yes No Custom index as a knowledge source Yes Yes Architecture The key design principle is simple: every chunk carries its parent document's metadata. Figure 1. Metadata-aware retrieval architecture with Azure AI Search and Foundry IQ. The ingestion pipeline extracts a document, creates chunks, attaches document-level metadata to every chunk, generates embeddings and writes the records to Azure AI Search. Foundry IQ then uses the index as a knowledge source. Azure AI Search holds the metadata. Foundry IQ decides when to use it. Figure 2. Detailed implementation view, including the baseline and metadata-aware retrieval paths. At query time, the search service calls the configured models for vectorisation and query planning. Where key authentication is disabled, the search service's managed identity needs the required access. In the tested implementation, the Cognitive Services User role resolved HTTP 401 responses from retrieve requests. Put metadata on every chunk A chunk can only be retrieved and ranked using information available on that chunk. Each metadata property should therefore remain in its own field: { "id": "doc1035-000", "parentId": "doc1035", "title": "Notification Service: failed sign-ins", "content": "<extracted review text>", "rootCauseCategory": "Configuration change", "contributingFactors": "Missing runbook; Change outside window", "detectionMethod": "Customer report", "severity": "Sev2" } A separate metadata index does not solve the same problem because a match against metadata in one index cannot raise the ranking of a content chunk in another. What influences retrieval Four areas matter in this design: Search fields: searchFields determine which fields generated subqueries search. Semantic configuration: prioritised fields give the semantic reranker access to important metadata. Query hints: hints help the planner connect natural-language requests to known metadata values. Filters: a baseFilter or request-level filterAddOn can enforce constraints. Boost hints influence ranking without excluding documents. Filter hints can narrow the result set when the planner determines that a filter is appropriate. "queryHints": { "boosts": [{ "kind": "fieldValue", "field": "rootCauseCategory", "fieldValues": ["Configuration change", "Capacity", "Software defect", "Dependency failure", "Certificate expiry"], "boost": 3.0, "boostInstructions": "Boost when the user describes what caused an incident." }] } Hints are best effort. Hard requirements should use a base filter or document-level access control rather than relying on the planner to select a hint. The tested configuration used the 2026-08-01-preview API. Current documentation should be checked for supported models, limits and behaviour before implementation. Measuring the impact Two knowledge bases were created over the same Azure AI Search index. The baseline searched title and content. The metadata-aware configuration used the same content plus structured metadata, semantic configuration and query hints. Ten questions were run through both configurations. Correctness was determined directly from the metadata attached to returned reviews, rather than by asking an LLM whether a result appeared relevant. For the question “What can be learned from outages caused by configuration changes?”, the planner generated: rootCauseCategory eq 'Configuration change' Matching reports in top 5 Score Baseline 0 Metadata-aware 3 Best possible 5 Across ten questions and four runs using gpt-5.4-mini for query planning, the baseline returned 26 matching reviews in the top five. The metadata-aware configuration returned 39 to 41, against a best possible score of 50. The gains appeared where metadata carried the missing meaning: Configuration changes: 0 → 3 Configuration changes reported by customers: 0 → 3 Capacity in production: 1 → 5 Alert fatigue: 3 → 5 Queries whose important terms already appeared in the document text scored 5/5 in both configurations. The result is therefore more specific than “metadata improves search”: metadata closes a retrieval gap when document text does not fully describe what the document represents. A failure mode worth handling Because query planning uses an LLM, the planner can occasionally generate a filter that the search index rejects. Two invalid examples observed during testing were: severity eq Sev1 changeRelated eq true The first omitted quotes around a string. The second treated an Edm.String field containing Yes and No as a Boolean. The latter caused the retrieve request to fail with HTTP 502. The fix was to make the schema and allowed values explicit: This is a text field, not a Boolean. The only valid values are 'Yes' and 'No'. Never compare the field with true or false. Application code should also handle retrieval failures rather than assuming every generated filter will be valid. Production considerations A custom index provides control, but the solution now owns ingestion. Options include the SharePoint indexer with custom columns, an Azure Function using Microsoft Graph, or an existing pipeline built with Logic Apps, Azure Data Factory or Microsoft Fabric. A custom Azure AI Search index does not automatically inherit the SharePoint permissions model. Where users have different document permissions, ACLs must be carried into ingestion and retrieval. Query hints should also be regenerated when taxonomy values change. Key takeaways Confirm that the required metadata reaches the index. Keep metadata structured rather than flattening it into one text field. Attach parent-document metadata to every chunk. Use search fields, semantic configuration, query hints and filters deliberately. Describe field types and valid values clearly in filter instructions. Evaluate against a baseline using objective correctness rules. Metadata-aware retrieval is not about making every search better. It gives the retrieval system access to context that does not exist in the document text. Try the proof of concept The complete proof of concept, synthetic dataset, index scripts, knowledge-base configurations and A/B evaluation harness are available in the GitHub - shikha-msft/foundryiq-metadata-agentic-rag. References Create a search index knowledge source Create a knowledge base Query a knowledge base via API or MCP What is Foundry IQ?93Views0likes0CommentsClosing the AI Agent Governance Gap with Microsoft Foundry
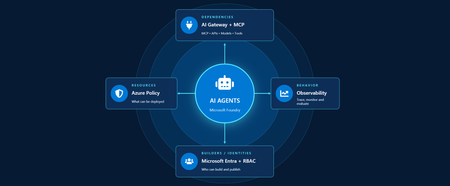
Developers are shipping agents faster than security teams can catalog them. As organizations move beyond pilots and begin operating dozens or hundreds of agents, one question keeps coming up: how do we actually get visibility into our AI agents across our environment? In this article, we'll walk through how Azure services can help establish visibility, guardrails, and cost accountability across your AI estate. Governance for AI happens across four layers: Resources – who can create new AI resources Builders – who can develop and publish agents in a certain scope Behavior – how agent outputs are evaluated, monitored, and governed Dependencies – what models, tools, APIs, and MCP servers agents can interact with Most organizations already have governance controls for identities, networking, and compliance. The challenge isn't creating new controls. It's connecting existing controls into an operating model that works for AI agents. Below we walk through each area and go a bit deeper on how to close the gap. Setting up boundaries with Azure Policy First, let's start in the Azure portal with Azure Policy. Azure Policy lets you set guardrails on what can be deployed in your environment and flags or blocks anything that doesn't comply. For AI workloads, the built-in definitions range from limiting models that people in your organization can deploy to locking down the network through enabling private endpoints. Some policies you get started with: Foundry model deployments should only use approved models: Restricts deployments to models or publishers your organization has explicitly approved Foundry model deployments should meet eligibility requirements (preview): Applies rules based on model attributes like preview vs. GA status and distribution source Azure AI Services resources should have key access disabled: Makes Microsoft Entra ID the only entry point The full list of policies related to Azure AI Services are available here: List of built-in policy definitions - Azure Policy | Microsoft Learn Why this comes first: Policy checks resources before they are created, so it proactively keeps your environment aligned with your standards. Implementing role-based access control (RBAC) Once these boundaries are in place, the next step is RBAC. Setting RBAC up early ensures that people and identities building agents have the right scope for what they actually need to do. Foundry roles only apply when you authenticate using Microsoft Entra ID. If you're using key-based authentication instead, the key grants full access with without role restrictions. API keys are convenient for quick development usage but when moving towards production, Microsoft Entra ID is the preferred method. Roles can be assigned at three scopes: the Foundry resource, a Foundry project, or an individual agent itself. Below is an example of how different personas within organization can map to a certain scope for creating and building agents with Foundry. Here's how each role in the diagram compares, from least to most privileged: Role Privilege Level What it does in Microsoft Foundry Foundry Agent Consumer Least Interact with agent endpoints in a project. This is your least-privilege role for people who only need to use agents. Foundry User Low Grants reader access to the Foundry project, the Foundry resource, and data actions for your Foundry project. Least-privilege access role for developers building and testing agents. Foundry Project Manager Medium This role lets you perform management actions on Foundry projects, build and develop with projects, and conditionally assign the Foundry User role to other user principals. Foundry Account Owner Higher Grants full access to manage Foundry projects and resources, and lets you assign the Foundry User role to other user principals. Foundry Owner Highest Grants full access to manage Foundry projects and resources to build and develop with projects. This role can also assign the Foundry User, ACR, and monitoring roles to users in the environment. Source: Role-based access control for Microsoft Foundry - Microsoft Foundry | Microsoft Learn For the agent resources themselves, assign managed identities rather than API keys since it lowers the risk of having compromised credentials. Note if you're scripting RBAC permissions: these roles were recently renamed from Azure AI User, Azure AI Owner, Azure AI Account Owner, and Azure AI Project Manager. The role IDs and permissions didn't change, so use the role definition GUID in your code to avoid issues while the rename rolls out. Observability in Microsoft Foundry Governance requires more than access control. Organizations also need evidence of how agents are being used. Observability provides the audit trail needed to investigate incidents, understand usage patterns, and track costs. The Foundry Control Plane brings these observability and governance tools together in one place, alongside services like Azure Monitor, Microsoft Entra, Microsoft Purview, and Azure Policy. In the Foundry portal, tracing is a good starting point. Once you connect an Application Insights resource to your project, Foundry turns on tracing automatically so every run, including the ones you test in the playground, is logged. After it is completed, you can search by Response ID or Trace ID to see the conversation history, token usage, run steps, tool calls, and inputs and outputs between the user and the agent. For more granular queries, you can write KQL to dive into individual agent runs or use the prebuilt Grafana dashboards in Azure Monitor. With client-side tracing, you can also export traces to observability tools you may already use, such as Datadog or Jaeger. Note: Permissions required for viewing this telemetry requires the Log Analytics Reader role on the connected Application Insights resource, and Privileged Monitoring Data Reader on top of that if the underlying Log Analytics tables are protected. Alongside all of these monitoring features, every agent comes with content safety guardrails and evaluations let you test and optimize performance before and after you publish your agents. When agents get published to Microsoft Teams and Microsoft 365 Copilot, Microsoft 365 admins can approve usage requests. These requests can be further scoped to a limited group for pilot testing/department usage or the full organization. Adding an AI gateway Observability tells you what your agents are doing, but how do you actually control them? This is where Azure API Management comes in. Once you have more than one agent, model deployment, or multiple teams consuming them, you need a single enforcement point between the agents and the resources they call. Adding Azure API Management in front of Microsoft Foundry gives you: Rate limiting and load balancing across regions and model deployments Consistent authentication and quota policies for model and tool traffic Usage tracking per team or cost center so you can accurately charge back to different departments Governed access to your custom and remote MCP servers Note: When choosing MCP servers, start with trusted, enterprise supported sources (GitHub, Microsoft, internally developed servers, etc.) that have documented security controls, enterprise authentication, clear ownership, and least-privilege permissions. Treat community MCP servers as untrusted until they have undergone a formal security review and are verified by organizations. Adding an AI gateway completes the governance picture. Azure Policy governs what can be deployed. RBAC governs who can build and manage agents. Observability provides evidence of how agents behave in production. The AI gateway extends governance into runtime, controlling how agents interact with models, tools, and external systems. Combined, these layers help organizations move beyond simply building agents to operating them responsibly at scale. Extend governance across the wider estate A few directions to take this further: MCP registry in Azure API Center – As MCP usage grows, you can create an approved inventory of MCP servers and APIs that can be used across an organization. Microsoft Agent 365 – Microsoft's enterprise control plane for AI agents. It gives every agent its own Microsoft Entra Agent ID and published Foundry agents sync to its registry automatically. This gives your IT team one place to run access reviews, lifecycle policies, and owner attestation across every agent in the tenant, including shadow agents discovered outside Foundry. Copilot Studio – when you add an MCP tool, you can point it at the API Management URL instead of the direct remote endpoint to gain additional observability through the gateway. GitHub Copilot – you can apply the same AI gateway-fronted MCP registry, applied to the developer side. Microsoft Purview – data classification, DLP, audit, and AI interaction governance across the wider estate. Where to go next Looking for a quick start? Turn on the three Azure Policy definitions above in audit mode against a non-production subscription and see what gets flagged that is out of compliance. Ready to design the end-to-end pattern? Take a look at this Cloud Adoption Framework guidance on AI governance and governing Azure platform services for AI. Want to go deeper on agent observability? Start with these articles around Application Insights integrations with Foundry: Use Insights in Microsoft Foundry and Monitor AI Agents with Application Insights Governing AI agents doesn't require starting from scratch. The identity, policy, monitoring, and cost controls you already use for the rest of your Azure estate can extend to AI workloads. Start with one layer, connect the next, and build a governance foundation that grows with your AI adoption.260Views2likes0CommentsResource Guide: Making Physical AI Practical for Real‑World Industrial Operations
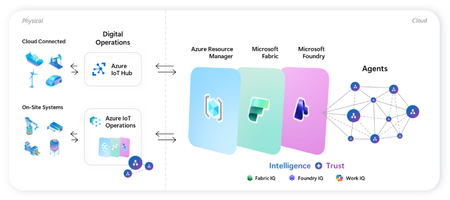
Microsoft's adaptive cloud approach brings cloud, edge, data, and AI together to help organizations turn operational technology (OT) data into intelligent action, without requiring everything to live in the cloud. At the center of this approach are key technologies that connect physical operations to cloud-scale data, analytics, and AI: Key Purpose Offering Direct-to-cloud device management + telemetry ingestion Azure IoT Hub Industrial connectivity + edge data plane Azure IoT Operations Unified analytics + real-time intelligence Microsoft Fabric On-device AI inferencing runtime Microsoft Foundry Industry recognition Microsoft named a Leader in the 2026 Gartner® Magic Quadrant™ for Global Industrial AIoT Platforms Read the announcement See it all come together Before diving into each component, watch this end-to-end demo showing how Azure IoT Operations, Azure IoT Hub, Microsoft Fabric, and Foundry Local work as one stack across the edge-to-cloud lifecycle - Making industrial AI practical for real-world operations with adaptive cloud. How these components work together Azure IoT Operations and Azure IoT Hub collect real-time data from operational assets and send semantically-ready, modeled data to Microsoft Fabric, where it's contextualized with enterprise data for downstream analytics. Microsoft Foundry extends to the edge through Foundry Local, so the same tooling used to deploy and manage AI models in the cloud applies to edge use cases. All of it integrates into Azure Resource Manager, bringing OT devices, assets, and edge AI models into the same management and security paradigm as every other Azure-managed resource. This blog walks through where to get started with each product capability: 1. Manage Cloud-Connected Devices and Telemetry with Azure IoT Hub Azure IoT Hub is a fully managed cloud service that enables secure bidirectional communication, device-to-cloud telemetry ingestion, cloud-to-device command execution, per-device authentication, remote management and more. Telemetry from IoT Hub can also be routed downstream into analytics platforms like Microsoft Fabric for visualization or AI modeling. Recommended Usage: Devices that utilize IoT Hub are distributed, stand-alone devices with fixed-functions. These devices typically do not require cloud-managed containerized workloads or cloud-managed proximal industrial protocol connectivity. Examples of appropriate device-to-cloud IoT Hub endpoint devices include water monitoring stations, vehicle telematics, distributed fluid level sensors, etc. Resources Current in-market services overview: IoT Hub: What is Azure IoT Hub? - Azure IoT Hub DPS: Overview of Azure IoT Hub Device Provisioning Service - Azure IoT Hub Device Provisioning Service ADU: Introduction to Device Update for Azure IoT Hub Building scalable solutions with Azure IoT platform: Best practices for large-scale IoT deployments - Azure IoT Hub Device Provisioning Service Scale Out an Azure IoT Hub-based Solution to Support Millions of Devices - Azure Architecture Center Azure IoT Hub scaling Try out our preview of new IoT Hub capabilities (integration with Azure Device Registry and Certificate Management) Learn more about these capabilities on our blog post: Azure IoT Hub + Azure Device Registry (Preview Refresh): Device Trust and Management at Fleet Scale… Integration with Azure Device Registry (preview): Integration with Azure Device Registry (preview) - Azure IoT Hub Microsoft-backed X.509 certificate management (preview): What is Microsoft-backed X.509 Certificate Management (Preview)? - Azure IoT Hub How to start with the preview: Deploy IoT Hub with ADR integration and certificate management (Preview) - Azure IoT Hub 2. Connect Industrial Assets with Azure IoT Operations Azure IoT Operations provides a unified data plane for the edge that runs on Azure Arc–enabled Kubernetes clusters and supports open industrial standards. It allows organizations to connect and capture equipment telemetry, normalize OT data locally, route hot-path signals to real-time analytics, securely manage layered industrial networks, and more. Edge‑processed data can then be sent upstream to Microsoft Fabric for AI‑driven analysis. Recommended Usage: Azure IoT Operations is intended to be the data plane for an adaptive cloud deployment extending the management, data, and AI capabilities of the Microsoft cloud to an on-prem device. This device binds to these cloud planes providing a platform for local data processing and intermittent connectivity. The target for these devices range from a small-gateway-style PC to a full data center. Azure IoT Operations endpoints enable cloud-managed containerized workloads and cloud-managed proximal industrial protocol connectivity. Examples of appropriate adaptive cloud and Azure IoT Operations endpoints include, on-robot computers, industrial machine controllers, retail store sensor/vision processing, and top-of-factory site infrastructure for line of business applications. Resources Azure IoT Operations Overview Azure IoT Operations Documentation Hub Releases · Azure/azure-iot-operations Quickstart: explore-iot-operations/quickstart at main · Azure-Samples/explore-iot-operations Latest release update: Open-source framework for scaling robotics from simulation to production on Azure + NVIDIA: microsoft/physical-ai-toolchain Demo video showcasing this in action: Making industrial AI practical for real-world operations with adaptive cloud How we built the demo: explore-iot-operations/quickstart at main · Azure-Samples/explore-iot-operations Edge-AI: microsoft/edge-ai: Production-ready Infrastructure as Code, applications, pluggable components, and… Latest Announcements & Blogs Making Physical AI Practical for Real-World Industrial Operations: Part 1 | Microsoft Community Hub Making Physical AI Practical for Real-World Industrial Operations: Part 2 | Microsoft Community Hub Introducing small form factor infrastructure: embed intelligence into physical systems Unlock Industrial Intelligence | Microsoft Hannover Messe 2026 From pilots to production: How Microsoft and partners are accelerating intelligent operations Partner Solutions How Mesh Systems Builds on Azure IoT Hub and Azure IoT Operations to Accelerate Industrial AI | Microsoft Community Hub Unlocking the Human Telemetry Layer for Safer Industrial Operations | Microsoft Community Hub Unlocking Smart Manufacturing: Siemens Industrial Edge Meets Azure IoT Operations Solving the Data Challenge for Manufacturers with Sight Machine & Azure IoT Operations | Microsoft Community Hub Microsoft and Rockwell Automation: Transforming Industrial AI Together | Microsoft Community Hub 3. Advanced Analytics with Microsoft Fabric Microsoft Fabric delivers a unified, end‑to‑end analytics platform that transforms streaming OT telemetry into real‑time insights and live dashboards. Fabric Operations Agents monitor industrial signals to recommend targeted actions, while Fabric IQ provides a shared semantic foundation that enables AI agents to reason over enterprise data with business context. Together, Fabric turns live industrial data into AI‑powered operational intelligence. Resources Get Started with Microsoft Fabric Learning Path Fabric Real-Time Intelligence documentation - Microsoft Fabric | Microsoft Learn Create and Configure Operations Agents - Microsoft Fabric | Microsoft Learn Fabric IQ documentation - Microsoft Fabric | Microsoft Learn 4.Run AI Models On‑Device with Foundry Local Foundry Local extends on‑device AI to Arc‑enabled Kubernetes edge clusters, providing a Microsoft‑validated inferencing layer for running AI models in industrial, disconnected or sovereign environments. Resources Foundry Local on Azure Local Documentation Participate in Foundry Local on Azure Local preview form Foundry Local on Azure Local: HELM deployment Demo Customer Stories Chevron: Chevron plans facilities of the future with Azure IoT Operations Husqvarna: Husqvarna Group Boosts Operational Efficiency with Azure Adaptive Cloud Ecopetrol: Azure IoT Operations and Azure IoT for energy help Ecopetrol optimize energy distribution while lowering operational costs P&G: Procter & Gamble cuts model deployment time up to 90% with Azure IoT Operations Toyota: Toyota Industries innovates its paint shop processes with Azure industrial AI and Azure IoT Hub1.3KViews3likes0Comments
Amplify Healthcare Intelligence: Data, AI, and Agent-Powered Transformation
Join Microsoft for Amplify Healthcare Intelligence, a webinar and in-person workshop series designed for healthcare and life sciences organizations building the foundation for trusted AI. Every session starts from the same premise: you cannot deliver trusted AI without a trusted data foundation. Across the series you will see how leading organizations unify their data estate, ground AI agents in real business context, and turn that foundation into results they can measure. What You Will Learn How to build a unified, AI-ready data foundation across a fragmented healthcare data estate How to ground AI agents in trusted healthcare data and real business context How to modernize analytics while reducing complexity and cost How to accelerate innovation with Microsoft Fabric, Azure AI Foundry, Microsoft IQ, and Copilot technologies How to deliver measurable impact across clinical, operational, research, and business scenarios Whether you are defining your AI strategy, modernizing your analytics platform, or scaling AI across your organization, these sessions offer practical guidance, real-world customer examples, and hands-on learning to help you move from AI ambition to business impact. Webinars & In-Person Workshops 🎥 Webinars One-hour virtual sessions with actionable guidance, live demonstrations, customer stories, and best practices from Microsoft experts. Each webinar shows how leading healthcare organizations are turning data, AI, and enterprise intelligence into measurable business outcomes. All sessions are from 3-4 ET (12-1 PT) and are free to attend. Date Topic Register Oct 7 3-4 ET (12-1 PT) Building an AI-Ready Healthcare Data Foundation Register Oct 14 3-4 ET (12-1 PT) Building Trusted Healthcare AI: Grounding Agents with Enterprise Data and Context Register Oct 21 3-4 ET (12-1 PT) Finance in the Agent Era: AI-Powered Planning, Forecasting, and Insights Register Oct 28 3-4 ET (12-1 PT) Reduce BI Sprawl, Cut Cost and Build an AI-Ready Analytics Foundation Register Cannot join live? Register anyway. We will send you the recording and session materials after the event. Additional sessions will be added through the end of the year, so check back or register for one session to be notified as new dates are announced. 🏢 In-Person Workshops Our two-day workshops combine executive strategy, healthcare-specific use cases, architecture guidance, and hands-on labs designed to help teams identify and accelerate high-value AI opportunities. Attendance is free. Participants are responsible for their own travel and accommodation, and space at each location is limited. Workshops run 9am to 4pm local time on both days. Day 1: From Healthcare Data to Healthcare Intelligence Day 1 focuses on healthcare transformation strategy, customer examples, and the architectural patterns that make trusted AI possible at scale. The day closes with a networking reception and peer exchange. The Frontier Transformation imperative: from AI ambition to measurable impact Microsoft IQ: turning data into enterprise intelligence Building the unified data foundation Building trusted AI: security, governance, privacy, and compliance Healthcare transformation in action: clinical, operational, research, and finance scenarios Activating data with AI data agents and Copilot experiences Day 2: Hands-On Healthcare AI and Analytics Lab Day 2 is a guided, end-to-end lab. Participants build a working healthcare intelligence solution from raw data through to a grounded AI agent, using Microsoft Fabric, Azure AI Foundry, Copilot technologies, and modern data architectures. Build the foundation: data ingestion, lakehouse architecture, and data engineering Create actionable insights: semantic models and dashboards Prepare data for AI: AI-ready data assets and data governance Build and ground AI agents in trusted enterprise data From insight to intelligent action: planning your organization's next steps What to bring: a laptop with a current browser. Lab environments and credentials are provided on site, and no prior Fabric or Foundry experience is assumed. Date City Venue Register October 13-14, 2026 9am - 4pm Boston Microsoft New England One Memorial Drive Cambridge, MA 02142 Register October 27-28, 2026 9am - 4pm Silicon Valley Microsoft Silicon Valley 1045 La Avenida Street Mountain View, CA 94043 Register November 10-11, 2026 9am - 4pm Chicago Microsoft Chicago (AON Center) 200 East Randolph Drive, Suite 200 Chicago, IL 60601 Register December 8-9, 2026 9am - 4pm New York Microsoft Garage 300 Lafayette Street New York, NY 10012 Register Who Should Attend This series is built for the people who own the data estate and the people who depend on it. Sessions are technical enough for practitioners and strategic enough for the leaders who fund the work. Chief data officers and data and analytics leaders Data platform, data engineering, and business intelligence teams Data architects, engineers, and data scientists AI and innovation leaders Healthcare and life sciences executives Clinical, operational, research, and finance transformation leaders No prior Microsoft Fabric experience is required for any session in this series. Questions Wondering whether a session is the right fit, or whether to bring a team rather than an individual? Contact Camille Whicker and we will help you choose the right sessions for your organization.
Your Agents Need More Than a Place to Run
In architecture reviews with enterprise teams moving their first agentic applications toward production, I often hear the same plan: the team has containerized their agent and intends to run it on the managed Kubernetes cluster the organization already trusts. The reasoning is sensible, since the platform team knows the tooling and security has approved the network model, and for the first use case or two it is often the right call. Having watched this unfold in my years leading AgenticAI customer engineers and forward deployed engineers, and now helping customers reach production on Azure, I want to describe what happens next, before leaders commit rather than after. One thing to note is Azure supports multiple ways to build and operate agents. Foundry Agent Service provides an integrated managed runtime around your agent code. Azure Kubernetes Service supports teams that need Kubernetes-level control or want to extend an established platform, while Azure Container Apps provides managed container hosting. These services can work together. The decision is which capabilities and responsibilities best fit the workload. Where the cluster is the right answer A stateless retrieval application, a document extraction pipeline, or a classification job is a web service that happens to call a model, and a container platform runs web services well. A large retail customer of mine ran an invoice extraction agent on containers for over a year with almost no issues, and I never suggested they move it. The cluster remains the right home for several other situations as well. LLM invocations embedded inside existing microservices, event driven, or batch pipelines fit container platforms naturally. Genuine constraints such as air-gapped or sovereign environment, regions where a managed service is not yet offered are a good reason to run your own stack, and strong engineering team that already operates at that level can be a real asset. Even when the agents themselves move to a managed runtime, the tool servers, business APIs, and data services those agents call, often stay on your cluster, so they are complementary far more often than they are competitors. The problem is that these early wins can make agents seem like just another workload. Where the wheels come off The first failure is the state. A research agent that plans, searches, and synthesizes for ninety minutes is a long-running stateful process, while a Kubernetes pod is a disposable container the scheduler may restart at any time. A financial services team I worked with lost costly research run to a routine node upgrade, and responded as capable engineers do by building checkpointing, a durable store, and a resume mechanism. It worked, but they now owned a piece of infrastructure they had to keep correct as their agent's framework changed beneath it. A managed agent runtime absorbs this. Hosted agents in Foundry Agent Service, as one example, give every session a VM-isolated sandbox with a persistent file system, a durable state store that survives crashes and restarts and can hold checkpoints for frameworks such as LangGraph or Microsoft Agent Framework, and a resilient execution mode that recovers long-running work after a process interruption. The second is the human-in-the-loop. A commercial insurance customer’s claims agent needed sign-off from an adjuster and sometimes a second reviewer, with days between steps. Stopping an agent cleanly at the moment it needs a decision, holding its full session for four days without paying to keep it running, and resuming it correctly when the approval arrives is not something a container orchestrator gives out the box. The team built agent session suspend and resume, a queue, a durable state store, notifications, and an approval interface, and ended up with a small workflow engine nobody had planned to own. In hosted agents, an idle session is deprovisioned with its state persisted and restored onto fresh compute when the same session ID returns, so an agent waiting on an approval cost nothing while it waits, and sessions are retained for up to thirty days of inactivity. The approval experience remains yours to design, which is where your engineers' time should go. The third is multi-turn conversation, which quietly pushes teams into building their own context management system. The first version appends each turn to history, and within few turns the history outgrows the context window while cost and latency climb. So, the team adds truncation, then summarization, then retrieval of earlier turns, then per-user and per-tenant scoping, then expiry and deletion rules for privacy. An industrial customer's safety compliance assistant, with conversations stretching across days, followed exactly this path and ended up with a bespoke thread store and summarization pipeline nobody had budgeted for. Its first serious incident came when a summary silently dropped a compliance-relevant instruction. With the Responses protocol in hosted agents in Foundry, conversation history is a durable, platform-managed record keyed by a conversation ID and reachable from any channel, so the thread store is no longer yours to build, although deciding what to summarize or retrieve remains a design choice for your agent. The fourth is identity. On a cluster, the path of least resistance is a shared service account, and in one review a security architect asked which actions had been taken on behalf of which user, only to learn that the logs could not say. Hosted agents create a dedicated Microsoft Entra agent identity for each agent at deploy time, use on-behalf-of flows to act with the user's delegated permissions in interactive scenarios and the agent's own identity in autonomous ones, and keep the agent identifiable for audit in both cases. The fifth is per-user session isolation, which is the difference between an agent that serves many people and an agent that mixes them up. Agents read files, run code, and hold working data, and on a shared pod the default is that many users share a process, a file system, and often a cache. Giving every user session its own sandboxed environment and storage, so that one person's documents and intermediate results can never surface in another's, means engineering hard isolation boundaries and proving them to your security team. Hosted agents make a VM-isolated sandbox per session the default, and their durable state store can partition items per end user, so one store is safe to share across the users of a multitenant agent. And lastly, Evaluation and optimization are where the gap widens. The largest difference between teams that scale and those that stall is evaluation. Because agents are probabilistic and multi-step, staging tests often miss failures such as a wrong tool choice or a policy violation deep in a task. One customer’s agent passed every offline check but degraded unnoticed for weeks after a model update because evaluation stopped at release. Mature teams continuously evaluate production traces, combine automated judges with sampled human review, and red-team regularly.Once quality is measurable, teams can deliberately balance prompts, models, tools, latency, and cost. One team cut per-task cost by routing simple steps to smaller models after evaluation confirmed quality held. Self-built stacks require teams to assemble and maintain tracing, datasets, judges, and release gates. Hosted agents instead combines default OpenTelemetry traces with continuous evaluation, adversarial testing, and datasets generated from agent instructions. Staged closed-loop optimization uses those traces to improve instructions, tool descriptions, and model selection without extra plumbing. The real cost is the velocity gap Leaders usually expect me to quantify the initial build, and that is the smaller number. A team of four building the first agent often becomes ten or twelve within a year, and a growing share of them are maintaining a runtime for agents rather than building agents that serve the business. The enterprise has quietly created an internal agent infrastructure company in a field where the patterns for memory, tools, evaluation, and safety are rewritten every few months, while hyperscalers put hundreds of engineers on exactly this problem and ship at a cadence no single platform group can match. Foundry Agent Service, for instance, bundle content safety guardrails into the runtime and route outbound traffic through a customer virtual network, capabilities that platform teams otherwise assemble one integration at a time. This plumbing does not differentiate your organization, so the question is whether your scarcest engineers should spend years on it or on the workflows, data, and judgment only your company has. This is also why the technology companies held up as examples are a poor template. Many built their own runtimes because managed options did not yet exist and had large platform organizations to carry the load. Even they tend to invest in a custom runtime for the first handful of use cases and then migrate as managed services mature, because the maintenance burden compounds while the strategic value of owning the plumbing does not. What I would do as the leader I am not arguing against Kubernetes or for moving everything tomorrow. Comparable managed runtimes exist across the hyperscalers, and I use hosted agents as the running example only because it is the one I know best from the inside. Managed agent services are still maturing, some workloads have real data residency or customization needs, and abstraction always constrains something. What I am arguing for is a deliberate choice for each use case, guided by three questions: whether the agent must outlive a single request by running long, waiting on humans, or remembering across sessions whether it must act with its own identity, auditable delegation, and policy enforcement whether your team would be building anything a managed service already provides, and who will still maintain it in two years. Key takeaways Match the runtime to the workload. Containers on your existing cluster suit stateless, short-lived agents, while long-running, human-in-the-loop, and memory-dependent agents need capabilities your platform team was never hired to build. Count the hidden team. The real cost of self-hosting is the growing group of engineers maintaining state, identity, memory, guardrails, and tracing instead of solving business problems. Make evaluation continuous and connected to production traces. Pre-release testing alone will miss the drift and trajectory failures that hurt you, and optimization of quality, cost, and latency depends on that evaluation data. Follow the pattern of the leaders, not their early architecture. Companies that built custom runtimes did so before managed options matured, and most of them move toward managed services as those options improve. A practical place to begin is your roadmap for the next twelve months. Sort each use case into stateless and short-lived or long-running and human-dependent, and for every agent in the second group put a price on the engineers who would maintain the runtime rather than the business logic. I would like to hear how you have drawn this line, and where a managed service was not yet ready for something you needed.536Views2likes0CommentsHow to make AI responses faster on Microsoft Foundry: lessons from 2,040 measurements
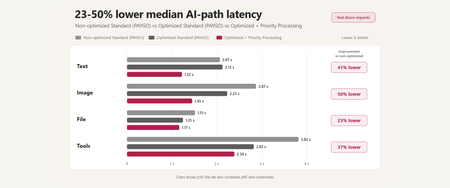
A reproducible Microsoft Foundry performance study covering prompt caching, multimodal input, tool orchestration, MCP lifecycle, Toolbox tool search, and Priority Processing - with correctness and reliability measured alongside latency.368Views0likes0Comments
Building Intelligent Apps With Azure
Technology is changing fast, and apps today can do far more than they used to. With artificial intelligence (AI) becoming part of everyday tools, organizations of all sizes are looking for ways to build smarter, more helpful apps. Microsoft Azure makes this easier by giving teams the tools and training they need to learn, experiment, and create with confidence. What Makes an App “Intelligent”? An intelligent app uses AI to make experiences feel more natural and responsive — like understanding language, recognizing images, or offering helpful suggestions. You can build these apps from scratch or modernize the ones you already have using Microsoft Azure. Cloud technology plays a big role because it keeps everything fast, secure, and easy to scale. Helping Teams Build With Confidence Working with AI can feel overwhelming at first. Teams often face challenges like: Not having much experience with AI Feeling unsure about which tools to use Wanting to make sure AI is used responsibly Azure supports teams with hands‑on learning, expert guidance, and built‑in responsible AI tools through frameworks like Microsoft Responsible AI, helping teams build safely and confidently. Start With the Basics Before building intelligent apps, it helps to understand where your team is today and what skills they may need. Azure and Microsoft Learn offer simple, practical resources to get started: AI fundamentals – Learn the basics of how AI works https://learn.microsoft.com/ai Generative AI – Explore tools like AI copilots and how to write effective prompts Craft effective prompts for Microsoft 365 Copilot - Training | Microsoft Learn Cloud‑native development – Build apps designed to run smoothly in the cloud Create cloud native apps with Azure and open-source software - Training | Microsoft Learn Modernizing older apps: Azure application modernization overview - Assess, plan, and modernize existing workloads Microsoft App Modernization Guidance for Azure - App Modernization Guidance | Microsoft Learn Power Platform modernization - Rebuild or extend legacy apps using low-code tools. Modernize applications with Power Platform - Power Platform | Microsoft Learn Azure & .NET modernization – Upgrade ASP.NET apps to modern .NET and deploy to Azure Modernize ASP.NET and ASP.NET Core web applications - App Modernization Guidance | Microsoft Learn These resources help teams learn at their own pace and build confidence as they go. Deploying Apps the Right Way Once your app is ready, you need a smooth way to launch it. Azure provides tools and best practices to help teams: Set up the right environment Build and test apps quickly Use containers and DevOps to speed up delivery Azure DevOps | Microsoft Azure Containers on Azure | Microsoft Azure Deploy AI features safely using Azure’s governance and security tools As many developers have noted, “What used to take weeks now takes hours.” Keep Improving Over Time Building an intelligent app isn’t a one‑time project. Teams need to monitor performance, keep apps secure, and make improvements as technology evolves. Azure offers resources to help with: Scaling apps as usage grows — Automatically adjust resources to meet demand while maintaining performance and reliability. Protecting apps from security threats — Use built‑in security, identity, and compliance tools to safeguard data and reduce risk. Improving accuracy and performance — Monitor models and applications to fine‑tune quality, responsiveness, and user experience. Managing costs — Track usage, optimize resources, and control spending as apps grow and evolve. Create a Culture of Continuous Learning The most successful organizations treat learning as an ongoing investment. As Forbes notes, helping people understand new technologies builds trust and prepares teams for the future. Microsoft offers a wide range of learning paths, tutorials, and hands‑on experiences to support your team as they explore AI and intelligent app development: https://learn.microsoft.com/ https://www.microsoft.com/nonprofits/offers-for-nonprofits https://learn.microsoft.com/industry/nonprofit/microsoft-for-nonprofits/287Views1like1CommentMicrosoft Industrial AI Partner Guide: Choosing the Right Data Expertise for Every Stage
As organizations scale Industrial AI, the challenge shifts from technology selection to deciding who should lead which part of the journey -- and when. Which partners should establish secure connectivity? Who enables production grade, AI ready industrial data? When do systems integrators step in to scale globally? This Partner Guide helps customers navigate these decisions with clarity and confidence: Identify which partners align to their current digital transformation and Industrial AI scenarios leveraging Azure IoT and Azure IoT Operations Confidently combine partners over time as they evolve from connectivity to intelligence to autonomous operations This guide focuses on the Industrial AI data plane – the partners and capabilities that extract, contextualize, and operationalize industrial data so it can reliably power AI at scale. It does not attempt to catalog or prescribe end‑to‑end Industrial AI applications or cloud‑hosted AI solutions. Instead, it helps customers understand how industrial partners create the trusted, contextualized data foundation upon which AI solutions can be built. Common Customer Journey Steps 1. Modernize Connectivity & Edge Foundations The industrial transformation journey starts with securely accessing operational data without touching deterministic control loops. Customers connect automation systems to a scalable, standards-based data foundation that modernizes operations while preserving safety, uptime and control. Outcomes customers realize Standardized OT data access across plants and sites Faster onboarding of legacy and new assets Clear OT–IT boundaries that protect safety and uptime Partner strengths at this stage Industrial hardware and edge infrastructure providers Protocol translation and OT connectivity Automation and edge platforms aligned with Azure IoT Operations 2. Accelerate Insights with Industrial AI With a consistent edge-to-cloud data plane in place, customers move beyond dashboards to repeatable, production-grade Industrial AI use cases. Customers rely on expert partners to turn standardized operational data into AI‑ready signals that can be consumed by analytics and AI solutions at scale across assets, lines, and sites. Outcomes customers realize Improved Operational efficiency and performance Adaptive facilities and production quality intelligence Energy, safety, and defect detection at scale Partner strengths at this stage Industrial data services that contextualize and standardize OT signals for AI consumption Domain-specific acceleration for common Industrial AI scenarios Data pipelines integrated with Azure IoT Operations and Microsoft Fabric 3. Prepare for Autonomous Operations As organizations advance toward closed‑loop optimization, the focus shifts to safe, scalable autonomy. Customers depend on partners to align data, infrastructure, and operational interfaces, while ensuring ongoing monitoring, governance, and lifecycle management across the full operational estate. Outcomes customers realize Proven reference architectures deployed across plants AI‑ready data foundations that adapt as operations scale Coordinated interaction between OT systems, AI models, and cloud intelligence Partner strengths at this stage Industrial automation leadership and control system expertise Edge infrastructure optimized and ready for Industrial AI scale Systems integrators enabling end‑to‑end implementation and repeatability Data Intelligence Plane of Industrial AI - Partner Matrix This matrix highlights which partners have the deepest expertise in accessing, contextualizing, and operationalizing industrial data so it can reliably power AI at scale. The matrix is not a catalog of end‑to‑end Industrial AI applications; it shows how specialized partners contribute data, infrastructure, and integration capabilities on a shared Azure foundation as organizations progress from connectivity to insight to autonomous operations. How to use this matrix: Start with your scenario → identify primary partner types → layer complementary partners as you scale. Partner Type Adaptive Cloud Primary Solution Example Scenarios Geography Advantech Industrial Hardware, Industrial Connectivity LoRaWAN gateway integration + Azure IoT Operations Industrial edge platforms with built in connectivity, industrial compute, LoRaWAN, sensor networks Global Accenture GSI Industrial AI, Digital Transformation, Modernization OEE, predictive maintenance, real-time defect detection, optimize supply chains, intelligent automation and robotics, energy efficiency Global Avanade GSI Factory Agents and Analytics based on Manufacturing Data Solutions Yield / Quality optimization, OEE, Agentic Root Cause Analysis and process optimization; Unified ISA-95 Manufacturing Data estate on MS Fabric Global Belden Industrial Connectivity, Networking, Security Belden Horizon Data Operations (BHDO) + LioN-X with Azure IoT Operations OT-IT convergence, network orchestration and monitoring, ruggedized ethernet and switching, industrial WiFi, multi-vendor protocol connectivity, OT security, OPC UA Global Capgemini GSI The new AI imperative in manufacturing OEE, maintenance, defect detection, energy, robotics Global DXC GSI Intelligent Boost AI and IoT Analytics Platform 5G Industrial Connectivity, Defect detection, OEE, safety, energy monitoring Global Innominds SI Intelligent Connected Edge Platform Predictive maintenance, AI on edge, asset tracking North America, EMEA Litmus Automation Industrial Connectivity, Industrial Data Ops Litmus Edge + Azure IoT Operations Edge Data, Smart manufacturing, IIoT deployments at scale Global, North America Mesh Systems GSI & ISV Azure IoT & Azure IoT Operations implementation services and solutions (including Azure IoT Operations-aligned connector patterns) Device connectivity and management, data platforms, visualization, AI agents, and security North America, EMEA Nortal GSI Data-driven Industry Solutions IT/OT Connectivity, Unified Namespace, Digital Twins, Optimization, Edge, Industrial Data, Real‑Time Analytics & AI EMEA, North America & LATAM NVIDIA Technology Partner Accelerated AI Infrastructure; Open libraries, models, frameworks, and blueprints for AI development and deployment. Cross industry digitalization and AI development and deployment: Generative AI, Agentic AI, Physical AI, Robotics Global Oracle ISV Oracle Fusion Cloud SCM + Azure IoT Operations Real-time manufacturing Intelligence, AI powered insights, and automated production workflows Global Rockwell Automation Industrial Automation FactoryTalk Optix + Azure IoT Operations Factory modernization, visualization, edge orchestration, DataOps with connectivity context at scale, AI ops and services, physical equipment, MES Global Schneider Electric Industrial Automation Industrial Edge Physical equipment, Device modernization, energy, grid Global Siemens Industrial Automation & Software Industrial Edge + Azure IoT Operations reference architecture Industrial edge infrastructure at scale, OT/IT convergence, DataOps, Industrial AI suite, virtualized automation. Global Sight Machine ISV Integrated Industrial AI Stack Industrial AI, bottling, process optimization Global Softing Industrial Industrial Connectivity edgeConnector + Azure IoT Operations OT connectivity, multi-vendor PLC- and machine data integration, OPC UA information model deployment EMEA, Global TCS GSI Sensor to cloud intelligence Operations optimization, healthcare digital twin experiences, supply chain monitoring Global This Ecosystem Model enables Industrial AI solutions to scale through clear roles, respected boundaries and composable systems: Control systems continue to be driven by automation leaders Safety‑critical, deterministic control stays with industrial automation partners who manage real‑time operations and plant safety. Customers modernize analytics and AI while preserving uptime, reliability, and operational integrity. Data, AI, and analytics scale independently A consistent edge to cloud data plane supports cloud scale analytics and AI, accelerating insight delivery without entangling control systems or slowing operational change. This separation allows customers and software providers to build AI solutions on top of a stable, industrial‑grade data foundation without redefining control system responsibilities. Specialized partners align solutions across the estate Partners contribute focused expertise across connectivity, analytics, security, and operations, assembling solutions that reduce integration risk, shorten deployment cycles, and speed time to value across the operational estate. From vision to production Industrial AI at scale depends on turning operational data into trusted, contextualized intelligence safely, repeatably, and across the enterprise. This guide shows how industrial partners, aligned on a shared Azure foundation, create the data plane that enables AI solutions to succeed in production. When data is ready, intelligence scales. Call to action: Use this guide to identify the partners and capabilities that best align to your current Industrial AI needs and take the next step toward production‑ready outcomes on Azure.2.1KViews4likes0CommentsChoosing a real-time voice architecture on Microsoft Foundry: three enterprise patterns
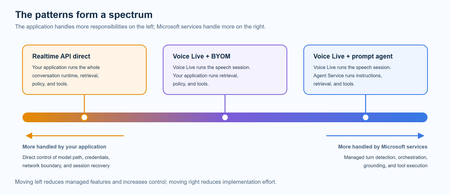
A practical comparison of three real-time voice architectures on Microsoft Foundry, including implementation tradeoffs and four enterprise release gates for residency, networking, retrieval authorization, and tool credentials.869Views2likes0CommentsModel router updates: new regions, a refreshed model pool, and understanding the hill climb
Across Microsoft, "hill climbing" has become shorthand for how real AI progress happens: not in one dramatic leap, but through a disciplined loop. Microsoft AI defines the hill climb as an organization that continuously improves, cycle after cycle, through more compute, better data, and sharper evaluation. Reinforcement fine-tuning in Foundry defines it as improving the deployable model package one measured step at a time across quality, latency, and cost. Different altitudes, same premise: progress is not a one-shot decision. It's a loop. For most teams, the decision of what model to use when is made manually or with custom routing tools. A developer picks a model based on benchmarks, familiarity, or the last launch that made headlines, ships it, and revisits the choice only when something breaks. In an ecosystem where the frontier moves monthly, that decision goes stale fast. Model router in Foundry Models brings the hill climb to the selection layer. What's new: a bigger pool, in more places This release expands where teams can deploy model router, broaden the supported model pool, and delivers updates through a stable endpoint. Together, these changes help teams run production workloads in more locations, match a wider range of tasks to suitable models, and adopt supported updates without changing the application integration. A refreshed model pool. The supported model list now includes Anthropic Claude Opus 4.8 — a high-capability model built for complex reasoning and long-form generation, for scenarios that demand depth, structure, and quality — and the GPT-5.6 family. Just as importantly, the pool is pruned: gpt-5-chat, gpt-5.2-chat, gpt-5.3-chat, Deepseek-V3.1 have been removed from the model router as models reach the end of their lifecycle and are deprecated in Foundry. New region availability. The model router is now available in 28 regions for global standard and 21 data zone regions. For many organizations, inference requests must stay within specific geographic boundaries for regulatory, governance, or customer-trust reasons — and intelligent routing shouldn't force a compromise on that. Find the full list of regions here. The most important detail is what you don't have to do: these updates occur automatically*. The endpoint remains stable as the supported model pool is refreshed, so teams do not need to redeploy the model router to receive the update. Applications can continue using the same integration while the model router evaluates requests against the current supported pool. Teams should continue monitoring routing traces and application outcomes to confirm that quality, cost, latency, and governance requirements are met. *Models from Anthropic still need to be deployed separately before they can be routed to through the model router. Interested in hearing more about what's new to the model router? Tune in for the next episode of Model Mondays with Sanjeev Jagtap and Lee Stott, where they talk all things model router from evaluations to hill climbing. Sign up here to watch live or view the replay: Model Mondays - Spotlight On Model router in Microsoft Foundry | Microsoft Reactor The selection-layer hill climb At the selection layer, a step is a routing decision. Each one is a micro-optimization against your objective, and each one is instrumented: every response from the model router includes a model field showing which underlying model was selected, so the climb leaves a complete, auditable trail. Model router supports three parts of the optimization loop: A/B testing to compare two router configurations to understand quality, cost, and latency tradeoffs; model decomposition to use routing results to decompose a single-model application into a multi-model or multi-agent design, and continuous routing to keep the router in production for continuous per-request selection. Each pattern turns model choice into a measured, repeatable process rather than a fixed decision. 1. A/B Testing Question: Which model or routing strategy should I use in production? A/B testing helps teams compare candidate models, model families, or router configurations against the same workload. Representative traffic is sent to competing deployments, and teams compare quality, cost, latency, and governance outcomes. The goal is to understand tradeoffs and identify the model or routing strategy that best meets workload requirements before promoting it to production. 2. Model Decomposition Question: What work is my application actually doing? Model decomposition uses model router as a diagnostic tool. By deploying the model router against a representative workload and examining routing telemetry, teams can see how requests naturally separate into different task classes. Simple retrieval, classification, and summarization requests may route to smaller models, while reasoning, planning, and agentic workflows may require more capable models. The goal is not to choose a winner, but to understand the structure of the workload and uncover opportunities for optimization, specialization, or architectural improvements. 3. Route continuously Question: Why choose a single model at all? Route continuously is the pattern model router was designed for but is not limited to. Rather than treating model selection as a one-time decision, teams leave the model router in production and allow the best-fit model to be selected for each request. As the supported model pool, regional availability, and platform capabilities evolve, teams can continue using the same endpoint while evaluating whether updates improve workload outcomes. Model selection becomes an ongoing optimization process rather than a project that must be repeated every time the model landscape changes. Together, these patterns illustrate a broader shift: the model router is more than a model. It is a tool for the optimization loop itself, helping teams evaluate tradeoffs, understand workload behavior, test hypotheses, and continuously refine model selection as requirements evolve. Whether used to compare candidate models, decompose applications into specialized tasks, or automate per-request routing in production, model router turns model selection into an observable, measurable, and repeatable process. As the model landscape continues to change, that optimization loop becomes a durable advantage. Getting Started Ready to start your own hill climb? Whether you're exploring the model router for the first time, evaluating routing strategies against your workload, or building a long-term optimization practice, these resources can help you move from experimentation to production with Microsoft Foundry. What's new in model router? Sign up for the next Model Mondays episode for a deep dive into new features, optimization patterns, and the latest model router updates. How do I build agents with model router? Check out the Model Router Agents Lab and build agent experiences with routing, retrieval, web search, tool calling, and multi-agent patterns. How do I evaluate model router? Compare model router against baseline models using your own prompts, then review quality, cost, latency, and routing decisions with the Auto Evaluation Toolkit. How do I optimize model router for my workload? Start your hill-climbing journey with the Model Mastery workshop, where you'll test one optimization lever at a time and measure how each change impacts workload outcomes. How do I build a model router optimization playbook? Explore the Model Releases repository to track new capabilities, understand the optimization question behind each release, and try focused notebooks that demonstrate one optimization lever at a time.2.8KViews2likes0Comments