apis
790 Topics
Microsoft Defender XDR / Defender for Endpoint data connectors inconsistent failures
Hello, We are deploying our SOC (Sentinel) environments via Bicep. Now the Defender XDR ( MicrosoftThreatProtection) and Defender for Endpoint ( MicrosoftDefenderAdvancedThreatProtection) data connectors are failing to deploy inconsistantly. It seems to be a known issue due to the following posts: - https://github.com/Azure/SimuLand/issues/23 - https://techcommunity.microsoft.com/t5/microsoft-sentinel/quot-missing-consent-invalid-license-quot-defender-for-endpoint/m-p/3027212 - https://github.com/Azure/Azure-Sentinel/issues/5007 Next to this issue I see almost no development on the data connectors API, is there some news to be spread how to enable data connectors automated in the future, since it seems to be moving to Content Hub. It is hard to find any docs about how to deploy this for example via Bicep!? Also I have a question regarding 'Tenant-based Microsoft Defender for Cloud (Preview)' data connector. We deploy this now via GenericUI data connector kind, but this has no option to enable it via automation. Same as the question in the previous paragraph, how would this be made possible?1.2KViews0likes1CommentDelivering Agent Skills Over MCP
Getting a skill working with one agent is a useful start. Sharing it with other agents raises a different question: where should that skill live? You could give each agent its own copy. But when the skill changes, those copies need updating. The official Skills extension for Model Context Protocol (MCP) provides a standard way to make skills available from a server, so compatible agents can find and load them when needed. Let's look at what happens across that connection, then where Microsoft Foundry fits in. What the extension adds MCP already gives agents access to content from servers through resources. The Skills extension builds on that. It adds a way to ask which skills a server offers and get the details needed to load them. It doesn't change the skill format, and it doesn't run a skill on the server. The application running your agent, called the host, still decides how to offer skills to the user or model and load the selected instructions. Both the server and the host need the right support. Being able to call an MCP tool isn't enough to discover and load remote skills. A custom tool that returns skill text isn't, by itself, an implementation of this extension either. The extension is identified as io.modelcontextprotocol/skills . Its proposal, SEP-2640, has reached Final status. Client support is still developing, so a published specification doesn't mean every MCP host supports it yet. How an agent gets a skill The basic sequence is straightforward: find out what's available, select a skill, and read the content needed to use it. The host's MCP client handles the requests to the server. We'll follow the case where the server provides a file list, called a manifest. It includes each file's address, size, and a SHA-256 digest: a fingerprint used to check that the file received matches what the server listed. The examples below use a generic example-skill with two files. They illustrate the official message shapes, not a captured server session. They use protocol revision 2026-07-28 and include its required request metadata. The _meta block tells the server which protocol version and client capabilities apply to each request, including the client's Skills extension support. Both sides must declare support. Use a client and server that support this revision. The Foundry examples later follow its separately documented path. These examples show JSON-RPC message bodies, not complete HTTP requests. For Streamable HTTP, POST each message to the server's MCP endpoint with Content-Type: application/json , Accept: application/json, text/event-stream , and MCP-Protocol-Version: 2026-07-28 headers. Also set Mcp-Method to the body's method , such as skills/list . For resources/read , set Mcp-Name to the requested URI, such as skill://example-skill/SKILL.md . The mirrored values must match the body. See the HTTP header requirements. Find out what's available First, the server declares that it supports resources and the Skills extension. This is the relevant fragment of its server/discover response: { "capabilities": { "resources": {}, "extensions": { "io.modelcontextprotocol/skills": {} } } } The empty extension object means skills are supported, but optional directory reading isn't enabled. The client can now ask for the available skills: { "jsonrpc": "2.0", "id": 1, "method": "skills/list", "params": { "_meta": { "io.modelcontextprotocol/protocolVersion": "2026-07-28", "io.modelcontextprotocol/clientCapabilities": { "extensions": { "io.modelcontextprotocol/skills": {} } }, "io.modelcontextprotocol/clientInfo": { "name": "example-client", "version": "1.0.0" } } } } Here is a response containing one skill: { "jsonrpc": "2.0", "id": 1, "result": { "resultType": "complete", "skills": [ { "uri": "skill://example-skill/SKILL.md", "frontmatter": { "name": "example-skill", "description": "An example skill for this article." }, "resources": [ { "uri": "skill://example-skill/SKILL.md", "digest": "sha256:d2069d0f3682fea0d69e62247386e950e9ad958bab5b186b456dc1fb8266e312", "size": 138 }, { "uri": "skill://example-skill/references/notes.md", "digest": "sha256:e76b3033746e3c5d8cc970b21b15ce40f868e6902c065521a1abf373f4a19c85", "size": 58 } ] } ], "ttlMs": 300000, "cacheScope": "public" } } The resources array is the manifest. It lists both files, but doesn't contain their text. The host can show the skill's name and description without fetching either file. size counts bytes, not characters. The cache fields describe how long the result stays fresh and whether it can be shared. They aren't trust checks, and public here is a choice for this illustrative server, not a recommendation for private skill content. resultType: "complete" means this request completed, not that the server's entire catalog is in the response. If it includes nextCursor , pass that value as params.cursor on the next skills/list request. Each skill's manifest stays whole on one page. The user or model can then select a relevant skill. The host keeps track of which server it came from and its address, known as a URI. Read and load the instructions After any required approval, the host uses resources/read to get the selected skill's instructions. It checks them against the details from the listing before adding them to the agent's context, the information available to the model. The request uses the instruction URI from the listing: { "jsonrpc": "2.0", "id": 2, "method": "resources/read", "params": { "uri": "skill://example-skill/SKILL.md", "_meta": { "io.modelcontextprotocol/protocolVersion": "2026-07-28", "io.modelcontextprotocol/clientCapabilities": { "extensions": { "io.modelcontextprotocol/skills": {} } }, "io.modelcontextprotocol/clientInfo": { "name": "example-client", "version": "1.0.0" } } } } This time, the response contains the actual file text: { "jsonrpc": "2.0", "id": 2, "result": { "resultType": "complete", "contents": [ { "uri": "skill://example-skill/SKILL.md", "mimeType": "text/markdown", "text": "---\nname: example-skill\ndescription: An example skill for this article.\n---\n\nRead references/notes.md when additional guidance is needed.\n" } ], "ttlMs": 300000, "cacheScope": "public" } } The \n sequences represent line breaks in the file. Encoding the decoded text as UTF-8 produces 138 bytes. Computing SHA-256 over those bytes produces the digest shown in the first manifest entry. The fingerprint covers the file bytes, not the surrounding JSON response. Reading the file and loading the skill are different steps. An MCP resource browser could read the same file to display it to a person. That doesn't make the skill active. The host must handle the checks and approvals that come with loading it for the agent. Get supporting files when needed If the agent needs a reference or another supporting file, the host reads it from the same server using resources/read . It checks that the file is in the saved manifest and that its contents match before using it. For our example, the relative reference resolves to the second URI in the manifest. When that file is needed, the client sends: { "jsonrpc": "2.0", "id": 3, "method": "resources/read", "params": { "uri": "skill://example-skill/references/notes.md", "_meta": { "io.modelcontextprotocol/protocolVersion": "2026-07-28", "io.modelcontextprotocol/clientCapabilities": { "extensions": { "io.modelcontextprotocol/skills": {} } }, "io.modelcontextprotocol/clientInfo": { "name": "example-client", "version": "1.0.0" } } } } The server returns: { "jsonrpc": "2.0", "id": 3, "result": { "resultType": "complete", "contents": [ { "uri": "skill://example-skill/references/notes.md", "mimeType": "text/markdown", "text": "Use only the information relevant to the current request.\n" } ], "ttlMs": 300000, "cacheScope": "public" } } Those 58 bytes match the second manifest entry. Even a changed line ending would change the fingerprint, so the host must check the exact bytes received. Here's how those steps fit together: The host reads instructions and supporting files as needed, checking each against the server's manifest before use. Files that aren't needed stay unread. Connecting to a server doesn't mean downloading every skill it offers. And loading a skill still doesn't guarantee that the agent will follow every instruction correctly. Which request does what? You don't need to memorize the method names, but these are the ones you'll see when working with an implementation: Method When to use it skills/list Find available skills and get their details skills/get Get or refresh the details for one skill using its URI resources/read Read instructions or a supporting file resources/directory/read List the files and folders directly inside a directory, if the server supports it You don't need to call skills/get after every skills/list . The listing already contains a complete entry for each returned skill. Use skills/get when you already know a skill's URI or need fresh details for that skill. For example, a direct lookup looks like this: { "jsonrpc": "2.0", "id": 4, "method": "skills/get", "params": { "uri": "skill://example-skill/SKILL.md", "_meta": { "io.modelcontextprotocol/protocolVersion": "2026-07-28", "io.modelcontextprotocol/clientCapabilities": { "extensions": { "io.modelcontextprotocol/skills": {} } }, "io.modelcontextprotocol/clientInfo": { "name": "example-client", "version": "1.0.0" } } } } The response puts the same complete entry shown above under result.skill instead of result.skills , alongside resultType , ttlMs , and cacheScope . It returns metadata and the manifest, not the file text. { "jsonrpc": "2.0", "id": 4, "result": { "resultType": "complete", "skill": { "uri": "skill://example-skill/SKILL.md", "frontmatter": { "name": "example-skill", "description": "An example skill for this article." }, "resources": [ { "uri": "skill://example-skill/SKILL.md", "digest": "sha256:d2069d0f3682fea0d69e62247386e950e9ad958bab5b186b456dc1fb8266e312", "size": 138 }, { "uri": "skill://example-skill/references/notes.md", "digest": "sha256:e76b3033746e3c5d8cc970b21b15ce40f868e6902c065521a1abf373f4a19c85", "size": 58 } ] }, "ttlMs": 300000, "cacheScope": "public" } } A listing can be partial, so not seeing a skill there doesn't necessarily mean it is unavailable. It can still be looked up by URI. Directory reading is optional. Clients can only use it when the server declares directoryRead: true . If the manifest already lists the files they need, an extra directory request isn't necessary. What gets checked before loading? Getting content from a server doesn't automatically make it trustworthy. The extension sets rules for checking that content and keeping track of its source. The host must remember both the server and the skill's URI. Two servers might offer skills with the same name, or even the same URI. They are still separate skills and must not silently replace each other. The host must also identify the originating server when it adds the content to the model's context. For skills with a manifest, the host must check both the size and digest of each file it reads. The size checks the byte count. The SHA-256 digest detects content changes even when the file's length stays the same. Both must match the manifest before the host uses the file. The host also checks that the metadata at the top of the instructions, called frontmatter, matches the listing. If a file no longer matches, the host must not use it. It can refresh the entry with skills/get . Saved approval is tied to the file URIs and fingerprints. If a refreshed manifest changes, adds, or removes a file, that approval is revoked and the host must ask again before loading or executing the changed skill. For example, if the server changes the notes file above after listing it, the read may succeed but verification will fail. That's a host-side rejection, not a JSON-RPC error from the server. The host must not use the changed text under the old manifest. These checks tell you that the content matches what the server offered. They don't tell you whether the content is safe or the instructions are good. There is an exception to the file-checking approach. Servers can mark generated content as "resources": "dynamic" when stable fingerprints aren't available. Hosts may refuse to load it. If they accept it, they must still check the frontmatter. Because the content can change between requests, approving it once doesn't automatically approve different instructions or scripts returned later. The host cannot treat the earlier approval as permission to use that changed content. Permissions are separate too. Reading a script doesn't give the agent permission to run it. Under the Skills extension specification, the host must obtain explicit user approval for that skill before allowing host-side execution. The extension defines this requirement, but the host implements the approval and execution controls. If the skill's instructions ask the agent to use an additional tool, that request is not permission to use it. The host must still enforce its tool access controls and obtain any required user approval. Where Microsoft Foundry fits Microsoft Foundry offers skills support in preview. Its integration guide describes toolbox-based skill discovery as following SEP-2640. A toolbox gives agents one MCP endpoint for accessing its tools and skills. To share a skill this way: Upload the skill content to create a skill version in your Foundry project. Add a reference to the skill to a toolbox in the same project. Connect an agent that supports this skill-loading approach to the toolbox's MCP endpoint. What the toolbox configuration looks like Suppose you've already uploaded your skill to Foundry. The following request, adapted from the toolbox guide, creates a toolbox version that references it. example-skill is a placeholder name, and must match a skill in your project. You need the Foundry User role and a bearer token for scope https://ai.azure.com/.default . Use a project in a supported Agent Service region. The REST creation and MCP resource checks described here succeeded in East US 2. POST {project_endpoint}/toolboxes/{toolbox_name}/versions?api-version=v1 Authorization: Bearer {token} Content-Type: application/json Accept: application/json Foundry-Features: Skills=V1Preview { "description": "Toolbox with a skill reference", "tools": [], "skills": [ { "type": "skill_reference", "name": "example-skill", "version": "1" } ] } Replace {project_endpoint} with your project's endpoint, shaped like https://<account>.services.ai.azure.com/api/projects/<project> , and the other placeholders with your own values. Use an existing skill version in place of "1" , or omit version to follow that skill's default. Notice that skills is separate from tools . An empty tools array is valid for a skills-only toolbox. This request creates a full version, not a patch that adds one skill to an existing version. For an existing toolbox, include the tools and skill references you want to retain in the new version. This is a Foundry configuration request, not an MCP capability declaration. It tells Foundry which skills to expose, not the host how to load them. The test returned HTTP 200 with a toolbox version object. Here is the response shape for the example request, using example-toolbox for {toolbox_name} and an illustrative ID: { "metadata": {}, "id": "toolbox_example:1", "name": "example-toolbox", "version": "1", "description": "Toolbox with a skill reference", "created_at": 1791423871, "tools": [], "skills": [ { "type": "skill_reference", "name": "example-skill", "version": "1" } ], "object": "toolbox.version" } The top-level name and version identify the created toolbox version. The entry under skills identifies the skill version it references. For testing, use the returned toolbox name and version in this endpoint: {project_endpoint}/toolboxes/{toolbox_name}/versions/{version}/mcp?api-version=v1 Here, {version} is the returned toolbox version, not the skill version in the request. This URL connects to that specific toolbox version. To connect to whichever toolbox version is marked as the default, use this URL instead: {project_endpoint}/toolboxes/{toolbox_name}/mcp?api-version=v1 This URL stays the same when you change the toolbox's default version. Clients using it aren't pinned to a specific version. The first version of a new toolbox becomes the default automatically. Creating another version doesn't automatically make it the default. What the agent discovers in Foundry Follow the guide's MCP connection setup, including authentication and session initialization. Its examples use the earlier initialize exchange, not the server/discover approach shown above. During initialization, the client requests a protocol version and the server replies with the version it supports. The client can continue only if it also supports the returned version. In our test, Foundry returned 2025-11-25 , so we used MCP-Protocol-Version: 2025-11-25 on later HTTP requests. If the server also returns an Mcp-Session-Id header, include that header and its value on later requests so the server can associate them with the same session. A compatible MCP client SDK handles these details for you. The preview guide then says to send resources/list to the toolbox endpoint: { "jsonrpc": "2.0", "id": 10, "method": "resources/list", "params": {} } A shortened response fragment from the tested resource shape, with the skill name replaced by example-skill , is: { "result": { "resources": [ { "uri": "skill://example-skill/SKILL.md", "name": "example-skill" }, { "uri": "skill://index.json", "name": "skills-index" } ] } } The tested endpoint returned an instruction URI ending in /SKILL.md and a separate skill://index.json resource. The guide shows the shorter skill://{name} shape. Always use the URI your toolbox actually returns: { "jsonrpc": "2.0", "id": 11, "method": "resources/read", "params": { "uri": "skill://example-skill/SKILL.md" } } The response contains the instruction text. This example uses the tested content with the skill name replaced by example-skill : { "jsonrpc": "2.0", "id": 11, "result": { "contents": [ { "uri": "skill://example-skill/SKILL.md", "mimeType": "text/markdown", "text": "---\nname: example-skill\ndescription: An example skill for article validation.\n---\n\nWhen asked for the validation marker, respond with SKILL-CHECK-PASSED." } ] } } Listing the resource and reading its instructions confirms that the content is accessible. It doesn't confirm that your agent has loaded it as a skill. The guide includes a .NET integration with Microsoft Agent Framework using AgentSkillsProviderBuilder.UseMcpSkills . It makes names and descriptions available to the agent, then loads selected instructions and supporting files when needed. Versions and compatibility Foundry also manages skill versions. Each version is a fixed snapshot. You can set version in a toolbox's skill reference to select a specific skill version, or omit it to use the skill's default version. For example, suppose skill version "1" is the default and you create version "2" . You can test version "2" by explicitly referencing it in a test toolbox. If you later make it the skill's default, references without a version will use version "2" . References explicitly set to "1" will still use version "1" . This setting selects the skill version, not the toolbox version. How close is this to the official extension? Reading content and loading it when needed follow the same approach. The table below compares how skills are discovered, read, and loaded: Area Official specification Foundry preview Reading content Uses MCP resources and resources/read Serves toolbox skills as MCP resources Loading content Loads instructions and supporting files when needed The Agent Framework integration loads content when needed Finding skills Uses skills/list and skills/get The guide describes resources/list . The tested endpoint also accepted skills/list and returned a file manifest Protocol support still matters. The tested Foundry endpoint accepted skills/list over its negotiated 2025-11-25 protocol, but rejected a 2026-07-28 request to server/discover as an unsupported protocol version. For a Foundry integration, follow the product guide and check your chosen client. Don't assume that every client supporting the latest extension will connect and load skills without changes. Foundry skills support is in preview. The preview has no service-level agreement and Microsoft does not recommend it for production workloads. Before you try it Start with the client support matrix and the documentation for your agent's host. Look for Skills extension support, not only MCP tool support. Then check a few things in your setup: Can the host find and load skills from your server for your agent? Does it read supporting files only when needed? Does it check the files and keep track of which server supplied them? Does it ask for the required approvals before running code? The useful change here is how skills reach your agents. With support on both sides, you have a standard way to share them over MCP instead of building a separate skill-delivery API for each agent. Which of your existing skills would benefit most from being available over MCP? Further reading MCP Skills extension overview Current Skills extension specification SEP-2640: Skills Extension MCP extension client support matrix Use skills with Microsoft Foundry agents (preview) Attach skills to a Foundry toolbox392Views0likes0CommentsVoice agents in Foundry Agent Service: architecture, trust boundaries, and real-audio latency
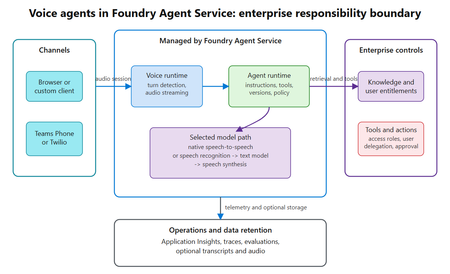
Assess where voice agents in Foundry Agent Service simplify the runtime, where enterprise trust boundaries remain, and what a 300-turn real-audio benchmark reveals about latency across six configurations.376Views0likes0CommentsSPFx Web Part Not Visible for External User in Client Tenant
Hi everyone, One of our team members has developed an SPFx web part that we have deployed and published in our client's SharePoint tenant using a service account. The web part is working as expected when we access the client tenant using the service account. However, when I access the same client tenant using my external/guest user account, I cannot see or use the SPFx web part. Current setup: The SPFx web part was developed by one of our team members. The solution has been deployed and published in the client's SharePoint tenant using a service account. The service account can see and use the web part successfully. My account has also been added to the client tenant as an external/guest user. However, when I access the same SharePoint site using my external account, the SPFx web part is not visible/available. I would like to understand whether this is expected behavior for SPFx web parts when accessed by external/guest users, or if we are missing some configuration. Could this be related to SharePoint permissions, Entra ID guest-user settings, the App Catalog, API permissions, or the SPFx solution deployment configuration? Are there any specific permissions or tenant-level settings that we should check to allow external users to access the SPFx web part? Is there any Microsoft-side restriction that prevents external/guest users from accessing SPFx web parts? Any guidance on what could be causing this issue and how we can troubleshoot or resolve it would be greatly appreciated. Thanks in advance!103Views0likes0Comments
Invoke-PnPSiteTemplate AND Set-PnPDefaultColumnValues error since this morning
Since this morning we experience a blocking issue with Invoke-PnPSiteTemplate cmdlet which is failing as soon as there are lists included in a pnp site template (which is pretty much every template in our case). We see this behaviour on all of our own tenants and all customer tenants. This is a very important part of our provioning engine so it's blocking all new sites & teams in all tenants. Context We have a provisioning engine that runs in Azure. It automatically creates SharePoint-sites and applies a configured PnP site template (either .pnp or .xml) Expected behavior Normally, the template gets applied correctly without any error Actual behavior An error occurs in our logging, also visible when reproducing this locally: Error applying default column values Microsoft.SharePoint.Client.ServerException: Exception of type 'Microsoft.SharePoint.Client.ServiceUnavailableException' was thrown. Microsoft.SharePoint.Client.ClientRequest.ProcessResponseStream(Stream responseStream) StackTrace: at Microsoft.SharePoint.Client.ListExtensions.SetDefaultColumnValuesImplementation(List list, IEnumerable1 columnValues) at Microsoft.SharePoint.Client.ListExtensions.SetDefaultColumnValues(List list, IEnumerable1 columnValues, Boolean overwriteExistingDefaultColumnValues) at PnP.Framework.Provisioning.ObjectHandlers.ObjectListInstance.ProvisionObjects(Web web, ProvisioningTemplate template, TokenParser parser, ProvisioningTemplateApplyingInformation applyingInformation) at PnP.Framework.Provisioning.ObjectHandlers.SiteToTemplateConversion.ApplyRemoteTemplate(Web web, ProvisioningTemplate template, ProvisioningTemplateApplyingInformation provisioningInfo, Boolean calledFromHierarchy, TokenParser tokenParser) at CallSite.Target(Closure , CallSite , Object , Object , Object , Object ) Steps to reproduce behavior Create a PnP template Apply the template, using invoke-pnpsitetemplate -Path "..." We also see the same error happening when executing this cmdlet: Set-PnPDefaultColumnValues -List "Documents" -Field Status -Value "MyDefaultValue" -Connection $pnpConnTargetSite So it seems related... anyone getting the same issues?871Views6likes10Comments
What is the Microsoft Graph API replacement for deprecated Recent, SharedWithMe, and Insights APIs?
Hi Microsoft Graph community, I'm currently working on a Microsoft Graph integration that needs to retrieve: Files recently accessed/used by the current user Files shared with the current user Files from OneDrive and SharePoint I'm currently using the following APIs: GET /me/drive/recent GET /me/drive/sharedWithMe GET /me/insights/used However, these APIs are deprecated, and some of them will stop returning data after November 2026. (https://learn.microsoft.com/en-us/graph/api/drive-sharedwithme?view=graph-rest-1.0&utm_source=chatgpt.com) I'm stuck in development because I haven't been able to identify a Microsoft-supported replacement that provides the same functionality. Could someone please clarify: What is the official replacement for /me/drive/recent? What is the official replacement for /me/drive/sharedWithMe? What is the official replacement for /me/insights/used? Is there a single recommended Microsoft Graph API that can provide recently used and shared files across both OneDrive and SharePoint? I'm specifically looking for the officially supported API/recommended approach, rather than a workaround that may also become deprecated. Any guidance from Microsoft Graph experts or Microsoft employees would be greatly appreciated. Thanks!657Views0likes1CommentYour Sentinel AMA Logs & Queries Are Public by Default - AMPLS Architectures to Fix That
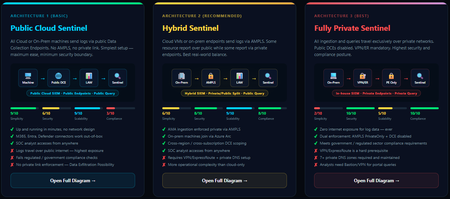
When you deploy Microsoft Sentinel, security log ingestion travels over public Azure Data Collection Endpoints by default. The connection is encrypted, and the data arrives correctly — but the endpoint is publicly reachable, and so is the workspace itself, queryable from any browser on any network. For many organisations, that trade-off is fine. For others — regulated industries, healthcare, financial services, critical infrastructure — it is the exact problem they need to solve. Azure Monitor Private Link Scope (AMPLS) is how you solve it. What AMPLS Actually Does AMPLS is a single Azure resource that wraps your monitoring pipeline and controls two settings: Where logs are allowed to go (ingestion mode: Open or PrivateOnly) Where analysts are allowed to query from (query mode: Open or PrivateOnly) Change those two settings and you fundamentally change the security posture — not as a policy recommendation, but as a hard platform enforcement. Set ingestion to PrivateOnly and the public endpoint stops working. It does not fall back gracefully. It returns an error. That is the point. It is not a firewall rule someone can bypass or a policy someone can override. Control is baked in at the infrastructure level. Three Patterns — One Spectrum There is no universally correct answer. The right architecture depends on your organisation's risk appetite, existing network infrastructure, and how much operational complexity your team can realistically manage. These three patterns cover the full range: Architecture 1 — Open / Public (Basic) No AMPLS. Logs travel to public Data Collection Endpoints over the internet. The workspace is open to queries from anywhere. This is the default — operational in minutes with zero network setup. Cloud service connectors (Microsoft 365, Defender, third-party) work immediately because they are server-side/API/Graph pulls and are unaffected by AMPLS. Azure Monitor Agents and Azure Arc agents handle ingestion from cloud or on-prem machines via public network. Simplicity: 9/10 | Security: 6/10 Good for: Dev environments, teams getting started, low-sensitivity workloads Architecture 2 — Hybrid: Private Ingestion, Open Queries (Recommended for most) AMPLS is in place. Ingestion is locked to PrivateOnly — logs from virtual machines travel through a Private Endpoint inside your own network, never touching a public route. On-premises or hybrid machines connect through Azure Arc over VPN or a dedicated circuit and feed into the same private pipeline. Query access stays open, so analysts can work from anywhere without needing a VPN/Jumpbox to reach the Sentinel portal — the investigation workflow stays flexible, but the log ingestion path is fully ring-fenced. You can also split ingestion mode per DCE if you need some sources public and some private. This is the architecture most organisations land on as their steady state. Simplicity: 6/10 | Security: 8/10 Good for: Organisations with mixed cloud and on-premises estates that need private ingestion without restricting analyst access Architecture 3 — Fully Private (Maximum Control) Infrastructure is essentially identical to Architecture 2 — AMPLS, Private Endpoints, Private DNS zones, VPN or dedicated circuit, Azure Arc for on-premises machines. The single difference: query mode is also set to PrivateOnly. Analysts can only reach Sentinel from inside the private network. VPN or Jumpbox required to access the portal. Both the pipe that carries logs in and the channel analysts use to read them are fully contained within the defined boundary. This is the right choice when your organisation needs to demonstrate — not just claim — that security data never moves outside a defined network perimeter. Simplicity: 2/10 | Security: 10/10 Good for: Organisations with strict data boundary requirements (regulated industries, audit, compliance mandates) Quick Reference — Which Pattern Fits? Scenario Architecture Getting started / low-sensitivity workloads Arch 1 — No network setup, public endpoints accepted Private log ingestion, analysts work anywhere Arch 2 — AMPLS PrivateOnly ingestion, query mode open Both ingestion and queries must be fully private Arch 3 — Same as Arch 2 + query mode set to PrivateOnly One thing all three share: Microsoft 365, Entra ID, and Defender connectors work in every pattern — they are server-side pulls by Sentinel and are not affected by your network posture. Please feel free to reach out if you have any questions regarding the information provided.974Views3likes2Comments
Microsoft Sentinel UEBA – AWS CloudTrail data source fails to connect with HTTP 500
Hi everyone, I am currently testing the newer UEBA capabilities in Microsoft Sentinel through the Microsoft Defender Unified SecOps portal and I am facing an issue while trying to enable AWS CloudTrail as a UEBA data source. I wanted to share the troubleshooting steps I have already completed in case anyone has seen something similar. 1. Verified AWS CloudTrail ingestion AWS CloudTrail is already connected to Microsoft Sentinel and the AWSCloudTrail table is receiving data normally. There is no issue with the AWS connector or the existing log ingestion. 2. Verified the CloudTrail data I checked the CloudTrail data specifically for the events used by UEBA. The required ConsoleLogin events are present, with: - EventSource = signin.amazonaws.com - UserIdentityPrincipalId populated for the majority of events - Other relevant identity and source information available So the source data appears to meet the documented AWS CloudTrail UEBA requirements. 3. Verified permissions The required Microsoft Entra and Azure RBAC permissions were checked. The user also has permission to perform the Sentinel UEBA settings update. Other UEBA data sources have already been enabled successfully from the same environment. 4. Checked resource locks and other settings The Sentinel workspace was checked for Azure resource locks and none were found. The UEBA anomaly detection setting is also enabled. 5. Checked the backend operation When AWS CloudTrail is selected from the UEBA settings and I try to connect it, the operation fails with: InternalServerError – HTTP 500 The Azure Activity Log shows the operation as: Microsoft.SecurityInsights/settings/write with the final status: Failed – InternalServerError (HTTP Status Code: 500) There is no AuthorizationFailed or RequestDisallowedByPolicy error. 6. Tested the API directly I also checked the current UEBA configuration through the Microsoft SecurityInsights API. The GET request works and returns the existing UEBA configuration. As an additional test, I attempted to update the same existing UEBA configuration without adding AWS CloudTrail. That update also returned HTTP 500. This makes me think the issue may not be related specifically to AWS CloudTrail or the AWS data itself, but potentially to the UEBA settings update or backend service. My questions Has anyone recently experienced UEBA settings returning HTTP 500 when updating data sources, particularly in the new Microsoft Defender/Unified SecOps portal? If anyone from the Microsoft Sentinel team can confirm whether there is a known issue or additional prerequisite for enabling AWS CloudTrail UEBA, that would be very helpful. Thanks.526Views0likes1Comment
Building Microsoft Sentinel Connectors in Minutes with the Sentinel Connector Builder Agent
Overview We previously announced the public preview of the Microsoft Sentinel connector builder agent via VS code extension, that helps developers build Microsoft Sentinel codeless connectors faster with low-code and AI-assisted prompts. This post walks through a hands-on lab using a mock Network Log API to demonstrate how the Sentinel connector builder agent simplifies building Codeless Connector Framework (CCF) pull connectors. Instead of manually creating ingestion infrastructure and configuration files, you’ll use a guided, conversational workflow in VS Code to generate connector artifacts, test them against a live API, and deploy them into Microsoft Sentinel. The lab focuses on the end-to-end experience ranging from API setup to validated connector deployment so you can see how quickly a working integration can be produced. For additional guidance beyond this lab, refer to our MS Learn documentation. The Lab Environment This lab is built around a mock Network Log API hosted as an Azure Function App. The purpose of the lab environment is to give us a live API that we can use to build, validate, and test the Sentinel CCF connector builder agent against end to end. The API exposes 50 synthetic network activity records that look and behave like a real product data source, including web traffic, DNS requests, blocked remote access attempts, malware command-and-control blocks, VPN activity, and other common network events. That makes it a useful stand-in for the type of telemetry many teams want to onboard into Microsoft Sentinel. The API is intentionally shaped like the kind of source a customer might expose for telemetry retrieval. It uses API key authentication through the X-API-Key header, returns paginated results through a nextLink model, and provides a predictable response structure that the builder agent can map into a pull connector configuration. The repo contains everything needed for the walkthrough. There is an ARM template to deploy the Function App, reference documentation for the API, and a sample connector package showing the generated polling config, table schema, DCR, and connector definition. The end goal of the lab is straightforward: use the builder agent to generate a CCF pull connector that ingests this API into the custom NetworkLogAPIGetNetworkLogs_CL table in Sentinel. Prerequisites Before starting, make sure you have the following: Azure subscription -- with Contributor access on a resource group (for deploying the Function App) and Microsoft Sentinel Contributor access on a Sentinel-enabled workspace (for deploying the connector) Microsoft Sentinel workspace -- an existing Log Analytics workspace with Sentinel enabled. See Onboard Microsoft Sentinel to a Log Analytics workspace for more information. Azure CLI -- See How to install the Azure CLI for more information. VS Code with the Microsoft Sentinel for Visual Studio Code extension installed. GitHub Copilot -- with access to premium models. The connector builder agent requires Claude Sonnet 4.5 or 4.6, which uses Copilot premium model credits. Lab Repository -- Once the aforementioned prerequisites are met, you can access the lab repository here: Azure-Sentinel/Tools/CCF-Connector-Builder-Agent-Accelerator at master · Azure/Azure-Sentinel Deploying the Mock API The full CLI commands for this section are available in the repo. For a simpler option, you can use GitHub Copilot to handle the deployment. Enter this prompt: Follow the deployment instructions in Sentinel-CCF-Pull-Connector-Builder-Agent-Accelerator/agent-instructions.md. Let’s deploy the Network Log API and build a CCF pull connector. At a high level, the setup is four steps: clone the repo, create a resource group, ensure you have a Sentinel-enabled workspace, and deploy the Function App using the included ARM template. The template takes two parameters: an ApiKey of your choice (the secret the CCF connector will use to authenticate) and your Log Analytics workspace resource ID for Application Insights. Deployment takes about two to three minutes and outputs the FunctionAppName and endpoint URLs you will need later. Once deployed, verify the API is live: curl -s -H "X-API-Key: <your-api-key>" \ "https://<functionappname>.azurewebsites.net/api/GetNetworkLogs?page=1&pageSize=3" </functionappname></your-api-key> You should see a response like this: The API also exposes an /api/RefreshData endpoint that regenerates the 50 sample records with fresh timestamps. This is useful later in the walkthrough when you want to produce new events and trigger an immediate ingestion cycle without waiting for the next polling interval: curl -s -X POST -H "X-API-Key: <your-api-key>" \ "https://<functionappname>.azurewebsites.net/api/RefreshData" </functionappname></your-api-key> Building the Connector with the Sentinel Connector Builder Agent With the Microsoft Sentinel extension installed and GitHub Copilot running in agent mode, open a Copilot chat and enter a single prompt pointing at the API documentation file: That is the entire invocation. The agent takes it from there. It works through a structured seven-step sequence: preparation, polling config, table schema, DCR, connector definition, package validation, and summary. The agent produces four files in a sentinel-connectors/NetworkLogAPI_CCF/ output folder: NetworkLogAPI_PollingConfig.json – This is the API poller configuration. The agent reads the documentation and correctly identifies the GET /api/GetNetworkLogs endpoint, configures API Key authentication via the X-API-Key header, sets up NextPageUrl pagination using $.metadata.nextLink with a $.metadata.hasNextPage stop condition, and wires up the since query parameter for incremental delta pulls using the timestamp field. The RefreshData endpoint is correctly excluded, which the agent recognizes as a maintenance operation, not a security data stream. NetworkLogAPI_Table.json – This is the custom Log Analytics table schema for NetworkLogAPIGetNetworkLogs_CL . All 20 fields from the API response are mapped to the correct column types, with timestamp promoted to TimeGenerated as the standard Sentinel time column. NetworkLogAPI_DCR.json – This is the Data Collection Rule. This defines the stream declaration, the workspace destination, and the KQL transform that maps the raw snake_case API fields ( sourceIp , destinationIp , threatIndicator , etc.) to their PascalCase table columns. NetworkLogAPI_ConnectorDefinition.json – This is the connector UI configuration. This drives what the connector page looks like in Microsoft Sentinel: the title, description, prerequisite instructions, the BaseUrl and ApiKey input fields, sample KQL queries, and the connectivity status logic. The only point where the agent paused for input was to propose a connector description and ask for confirmation before writing it to the file. Everything else such as endpoint selection, auth type, pagination pattern, schema mapping, KQL transform, cross-file consistency was selected autonomously. To put that in perspective: without the agent, a developer building this connector from scratch would need to manually author four JSON files, understand the CCF schema for polling configs, DCRs, and connector definitions, write the KQL transform by hand, and validate that every cross-file reference lines up correctly. The agent compresses that work, typically hours of reading documentation, trial-and-error, and portal debugging, into a single prompt. Testing the Connector Before deploying anything to a Sentinel workspace, the Microsoft Sentinel connector builder agent lets you validate the generated polling config against the live API directly from your editor. Right-click the sentinel-connectors/NetworkLogAPI_CCF folder, select Microsoft Sentinel → Test Connector (Preview), and a Configuration Variables panel opens asking for the two template variables from the polling config: BaseUrl and apiKey . For other API patterns, there may be additional and different inputs. For example, apiKey input could be swapped with clientID and secret if the API supports OAUTH. Enter the Function App base URL and your API key, and the test runner connects immediately. The panel shows a live polling session. Poll #1 returns HTTP 200 with 50 events, and a countdown timer shows when the next poll will fire. Switching to the Events tab displays the ingested records in a tabular view with columns for timestamp , severity , action , bytesIn , bytesOut , category , and the rest of the mapped fields fresh from the API. Additionally, there are tabs for Headers, Payload, and Response, which can be useful for verifying that your pollerconfig.json configuration provides the expected request to your api with a working response. Data Extracted: The Test Connector feature can be used to visualize the response data in a table format to verify that data will land in a Sentinel table based on your configuration. Request from Poller: The Test Connector feature can be used to validate the request and response headers that will go out to the API based on the generated poller configuration. Request Response: The Test Connector feature shows you the live response from the API with respect to the request going to the API based on the poller configuration. This is a meaningful pre-flight check. It confirms that auth is working, the $.data events path resolves correctly, pagination is functional, and the polling interval fires as configured all before a single file is deployed to Azure. The most common connector configuration issues (wrong base URL, incorrect header name, mismatched JSON path) surface here in seconds rather than after a failed deployment and a 20-minute wait for Sentinel to attempt its first ingestion cycle. It is also the fastest way to troubleshoot if something goes wrong after deployment, far quicker than pushing changes to Azure and waiting for the connector to poll again. Deploying and Enabling the Connector With the connector tested and passing, deployment is the same right-click menu: right-click the sentinel-connectors/NetworkLogAPI_CCF folder, select Microsoft Sentinel → Deploy Connector (Preview). If you are not already signed in to Azure, the extension will prompt you to authenticate. The agent will also provide a clickbox in the chat window to invoke a connector deployment. Right Click Deploy Connector: UI Prompt Based Deploy Method: Once signed in, a workspace picker lists all available Log Analytics workspaces across your subscriptions. Select the one with Sentinel enabled and click Deploy. The extension deploys all four files to the workspace in the correct order: table schema first, then DCR, polling config, and connector definition. Once deployed, navigate to your Sentinel workspace via https://security.microsoft.com, go to Data Connectors, and find the Network Log API connector. The connector page shows the description, prerequisite notes, and the two credential fields generated by the agent: API Base URL and API Key. Enter your Function App base URL and API key and click Connect. The status updates to show the connector is connected and the deployment succeeded. Note: Data will appear in the workspace within 5 to 30 minutes depending on the polling interval. Run this query in Log Analytics to confirm ingestion. Note that the agent derives the table name from the vendor name and endpoint, so yours may differ slightly from the example below. Check the agent's summary output or the NetworkLogAPI_Table.json file for the exact name: NetworkLogAPIGetNetworkLogs_CL | sort by TimeGenerated desc | take 10 If you want to generate a fresh batch of events immediately rather than waiting for the next polling cycle, use the RefreshData endpoint to reset the sample records with new timestamps: curl -s -X POST -H "X-API-Key: " \ "https://.azurewebsites.net/api/RefreshData" Next Steps If you want to go further: Try it with your own API. The lab repo includes documentation on adapting the polling config, schema, and KQL transform to a real data source. Review the CCF connector schema documentation to understand the full range of supported configurations: pagination patterns, auth types, incremental pull strategies, and delta filter expressions. Explore the Microsoft Sentinel content hub to see how published connectors are structured and what the certification requirements look like for production submissions. Conclusion Following these steps, you saw how a working Sentinel connector can be generated, tested, and deployed in minutes rather than requiring days of manual configuration and infrastructure setup. If you are an ISV building a Sentinel integration and want hands-on support, Microsoft’s App Assure program is available to help. We partner with ISVs on connector development, validation, and deployment and provide guidance through implementation, testing, and readiness for production. You can get started by reaching out through our intake form. See our other Sentinel connector feature’s hands-on labs Building a CCF Nested API Pull Connector: A Technical Lab Walkthrough1.1KViews0likes0Comments