analytics
195 TopicsIntroducing the Microsoft Sentinel ASIM EmailEvent schema
Email remains one of the most common entry points for security threats. Yet email products often describe the same activity with different table names, fields, and values. This makes it harder to build detections and investigations that work consistently across data sources. The Microsoft Sentinel Advanced Security Information Model, or ASIM, EmailEvent schema is now available. It provides a common structure for email delivery and inspection events, helping customers and partners create security content that works across supported email data sources. A consistent view of email security activity EmailEvent standardizes the information analysts need to understand what happened to an email and why. It covers: Email delivery and inspection events Sender, source, and recipient information Message subject, size, direction, and delivery location URLs and file attachments SPF, DKIM, and DMARC authentication results Delivery actions such as delivered, blocked, quarantined, or deleted Threat, risk, confidence, tactic, technique, and remediation details Instead of learning a different data model for every product, analysts can query the normalized EmailEvent fields. Parser developers map each source's native data to the same schema. How it works Consider an email that contains a suspicious attachment. The email security product records the sender, recipients, attachment, authentication results, inspection verdict, and final action. A connector collects that event. A parser or Data Collection Rule maps the source fields to EmailEvent. Microsoft Sentinel can then query the normalized record using the same field names used for other supported email sources. This common structure separates security content from the details of a specific product. When another source adds an EmailEvent parser, existing source-independent queries and detections can work with that source without being rewritten around its native field names. Why it matters Simpler analytics: Write queries against one consistent set of email fields. Broader coverage: Apply source-independent security content across normalized email sources. Faster investigations: Compare delivery, authentication, attachment, URL, and threat details without translating different data models. Easier integration: Give connector and parser developers a defined contract for bringing new email telemetry into ASIM. EmailEvent does not replace the rich native data produced by email security products. It provides a consistent security layer that makes that data easier to use together. Build on EmailEvent The EmailEvent release includes the schema definition, source-independent parser framework, filtering parser, deployment templates, and validation support in the Azure-Sentinel repository. The schema version is 1.0.0. Customers can use normalized EmailEvent data to develop hunting queries, analytics rules, workbooks, and investigation experiences. Partners and community contributors can create source-specific parsers that map their email data to the schema. Get started Normalization Email Schema MS Learn Learn about normalization and ASIM Explore the EmailEvent implementation in Azure-Sentinel Deploy ASIM parsers Thank you to the ASIM engineering and partner teams who contributed to the schema, deployment path, validation, and release.849Views1like0CommentsYour Sentinel AMA Logs & Queries Are Public by Default - AMPLS Architectures to Fix That
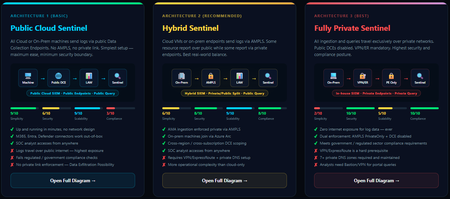
When you deploy Microsoft Sentinel, security log ingestion travels over public Azure Data Collection Endpoints by default. The connection is encrypted, and the data arrives correctly — but the endpoint is publicly reachable, and so is the workspace itself, queryable from any browser on any network. For many organisations, that trade-off is fine. For others — regulated industries, healthcare, financial services, critical infrastructure — it is the exact problem they need to solve. Azure Monitor Private Link Scope (AMPLS) is how you solve it. What AMPLS Actually Does AMPLS is a single Azure resource that wraps your monitoring pipeline and controls two settings: Where logs are allowed to go (ingestion mode: Open or PrivateOnly) Where analysts are allowed to query from (query mode: Open or PrivateOnly) Change those two settings and you fundamentally change the security posture — not as a policy recommendation, but as a hard platform enforcement. Set ingestion to PrivateOnly and the public endpoint stops working. It does not fall back gracefully. It returns an error. That is the point. It is not a firewall rule someone can bypass or a policy someone can override. Control is baked in at the infrastructure level. Three Patterns — One Spectrum There is no universally correct answer. The right architecture depends on your organisation's risk appetite, existing network infrastructure, and how much operational complexity your team can realistically manage. These three patterns cover the full range: Architecture 1 — Open / Public (Basic) No AMPLS. Logs travel to public Data Collection Endpoints over the internet. The workspace is open to queries from anywhere. This is the default — operational in minutes with zero network setup. Cloud service connectors (Microsoft 365, Defender, third-party) work immediately because they are server-side/API/Graph pulls and are unaffected by AMPLS. Azure Monitor Agents and Azure Arc agents handle ingestion from cloud or on-prem machines via public network. Simplicity: 9/10 | Security: 6/10 Good for: Dev environments, teams getting started, low-sensitivity workloads Architecture 2 — Hybrid: Private Ingestion, Open Queries (Recommended for most) AMPLS is in place. Ingestion is locked to PrivateOnly — logs from virtual machines travel through a Private Endpoint inside your own network, never touching a public route. On-premises or hybrid machines connect through Azure Arc over VPN or a dedicated circuit and feed into the same private pipeline. Query access stays open, so analysts can work from anywhere without needing a VPN/Jumpbox to reach the Sentinel portal — the investigation workflow stays flexible, but the log ingestion path is fully ring-fenced. You can also split ingestion mode per DCE if you need some sources public and some private. This is the architecture most organisations land on as their steady state. Simplicity: 6/10 | Security: 8/10 Good for: Organisations with mixed cloud and on-premises estates that need private ingestion without restricting analyst access Architecture 3 — Fully Private (Maximum Control) Infrastructure is essentially identical to Architecture 2 — AMPLS, Private Endpoints, Private DNS zones, VPN or dedicated circuit, Azure Arc for on-premises machines. The single difference: query mode is also set to PrivateOnly. Analysts can only reach Sentinel from inside the private network. VPN or Jumpbox required to access the portal. Both the pipe that carries logs in and the channel analysts use to read them are fully contained within the defined boundary. This is the right choice when your organisation needs to demonstrate — not just claim — that security data never moves outside a defined network perimeter. Simplicity: 2/10 | Security: 10/10 Good for: Organisations with strict data boundary requirements (regulated industries, audit, compliance mandates) Quick Reference — Which Pattern Fits? Scenario Architecture Getting started / low-sensitivity workloads Arch 1 — No network setup, public endpoints accepted Private log ingestion, analysts work anywhere Arch 2 — AMPLS PrivateOnly ingestion, query mode open Both ingestion and queries must be fully private Arch 3 — Same as Arch 2 + query mode set to PrivateOnly One thing all three share: Microsoft 365, Entra ID, and Defender connectors work in every pattern — they are server-side pulls by Sentinel and are not affected by your network posture. Please feel free to reach out if you have any questions regarding the information provided.1.1KViews3likes2Comments
Building Microsoft Sentinel Connectors in Minutes with the Sentinel Connector Builder Agent
Overview We previously announced the public preview of the Microsoft Sentinel connector builder agent via VS code extension, that helps developers build Microsoft Sentinel codeless connectors faster with low-code and AI-assisted prompts. This post walks through a hands-on lab using a mock Network Log API to demonstrate how the Sentinel connector builder agent simplifies building Codeless Connector Framework (CCF) pull connectors. Instead of manually creating ingestion infrastructure and configuration files, you’ll use a guided, conversational workflow in VS Code to generate connector artifacts, test them against a live API, and deploy them into Microsoft Sentinel. The lab focuses on the end-to-end experience ranging from API setup to validated connector deployment so you can see how quickly a working integration can be produced. For additional guidance beyond this lab, refer to our MS Learn documentation. The Lab Environment This lab is built around a mock Network Log API hosted as an Azure Function App. The purpose of the lab environment is to give us a live API that we can use to build, validate, and test the Sentinel CCF connector builder agent against end to end. The API exposes 50 synthetic network activity records that look and behave like a real product data source, including web traffic, DNS requests, blocked remote access attempts, malware command-and-control blocks, VPN activity, and other common network events. That makes it a useful stand-in for the type of telemetry many teams want to onboard into Microsoft Sentinel. The API is intentionally shaped like the kind of source a customer might expose for telemetry retrieval. It uses API key authentication through the X-API-Key header, returns paginated results through a nextLink model, and provides a predictable response structure that the builder agent can map into a pull connector configuration. The repo contains everything needed for the walkthrough. There is an ARM template to deploy the Function App, reference documentation for the API, and a sample connector package showing the generated polling config, table schema, DCR, and connector definition. The end goal of the lab is straightforward: use the builder agent to generate a CCF pull connector that ingests this API into the custom NetworkLogAPIGetNetworkLogs_CL table in Sentinel. Prerequisites Before starting, make sure you have the following: Azure subscription -- with Contributor access on a resource group (for deploying the Function App) and Microsoft Sentinel Contributor access on a Sentinel-enabled workspace (for deploying the connector) Microsoft Sentinel workspace -- an existing Log Analytics workspace with Sentinel enabled. See Onboard Microsoft Sentinel to a Log Analytics workspace for more information. Azure CLI -- See How to install the Azure CLI for more information. VS Code with the Microsoft Sentinel for Visual Studio Code extension installed. GitHub Copilot -- with access to premium models. The connector builder agent requires Claude Sonnet 4.5 or 4.6, which uses Copilot premium model credits. Lab Repository -- Once the aforementioned prerequisites are met, you can access the lab repository here: Azure-Sentinel/Tools/CCF-Connector-Builder-Agent-Accelerator at master · Azure/Azure-Sentinel Deploying the Mock API The full CLI commands for this section are available in the repo. For a simpler option, you can use GitHub Copilot to handle the deployment. Enter this prompt: Follow the deployment instructions in Sentinel-CCF-Pull-Connector-Builder-Agent-Accelerator/agent-instructions.md. Let’s deploy the Network Log API and build a CCF pull connector. At a high level, the setup is four steps: clone the repo, create a resource group, ensure you have a Sentinel-enabled workspace, and deploy the Function App using the included ARM template. The template takes two parameters: an ApiKey of your choice (the secret the CCF connector will use to authenticate) and your Log Analytics workspace resource ID for Application Insights. Deployment takes about two to three minutes and outputs the FunctionAppName and endpoint URLs you will need later. Once deployed, verify the API is live: curl -s -H "X-API-Key: <your-api-key>" \ "https://<functionappname>.azurewebsites.net/api/GetNetworkLogs?page=1&pageSize=3" </functionappname></your-api-key> You should see a response like this: The API also exposes an /api/RefreshData endpoint that regenerates the 50 sample records with fresh timestamps. This is useful later in the walkthrough when you want to produce new events and trigger an immediate ingestion cycle without waiting for the next polling interval: curl -s -X POST -H "X-API-Key: <your-api-key>" \ "https://<functionappname>.azurewebsites.net/api/RefreshData" </functionappname></your-api-key> Building the Connector with the Sentinel Connector Builder Agent With the Microsoft Sentinel extension installed and GitHub Copilot running in agent mode, open a Copilot chat and enter a single prompt pointing at the API documentation file: That is the entire invocation. The agent takes it from there. It works through a structured seven-step sequence: preparation, polling config, table schema, DCR, connector definition, package validation, and summary. The agent produces four files in a sentinel-connectors/NetworkLogAPI_CCF/ output folder: NetworkLogAPI_PollingConfig.json – This is the API poller configuration. The agent reads the documentation and correctly identifies the GET /api/GetNetworkLogs endpoint, configures API Key authentication via the X-API-Key header, sets up NextPageUrl pagination using $.metadata.nextLink with a $.metadata.hasNextPage stop condition, and wires up the since query parameter for incremental delta pulls using the timestamp field. The RefreshData endpoint is correctly excluded, which the agent recognizes as a maintenance operation, not a security data stream. NetworkLogAPI_Table.json – This is the custom Log Analytics table schema for NetworkLogAPIGetNetworkLogs_CL . All 20 fields from the API response are mapped to the correct column types, with timestamp promoted to TimeGenerated as the standard Sentinel time column. NetworkLogAPI_DCR.json – This is the Data Collection Rule. This defines the stream declaration, the workspace destination, and the KQL transform that maps the raw snake_case API fields ( sourceIp , destinationIp , threatIndicator , etc.) to their PascalCase table columns. NetworkLogAPI_ConnectorDefinition.json – This is the connector UI configuration. This drives what the connector page looks like in Microsoft Sentinel: the title, description, prerequisite instructions, the BaseUrl and ApiKey input fields, sample KQL queries, and the connectivity status logic. The only point where the agent paused for input was to propose a connector description and ask for confirmation before writing it to the file. Everything else such as endpoint selection, auth type, pagination pattern, schema mapping, KQL transform, cross-file consistency was selected autonomously. To put that in perspective: without the agent, a developer building this connector from scratch would need to manually author four JSON files, understand the CCF schema for polling configs, DCRs, and connector definitions, write the KQL transform by hand, and validate that every cross-file reference lines up correctly. The agent compresses that work, typically hours of reading documentation, trial-and-error, and portal debugging, into a single prompt. Testing the Connector Before deploying anything to a Sentinel workspace, the Microsoft Sentinel connector builder agent lets you validate the generated polling config against the live API directly from your editor. Right-click the sentinel-connectors/NetworkLogAPI_CCF folder, select Microsoft Sentinel → Test Connector (Preview), and a Configuration Variables panel opens asking for the two template variables from the polling config: BaseUrl and apiKey . For other API patterns, there may be additional and different inputs. For example, apiKey input could be swapped with clientID and secret if the API supports OAUTH. Enter the Function App base URL and your API key, and the test runner connects immediately. The panel shows a live polling session. Poll #1 returns HTTP 200 with 50 events, and a countdown timer shows when the next poll will fire. Switching to the Events tab displays the ingested records in a tabular view with columns for timestamp , severity , action , bytesIn , bytesOut , category , and the rest of the mapped fields fresh from the API. Additionally, there are tabs for Headers, Payload, and Response, which can be useful for verifying that your pollerconfig.json configuration provides the expected request to your api with a working response. Data Extracted: The Test Connector feature can be used to visualize the response data in a table format to verify that data will land in a Sentinel table based on your configuration. Request from Poller: The Test Connector feature can be used to validate the request and response headers that will go out to the API based on the generated poller configuration. Request Response: The Test Connector feature shows you the live response from the API with respect to the request going to the API based on the poller configuration. This is a meaningful pre-flight check. It confirms that auth is working, the $.data events path resolves correctly, pagination is functional, and the polling interval fires as configured all before a single file is deployed to Azure. The most common connector configuration issues (wrong base URL, incorrect header name, mismatched JSON path) surface here in seconds rather than after a failed deployment and a 20-minute wait for Sentinel to attempt its first ingestion cycle. It is also the fastest way to troubleshoot if something goes wrong after deployment, far quicker than pushing changes to Azure and waiting for the connector to poll again. Deploying and Enabling the Connector With the connector tested and passing, deployment is the same right-click menu: right-click the sentinel-connectors/NetworkLogAPI_CCF folder, select Microsoft Sentinel → Deploy Connector (Preview). If you are not already signed in to Azure, the extension will prompt you to authenticate. The agent will also provide a clickbox in the chat window to invoke a connector deployment. Right Click Deploy Connector: UI Prompt Based Deploy Method: Once signed in, a workspace picker lists all available Log Analytics workspaces across your subscriptions. Select the one with Sentinel enabled and click Deploy. The extension deploys all four files to the workspace in the correct order: table schema first, then DCR, polling config, and connector definition. Once deployed, navigate to your Sentinel workspace via https://security.microsoft.com, go to Data Connectors, and find the Network Log API connector. The connector page shows the description, prerequisite notes, and the two credential fields generated by the agent: API Base URL and API Key. Enter your Function App base URL and API key and click Connect. The status updates to show the connector is connected and the deployment succeeded. Note: Data will appear in the workspace within 5 to 30 minutes depending on the polling interval. Run this query in Log Analytics to confirm ingestion. Note that the agent derives the table name from the vendor name and endpoint, so yours may differ slightly from the example below. Check the agent's summary output or the NetworkLogAPI_Table.json file for the exact name: NetworkLogAPIGetNetworkLogs_CL | sort by TimeGenerated desc | take 10 If you want to generate a fresh batch of events immediately rather than waiting for the next polling cycle, use the RefreshData endpoint to reset the sample records with new timestamps: curl -s -X POST -H "X-API-Key: " \ "https://.azurewebsites.net/api/RefreshData" Next Steps If you want to go further: Try it with your own API. The lab repo includes documentation on adapting the polling config, schema, and KQL transform to a real data source. Review the CCF connector schema documentation to understand the full range of supported configurations: pagination patterns, auth types, incremental pull strategies, and delta filter expressions. Explore the Microsoft Sentinel content hub to see how published connectors are structured and what the certification requirements look like for production submissions. Conclusion Following these steps, you saw how a working Sentinel connector can be generated, tested, and deployed in minutes rather than requiring days of manual configuration and infrastructure setup. If you are an ISV building a Sentinel integration and want hands-on support, Microsoft’s App Assure program is available to help. We partner with ISVs on connector development, validation, and deployment and provide guidance through implementation, testing, and readiness for production. You can get started by reaching out through our intake form. See our other Sentinel connector feature’s hands-on labs Building a CCF Nested API Pull Connector: A Technical Lab Walkthrough1.3KViews0likes0CommentsSentinel Foundry - MCP Server (Github Community Release)
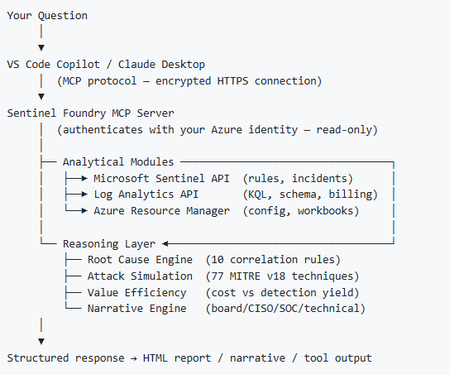
I’ve been cooking something that a lot of people in SOC have been struggling with — especially on the engineering side of Microsoft Sentinel. Thanks to the Microsoft Security team for shaping the capabilities of Sentinel even better with Sentinel Data Lake & Modern SecOps. Today’s the day I can finally share it. Note: This is not an official Microsoft product, but it is designed to make the Sentinel Build even better (complement) with much more intelligence. 🚀 Sentinel Foundry is now in public preview with 43 tools. (Sentinel Foundry - MCP Server) It’s an MCP server built to act like the brain of a strong Sentinel engineer — helping make building, improving, and operating Sentinel far more practical, faster, and honestly more enjoyable. For a lot of teams, the challenge is not understanding what Sentinel can do. The hard part is the engineering work around it: -> Deciding what data should actually be ingested -> Building a clean, scalable Sentinel foundation -> Writing useful detections instead of noisy ones -> Balancing security value with cost -> Turning ideas into deployable engineering outputs That is exactly why I built Sentinel Foundry to help communities grow stronger. It helps with the real engineering tasks behind Sentinel — from architecture thinking to detection design, deployment planning, ingestion strategy, automation ideas, and many of the workflows outlined in the GitHub project. How does it work? Here’s one of the flagship prompts I ran with it: “Give me a complete security posture report for our workspace. Score each pillar and tell me what to prioritise.” And within seconds, it produced a structured engineering blueprint that would normally take a lot longer to pull together manually. You can see the example prompts here in what it can do: https://github.com/prabhukiranveesam/Sentinel-Foundry#what-can-it-do I want building Sentinel to feel less like repetitive engineering overhead — and more like real security engineering that is fast, creative, and enjoyable. If you work with Sentinel as a SOC L2 analyst, engineer, detection engineer, consultant, or architect, I’d genuinely love for you to try it and tell me what you think. 🔗 Public Preview: https://github.com/prabhukiranveesam/Sentinel-Foundry This is just the start of an AI era — and I’m excited to keep shaping it with more powerful features over the coming days. This is very easy to set up and will be available to all of you at no cost during this month as part of the public preview, and your feedback is extremely valuable to shape this as a powerful solution.1.3KViews0likes2CommentsSentinel - Defender XDR KQL Queries Library
Hello all, I’ve been building something over the past few weeks that I think the security community might find useful. https://goxdr.fyi is a searchable KQL query library for Microsoft Sentinel and Defender XDR. The name comes from a nickname my colleagues gave me (GoX) combined with XDR. I also picked up https://goxdr.fyi as a short and easy to remember domain for it. You can check it out here: https://goxdr.fyi The idea came from my own day to day work as someone working in IAM and SOC operations. I constantly find myself writing and refining KQL queries for threat hunting, detection engineering and incident investigation. Over time I realized I had a growing collection of queries that I kept going back to and I thought why not make these available to others? It currently has 117 queries covering identity security, BEC/AiTM detection, NTLM and LDAP attack hunting, OAuth governance, AI/Copilot security, Sentinel alert trending, SOC performance metrics and more. Some of these queries are ones I wrote from scratch based on real scenarios I encountered in production environments. Others are community queries I tested and validated in my own setup. Only the ones I found genuinely useful and that actually worked against real data made it in. Each query comes with a description explaining what it detects and why it matters, along with severity levels, platform tags (Sentinel, XDR or both) and a copy button so you can paste it directly into Advanced Hunting or use it as the basis for an Analytics Rule. The site is open source, hosted on GitHub Pages and licensed under CC BY 4.0. No sign-up, no paywall, no tracking. The source is available. I’ll keep adding queries as new scenarios come up. If there’s enough interest I’m also considering adding Cortex XQL queries for Palo Alto environments. Suggestions, feedback or ideas for new detections are always welcome. Feel free to reach out. Thanks367Views0likes0Comments
SentinelHealth: Scheduled Rule Retry Logging Does Not Match Docs
## Objective I am working on a health checks architecture for Microsoft Sentinel analytic rules. The goal is to build a set of monitoring queries/approaches that cover rule execution failures, configuration issues (entity mapping, partial success), rule audit tracking, and auto-disabled rule detection. ## My Current Approach So far I have built monitoring for the following areas using the SentinelHealth and SentinelAudit tables: - Scheduled rule window failures (retry exhaustion) - NRT rule execution delays (cumulative delay over 25 minutes) - Partial success and configuration issues (entity mapping drops, alert size limits, semantic errors) with transient error codes filtered out - Auto-disabled rules detection - Rule disable/delete audit tracking via SentinelAudit + AzActivity ## The Issue: Scheduled Rule Retry Logging The documentation at https://learn.microsoft.com/en-us/azure/sentinel/monitor-analytics-rule-integrity#scheduled-rules states that when a scheduled rule fails, it is retried 5 more times on the same window (6 total attempts). It also provides this query to detect completely skipped windows: ```kql _SentinelHealth() | where SentinelResourceType == @"Analytics Rule" | where SentinelResourceKind == "Scheduled" | where Status != "Success" | extend startTime = tostring(ExtendedProperties["QueryStartTimeUTC"]) | summarize failuresByStartTime = count() by startTime, SentinelResourceId | where failuresByStartTime == 6 | summarize count() by SentinelResourceId ``` This query assumes that each retry attempt is logged as a separate event in SentinelHealth, all sharing the same QueryStartTimeUTC. You would then count 6 failure records per startTime to identify a fully skipped window. However, in practice I am seeing different behavior. I ran a diagnostic query with a 90-day lookback (480 non-success events total, 73 unique rules). Every single event had a count of 1 per unique (SentinelResourceName, startTime) combination. No grouping of retries was observed at all. I then found an actual failed-window event that confirms this. Here is the record: - Rule: Port scan detected (ASIM Network Session schema) - Status: Failure - Description: "Rule's scheduled run at 06/01/2026 10:43:55 failed after numerous attempts. It will be re-executed over the next scheduled time." - Issue Code: SemanticErrorInQuery - Only 1 SentinelHealth record exists for this failed window The Description field says "failed after numerous attempts" which indicates the retries happened internally, but only one consolidated Failure event was written to SentinelHealth after all retries were exhausted. The individual retry attempts do not appear as separate records. This means the failuresByStartTime == 6 query from the documentation would never match this pattern, because there is only 1 record per failed window, not 6. ## Why This Matters Yes, completely skipped windows are rare. In my 90-day dataset most failures were permanent types (SemanticErrorInQuery, QueryGeneralError) that would not benefit from retries anyway. But they still happen, and if a tenant experiences a transient issue that causes a higher rate of failed windows, the documented query would silently return nothing. For my health checks I have rewritten the detection to simply look for Status == "Failure" with Description containing "failed after numerous attempts" which matches the actual consolidated event Sentinel writes. ## Questions Is the documented failuresByStartTime == 6 query still accurate? Or has the retry logging behavior changed to write a single consolidated event per failed window? Are there specific failure types or conditions where individual retries are logged as separate events? Perhaps transient failures behave differently from permanent ones in this regard? For anyone else building health monitoring on SentinelHealth - am I missing any important use cases beyond what I described above? Any clarification would be appreciated.438Views0likes1CommentDetecting AI agents and non-human identities in Microsoft Sentinel: the classic-agent blind spot
Build 2026 made the direction official. The industry is moving from the app era into the agent era, and Microsoft spent a real share of the keynote on securing agents across their lifecycle, from discovering what is exploitable to governing what is running in production. On the identity side the centerpiece is Microsoft Entra Agent ID, now generally available, which gives AI agents first-class identities and extends Conditional Access, Identity Protection, and full audit logging to them. That is good news for agents you build the new way. It is not the whole picture, and the gap is where most SOCs will get hurt first. Modern agents are covered. Classic agents are not. Entra Agent ID draws a hard line between two kinds of agent. Modern agents are created through the Agent ID platform, each backed by an agent identity blueprint. They carry a proper Agent ID, a full audit trail, and the complete set of governance capabilities, including Identity Protection for Agents, which establishes a baseline for an agent's normal activity and flags anomalies automatically. Classic agents are everything that came before, or that gets built outside the platform: AI agents implemented as ordinary service principals or app registrations, for example Copilot Studio agents created before Agent ID was enabled, or any home-grown automation calling Graph with client credentials. In the Entra agent registry they appear with "Has Agent ID: No," and that flag matters, because the Agent ID protections apply to identities that actually hold an Agent ID. Classic agents sit outside Identity Protection for Agents and Conditional Access for Agents. Here is the uncomfortable part. The non-human identities you already run, the service principals behind your pipelines, your integrations, your scripts, your pre-platform Copilot Studio bots, are almost all classic agents. They tend to outnumber your human accounts, they have no MFA in any meaningful sense, and a credential added to one does not show up in the Azure portal. The new platform protections do not reach them. Until you migrate them, the only place you get detection coverage on that population is your SIEM. So this is the job Sentinel does that Agent ID does not: detect risky behavior on the classic, service-principal-backed agents that the platform cannot yet protect. The telemetry you have, and the one switch people forget Three tables carry most of the signal. AADServicePrincipalSignInLogs records service principal authentications, the client-credentials sign-ins your agents and automation use. No user, no MFA, just an app proving it holds a secret or certificate. AADManagedIdentitySignInLogs does the same for managed identities. AuditLogs records directory changes, including the one that matters most for persistence: a new credential added to an application or service principal. One practical warning before any of this works. Service principal and managed identity sign-in logs are not streamed by default. You have to enable those categories explicitly in the Entra diagnostic settings feeding your workspace. Plenty of teams write the detection, never check, and never notice the table is empty. Verify that first. Detection 1: a new credential on a service principal or app Adding a secret or certificate to an existing service principal is one of the cleanest persistence techniques in a Microsoft cloud. The attacker compromises a privileged user or app, drops a fresh credential on a service principal that already holds useful Graph permissions, and now has access that survives password resets and session revocation. It maps to MITRE T1098.001, Account Manipulation: Additional Cloud Credentials. For a classic agent it is especially nasty, because there is no Identity Protection baseline watching it. // Detection 1: new secret or certificate added to an application or service principal // MITRE T1098.001 - Account Manipulation: Additional Cloud Credentials AuditLogs | where OperationName has_any ("Add service principal", "Certificates and secrets management") | where Result =~ "success" | extend Initiator = coalesce( tostring(InitiatedBy.user.userPrincipalName), tostring(InitiatedBy.app.displayName)) | extend InitiatorIp = tostring(InitiatedBy.user.ipAddress) | mv-apply Target = TargetResources on ( where Target.type =~ "Application" | extend TargetName = tostring(Target.displayName), TargetId = tostring(Target.id), KeyChanges = Target.modifiedProperties ) | mv-apply Prop = KeyChanges on ( where tostring(Prop.displayName) =~ "KeyDescription" | extend NewKeys = parse_json(tostring(Prop.newValue)), OldKeys = parse_json(tostring(Prop.oldValue)) ) | extend AddedKeys = set_difference(NewKeys, OldKeys) | where array_length(AddedKeys) > 0 | project TimeGenerated, Initiator, InitiatorIp, TargetName, TargetId, AddedKeys | order by TimeGenerated desc The operation filter catches the three shapes this event takes in the log: "Add service principal," "Add service principal credentials," and "Update application - Certificates and secrets management." The modifiedProperties parsing isolates the KeyDescription change, and set_difference confirms a key was actually added rather than removed, so rotating out an old credential does not, on its own, fire the rule. False positives come from legitimate rotation and from automation that provisions app credentials (CI/CD, infrastructure as code). The initiator is the discriminant. A credential added by your deployment pipeline's service account at the usual time is routine. The same change initiated by an interactive admin out of hours, or by an account that never normally touches app credentials, is what you want to surface. Allow-list the expected initiators, not the targets. Detection 2: a classic agent signing in from a first-seen IP A service principal that has only ever authenticated from your Azure regions and suddenly signs in from somewhere new is a strong signal that its credential has been lifted and is being used elsewhere. Service principals have stable, boring network behavior, which makes a first-seen IP a far cleaner indicator for them than it is for roaming human users. This is the behavioral baseline Identity Protection gives you for free on modern agents, rebuilt in KQL for the classic ones it ignores. MITRE T1078.004, Valid Accounts: Cloud Accounts. // Detection 2: classic-agent service principal signing in from a previously unseen IP // MITRE T1078.004 - Valid Accounts: Cloud Accounts let baseline = 14d; let detection = 1d; let KnownIPs = AADServicePrincipalSignInLogs | where TimeGenerated between (ago(baseline + detection) .. ago(detection)) | where tostring(ResultType) == "0" | summarize KnownIPSet = make_set(IPAddress) by AppId; AADServicePrincipalSignInLogs | where TimeGenerated > ago(detection) | where tostring(ResultType) == "0" | lookup kind=leftouter KnownIPs on AppId | where set_has_element(KnownIPSet, IPAddress) == false | summarize FirstSeen = min(TimeGenerated), Resources = make_set(ResourceDisplayName, 10) by ServicePrincipalName, AppId, IPAddress | order by FirstSeen desc The query builds a per-application baseline of source IPs over the previous two weeks, then flags any successful sign-in today from an address outside that set. Two tuning notes. Brand-new service principals have no baseline, so they surface on first use. That is usually worth seeing once, but you can exclude AppIds younger than the baseline window if it gets noisy. And if your agents egress through shifting cloud IP ranges, widen the comparison from an exact IP to the autonomous system number or a known-range allow-list, otherwise you will chase your own infrastructure. This complements Agent ID, it does not replace it! The endgame is not to run these rules forever. It is to shrink the population they apply to. Inventory your tenant for agents marked "Has Agent ID: No," prioritize the ones holding sensitive Graph permissions, and migrate them onto the Agent ID platform, where Identity Protection and Conditional Access take over the baselining you are doing here by hand. Microsoft has signaled a migration path from classic to modern agents. Treat these two detections as the coverage you need in the meantime, and as a permanent safety net for anything that never makes the move. If you do one thing this week: enable the service principal sign-in log category, deploy detection 1, and pull a list of every service principal that had a credential added in the last 90 days. That list alone tends to be more interesting than people expect. Cheers, Marcel840Views0likes0Comments
Understand New Sentinel Pricing Model with Sentinel Data Lake Tier
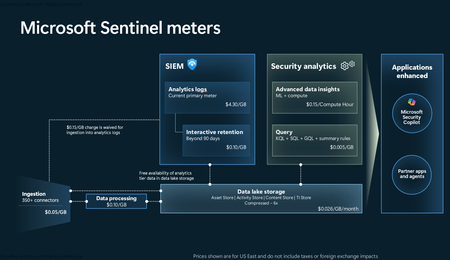
Introduction on Sentinel and its New Pricing Model Microsoft Sentinel is a cloud-native Security Information and Event Management (SIEM) and Security Orchestration, Automation, and Response (SOAR) platform that collects, analyzes, and correlates security data from across your environment to detect threats and automate response. Traditionally, Sentinel stored all ingested data in the Analytics tier (Log Analytics workspace), which is powerful but expensive for high-volume logs. To reduce cost and enable customers to retain all security data without compromise, Microsoft introduced a new dual-tier pricing model consisting of the Analytics tier and the Data Lake tier. The Analytics tier continues to support fast, real-time querying and analytics for core security scenarios, while the new Data Lake tier provides very low-cost storage for long-term retention and high-volume datasets. Customers can now choose where each data type lands—analytics for high-value detections and investigations, and data lake for large or archival types—allowing organizations to significantly lower cost while still retaining all their security data for analytics, compliance, and hunting. Please flow diagram depicts new sentinel pricing model: Now let's understand this new pricing model with below scenarios: Scenario 1A (PAY GO) Scenario 1B (Usage Commitment) Scenario 2 (Data Lake Tier Only) Scenario 1A (PAY GO) Requirement Suppose you need to ingest 10 GB of data per day, and you must retain that data for 2 years. However, you will only frequently use, query, and analyze the data for the first 6 months. Solution To optimize cost, you can ingest the data into the Analytics tier and retain it there for the first 6 months, where active querying and investigation happen. After that period, the remaining 18 months of retention can be shifted to the Data Lake tier, which provides low-cost storage for compliance and auditing needs. But you will be charged separately for data lake tier querying and analytics which depicted as Compute (D) in pricing flow diagram. Pricing Flow / Notes The first 10 GB/day ingested into the Analytics tier is free for 31 days under the Analytics logs plan. All data ingested into the Analytics tier is automatically mirrored to the Data Lake tier at no additional ingestion or retention cost. For the first 6 months, you pay only for Analytics tier ingestion and retention, excluding any free capacity. For the next 18 months, you pay only for Data Lake tier retention, which is significantly cheaper. Azure Pricing Calculator Equivalent Assuming no data is queried or analyzed during the 18-month Data Lake tier retention period: Although the Analytics tier retention is set to 6 months, the first 3 months of retention fall under the free retention limit, so retention charges apply only for the remaining 3 months of the analytics retention window. Azure pricing calculator will adjust accordingly. Scenario 1B (Usage Commitment) Now, suppose you are ingesting 100 GB per day. If you follow the same pay-as-you-go pricing model described above, your estimated cost would be approximately $15,204 per month. However, you can reduce this cost by choosing a Commitment Tier, where Analytics tier ingestion is billed at a discounted rate. Note that the discount applies only to Analytics tier ingestion—it does not apply to Analytics tier retention costs or to any Data Lake tier–related charges. Please refer to the pricing flow and the equivalent pricing calculator results shown below. Monthly cost savings: $15,204 – $11,184 = $4,020 per month Now the question is: What happens if your usage reaches 150 GB per day? Will the additional 50 GB be billed at the Pay-As-You-Go rate? No. The entire 150 GB/day will still be billed at the discounted rate associated with the 100 GB/day commitment tier bucket. Azure Pricing Calculator Equivalent (100 GB/ Day) Azure Pricing Calculator Equivalent (150 GB/ Day) Scenario 2 (Data Lake Tier Only) Requirement Suppose you need to store certain audit or compliance logs amounting to 10 GB per day. These logs are not used for querying, analytics, or investigations on a regular basis, but must be retained for 2 years as per your organization’s compliance or forensic policies. Solution Since these logs are not actively analyzed, you should avoid ingesting them into the Analytics tier, which is more expensive and optimized for active querying. Instead, send them directly to the Data Lake tier, where they can be retained cost-effectively for future audit, compliance, or forensic needs. Pricing Flow Because the data is ingested directly into the Data Lake tier, you pay both ingestion and retention costs there for the entire 2-year period. If, at any point in the future, you need to perform advanced analytics, querying, or search, you will incur additional compute charges, based on actual usage. Even with occasional compute charges, the cost remains significantly lower than storing the same data in the Analytics tier. Realized Savings Scenario Cost per Month Scenario 1: 10 GB/day in Analytics tier $1,520.40 Scenario 2: 10 GB/day directly into Data Lake tier $202.20 (without compute) $257.20 (with sample compute price) Savings with no compute activity: $1,520.40 – $202.20 = $1,318.20 per month Savings with some compute activity (sample value): $1,520.40 – $257.20 = $1,263.20 per month Azure calculator equivalent without compute Azure calculator equivalent with Sample Compute Conclusion The combination of the Analytics tier and the Data Lake tier in Microsoft Sentinel enables organizations to optimize cost based on how their security data is used. High-value logs that require frequent querying, real-time analytics, and investigation can be stored in the Analytics tier, which provides powerful search performance and built-in detection capabilities. At the same time, large-volume or infrequently accessed logs—such as audit, compliance, or long-term retention data—can be directed to the Data Lake tier, which offers dramatically lower storage and ingestion costs. Because all Analytics tier data is automatically mirrored to the Data Lake tier at no extra cost, customers can use the Analytics tier only for the period they actively query data, and rely on the Data Lake tier for the remaining retention. This tiered model allows different scenarios—active investigation, archival storage, compliance retention, or large-scale telemetry ingestion—to be handled at the most cost-effective layer, ultimately delivering substantial savings without sacrificing visibility, retention, or future analytical capabilities.Solved4KViews2likes6Comments
How Should a Fresher Learn Microsoft Sentinel Properly?
Hello everyone, I am a fresher interested in learning Microsoft Sentinel and preparing for SOC roles. Since Sentinel is a cloud-native enterprise tool and usually used inside organizations, I am unsure how individuals without company access are expected to gain real hands-on experience. I would like to hear from professionals who actively use Sentinel: - How do freshers typically learn and practice Sentinel? - What learning resources or environments are commonly used by beginners? - What level of hands-on experience is realistically expected at entry level? I am looking for guidance based on real industry practice. Thank you for your time.515Views0likes2Comments
Missing details in Azure Activity Logs – MICROSOFT.SECURITYINSIGHTS/ENTITIES/ACTION
The Azure Activity Logs are crucial for tracking access and actions within Sentinel. However, I’m encountering a significant lack of documentation and clarity regarding some specific operation types. Resources consulted: https://learn.microsoft.com/en-us/azure/sentinel/audit-sentinel-data https://learn.microsoft.com/en-us/rest/api/securityinsights/entities?view=rest-securityinsights-2024-01-01-preview https://learn.microsoft.com/en-us/rest/api/securityinsights/operations/list?view=rest-securityinsights-2024-09-01&tabs=HTTP My issue: I observed unauthorized activity on our Sentinel workspace. The Azure Activity Logs clearly indicate the user involved, the resource, and the operation type: "MICROSOFT.SECURITYINSIGHTS/ENTITIES/ACTION" But that’s it. No detail about what the action was, what entity it targeted, or how it was triggered. This makes auditing extremely difficult. It's clear the person was in Sentinel and perform an activity through it, from search, KQL, logs to find an entity from a KQL query. But, that's all... Strangely, this operation is not even listed in the official Sentinel Operations documentation linked above. My question: Has anyone encountered this and found a way to interpret this operation type properly? Any insight into how to retrieve more meaningful details (action context, target entity, etc.) from these events would be greatly appreciated.648Views0likes3Comments