pgvector
18 TopicsIntroducing Durable Functions in PostgreSQL
By Abe Omorogbe, Senior PM | Pino De Candia, Principal Software Engineer | TJ Green, Principal Software Engineer Postgres will happily store your data, run your queries, and scale with you for years. But the moment you need to do more with that data, such as running multi-step transformation, scheduling nightly rollups, generating embeddings or waiting on an approval, you hit a wall. Postgres has no built-in way to run long-lived, fault-tolerant work. That's why we built pg_durable, a new open-source PostgreSQL extension that brings durable execution directly into the database. With pg_durable, Postgres doesn’t just store your data, it runs long-lived, fault-tolerant workflows on it, with built-in retries, parallelism, scheduling, and recovery. Instead of stitching together PL/pgSQL functions or building external orchestration systems, you can now define and run resilient workflows entirely in your database, backed by Postgres' durability and high availability. And on Azure HorizonDB, pg_durable also powers AI pipelines, enabling production-ready data and AI workflows, end-to-end, right inside the database. In this post, we'll cover: The hidden trap: blocking background work What pg_durable is and the DSL that drives it How this engine powers AI pipelines on HorizonDB Sample patterns worth exploring Getting started on HorizonDB, on your laptop, and in VS Code 🚀 Want to try it out? pg_durable ships in Azure HorizonDB, Microsoft's new PostgreSQL cloud service. The HorizonDB Preview is the fastest way to try pg_durable and AI pipelines together. Get started in HorizonDB → pg_durable visualization The hidden trap: blocking background work Most Postgres teams eventually reach a point where they need to run critical tasks on their data: transformations, nightly aggregations, database maintenance workflows, embedding jobs, or multi-step business processes. So, they do the natural thing and try to keep that work inside Postgres. They end up on a journey of increasing complexity and maintenance burden. First, just run the task as a function in your database You cram the whole workflow into one PL/pgSQL function: loop, transform, call APIs, write results, return. It looks simple until you have to run it in production. One connection stays tied up the whole time. Everything runs inside one big transaction, with long locks and no visibility into partial progress. If the connection drops or the database restarts, the whole run is gone. No per-step retries. No parallelism. No scheduling. No clean way to pause for human input. When it fails, you move it outside You push the workflow into an external service: a job queue, polling workers, state tables, step coordination, retry logic, crash-recovery sweeps, and cleanup jobs. What started as a few background tasks turns into a full distributed system. Before you’ve even touched the business logic, you’re building and operating infrastructure just to coordinate work that’s still fundamentally tied to your data. Both paths are workarounds for the same missing primitive: durable, asynchronous background work that lives where your data lives. That's the gap pg_durable fills. What pg_durable actually is pg_durable is a Postgres extension that consists of a DSL (Domain specific language) and the duroxide runtime hosted in a Postgres background worker. You describe a workflow as a small SQL expression, call df.start(...), and get an instance ID back immediately. The work runs off to the side in a background worker, so it never blocks your connection or transaction, and you can check progress later with df.status() and df.result(). The execution state lives in Postgres, which means it benefits from the database’s durability, HA, backups, and recovery. Additionally, the workflow definition does not have to live in the database: your application can send it to df.start(...) over a regular Postgres connection. 2: pg_durable orchestration of worker and schema Because execution is asynchronous, pg_durable automatically breaks a workflow into discrete steps. Each step runs in its own session and transaction, commits its progress, and hands off to the next instead of keeping one giant transaction open. Steps are checkpointed in Postgres and recovered by deterministic replay, so workflows survive crashes, restarts, and failovers and resume where they left off. If a step fails, only that step retries. The whole thing is expressed through a tiny DSL of composable operators: Operator Meaning ~> Sequential. run this, then that & Parallel. fan out, wait for all | Race. fan out, take the first to finish ?> / !> Conditional. if / else @> Loop. repeat durably, survive restarts |=> Capture a step's result into a variable (reuse with $) Advanced Functions df.if() Conditional branch df.loop() Repeat statements df.join() Execute in parallel, wait for all df.http() To call an allowlisted endpoint df.wait_for_schedule() For cron-style timing df.wait_for_signal() Pause for an external event Read more about all operators and functions in pg_durable Without pg_durable vs. with pg_durable The hand-rolled version of "run three aggregations in parallel, then refresh a dashboard with retries and crash recovery" usually means 300+ lines of queue tables, polling workers, state-machine rows, per-step retry logic, crash-recovery sweeps, and cleanup jobs. Plus, the runbook to operate it. The pg_durable version: SELECT df.start( 'SELECT count(*) FROM users' & 'SELECT count(*) FROM orders' & 'SELECT sum(amount) FROM orders' ~> 'REFRESH MATERIALIZED VIEW metrics', 'refresh-dashboard' ); You write the SQL. pg_durable owns the queue, the state, the coordination, the retries, and the crash recovery. Two ways to use pg_durable 1: Use pg_durable directly (works on Azure HorizonDB or any Postgres 17) Enable it and start orchestrating: CREATE EXTENSION pg_durable; SELECT df.start($$ SELECT 'Hello, durable world!' AS message $$); -- returns an instance ID immediately; the worker runs it asynchronously From there you compose: sequential pipelines, conditional branches, races for timeout-or-result, variable passing between steps, human-in-the-loop approvals, scheduled maintenance all in SQL, close to the data, with no new infrastructure. This is the "just use Postgres" answer to a problem teams usually solve by leaving Postgres. Because it's open source under the permissive PostgreSQL License, you can clone the repo and run it on your laptop, your server, or any cloud. 2: AI pipelines (HorizonDB capability) On HorizonDB, pg_durable becomes the foundation for something even more approachable: a managed, declarative AI pipeline surface in the azure_ai extension. pg_durable gives you the durable execution engine, while the ai.* API gives you an AI-shaped model of sources, steps, sinks, and triggers that compile into a durable graph. Traditional app-tier embedding pipelines fail in predictable ways: a transient API error mid-batch with no shared checkpoint, a worker that crashes after writing chunks but before marking the parent row processed, no clean way to re-embed just the rows that changed. Move that logic into HorizonDB and the source, the steps, the sink, and the run history are all SQL, protected by the same transactions, backups, and PITR (point-in-time recovery) your data already has. A complete chunk → embed AI pipeline is one definition: SELECT ai.create_pipeline( name => 'ai_pipeline', source => ai.table_source(table_name => 'documents_ai_pipeline'), steps => ARRAY[ ai.chunk(input => 'content'), ai.embed(model => 'default-embedding', input => 'chunk_text', dimensions => 1536) ], trigger => 'on_change', sink => ai.table_sink('documents_ai_pipeline_output') ); SELECT ai.run('ai_pipeline'); Each AI step becomes a durable node, so if ai.embed() fails, ai.chunk() doesn’t run again. And with trigger => 'on_change', the pipeline runs automatically as rows change, embedding only what’s new. Add a DiskANN index on the resulting table, and you have production-ready vector search end to end, entirely inside the database. Where pg_durable fits and where it doesn't If you've used external orchestrators such as Temporal or Airflow, your first reaction is probably: why would I put control flow in my database? Fair question. pg_durable isn't trying to be a universal orchestrator. Reach for pg_durable when the workflow is tightly coupled to Postgres state. The rows it reads and writes live in the same database, it benefits from the database's own durability, backups, and PITR, and you'd rather not stand up a separate system to coordinate work that never leaves the data tier. Think: embedding pipelines, ETL jobs, scheduled maintenance, and queue-style background jobs. Reach for a dedicated orchestrator when the workflow's center of gravity is outside Postgres, fanning across heterogeneous services, or running arbitrary application logic that does not map cleanly to SQL steps, branching, loops, or HTTP calls. Get started On Azure HorizonDB CREATE EXTENSION IF NOT EXISTS pg_durable; -- Execute a simple SQL query as a durable function SELECT df.start($$ SELECT 'Hello, durable world!' AS message $$); -- Returns: a1b2c3d4 (8-character instance ID) -- Get result of a specific instance SELECT df.result(<ID>); That's it: submit, walk away, inspect. Read the documentation for more details. In VS Code, with the PostgreSQL extension A dense one-liner of ~>, &, and |=> is precise once it clicks, but the learning curve is real so flatten it with tooling. Install the PostgreSQL extension for VS Code from the Marketplace: Connect to HorizonDB or your local Postgres directly from the extension Let Copilot write the SQL. The pg-durable-sql skill turns a plain-English description ("every night, archive orders older than 90 days") into correct pg_durable syntax. Run it and watch it. The extension renders pg_durable workflows and azure_ai pipelines as live graphs, definition and each run, so you can see every step, its timing, and exactly where a failure happened. Authoring, execution, run visualization, and inspection in one window and the same tooling works against any Postgres, not just HorizonDB. On your laptop Prefer to run it yourself? Clone microsoft/pg_durable, use the Codespace prebuild or VS Code Dev Container, and add the extension on any Postgres 17. Sample patterns worth exploring The scenario guide has a full catalog of scenarios; however, these are the three I would start with. ETL Pipeline: a multi-step data transformation where each step must be completed before the next begins. Failures should stop the pipeline. SELECT df.start( 'DELETE FROM target WHERE loaded_at < now() - interval ''7 days''' -- Step 1: Cleanup old ~> 'UPDATE staging SET processed_at = now() WHERE processed_at IS NULL' -- Step 2: Mark staging ~> 'INSERT INTO target (data, source_id) SELECT data, source_id FROM staging WHERE processed_at IS NOT NULL', -- Step 3: Load 'etl-pipeline' -- Label for easy identification ); If the database restarts mid-backfill, it picks up from the last checkpointed batch, not row zero. See full example Scheduled Data Sync: poll an external API or run a job on a schedule (hourly, daily, every 30 minutes). The job should run forever and survive restarts. (See full example): -- Scheduled sync: fetch data every 30 minutes (runs forever) SELECT df.start( @> ( -- @> creates an eternal loop -- Fetch from external API (df.http( 'https://httpbingo.org/json', 'GET' ) |=> 'response') -- Store the response ~> 'INSERT INTO external_data_sync (data) VALUES ($response::jsonb)' -- Wait for next scheduled run ~> df.wait_for_schedule('*/30 * * * *') -- Cron: every 30 minutes ), 'scheduled-data-sync' ); Human-in-the-loop approval: auto-apply routine changes, pause the risky ones until a person signals approval (See full example): SELECT df.start( 'SELECT amount > 10000 AS needs_review FROM invoices WHERE id = 42' |=> 'risky' ?> ( df.wait_for_signal('invoice-42') ~> 'UPDATE invoices SET status = ''paid'' WHERE id = 42' ) !> 'UPDATE invoices SET status = ''paid'' WHERE id = 42', 'invoice-approval' ); The workflow simply waits minutes or days until a reviewer releases it with the matching signal, then resumes. The community is already running with it pg_durable launched as open source and the community is already kicking the tires. The project was a top article on Hacker News on launch day and 1.7K stars on GitHub within its first few days of initial launch. Also Franck Pachot (PostgreSQL community veteran) published an independent walkthrough, Getting Started with pg_durable: durable workflows inside PostgreSQL within days of release. The repo is actively developed, and the maintainers are reading every issue and PR. If you want improvements in our DSL ergonomics, say so. If you want an operator that doesn't exist yet, open an issue. If you've got a scenario we haven't covered, send a PR. The syntax, the docs, and the rough edges all get better when people who run Postgres in production push back. So, clone it, and build something real. If you find rough edges, open an issue or send a PR at microsoft/pg_durable. We think you'll be surprised by how much it can take. Learn more pg_durable on GitHub Durable Functions on HorizonDB AI pipelines on HorizonDB3.6KViews2likes0CommentsSubgenAI makes AI practical, scalable, and sustainable with Azure Database for PostgreSQL
Authors: Abe Omorogbe, Senior Program Manager at Microsoft and Julia Schröder Langhaeuser, VP of Product Serenity Star at SubgenAI AI agents are thriving in pilots and prototypes. However, scaling them across organizations is more difficult. A recent MIT report shows that 95 percent of projects fail to reach production. Long development cycles, lack of observability, and compliance hurdles leave enterprises struggling to deliver production-ready agents. SubgenAI, a European generative AI company that focuses on democratizing AI for businesses and governments, saw an opportunity to change this. Its flagship platform, Serenity Star, transforms AI agent development from a code-heavy, fragmented process into a streamlined, no-code experience. Built on Microsoft Azure Database for PostgreSQL, Semantic Kernel, and Microsoft Foundry, Serenity Star empowers organizations to deploy production-grade AI agents in minutes, not months. SubgenAI’s mission is to make generative AI accessible, scalable, and secure for every organization. Whether you're a startup or a multinational, Serenity Star offers the tools to build intelligent agents tailored to your business logic, with full control over data and deployment. “Many things must happen around it in the coming years. Serenity Star is designed to solve problems like data control, compliance, and decision ethics—so companies can unleash the full potential of generative AI without compromising trust or profitability” - Lorenzo Serratosa Simplifying complex AI agent development Technical and operational challenges are inherent in enterprise-wide AI agent deployments. Examples include time-consuming iteration cycles, lack of observability and cost control, security concerns, and data sovereignty requirements. Serenity Star addresses these pain points by handling the entire AI agent lifecycle while providing enterprise-grade security and compliance features. Users can focus on defining their agent's purpose and behavior rather than wrestling with technical implementation details. Its framework focuses on four essentials for AI agents: the brain (underlying model), knowledge (accessible information), behavior (programmed responses), and tools (external system integrations). This framework directly influenced the technology stack choices for Serenity Star, with Azure Database for PostgreSQL powering the knowledge retrieval and Semantic Kernel enabling flexible model orchestration. Real-world architecture in action When a user query comes in, Serenity Star uses the vector capabilities of Azure Database for PostgreSQL to retrieve the most relevant knowledge. That context, combined with the user’s input, forms a complete prompt. Semantic Kernel then routes the request to the right large language model, ensuring the agent delivers accurate and context-aware responses. Serenity Star’s native connectors to platforms such as Microsoft Teams, WhatsApp, and Google Tag Manager are also part of this architecture, delivering answers directly in the collaboration and communication tools enterprises already use every day. Figure 1: Serenity Star Architecture This routing and orchestration architecture applies to the multi-tenant SaaS deployments and dedicated customer instances offered by Serenity Star. Azure Database for PostgreSQL provides native Row-Level Security (RLS) capabilities, a key advantage for securely managing multi-tenant environments. Multi-tenant deployments allow organizations to get started quickly with lower overhead, while dedicated instances meet the needs of enterprises with strict compliance and data sovereignty requirements. Optimizing for scale The same architecture that powers retrieval, routing, and multi-channel delivery also provides a foundation for performance at scale. As adoption grows, the team continuously monitors query volume, response times, and resource efficiency across both multi-tenant and dedicated environments. To stay ahead of demand, SubgenAI actively experiments with new Azure Database for PostgreSQL features such as DiskANN for faster vector search. These optimizations keep latency low even as more users and connectors are added. The result is a platform that maintains sub-60-second response times for 99 percent of chart generations, regardless of deployment model or integration point. With this systematic approach to scaling, organizations can deploy fully functional AI agents that are connected to their preferred communication platforms in just 15 minutes instead of hours. For enterprises that have struggled with failed AI projects, Serenity Star offers not only a secure and compliant solution but also one proven to grow with their needs. Why Azure Database for PostgreSQL is a cornerstone The knowledge component of AI agents relies heavily on retrieval-augmented generation (RAG) systems that perform similarity searches against embedded content. This requires a database capable of handling efficient vector search while maintaining enterprise-grade reliability and security. SubgenAI evaluated multiple vector database options. However, Azure Database for PostgreSQL with PGVector emerged as the clear winner. There were several compelling reasons for this. One is its mature technology, which provides immediate credibility with enterprise customers. Two, the ability to scale GenAI use cases with features like DiskANN for accurate and scalable vector search. There, the flexibility and appeal of using an open-source database with a vibrant and fast-moving community. As CPO Leandro Harillo explains: “When we tell them their data runs on Azure Database for PostgreSQL, it’s a relief. It's a well-known technology versus other options that were born with this new AI revolution.” As an open-source relational database management system, Azure Database for PostgreSQL offers extensibility and seamless integration with Microsoft’s enterprise ecosystem. It has a trusted reputation that appeals to organizations with strict data sovereignty and compliance requirements such as those in healthcare and insurance where reliability and governance are non-negotiable. The integration with Azure's broader ecosystem also simplified implementation. With Serenity Star built entirely on Azure infrastructure, Azure Database for PostgreSQL provided seamless connectivity and consistent performance characteristics. The fast response times necessary for real-time agent interactions are the result, along with maintaining the reliability demanded by enterprise customers. Semantic Kernel: Enabling model flexibility at scale Enterprise AI success requires the ability to experiment with different models and adapt quickly as technology evolves. Semantic Kernel makes this possible, supporting over 300 LLMs and embedding models through a unified interface. With Serenity Star, organizations can make genuine choices about their AI implementations without vendor lock-in. Companies can use embedding models from OpenAI through Azure deployments, ensuring their information remains in their own infrastructure while accessing cutting-edge capabilities. If business requirements change or new models emerge, switching becomes a configuration change rather than a development project. Semantic Kernel's comprehensive connector ecosystem also accelerated SubgenAI's own development process. Interfaces for different vector databases enabled rapid prototyping and comparison during the evaluation phase. “Semantic Kernel helped us to be able to try the different ones and choose the one that fit better for us,” notes Julia Schroder, VP of Product. The SubgenAI team has also extended Semantic Kernel to support more features in Azure Database for PostgreSQL, which is easier because of how well-known and popular PostgreSQL is. SubgenAI has also contributed improvements back to the community. This collaborative approach ensures the platform benefits from the latest developments while helping advance the broader ecosystem. Proven impact of Azure Database for PostgreSQL across industries Because organizations struggle to deliver production-ready agents because of long development cycles, lack of observability, and compliance, the effectiveness of Azure Database for PostgreSQL and other Azure services is reflected in deployment metrics and customer feedback. Production-ready agents typically require around 30 iterations for basic implementations. Complex use cases demand significantly more refinement. One GenAI customer in medical education required over 200 iterations to perfect an agent that evaluates medical students through complex case analysis. Azure PostgreSQL and other Azure services support hour-long iteration cycles rather than week-long sprints, which made this level of refinement economically feasible. Cost efficiency is another significant advantage. SubgenAI provisions and configures models in Microsoft Foundry, which eliminates idling GPU resources while providing detailed cost breakdowns. Users can see exactly how tokens are consumed across prompt text, RAG context, and tool usage, enabling data-driven optimization decisions. Consulting partnerships validate the platform's market position. One consulting firm with 50,000 employees is delighted with the easier implementation, faster deployment, and reliable production performance. Conclusion The combination of Azure Database for PostgreSQL and Semantic Kernel has enabled SubgenAI to address the fundamental challenges that cause 95 percent of enterprise AI projects to fail. Organizations using Serenity Star bypass the traditional barriers of lengthy development cycles, limited observability, and compliance hurdles that typically derail AI initiatives. The platform's architecture delivers measurable results, including a 50 percent reduction in coding time, support for complex agents requiring 200+ iterations, and deployment capabilities that compress months-long projects into 15-minute implementations. Azure Database for PostgreSQL provides the enterprise-grade foundation that customers in regulated industries require, while Semantic Kernel ensures organizations retain flexibility as AI technology evolves. This technological partnership creates a reliable pathway for companies to deploy production-ready AI agents without sacrificing data sovereignty or operational control. Through the reliability of Azure Database for PostgreSQL and the flexibility of Semantic Kernel, Serenity Star delivers an enterprise-ready foundation that makes AI practical, scalable, and sustainable.1.3KViews1like0CommentsBuild Enterprise-Ready AI Agents with the New Azure Postgres LangChain + LangGraph Connector
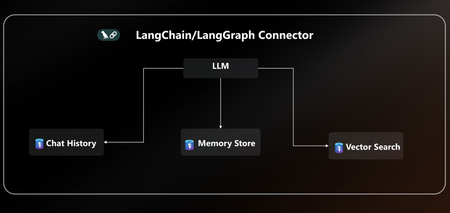
AI agents are only as powerful as the data layer behind them. That’s why we’re excited to announce native LangChain + LangGraph connector for Azure Database for PostgreSQL. With this release, Postgres becomes your single source of truth for AI agents, handling knowledge retrieval, chat history, and long-term memory all in one place. This new connector is packed with everything you need to build secure, scalable and enterprise-ready AI agents on Azure without the complexity. With EntraID authentication, DiskANN acceleration, vector store, and a dedicated agent store, you can go from prototype to production on Azure faster than ever. You can quickly get started with the LangChain + LangGraph connector today pip install langchain-azure-postgresql In this post, we’ll cover: How Azure Postgres connector for LangGraph can serve as the single persistence + retrieval layer for an AI agent New first-class connector for LangChain +LangGraph A practical example to help you get started Azure PostgreSQL as the single persistence + retrieval layer for an AI agent When building AI agents today, developers face a fragmented stack: Vector storage and search require a library, service or separate database. Chat history & short-term memory need yet another data source. Long-term memory often means bolting on yet another system. This sprawl leads to complex integrations, higher costs, and weaker security, making it hard to scale AI agents reliably. The Solution The new Azure Postgres connector for LangChain + LangGraph transforms your Azure Postgres database to the single persistence + retrieval layer for AI agents. Instead of working on a fragmented stack, developers can now: Run embeddings + semantic search with built-in DiskANN acceleration in the same database that powers their application logic. Persist chat history and short-term memory and keep agent conversations grounded via seamless context retrieval from data stored in Postgres. Capture, retrieve, and evolve knowledge over time with a built-in long-term memory without bolting on external systems. All in one database, simplified, secure, and enterprise ready. Postgres becomes the persistent and retrieval data layer for your AI agent. Built for Enterprise Readiness: LangChain + LangGraph Connector This release unlocks several new capabilities that make it easy to build robust, production-ready agents: Auth with EntraID: Enterprise-grade identity to securely connect LangChain + LangGraph workflows to Azure Database for PostgreSQL within a centrally managed security perimeter based on identity. DiskANN & Extensions: First-class support for faster vector search using pgvector combined with DiskANN indexing, enabling support for high-dimensional vectors and cost-efficient search. Additionally, helper functions ensure your favorite extensions are installed. Native Vector Store: Store and query embeddings, enabling semantic search and Retrieval-Augmented Generation (RAG) scenarios. Dedicated Agent Store: Persist agent state, memory, and chat history with structured access patterns, perfect for multi-turn conversations and long-term context. Together, these features give developers a turnkey persistence solution for building reliable AI agents without stitching together multiple storage systems. Using LangGraph on Azure Database for PostgreSQL Using LangGraph with Azure Database for PostgreSQL is easy. Enable the vector & pg_diskann Extension: Allowlist the vector and pg_diskann extension within your server configuration. Import LangChain + LangGraph connector pip install langchain-azure-postgresql pip install -qU langchain-openai pip install -qU azure-identity Login to Azure, to your Entra ID Run az login in your terminal, where you will also run the LangGraph code. az login To get started, you need to set up a production-ready vector store for your agent in a few lines of code. # 1. Auth: Securely connect to Azure Postgres connection_pool = AzurePGConnectionPool(azure_conn_info=ConnectionInfo(host=os.environ["PGHOST"])) #2. Create embeddings embeddings = AzureOpenAIEmbeddings(model="text-embedding-3-small") # 3. Initialize a vector store in Postgres with DiskANN vector_store = AzurePGVectorStore(connection=connection, embedding=embeddings) Use LangGraph to build a sample agent. Here’s a practical example that combines vector search and checkpointer inside Postgres: #4 Define the tool for data retrieval. def get_data_from_vector_store(query: str) -> str: """Get data from the vector store.""" results = vector_store.similarity_search(query) return results #5 Define the agent, checkpointer and memory store. with connection_pool.getconn() as conn: agent = create_react_agent( model=model, tools=[get_data_from_vector_store], checkpointer=PostgresSaver(conn) ) #6 Run the agent and print results config = {"configurable": {"thread_id": "1", "user_id": "1"}} response = agent.invoke( {"messages": [{"role": "user", "content": "What does my database say about cats? Make sure you address me with my name"}]}, config ) for msg in response["messages"][-2:]: msg.pretty_print() With just a few lines of code, you can: Uses the vector store backed by Postgres Enable DiskANN for semantic search Use checkpointers for short-term conversation history Learn More This is just the beginning. With native LangChain + LangGraph support in Azure PostgreSQL, developers can now rely on a single, secure, high-performance data layer for building the next generation of AI agents. 👉 Ready to start? All the code are available in the Azure Postgres Agents Demo GitHub repository. See how easy it is to bring your AI agent to life on Azure. 👉 Check out the docs for more details on the LangChain + LangGraph connector.4.6KViews3likes0CommentsFueling the Agentic Web Revolution with NLWeb and PostgreSQL
We’re excited to announce that NLWeb (Natural Language Web), Microsoft’s open project for natural language interfaces on websites now supports PostgreSQL. With this enhancement, developers can leverage PostgreSQL and NLWeb to transform any website into an AI-powered application or Model Context Protocol (MCP) server. This integration allows organizations to utilize a familiar, robust database as the foundation for conversational AI experiences, streamlining deployment and maximizing data security and scalability. Soon, autonomous agents, not just human users, will consume and interpret website content, transforming how information is accessed and utilized online. During Microsoft //Build 2025, Microsoft introduced the era of the open agentic web, in which the internet is an open agentic web a new paradigm in which autonomous agents seamlessly interact across individual, organizational, team and end-to-end business contexts. To realize the future of an open agentic web, Microsoft announced the NLWeb project. NLWeb transforms any website to an AI-powered application with just a few lines of code and by connecting to an AI model and a knowledge base. In this post, we’ll cover: What NLWeb is and how it works with vector databases How pgvector enables vector similarity search in PostgreSQL for NLWeb Get started using NLWeb with Postgres Let’s dive in and see how Postgres + NLWeb can redefine conversational web interfaces while keeping your data in a familiar, powerful database. What is NLWeb? A Quick Overview of Conversational Web Interfaces NLWeb is an open project developed by Microsoft to simplify adding conversational AI interfaces to websites. How NLWeb works under the hood: Processes existing data/website content that exists in semi-structured formats like Schema.org, RSS, and other data that websites already publish Embeds and indexes all the content in a vector store (i.e PostgreSQL with pgvector) Routes user queries through several processes which handle natural langague understanding, reranking and retrieval. Answers queries with an LLM The result is a high-quality natural language interface on top of web data, giving developers the ability to let users “talk to” web data. By default, every NLWeb instance is also a Model Context Protocol (MCP) server, allowing websites to make their content discoverable and accessible to agents and other participants in the MCP ecosystem if they choose. Importantly, NLWeb is platform-agnostic and supports many major operating systems, AI models, and vector stores and the NLWeb project is modular by design, so developers can bring their own retrieval system, model APIs, and define their own extensions. NLWeb with PostgreSQL PostgreSQL is now embedded into the NLWeb reference stack as a native retriever, creating a scalable and flexible path for deploying NLWeb instances using open-source infrastructure. Retrieval Powered by pgvector NLWeb leverages pgvector, a PostgreSQL extension for efficient vector similarity search, to handle natural language retrieval at scale. By integrating pgvector into the NLWeb stack, teams can eliminate the need for external vector databases. Web data stored in PostgreSQL becomes immediately searchable and usable for NLWeb experiences, streamlining infrastructure and enhancing security. PostgreSQL's robust governance features and wide adoption align with NLWeb’s mission to enable conversational AI for any website or content platform. With pgvector retrieval built in, developers can confidently launch NLWeb instances on their own databases no additional infrastructure required. Implementation example We are going to use NLWeb and Postgres, to create a conversational AI app and MCP server that will let us chat with content from the Talking Postgres with Claire Giordano Podcast! Prerequisites An active Azure account. Enable and configure the pg_vector extensions. Create an Azure AI Foundry project. Deploy models gpt-4.1, gpt-4.1-mini and text-embedding-3-small. Install Visual Studio Code. Install the Python extension. Install Python 3.11.x. Install the Azure CLI (latest version). Getting started All the code and sample datasets are available in this GitHub repository. Step 1: Setup NLWeb Server 1. Clone or download the code from the repo. git clone https://github.com/microsoft/NLWeb cd NLWeb 2. Open a terminal to create a virtual python environment and activate it. python -m venv myenv source myenv/bin/activate # Or on Windows: myenv\Scripts\activate 3. Go to the 'code/python' folder in NLWeb to install the dependencies. cd code/python pip install -r requirements.txt 4. Go to the project root folder in NLWeb and copy the .env.template file to a new .env file cd ../../ cp .env.template .env 5. In the .env file, update the API key you will use for your LLM endpoint of choice and update the Postgres connection string. For example: AZURE_OPENAI_ENDPOINT="https://TODO.openai.azure.com/" AZURE_OPENAI_API_KEY="<TODO>" # If using Postgres connection string POSTGRES_CONNECTION_STRING="postgresql://<HOST>:<PORT>/<DATABASE>?user=<USERNAME>&sslmode=require" POSTGRES_PASSWORD="<PASSWORD>" 6. Update your config files (located in the config folder) to make sure your preferred providers match your .env file. There are three files that may need changes. config_llm.yaml: Update the first line to the LLM provider you set in the .env file. By default it is Azure OpenAI. You can also adjust the models you call here by updating the models noted. By default, we are assuming 4.1 and 4.1-mini. config_embedding.yaml: Update the first line to your preferred embedding provider. By default it is Azure OpenAI, using text-embedding-3-small. config_retrieval.yaml: Update the first line to postgres. You should update write_endpoint to postgres and You should update postgres retrieval endpoint is enabled to 'true' in the following list of possible endpoints. Step 2: Initialize Postgres Server Go to the 'code/python/misc folder in NLWeb to run Postgres initializer. NOTE: If you are using Azure Postgres Flexible server make sure you have `vector` extension allow-listed and make sure the database has the vector extension enabled, cd code/python/misc python postgres_load.py Step 3: Ingest Data from Talk Postgres Podcast Now we will load some data in our local vector database to test with. We've listed a few RSS feeds you can choose from below. Go to the 'code/python folder in NLWeb and run the command. The format of the command is as follows (make sure you are still in the 'python' folder when you run this): python -m data_loading.db_load <RSS URL> <site-name> Talking Postgres with Claire Giordano Podcast: python -m data_loading.db_load https://feeds.transistor.fm/talkingpostgres Talking-Postgres (Optional) You can check the documents table in your Postgres database and verify the table looks like the one below. To verify all the data from the website was uploaded. Test NLWeb Server Start your NLWeb server (again from the 'python' folder): python app-file.py Go to http://localhost:8000/ Start ask questions about the Talking Postgres with Claire Giordano Podcast, you may try different modes. Trying List Mode: Sample Prompt: “I want to listen to something that talks about the advances in vector search such as DiskANN” Trying Generate Mode Sample Prompt: “What did Shireesh Thota say about the future of Postgres?” Running NLWeb with MCP 1. If you do not already have it, install MCP in your venv: pip install mcp 2. Next, configure your Claude MCP server. If you don’t have the config file already, you can create the file at the following locations: macOS: ~/Library/Application Support/Claude/claude_desktop_config.json Windows: %APPDATA%\Claude\claude_desktop_config.json The default MCP JSON file needs to be modified as shown below: macOS Example Configuration { “mcpServers”: { “ask_nlw”: { “command”: “/Users/yourname/NLWeb/myenv/bin/python”, “args”: [ “/Users/yourname/NLWeb/code/chatbot_interface.py”, “—server”, “http://localhost:8000”, “—endpoint”, “/mcp” ], “cwd”: “/Users/yourname/NLWeb/code” } } } Windows Example Configuration { “mcpServers”: { “ask_nlw”: { “command”: “C:\\Users\\yourusername\\NLWeb\\myenv\\Scripts\\python”, “args”: [ “C:\\Users\\yourusername\\NLWeb\\code\\chatbot_interface.py”, “—server”, “http://localhost:8000”, “—endpoint”, “/mcp” ], “cwd”: “C:\\Users\\yourusername\\NLWeb\\code” } } } Note: For Windows paths, you need to use double backslashes (\\) to escape the backslash character in JSON. 3. Go to the 'code/python’ folder in NLWeb and run the command. Enter your virtual environment and start your NLWeb local server. Make sure it is configured to access the data you would like to ask about from Claude. # On macOS source ../myenv/bin/activate python app-file.py # On Windows ..\myenv\Scripts\activate python app-file.py 4. Open Claude Desktop. It should ask you to trust the 'ask_nlw' external connection if it is configured correctly. After clicking yes and the welcome page appears, you should see 'ask_nlw' in the bottom right '+' options. Select it to start a query. 5. To query NLWeb, just type 'ask_nlw' in your prompt to Claude. You'll notice that you also get the full JSON script for your results. Remember, you must have your local NLWeb server started to use this option. Learn More Vector Store in Azure Postgres Flexible Server Generative AI in Azure Postgres Flexible Server NLWeb GitHub repo includes: A reference server for handling natural language queries PGvector integration1.2KViews3likes1CommentBuild AI-Ready Apps and Agents with PostgreSQL on Azure
As developers, we’re constantly looking for ways to build smarter, faster, and more scalable applications. The Microsoft Reactor series, Build AI apps with Azure Database for PostgreSQL, is a four-part livestream experience designed to help you do just that—by combining the power of PostgreSQL with Azure’s AI capabilities. Dive into the world of AI apps and agents with Azure Database for PostgreSQL in this engaging video series—your ideal starting point for building intelligent solutions and improving your workflow. Get ready to explore the fundamentals of AI and discover how vector support in databases can elevate your applications. Uncover how innovative tools like the Visual Studio Code extension for PostgreSQL and GitHub Copilot can make your database work faster and more efficient. You'll also see how to create intelligent apps and AI agents using frameworks such as LangChain and Semantic Kernel. Why This Series Matters PostgreSQL is already a favorite among developers for its flexibility and open-source strength. But when paired with Azure’s AI services, it becomes a launchpad for intelligent applications. This series walks you through how to: Orchestrate AI agents using PostgreSQL as a foundation. Enhance semantic search with vector support and indexes like DiskANN. Integrate Azure AI services to enrich your data and user experiences. Boost productivity with tools like the Visual Studio Code PostgreSQL extension and GitHub Copilot. What You'll Learn Each session is packed with practical insights: Episode 1: Laying the foundation: AI-powered apps and agents with Azure Database for PostgreSQL We introduce key AI concepts, setting the stage for a deeper understanding of Large Language Models (LLMs) and its applications, we will explore the capabilities of Azure Database for PostgreSQL, focusing on how its vector support enables advanced semantic search through technologies like DiskANN indexes. We'll also discuss the Azure AI extension, which brings powerful AI features to your data projects, helping you enrich your applications with enhanced search relevance and intelligent insights, and provide a solid foundation for leveraging these tools in your own solutions. Register here Episode 2: Accelerate your data and AI tasks with the VS Code extension for PostgreSQL and GitHub Copilot This talk will delve into how the Visual Studio Code extension for PostgreSQL can streamline your database management, while GitHub Copilot's AI-powered assistance can boost your productivity. Learn how to seamlessly integrate these tools to enhance your workflow, automate repetitive tasks, and write efficient code faster. Whether you're a developer, data scientist, or database administrator, this session will provide you with practical insights and techniques to elevate your data and AI projects. Join us to learn how to effectively use these advanced tools and take your data skills to the next level. Register here Episode 3: Build your own AI copilot for financial apps with PostgreSQL Join us to discover how to transform traditional financial applications into intelligent, AI-powered solutions with Azure Database for PostgreSQL. In this hands-on session, you'll learn to integrate generative AI for high-quality responses to financial queries using PDF-based Statements of Work and invoices, perform AI-driven data validation, apply the Azure AI extension, implement vector search with DiskANN indexes, enhance results with semantic re-ranking, use the LangChain framework, and leverage GraphRAG on Azure Database for PostgreSQL. By the end, you’ll have gained practical skills to build end-to-end AI-driven applications using your own data and projects. Register here Episode 4: Build advanced AI Agents with PostgreSQL Using a sample dataset of legal cases, we’ll show how AI technologies empower intelligent agents to provide high-quality answers to legal queries. In this session, you’ll learn to build an advanced AI agent with Azure Database for PostgreSQL, integrating generative AI for enhanced data validation, retrieval-augmented generation (RAG), semantic re-ranking, Semantic Kernel, and GraphRAG via the Apache AGE Graph extension. This practical demonstration offers insights into developing robust, intelligent solutions using your own data. Register here Join us for an inspiring and hands-on experience—don’t miss out! Get the full series details and register now: https://aka.ms/postgres-ai-reactor-series744Views2likes0CommentsDiskANN on Azure Database for PostgreSQL – Now Generally Available
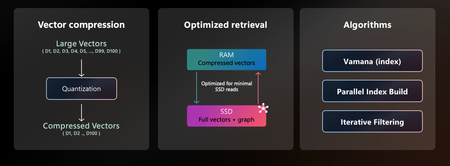
By Abe Omorogbe, Senior PM We’re thrilled to announce the General Availability (GA) of DiskANN for Azure Database for PostgreSQL unlocking fast, scalable, and cost-effective vector search for production workloads. Building on momentum from our private and public previews, this release brings major upgrades that directly reflect customer feedback for better performance, lower memory usage, and greater flexibility for advanced GenAI applications. Whether you're working with massive datasets or deploying on resource-constrained environments, DiskANN now offers an index that scales effortlessly. DiskANN delivers up to 10x faster speed, 4x lower costs and up to 96x lower memory footprint compared to the industry standard pgvector HNSW. In this post, we’ll highlight the following: Common pain points in large-scale vector search New features in the GA release Dive into product quantization (PQ) the main optimization that powers DiskANN’s performance Share internal testing results that demonstrate how DiskANN stacks up against alternatives like HNSW. Read on to see why DiskANN is ready for your most demanding vector search workloads. What is DiskANN? Developed by Microsoft Research and battle-tested across global services like Bing and Microsoft 365, DiskANN is a high-performance approximate nearest neighbor (ANN) search algorithm built for scalable vector search. It delivers the high recall, high throughput, and low latency required by today’s most demanding agentic AI and retrieval-augmented generation (RAG) workloads. DiskANN offers the following benefits: Low Latency: Its graph-based index structure minimizes SSD reads during search, enabling high throughput and consistently low query latency. Cost Efficiency: DiskANN’s design reduces memory usage up to 96x smaller than standard indexing methods helping lower infrastructure costs. Scalability: Optimized for massive datasets, DiskANN is built to efficiently handle millions of vectors, making it ideal for production-scale applications. Accuracy: DiskANN delivers highly accurate results without sacrificing speed or precision. Integration: DiskANN works natively with Azure Database for PostgreSQL, leveraging the power and flexibility of PostgreSQL. Breaking Through the Limits of Large-Scale Vector Search Vector search has become essential for powering AI applications from recommendation systems to agentic AI but scaling it has been anything but easy. If you've worked with large vector datasets, you've likely run into the same roadblocks: Your data is too big to fit in memory leading to slower searches. Building indexes takes forever and eats up your resources. You have no idea how long the indexing process will take or where it’s stuck. Your embedding model outputs high-dimensional vectors, but your database can’t handle them. Database bills spiral out of control due to memory intensive machines needed for efficient search on a large dataset. Sound familiar? These are not edge cases they’re the standard challenges faced by anyone trying to scale Postgres’s vector search capabilities into real-world production workloads. With the General Availability (GA) release of DiskANN for Azure Database for PostgreSQL, we’re tackling these problems head-on, bringing production-ready scale, speed, and efficiency to vector search. Let’s break down how. Product Quantization (PQ) for Lower Memory and Storage Costs (preview) One of the biggest blockers in vector search is fitting your data into memory. When using pgvector’s HNSW and your vector data doesn't fit in memory, this can lead to compute intensive I/O operations, causing degraded performance. With the GA release, DiskANN introduces a preview version of Product Quantization (PQ)—a powerful vector compression technique that makes it possible to store and search massive datasets with a dramatically smaller memory footprint. With PQ enabled, you get: Reduced memory usage — enabling datasets that previously couldn’t fit in RAM. Lower memory costs — compressed vectors mean smaller indexes and cheaper monthly bills. Faster performance — less I/O pressure means lower latency and higher throughput. Example results In our internal testing, we use pg_diskann on Azure Postgres to build an index of 35 million 768D vectors and ran benchmarking queries on an 8-core 32GB machine. The results were: 32x lower memory footprint than using pgvector’s HNSW and 4x lower cost due to significantly less resources needed to run vector search queries effectively compared to HNSW. Also, compared to standard HSNW, pg_diskann delivers up to 10x lower latency @ 95% recall especially in large scale scenarios with millions of vectors. When testing higher quality embedding such as OpenAI v3-large (3072 dimensions), we saw up to 96x lower memory footprint, due to extremely efficient compressing. In this scenario PQ compresses each vector from 12KB (3072 D, 4 bytes/D) to just 128B per quantized vector. Sign up for the preview today! To get access. Go Big: Supports vectors up to 16,000 dimensions Another big blocker for customers developing advanced GenAI applications with pgvector is that HNSW only supports indexing vectors up to 2,000 dimensions a limit that constrains the development of applications using high-dimensional embedding models which deliver high accuracy (i.e. text-embedding-large). With this release, DiskANN now supports vectors up to 16,000 dimensions. When you have product quantization enabled. Popular embedding models with over 2000 dimensions (text-embedding-large, E5-mistral-7b-instruct and NV-embed-v2) Faster Index Builds, Smarter Memory Usage Index creation has historically been a pain point, especially in previous versions of pg_diskann—especially for large datasets. In this GA release, we’ve significantly accelerated the build process through: Improved memory management using `maintenance_work_mem` more efficiently. Optimized algorithms that reduce disk I/O and CPU usage during indexing We’ve also published detailed documentation to guide you through best practices for faster index builds. The result? Index builds that are not only faster but more predictable and resource friendly. When indexing 1 millions vectors, the DiskANN GA version is ~2x faster. It took 696.0630 seconds vs 1172.3314 seconds in our DiskANN preview build. Real-Time Index Progress Tracking Previously, with pg_diskann building large indexes felt like working in the dark. Now, with the addition of improved progress reporting support, you can track exactly how far along your index build is—making it easier to monitor, plan, and troubleshoot during creation. Checking index build progress with PSQL in VSCode Use the following command in PSQL to check pg_diskann index build progress. SELECT phase, round(100.0 * blocks_done / nullif(blocks_total, 0), 1) AS "%" FROM pg_stat_progress_create_index; Using DiskANN on Azure Database for PostgreSQL Using DiskANN on Azure Database for PostgreSQL is easy. Enable the pgvector & diskann Extension: Allowlist the pgvector and diskann extension within your server configuration. Activating DiskANN in Azure Database for PostgreSQL Create Extension in Postgres: Create the pg_diskann extension on your database along with any dependencies. CREATE EXTENSION IF NOT EXISTS pg_diskann CASCADE; Create a Vector Column: Define a table to store your vector data, including a column of type vector for the vector embeddings. CREATE TABLE demo ( id INT GENERATED ALWAYS AS IDENTITY PRIMARY KEY, embedding public.vector(3) ); INSERT INTO demo (embedding) VALUES ('[1.0, 2.0, 3.0]'), ('[4.0, 5.0, 6.0]'), ('[7.0, 8.0, 9.0]'); Index the Vector Column: Create an index on the vector column to optimize search performance. The pg_diskann PostgreSQL extension is compatible with pgvector, it uses the same types, distance functions and syntactic style. To use Product Quanatization sign up for the preview today! CREATE INDEX demo_embedding_diskann_idx ON demo USING diskann (embedding vector_cosine_ops) Perform Vector Searches: Use SQL queries to search for similar vectors based on various distance metrics (cosine similarity in the example below). SELECT id, embedding FROM demo ORDER BY embedding <=> '[2.0, 3.0, 4.0]' LIMIT 5; Ready to Dive In? DiskANN’s GA release transforms PostgreSQL into a fully capable vector search platform for production AI workloads. It delivers: Support for millions of compressed vectors Compatibility with pgvector Reduced memory and storage costs Faster index creation Support for high-dimensional vectors Real-time indexing progress visibility Whether you’re building an enterprise-scale retrieval system or optimizing costs in a lean AI application, Use the DiskANN today and explore the future of AI-driven applications with the power of Azure Database for PostgreSQL! Run our end-to-end sample RAG app with DiskANN Learn More DiskANN on Azure Database for PostgreSQL is ready for production workloads. With Product Quantization, support for high-dimensional vectors, faster index creation, and clearer operational visibility, you can now scale your vector search applications even further — all while keeping costs low. To learn more, check out our documentation and start building today!1.8KViews2likes0Comments