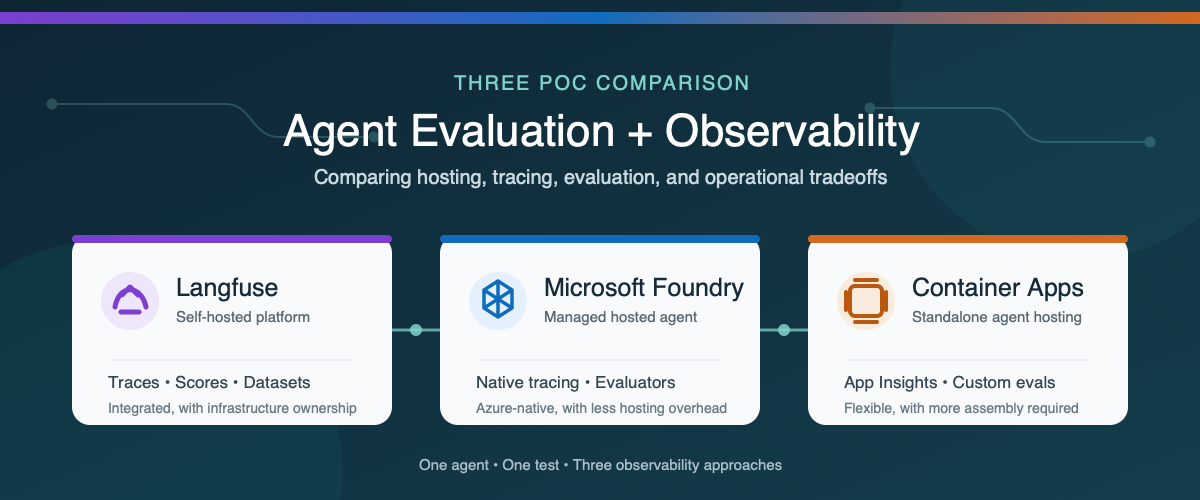
This article compares three approaches to AI agent evaluation and observability: self-hosted Langfuse, a Microsoft Foundry hosted agent, and a standalone agent on Azure Container Apps with Azure Monitor. We examine how tracing, evaluation, custom metrics, dashboards, and operational responsibilities differ across each option. The findings can help teams choose an approach that fits their authentication, networking, security, and operating requirements.
Why evaluation and observability belong together
Agent evaluation and observability answer two related questions:
- Is the agent producing the right result?
- What happened from the initial request through every model and tool call?
Evaluation measures quality with repeatable scores (is our system working), such as task completion, tool-call accuracy, groundedness, or safety. Observability captures the end-to-end execution flow, including prompts, model responses, tool calls, latency, token usage, and errors.
You need both. A score can tell you that an agent failed, while a trace helps you understand why.
Microsoft provides several ways to host and monitor agents. You can use a Microsoft Foundry hosted agent with integrated tracing and evaluation, or run the agent independently on a service such as Azure Container Apps and connect it to Azure Monitor. Open-source platforms such as Langfuse provide another option and can be self-hosted in Azure.
We built three proofs of concept (POCs) to compare these approaches:
- Self-hosted Langfuse
- A Microsoft Foundry hosted agent
- A standalone agent on Azure Container Apps
The best choice depends on more than features. Authentication, networking, security boundaries, operational ownership, and the existing Azure architecture all affect the decision.
Note
These findings come from one controlled comparison, not a general performance benchmark. We used the same agent image, model deployment, prompt, tools, and synthetic test data in all three POCs.
The common test
The test agent summarized a synthetic portfolio. It had to call three deterministic tools in a fixed order:
- Load the dataset
- Validate its schema
- Compute the summary
The expected answer was known in advance, which allowed us to evaluate both the final result and the tool trajectory. We also created a deterministic tool-call-accuracy score so we could compare how each platform stored and displayed the same custom metric.
POC 1: Self-hosted Langfuse
For the Langfuse POC, one private Azure virtual machine ran the agent and the Langfuse stack with Docker Compose. The deployment included Langfuse web and worker services, PostgreSQL, ClickHouse, Redis, MinIO, and an OpenTelemetry Collector. Azure Bastion provided private administrative access, and a managed identity retrieved secrets from Azure Key Vault.
The main advantage was the integrated experience. Traces, scores, datasets, experiments, annotations, latency, token usage, and cost appeared in one application. We could move from the original prompt to each tool call, the final response, and the evaluation score without building a separate dashboard.
That capability comes with operational responsibility. A production self-hosted deployment requires patching, scaling, backup, recovery, data retention, access control, and monitoring for the Langfuse services and their data stores.
Choose this approach when a unified, open-source AI engineering platform and deployment control are higher priorities than minimizing platform operations.
POC 2: Microsoft Foundry hosted agent
For the Foundry POC, Microsoft Foundry hosted the agent from a pinned container image. Application Insights and Log Analytics stored the telemetry. We used Foundry's Traces experience for agent trajectories and added an Azure Workbook for custom evaluation metrics.
Foundry provided the strongest Azure-native developer experience. Its trace view displayed model and tool activity as an agent trajectory, and its evaluation capabilities included built-in and custom evaluators. The underlying traces still flowed to Application Insights, where they could be queried and used in Azure Monitor visualizations.
The tradeoff is architectural alignment. The application must fit the customer's Foundry account, identity, networking, and deployment model. Custom business metrics can also require additional emission and visualization work beyond the native evaluation experience.
Choose this approach when managed agent hosting, Foundry-native tracing, and Azure-native evaluation are the priorities.
POC 3: Standalone agent on Azure Container Apps
For the third POC, we removed Foundry from the hosting path. The same image ran as an Azure Container App and used a managed identity to pull from Azure Container Registry and call Azure OpenAI. OpenTelemetry sent agent activity to Application Insights and Log Analytics.
This POC demonstrated that the Azure Monitor foundation is not limited to Foundry-hosted agents. Application Insights still provided an end-to-end transaction waterfall showing model calls, tool executions, latency, and errors, along with agent-level monitoring views.
The difference was the amount of assembly required. The team owns application instrumentation, the evaluation runner, custom metric emission, dashboards, and CI integration. The result offers more control over hosting, authentication, ingress, and network placement, but it requires more engineering than the Foundry-native experience.
Choose this approach when the agent must fit an existing container platform or custom security architecture and the team is prepared to build the evaluation workflow around it.
Side-by-side comparison
| Decision area | Langfuse | Foundry hosted agent | Azure Container Apps |
|---|---|---|---|
| Agent hosting | Customer-operated in this POC | Microsoft-managed hosted agent | Customer-managed container app |
| Primary trace experience | Native Langfuse tracing | Foundry Traces plus Application Insights | Application Insights |
| Evaluation | Native scores, evaluators, datasets, and experiments | Foundry built-in and custom evaluators | Custom runner or separate evaluation service |
| Custom metrics | Native scores and dashboards | Emit to Azure Monitor and visualize as needed | Emit to Azure Monitor and visualize as needed |
| Infrastructure ownership | Highest | Lowest for agent hosting | Moderate |
| Architecture flexibility | High, but the platform must be operated | Aligned to Foundry architecture | Highest for the application hosting layer |
| Best fit | Integrated open-source AI engineering platform | Managed Azure-native agent experience | Existing container and security architecture |
What we learned
All three approaches can support meaningful evaluation and observability. The real difference is where the capabilities live and how much the customer must assemble and operate.
- Langfuse provided the most integrated tracing and evaluation experience in this comparison, but we owned the platform infrastructure.
- Foundry reduced hosting operations and provided a purpose-built agent trace and evaluation experience.
- Azure Container Apps provided the greatest hosting flexibility while preserving Azure Monitor observability, but required us to supply the evaluation and custom visualization layers.
Because all three POCs used the same model, prompt, and tool sequence, the LLM token cost for an equivalent run was effectively the same. Platform and infrastructure costs were not equivalent and require a separate estimate based on scale, retention, networking, support, and operational requirements.
The decision should start with the customer's constraints:
- Does the agent fit the Foundry hosting and identity model?
- Does the organization want to operate an open-source observability platform?
- Does the agent need to run inside an existing container and network architecture?
- Which evaluation capabilities must be available before deployment and in production?
- Who will own instrumentation, dashboards, storage, upgrades, and incident response?
There is no single correct platform for every agent. The right choice is the one that provides the required evidence about quality and behavior while fitting the customer's security, architecture, and operating model.
Learn more

 Microsoft