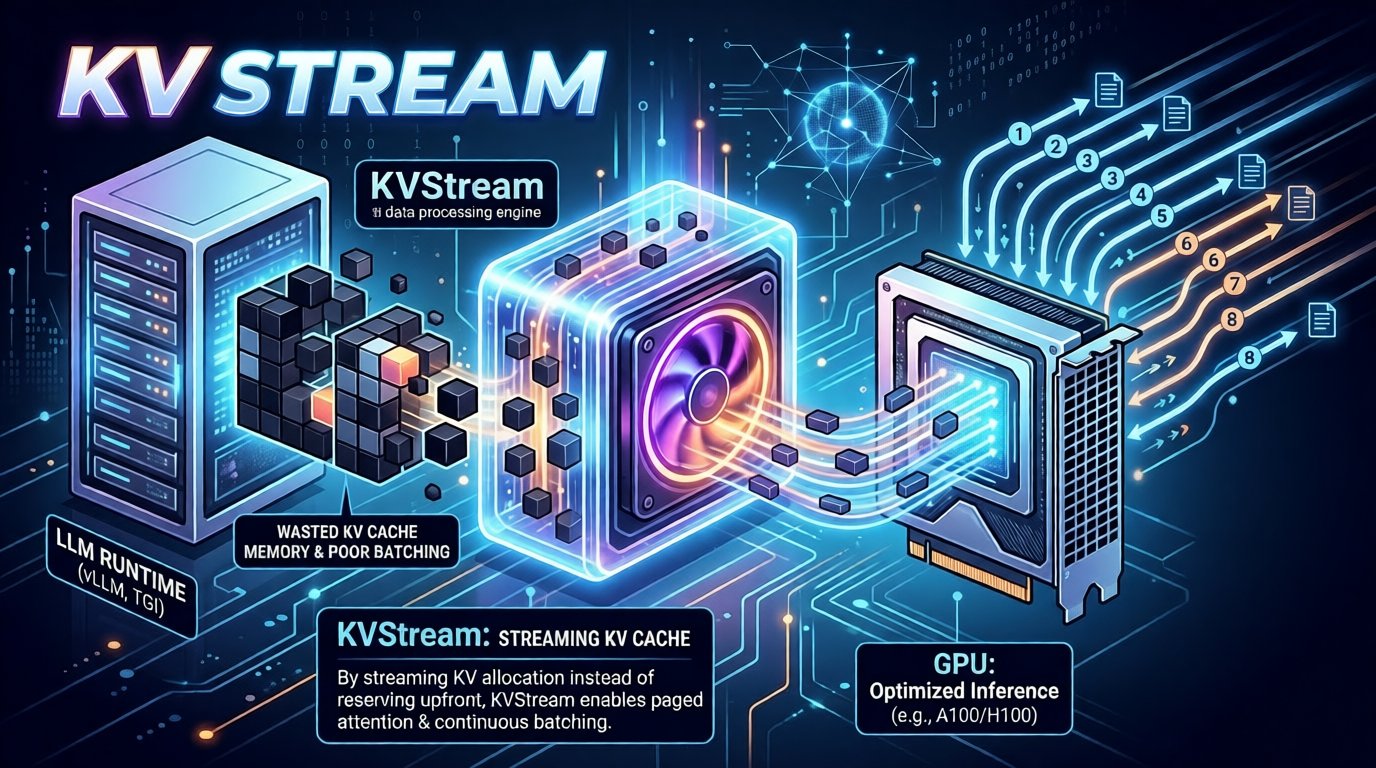
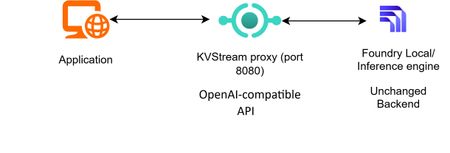
In the world of local LLM deployment, the biggest bottleneck isn't always raw computing power it's memory management, where static, upfront allocations for Key-Value (KV) caching lead to severely wasted VRAM and rigid, inefficient batching. Designed to sit directly in front of your existing LLM runtime, KVStream solves this by dynamically streaming KV allocation on the fly instead of pre-reserving it. This approach unlocks seamless paged attention and continuous batching, allowing you to maximize hardware efficiency and squeeze up to 8× more concurrent requests out of the exact same GPU.
Updated Jun 23, 2026
Version 2.0
