sql server
439 Topics
SSMS Object Explorer doesn't show any of my databases
I'm a very green amateur sysadmin of a SQL Server installation that only I will use. I've gotten myself in trouble, and I hope someone can help me get out of it! I installed an updated version of SQL Server without understanding how a connection's server name determines which version is used. I ended up with the new version installed, but the old version still executing queries. I eventually found a clear explanation of how server names work, and I fixed the problem, but I did a lot of thrashing around first, and now I find that none of my databases are visible to any of the defined server names in SSMS's Object Explorer. The databases are still present in the file system, but I can't get at them. I have never created a user (another concept I initially didn't understand), so every defined server name must be connecting as the default user created by the installer, with role 'sysadmin'. (I have confirmed that the user is a sysadmin with a query.) Sysadmin users are supposed to have access to all databases. I understand that it's not even possible to deny a sysadmin access to a database with REVOKE or DENY, or, I assume, by any similar means. Given that, how could my databases have disappeared from Object Explorer? How can I get them back?49Views0likes3Comments
Managing security with Database Hub in Fabric: From signals to action
As organizations embrace AI, cloud modernization, and increasingly complex application architectures, the database estate continues to grow. What was once a handful of databases can quickly become hundreds or thousands of resources spread across subscriptions, regions, clouds, and database platforms. Security teams and database administrators face a common challenge: understanding the security posture of this growing estate and knowing where to focus attention first. While security controls exist across individual database services, assessing security posture at an estate level often requires navigating multiple portals, manually collecting findings, and piecing together information from different tools. Database Hub in Microsoft Fabric, now in public preview, gives database teams a unified place to discover their database estate and review security posture across supported database platforms. This estate-wide experience helps teams identify potential security gaps, understand where attention may be needed, and determine the right next step to improve overall security posture for databases. Security challenges at database estate scale Most organizations are no longer managing a single database platform. A typical enterprise environment may include: Azure SQL Database, Azure Database for PostgreSQL, Azure Cosmos DB, SQL Server instances running on-premises or through Azure Arc, SQL databases running inside Microsoft Fabric and additional database platforms. As environments expand, common security questions become increasingly difficult to answer: Which databases require attention? Where are security best practices not being followed? Which issues affect the largest portion of the estate? What action should be taken first? Customers need a simpler way to assess security posture across the entire estate rather than investigating databases individually. Database Hub was designed to help answer those questions. Security posture at a glance Database Hub provides a centralized view of database inventory, health, performance, optimization opportunities, and security findings across supported platforms. For security scenarios, the goal is simple: Help customers quickly understand the current posture of their database estate and identify the issues that matter most. Database Hub aggregates security findings across available resources and presents them in an estate-wide view, allowing teams to immediately see areas that require attention. Instead of manually reviewing databases one at a time, administrators can start with a single consolidated view and understand where security gaps exist across their environment. The current public preview introduces an initial set of security checks across supported database platforms. Depending on the database type, these checks cover areas such as authentication, data protection, auditing, and network security. For details about the checks currently available for database resources, refer to the Learn documentation. As we continue to work with customers throughout the preview and beyond, we will use feedback to refine the security experience, expand coverage across database platforms, and introduce additional capabilities. These signals aren't intended to replace the deeper security capabilities available within each database platform. Instead, Database Hub provides an estate-level starting point for identifying potential gaps and deciding where to investigate further. Database Hub complements existing security products and services by providing a unified view of broadly applicable security practices across the database estate. Customers can use these experiences together for a more complete understanding of database security posture. Prioritize what matters most Not all security findings have the same impact. Some controls affect a small number of databases. Others may represent risks across large portions of the estate. Database Hub helps customers focus on their investigation by distinguishing security issues that may require immediate attention from longer-term suggestions, and by showing how many resources are affected. This estate-wide context helps teams understand the potential scope of a finding and decide where to investigate first. Rather than asking: "Which database should I investigate next?" Teams can answer: "Which security issue should I address first?" Move from discovery to action Visibility alone is not enough. Once a finding is identified, the next step is to understand why it matters and what action should be taken. Database Hub provides additional context for findings and helps guide customers toward remediation. Teams can review affected resources, understand the recommendation, and, where supported, refer to relevant documentation and continue to the appropriate management experience to take corrective action. What’s next for security in Database Hub The security signals described above are available as part of the current public preview. Looking ahead, we plan to build on this foundation with additional capabilities that help teams continuously understand, prioritize, and improve security posture across their database estate. We are exploring several areas of investment, including: Broader security coverage: We plan to add security signals across more supported database types and security areas, providing a more complete picture of your database security posture. A dedicated Security page in Database Hub: We plan to create a focused experience that brings security posture, prioritized findings, and affected resources together. The goal is to help security administrators understand overall posture at a glance, see what parts of the estate need attention, and take the right action to improve it. Agentic security analysis: We are exploring agentic capabilities that go beyond configuration-based checks to analyze more complex security scenarios and surface insights, for example, identifying users or applications that may have more privileges than they need and recommend opportunities to move toward least-privilege access. These capabilities represent our forward-looking direction and are not part of the current preview. Customer feedback will help us refine this vision and prioritize the capabilities that provide the greatest value. Try security experiences in Database Hub today Whether you're responsible for a handful of databases or a global database estate spanning multiple platforms, Database Hub provides a simpler way to understand security posture, prioritize action, and move towards a more secure database environment. If you're using Database Hub today, you can already explore the available security experiences and security findings across supported database platforms. As you explore Database Hub, we’d love to hear which security signals, insights, and agentic experiences would be most valuable for managing your database estate. Please share your feedback directly within Database Hub by using the "Feedback" option. Your feedback will help us prioritize the capabilities and experiences we build next and align the Database Hub security roadmap with how you manage security in real-world database estates. We're excited to continue learning from customers and shaping the next generation of database security experiences together. Learn more Explore Database Hub in Microsoft Fabric Review Database Hub documentation on Microsoft Learn262Views1like0CommentsMake Estate yours: Focus on the databases and issues you own in Database Hub
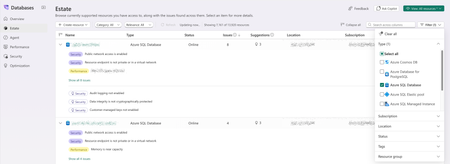
Database Hub in Microsoft Fabric is now in public preview. Estate experience brings every supported database you can access into one inventory, with the issues and suggestions found across them. In a large organization, that can mean thousands of resources. But most people own only part of the estate: a set of production databases, a few subscriptions, one resource group. This post shows how to shape Estate around your part, save it as a custom view, and use it to triage and bring in help. The examples use Azure SQL Database; the same steps work for PostgreSQL and Azure Cosmos DB. Which resources are mine? While in Estate view select Filter to narrow the list by Type, Subscription, Location, Status, Tags, or Resource group. The grid and the resource count update as you select values; Filter (1) shows how many dimensions are active, and Clear all resets them. Looking for one resource? Search across columns matches names, locations, subscriptions, and more. Which issues should I focus on? Each row shows its Issues and Suggestions counts and opens expanded, so findings are readable at a glance: issues with a filled Security or Performance tag, suggestions marked with a lightbulb. Open Category and select Security, Performance, Optimization, or a combination. Use Relevance to keep only resources with Issues or Suggestions. The grid is sorted by issue count, so the resources that need the most attention come first. How do I get back here tomorrow? Once Estate shows what you want, save it. An asterisk after the view name (View: All resources *) means your filters have unsaved changes. Select View > Save. Choose Save as new custom view and give it a name that describes the scope, such as sqlDB-sec-perf-issues. Select Apply. The view now appears under Custom views in the View menu. It saves filters, not results, so you always see the current state of those resources. What's wrong, and what should I do about it? Select an issue to open its detail page. Here, the top database reports Public network access is enabled. The Summary explains why it matters: public reachability increases exposure to credential attacks, scanning, and firewall mistakes. The Recommended action gives the fix and its precondition: Disable public network access after confirming that all clients can connect through approved private connectivity. Resolve in Azure portal opens the resource. Database Hub doesn't change the resource for you; you make the change in the tool that owns it, under your existing permissions. Back returns you to Estate with your view intact. Who can help me fix it? That precondition is often the hard part: confirming every client can connect privately may take your networking or application team. Bring them into the same view. Select View > Share, then Copy link. The link carries your current filters, so a colleague starts from the same scope. Each person still sees only the resources they already have access to; sharing never grants access. Need the list for a change ticket? Select Export view (as .csv). CSV files don't carry sensitivity labels, so handle the file according to your organization's data policies. What needs attention in my part of the estate? Your view isn't limited to Estate. Open Overview, select the same view from the View menu, and every card and chart rescopes to it: the Estate issues summary, the Security, Performance, and Optimization cards with their top issues, and the performance trends. Overview now summarizes your backlog instead of the whole estate. Views are managed in Estate; Manage views (Estate) takes you there. o the resources you own. More in Estate Look up a resource without leaving the list Select a resource name to open its details next to the list: subscription, resource group, and logical server (each linking to the Azure portal), status, location, pricing tier, max storage, and tags. Connection strings for ADO.NET, JDBC, ODBC, PHP, and Go use Microsoft Entra authentication, and Open in Azure portal, Open in VS Code, and Open in SSMS are at the top. The … menu on each row adds quick actions Copy connection string, Open in editor, Enable performance monitoring, Create monitor from template and Set alert from template. Create a database where you work Create resource starts a new database from Estate, grouped by engine: SQL database in Fabric, Azure SQL Database, SQL Server instance, Azure Database for PostgreSQL, and Azure Cosmos DB for NoSQL. Get started Open Estate, filter to the resources you own, focus on the categories you triage, and save the result as a view. Then select it on Overview and start with what needs attention. Database Hub is in public preview; capabilities vary by service and preview configuration. See the Database Hub documentation for supported services and setup, and use Feedback in Database Hub to tell us what you'd like next.219Views1like1CommentMI link support for multiple databases in an Always On availability group for SQL Server (Preview)
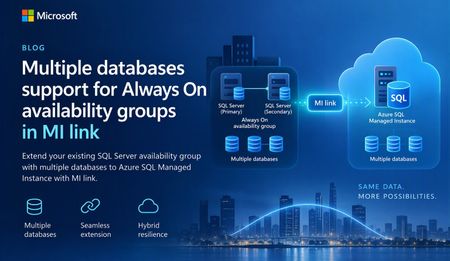
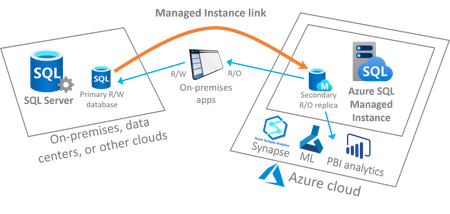
A simpler way to extend availability groups to Azure We are pleased to announce the preview of multi-database mode for Managed Instance link. The new mode lets you replicate multiple databases from an existing Always On availability group through a single link between SQL Server and Azure SQL Managed Instance. Managed Instance link uses distributed availability group technology to provide near-real-time replication between SQL Server and Azure SQL Managed Instance. It supports hybrid architectures, online migration, disaster recovery, and read-only workload offload. The link can be configured and managed through SQL Server Management Studio (SSMS), PowerShell, Azure CLI, and Azure APIs. Previously, each link supported one database. Customers with multi-database availability groups therefore had to split databases into separate availability groups and create a link for each database. Multi-database mode removes that limitation for supported SQL Server versions and editions, while the existing single-database mode remains available for earlier versions and other supported configurations. What you can do with multi-database link mode Migrate multiple databases to Azure SQL Managed Instance with minimal cutover downtime. Offload read-only workloads, including reporting and analytics, to the secondary replica. Use Azure SQL Managed Instance as a disaster recovery target for supported SQL Server versions. Start replication in either direction when the SQL Server version and Azure SQL Managed Instance update policy support that direction. Reverse primary and secondary roles through a planned failover. Build hybrid and multicloud topologies that place database groups where they are most useful. Preview requirements Requirement Details SQL Server SQL Server 2022 with CU27 and later or SQL Server 2025 with CU9 and later. Edition Enterprise or Developer edition. Standard edition is not supported for multi-database mode because Basic availability groups support only a single database. Azure SQL Managed Instance Use a compatible managed instance update policy , either SQL Server 2025, or Always-up-to-date. Note: Managed Instances with SQL Server 2022 update policy are not supported at this time. You can still use SQL Server 2022 to replicate your availability group to a Managed Instance with the SQL Server 2025 or Always-up-to-date update policy, but you will not be able to fail back to SQL Server 2022. We expect support for Managed Instances using the SQL Server 2022 update policy to become available in the coming weeks. This blog post will be updated when support becomes available. SSMS SSMS 22.10.2 or later for the multi-database link capability. Automation Az module 16.3.0 or later and Az.Sql 7.1.0 or later, or the corresponding Azure APIs. One link for an existing multi-database availability group If you already use an Always On availability group, multi-database link mode lets you extend the complete database group to Azure SQL Managed Instance without creating a separate availability group for every database. All databases in the link move together as one managed group. Databases on the primary are read-write, while their copies on the secondary are read-only. Use of your existing Always On AG listener endpoint is supported with multi-database mode MI link, allowing the link to remain operational after a local AG failover. Image 1: A multi-database Always On availability group replicated to Azure SQL Managed Instance through one Managed Instance link. The diagram illustrates the availability group relationship rather than a specific Azure SQL Managed Instance service-tier replica count. Managed Instance link is supported across all Azure SQL Managed Instance service tiers. Run multiple links in different directions A single SQL Server instance can participate in multiple links. Each link can carry a different availability group, and supported links can replicate in different directions at the same time. In the following example, AG1 (containing DB1, DB2, and DB3) replicates from SQL Server to Azure SQL Managed Instance through MI link 1. AG2 (containing DB4, DB5, and DB6) replicates from Azure SQL Managed Instance to SQL Server through MI link 2. Both links can operate at the same time between the two instances. Image 2: Two multi-database availability groups using separate links with opposite replication directions. Important: Database names must be unique in this configuration. A database cannot be renamed on the secondary while it is participating in replication to resolve a naming conflict. Replicate one availability group to multiple managed instances Multi-database mode also supports fan-out topologies. You can replicate multiple availability groups to one managed instance, or replicate the same availability group to different managed instances. For example, separate links can target managed instances in different Azure regions. Image 3: One multi-database availability group replicated through separate links to two Azure SQL managed instances. Get started To evaluate multi-database mode during preview: Confirm that the SQL Server version, edition, servicing level, and Azure SQL Managed Instance update policy meet the preview requirements. Upgrade to SSMS 22.10.2 or later, or use a supported automation interface. Enable multi-database mode before creating a multi-database link. Create the link from the existing Always On availability group and validate synchronization for every database. Review the Azure documentation for multi-database Managed Instance link configuration, limitations, monitoring, failover, and cleanup guidance. Share your feedback We would love to hear about your experience with multi-database mode. Please share questions, feedback, and feature suggestions through the Managed Instance link feedback form.461Views0likes0CommentsManaged Instance link with failover groups (limited preview)
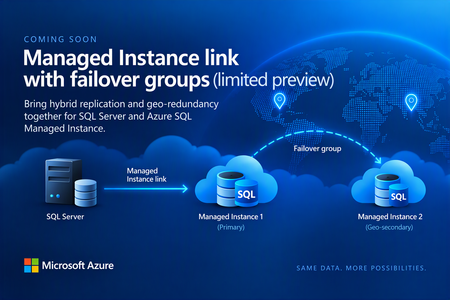
Before we kick off the preview, we’d like to hear from customers interested in trying it. The new capability will let you replicate data from SQL Server to a managed instance that’s part of a failover group, combining hybrid replication with geo-redundancy in Azure. The preview isn’t starting just yet. We expect to begin onboarding customers in the coming weeks, and capacity will be very limited. If this is something you’d like to try, let us know by filling out the sign-up form. Register your interest in the upcoming limited preview: https://aka.ms/milink-fog-signup What are the Managed Instance link and failover groups? The Managed Instance link enables near real-time data replication between SQL Server and Azure SQL Managed Instance. Built on distributed availability groups, it replicates user databases in near real time from SQL Server 2016 and later hosted anywhere to Azure SQL Managed Instance, or from Azure SQL Managed Instance to SQL Server 2022 or later. Customers use the Managed Instance link for: Offloading read-only workloads to Azure, or from Azure back to on-premises. Online migration from on-premises to Azure, or from Azure back to on-premises, with minimal downtime. Bidirectional disaster recovery between SQL Server and Azure. Failover groups, also known as geo-replication, manage the replication and failover of user databases from one managed instance to another managed instance in a different Azure region. They provide read-write and read-only listener endpoints that remain unchanged after a geo-failover, so applications don’t need connection-string changes. The geo-secondary can also take on read-only workloads. Until now, you couldn’t combine the two scenarios. Establishing a two-hop replication path from SQL Server to Managed Instance 1 and then to Managed Instance 2 presents a technical challenge and isn’t supported today. As a result, you’ve had to choose between using the MI link with a single managed instance or using failover groups without the MI link. The capability we’re getting ready to preview removes that trade-off. SQL Server replicates to MI-1 through the Managed Instance link, while the failover group keeps MI-2 in sync in a second Azure region, as shown in the figure below. Figure 1: SQL Server replicating to a primary managed instance through the Managed Instance link, with the failover group geo-replicating to a secondary managed instance in another region. Replication in both directions In this configuration, the link works bidirectionally. You can replicate from SQL Server to Azure and back from Azure to SQL Server. In practice, that means you can fail over to Azure and, when you’re ready, fail back to SQL Server. Version requirements follow the existing MI link documentation. Two-way replication and failback require SQL Server 2022 or SQL Server 2025, with the managed instance on the matching SQL Server 2022 or SQL Server 2025 update policy. SQL Server 2016 through 2019 support only one-way replication to Azure. What this unlocks Hybrid disaster recovery with regional resilience in Azure: Keep SQL Server as your primary, protected by Managed Instance in one Azure region and a geo-secondary Managed Instance in another Azure region. Migration to Azure with minimal downtime: Land directly in a geo-redundant configuration without having to re-seed or re-architect after cutover. Reverse migration: Move from a geo-redundant Azure configuration back to on-premises SQL Server. Read scale-out: Offload read-only workloads to a geo-redundant Azure SQL Managed Instance configuration. Reverse data replication: Replicate data from a geo-redundant Managed Instance configuration back to on-premises SQL Server. Who should apply and how the limited preview works If you run SQL Server workloads that could benefit from both hybrid replication and geo redundancy on Azure SQL Managed Instance, we’d love to hear from you. A few things to know The limited preview hasn’t started yet. Right now, we’re collecting interest from customers who would like to participate. We expect onboarding to begin in the coming weeks. Capacity will be limited, and the product team will contact selected participants directly. The preview isn’t intended for production workloads unless agreed with the product team. We’ll be looking for feedback from participating customers to help us shape the capability as it evolves. Interested? Let us know If combining the Managed Instance link with failover groups could simplify your hybrid, disaster recovery, or migration architecture, register your interest today. We’re looking forward to hearing about your scenarios and working with some of you as we get the preview underway. Register your interest in the upcoming limited preview: https://aka.ms/milink-fog-signup Learn more • Overview of the Managed Instance link • Overview of Failover groups for Azure SQL Managed Instance239Views2likes0CommentsLessons Learned #560: SQL Is Slow — What Can Query Store and SSMS Copilot Uncover?
In our recently delivered session, “SQL Is Slow — What Can Query Store and SSMS Copilot Uncover?”, we demonstrated step by step how to investigate a performance problem by combining Query Store with Copilot’s capabilities in SSMS. The demonstration starts with a PHP program executing queries while we grow a table from a few hundred to millions of rows. As different execution plans appear and performance changes, we follow the evidence in Query Store to uncover what is happening and decide what to investigate next. One clue stood out. The query took about 12 milliseconds per execution in one interval and almost 2.5 seconds in another interval under the same Plan ID. Other plans appeared during the complete lab. Understanding both the differences between plans and the changes within a plan became part of the investigation. Along the way, we demonstrated how a guided conversation with Copilot can become an Agent investigation, and how the investigation itself can be captured in a reusable skill. The useful result was a method that keeps asking for evidence before accepting an explanation. The session brings the two tools together: Query Store supplies the recorded history, and Copilot helps us examine it and decide what to investigate next. The same troubleshooting story lets the audience follow Ask mode, Agent mode and the reusable skill without losing the connection to the underlying SQL evidence. A growing table and several execution plans For our sessions, we use a PHP program that generates 16 different simulations of performance and connectivity problems, allowing us to demonstrate how to investigate these scenarios through practical demos. We also have code developed in .NET and Java. In this demonstration, we add records to dbo.Notes in stages, reaching approximately 200, 32,000, 65,000, 2 million, and 4 million rows, while the PHP program executes dbo.GiveNotes with different @N values. This lets us observe how performance and execution plans evolve as the data volume grows. Several execution plans accumulated during the complete demonstration. We compared all of them, then inspected the runtime intervals within each Plan ID. The reference run revealed this change within the history of one plan: Average per execution Healthy interval Degraded interval Approximate increase CPU 7.69 ms 1,443.19 ms 188 times Duration 12.39 ms 2,473.68 ms 200 times Logical reads 68.39 12,233.10 179 times The duration increase was approximately 200 times. This comparison covers two intervals for one Plan ID, not the whole sequence of table sizes. It does not assign a particular plan or timing to each row-count stage. These are lab observations; identifiers and timings vary between runs. The reads were particularly revealing. Each execution was touching far more pages. A later plan change could not, by itself, explain degradation that had already started while the earlier plan remained in use. The next step was to investigate what had increased the work per execution. Build the timeline before choosing the explanation We first compared workload contributors using total CPU, elapsed duration, logical reads and execution count. Total consumption identified where the workload impact was concentrated; averages per execution helped distinguish expensive executions from a high volume of individually inexpensive calls. Next, we collected every plan for the selected query and compared runtime intervals chronologically. We discovered the identifiers from the database instead of supplying fixed Query IDs or Plan IDs. We asked both when another plan appeared and whether the cost had already increased before that change. A plan summary alone can hide this story. One average across a plan’s entire history blends its healthy and degraded periods. The interval history shows when the work changed and whether that happened before another plan appeared. Aggregation mattered. When combining runtime statistics, we weighted each average by its execution count. A simple average of interval averages would give a lightly used interval the same influence as a heavily used one. We also kept units explicit and separated execution types where needed. Weighted average = SUM(average value * execution count) / SUM(execution count) The increase in logical reads directed the investigation toward the amount of data processed and the access path. Waits could help explain elapsed time, but waits alone would not explain that increase in reads. dbo.GiveNotes filtered dbo.Notes on ID < @N and grouped by Name. The clustered primary key was on id2, a different column from the predicate. As rows were added, a reused plan could process more data; changing @N could also change how many rows qualified. A new Plan ID was a separate event to investigate, not an explanation to assume. Different @N values can qualify different numbers of rows, and table growth can increase the work even with an unchanged plan. We inspected distribution, statistics and access paths to test that explanation. Query Store interval averages alone do not tell us the parameter used by every execution, and parameter-sensitive behavior does not automatically prove parameter sniffing. One investigation through three Copilot experiences In Ask mode, we guided the conversation one question at a time. We first requested the Query Store overview, then asked which contributor to investigate and how its plans behaved over time. The staged prompts delayed statistics, index and parameter analysis until the runtime evidence justified those questions. Where required, we ran generated diagnostic T-SQL and brought the results back into the conversation. In Agent mode, we supplied the investigation goal and allowed Copilot to choose and execute diagnostic steps using the available SQL tools. We reviewed the proposed actions and kept the investigation read-only. The agent could use each result to decide what to inspect next. Finally, we captured the sequence in an Agent Skill. We wanted the next investigation to preserve the critical question: did the query become more expensive while the same plan was still being reused? Agent Skills provide task-specific instructions that Copilot can discover and use in Agent mode. We also demonstrated the reusable method through GitHub Copilot CLI. Database execution still requires a configured SQL tool or MCP server; without that capability, the workflow must generate diagnostics for the engineer to run. What we put into the reusable skill The SQL Performance Investigator pack captures the diagnostic sequence alongside the calculation rules and starting prompts. The agent is instructed to: Identify the main workload contributor and retain its Query ID. Collect all associated plans and their runtime history. Check whether degradation began while the same plan remained in use. Investigate relevant selectivity, statistics and index evidence. Separate confirmed observations from hypotheses and propose validation. A skill makes the method reusable; it does not guarantee the diagnosis is correct. Missing history, incorrect aggregation or a plausible but unsupported inference still need an engineer’s attention. We kept discovery read-only, with SQL permissions enforcing the access boundary. A proposed index still needs evidence of improvement In the demonstration, we evaluated an index with ID as its leading key and Name as an included column: CREATE NONCLUSTERED INDEX NOTES_IX1 ON dbo.Notes (ID) INCLUDE (Name); The key matches the range predicate, while the included column makes Name available for the aggregation. Whether this improves the workload depends on selectivity, data volume and the competing plans. Its storage and write costs also matter. We treated this as a remediation candidate. Validation requires a comparable workload, including parameter distribution and concurrency, followed by a Query Store comparison of reads, CPU, duration and variability. We did not equate an index recommendation with a demonstrated improvement. Statistics also need careful interpretation. An index histogram describes its leading key; adding Name as an INCLUDE column does not create a histogram on Name. An existing auto-created statistic should not be dropped merely because its column appears in a covering index. The lesson we took from the demonstration The complete story contained a growing table and multiple plans. Within that history, one plan became much more expensive before a later plan could explain the change. Comparing plans and examining changes within each plan gave us complementary evidence. Copilot helped us follow it, and the skill preserved the investigation sequence for another database. We enjoyed presenting this session. For DBAs, developers and support engineers, the session offers a practical way to watch a performance investigation unfold, from the PHP workload and Query Store history to the prompts and reusable skill. We look forward to continuing this demonstration and discussion with SQL user groups and the wider technical community. If you have encountered a query that became slower while the same plan remained in use, which evidence helped you explain the change? We would be interested to hear how you approached it. References and prerequisites For the SSMS Agent and Skills experience described here, Microsoft documents SSMS 22.7 or later with the AI Assistance workload and GitHub Copilot access. Query Store must be enabled with relevant history available. Specify the target server and database in the Agent prompt rather than relying on the active editor context. Check the current documentation before reproducing the session. GitHub Copilot Agent mode in SSMS Agent Skills in SSMS Monitoring performance by using Query Store Query Store runtime statistics Try the investigation with our prompts These prompts offer a practical starting point for the method demonstrated in our session. The Ask prompt is the opening prompt from our session workflow. The Agent prompts are adapted from our accompanying pack to make the target server, database and investigation window explicit. Replace the angle-bracket placeholders before submitting them. Start with Ask mode We began with a request for evidence, deliberately postponing diagnosis. Run the generated diagnostic query against the intended lab database and use its results for the next questions. I want to start a SQL performance troubleshooting investigation using Query Store. Generate a single read-only T-SQL query that I can execute in the current database to identify the main performance contributors. The query must use Query Store and return, for each query: * Query ID * Query text * Object or stored procedure name, when available * Number of execution plans * Number of executions * Total CPU time * Average CPU time per execution * Total duration * Average duration per execution * Total logical reads * Average logical reads per execution Aggregate Query Store runtime statistics correctly across runtime intervals and execution plans. Use weighted calculations based on count_executions. Do not calculate averages by simply averaging Query Store average values. Return CPU and duration values in milliseconds. Rank the results by total CPU consumption, but include all the metrics above so that we can determine later which resource is having the highest impact. Do not perform root-cause analysis yet. Do not include execution plan analysis, parameter sensitivity, statistics analysis, index analysis, or remediation recommendations. Only generate the read-only diagnostic T-SQL query that I should execute. We then asked which resource deserved investigation, which query contributed most, how all its plans performed over time, and whether the same Plan ID had become more expensive. Only after those answers did we investigate selectivity, statistics and indexes. The complete session workflow contains the staged follow-up prompts. Convert the conversation into an Agent investigation We moved the recurring calculation rules and diagnostic sequence into sql-performance-investigator. The starting prompt could then state the goal, scope and execution boundaries. The skill supplies the detailed method; the available SQL tools supply execution capability. The agent retains the discovered query and plan identifiers within the investigation. It should not ask the engineer to copy them between steps or assume the identifiers from a previous lab run. Run the method in SSMS Agent mode Make the skill available to SSMS, select Agent mode and verify the SQL tools are enabled. Specify the target explicitly because Agent mode does not inherit the active query editor context. Investigate the SQL performance problem on server <server>, database <database>, using Query Store for <UTC start> to <UTC end>. Use the sql-performance-investigator skill. Use the available sql-tools to execute read-only diagnostics and continue through the investigation, requesting approval where the host requires it. Automatically discover the dominant performance metric, target query, Query ID, all Plan IDs, runtime history, and any same-plan degradation. Retain the discovered identifiers internally. Investigate the evidence needed to explain the change, including selectivity, data distribution, statistics and existing indexes when relevant. Do not assume a plan change caused the degradation or label it parameter sniffing without evidence. Keep confirmed evidence, inference, hypotheses and missing evidence separate. Use execution-weighted averages and explicit units. If the requested history or permissions are unavailable, report the limitation. Do not create/drop indexes, update/drop statistics, force plans, clear caches, modify Query Store, or change data/schema. Finish with a supported diagnosis or remaining uncertainty, a proposed remediation if justified, and a Query Store before/after validation plan. Do not execute remediation. Use the same method in GitHub Copilot Our pack places the skill at .github/skills/sql-performance-investigator/SKILL.md and the Custom Agent at .github/agents/sql-performance-investigator.agent.md. The skill references workflow.md and query-store-rules.md for the detailed method. In GitHub Copilot CLI, select the SQL Performance Investigator custom agent and use this adapted starting prompt: Use the SQL Performance Investigator custom agent and the sql-performance-investigator skill. Investigate SQL performance on <server>, database <database>, for <UTC start> to <UTC end>, using Query Store from evidence to diagnosis. If a SQL execution tool/MCP is available, run only read-only diagnostics and continue through the investigation. Discover Query IDs and Plan IDs automatically and retain them internally. Follow the host approval requirements. If no SQL execution capability is available, generate one self-contained read-only diagnostic batch for me to run, then continue when I provide the result. Do not claim that SQL was executed. Do not apply remediation. Propose an index/statistics action only after the evidence supports it. Finish with a before/after Query Store validation plan. The reusable asset is the investigation procedure behind these prompts. Query Store supplies the evidence, Copilot helps carry out the investigation, and the engineer reviews whether the explanation and proposed change are supported by the results.220Views0likes0CommentsManaged Instance link – connecting SQL Server to Azure reimagined
Link feature for Managed Instance is a new feature reimagining the connection between SQL Server hosted anywhere and the fully managed PaaS service Azure SQL Managed Instance, providing unprecedented hybrid flexibility and database mobility. With an approach that uses near real-time data replication to Azure, you can offload workloads to read-only secondaries on Azure to take advantage of a fully managed database platform, performance, and scale. The link can be operated for as long as you need it – months and years at a time, empowering you to get all the modern benefits of Azure today without migrating to the cloud. On your modernization journey, when and if you are ready to migrate to the cloud, the link de-risks your migration experience allowing you to validate your workloads in Azure prior to migrating with a seamless and instant experience, and at your own pace. This article provides deeper insights into this new feature.27KViews4likes9Comments
SQL Data Discrepancy check
SQL issue - Power BI Excel/CSV files imported into SQL Tables and I need to do data discrepancy check - find logical discrepancy - find out dependency of fields and tables, Null, duplicates, Unwanted Fields, Junk elements, Logical Discrepancy, check tables I have tables as below 1) ACTIVECUSTOMER, 2) Bank_Departure,3) CreditCard, 4) CUSTOMERINFO, 5) EXITCUSTOMER,6) GENDER, 7) GEOGRAPHY based on these tables how to check data discrepancy into SQL server, any inputs are much appreciated131Views0likes1CommentDatabase Hub in Fabric: Now in Public Preview -Turn Database Signals into Guided Action
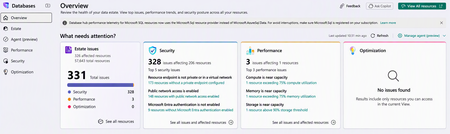
As applications grow, so does the database estate behind them. What starts with a handful of databases can become hundreds or thousands of resources spread across services, subscriptions, and environments. For the teams responsible for keeping them healthy, the challenge is no longer just collecting signals. It is knowing what needs attention, why it matters, and what to do next. Now in public preview, Database Hub in Microsoft Fabric brings inventory, health, performance, security, and optimization insights into one connected experience. It helps administrators and developers see the bigger picture, identify affected resources, and move from estate-wide visibility to focused investigation, without losing the context that brought them there. The preview brings together supported resources across Azure SQL Database, SQL Server enabled by Azure Arc, Azure Database for PostgreSQL, Azure Cosmos DB, and SQL database in Fabric. Available capabilities and signals vary by service and preview configuration. Database Hub Overview brings together estate-wide findings and cross-engine performance trends to help you prioritize what needs attention. Start with what needs your attention When you manage a large database estate, another dashboard is only useful if it helps you decide where to spend your time. The Overview page provides that starting point, bringing together findings across security, performance, and optimization. It distinguishes Issues, which require timely attention, from Suggestions, which highlight opportunities to improve your estate over time. You might begin with a security configuration that needs review or a performance signal that warrants investigation. Selecting a finding opens Estate with the relevant filters already applied, so you can see the affected resources rather than search for them again. The result is a more direct path from “something needs attention” to “these are the resources I should investigate.” Overview highlights issues across Security, Performance, and Optimization, with affected-resource counts and direct links to investigate further. Bring your estate into one view, and make it relevant to you The Estate experience brings supported resources into a unified inventory, scoped to your existing permissions. Search and filters help you narrow that inventory to the service, subscription, or resource group you manage. This is especially useful when your responsibilities span database engines. You can begin with a broader view, then focus on Azure SQL databases, Arc-enabled SQL Server resources, or Azure Database for PostgreSQL flexible servers without rebuilding the resource list in separate portals. Each resource brings its associated Issues and Suggestions into context. Open a finding to review the affected resource, supporting information, and recommended next step. The inventory also respects the resource model of each service. For example, the PostgreSQL view represents flexible server instances, rather than every database hosted within them. A unified view does not mean moving your databases. Your Azure resources remain in their existing subscriptions, and on-premises SQL Server instances remain on-premises, connected through Azure Arc. Database Hub brings operational context together; it does not require relocating or mirroring your application data into Fabric. Estate brings resource inventory, Issues, and Suggestions into one view, with quick actions to continue investigation in the Azure portal, VS Code, or SSMS. Understand security posture and performance in context Database Hub helps you identify configurations worth reviewing and resources that need a closer look. For security, supported signals can include Microsoft Entra authentication, customer-managed keys, and auditing coverage, depending on the database service. These findings provide a starting point for investigation, not a blanket judgment that every flagged resource is insecure or noncompliant. For example, a suggestion to review customer-managed keys should be evaluated against your organization’s requirements. A resource using service-managed keys is still encrypted at rest. For performance, built-in dashboards bring supported utilization and activity signals into view, including CPU, memory, storage, I/O, and connections. Review trends across your estate, then narrow the scope and time range to investigate individual resources. Metric availability varies by engine and monitoring configuration; missing data should not be interpreted as good health. For supported SQL monitoring scenarios, you can also create a custom monitoring dashboard from a template and tailor its charts and layout to the resources your team follows regularly. Together, these experiences help answer two practical questions: Where is pressure building, and where is there an opportunity to improve? Performance summaries highlight recent capacity signals and trends across Microsoft SQL, PostgreSQL, and Cosmos DB. The Security dashboard summarizes Microsoft Entra authentication, audit logging, and customer-managed key coverage, helping you identify configurations that warrant review across your estate. The Performance monitoring dashboard combines memory-pressure trends, resource-level details, and interpretation guidance to help focus your investigation. Move from a finding to an informed next step Estate-wide visibility is the beginning of an investigation, not a replacement for database expertise. When a finding needs deeper analysis, Database Hub helps you review the evidence and continue in the appropriate native experience, such as the Azure portal or SQL Server Management Studio (SSMS). Engine-specific diagnostics and configuration changes remain in the tools designed for that work. Consider a performance issue that occurred before an administrator could inspect it. In supported agent-assisted scenarios, captured incident evidence can help establish what happened, when it happened, and which queries or sessions were involved. That context gives the administrator a more informed starting point for investigation. The operator remains in control: review the evidence, evaluate the recommendation, and apply authorized changes through the appropriate service tools. The preview investigation workflow does not automatically remediate issues, and existing permissions and approval requirements continue to apply. Bring database expertise into agent-assisted workflows We are also making database operational intelligence available through agent skills: reusable capabilities that agents can call to support observability, monitoring, diagnostics, optimization, and other database operations. Database Hub provides estate context; skills provide a way to bring database expertise into an agent-assisted investigation. This creates a foundation for helping teams move from identifying an affected resource to understanding its signals and evaluating the next step. We’re building toward making this expertise available in the AI companions and development tools teams already use, with recommendations grounded in evidence, the specific database, and your organization’s operational controls. If we take a step back, our broader vision brings together a free, extensible Database Hub experience, agentic observability, and OneLake integration, all within Microsoft Fabric. It’s a foundation for connecting database operations with analytics and AI and helping teams turn signals into informed action. Get started with Database Hub Start with the Database Hub documentation to review preview availability, supported services, and setup requirements. Ask your Fabric administrator to enable the preview where required, confirm that you have the appropriate resource permissions, and complete any service-specific monitoring prerequisites. Then open Microsoft Fabric, select Databases in the left navigation, and begin with Overview. Choose a finding, explore the affected resources in Estate, and follow the evidence into your next investigation. For more details on supported services and getting set up, the Database Hub documentation is also available on Microsoft Learn. Learn more What is Database Hub in Fabric? Enable performance monitoring for Microsoft SQL Performance Monitoring for Azure SQL in Database Hub1KViews5likes1CommentSQLCon is Back: 5 Reasons to Attend the European Microsoft Fabric + SQL Community Conference
5 Reasons to Attend the European Microsoft Fabric + SQL Community Conference This year the SQL community joins Fabric in Europe for the first time at the Microsoft Fabric + SQL Community Conference happening September 28th - October 1st in Barcelona, Spain. Hear the latest announcements and roadmap directly from Microsoft leaders. With a full week of deep technical sessions and workshops covering the topics you care about most across and see how we’re helping solve your most pressing data challenges, from strengthening data sovereignty to powering agentic AI and unlocking trusted, actionable intelligence. And while there’s no shortage of topics, here are a couple of things we’re the most excited about heading to Barcelona: Unify your data (conference) experience With one registration, this event doubles your opportunity to sharpen your skillset with 130+ expert led sessions, workshops, and keynotes coming together in one high- impact week. Mix and match sessions to best meet your learning goals while you move seamlessly across tracks, visit the shared expo, and connect with peers in the community hub, all under one roof. The ultimate SQL experience, like only Microsoft can deliver With more than 25 dedicated SQL sessions, whether you’re a DBA or, a developer building AI apps, you can create your custom agenda with the topics you care about most. Pre-day programming is for the builders; bring your laptop and start your week with any of our full- day SQL workshops for the demos, practical guidance, and repeatable patterns you can start using immediately. Tuesday kicks off the official event with our opening keynote, three corenotes, and general sessions focused on SQL Server 2025, Azure SQL, and SQL in Fabric. Learn the latest in performance, tuning and tools like SSMS and VS Code delivered directly from SQL experts, MVPs, and community leaders. Ready to start building your agenda? Try our new session planner to curate your schedule based on your interests. The backdrop: Barcelona This year’s conference takes place in the historic, vibrant city of Barcelona, set along the Mediterranean Sea, the ideal setting for the first European SQLCon. When you’re ready for a break, you’re only a 15-minute ride away from the city center, perfect for exploring Gaudí’s iconic architecture or enjoying some local bites. Don’t miss the wrap- up celebration taking place in Barcelona’s exclusive Sutton Club. Community Connection SQLCon is more than just sessions; we’re bringing together more than 4,000 of the most dedicated Microsoft community members together for a week of endless connection opportunities. The Community Hub will bring some of our most popular experiences to life, from in-person meetups and user group connections to hands-on learning and certification opportunities all designed to help you grow your skills and expand your network. Launching Soon: SQLCon TV Enjoyed catching all the behind-the-scenes action on FabCon TV? In Barcelona we’ll bring SQLCon TV to the stage, with the content, demos, and interviews every SQL fan will want to see. Save your spot today. The earlier you register, the more opportunities you have to take advantage of early pricing specials. See you in Barcelona!476Views0likes2Comments