semantic kernel
64 Topics
Your Agents Need More Than a Place to Run
In architecture reviews with enterprise teams moving their first agentic applications toward production, I often hear the same plan: the team has containerized their agent and intends to run it on the managed Kubernetes cluster the organization already trusts. The reasoning is sensible, since the platform team knows the tooling and security has approved the network model, and for the first use case or two it is often the right call. Having watched this unfold in my years leading AgenticAI customer engineers and forward deployed engineers, and now helping customers reach production on Azure, I want to describe what happens next, before leaders commit rather than after. One thing to note is Azure supports multiple ways to build and operate agents. Foundry Agent Service provides an integrated managed runtime around your agent code. Azure Kubernetes Service supports teams that need Kubernetes-level control or want to extend an established platform, while Azure Container Apps provides managed container hosting. These services can work together. The decision is which capabilities and responsibilities best fit the workload. Where the cluster is the right answer A stateless retrieval application, a document extraction pipeline, or a classification job is a web service that happens to call a model, and a container platform runs web services well. A large retail customer of mine ran an invoice extraction agent on containers for over a year with almost no issues, and I never suggested they move it. The cluster remains the right home for several other situations as well. LLM invocations embedded inside existing microservices, event driven, or batch pipelines fit container platforms naturally. Genuine constraints such as air-gapped or sovereign environment, regions where a managed service is not yet offered are a good reason to run your own stack, and strong engineering team that already operates at that level can be a real asset. Even when the agents themselves move to a managed runtime, the tool servers, business APIs, and data services those agents call, often stay on your cluster, so they are complementary far more often than they are competitors. The problem is that these early wins can make agents seem like just another workload. Where the wheels come off The first failure is the state. A research agent that plans, searches, and synthesizes for ninety minutes is a long-running stateful process, while a Kubernetes pod is a disposable container the scheduler may restart at any time. A financial services team I worked with lost costly research run to a routine node upgrade, and responded as capable engineers do by building checkpointing, a durable store, and a resume mechanism. It worked, but they now owned a piece of infrastructure they had to keep correct as their agent's framework changed beneath it. A managed agent runtime absorbs this. Hosted agents in Foundry Agent Service, as one example, give every session a VM-isolated sandbox with a persistent file system, a durable state store that survives crashes and restarts and can hold checkpoints for frameworks such as LangGraph or Microsoft Agent Framework, and a resilient execution mode that recovers long-running work after a process interruption. The second is the human-in-the-loop. A commercial insurance customer’s claims agent needed sign-off from an adjuster and sometimes a second reviewer, with days between steps. Stopping an agent cleanly at the moment it needs a decision, holding its full session for four days without paying to keep it running, and resuming it correctly when the approval arrives is not something a container orchestrator gives out the box. The team built agent session suspend and resume, a queue, a durable state store, notifications, and an approval interface, and ended up with a small workflow engine nobody had planned to own. In hosted agents, an idle session is deprovisioned with its state persisted and restored onto fresh compute when the same session ID returns, so an agent waiting on an approval cost nothing while it waits, and sessions are retained for up to thirty days of inactivity. The approval experience remains yours to design, which is where your engineers' time should go. The third is multi-turn conversation, which quietly pushes teams into building their own context management system. The first version appends each turn to history, and within few turns the history outgrows the context window while cost and latency climb. So, the team adds truncation, then summarization, then retrieval of earlier turns, then per-user and per-tenant scoping, then expiry and deletion rules for privacy. An industrial customer's safety compliance assistant, with conversations stretching across days, followed exactly this path and ended up with a bespoke thread store and summarization pipeline nobody had budgeted for. Its first serious incident came when a summary silently dropped a compliance-relevant instruction. With the Responses protocol in hosted agents in Foundry, conversation history is a durable, platform-managed record keyed by a conversation ID and reachable from any channel, so the thread store is no longer yours to build, although deciding what to summarize or retrieve remains a design choice for your agent. The fourth is identity. On a cluster, the path of least resistance is a shared service account, and in one review a security architect asked which actions had been taken on behalf of which user, only to learn that the logs could not say. Hosted agents create a dedicated Microsoft Entra agent identity for each agent at deploy time, use on-behalf-of flows to act with the user's delegated permissions in interactive scenarios and the agent's own identity in autonomous ones, and keep the agent identifiable for audit in both cases. The fifth is per-user session isolation, which is the difference between an agent that serves many people and an agent that mixes them up. Agents read files, run code, and hold working data, and on a shared pod the default is that many users share a process, a file system, and often a cache. Giving every user session its own sandboxed environment and storage, so that one person's documents and intermediate results can never surface in another's, means engineering hard isolation boundaries and proving them to your security team. Hosted agents make a VM-isolated sandbox per session the default, and their durable state store can partition items per end user, so one store is safe to share across the users of a multitenant agent. And lastly, Evaluation and optimization are where the gap widens. The largest difference between teams that scale and those that stall is evaluation. Because agents are probabilistic and multi-step, staging tests often miss failures such as a wrong tool choice or a policy violation deep in a task. One customer’s agent passed every offline check but degraded unnoticed for weeks after a model update because evaluation stopped at release. Mature teams continuously evaluate production traces, combine automated judges with sampled human review, and red-team regularly.Once quality is measurable, teams can deliberately balance prompts, models, tools, latency, and cost. One team cut per-task cost by routing simple steps to smaller models after evaluation confirmed quality held. Self-built stacks require teams to assemble and maintain tracing, datasets, judges, and release gates. Hosted agents instead combines default OpenTelemetry traces with continuous evaluation, adversarial testing, and datasets generated from agent instructions. Staged closed-loop optimization uses those traces to improve instructions, tool descriptions, and model selection without extra plumbing. The real cost is the velocity gap Leaders usually expect me to quantify the initial build, and that is the smaller number. A team of four building the first agent often becomes ten or twelve within a year, and a growing share of them are maintaining a runtime for agents rather than building agents that serve the business. The enterprise has quietly created an internal agent infrastructure company in a field where the patterns for memory, tools, evaluation, and safety are rewritten every few months, while hyperscalers put hundreds of engineers on exactly this problem and ship at a cadence no single platform group can match. Foundry Agent Service, for instance, bundle content safety guardrails into the runtime and route outbound traffic through a customer virtual network, capabilities that platform teams otherwise assemble one integration at a time. This plumbing does not differentiate your organization, so the question is whether your scarcest engineers should spend years on it or on the workflows, data, and judgment only your company has. This is also why the technology companies held up as examples are a poor template. Many built their own runtimes because managed options did not yet exist and had large platform organizations to carry the load. Even they tend to invest in a custom runtime for the first handful of use cases and then migrate as managed services mature, because the maintenance burden compounds while the strategic value of owning the plumbing does not. What I would do as the leader I am not arguing against Kubernetes or for moving everything tomorrow. Comparable managed runtimes exist across the hyperscalers, and I use hosted agents as the running example only because it is the one I know best from the inside. Managed agent services are still maturing, some workloads have real data residency or customization needs, and abstraction always constrains something. What I am arguing for is a deliberate choice for each use case, guided by three questions: whether the agent must outlive a single request by running long, waiting on humans, or remembering across sessions whether it must act with its own identity, auditable delegation, and policy enforcement whether your team would be building anything a managed service already provides, and who will still maintain it in two years. Key takeaways Match the runtime to the workload. Containers on your existing cluster suit stateless, short-lived agents, while long-running, human-in-the-loop, and memory-dependent agents need capabilities your platform team was never hired to build. Count the hidden team. The real cost of self-hosting is the growing group of engineers maintaining state, identity, memory, guardrails, and tracing instead of solving business problems. Make evaluation continuous and connected to production traces. Pre-release testing alone will miss the drift and trajectory failures that hurt you, and optimization of quality, cost, and latency depends on that evaluation data. Follow the pattern of the leaders, not their early architecture. Companies that built custom runtimes did so before managed options matured, and most of them move toward managed services as those options improve. A practical place to begin is your roadmap for the next twelve months. Sort each use case into stateless and short-lived or long-running and human-dependent, and for every agent in the second group put a price on the engineers who would maintain the runtime rather than the business logic. I would like to hear how you have drawn this line, and where a managed service was not yet ready for something you needed.704Views2likes0CommentsStaying in the flow: SleekFlow and Azure turn customer conversations into conversions
A customer adds three items to their cart but never checks out. Another asks about shipping, gets stuck waiting eight minutes, only to drop the call. A lead responds to an offer but is never followed up with in time. Each of these moments represents lost revenue, and they happen to businesses every day. SleekFlow was founded in 2019 to help companies turn those almost-lost-customer moments into connection, retention, and growth. Today we serve more than 2,000 mid-market and enterprise organizations across industries including retail and e-commerce, financial services, healthcare, travel and hospitality, telecommunications, real estate, and professional services. In total, those customers rely on SleekFlow to orchestrate more than 600,000 daily customer interactions across WhatsApp, Instagram, web chat, email, and more. Our name reflects what makes us different. Sleek is about unified, polished experiences—consolidating conversations into one intelligent, enterprise-ready platform. Flow is about orchestration—AI and human agents working together to move each conversation forward, from first inquiry to purchase to renewal. The drive for enterprise-ready agentic AI Enterprises today expect always-on, intelligent conversations—but delivering that at scale proved daunting. When we set out to build AgentFlow, our agentic AI platform, we quickly ran into familiar roadblocks: downtime that disrupted peak-hour interactions, vector search delays that hurt accuracy, and costs that ballooned under multi-tenant workloads. Development slowed from limited compatibility with other technologies, while customer onboarding stalled without clear compliance assurances. To move past these barriers, we needed a foundation that could deliver the performance, trust, and global scale enterprises demand. The platform behind the flow: How Azure powers AgentFlow We chose Azure because building AgentFlow required more than raw compute power. Chatbots built on a single-agent model often stall out. They struggle to retrieve the right context, they miss critical handoffs, and they return answers too slowly to keep a customer engaged. To fix that, we needed an ecosystem capable of supporting a team of specialized AI agents working together at enterprise scale. Azure Cosmos DB provides the backbone for memory and context, managing short-term interactions, long-term histories, and vector embeddings in containers that respond in 15–20 milliseconds. Powered by Azure AI Foundry, our agents use Azure OpenAI models within Azure AI Foundry to understand and generate responses natively in multiple languages. Whether in English, Chinese, or Portuguese, the responses feel natural and aligned with the brand. Semantic Kernel acts as the conductor, orchestrating multiple agents, each of which retrieves the necessary knowledge and context, including chat histories, transactional data, and vector embeddings, directly from Azure Cosmos DB. For example, one agent could be retrieving pricing data, another summarizing it, and a third preparing it for a human handoff. The result is not just responsiveness but accuracy. A telecom provider can resolve a billing question while surfacing an upsell opportunity in the same dialogue. A financial advisor can walk into a call with a complete dossier prepared in seconds rather than hours. A retailer can save a purchase by offering an in-stock substitute before the shopper abandons the cart. Each of these conversations is different, yet the foundation is consistent on AgentFlow. Fast, fluent, and focused: Azure keeps conversations moving Speed is the heartbeat of a good conversation. A delayed answer feels like a dropped call, and an irrelevant one breaks trust. For AgentFlow to keep customers engaged, every operation behind the scenes has to happen in milliseconds. A single interaction can involve dozens of steps. One agent pulls product information from embeddings, another checks it against structured policy data, and a third generates a concise, brand-aligned response. If any of these steps lag, the dialogue falters. On Azure, they don’t. Azure Cosmos DB manages conversational memory and agent state across dedicated containers for short-term exchanges, long-term history, and vector search. Sharded DiskANN indexing powers semantic lookups that resolve in the 15–20 millisecond range—fast enough that the customer never feels a pause. Microsoft Phi’s model Phi-4 as well as Azure OpenAI in Foundry Models like o3-mini and o4-mini, provide the reasoning, and Azure Container Apps scale elastically, so performance holds steady during event-driven bursts, such as campaign broadcasts that can push the platform from a few to thousands of conversations per minute, and during daily peak-hour surges. To support that level of responsiveness, we run Azure Container Apps on the Pay-As-You-Go consumption plan, using KEDA-based autoscaling to expand from five idle containers to more than 160 within seconds. Meanwhile, Microsoft Orleans coordinates lightweight in-memory clustering to keep conversations sleek and flowing. The results are tangible. Retrieval-augmented generation recall improved from 50 to 70 percent. Execution speed is about 50 percent faster. For SleekFlow’s customers, that means carts are recovered before they’re abandoned, leads are qualified in real time, and support inquiries move forward instead of stalling out. With Azure handling the complexity under the hood, conversations flow naturally on the surface—and that’s what keeps customers engaged. Secure enough for enterprises, human enough for customers AgentFlow was built with security-by-design as a first principle, giving businesses confidence that every interaction is private, compliant, and reliable. On Azure, every AI agent operates inside guardrails enterprises can depend on. Azure Cosmos DB enforces strict per-tenant isolation through logical partitioning, encryption, and role-based access control, ensuring chat histories, knowledge bases, and embeddings remain auditable and contained. Models deployed through Azure AI Foundry, including Azure OpenAI and Microsoft Phi, process data entirely within SleekFlow’s Azure environment and guarantees it is never used to train public models, with activity logged for transparency. And Azure’s certifications—including ISO 27001, SOC 2, and GDPR—are backed by continuous monitoring and regional data residency options, proving compliance at a global scale. But trust is more than a checklist of certifications. AgentFlow brings human-like fluency and empathy to every interaction, powered by Azure OpenAI running with high token-per-second throughput so responses feel natural in real time. Quality control isn’t left to chance. Human override workflows are orchestrated through Azure Container Apps and Azure App Service, ensuring AI agents can carry conversations confidently until they’re ready for human agents. Enterprises gain the confidence to let AI handle revenue-critical moments, knowing Azure provides the foundation and SleekFlow provides the human-centered design. Shaping the next era of conversational AI on Azure The benefits of Azure show up not only in customer conversations but also in the way our own teams work. Faster processing speeds and high token-per-second throughput reduce latency, so we spend less time debugging and more time building. Stable infrastructure minimizes downtime and troubleshooting, lowering operational costs. That same reliability and scalability have transformed the way we engineer AgentFlow. AgentFlow started as part of our monolithic system. Shipping new features used to take about a month of development and another week of heavy testing to make sure everything held together. After moving AgentFlow to a microservices architecture on Azure Container Apps, we can now deploy updates almost daily with no down time or customer impact. And this is all thanks to native support for rolling updates and blue-green deployments. This agility is what excites us most about what's ahead. With Azure as our foundation, SleekFlow is not simply keeping pace with the evolution of conversational AI—we are shaping what comes next. Every interaction we refine, every second we save, and every workflow we streamline brings us closer to our mission: keeping conversations sleek, flowing, and valuable for enterprises everywhere.850Views3likes0Comments
When RAG Hits the Wall: Designing Systems That Scale from 1,000 to 1 million Documents
Introduction Retrieval-Augmented Generation (RAG) has quickly become the default architecture for grounding Large Language Models (LLMs) in enterprise data. And at small scale, it works exceptionally well. 100 documents → Excellent accuracy 1,000 documents → Still predictable With around 100 documents, RAG systems tend to produce highly accurate responses. Even at 1,000 documents, behavior remains predictable and reliable. However, as systems grow beyond tens of thousands - and especially into the range of hundreds of thousands or millions of documents - many implementations begin to degrade in surprising ways. Latency begins to rise nonlinearly. Retrieval precision declines, costs increase, and responses grow inconsistent. What looks like a model issue is usually an architectural one. The Hidden Theory Behind Early RAG Success Early RAG systems work well not because they are perfectly designed, but because small datasets are forgiving. In smaller corpora, irrelevant retrieval is naturally rare. Semantic similarity remains tightly clustered, and noise does not overwhelm signal. This creates an illusion of robustness - systems seem accurate even when the underlying retrieval strategy is weak. As scale increases, this illusion disappears. Breaking Point #1: Chunk Explosion (Entropy Growth) What Happens Most ingestion pipelines rely on token-based chunking: Document -> Fixed-size chunks -> Embed everything As document count increases, the system experiences entropy growth: The number of chunks grows faster than the number of documents, leading to a dense and noisy vector space. Similar information becomes fragmented, and retrieval precision drops. This is a manifestation of the curse of dimensionality - as the number of vectors increases, distance metrics lose meaning, and “nearest neighbors” stop being truly relevant. The Shift: Structural Information Retrieval To solve this production-grade RAG systems reintroduce structure. Instead of blindly splitting text, semantic chunking aligns content with logical boundaries like headings and sections. This preserves meaning and improves retrieval quality. Deduplication removes repeated templates and boilerplate, reducing unnecessary noise in the system. Hierarchical indexing allows retrieval to operate at multiple levels - document, section, and chunk - making search both more efficient and more accurate. These changes restore order in the vector space and significantly improve retrieval performance. Breaking Point #2: Vector Search Saturation What Happens As data grows, latency becomes one of the biggest bottlenecks. Many systems rely on runtime-heavy operations such as generating embeddings on demand or querying large, unpartitioned indexes. This leads to unbounded computation and poor scalability. Over time, retrieval cost trends toward linear complexity. Cache inefficiencies increase, and tail latency begins to dominate the user experience. The Shift: Systems Thinking Scaling RAG requires applying distributed systems principles. Partitioned indexes reduce the search space, allowing queries to operate on smaller, more relevant subsets of data. Precomputed embeddings shift expensive computation to ingestion time, eliminating runtime overhead. Caching strategies, informed by real-world usage patterns, significantly improve performance by reusing frequent query results. Together, these changes make latency predictable and systems more cost-efficient. The Final Trap: Context does not equal to Intelligence What Happens A common mistake in RAG systems is assuming that more context leads to better answers. In reality, LLMs are attention limited. As more tokens are added, attention becomes diluted, and the model struggles to focus on what matters. Excessive context introduces noise, reducing the overall quality of responses. The Shift: Information Compression Effective systems focus on quality over quantity. By limiting retrieval to the most relevant chunks, summarizing context, and grounding responses with citations, RAG systems achieve higher information density and better reasoning performance. What a Scalable RAG System Actually Represent At scale, RAG is no longer an LLM feature. It becomes a retrieval system with an LLM as a reasoning layer. Prototype RAG Production RAG Token chunking Structured IR Vector-only search Hybrid retrieval No ranking theory Reranking models Runtime-heavy Precomputed pipelines More context Information compression Final Insight Scaling RAG is not primarily a machine learning problem. It is a combination of information retrieval and distributed systems engineering, with the LLM acting as the final layer. Closing Thought If your RAG system works with 1,000 documents, you’ve validated an idea. If it works with 1 million documents, you’ve respected theory - and built an architecture. References RAG and Generative AI - Azure AI Search | Microsoft Learn Chunk and Vectorize by Document Layout - Azure AI Search | Microsoft Learn Chunk Documents - Azure AI Search | Microsoft Learn Hybrid Search Overview - Azure AI Search | Microsoft Learn
The Future of Agentic AI: Inside Microsoft Agent Framework 1.0
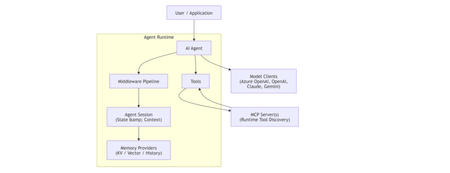
Agentic AI is rapidly moving beyond demos and chatbots toward long‑running, autonomous systems that reason, call tools, collaborate with other agents, and operate reliably in production. On April 3, 2026, Microsoft marked a major milestone with the General Availability (GA) release of Microsoft Agent Framework 1.0, a production‑ready, open‑source framework for building agents and multi‑agent workflows in.NET and Python. [techcommun...rosoft.com] In this post, we’ll deep‑dive into: What Microsoft Agent Framework actually is Its core architecture and design principles What’s new in version 1.0 How it differs from other agent frameworks When and how to use it—with real code examples What Is Microsoft Agent Framework? According to the official announcement, Microsoft Agent Framework is an open‑source SDK and runtime for building AI agents and multi‑agent workflows with strong enterprise foundations. Agent Framework provides two primary capability categories: 1. Agents Agents are long‑lived runtime components that: Use LLMs to interpret inputs Call tools and MCP servers Maintain session state Generate responses They are not just prompt wrappers, but stateful execution units. 2. Workflows Workflows are graph‑based orchestration engines that: Connect agents and functions Enforce execution order Support checkpointing and human‑in‑the‑loop scenarios This leads to a clean separation of responsibilities: Concern Handled By Reasoning & interpretation Agent Execution policy & control flow Workflow This separation is a foundational design decision. High‑Level Architecture From the official overview, Agent Framework is composed of several core building blocks: Model clients (chat completions & responses) Agent sessions (state & conversation management) Context providers (memory and retrieval) Middleware pipeline (interception, filtering, telemetry) MCP clients (tool discovery and invocation) Workflow engine (graph‑based orchestration) Conceptual Flow 🌟 What’s New in Version 1.0 Version 1.0 marks the transition from "Release Candidate" to "General Availability" (GA). Production-Ready Stability: Unlike the earlier experimental packages, 1.0 offers stable APIs, versioned releases, and a commitment to long-term support (LTS). A2A Protocol (Agent-to-Agent): A new structured messaging protocol that allows agents to communicate across different runtimes. For example, an agent built in Python can seamlessly coordinate with an agent running in a .NET environment. MCP (Model Context Protocol) Support: Full integration with the Model Context Protocol, enabling agents to dynamically discover and invoke external tools and data sources without manual integration code. Multi-Agent Orchestration Patterns: Stable implementations of complex patterns, including: Sequential: Linear handoffs between specialized agents. Group Chat: Collaborative reasoning where agents discuss and solve problems. Magentic-One: A sophisticated pattern for task-oriented reasoning and planning. Middleware Pipeline: The new middleware architecture lets you inject logic into the agent's execution loop without modifying the core prompts. This is essential for Responsible AI (RAI), allowing you to add content safety filters, logging, and compliance checks globally. DevUI Debugger: A browser-based local debugger that provides a real-time visual representation of agent message flows, tool calls, and state changes. Code Examples Creating a Simple Agent (C#) From Microsoft Learn : using Azure.AI.Projects; using Azure.Identity; using Microsoft.Agents.AI; AIAgent agent = new AIProjectClient( new Uri("https://your-foundry-service.services.ai.azure.com/api/projects/your-project"), new AzureCliCredential()) .AsAIAgent( model: "gpt-5.4-mini", instructions: "You are a friendly assistant. Keep your answers brief."); Console.WriteLine(await agent.RunAsync("What is the largest city in France?")); This shows: Provider‑agnostic model access Session‑aware agent execution Minimal setup for production agents Creating a Simple Agent (Python) from agent_framework.foundry import FoundryChatClient from azure.identity import AzureCliCredential client = FoundryChatClient( project_endpoint="https://your-foundry-service.services.ai.azure.com/api/projects/your-project", model="gpt-5.4-mini", credential=AzureCliCredential(), ) agent = client.as_agent( name="HelloAgent", instructions="You are a friendly assistant. Keep your answers brief.", ) result = await agent.run("What is the largest city in France?") print(result) The same agent abstraction applies across languages. When to Use Agents vs Workflows Microsoft provides clear guidance: Use an Agent when… Use a Workflow when… Task is open‑ended Steps are well‑defined Autonomous tool use is needed Execution order matters Single decision point Multiple agents/functions collaborate Key principle: If you can solve the task with deterministic code, do that instead of using an AI agent. 🔄 How It Differs from Other Frameworks Microsoft Agent Framework 1.0 distinguishes itself by focusing on "Enterprise Readiness" and "Interoperability." Feature Microsoft Agent Framework 1.0 Semantic Kernel / AutoGen LangChain / CrewAI Philosophy Unified, production-ready SDK. Research-focused or tool-specific. High-level, developer-friendly abstractions. Integration Deeply integrated with Microsoft Foundry and Azure. Varied; often requires more glue code. Generally cloud-agnostic. Interoperability Native A2A and MCP for cross-framework tasks. Limited to internal ecosystem. Uses proprietary connectors. Runtime Identical API parity for .NET and Python. Primarily Python-first (SK has C#). Primarily Python. Control Graph-based deterministic workflows. More non-deterministic/experimental. Mixture of role-based and agentic. 🛠️ Key Technical Components Agent Harness: The execution layer that provides agents with controlled access to the shell, file system, and messaging loops. Agent Skills: A portable, file-based or code-defined format for packaging domain expertise. Implementation Tip: If you are coming from Semantic Kernel, Microsoft provides migration assistants that analyze your existing code and generate step-by-step plans to upgrade to the new Agent Framework 1.0 standards. Microsoft Agent Framework Version 1.0 | Microsoft Agent Framework Agent Framework documentation 🎯 Summary Microsoft Agent Framework 1.0 is the "grown-up" version of AI orchestration. By standardizing the way agents talk to each other (A2A), discover tools (MCP), and process information (Middleware), Microsoft has provided a clear path for taking AI experiments into production. For more detailed guides, check out the official Microsoft Agent Framework DocumentationMicrosoft Agent Framework - .NET AI Community Standup
Building an Enterprise HR Chatbot with Multi-Strategy RAG and Live Agent Handoff on Azure
HR teams deal with thousands of employee questions every day — policy lookups, leave balances, case escalations, and sensitive topics like harassment or misconduct. AI chatbots can handle the routine stuff and free up HR advisors for the hard cases. But most chatbot projects get stuck at basic Q&A. They can't handle multi-country policies, employee slang, or smooth handoffs to a real person. This post covers how we built Eva, a production HR chatbot using Microsoft Bot Framework and Semantic Kernel on Azure. I'll focus on three problems and how we solved them: Getting accurate answers when employees and policy documents use different words Handing off to a live human advisor in real time Catching answer quality regressions automatically Why basic RAG isn't enough for HR Retrieval-Augmented Generation (RAG) — fetching relevant documents and feeding them to an LLM — is the standard approach. But plain RAG breaks down in HR for a few reasons: Vocabulary mismatch. An employee asks "How does misconduct affect my ACB?" but the policy document says "Annual Cash Bonus eligibility criteria." The search doesn't connect the two. Multi-country ambiguity. The same question can have different answers depending on the employee's country, grade, or role. Sensitive topics. Questions about harassment, disability, or whistleblowing should go to a human, not get an AI-generated answer. Ranking noise. Search results often include globally relevant but locally irrelevant documents. Eva handles these with a layered pipeline: query augmentation → multi-index search → LLM reranking → answer generation → citation handling. Architecture at a glance Layer Technology Bot framework Microsoft Agents SDK (aiohttp) LLM orchestration Semantic Kernel Primary LLM Azure OpenAI Service (GPT-4.1 / GPT-4o) Knowledge search Azure AI Search (hybrid + vector) Live agent chat Salesforce MIAW via server-sent events Evaluation Azure AI Evaluation SDK + custom LLM judge Config Pydantic-settings + Azure App Configuration + Key Vault Four retrieval strategies, controlled by feature flags Instead of one search approach, Eva supports four — toggled by feature flags so we can A/B test per country without code changes. They run in a priority cascade: HyDE (Hypothetical Document Embeddings) Instead of searching with the employee's question, the LLM first generates a hypothetical policy document thatwouldanswer it. We embed that synthetic document and use it as the search query. Since a hypothetical answer is closer in embedding space to the real answer than the original question is, this bridges vocabulary gaps effectively. Step-back prompting The LLM broadens the question. "How does misconduct affect my ACB?" becomes "What is the Annual Cash Bonus policy and what factors affect eligibility?" This works well when answers live in broader policy sections. Query rewrite The LLM expands abbreviations and adds HR domain context, then runs a hybrid (text + vector) search. Standard search (fallback) Basic intent classification with hybrid search. No augmentation. All four strategies return the same Pydantic model, so the rest of the pipeline doesn't care which one ran. The team can enable HyDE globally, roll out step-back to specific countries, or revert instantly if something underperforms. LLM reranking After pulling results from both a country-specific index and a global index, Eva optionally reranks them using a RankGPT-style approach — the LLM scores document relevance with a bias toward local content. If reranking fails for any reason, it falls back to the original ordering so the pipeline keeps moving. Answer generation with local vs. global context The answer stage separates retrieved documents into local context (country-specific) and global context (company-wide), injected as distinct prompt sections. The LLM returns a structured response with reasoning, the actual answer, citations, and a coverage classification (full, partial, or denial). Prompts are stored as version-controlled .txt files with per-model variants (e.g., gpt-4o.txt, gpt-4.1.txt), resolved at runtime. This makes prompts reviewable in PRs and deployable without code changes. Live agent handoff with Salesforce When Eva determines a question needs a human — sensitive topic, complex case, or the employee simply asks — it hands off to a Salesforce advisor in real time. SSE streaming. Eva keeps a persistent HTTP connection to Salesforce for real-time messages, typing indicators, and session end signals. Session resilience. Session state persists across three layers — in-memory cache, Azure Cosmos DB, and Bot Framework turn state — to survive restarts and failovers. Message delivery workers. Each session has a dedicated async worker with exponential backoff retry. Overflow messages go to a failed messages list rather than being silently dropped. Queue position updates. While employees wait, Eva queries Salesforce for queue position and sends rate-limited updates. Context handoff. On session start, Eva sends the full conversation transcript so advisors don't ask employees to repeat themselves. Automated evaluation Eva includes an evaluation framework that runs as a separate process, testing against ground-truth Q&A pairs from CSV files. Factual questions are scored using Azure AI's SimilarityEvaluator on a 1–5 scale, with optional relevance and groundedness checks. Sensitive questions (harassment, disability, whistleblowing) use a custom LLM judge that checks whether the response acknowledges sensitivity and directs the employee to create a case or speak with an advisor. A deviation detector flags score drops between runs. SQLite stores results for trending, and Application Insights powers dashboards. Long evaluation runs support resume — the framework skips already-completed test cases on restart. Key takeaways Make retrieval strategies swappable. Feature flags let you A/B test without redeploying. Separate local and global knowledge explicitly. Don't rely on the LLM to figure out which country's policy applies. Invest in evaluation early. Ground-truth datasets with factual and behavioral scoring catch regressions that manual testing misses. Build resilience into live agent handoff. Multi-tier session recovery and retry logic prevent dropped conversations. Treat prompts as code. File-based, model-variant-aware prompts are easier to maintain than inline strings. Use Pydantic for structured LLM outputs. Typed models catch bad output at the validation boundary instead of letting it propagate. Get started Semantic Kernel documentation — LLM orchestration with plugins and structured outputs Azure OpenAI Service quickstart — Deploy GPT-4o or GPT-4.1 Azure AI Search vector search tutorial — Hybrid and vector search indices Microsoft Bot Framework SDK — Build bots for Teams and web Azure AI Evaluation SDK — Score for similarity, relevance, and groundednessHow Do We Know AI Isn’t Lying? The Art of Evaluating LLMs in RAG Systems
🔍 1. Why Evaluating LLM Responses is Hard In classical programming, correctness is binary. Input Expected Result 2 + 2 4 ✔ Correct 2 + 2 5 ✘ Wrong Software is deterministic — same input → same output. LLMs are probabilistic. They generate one of many valid word combinations, like forming sentences from multiple possible synonyms and sentence structures. Example: Prompt: "Explain gravity like I'm 10" Possible responses: Response A Response B Gravity is a force that pulls everything to Earth. Gravity bends space-time causing objects to attract. Both are correct. Which is better? Depends on audience. So evaluation needs to look beyond text similarity. We must check: ✔ Is the answer meaningful? ✔ Is it correct? ✔ Is it easy to understand? ✔ Does it follow prompt intent? Testing LLMs is like grading essays — not checking numeric outputs. 🧠 2. Why RAG Evaluation is Even Harder RAG introduces an additional layer — retrieval. The model no longer answers from memory; it must first read context, then summarise it. Evaluation now has multi-dimensions: Evaluation Layer What we must verify Retrieval Did we fetch the right documents? Understanding Did the model interpret context correctly? Grounding Is the answer based on retrieved data? Generation Quality Is final response complete & clear? A simple story makes this intuitive: Teacher asks student to explain Photosynthesis. Student goes to library → selects a book → reads → writes explanation. We must evaluate: Did they pick the right book? → Retrieval Did they understand the topic? → Reasoning Did they copy facts correctly without inventing? → Faithfulness Is written explanation clear enough for another child to learn from? → Answer Quality One failure → total failure. 🧩 3. Two Types of Evaluation 🔹 Intrinsic Evaluation — Quality of the Response Itself Here we judge the answer, ignoring real-world impact. We check: ✔ Grammar & coherence ✔ Completeness of explanation ✔ No hallucination ✔ Logic flow & clarity ✔ Semantic correctness This is similar to checking how well the essay is written. Even if the result did not solve the real problem, the answer could still look good — that’s why intrinsic alone is not enough. 🔹 Extrinsic Evaluation — Did It Achieve the Goal? This measures task success. If a customer support bot writes a beautifully worded paragraph, but the user still doesn’t get their refund — it failed extrinsically. Examples: System Type Extrinsic Goal Banking RAG Bot Did user get correct KYC procedure? Medical RAG Was advice safe & factual? Legal search assistant Did it return the right section of the law? Technical summariser Did summary capture key meaning? Intrinsic = writing quality. Extrinsic = impact quality. A production-grade RAG system must satisfy both. 📏 4. Core RAG Evaluation Metrics (Explained with Very Simple Analogies) Metric Meaning Analogy Relevance Does answer match question? Ask who invented C++? → model talks about Java ❌ Faithfulness No invented facts Book says started 2004, response says 1990 ❌ Groundedness Answer traceable to sources Claims facts that don’t exist in context ❌ Completeness Covers all parts of question User asks Windows vs Linux → only explains Windows Context Recall / Precision Correct docs retrieved & used Student opens wrong chapter Hallucination Rate Degree of made-up info “Taj Mahal is in London” 😱 Semantic Similarity Meaning-level match “Engine died” = “Car stopped running” 💡 Good evaluation doesn’t check exact wording. It checks meaning + truth + usefulness. 🛠 5. Tools for RAG Evaluation 🔹 1. RAGAS — Foundation for RAG Scoring RAGAS evaluates responses based on: ✔ Faithfulness ✔ Relevance ✔ Context recall ✔ Answer similarity Think of RAGAS as a teacher grading with a rubric. It reads both answer + source documents, then scores based on truthfulness & alignment. 🔹 2. LangChain Evaluators LangChain offers multiple evaluation types: Type What it checks String or regex Basic keyword presence Embedding based Meaning similarity, not text match LLM-as-a-Judge AI evaluates AI (deep reasoning) LangChain = testing toolbox RAGAS = grading framework Together they form a complete QA ecosystem. 🔹 3. PyTest + CI for Automated LLM Testing Instead of manually validating outputs, we automate: Feed preset questions to RAG Capture answers Run RAGAS/LangChain scoring Fail test if hallucination > threshold This brings AI closer to software-engineering discipline. RAG systems stop being experiments — they become testable, trackable, production-grade products. 🚀 6. The Future: LLM-as-a-Judge The future of evaluation is simple: LLMs will evaluate other LLMs. One model writes an answer. Another model checks: ✔ Was it truthful? ✔ Was it relevant? ✔ Did it follow context? This enables: Benefit Why it matters Scalable evaluation No humans needed for every query Continuous improvement Model learns from mistakes Real-time scoring Detect errors before user sees them This is like autopilot for AI systems — not only navigating, but self-correcting mid-flight. And that is where enterprise AI is headed. 🎯 Final Summary Evaluating LLM responses is not checking if strings match. It is checking if the machine: ✔ Understood the question ✔ Retrieved relevant knowledge ✔ Avoided hallucination ✔ Provided complete, meaningful reasoning ✔ Grounded answer in real source text RAG evaluation demands multi-layer validation — retrieval, reasoning, grounding, semantics, safety. Frameworks like RAGAS + LangChain evaluators + PyTest pipelines are shaping the discipline of measurable, reliable AI — pushing LLM-powered RAG from cool demo → trustworthy enterprise intelligence. Useful Resources What is Retrieval-Augmented Generation (RAG) : https://azure.microsoft.com/en-in/resources/cloud-computing-dictionary/what-is-retrieval-augmented-generation-rag/ Retrieval-Augmented Generation concepts (Azure AI) : https://learn.microsoft.com/en-us/azure/ai-services/content-understanding/concepts/retrieval-augmented-generation RAG with Azure AI Search – Overview : https://learn.microsoft.com/en-us/azure/search/retrieval-augmented-generation-overview Evaluate Generative AI Applications (Microsoft Learn – Learning Path) : https://learn.microsoft.com/en-us/training/paths/evaluate-generative-ai-apps/ Evaluate Generative AI Models in Microsoft Foundry Portal : https://learn.microsoft.com/en-us/training/modules/evaluate-models-azure-ai-studio/ RAG Evaluation Metrics (Relevance, Groundedness, Faithfulness) : https://learn.microsoft.com/en-us/azure/ai-foundry/concepts/evaluation-evaluators/rag-evaluators RAGAS – Evaluation Framework for RAG Systems : https://docs.ragas.io/849Views0likes0Comments
Building High-Performance Agentic Systems
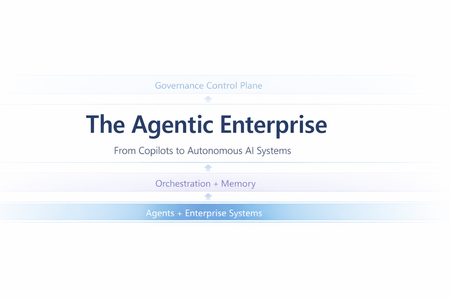
Most enterprise chatbots fail in the same quiet way. They answer questions. They impress in demos. And then they stall in production. Knowledge goes stale. Answers cannot be audited. The system cannot act beyond generating text. When workflows require coordination, execution, or accountability, the chatbot stops being useful. Agentic systems exist because that model is insufficient. Instead of treating the LLM as the product, agentic architecture embeds it inside a bounded control loop: plan → act (tools) → observe → refine The model becomes one component in a runtime system with explicit state management, safety policies, identity enforcement, and operational telemetry. This shift is not speculative. A late-2025 MIT Sloan Management Review / BCG study reports that 35% of organizations have already adopted AI agents, with another 44% planning deployment. Microsoft is advancing open protocols for what it calls the “agentic web,” including Agent-to-Agent (A2A) interoperability and Model Context Protocol (MCP), with integration paths emerging across Copilot Studio and Azure AI Foundry. The real question is no longer whether agents are coming. It is whether enterprise architecture is ready for them. This article translates “agentic” into engineering reality: the runtime layers, latency and cost levers, orchestration patterns, and governance controls required for production deployment. The Core Capabilities of Agentic AI What makes an AI “agentic” is not a single feature—it’s the interaction of different capabilities. Together, they form the minimum set needed to move from “answering” to “operating”. Autonomy – Goal-Driven Task Completion Traditional bots are reactive: they wait for a prompt and produce output. Autonomy introduces a goal state and a control loop. The agent is given an objective (or a trigger) and it can decide the next step without being micromanaged. The critical engineering distinction is that autonomy must be bounded: in production, you implement it with explicit budgets and stop conditions—maximum tool calls, maximum retries, timeouts, and confidence thresholds. The typical execution shape is a loop: plan → act → observe → refine. A project-management agent, for example, doesn’t just answer “what’s the status?” It monitors signals (work items, commits, build health), detects a risk pattern (slippage, dependency blockage), and then either surfaces an alert or prepares a remediation action (re-plan milestones, notify owners). In high-stakes environments, autonomy is usually human-in-the-loop by design: the agent can draft changes, propose next actions, and only execute after approval. Over time, teams expand the autonomy envelope for low-risk actions while keeping approvals for irreversible or financially sensitive operations. Tool Integration – Taking Action and Staying Current A standalone LLM cannot fetch live enterprise state and cannot change it. Tool integration is how an agent becomes operational: it can query systems of record, call APIs, trigger workflows, and produce outputs that reflect the current world rather than the model’s pretraining snapshot. There are two classes of tools that matter in enterprise agents: Retrieval tools (grounding / RAG)When the agent needs facts, it retrieves them. This is the backbone of reducing hallucination: instead of guessing, the agent pulls authoritative content (SharePoint, Confluence, policy repositories, CRM records, Fabric datasets) and uses it as evidence. In practice, retrieval works best when it is engineered as a pipeline: query rewrite (optional) → hybrid search (keyword + vector) → filtering (metadata/ACL) → reranking → compact context injection. The point is not “stuff the prompt with documents,” but “inject only the minimum evidence required to answer accurately.” Action tools (function calling / connectors) These are the hands of the agent: update a CRM record, create a ticket, send an email, schedule a meeting, generate a report, run a pipeline. Tool integration shifts value from “advice” to “execution,” but also introduces risk—so action tools need guardrails: least-privilege permissions, input validation, idempotency keys, and post-condition checks (confirm the update actually happened). In Microsoft ecosystems, this tool plane often maps to Graph actions + business connectors (via Logic Apps/Power Automate) + custom APIs, with Copilot Studio (low code) or Foundry-style runtimes (pro code) orchestrating the calls. Memory (Context & Learning) – Context Awareness and Adaptation “Memory” is not just a long prompt. In agentic systems, memory is an explicit state strategy: Working memory: what the agent has learned during the current run (intermediate tool results, constraints, partial plans). Session memory: what should persist across turns (user preferences, ongoing tasks, summarized history). Long-term memory: enterprise knowledge the agent can retrieve (indexed documents, structured facts, embeddings + metadata). Short-term memory enables multi-step workflows without repeating questions. An HR onboarding agent can carry a new hire’s details from intake through provisioning without re-asking, because the workflow state is persisted and referenced. Long-term “learning” is typically implemented through feedback loops rather than real-time model weight updates: capturing corrections, storing validated outcomes, and periodically improving prompts, routing logic, retrieval configuration, or (where appropriate) fine-tuning. The key design rule is that memory must be policy-aware: retention rules, PII handling, and permission trimming apply to stored state as much as they apply to retrieved documents. Orchestration – Coordinating Multi-Agent Teams Complex enterprise work is rarely single-skill. Orchestration is how agentic systems scale capability without turning one agent into an unmaintainable monolith. The pattern is “manager + specialists”: an orchestrator decomposes the goal into subtasks, routes each to the best tool or sub-agent, and then composes a final response. This can be done sequentially or in parallel. Employee onboarding is a classic: HR intake, IT account creation, equipment provisioning, and training scheduling can run in parallel where dependencies allow. The engineering challenge is making orchestration reliable: defining strict input/output contracts between agents (often structured JSON), handling failures (timeouts, partial completion), and ensuring only one component has authority to send the final user-facing message to avoid conflicting outputs. In Microsoft terms, orchestration can be implemented as agentic flows in Copilot Studio, connected-agent patterns in Foundry, or explicit orchestrators in code using structured tool schemas and shared state. Strategic Impact – How Agentic AI Changes Knowledge Work Agentic AI is no longer an experimental overlay to enterprise systems. It is becoming an embedded operational layer inside core workflows. Unlike earlier chatbot deployments that answered isolated questions, modern enterprise agents execute end-to-end processes, interact with structured systems, maintain context, and operate within governed boundaries. The shift is not about conversational intelligence alone; it is about workflow execution at scale. The transformation becomes clearer when examining real implementations across industries. In legal services, agentic systems have moved beyond document summarization into operational case automation. Assembly Software’s NeosAI, built on Azure AI infrastructure, integrates directly into legal case management systems and automates document analysis, structured data extraction, and first-draft generation of legal correspondence. What makes this deployment impactful is not merely the generative drafting capability, but the integration architecture. NeosAI is not an isolated chatbot; it operates within the same document management systems, billing systems, and communication platforms lawyers already use. Firms report time savings of up to 25 hours per case, with document drafting cycles reduced from days to minutes for first-pass outputs. Importantly, the system runs within secure Azure environments with zero data retention policies, addressing one of the most sensitive concerns in legal AI adoption: client confidentiality. JPMorgan’s COiN platform represents another dimension of legal and financial automation. Instead of conversational assistance, COiN performs structured contract intelligence at production scale. It analyzes more than 12,000 commercial loan agreements annually, extracting over 150 clause attributes per document. Work that previously required approximately 360,000 human hours now executes in seconds. The architecture emphasizes structured NLP pipelines, taxonomy-based clause classification, and private cloud deployment for regulatory compliance. Rather than replacing legal professionals, the system flags unusual clauses for human review, maintaining oversight while dramatically accelerating analysis. Over time, COiN has also served as a knowledge retention mechanism, preserving institutional contract intelligence that would otherwise be lost with employee turnover. In financial services, the impact is similarly structural. Morgan Stanley’s internal AI Assistant allows wealth advisors to query over 100,000 proprietary research documents using natural language. Adoption has reached nearly universal usage across advisor teams, not because it replaces expertise, but because it compresses research time and surfaces insights instantly. Building on this foundation, the firm introduced an AI meeting debrief agent that transcribes client conversations using speech-to-text models and generates CRM notes and follow-up drafts through GPT-based reasoning. Advisors review outputs before finalization, preserving human judgment. The result is faster client engagement and measurable productivity improvements. What differentiates Morgan Stanley’s approach is not only deployment scale, but disciplined evaluation before release. The firm established rigorous benchmarking frameworks to test model outputs against expert standards for accuracy, compliance, and clarity. Only after meeting defined thresholds were systems expanded firmwide. This pattern—evaluation before scale—is becoming a defining trait of successful enterprise agent deployment. Human Resources provides a different perspective on agentic AI. Johnson Controls deployed an AI HR assistant inside Slack to manage policy questions, payroll inquiries, and onboarding support across a global workforce exceeding 100,000 employees. By embedding the agent in a channel employees already use, adoption barriers were reduced significantly. The result was a 30–40% reduction in live HR call volume, allowing HR teams to redirect focus toward strategic workforce initiatives. Similarly, Ciena integrated an AI assistant directly into Microsoft Teams, unifying HR and IT support through a single conversational interface. Employees no longer navigate separate portals; the agent orchestrates requests across backend systems such as Workday and ServiceNow. The technical lesson here is clear: integration breadth drives usability, and usability drives adoption. Engineering and IT operations reveal perhaps the most technically sophisticated application of agentic AI: multi-agent orchestration. In a proof-of-concept developed through collaboration between Microsoft and ServiceNow, an AI-driven incident response system coordinates multiple agents during high-priority outages. Microsoft 365 Copilot transcribes live war-room discussions and extracts action items, while ServiceNow’s Now Assist executes operational updates within IT service management systems. A Semantic Kernel–based manager agent maintains shared context and synchronizes activity across platforms. This eliminates the longstanding gap between real-time discussion and structured documentation, automatically generating incident reports while freeing engineers to focus on remediation rather than clerical tasks. The system demonstrates that orchestration is not conceptual—it is operational. Across these examples, the pattern is consistent. Agentic AI changes knowledge work by absorbing structured cognitive labor: document parsing, compliance classification, research synthesis, workflow routing, transcription, and task coordination. Humans remain essential for judgment, ethics, and accountability, but the operational layer increasingly runs through AI-mediated execution. The result is not incremental productivity improvement; it is structural acceleration of knowledge processes. Design and Governance Challenges – Managing the Risks As agentic AI shifts from answering questions to executing workflows, governance must mature accordingly. These systems retrieve enterprise data, invoke APIs, update records, and coordinate across platforms. That makes them operational actors inside your architecture—not just assistants. The primary shift is this: autonomy increases responsibility. Agents must be observable. Every retrieval, reasoning step, and tool invocation should be traceable. Without structured telemetry and audit trails, enterprises lose visibility into why an agent acted the way it did. Agents must also operate within scoped authority. Least-privilege access, role-based identity, and bounded credentials are essential. An HR agent should not access finance systems. A finance agent should not modify compliance data without policy constraints. Autonomy only works when it is deliberately constrained. Execution boundaries are equally critical. High-risk actions—financial approvals, legal submissions, production changes—should include embedded thresholds or human approval gates. Autonomy should be progressive, not absolute. Cost and performance must be governed just like cloud infrastructure. Agentic systems can trigger recursive calls and model loops. Without usage monitoring, rate limits, and model-tier routing, compute consumption can escalate unpredictably. Finally, agentic systems require continuous evaluation. Real-world testing, live monitoring, and drift detection ensure the system remains aligned with business rules and compliance requirements. These are not “set and forget” deployments. In short, agentic AI becomes sustainable only when autonomy is paired with observability, scoped authority, embedded guardrails, cost control, and structured oversight. Conclusion – Towards the Agentic Enterprise The organizations achieving meaningful returns from agentic AI share a common pattern. They do not treat AI agents as experimental tools. They design them as production systems with defined roles, scoped authority, measurable KPIs, embedded observability, and formal governance layers. When autonomy is paired with integration, memory, orchestration, and governance discipline, agentic AI becomes more than automation—it becomes an operational architecture. Enterprises that master this architecture are not merely reducing costs; they are redefining how knowledge work is executed. In this emerging model, human professionals focus on strategic judgment and innovation, while AI agents manage structured cognitive execution at scale. The competitive advantage will not belong to those who deploy the most AI, but to those who deploy it with architectural rigor and governance maturity. Before we rush to deploy more agents, a few questions are worth asking: If an AI agent executes a workflow in your enterprise today, can you trace every reasoning step and tool invocation behind that decision? Does your architecture treat AI as a conversational layer - or as an operational actor with scoped identity, cost controls, and policy enforcement? Where should autonomy stop in your organization - and who defines that boundary? Agentic AI is not just a capability shift. It is an architectural decision. Curious to hear how others are designing their control planes and orchestration layers. References MIT Sloan – “Agentic AI, Explained” by Beth Stackpole: A foundational overview of agentic AI, its distinction from traditional generative AI, and its implications for enterprise workflows, governance, and strategy. Microsoft TechCommunity – “Introducing Multi-Agent Orchestration in Foundry Agent Service”: Details Microsoft’s multi-agent orchestration capabilities, including Connected Agents, Multi-Agent Workflows, and integration with A2A and MCP protocols. Microsoft Learn – “Extend the Capabilities of Your Agent – Copilot Studio”: Explains how to build and extend custom agents in Microsoft Copilot Studio using tools, connectors, and enterprise data sources. Assembly Software’s NeosAI case – Microsoft Customer Stories JPMorgan COiN platform – GreenData Case Study HR support AI (Johnson Controls, Ciena, Databricks) – Moveworks case studies ServiceNow & Semantic Kernel multi-agent P1 Incident – Microsoft Semantic Kernel BlogDeep dive into the SSMA Code Conversion Copilot Architecture
The Problem We Set Out to Solve Migrating from Oracle PL/SQL to SQL Server T‑SQL is notoriously complex. While SSMA’s rule engine covers hundreds of conversion rules, edge cases, custom logic, and nuanced syntax but it often slips through. Developers end up spending hours manually fixing scripts, validating correctness, and worrying about regressions. The Copilot was built to tackle this pain point: augment SSMA’s rule engine with large language models (LLMs) that can reason about tricky conversions, explain their logic, and accelerate the migration process. But building trust in AI‑generated code meant we had to design an architecture that was controllable, reliable, and secure. SSMA Code Conversion Copilot was released back in the month of May and some of the use cases are elaborated here. This blog talks about the inner working of Copilot. ⚙️ Semantic Kernel for Skill / Plugin Management At the heart of SSMA Copilot lies Semantic Kernel, Microsoft’s open‑source framework for integrating LLMs. It offers two big capabilities: Prompt management — defining prompts as reusable “skills” with parameters like model, temperature, and token count. Agentic orchestration — automating workflows by chaining tools and prompts together. For Copilot, we deliberately chose only prompt management at this point. We have also added native skills such as checking the correctness of syntax and semantics but have not used agentic orchestration for the current implementation. ❌ Why Not Agentic Features? Agentic orchestration can be powerful, but in practice it wasn’t reliable enough for production migrations. Tool selection logic sometimes failed, leading to incorrect validations or spurious edits. Moreover, we saw an issue with latency. Instead, we implemented a deterministic workflow that gave us full control. ✅ Manual Orchestration Workflow Our workflow looks like this (please refer to the diagram): Partial Migration: SSMA generates a baseline conversion. Copilot Authentication: The Copilot is authenticated using the inputs provided by the user. This is where the model is also decided. Alternately, the user can use the managed endpoint that is controlled by Microsoft. LLM Completion: Copilot fills in gaps. Moreover, it explains the solution, points out the error that it is trying to resolve in simple language. Parsing & Compilation: A target‑dialect parser checks syntax. This catches unsupported constructs or binding issues far more reliably than prompt tuning. Spurious Edit Detection: LLMs are instructed to only enhance flagged portions of code. Any edits to “correct” blocks incur penalties, with a strict threshold of zero spurious edits allowed. Query Execution & Data Generation: Where possible, we generate minimal synthetic data (two rows per table) to validate equivalence between source and target queries. Semantic Equivalence Checks: For cases where execution isn’t feasible, we use LLM‑based scoring to judge logical fidelity. This loop repeats until syntactic and semantic correctness is achieved. By using this workflow, we avoided regression spirals and ensured predictable outcomes across dialects. This workflow was tested using our built-in evaluation framework which has leveraged the rich test cases of SSMA. 🔑 Feature Comparison Managed Endpoint Authentication was released with SSMA 10.4 in November 2025. Managed Endpoint BYOK Provisioning OpenAI Endpoint No Yes LLM Model Selection Automatic Manual Authentication Mandatory Entra ID OpenAI Endpoint and Key Private Endpoint Support No Yes Cross Tenant Dependency* Yes No Pricing Free Consumption in actuals *Cross Tenant Dependency: The endpoint is hosted in Microsoft tenant while the authentication happens in the user tenant. 🔒 Privacy and Data Handling A critical point: we don’t store your data. The scripts you provide are used only for generating the migration output. Once the process completes, the data is flushed. No proprietary code or schema information is retained. This design ensures: Security: We run OpenAI in Microsoft tenant following all security protocols. Trust: Copilot is a tool, not a repository. Compliance: Aligns with enterprise privacy expectations. 🌟 Why This Matters By combining Semantic Kernel framework, SSMA Copilot delivers reliable migrations without sacrificing flexibility. And with the managed endpoint, it’s now easier and safer than ever to adopt — no keys, no storage, no friction. This isn’t just about faster migrations. It’s about building trust in AI‑assisted workflows, ensuring correctness, and giving enterprises confidence that their data is secure. Get started with your Copilot based migration journey using SSMA for OracleAzure Skilling at Microsoft Ignite 2025
The energy at Microsoft Ignite was unmistakable. Developers, architects, and technical decision-makers converged in San Francisco to explore the latest innovations in cloud technology, AI applications, and data platforms. Beyond the keynotes and product announcements was something even more valuable: an integrated skilling ecosystem designed to transform how you build with Azure. This year Azure Skilling at Microsoft Ignite 2025 brought together distinct learning experiences, over 150+ hands-on labs, and multiple pathways to industry-recognized credentials—all designed to help you master skills that matter most in today's AI-driven cloud landscape. Just Launched at Ignite Microsoft Ignite 2025 offered an exceptional array of learning opportunities, each designed to meet developers anywhere on the skilling journey. Whether you joined us in-person or on-demand in the virtual experience, multiple touchpoints are available to deepen your Azure expertise. Ignite 2025 is in the books, but you can still engage with the latest Microsoft skilling opportunities, including: The Azure Skills Challenge provides a gamified learning experience that lets you compete while completing task-based achievements across Azure's most critical technologies. These challenges aren't just about badges and bragging rights—they're carefully designed to help you advance technical skills and prepare for Microsoft role-based certifications. The competitive element adds urgency and motivation, turning learning into an engaging race against the clock and your peers. For those seeking structured guidance, Plans on Learn offer curated sets of content designed to help you achieve specific learning outcomes. These carefully assembled learning journeys include built-in milestones, progress tracking, and optional email reminders to keep you on track. Each plan represents 12-15 hours of focused learning, taking you from concept to capability in areas like AI application development, data platform modernization, or infrastructure optimization. The Microsoft Reactor Azure Skilling Series, running December 3-11, brings skilling to life through engaging video content, mixing regular programming with special Ignite-specific episodes. This series will deliver technical readiness and programming guidance in a livestream presentation that's more digestible than traditional documentation. Whether you're catching episodes live with interactive Q&A or watching on-demand later, you’ll get world-class instruction that makes complex topics approachable. Beyond Ignite: Your Continuous Learning Journey Here's the critical insight that separates Ignite attendees who transform their careers from those who simply collect swag: the real learning begins after the event ends. Microsoft Ignite is your launchpad, not your destination. Every module you start, every lab you complete, and every challenge you tackle connects to a comprehensive learning ecosystem on Microsoft Learn that's available 24/7, 365 days a year. Think of Ignite as your intensive immersion experience—the moment when you gain context, build momentum, and identify the skills that will have the biggest impact on your work. What you do in the weeks and months following determines whether that momentum compounds into career-defining expertise or dissipates into business as usual. For those targeting career advancement through formal credentials, Microsoft Certifications, Applied Skills and AI Skills Navigator, provide globally recognized validation of your expertise. Applied Skills focus on scenario-based competencies, demonstrating that you can build and deploy solutions, not simply answer theoretical questions. Certifications cover role-based scenarios for developers, data engineers, AI engineers, and solution architects. The assessment experiences include performance-based testing in dedicated Azure tenants where you complete real configuration and development tasks. And finally, the NEW AI Skills Navigator is an agentic learning space, bringing together AI-powered skilling experiences and credentials in a single, unified experience with Microsoft, LinkedIn Learning and GitHub – all in one spot Why This Matters: The Competitive Context The cloud skills race is intensifying. While our competitors offer robust training and content, Microsoft's differentiation comes not from having more content—though our 1.4 million module completions last fiscal year and 35,000+ certifications awarded speak to scale—but from integration of services to orchestrate workflows. Only Microsoft offers a truly unified ecosystem where GitHub Copilot accelerates your development, Azure AI services power your applications, and Azure platform services deploy and scale your solutions—all backed by integrated skilling content that teaches you to maximize this connected experience. When you continue your learning journey after Ignite, you're not just accumulating technical knowledge. You're developing fluency in an integrated development environment that no competitor can replicate. You're learning to leverage AI-powered development tools, cloud-native architectures, and enterprise-grade security in ways that compound each other's value. This unified expertise is what transforms individual developers into force-multipliers for their organizations. Start Now, Build Momentum, Never Stop Microsoft Ignite 2025 offered the chance to compress months of learning into days of intensive, hands-on experience, but you can still take part through the on-demand videos, the Global Ignite Skills Challenge, visiting the GitHub repos for the /Ignite25 labs, the Reactor Azure Skilling Series, and the curated Plans on Learn provide multiple entry points regardless of your current skill level or preferred learning style. But remember: the developers who extract the most value from Ignite are those who treat the event as the beginning, not the culmination, of their learning journey. They join hackathons, contribute to GitHub repositories, and engage with the Azure community on Discord and technical forums. The question isn't whether you'll learn something valuable from Microsoft Ignite 2025-that's guaranteed. The question is whether you'll convert that learning into sustained momentum that compounds over months and years into career-defining expertise. The ecosystem is here. The content is ready. Your skilling journey doesn't end when Ignite does—it accelerates.Foundry Agent Service at Ignite 2025: Simple to Build. Powerful to Deploy. Trusted to Operate.
The upgraded Foundry Agent Service delivers a unified, simplified platform with managed hosting, built-in memory, tool catalogs, and seamless integration with Microsoft Agent Framework. Developers can now deploy agents faster and more securely, leveraging one-click publishing to Microsoft 365 and advanced governance features for streamlined enterprise AI operations.11KViews3likes1Comment