openai
142 TopicsMicrosoft Foundry Guardrails Getting in Your Way? Here’s How to Dial Them Down
How This All Started So here’s the story. I just got back from a trip and had a pile of footage sitting on my laptop. Being the lazy (sorry, efficient) person I am, I fired up OpenCode and asked GPT-6 Astra, running on Microsoft Foundry, to cut me a travelogue. Nothing fancy: under two minutes, nice lighting, clean transitions, no cringy effects, a quick QA before showing me, and the output in its own folder. Easy, right? Nope. This is what I got instead: “Image processing blocked due to content policy violation.” Seriously? It’s holiday footage! Nothing even remotely dodgy in there. This is a classic false positive from the default guardrails, and the good news is it’s totally fixable. Let me show you how. My Setup Quick context before we dive in: I’ve got two models deployed on Microsoft Foundry, gpt-6-astra and gpt-6-sol. Both were running on Microsoft’s out-of-the-box guardrail. Step 1: Find the Guardrails Page Head over to the Microsoft Foundry portal, click Build, then hit Guardrails in the left menu. You’ll see three guardrails that Microsoft gives you by default: Microsoft.Default, Microsoft.DefaultV2 and Microsoft.MAIDefault. Microsoft.DefaultV2 is the one every new deployment gets, which is why it’s sitting on both of my models. Here’s the catch: you can’t edit or delete these Microsoft-managed defaults. So instead of tweaking them, we’re going to build our own guardrail and swap it in. Step 2: Create Your Own Guardrail Smash that "Create" button and you’ll land on the Create guardrail page. This is where all the knobs and switches live: Every control has three bits: the risk type, the intervention point (does it check what you send in, what the model spits out, or both?) and the action. The magic trick for loosening things up is flipping the action from Block to Annotate. With Annotate, Foundry still scans the content and tags it in the API response, but it stops slamming the door on your request. So What Does Each Setting Actually Do? Before you go on a switching-off spree, it’s worth knowing what each of these does and what you’re giving up when you loosen it. Here’s the quick tour: Jailbreak: This one catches prompts trying to trick the model into ignoring its rules. On Block, those prompts get rejected outright. On Annotate, they go through with a flag. Turn it off completely and you’re trusting the model’s own training to keep it in line. Network (egress rules): Controls which outbound calls a hosted agent is allowed to make. As the portal points out, it only applies to hosted agents, so for plain model deployments like mine it doesn’t change a thing. Indirect prompt injections: Watches user input and tool responses (files, docs, web pages the model reads) for sneaky instructions someone has planted. Leave it on and your agents are protected when they read outside content; switch it off and a dodgy file could quietly hijack your model. For an agentic tool like OpenCode, which reads files and runs shell commands, I’d honestly keep this one on, even if it’s just on Annotate. Spotlighting (Preview): Tags external content inside the prompt so the model can tell your real instructions apart from random untrusted data. Think of it as an extra seatbelt against indirect attacks. Content harms (Hate, Sexual, Self-harm, Violence): Each of these has a severity slider that starts at Medium blocking, meaning anything rated medium or higher gets blocked. Slide it down to Lowest blocking and only the really nasty stuff gets stopped, which kills off most false positives like mine. The asterisk means these four are mandatory: you can turn the dial down, but you can’t switch them off. Blocklists: Want to ban specific words or phrases, like profanity or your competitor’s name? This is where you do it. It’s off by default. Protected material for code and text: Checks whether the model is about to spit out known copyrighted text (song lyrics, articles and so on) or code lifted from public repos. Block stops it; Annotate lets it through with a flag. Switch it off and you’re rolling the dice on your app reproducing someone else’s copyrighted work. Step 3: Pick Your Models Hit Next and Foundry asks which agents and models you want this guardrail on. Any model you’ve already deployed in your project shows up here. For me that’s gpt-6-astra and gpt-6-sol, so I ticked both. Step 4: Name It and Pick a Streaming Mode One more Next and you’re on the Review page. Give your guardrail a name (I went with NoGuardrails, because subtlety isn’t my thing) and pick a streaming mode. You’ve got two choices: Default: Foundry buffers the response and runs it through the guardrail before each chunk goes out. Nothing reaches the user until it’s been checked. Safest option, but you’ll feel a bit of lag when streaming. Asynchronous: Content streams back the moment it’s generated, with the filters running in the background. Much snappier, but flagged content might flash up briefly before the filter catches it, so your app has to clean up after the fact. Microsoft pitches this for low-latency stuff like internal dev tools, which is exactly my use case. Give the summary a quick once-over, then click Create. Done! Did It Work? Yep! With my shiny new guardrail in place, I fired off the exact same request, this time to GPT-6 Sol. And boom: no more content policy error. The model went straight to work scanning my footage and putting the video together. Wrapping Up Look, Microsoft’s default guardrails are a solid starting point, but they can be a bit trigger-happy when you’re doing perfectly legit stuff like video editing, creative work or internal tooling. Since you can’t touch the defaults, the trick is to roll your own: flip Block to Annotate where it makes sense, drag those content harm sliders down, pick the streaming mode that fits your app, and assign it to your deployments. That’s it! One friendly word of warning though: with great power comes great responsibility. Only loosen what you actually need, keep things like indirect prompt injection detection switched on for any agent that reads files or browses the web, and think twice before doing this on anything customer-facing. And if you want to go further than the portal lets you, like switching content filters off completely, you’ll need to apply to Microsoft for approval first. Happy building!114Views0likes0Comments
Update network rules for the API Management service tag
To improve Azure API Management resiliency and scalability, we’re expanding our infrastructure and adding control-plane IP addresses. These addresses are included in the ApiManagement service tag. If you use VNet internal or VNET external with the classic (v1) tiers, check your network security groups (NSGs), user-defined routes (UDRs), and firewalls. Replace hard-coded API Management IP addresses with the service tag wherever supported. Make this change by November 30, 2026, to avoid disruption to management access. If network rules block connectivity to the management endpoint after that date, you may be unable to manage your API Management configuration—such as APIs, operations, and policies—from the Azure portal or CLI. This change affects management-plane traffic only. Runtime traffic, including API calls to your services, is not impacted. Find the ApiManagement tag in Microsoft’s Azure service tags overview or the latest Azure IP Ranges and Service Tags JSON download. If your firewall doesn’t support service tags, use the published list and keep your IP rules synchronized with its latest version. Don’t rely on a fixed, point-in-time IP list. During the transition, the service tag includes both existing and new addresses. For reference: Use API Management in an internal virtual networkLogic Apps Aviators Newsletter - September 2026
In this issue: Ace Aviator of the Month News from our product group News from our community Ace Aviator of the Month September 2026's Ace Aviator: Parth Talaviya What's your role and title? What are your responsibilities? AI-Powered Azure/.NET Solution Architect I work as an Azure/.NET Solution Architect, combining technical leadership with building a Microsoft-focused boutique company. My work mainly revolves around application modernization and migration, cloud architecture, integrations, and team leadership. I also stay hands-on with development, architecture reviews, production troubleshooting, and mentoring developers. Can you give us some insights into your day-to-day activities and what a typical day in your role looks like? My day usually starts with thinking about how we can add more value to our clients' businesses. It includes reviewing project priorities, solving technical challenges, discussing architecture, supporting developers, and collaborating with stakeholders. I mainly work across .NET, Azure, APIs, integrations, DevOps, and AI automation, so every day brings something new to learn and solve. What motivates and inspires you to be an active member of the Aviators/Microsoft community? What really motivates me is how active and supportive the Microsoft community is. People are genuinely willing to help each other, share experiences, and solve problems together. Being able to use my own experience to help someone overcome a challenge genuinely makes my day, while learning from others keeps me motivated to continuously improve. Looking back, what advice do you wish you had been given earlier that you'd now share with those looking to get into STEM/technology? You don’t have to do everything alone. In technology, especially when you are stuck on a very specific problem, it can sometimes feel that way. Asking questions, learning from the community, and collaborating with others can make a huge difference. I would also say: embrace AI early, but use it wisely. Don’t use AI only to generate code. Use it to understand concepts, challenge your thinking, explore better approaches, review your work, and become a better problem-solver. What has helped you grow professionally? Continuous learning and solving real-world challenges have helped me grow the most. Working on legacy modernization, cloud architecture, large-scale data systems, automation, and AI has taught me to think beyond writing code and understand the broader business impact. Being part of a strong technical community has also helped significantly. Whenever you are stuck, there is often someone who has faced a similar challenge and is willing to share their experience. If you had a magic wand that could create a feature in Logic Apps, what would it be and why? I would create an AI-powered Copilot troubleshooting and self-healing assistant for Logic Apps. It could analyze failed workflows, understand the execution context, identify the likely root cause, suggest a fix, and provide safe recovery options. For complex integrations, this could save significant troubleshooting time and allow developers to focus more on building solutions rather than spending hours finding where something went wrong. News from our product group Use connectors with Managed Identity in the Logic Apps Standard extension Managed Identity is Azure's built-in way to authenticate to Microsoft Entra-protected resources without storing credentials, secrets, or connection strings. Deployed Logic Apps have supported it for some time, and this post explains connector support in the Logic Apps Standard extension. Introducing dependency telemetry in Application Insights for Azure API Management policies Running API platforms at scale requires both handling load and understanding where inefficiencies occur. This post introduces dependency telemetry in Application Insights for Azure API Management policies to help teams identify performance bottlenecks. Power Azure SRE Agent with the tools it needs Azure SRE Agent is an AI-powered service designed to reduce operational toil. Teams can use it to investigate incidents, identify probable causes, and automate health-related operational work using connected tools. Give your Copilot agents real tools, without hand-wiring MCP GitHub Copilot coding agents can work independently on branches, but some tasks require access to external systems. This post shows how to equip agents with real tools without manually wiring Model Context Protocol integrations. Zonal redundancy in API management Standard v2 APIs power modern mobile experiences, microservices, AI-driven applications, and business-critical integrations. This post explains zonal redundancy in Azure API Management Standard v2 for improving resilience as customers modernize their API platforms. BizTalk Server 2020 End-of-Sale Announcement Microsoft announces that BizTalk Server 2020 and Host Integration Server 2020 sales are expected to end on March 31, 2027. Existing licensed deployments can continue to be used, while mainstream support for BizTalk Server 2020 is scheduled through April 12, 2028. An optional paid extended-mainstream support offering is planned for eligible customers through April 10, 2030, with final terms to be published later. The post recommends beginning migration planning now, evaluating Azure Logic Apps Standard or Azure Logic Apps Hybrid, inventorying dependencies, and using the Logic Apps Migration Agent to assess and convert supported workloads. Logic App Storage Inspector Logic App Storage Inspector is a read-only Kudu site extension for examining storage used by an Azure Logic App Standard application. It supports searching workflow action and trigger history by workflow, date, or text, with results exportable as CSV or JSON. Users can browse and compare workflow-definition versions, review table and queue information, and monitor health indicators and refresh status. The extension isolates access to the current Logic App site, uses asynchronous paged operations for large storage accounts, and can be installed from Kudu Site Extensions. News from our community Azure Logic Apps Automation – A Practical Infrastructure Lab with Agentic Remediation Post by João Paulo Costa João Paulo Costa tests Azure Logic Apps Automation through an after-hours virtual-machine remediation lab. The workflow uses an agent to inspect VM metadata, tags, and runtime state, then apply guardrails before deciding whether to deallocate the resource, leave it unchanged, or request review. The article contrasts agentic decision-making with deterministic workflows, documents tool and connector choices, and examines preview limitations such as runtime-state retrieval and managed-identity support. It also emphasizes constrained permissions, explicit policies, verification after actions, and negative testing for production, exemptions, missing ownership, and disabled remediation. Agentic Integration: Non-Deterministic Experience, Solid Core Post by Massimo Crippa Massimo Crippa examines whether agentic capabilities make enterprise integration non-deterministic. He separates an agent’s variable decision-making from the predictable integration layer that executes selected capabilities. The article highlights durable messaging, reliable contracts, idempotency, transactional boundaries, retries, compensation, governance, and observability as continuing requirements. It presents tools as the boundary between reasoning and execution: agents determine what should happen, while integration platforms control how operations are performed safely. Azure Logic Apps is positioned as both a deterministic integration foundation and a platform that can expose governed capabilities to emerging agentic experiences. Build AI Agents in Azure Logic Apps (Conversational + Autonomous) Video by Rafsan Huseynov Rafsan Huseynov presents a video on building conversational and autonomous AI agents with Azure Logic Apps. The session describes Logic Apps as more than a background integration layer, covering orchestration, managed identities, agent loops, and the use of workflows as MCP tools. Demonstrations explore connections with Document Intelligence, Blob Storage, Microsoft Foundry, and Copilot Studio workflows, alongside conversational and autonomous agent patterns. The video also introduces a separate low-code automation experience with scoped permissions, while noting that the demonstrations use synthetic data and that the experience remains in preview. BizTalk to Logic Apps migration (three things, everyone gets wrong) Post by Brajesh Sinha Brajesh Sinha explains why simple counts of BizTalk orchestrations and maps produce unreliable Logic Apps migration estimates. One orchestration can fan out into several Azure resources, supposedly simple maps may hide substantial transformation complexity, and operational requirements are often omitted from statements of work. The article highlights the architecture, mapping, and production-readiness effort that teams frequently underestimate. It encourages migration planners to assess actual behavior and dependencies rather than relying on inventory totals, helping create more realistic timelines, scope, and delivery expectations. Hybrid Logic Apps on RKE2: a self-managed cluster with MetalLB Post by Sonny Gillissen Sonny Gillissen demonstrates how to run Azure Logic Apps Hybrid on a self-managed RKE2 Kubernetes cluster. Because RKE2 does not include a native load balancer, the walkthrough uses MetalLB to assign the ingress IP required by the deployment. It covers creating the cluster, configuring networking, connecting the environment to Azure Arc, and handling the platform-specific details needed for Logic Apps. The article provides a practical alternative for teams evaluating hybrid integration workloads outside managed Kubernetes services, extending earlier guidance for OpenShift environments. An Introduction to Logic Apps Standard SDK Video by Marcel Medina Marcel Medina shares a Coding Night ANZ recording introducing the Logic Apps Standard SDK. The session shows how the SDK brings a modern, code-first .NET development experience to Azure Logic Apps while retaining the platform’s connectors, triggers, monitoring, and managed runtime. It is aimed at developers who want familiar tooling and stronger source-driven workflow development without giving up managed integration capabilities. The post also thanks the community for its questions and participation and provides the complete session recording for anyone who missed the live event. Managed Identity in Logic Apps Standard: A Zero Trust Read Post by Steef-Jan Wiggers Steef-Jan Wiggers examines new Managed Identity support for connectors in the Logic Apps Standard local development experience. Developers can now use a consistent authentication model from development through production instead of swapping connection strings before deployment, removing a common source of unmanaged secrets. The article frames this improvement through Zero Trust while stressing that authentication alone does not replace disciplined RBAC. A working azd sample demonstrates the setup and highlights a critical application setting whose absence causes the otherwise correctly configured connection, access policy, and role assignment to fail.690Views0likes0CommentsAI Gateway tier of Azure API Management — August 2026 updates
The August 2026 update for the AI Gateway tier (preview) of Azure API Management introduces new capabilities for observing AI workloads and governing model spend. Release highlights Richer OpenTelemetry observability: AI Gateway can now emit logs, distributed traces, token metrics, and estimated cost metrics through the OpenTelemetry Protocol. The built-in monitoring experience helps teams investigate model and MCP tool activity, policy execution, latency, errors, token consumption, and individual traces. Model cost monitoring and budget enforcement: Teams can review estimated model spend by API key and model, then use cost limit policies to set calendar-based budgets and block requests when configured limits are reached. The release also streamlines Microsoft Foundry model imports, refines provider onboarding, improves portal reliability and error guidance, expands Anthropic Messages compatibility, and adds an in-product What's new experience. For configuration guidance, important upgrade information, and the complete list of changes, read the full August 2026 release notes in the AI Gateway portal. Try the latest capabilities in the AI Gateway portal.852Views0likes0CommentsIntroducing APIOps CLI
APIOps CLI helps teams extract, version, review, preview, and publish Azure API Management configuration through source-controlled DevOps workflows. Today, we're excited to announce APIOps CLI, a new command-line experience designed to help organizations manage Azure API Management (APIM) using modern configuration-as-code and GitOps practices. As APIs become increasingly central to digital transformation, organizations need a reliable way to manage API definitions, policies, products, diagnostics, and gateway configuration across multiple environments. APIOps CLI provides a streamlined, developer-friendly approach to extract, version, review, and publish API Management configuration through familiar DevOps workflows. Why APIOps CLI? Traditional API management processes often rely on manual configuration changes, environment-specific customizations, and limited visibility into what changed and why. As API estates grow, these approaches become difficult to scale, audit, and govern. APIOps CLI addresses these challenges by enabling teams to manage API Management configuration as source-controlled artifacts. Every change can be reviewed through pull requests, tracked through Git history, and promoted consistently across development, test, and production environments. The result is improved governance, greater reliability, better collaboration between API developers and platform operators, and a simpler path toward enterprise-scale API operations. What APIOps CLI Enables APIOps CLI provides capabilities that help organizations adopt a true APIOps model: Extract API Management configuration into local artifact files Store and version configuration in Git repositories Review changes through standard pull request workflows Publish approved artifacts back into API Management environments Promote configuration consistently across environments Scaffold GitHub Actions and Azure DevOps pipelines Support automated CI/CD deployment patterns Enable auditable, repeatable API configuration management By treating API Management configuration as code, organizations gain the same operational excellence practices that software development teams have relied on for years. A Modern GitOps Workflow for APIs The APIOps CLI workflow follows a simple yet powerful pattern: Extract configuration from an existing API Management instance. Store the generated artifacts in source control. Review and approve changes through pull requests. Run automated validation and deployment pipelines. Publish approved configuration back to target API Management environments. This approach creates a clear separation between authoring, review, approval, and deployment while maintaining a complete audit trail of API platform changes. For organizations already practicing GitOps, APIOps CLI integrates naturally into existing development workflows and governance processes. Built for Real-World Enterprise Scenarios APIOps CLI is designed to support customers operating at enterprise scale. Common use cases include: Migrating away from manual API Management administration Standardizing deployments across multiple environments Establishing controlled promotion paths from development to production Implementing governance and compliance requirements Supporting platform engineering and API platform teams Managing large inventories of APIs, products, policies, and configurations Enabling self-service API development with centralized governance Whether you're operating a single API Management instance or managing a large multi-team API platform, APIOps CLI provides a foundation for consistent and repeatable operations. Integrated with Your Existing Toolchain APIOps CLI works alongside the tools teams already use: GitHub Azure DevOps Azure Pipelines GitHub Actions Azure CLI Existing Git repositories and branching strategies The tool can generate CI/CD scaffolding to accelerate adoption, helping teams move from manual operations to automated deployments with less effort. Open Source and Community Driven APIOps CLI is available as an open-source project under the Azure GitHub organization. The repository includes source code, architecture guidance, command documentation, CI/CD examples, walkthroughs, troubleshooting guidance, and reference material. By making the project open and community-driven, we are enabling customers, partners, and contributors to participate directly in the evolution of Azure API Management DevOps practices. Getting Started Getting started is straightforward: Install the APIOps CLI package. Authenticate with Azure. Extract an existing API Management instance into local artifacts. Commit those artifacts to a Git repository. Review and approve changes through pull requests. Publish approved changes back to Azure API Management. We recommend beginning with a non-production environment to establish your workflow, validate governance processes, and familiarize teams with the configuration-as-code model. Looking Ahead APIs have become a strategic asset for every organization. As API estates continue to expand, successful teams will increasingly adopt automation, governance, and GitOps practices to maintain speed without sacrificing control. APIOps CLI is an important step in that journey. It provides a modern foundation for managing Azure API Management configurations with the same rigor, automation, and reliability that organizations expect from modern software delivery practices. We invite you to explore APIOps CLI, try it in your environment, share feedback, and join us in shaping the future of API operations on Azure. Resources APIOps CLI GitHub repository: https://github.com/Azure/apiops-cli/tree/main Microsoft Learn: Manage API Management configuration with APIOps CLIAdding a Fallback Model to Hermes with Microsoft Foundry
So the plan was simple. Leave the Bedrock configuration untouched, then wire Microsoft Foundry in behind it as a fallback, so Hermes always has somewhere else to go when the primary provider is not responding. A few other reasons pushed me towards Foundry in particular: Redundancy that does not need me. If Bedrock is throttled or out of quota, I want Hermes to fail over on its own rather than waiting for me to notice. A catalogue I already pay for. Foundry puts the latest GPT models next to open-weight and partner models in one place, so I can pick a model that suits the task instead of settling for whatever a single provider happens to offer. Enterprise controls out of the box. Region pinning, private networking, content filters and per-deployment quota all sit in the same portal, which makes the setup far easier to defend to a security reviewer. Learning the mechanics before I need them. Working out how Hermes handles a provider chain is much nicer on a quiet Tuesday than during a live outage. Here is the short version, if you are deciding whether to read on. Time: about thirty minutes if nothing goes wrong. Cost: pay-as-you-go tokens only, and none at all while the fallback sits idle. Result: an assistant that keeps answering when your primary provider stops. Before you start, you will need three things: a machine with Hermes already installed and a working primary provider configured, an Azure subscription with access to Microsoft Foundry in a region you can actually deploy into, and enough quota in that region to create a deployment. One thing that made this easy to justify: Foundry deployments bill per token on the standard pay-as-you-go tier. A fallback provider that never gets invoked costs nothing beyond the requests it actually serves, so the insurance is close to free until the day you need it. Chat surface (CLI, messaging) → Hermes Gateway → Primary Amazon Bedrock → Fallback Microsoft Foundry Figure 1: Where the fallback sits. Every request goes through the Hermes gateway to the primary provider; only when that provider is unavailable does the chain continue to Microsoft Foundry. Part 1: Deploying a Model on Microsoft Foundry The first half of this job happens entirely inside the Microsoft Foundry portal and has nothing to do with Hermes yet. All you are really doing here is making sure your Azure subscription can serve a model, and that you hold an endpoint and key Hermes can authenticate with later. 1. Deploy model in Foundry → 2. Copy endpoint + key → 3. hermes fallback add → 4. Authenticate → 5. Select models, test Figure 2: The whole setup in five moves. The first two happen in the Microsoft Foundry portal (orange); the rest happen on the Hermes machine (blue). Go to Microsoft Foundry > Build > Models > Deploy > Deploy a base model. You can deploy a fine-tuned model instead if you already have one, which works just as well with Hermes. Check the region shown at the top of the portal before you commit, because both model availability and deployment quota differ from one region to the next. Then deploy the model you have selected: In this case I deployed gpt-5.6-sol, which is the model Hermes will fall back to. The choice was deliberate rather than exciting. My primary model on Bedrock is a general-purpose chat model, and a fallback is only useful if the answers it gives feel like a continuation of the same conversation rather than a different assistant wearing the same name. The gpt-5.6-sol deployment matches that behaviour closely, it was available in the region I wanted to pin, and the quota I was granted comfortably covers a day of normal use. If a fallback surprises you the first time it fires, it is the wrong fallback. Once the deployment finishes, open it and take note of two values: the target endpoint URI and the API key. Copy both somewhere safe now, because you will be pasting them into Hermes in the next part. If your organisation rotates keys on a schedule, use a key with the longest life you are allowed, since a fallback secured with a credential that expires quietly stops being a fallback. What to copy Where it lives in the portal Where Hermes asks for it Target endpoint URI Deployment > Endpoint > Target URI "Endpoint" prompt in hermes fallback add API key Deployment > Endpoint > Key "API key" prompt, or choose Entra ID instead Deployment name Deployment > Details > Name Shown in the model list Hermes returns Region Top of the portal, next to the resource Must match the region you deployed into Figure 3: Everything Hermes will ask for, and where to find each value before you leave the portal. Part 2: Adding Foundry to Hermes as a Fallback With the Foundry side sorted, everything from here happens in the Hermes CLI. One thing worth knowing before you start: this is the fallback command, not the primary model command, so your existing Bedrock configuration is left completely alone. Nothing in this section can break what is already working, which makes it a good one to try on a live setup. Run the Hermes fallback command: When Hermes asks which provider to add, choose Azure Foundry. The picker still carries the old name; it is the same service that the portal now calls Microsoft Foundry. Paste the target endpoint URI from your deployment, then authenticate with the API key you copied earlier. Hermes also offers Microsoft Entra ID at this prompt, which is the better option if your organisation would rather not have a static key sitting on the machine. If authentication fails here, check the endpoint before you start suspecting the key. In my experience the endpoint is wrong far more often than the credential is, usually because the deployment name at the end of the URI does not match the deployment you actually created. Once authentication succeeds, Hermes lists the deployments your Foundry resource exposes and asks which ones you want to use. You can select more than one, and the order is not cosmetic: Hermes walks down the chain from top to bottom whenever the provider above is unavailable. Treat that list as a priority order, not a shopping basket. What happens to the primary What Hermes does What you see in the chat Responds normally Routes every request to the primary and never touches the chain Nothing. The fallback stays idle Throttled or out of quota Retries the next provider down the chain on the same request A reply, served by the fallback model Endpoint unreachable Keeps failing over on each new request until the primary recovers Slightly different tone and latency, but a working assistant Every provider fails Returns the error rather than hanging An error worth chasing with hermes status Figure 4: The chain in practice. The fallback only earns its keep in the middle two rows, which is exactly why it is easy to forget you configured it. Part 3: Promoting Foundry to the Primary Model At this stage Foundry is sitting in the back seat as a backup. I wanted to reverse the arrangement and make Foundry the primary while Bedrock slides down into the fallback slot, partly because I preferred keeping day-to-day traffic inside my Azure subscription, and partly because I wanted proof the chain works in both directions. Before promotion After promotion Primary: Amazon Bedrock → Primary: Microsoft Foundry Fallback: Microsoft Foundry → Fallback: Amazon Bedrock Figure 5: The promotion, in effect. Nothing is added or removed; the two providers simply trade places in the chain. There is no dedicated "promote" command in Hermes, so the manual route is a short sequence of steps rather than a single instruction: Select the fallback provider/model as the new primary: hermes model Remove the now-duplicate model from the fallback chain: hermes fallback remove Optionally add the old primary model as a fallback: hermes fallback add Restart the messaging gateway: hermes gateway restart Verify the result: hermes status / hermes fallback list That sequence works, and it is good to know what is happening underneath. But since I already had a working provider configured, I would rather just ask Hermes to rearrange itself. This is the part I genuinely enjoy about the tool: the configuration is something you can talk to, not only something you type commands at. Prompt: Okay now please make the model I configured on Microsoft Foundry into the main model, and make the Bedrock one the fallback model! Hermes rewrites the provider chain on its own and confirms the swap once it is done, which is a great deal less error-prone than running the five commands by hand. Part 4: Testing the Switch Configuration you have not tested is just an assumption with extra steps, so the next thing is to confirm Hermes really is talking to Foundry. Type /model when running Hermes to bring up the model picker. You will be prompted to select a provider first. Pick the Microsoft Foundry entry, then choose the specific deployment from the list underneath it. The active model should switch straight away. Send it a plain "Hello" to check that the deployment actually responds, rather than just looking correct in the menu. Appearing in a dropdown and serving a request are two very different things. A second test is worth the thirty seconds it costs: run hermes status to confirm which provider is live, then hermes fallback list to confirm the chain is ordered the way you intended. The picker tells you what you selected; those two commands tell you what Hermes will actually do at three in the morning. Part 5: The Obstacle, and What It Actually Taught Me Every walkthrough has the part the author quietly leaves out. Here is mine: the wrinkle was not the model, it was capacity. My first attempt deployed into the region closest to me out of habit, and the portal turned it down because there was no capacity left for that model at the tier I asked for. The model was clearly listed in the catalogue; being listed and being deployable in your region, on your subscription, at your quota, are three separate questions. Redeploying in a different region fixed it in a couple of minutes, but it meant the endpoint URI changed, which in turn meant the value I had already pasted into Hermes was stale. Re-running hermes fallback add against the new endpoint sorted it out. The lesson is cheap enough to hand over for free: check quota and regional capacity for your specific subscription before you design a walkthrough, a demo or a production fallback around one deployment. In the Foundry portal, Management then Quota shows exactly what you have been granted per region and per model family, which is the only list that matters. Symptom Likely cause Fix Deployment rejected in the portal No capacity for that model at the tier you asked for, in that region Deploy in another region, or drop to a smaller tier Hermes rejects the credential Endpoint URI does not match the deployment you created Re-copy the target URI from the deployment, not the resource Provider authenticates but lists nothing Key belongs to a different Foundry resource Check you are in the right resource, then re-run hermes fallback add Fallback never fires Chain ordered the wrong way round hermes fallback list, then reorder Figure 6: The four things that went wrong, or nearly did, and what fixed each one. There is a silver lining worth stating plainly. Because the fallback chain was already in place, a deployment that refused to come up did not take the assistant down with it. That is precisely the scenario this whole exercise was meant to cover, and it turned up on day one without me having to simulate it. Command Cheat Sheet Everything used in this walkthrough, collected in one place: hermes fallback add: attach a provider to the fallback chain hermes fallback remove: drop a provider from the chain hermes fallback list: show the chain in priority order hermes model: set the primary model hermes gateway restart: restart the messaging gateway after a change hermes status: confirm which provider is currently live /model: switch models from inside a running session Conclusion Adding Microsoft Foundry as a fallback behind my existing Bedrock setup took an afternoon, and most of that was spent recovering from a regional capacity limit I should have checked first. The work itself is small: deploy a model, copy the endpoint and key, run hermes fallback add, authenticate, pick your deployments. The payoff is that Hermes no longer depends on one provider staying healthy. Three things are worth carrying away from this: Check quota, not just the catalogue. The Foundry catalogue shows what Microsoft offers. It does not show what your subscription and region can actually deploy today. Confirm that first, before you build anything on top of a specific deployment. Order your fallback chain deliberately. Hermes works down the list from top to bottom, so the sequence you choose during setup is the failover policy you are going to live with. Put the model you actually trust at the top. Treat the endpoint as part of the credential. Redeploying in a new region changes the endpoint URI, and a fallback pointed at an endpoint that no longer exists is not a fallback. Re-run the setup whenever the deployment moves. The switch from Bedrock primary to Foundry primary also proved the chain runs in both directions, which is the real point. Provider redundancy is only useful if you have watched it work. Next on my list is deliberately breaking the primary provider to confirm the failover triggers on its own, without me typing a single command. If you run this against a different model, region or provider pairing, I would genuinely like to know how it went, particularly if your quota experience was better than mine. Drop it in the comments.383Views0likes0CommentsAnnouncing the General Availability (GA) of the Premium v2 tier of Azure API Management
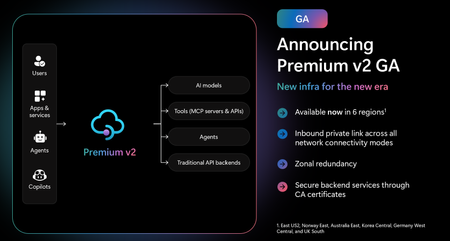
Superior capacity, highest entity limits, unlimited included calls, and the most comprehensive set of features set the Premium v2 tier apart from other API Management tiers. Customers rely on the Premium v2 tier for running enterprise-wide API programs at scale, with high availability, and performance. The Premium v2 tier has a new architecture that eliminates management traffic from the customer VNet, making private networking much more secure and easier to setup. During the creation of a Premium v2 instance, you can choose between VNet injection or VNet integration (introduced in the Standard v2 tier) options. In addition, today we are also adding three new features to Premium v2: Inbound Private Link: You can now enable private endpoint connectivity to restrict inbound access to your Premium v2 instance. It can be enabled along with VNet injection or VNet integration or without a VNet. Availability zone support: Premium v2 now supports availability zones (zone redundancy) to enhance the reliability and resilience of your API gateway. Custom CA certificates: Azure API management v2 gateway can now validate TLS connections with the backend service using custom CA certificates. New and improved VNet injection Using VNet injection in Premium v2 no longer requires configuring routes or service endpoints. Customers can secure their API workloads without impacting API Management dependencies, while Microsoft can secure the infrastructure without interfering with customer API workloads. In short, the new VNet injection implementation enables both parties to manage network security and configuration settings independently and without affecting each other. You can now configure your APIs with complete networking flexibility: force tunnel all outbound traffic to on-premises, send all outbound traffic through an NVA, or add a WAF device to monitor all inbound traffic to your API Management Premium v2—all without constraints. Inbound Private Link Customers can now configure an inbound private endpoint for their API Management Premium v2 instance to allow your API consumers securely access the API Management gateway over Azure Private Link. The private endpoint uses an IP address from an Azure virtual network in which it's hosted. Network traffic between a client on your private network and API Management traverses over the virtual network and a Private Link on the Microsoft backbone network, eliminating exposure from the public internet. Further, you can configure custom DNS settings or an Azure DNS private zone to map the API Management hostname to the endpoint's private IP address. With a private endpoint and Private Link, you can: Create multiple Private Link connections to an API Management instance. Use the private endpoint to send inbound traffic on a secure connection. Apply different API Management policies based on whether traffic comes from the private endpoint. Limit incoming traffic only to private endpoints, preventing data exfiltration. Combine with inbound virtual network injection or outbound virtual network integration to provide end-to-end network isolation of your API Management clients and backend services. More details can be found here Today, only the API Management instance’s Gateway endpoint supports inbound private link connections. Each API management instance can support at most 100 Private Link connections. Availability zones Azure API Management Premium v2 now supports Availability Zones (AZ) redundancy to enhance the reliability and resilience of your API gateway. When deploying an API Management instance in an AZ-enabled region, users can choose to enable zone redundancy. This distributes the service's units, including Gateway, management plane, and developer portal, across multiple, physically separate AZs within that region. Learn how to enable AZs here. CA certificates If the API Management Gateway needs to connect to the backends secured with TLS certificates issued by private certificate authorities (CA), you need to configure custom CA certificates in the API Management instance. Custom CA certificates can be added and managed as Authorization Credentials in the Backend entities. The Backend entity has been extended with new properties allowing customers to specify a list of certificate thumbprints or subject name + issuer thumbprint pairs that Gateway should trust when establishing TLS connection with associated backend endpoint. More details can be found here. Region availability The Premium v2 tier is now generally available in six public regions (Australia East, East US2, Germany West Central, Korea Central, Norway East and UK South) with additional regions coming soon. For pricing information and regional availability, please visit the API Management pricing page. Learn more API Management v2 tiers FAQ API Management v2 tiers documentation API Management overview documentationGive your Copilot agents real tools, without hand-wiring MCP
You’re running agents in the GitHub Copilot app - maybe three at once, each on its own branch, each working a task while you steer. It’s a good way to work, right up until an agent needs to reach outside your repo. It needs to read a SharePoint library, file a Salesforce record, or check an Outlook calendar, and suddenly it’s blind. An agent is only as capable as the tools you hand it. The usual way to hand it one of those tools is to wire up a Model Context Protocol (MCP) server by hand: find the endpoint, paste it into config, add an auth header, keep the token alive, and hope you got the casing right. Then your teammate does the same thing on their machine, and the next person after that. The MCP Connectors canvas removes the hand-wiring. It’s a plugin for the GitHub Copilot app: it lists the hosted MCP servers already published in your Azure Connector Namespace, and you connect one to Copilot by selecting it - no URL, no header, no local proxy. Where the servers come from Connector Namespace is the managed Azure service on the other end. It provides a list of curated MCP Servers that you can use to quickly create and manage MCPs connections. It also does the work you’d rather not: it stores and rotates the credentials, applies retry and throttling policies, and scales the server. Your machine never holds a raw secret related to the end systems that MCP touches, and access is governed by access policies, allowing fine grained control on who can use the MCP servers. So, when you connect a server from the canvas, you’re not standing up infrastructure. The server already exists, already authenticated, already managed. You’re pointing Copilot at it. Prerequisites GitHub Copilot app with canvas extension support. An Azure subscription with permission to cerate and view the namespace and to create connections and hosted managed MCP server configurations. Connector Namespace is in preview, and availability varies by region. Install From the GitHub Copilot app, add the following prompt. Install connector-namespaces v1.2.0 for my user account, reload it, verify it is running, then open the MCP Connectors canvas. Open the Connector Namespace canvas in a new session Once you install if you need to open the Connector Namespace in a new session, just request it in a prompt: Open the MCP Connectors canvas. Connect an MCP server Open the MCP Connectors canvas. Select Sign in to Azure, then choose a subscription and Connector Namespace. Browse or search the MCP servers grouped under Microsoft and Partners. Select Connect and complete the connector’s separate authentication or consent flow. Confirm the server appears under My MCPs. Restart GitHub Copilot so a new session loads the added tools. ℹ️Note That last step matters more than it look. Copilot loads an agent’s tools when a session starts, so a server you add mid-session shows up in the next one, not the one you’re in. Manage connected servers My MCPs shows the servers connected to Copilot. Sandbox opens a connected server in the Connector Namespace playground, so you can try a tool call yourself before you let an agent lean on it. Disconnect removes the MCP registration from your MCP configuration. The MCP is still available in Connector namespace to be added again later. Also if you are sharing the connector namespace with other developers, this only remove the your local configuration. Connect adds configured MCP connectors that are not registered locally yet to your local MCP configuration. Delete from namespace… removes the MCP registration from your MCP configuration and deletes the MCP connection from your connector namespace. If you are sharing the connector namespace with other developers this will affect any developer using this MCP connector – be careful when using this. Switch namespace switches the active subscription or namespace - useful when you keep dev and production connections apart. How it works and security The extension registers each server directly in Copilot’s user-scoped MCP configuration. There’s no local MCP proxy sitting in the tool path between the agent and the server. The canvas itself runs on loopback. Your Azure tokens stay in process memory, the selected namespace coordinates may be cached locally, and gateway credentials are sent only to the server’s configured HTTPS endpoints. The connector’s own secrets never reach your machine. That’s the namespace’s job, which is also why an admin can rotate or revoke a connection in one place instead of chasing down every developer’s config. Where can I use my connected MCP servers You manage the servers from the canvas, but they don’t only work there. The canvas writes to Copilot’s user-scoped MCP configuration at ~/.copilot/mcp-config.json, and the GitHub Copilot app is built on GitHub Copilot CLI. Connect a server once and it’s available to both. Agent sessions in the app. Any session on your machine picks the server up, whatever repository or branch it’s working on, because the config is user-scoped rather than per-project. Copilot CLI. The same server shows up in the terminal. Run copilot mcp list to confirm it, or /mcp show SERVER-NAME in an interactive session to see the tools it exposes. Two things to know: Tools load when a session starts, so connect first and start the session second. A project-level .mcp.json or .github/mcp.json takes precedence over your user config when the names collide, which is what you want if a repository pins its own version of a server. VS Code is the exception. Copilot Chat there reads .vscode/mcp.json, a separate file the CLI doesn’t use, so a server you connect in the canvas won’t appear in VS Code until you configure it there too. Where this all sits today The GitHub Copilot app went generally available in June 2026, and canvases shipped with it, so neither is a preview feature. The MCP Connectors canvas is a published extension you install at personal scope. You get the version we ship and tested, not one an agent generates on the fly from a prompt. Two caveats. GitHub doesn't publish a compatibility guarantee for the canvas extension format, so an app update may need a matching update from us. Re-run the install commands above to pick it up if you see any issues. On the Azure side, Connector Namespace is still in preview. Check the documentation for more details on this service outside the GitHub Copilot App support. If you're on Copilot Business or Enterprise, check with your admin that the GitHub Copilot app policy is enabled. It's on by default, and it's separate from the Copilot CLI policy. Try it Install the plugin, point it at a namespace, and connect one server your agents keep reaching for: the SharePoint library, the CRM, whatever it is. Then watch an agent actually use it in the next session. Tell me where the canvas saved you a config headache and where it got in your way. That’s the feedback we act on before general availability.914Views2likes2CommentsSet Up Plaud Note Pro with Microsoft Foundry
Prerequisites Riffado, up and running: follow the setup guide in the official Riffado repository to get it going with Docker Compose. A Microsoft Foundry (formerly Azure AI Foundry) resource, with the models you want deployed; in my case, whisper for transcription and o3-mini for summaries. A Plaud device, or any audio recordings you can import into Riffado. Once Riffado is up, head to the Settings page > Providers > Add Provider, and select Custom. This is where the Azure details will go. Why "OpenAI-compatible" isn’t one thing on Microsoft Foundry Azure AI Foundry exposes two different API surfaces on the same resource, and which one serves your model depends on the model: Surface Path shape Serves OpenAI-compatible? v1 route /openai/v1/… gpt-4o-transcribe, gpt-4o-mini-transcribe, chat models, embeddings Yes: Bearer auth, model in the body, no api-version needed Classic route /openai/deployments/{name}/… Whisper (and other legacy audio) No: deployment name lives in the URL, and ?api-version= is mandatory A generic OpenAI client (Riffado's included) can only speak the first dialect. It has nowhere to put a deployment name in the path and no way to append a query parameter. That single fact drives everything below. Part 1 - Transcription Whisper and the DeploymentNotFound mystery Symptom My very first transcription attempt in Riffado failed with 404 Resource not found. Off to a flying start. Configured provider: base URL https://<resource>.services.ai.azure.com, model whisper. Dead end #1: the missing path The first bug was mine: the base URL had no path. Riffado's OpenAI client appends /audio/transcriptions to whatever you give it, so requests were hitting https://<resource>…/audio/transcriptions, a path that doesn't exist on the resource at all. Fixing the base URL to end in /openai/v1 got us to a more interesting error: POST /openai/v1/audio/transcriptions · model=whisper {"error":{"code":"DeploymentNotFound","message":"The API deployment for this resource does not exist. If you created the deployment within the last 5 minutes, please wait a moment and try again."}} Dead end #2: catalog ≠ deployment Worth checking before anything else: selecting a model in the Foundry catalog is not deploying it. GET /openai/v1/models lists everything you could deploy; only Deployments → Deploy model creates an endpoint that answers. If you get DeploymentNotFound, first confirm a deployment actually exists (the listing below requires only the API key): enumerate real deployments (classic control-plane, key auth) curl -s -H "api-key: $KEY" \ "https://<resource>.openai.azure.com/openai/deployments?api-version=2023-03-15-preview" # → {"data":[{"id":"whisper","model":"whisper","status":"succeeded",…}]} The actual cause Here is the part that nearly drove me mad: the deployment existed and was succeeded, yet the v1 route still said DeploymentNotFound. Because Whisper deployments are not served on the v1 route at all. They only answer on the classic path. Verified side by side with the same tiny WAV file: Request Result POST /openai/v1/audio/transcriptions · model=whisper · Bearer 404 DeploymentNotFound POST /openai/deployments/whisper/audio/transcriptions?api-version=2024-06-01 · Bearer 200 {"text":"you"} Same classic path, without ?api-version= 404 Resource not found Three constraints, then: Whisper needs the classic path; the classic path needs api-version; Riffado can send neither. One piece of good news hiding in the table: the classic route accepts Authorization: Bearer, not just Azure's api-key header, so the shim doesn't have to touch auth at all. The fix: a Caddy shim Drop a stock caddy:2-alpine container into the Compose network. Riffado points at it as if it were OpenAI; the shim rewrites the path, injects api-version, and proxies to Azure. The Bearer header passes through untouched. azure-shim.Caddyfile { admin off auto_https off } :80 { @transcribe path /v1/audio/transcriptions /audio/transcriptions handle @transcribe { rewrite * /openai/deployments/whisper/audio/transcriptions?api-version=2024-06-01 reverse_proxy https://<resource>.services.ai.azure.com { header_up Host <resource>.services.ai.azure.com } } handle { respond "azure-shim ok" 200 } } docker-compose.yml (added service) azure-shim: image: caddy:2-alpine restart: unless-stopped volumes: - ./azure-shim.Caddyfile:/etc/caddy/Caddyfile:ro Riffado's provider settings become: Field Value Base URL http://azure-shim/v1 Model whisper (must equal the deployment name) API key the Azure resource key (forwarded as Bearer) Verified From inside the Riffado container: POST http://azure-shim/v1/audio/transcriptions → 200 {"text":"…"}. Transcription works end-to-end in the UI. Part 2 · Summaries & titles o3-mini and the empty answer Symptom The summary button showed "An unexpected error occurred." The container logs were more honest: riffado-app logs Error generating title: TypeError: undefined is not an object (evaluating 'C.choices[0]') Riffado calls chat/completions and reads choices[0] without checking whether the response was an error. So anything the API refuses becomes "an unexpected error." What was it refusing? Cause 1: reasoning models reject the classic knobs o3-mini belongs to Azure/OpenAI's o-series reasoning models, which hard-reject parameters every classic chat client sends. Riffado sends temperature: 0.7 and max_tokens: 50 for titles (0.5 / 2000 for summaries), and o3-mini answers: POST /openai/v1/chat/completions · model=o3-mini HTTP 400 {"error":{"message":"Unsupported parameter: 'max_tokens' is not supported with this model. Use 'max_completion_tokens' instead.", …}} # and with max_tokens fixed: HTTP 400 {"error":{"message":"Unsupported parameter: 'temperature' is not supported with this model.", …}} Cause 2: reasoning tokens starve the output Stripping the bad params gets you to 200, and then comes a subtler failure, my personal favourite of this whole saga. Reasoning models spend completion tokens on internal "thinking" before emitting a single visible character. Riffado's 50-token title budget is consumed entirely by reasoning, and the reply comes back syntactically valid and empty: max_completion_tokens reasoning_effort finish_reason content 50 not set length "" (all 50 spent reasoning) 2000 not set stop "Q3 Budget Planning Strategy Meeting" 2000 low stop same, less reasoning overhead The fix: a Node shim that rewrites the request body Caddy can rewrite paths but not JSON bodies, so this shim is ~60 lines of dependency-free Node on node:20-alpine. Per request it: converts max_tokens → max_completion_tokens, strips temperature / top_p / penalties, floors the token budget at 4000, sets reasoning_effort: "low", maps /v1/* → /openai/v1/*, and forwards to the Azure resource. o3-shim.js const http = require('http'); const https = require('https'); const UPSTREAM_HOST = '<resource>.services.ai.azure.com'; // Params o-series reasoning models reject on chat/completions. const STRIP = ['temperature','top_p','presence_penalty', 'frequency_penalty','logprobs','top_logprobs']; const server = http.createServer((req, res) => { const chunks = []; req.on('data', c => chunks.push(c)); req.on('end', () => { let body = Buffer.concat(chunks); // Riffado's base_url is http://o3-shim/v1 → map to Azure's /openai/v1 let path = req.url; if (path.startsWith('/v1/')) path = '/openai' + path; const ct = (req.headers['content-type'] || '').toLowerCase(); if (ct.includes('application/json') && body.length) { try { const j = JSON.parse(body.toString('utf8')); if (j && typeof j === 'object' && !Array.isArray(j)) { if ('max_tokens' in j) { if (!('max_completion_tokens' in j)) j.max_completion_tokens = j.max_tokens; delete j.max_tokens; } // Reasoning spends tokens before any visible output; small // budgets (Riffado sends 50 for titles) return empty strings. if (Array.isArray(j.messages)) { j.max_completion_tokens = Math.max(Number(j.max_completion_tokens) || 0, 4000); if (!('reasoning_effort' in j)) j.reasoning_effort = 'low'; } for (const k of STRIP) delete j[k]; body = Buffer.from(JSON.stringify(j)); } } catch (_) { /* not JSON - forward untouched */ } } const headers = { ...req.headers, host: UPSTREAM_HOST, 'content-length': Buffer.byteLength(body) }; const up = https.request( { host: UPSTREAM_HOST, port: 443, method: req.method, path, headers }, upRes => { res.writeHead(upRes.statusCode, upRes.headers); upRes.pipe(res); } ); up.on('error', e => { res.writeHead(502, {'content-type':'application/json'}); res.end(JSON.stringify({error:{message:'o3-shim upstream error: '+e.message}})); }); up.end(body); }); }); server.listen(80, () => console.log('o3-shim listening on :80')); docker-compose.yml (added service) o3-shim: image: node:20-alpine restart: unless-stopped working_dir: /app command: ["node", "/app/o3-shim.js"] volumes: - ./o3-shim.js:/app/o3-shim.js:ro Add a second provider in Riffado (base URL http://o3-shim/v1, model o3-mini, the resource's API key) and set it as the default enhancement provider (summaries/titles), keeping the Whisper one as default for transcription. Riffado's exact title request (temperature: 0.7, max_tokens: 50) through the shim → 200, finish_reason: stop, real title text. A full meeting-transcript summary returns structured key points and action items. The final shape Reading it left to right: Riffado never talks to Azure directly. Transcription requests pass through azure-shim, a stock Caddy container that rewrites each request onto Whisper's classic deployment path and injects the mandatory api-version parameter. Summary and title requests pass through o3-shim, a tiny Node server that rewrites the request body into the shape o3-mini accepts and floors the token budget so the model's internal reasoning cannot starve the actual answer. As far as Riffado is concerned, it is simply talking to two ordinary OpenAI providers. Both shims live on the Compose network only; nothing is exposed publicly. Riffado is unmodified. Verification checklist Each layer, testable in isolation. Run these before blaming the app: smoke tests # 1. Key + resource alive? (v1 models listing, Bearer auth) curl -s -H "Authorization: Bearer $KEY" \ https://<resource>.services.ai.azure.com/openai/v1/models | head -c 200 # 2. Whisper answers on the classic path? curl -s -H "Authorization: Bearer $KEY" -F file=@test.wav \ "https://<resource>.services.ai.azure.com/openai/deployments/whisper/audio/transcriptions?api-version=2024-06-01" # 3. Shim translates correctly? (from inside the compose network) docker exec riffado-app node -e "fetch('http://azure-shim/') .then(r=>r.text()).then(console.log)" # 4. o3-mini via shim, sending the params Riffado sends? # (temperature + max_tokens:50; the shim must absorb both) If you'd rather not run shims Both shims exist because of the specific models chosen. Pick models that live natively on the v1 route and Riffado connects directly, with base URL https://<resource>.services.ai.azure.com/openai/v1 and zero extra containers: Transcription: deploy gpt-4o-mini-transcribe (or gpt-4o-transcribe) instead of Whisper. Summaries: deploy a non-reasoning chat model such as gpt-4o-mini, which happily accepts temperature and max_tokens. The shim approach earns its keep when you're standardized on specific models (Whisper's transcription quality, o3-mini's reasoning), or when you want a control point to add logging, retries, or budget caps later. For reference, this is what the finished setup looks like on Riffado's side. Each shim is registered as a plain Custom provider. Here is the whisper provider pointing at azure-shim, with Use for transcription ticked: And once both are saved, they sit side by side in the providers list, whisper tagged for transcription and o3-mini tagged for enhancement: A quick look at the Foundry portal In the Microsoft Foundry portal, head over to Models > AI Services and you will find a pleasant surprise: fifteen AI service models already deployed and ready to use, covering the Azure Speech family (including Voice Live and Speech to Text), Azure Translator, Azure Language, and Content Understanding: You can of course deploy another model for this, but the pre-deployed ones are a handy cost-saving option. Click on the Azure Speech – Voice Live radio button and you will be shown the Base URL and API Key, which you can then paste into the provider settings on Riffado's Settings page. A quick note on cost: these services are not free. They are billed pay-as-you-go based on usage. Azure Speech transcription is charged per audio hour, and Voice Live pricing is tiered by the model you choose. The free tier does include a monthly allowance, though. Check the Azure Speech pricing page before committing. And if you would rather deploy a dedicated transcription model such as whisper, Foundry gives you the flexibility to do just that. Open the model page in the catalogue, click Deploy, and go with Default settings unless you need custom quotas or guardrails: Let's test the setup On your Plaud device, just tap to start recording. The little LED bars light up to show it is listening: Or skip the device entirely and upload an audio file straight into Riffado using the Upload Audio button. Either way, the recording lands on the Recordings page; hit Transcribe and let the spinner do its thing: As you can see below, whisper, the transcription model we deployed earlier, even managed to transcribe a recording in Malay without a hitch. My 3:32 test clip came back as 186 words of clean Malay, with the language correctly detected and tagged: I have also set o3-mini as the enhancement provider, and it enhanced the transcription with a proper summary, key points, and title as well! The Meeting Notes-style summary came straight out of o3-mini through the shim, with zero manual prompting. Wrapping up What started as a TikTok-fuelled impulse buy nearly killed off by subscription pricing ended up as a fully self-hosted pipeline: Plaud for recording, Riffado as the interface, and Microsoft Foundry serving whisper and o3-mini behind two tiny shims. The total extra infrastructure came to two containers and roughly sixty lines of code, and not a single monthly subscription in sight. If you try this setup and run into a failure mode I have not covered here, do share it in the comments. Half the fun is in the debugging.404Views0likes0CommentsMicrosoft Agent Framework Multi-Agent Workflow Architecture for Automated Kubernetes Assessments
Why this system generates tests (design rationale) This project does not generate tests just to "check code." It generates tests because, in a Kubernetes learning game, the test suite is the grading contract. The design goals are: Scale content creation: instructors should not hand-author every task and checker. Keep grading objective: student success is measured against Kubernetes API state, not subjective review. Avoid fragile tasks: generated tasks must survive empty/wrong cluster states without crashing. Make failures repairable: when checks break, the system should patch and re-validate automatically. So the pipeline generates a full task package (setup, answer, check, cleanup) where tests define exactly what "correct" means. Lifecycle: from concept to production-ready grader Reader mental model: this is a content compiler with validation stages, not a single chat completion. Phase 1: Pedagogical intent -> structured concept The Idea Agent converts a topic into a constrained concept object (objective, progression, task IDs, difficulty variants). Memory rules block duplicates and previously failed concepts. Phase 2: Concept -> executable grading package The Generator Agent turns that concept into files: student instructions (instruction.md) learning material (concept.md) parameter source (session.json) setup and answer manifests (setup.template.yaml, answer.template.yaml) deterministic pytest flow (test_01 ... test_06) At this point, output is still untrusted draft content. Phase 3: Structural correctness gate Deterministic validation checks file presence, syntax, JSON/YAML shape, and template correctness. This catches basic integrity issues before cluster execution. Phase 4: Behavioral correctness gate (real cluster) Pytest executes against Kubernetes and verifies runtime behavior using real kubectl-derived state. This proves that generated checks actually evaluate cluster resources as intended. Phase 5: Anti-false-positive gate (skip-answer mode) The same suite runs with SKIP_ANSWER_TESTS=True to verify grader integrity: answer deployment is skipped test_05_check.py must fail If it still passes, the grader is invalid (it would accept wrong student submissions). Phase 6: Self-healing repair loop On any failure, deterministic error logs are fed into the Fixer Agent, which patches only broken files. The workflow then re-enters validation + test gates. Phase 7: Finalization If all gates pass -> task is kept as production-ready content. If retries are exhausted -> task is moved to unsuccessful/ with FAILURE_REPORT.txt for human triage. This lifecycle explains the core architecture decision: LLMs generate candidate graders, deterministic execution certifies them. Concrete generated sample (what the pipeline actually produces) Below is a representative generated task for topic: ConfigMap Environment Variable Injection. Generated directory layout tests/game01/050_configmap_env_injection/ ├── __init__.py ├── instruction.md ├── concept.md ├── session.json ├── setup.template.yaml ├── answer.template.yaml ├── test_01_setup.py ├── test_02_ready.py ├── test_03_answer.py ├── test_05_check.py └── test_06_cleanup.py session.json (runtime variables) { "namespace": "{{random_name()}}{{random_number(100,999)}}{{student_id()}}", "configmap_name": "{{random_name()}}", "deployment_name": "{{random_name()}}", "container_name": "app", "env_key": "APP_MODE", "env_value": "production" } Why this exists: task values are randomized per student/session, so tests verify behavior by variable contract instead of hardcoded names. setup.template.yaml (baseline state only) apiVersion: v1 kind: Namespace metadata: name: {{ namespace }} Why this exists: setup should create prerequisites only. It must not accidentally include the final answer. answer.template.yaml (expected correct solution) apiVersion: v1 kind: ConfigMap metadata: name: {{ configmap_name }} namespace: {{ namespace }} data: {{ env_key }}: "{{ env_value }}" --- apiVersion: apps/v1 kind: Deployment metadata: name: {{ deployment_name }} namespace: {{ namespace }} spec: replicas: 1 selector: matchLabels: app: env-demo template: metadata: labels: app: env-demo spec: containers: - name: {{ container_name }} image: nginx:latest env: - name: {{ env_key }} valueFrom: configMapKeyRef: name: {{ configmap_name }} key: {{ env_key }} Why this exists: defines canonical "correct cluster state" that graders must detect. test_02_ready.py (wait for setup resources) import json import time from tests.helper.kubectrl_helper import build_kube_config, run_kubectl_command class TestReady: def test_001_namespace_active(self, json_input): kube_config = build_kube_config( json_input["cert_file"], json_input["key_file"], json_input["host"] ) time.sleep(2) result = run_kubectl_command( kube_config, f"kubectl get namespace {json_input['namespace']} -o json", ) data = json.loads(result) assert data.get("status", {}).get("phase") == "Active" Why this matters: validates setup-stage readiness only. It should not check answer resources yet. test_05_check.py (student grading contract) import json from tests.helper.kubectrl_helper import build_kube_config, run_kubectl_command class TestCheck: def test_001_configmap_key_exists(self, json_input): kube_config = build_kube_config( json_input["cert_file"], json_input["key_file"], json_input["host"] ) result = run_kubectl_command( kube_config, f"kubectl get configmap {json_input['configmap_name']} -n {json_input['namespace']} -o json", ) data = json.loads(result) assert data["data"][json_input["env_key"]] == json_input["env_value"] def test_002_deployment_uses_configmap_env(self, json_input): kube_config = build_kube_config( json_input["cert_file"], json_input["key_file"], json_input["host"] ) result = run_kubectl_command( kube_config, f"kubectl get deployment {json_input['deployment_name']} -n {json_input['namespace']} -o json", ) data = json.loads(result) env = data["spec"]["template"]["spec"]["containers"][0].get("env", []) matched = [ e for e in env if e.get("name") == json_input["env_key"] and e.get("valueFrom", {}).get("configMapKeyRef", {}).get("name") == json_input["configmap_name"] and e.get("valueFrom", {}).get("configMapKeyRef", {}).get("key") == json_input["env_key"] ] assert matched, "Deployment container must consume env var from ConfigMap key" Why this matters: this is the real grading logic. If a student deploys wrong resource wiring, this test fails with explicit reason. Why skip-answer validation is essential for this sample When SKIP_ANSWER_TESTS=True, answer deployment is skipped. In this mode: test_03_answer.py should be skipped test_05_check.py must fail (ConfigMap/Deployment wiring is absent) If test_05_check.py still passes, the grader is broken (false positive), and the workflow routes to Fixer. Rule Builder Workflow Flowchart Multi-graph architecture views 1) Control-plane graph (orchestration DAG) 2) Runtime sequence (who calls what) 3) State machine (task lifecycle) 4) Prompt lifecycle graph (how prompts evolve) 5) MCP + Kubernetes execution boundary graph Core Agent Framework Primitives Used This repository is a practical example of Agent Framework as a graph orchestrator, not just an agent wrapper. WorkflowBuilder builds a typed DAG with explicit edges. @executor functions implement deterministic nodes (validation, pytest, decisions, routing prep). AgentExecutor wraps LLM agents so they behave as graph nodes. WorkflowContext shared state carries typed data and retry metadata between nodes. add_multi_selection_edge_group(...) + selector functions enforce conditional routing. MCPStdioTool connects filesystem MCP tools into agents for controlled file I/O. Production graph construction (from workflow/builder.py) looks like this: workflow = ( WorkflowBuilder(start_executor=initialize_retry) .add_edge(initialize_retry, generator_executor) .add_edge(generator_executor, parse_generated_task) .add_edge(parse_generated_task, run_validation) .add_edge(run_validation, run_pytest) .add_edge(run_pytest, make_decision) .add_multi_selection_edge_group( make_decision, [keep_task, remove_task], selection_func=select_action, ) .add_edge(keep_task, run_pytest_skip_answer) .add_multi_selection_edge_group( run_pytest_skip_answer, [check_loop, complete_workflow], selection_func=select_skip_answer_action, ) .add_multi_selection_edge_group( check_loop, [fix_task, complete_workflow], selection_func=select_loop_action, ) .add_edge(fix_task, fixer_executor) .add_edge(fixer_executor, parse_generated_task) .build() ) This is the architectural heart of the system: agents and deterministic executors are first-class nodes in the same graph. Detailed Node-by-Node Mechanics 1. Idea Agent (🧠): Concept Synthesis with Memory Constraints The Idea Agent (agents/k8s_task_idea_agent.py) generates a structured concept with three difficulty variations (BEGINNER/INTERMEDIATE/ADVANCED). It is memory-aware: task_ideas_memory.json tracks successful concepts. task_ideas_failure_memory.json tracks concepts that failed downstream. Memory constraints are injected using AgentMiddleware (system-level prompt injection) to avoid duplicate or previously failed concepts. For Responses-only models, the agent switches to a tool-call contract (save_k8s_task_concept) instead of structured response formatting. 2. Generator Agent (⚙️): MCP-Backed File Authoring The Generator Agent receives a strict prompt and writes task files through MCP filesystem tools. Key framework details: Built through chat_client.as_agent(...). MCP tool attached via tools=mcp_tool. Function-call execution observability added with LoggingFunctionMiddleware. Uses absolute-path-only policy in instructions to prevent path drift. 3. Deterministic Validation + Test (✅): Non-LLM Gates After generation, the graph moves through deterministic executors: run_validation calls pure Python checks (k8s_task_validator). run_pytest executes pytest --import-mode=importlib --rootdir=. .... Raw pytest output is persisted in workflow state for later fixing. This is critical: no LLM is asked whether code is correct. 4. Skip-Answer Test (🧪): Grader Correctness Gate Even if standard tests pass, the workflow enforces a second tier: SKIP_ANSWER_TESTS=True pytest --import-mode=importlib --rootdir=. Implementation detail: the executor writes JUnit XML, parses it, and asserts that: test_03_answer.py is skipped test_05_check.py fails as expected If test_05_check.py does not fail, the task is treated as invalid and sent back to retry/fix. 5. Fixer Agent + Retry Loop (🔧): Bounded Self-Healing On failure, fix_task builds a targeted prompt containing: failure reasons from deterministic nodes full captured pytest output explicit rule to patch only broken files in place The Fixer Agent runs through AgentExecutor, writes patches via MCP, and the graph loops back to parse_generated_task. Retries are stateful (retry_count, max_retries) and hard-bounded. On exhaustion, complete_workflow moves the task to unsuccessful/<game>/ and writes FAILURE_REPORT.txt. Agent Prompt Design (The Part That Makes It Work) If you want to understand why this pipeline works, you need to inspect prompts as operational contracts, not generic instructions. Real Idea Agent Prompt (from code) IDEA_AGENT_INSTRUCTIONS = ( "You are a Kubernetes task idea generator that creates detailed task concepts with three difficulty variations. " "Read official K8s documentation and propose comprehensive learning concepts for a Kubernetes game. " "\n\nYour task:\n" "1. Choose ONE Kubernetes concept not yet covered (check context for existing concepts)\n" "2. Generate exactly 3 variations: BEGINNER, INTERMEDIATE, and ADVANCED\n" "3. Use 3-digit task IDs (001-999) in format: XXX_concept_name_level (e.g., 041_secrets_basic)\n" "4. Each variation should build on the previous one with increasing complexity\n" "5. Include practical, hands-on scenarios covering: Workloads, Services, Storage, Configuration, Security, Scheduling, Policies\n" "\nProvide the concept, tags, description, and 3 variations with task_id, difficulty, title, objective, key_skills, and estimated_time." ) Responses-only models use a stricter tool-call version: IDEA_AGENT_INSTRUCTIONS_TOOL_CALL = ( IDEA_AGENT_INSTRUCTIONS + "\n\n" "**CRITICAL**: You MUST call the save_k8s_task_concept tool to save your generated concept.\n" "...\n" "Always call save_k8s_task_concept with your generated concept." ) Idea Agent Prompt Contract The Idea Agent prompt enforces: one concept per run exactly three difficulty variations strict task ID format (XXX_concept_name_level) practical skill progression Core pattern: You are a Kubernetes task idea generator... 1. Choose ONE Kubernetes concept not yet covered 2. Generate exactly 3 variations: BEGINNER, INTERMEDIATE, ADVANCED 3. Use 3-digit task IDs in format XXX_concept_name_level ... It is strengthened by runtime memory injection: previously generated concepts are blocked previously failed concepts are blocked For Responses-only models, the contract becomes tool-driven: CRITICAL: You MUST call the save_k8s_task_concept tool... This reduces ambiguity in output structure and makes downstream parsing deterministic. Real Generator Agent Prompt (from code) def _get_generator_instructions(): return ( "You are a Kubernetes task generator with filesystem tools.\n" f"The MCP filesystem is rooted at: {PATHS.tests_root.parent}\n" f"You MUST use ABSOLUTE paths for ALL file operations.\n" f"Task directory: {PATHS.game_root}/XXX_task_name/\n" "...\n" "CRITICAL: test_02_ready.py checks resources from setup.template.yaml, NOT answer.template.yaml.\n" "...\n" "MUST use polling loops (60s timeout, 15s interval)\n" "MUST use try/except and safe .get() JSON access\n" ) The generator prompt is long on purpose: it encodes path correctness, file schema, YAML/Jinja structure, and testing strategy in a single deterministic contract. Generator Agent Prompt Contract The Generator prompt is intentionally long and prescriptive because it defines filesystem safety and grading correctness requirements. Key constraints encoded in the prompt: Absolute path writes only (prevents writing to wrong workspace paths) No directory creation (directory is pre-created by executor) Required file set (instruction.md, concept.md, session.json, templates, tests) test-flow invariants: test_01_setup.py deploys setup test_02_ready.py checks setup resources only test_03_answer.py deploys answer test_05_check.py validates final solution robust test coding style: polling loops, try/except, .get()-based JSON parsing, explicit debug output Example contract fragment: CRITICAL PATH RULES: ✅ CORRECT: /abs/path/tests/gameXX/050_task/file.py ❌ WRONG: tests/gameXX/050_task/file.py (relative) CRITICAL: test_02_ready.py checks resources from setup.template.yaml, NOT answer.template.yaml. This is why generation quality is high before the Fixer loop even starts. Real Runtime Retry Prompt Builder (from code) def _build_retry_generation_prompt(combined: CombinedValidationResult) -> str: task_id = combined.test.task_id failure_reasons = _build_failure_reasons(combined) return ( f"Generate a complete Kubernetes learning task with ID '{task_id}' about '{combined.target_topic}'. " f"This is retry attempt {combined.retry_count + 1} of {combined.max_retries}. " f"\n\n⚠️ PREVIOUS ATTEMPT FAILED:" f"\n{chr(10).join([f' - {reason}' for reason in failure_reasons])}" f"\n\nIMPORTANT: You MUST use the exact task ID '{task_id}' - do not generate a new ID." f"\n\n✅ Directory already exists: {PATHS.game_root}/{task_id}/" f"\nWrite all files directly into this directory. Do NOT call create_directory." "..." ) This means retries are not generic retries; they are failure-conditioned retries with precise constraints. Fixer Agent Prompt Contract The Fixer prompt is a repair protocol, not a regeneration prompt. It includes: exact failure reasons from deterministic validators raw pytest output instruction to read current task files first strict directive to patch only broken files Core behavior constraints: DO NOT rewrite all files. Make TARGETED FIXES to ONLY the broken files. Use ABSOLUTE paths for all file operations. This keeps retries cheap, preserves working artifacts, and improves convergence speed. Real Runtime Fix Prompt Builder (from code) def _build_fix_prompt(combined: CombinedValidationResult, raw_test_output: str) -> str: task_id = combined.test.task_id failure_reasons = _build_failure_reasons(combined) prompt = ( f"Fix the failed Kubernetes task '{task_id}' located in '{PATHS.game_root}/{task_id}/'." f"\n\nThis is fix attempt {combined.retry_count + 1} of {combined.max_retries}." f"\n\n⚠️ TASK FAILED WITH THESE ERRORS:" f"\n{chr(10).join([f' - {reason}' for reason in failure_reasons])}" ) if raw_test_output: prompt += f"\n\n📋 FULL TEST OUTPUT:\n```\n{raw_test_output}\n```" prompt += ( f"\n\n🔍 YOUR TASK:" f"\n1. READ all files from '{PATHS.game_root}/{task_id}/'" f"\n6. Make TARGETED FIXES to ONLY the broken files" f"\n7. WRITE ONLY the fixed files back" f"\n\n⚠️ CRITICAL: DO NOT rewrite all files! Only fix the broken ones!" ) return prompt How Prompt Output Enters the Agent Framework Graph The prompt builders above are used by deterministic executors and sent to agent nodes through AgentExecutorRequest: await ctx.send_message( AgentExecutorRequest( messages=[Message(role="user", contents=[fix_prompt])], should_respond=True ) ) So prompt generation and graph routing are tightly coupled: each route transition emits a specific prompt payload into the next LLM node. Runtime-Constructed Prompts in Executors The most important prompts are built dynamically in workflow executors: _build_retry_generation_prompt(...) _build_fix_prompt(...) These functions inject live context: retry_count / max_retries concept + objective metadata validation/test failure reasons full captured test logs So each retry is context-rich and specific, not another blind generation attempt. Prompt + Middleware + Deterministic Gates = Reliability In this repository, reliability does not come from prompt text alone. It comes from three layers working together: Prompt contracts constrain agent behavior. Middleware injects memory and logs tool invocations. Deterministic executors enforce objective pass/fail gates. That combination is why the workflow remains auditable and predictable even when LLM outputs vary. Agent Framework Execution Model in This Repo Strongly-Typed Message Passing workflow/models.py defines transport models used between nodes: ValidationResult and TestResult (Pydantic) CombinedValidationResult (dataclass with should_keep and should_retry) InitialWorkflowState (seed payload for each run) This keeps node contracts explicit and simplifies selector logic. Fail-Fast Shared State Management Executors use ctx.get_state(...) with a sentinel (_MISSING) and raise explicit exceptions if required state is absent. This prevents hidden fallback behavior and catches graph/data wiring errors early. Conditional Routing with Selectors Selectors (workflow/selectors.py) encode graph decisions: select_action → keep vs remove select_skip_answer_action → complete vs loop select_loop_action → fix vs complete This separates decision policy from executor implementation. Streaming Workflow Runtime workflow.run(initial_state, stream=True) emits output events incrementally. The runner (workflow/runner.py) consumes these events to detect successful completions and update concept memory accordingly. Agent Construction and API Selection Strategy The repository uses Azure CLI auth (AzureCliCredential) and dynamically selects API mode by deployment name (agents/config.py): Chat Completions path: OpenAIChatCompletionClient Responses-only model path: OpenAIChatClient or custom ResponsesAgent Why this matters: some codex-class deployments are Responses-only, so the architecture supports both without changing workflow logic. How MCP Actually Controls Kubernetes (Important Distinction) In this repo, MCP is used for filesystem control; Kubernetes control is done through kubectl tools. 1) MCP server role: controlled file I/O The workflow starts MCP stdio servers (official filesystem server) and mounts them into agents: docs_mcp_tool = MCPStdioTool( name="filesystem_docs", command="npx", args=["-y", "@modelcontextprotocol/server-filesystem", str(PATHS.k8s_docs_root)], load_prompts=False, ) tests_mcp_tool = MCPStdioTool( name="filesystem_tests", command="npx", args=["-y", "@modelcontextprotocol/server-filesystem", str(PATHS.tests_root.parent)], load_prompts=False, ) Those MCP tools are passed into Generator/Fixer agents, which then call MCP file functions (read/write/list) inside allowed roots only. 2) Kubernetes cluster control role: kubectl execution tool Cluster actions are not performed by MCP filesystem server; they are performed by a dedicated function tool: def run_kubectl_command(command: str) -> str: kubeconfig_path = os.environ.get("KUBECONFIG", "/home/developer/.kube/config") cmd_list = ["kubectl"] + command.split() result = subprocess.run( cmd_list, capture_output=True, text=True, check=True, env={**os.environ, "KUBECONFIG": kubeconfig_path}, ) return result.stdout And the Kubernetes agent forces tool usage: agent = responses_client.as_agent( name="KubernetesAgent", instructions="...You MUST use the run_kubectl_command tool...", tools=[run_kubectl_command], default_options={"tool_choice": "required"}, ) So the control plane is: MCP filesystem → manipulate generated task files. kubectl tool → query/mutate real cluster state. deterministic pytest/validator executors → accept or reject results. 3) End-to-end command flow in practice When generated tests run, they execute real kubectl get ... -o json checks in test code, and the deterministic runner captures raw output: pytest_command = f"pytest --import-mode=importlib --rootdir=. {task_with_val.task_directory}/" result = run_pytest_command(pytest_command) ctx.set_state(f"raw_output_{task_with_val.task_id}", raw_output) This means Kubernetes state verification is always grounded in live command output, not model speculation. Should MCP run Kubernetes tests? Short answer: not in this design. Current architecture keeps test execution deterministic and local: pytest is run by run_pytest_command(...) (pure Python subprocess runner) test results are parsed and stored in workflow state retry/fix routing uses those deterministic outputs This is intentional. If test execution were delegated to an LLM-facing MCP command tool, you would lose strict control over execution semantics and error handling. Recommended pattern: Use MCP for file/document access and controlled editing. Use deterministic executors for pytest and validation. Use LLM agents only for generation and repair. If you still want MCP-driven test execution, add a separate locked-down command MCP server (only whitelisted pytest/kubectl commands), but keep pass/fail decision logic in deterministic executors. How tests are run in this workflow (with code) The workflow executes tests in deterministic executors, not inside LLM agents. 1) Workflow node calls pytest runner run_pytest executor builds the command and calls the pure Python runner: @executor(id="run_pytest") async def run_pytest(task_with_val: TaskWithValidation, ctx: WorkflowContext[TestResult]) -> None: from agents.pytest_runner import run_pytest_command pytest_command = f"pytest --import-mode=importlib --rootdir=. {task_with_val.task_directory}/" result = run_pytest_command(pytest_command) raw_output = result["details"][0] if result.get("details") else "" ctx.set_state(f"raw_output_{task_with_val.task_id}", raw_output) ... 2) Deterministic subprocess execution The runner normalizes command flags and executes pytest via subprocess: def run_pytest_command(command: str) -> dict[str, Any]: normalized_command = _normalize_pytest_command(command) # adds -s if needed cmd_list = shlex.split(normalized_command) result = subprocess.run( cmd_list, capture_output=True, text=True, check=False, cwd=str(PATHS.pytest_rootdir), ) combined_output = result.stdout + "\n" + result.stderr _save_test_output(normalized_command, combined_output, skip_answer) ... Exit codes are interpreted deterministically: 0 → pass 5 → no tests collected (fail) others → fail with exit code reason 3) Skip-answer validation tier After normal pass, the workflow runs pytest again with SKIP_ANSWER_TESTS=True and parses JUnit XML: os.environ["SKIP_ANSWER_TESTS"] = "True" pytest_command = f"pytest --import-mode=importlib --rootdir=. --junitxml={junit_path} {task_dir}/" result = run_pytest_command(pytest_command) test_05_failed, test_03_skipped = _parse_skip_answer_junit(junit_path) The parser checks per-testcase outcomes: if "test_05_check.py" in context and has_failure_or_error: test_05_failed = True if "test_03_answer.py" in context and has_skipped: test_03_skipped = True 4) How failures trigger fix loop If pytest fails (or skip-answer logic fails), failure reasons and raw output are pushed into state, then the Fixer Agent receives a generated fix prompt containing that output: ctx.set_state(f"failure_reasons_{task_id}", reasons) ctx.set_state(f"raw_output_{task_id}", raw_output) fix_prompt = _build_fix_prompt(combined, raw_test_output) await ctx.send_message( AgentExecutorRequest( messages=[Message(role="user", contents=[fix_prompt])], should_respond=True ) ) That is the key loop: deterministic test output drives LLM repair, then deterministic tests re-run. ResponsesAgent Internals (Advanced Agent Framework Pattern) The custom ResponsesAgent (agents/responses_agent.py) demonstrates a lower-level integration pattern: Connect MCP tool lazily. Call Responses API. Parse ResponseFunctionToolCall items. Execute tools (MCP + custom callables). Feed function_call_output back to model. Repeat until final text response. It also runs a middleware chain around tool invocations, preserving observability and consistency with standard agent paths. Why This Architecture Is Robust This design works because Agent Framework is used as a deterministic orchestration layer around probabilistic generation: LLM creativity is constrained by typed state and strict prompts. deterministic executors act as objective quality gates. retries are targeted, bounded, and auditable. failures produce durable forensic artifacts (FAILURE_REPORT.txt + test logs). For Kubernetes education pipelines, this yields high throughput without sacrificing grader reliability. GitHub Repo - https://github.com/wongcyrus/k8s-game-rule-builder About the Author Cyrus Wong is the senior lecturer of Hong Kong Institute of Information Technology (HKIIT) @ IVE(Lee Wai Lee).and he focuses on teaching public Cloud technologies. He is a passionate advocate for the adoption of cloud technology across various media and events. With his extensive knowledge and expertise, he has earned prestigious recognitions such as AWS AI Hero, Microsoft MVP- Microsoft Foundry, and Google Developer Expert - Cloud(AI).465Views0likes0Comments