msignite
107 Topics
Production Touch Ledger (PTL): Verifiable records for operator transparency in the Sovereign Cloud
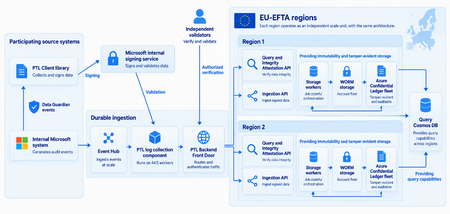
This post follows the broader Sovereign Public Cloud update by focusing on one technical mechanism for operational transparency: how PTL is designed to turn supported production-access event flows into reviewable tamper-evident records. As of October 2026, PTL is being rolled out in phases. Today, it covers production-access events from systems involved in the Data Guardian workflow in EU and EFTA cloud regions. Throughout this post, 'covered or in-scope systems' refers to these participating sources; coverage is expected to expand over time. For environments with sovereignty and regulatory requirements, the Production Touch Ledger (PTL) is designed to strengthen transparency and accountability for production-access activities. A production-access event represents an in-scope action performed during remote access by a Microsoft engineer to a production system in an EU or EFTA cloud region, captured by a supported source system - for example, reading a key in Azure Key Vault after being granted temporary access through Microsoft's just-in-time (JIT) access system. These events are recorded in an append-only, tamper-evident ledger, so any attempt to alter or delete the authoritative record — including by Microsoft — can be detected through verification. PTL records help address three critical questions: What happened? Who did it? And can unauthorized changes be detected? With PTL, authorized verification workflows can be used to verify the integrity of tamper-evident records of production activity, rather than relying solely on statements and assurances. Its architecture separates validation, signing, ingestion, processing, persistence, reconstruction, and verification so that each stage can be observed, tested, and governed. PTL provides documentation and verification of supported production-access activity. It does not replace the controls that determine whether production access is permitted. Why PTL exists In many systems, records handling can be implicit: events may be accepted, transformed, and queried in ways that make later verification difficult. PTL is designed to make records handling for supported production-access event flows explicit through defined stages and controls. PTL is engineered around three key capabilities: Verifiable records: PTL is designed to create durable, tamper-evident records of in-scope production-access events. Cryptographic integrity: PTL combines source signing, immutable storage, and cryptographic integrity proofs to support integrity verification. This verifiable-receipt model draws on is related to the approach Microsoft describes for software signing in Signing Transparency. Independent verification: Authorized verification workflows are designed to evaluate record integrity and identify inconsistencies in supported event records using integrity information maintained separately from the originating source system. Architecture at a glance PTL organizes in-scope production-access records processing into a seven-element conceptual flow: a participating source followed by six processing stages. Together, these stages show one way to combine source validation, durable ingestion, purpose-specific storage, reconstruction, and independent verification. This is one approach to combining these Azure services — not a prescriptive reference architecture — that architects can adapt to their own requirements Validation and signing: events are checked against the expected schema and cryptographically signed at the source. Durable ingestion: PTL is designed to acknowledge an event after durable capture. Downstream processing is then designed to complete or quarantine the event explicitly, so that processing failures can be surfaced for investigation. Secure processing: accepted events move through an asynchronous processing pipeline that validates each event, keeps it linked to the source system that produced it, and persists it for tamper-evident retention. Tamper-evident persistence: PTL is designed to retain signed events from supported source systems in Azure Blob Storage configured with immutability policies, record integrity references in Azure Confidential Ledger, and maintain query-ready projections in Azure Cosmos DB. Azure documentation describes Blob Storage write-once-read-many protections, Confidential Ledger's append-only and tamper-evident records, and Cosmos DB's indexing and query capabilities; PTL's end-to-end assurance still depends on its configuration, source coverage, and verification workflows. Record reconstruction: authorized workflows reconstruct event sequences and identify missing or inconsistent records. Authorized verification: authorized verification workflows are designed to evaluate event origin, integrity records, expected-event completeness, and records consistency beyond the producing system alone. Engineering deep dive Conceptual architecture: Participating source -> Validation and signing -> Durable ingestion -> Processing -> Tamper-evident persistence -> Record reconstruction -> Authorized verification. 1) Validation and source attribution PTL events are checked for structural conformance and signed at the source, then evaluated for cryptographic validity and source attribution through authorized verification workflows. 2) Asynchronous processing PTL’s ingestion design is intended to tie event acknowledgment to durable capture. After ingestion, accepted events move through an asynchronous pipeline, meaning processing continues in the background after the event is acknowledged. Controls in that pipeline help validate required attributes such as schema and signature, maintain the association between the event and their originating source system, record processing outcomes, and associate the retained event with the integrity information needed for later verification. Processing then completes, or the event is explicitly quarantined, so that processing outcomes can be surfaced for investigation. 3) Tamper-evident integrity association PTL retains signed event material alongside append-only integrity records that preserve verifiable linkage. Completeness checks help identify gaps among expected events from participating sources, while integrity verification is designed to identify inconsistencies resulting from covered modifications or deletions. These checks do not establish that every production action generated an event. 4) Purpose-specific persistence and record reconstruction PTL separates signed event material, append-only integrity records, and query-ready projections across purpose-specific Azure services. Each record surface serves a distinct role in retention, independent verification, or reconstruction of production activity. 5) Governed records retrieval PTL is designed to route records retrieval through authorized, role-scoped workflows rather than provide direct access to the underlying records stores. This keeps governance attached to records release as well as records retention. Closing PTL is best understood as a capability designed to provide reviewable records about supported production-access activity. Its architecture combines source validation and signing, durable ingestion, asynchronous processing, bounded completeness checks, tamper-evident persistence, record reconstruction, and governed retrieval. PTL is intended to support review of how in-scope production-access activity is captured, attributed, protected against undetected change, and released through governed workflows. This supports the broader Sovereign Public Cloud goal of operational oversight and transparency while remaining bounded by participating sources, configured controls, and published availability. In November 2026, Production Touch Ledger (PTL) was independently assessed by an authorized third party who evaluated its design and capabilities to provide verifiable, tamper-evident records of production access. 3P Validation report assessment supports greater transparency, trust, and accountability in sovereign and regulated environments.30Views0likes0Comments
A year of Azure Deployments: highlights from 2026
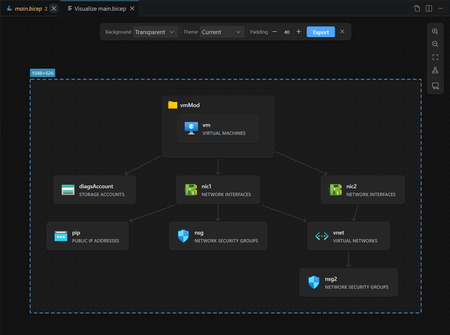
This year we had a lot of highlights to celebrate - we put out more than ten Bicep releases, What-If for Deployment Stacks went GA, the Bicep MCP server got new tools, and the Azure Verified Modules team joined us. A lot of these features started as GitHub issues, community call questions, or "why can't I just..." comments at conferences. So before anything else - thank you to our community. If you filed an issue, sent a PR, or challenged us on syntax during a community call, you played a part in improving Azure deployments for everyone. 1. Deployment Stacks: see what's going to be deleted before you delete it 1.a. What-If for Deployment Stacks is generally available. Stacks What-If shows you what a stack deployment will create, modify, detach, or delete before you run it. It compares your template against the current state of the resources the stack manages, and filters out the differences that were already there after the stack's last deployment. In practice that cuts out most of the noise you've seen from regular deployment What-If. When we went GA, we were able to close out nearly 200 open What-If issues on GitHub, many of them noise reports. It works across Azure CLI ( az stack-whatif ) and Azure PowerShell, at resource group, subscription, and management group scope. You can also use Stacks What-If to find configuration drift, i.e. changes made to a stack's resources outside the stack since its last deployment: Use what-if to investigate configuration drift Why it matters: you can finally use Stacks for real lifecycle management, including deletes, with a reviewable preview in your PR. If you've been running Stacks in detach mode "just to be safe," this is your sign to try delete. Docs: Preview deployment stack changes with what-if 2. Deploying from your pipeline: Bicep Deploy for GitHub Actions and Azure DevOps The bicep-deploy GitHub Action handles both regular deployments and Deployment Stacks, with create , validate , whatIf and (for stacks) delete operations, from one GH action. This year it picked up Stacks What-If support, better What-If error handling and output fixes. It also checks up front that your template path points to a file, and your JSON parameters file exists, so you get a clear failure instead of a confusing one halfway through a run. - name: Preview stack changes uses: azure/bicep-deploy@v2 with: type: deploymentStack operation: whatIf name: platform-stack scope: resourceGroup subscription-id: ${{ secrets.AZURE_SUBSCRIPTION_ID }} resource-group-name: rg-platform template-file: ./main.bicep parameters-file: ./main.bicepparam action-on-unmanage-resources: delete deny-settings-mode: none We also added support for Azure DevOps this year with the BicepDeploy@0 task. It shares a library ( bicep-deploy-common ) with the GitHub Action, so the behavior and functionality should feel familiar across both tools. New features can reach the two tools at different times. Why it matters: "What-If on every PR, deploy on merge" is now a few lines of YAML, and the action works the same way for stacks and deployments. Docs: Deploy Bicep files by using GitHub Actions · BicepDeploy@0 task · Repo: github.com/Azure/bicep-deploy 3. Parameter files that scale with your environments 3.a. Extendable parameter files (GA) If you have dev, test, and prod, you probably have three .bicepparam files that are 90% identical. Extendable params let you put the shared values in one file and override only what's different: // shared.bicepparam using none param namePrefix = 'contoso' param location = 'westus3' // dev.bicepparam using './main.bicep' extends './shared.bicepparam' param namePrefix = 'contoso-dev' // overrides the shared value Inherited parameters are also optional now. Your shared file can hold values that not every template uses, without the compiler complaining. This means when a parameter changes you don’t have to remember to change it in three places - change it in one place and get the benefit across environments. Docs: Extendable parameter files in Bicep 3.b. bicepconfig.json inheritance A bicepconfig.json can now extend another config file and override only the settings it cares about. Platform teams can define one org-wide baseline (linter levels, registry aliases, and so on) and have every repo inherit it: { "extends": "../shared/bicepconfig.base.json", "analyzers": { "core": { "rules": { "no-hardcoded-env-urls": { "level": "error" } } } } } Docs: Bicep configuration inheritance Why it matters: less copy-paste, less drift between environments, and one place to change a setting instead of thirty repos. 4. Language features: fewer workarounds, fewer failed deployments 4.a. @nullIfNotFound() and the this namespace (GA) "Deploy this if it doesn't exist, otherwise reference it" used to mean deployment scripts or parameters passed in from the pipeline. Now: @nullIfNotFound() resource kv 'Microsoft.KeyVault/vaults@2023-07-01' existing = { name: keyVaultName } output kvUri string = kv.?properties.vaultUri ?? 'not deployed yet' The this namespace lets a resource look at its own current state. this.exists() returns a bool, and this.existingResource() returns the resource if it's there or null if it isn't: resource sa 'Microsoft.Storage/storageAccounts@2023-05-01' = { name: storageName location: location kind: 'StorageV2' sku: { name: 'Standard_LRS' } properties: { // keep whatever TLS setting is already on the resource; default new ones to 1.2 minimumTlsVersion: this.existingResource().?properties.minimumTlsVersion ?? 'TLS1_2' } } We also added runtime values in tags and sku as an experimental feature, so a redeploy can keep the values that are already on a resource instead of stomping them. As the experimental features doc notes, it won't work until the backend support is deployed. Docs: @nullIfNotFound() · The this namespace 4.b. @retryOn() (GA) Some deployments fail on transient errors that succeed on a second try. Instead of wrapping your whole pipeline in retry logic, you can now retry just the resource that needs it, on just the error codes you expect: @retryOn(['ResourceNotFound'], 10) resource storageAccount 'Microsoft.Storage/storageAccounts@2023-05-01' = { name: 'srp1' location: location sku: { name: 'Premium_LRS' } kind: 'BlobStorage' } Docs: Retry resource deployments in Bicep 4.c. Resource provider registration (experimental) With the azExtensionConfig experimental feature, a template can list resource provider namespaces in the providers property of the az extension. ARM then registers each one on the target subscription at the start of the deployment. It registers resource providers only, not preview features. As the experimental features doc notes, it won't work until the backend support is deployed. extension az with { providers: [ 'Microsoft.Storage' 'Microsoft.Compute' ] } 4.d. New functions: like() , distinct() , roleDefinitions() , getRoleAssignmentName() Each one replaces something people were hand-rolling: output isProd bool = like(environmentName, '*prod*') // wildcard matching output regions array = distinct(['eastus', 'westus', 'eastus']) properties: { roleDefinitionId: roleDefinitions('Storage Blob Data Reader').id // look up built-in roles by name, no more GUIDs principalId: identity.properties.principalId } getRoleAssignmentName() gives role assignments a deterministic name, which helps a lot with the "duplicate role assignment" errors you hit when different tools name the same assignment differently. Docs: like() · distinct() · roleDefinitions() · getRoleAssignmentName() 4.e. Multi-line interpolated strings (GA) Embedding a script, a policy rule, or a chunk of JSON in a template no longer means a wall of concat() or escaping: var policyRule = $''' { "if": { "field": "tags['${tagName}']", "exists": "false" }, "then": { "effect": "${policyEffect}" } } ''' Docs: Multi-line strings 4.f. Extension namespace functions Extension authors can now ship typed functions for .bicepparam files. You declare the extension in the parameters file and call its function, for example something like ext.config('redis') , instead of writing raw externalInput() calls and memorizing the expression format. Bicep checks the arguments against the types the extension publishes, then turns the call into an externalInput() request, and the tool that runs the deployment supplies the value. Docs are on the way. For now, see externalInput() . Why it matters: most of these remove a reason to drop out of Bicep into a script. Fewer scripts means fewer moving parts, and deployments that are easier to reason about. 5. Tooling: Console, Snapshot, Visualizer, and friends 5.a. Bicep Console (GA) bicep console is a REPL for Bicep expressions. It's the fastest way to check what a function returns without deploying anything (functions that need Azure context, such as resourceGroup() , don't work there). Since it went GA, it has added Home and End keys, word-by-word cursor jumps, and undo/redo. It also supports the load*() functions, and you can pipe input into it: echo "parseCidr('172.18.0.0/20')" | bicep console Docs: bicep console 5.b. Snapshot (GA) bicep snapshot produces a normalized, fully evaluated view of what a .bicepparam file will deploy. You commit it, and on the next change you validate against it. The diff shows exactly which resources and properties moved, all locally with no Azure connection: bicep snapshot main.bicepparam --mode overwrite # capture bicep snapshot main.bicepparam --mode validate # compare against the last snapshot You can also pass subscription, resource group, and location to evaluate with real deployment context. This is great for refactoring: if the snapshot doesn't change, your refactor didn't change what gets deployed. Docs: Test Bicep changes with snapshots 5.c. A rebuilt Visual Designer The visualizer got rebuilt. The language server now builds the graph and lays it out (with MSAGL), and you can collapse modules, export the graph as a PNG, and use high-contrast themes. Resources with errors are marked on the graph, and you can undo or redo node moves and layout changes. An experimental setting ( bicep.visualizer.experimental.enableResourceEditing ) also lets you add resources from a palette, which lists only the resource types that can deploy at the file's target scope. Docs: Open Bicep Visualizer command. Docs for the new designer features are on the way. 5.d. Bicep Playground redesign The Playground got a new look. Compilation moved off the main thread, so the UI doesn't freeze, and you now get diagnostics and light/dark themes. It's a nice way to try a feature or share a repro without installing anything. Try it: Bicep Playground 5.e. Module documentation generation (experimental) bicep docs generate builds Markdown docs for a module from the Bicep code itself. This came straight out of AVM, which needed a way to drop a pile of custom PowerShell. It's also something module authors have been asking for, for a long time. bicep docs generate ./main.bicep bicep docs generate --pattern './modules/**/main.bicep' Docs: Generate module documentation 5.f. Language server as a standalone tool The Bicep language server is now published as a .NET tool, so you can run it outside VS Code in Neovim, Emacs, or whatever your editor of choice is: dnx -y Azure.Bicep.LangServer Docs: Bicep language server .NET tool 5.g. Faster CLI We spent time on performance this year: caching fixes in the compiler and language server, plus ReadyToRun compilation to bring CLI cold-start times down. In our benchmark on Windows x64, a cold bicep build went from about 3.6 seconds to 1.3. If you run bicep build in CI, you'll notice. Details: v0.47.16 release notes 5.h. New linter rules A batch of new rules catches mistakes while you're authoring instead of at deploy time, including: use-description-params , -vars , -outputs , -types , -type-properties (off by default) to enforce @description() on everything no-unused-types secure-params-in-parameters-file , which flags secure values leaking into non-secure parameters no-hardcoded-outputs (off by default) use-recognized-resource-type , for typos in reference() / list*() calls no-module-name (optional), now that module names are optional Docs: Use Bicep linter 6. Bicep MCP server If you're writing Bicep with GitHub Copilot or another agent, the Bicep MCP server gives the model tools for Bicep generation. It can fetch the schema for a resource type and API version, get Bicep best practices, list Azure Verified Modules metadata, build a file and return its diagnostics, format a file, decompile ARM JSON, and generate a deployment snapshot from a .bicepparam file. The model can check its own work against the compiler before it hands anything back to you. It ships in the VS Code Bicep extension, and you can run it with any MCP-capable client (it needs the .NET 10 SDK): dnx -y Azure.Bicep.McpServer We also published the core library ( Azure.Bicep.McpServer.Core ) so you can build your own remote MCP server on top of it. Why it matters: AI-generated Bicep that compiles, uses real API versions, and follows best practices on the first try. Docs: Bicep MCP server. We'd also love your feedback on how you use Bicep with AI: aka.ms/BicepwithAI 7. Modules, registries, and samples 7.a. OCI registry support (experimental) You're no longer tied to Azure Container Registry for publishing and consuming modules and extensions. With the ociEnabled experimental feature turned on, bicep publish can target any OCI registry, such as GitHub Container Registry: bicep publish ./main.bicep --target br:ghcr.io/myorg/modules/storage:v1 Docs: Using OCI registries (experimental) 7.b. Azure Verified Modules joined the team AVM moved into Azure engineering and is now part of the Azure Deployments team. AVM stays open source, and now has more investment behind it. We also restarted the AVM community call and published the Avm.Authoring PowerShell module for module authors. For more, see the AVM announcement and the October AVM community call recording. Docs: Azure Verified Modules 7.c. Bicep and Terraform samples in the template reference The Azure template reference docs now include Bicep and Terraform samples. You can look up a resource type and find an example in the language you use, not just ARM JSON. Docs: Azure template reference 8. Azure Blueprints is retiring: move to Deployment Stacks Azure Blueprints (preview) retires on January 31, 2027, and the phased retirement has already started. Deployment Stacks, along with Template Specs for versioning, is the replacement. Most of what Blueprints did maps cleanly: Artifacts become ARM or Bicep templates. Locks become deny settings. Assignment lifecycle becomes stack lifecycle, and now you get What-If too. If you're still on Blueprints, start now. Migration guide: Migrate blueprints to deployment stacks · Retirement details: aka.ms/AzureBlueprintsRetirement Stay in touch We'll walk through these highlights live in the Bicep Ignite Special on Thursday, November 19 at 9:00 AM PT. If you want to follow along with the demos, the code is in github.com/SydneyhSmith/ignite2026-demo. After that, join us for the next Bicep community call on Wednesday, December 2 at 9:00 AM PT, and sign up for community call invites at aka.ms/AzureBicep. Tell us what's working and what isn't. Open an issue in Azure/bicep, Azure/deployment-stacks, or Azure/bicep-deploy, and share how you use Bicep with AI at aka.ms/BicepwithAI. For news between calls, follow @BicepLang on X and biceplang.bsky.social on Bluesky.Microsoft named a Leader in 2026 Gartner Magic Quadrant™ Report and IDC MarketScape for databases
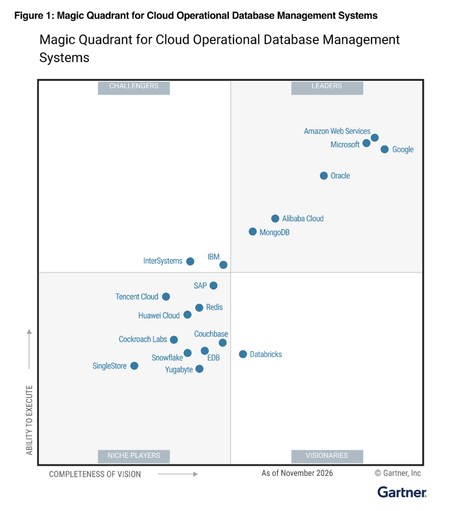
By Wangui McKelvey, Vice President Azure Data Product Marketing We’re proud to share recognition for Microsoft in two evaluations from industry analyst firms: Microsoft has been named a Leader in both the 2026 Gartner® Magic Quadrant™ for Cloud Operational Database Management Systems and the IDC MarketScape: Worldwide Operational Databases 2026. Gartner recognizes Microsoft’s cloud operational databases portfolio Gartner says “Leaders in the cloud operational DBMS market demonstrate broad support for mission-critical transactional workloads. They offer mature, highly scalable platforms with proven performance, high availability, and strong operational resilience. These vendors lead the market by investing in advanced capabilities, including serverless architectures, robust financial governance, developer productivity tools, and built-in AI capabilities such as vector search and support for agentic AI workflows. Leaders support flexible deployment options, including multicloud, hybrid, and distributed environments, and maintain extensive ecosystem integrations. They possess a large, satisfied customer base, high market visibility, and strong financial viability, making them low-risk choices for enterprise operational applications.” IDC MarketScape recognizes Microsoft According to the IDC MarketScape, “With decades of production deployment, a large installed base, and broad capability across transactional, analytical, and AI workloads, Microsoft SQL positions itself as a relational platform that aligns well with organizations invested in the Microsoft and Azure ecosystem that prioritize operational maturity, converged workloads, and a dependable foundation for transactional and AI-enabled applications.” The report also notes, “Microsoft SQL pairs its established transactional engine with native vector search, in-database embedding generation, and a columnstore capability for combined transactional and analytical processing in a single engine.” SAP shows this modernization in practice. They migrated 6,000 Commerce Cloud databases to Azure SQL Database Hyperscale, with Azure Kubernetes Service supporting application scaling. On Black Friday 2025, the platform processed $17.8 billion in gross merchandise with no downtime. One Microsoft database portfolio for enterprise applications and AI Microsoft has been building operational databases for more than 30 years, beginning with SQL Server and extending to the cloud with Azure SQL, built on the same core engine. Today, our comprehensive database portfolio also spans managed open-source relational database services, NoSQL databases, and an in-memory caching service. Across this portfolio, our focus is to help enterprises run critical applications with confidence and put operational data to work in new AI experiences. Operational databases power the business-critical applications enterprises rely on to serve customers and run their operations. Organizations need a database foundation that keeps those applications secure, responsive, and available as they grow, while helping them manage operating costs and modernize existing workloads. Our approach to databases brings three priorities together: Keep mission-critical workloads running reliably and fast. Enterprises need dependable transaction processing, responsive reads and writes, and protection for operational records. The Microsoft database portfolio offers choices for performance, scaling, high availability, and recovery that enterprises can match to each workload's requirements. Reduce Operational complexity. Fully managed Azure database services reduce routine work such as patching and backups, while flexible scaling helps align resources with demand. Database Hub in Microsoft Fabric brings supported database resources and gives teams a single place to discover and monitor Microsoft operational databases, investigate performance issues, and take guided action to keep applications running smoothly. Connect operational data with AI and analytics. Microsoft databases do more than store the records behind enterprise applications. Built-in capabilities such as vector search help applications ground AI experiences in relevant data. Integrations with Microsoft Foundry connect that database context to AI models, while Fabric mirroring replicates operational data into OneLake for analytics and reporting, reducing or eliminating the need to build custom data pipelines. The right database for every enterprise workload Building on a dependable operational foundation means giving enterprises room to evolve their applications. Within our broader portfolio, three cloud-native offerings support that growth. Azure SQL Database Hyperscale combines familiar SQL capabilities with flexible scaling for growing transactional and read-intensive workloads. Azure HorizonDB brings PostgreSQL compatibility together with an architecture designed for demanding transaction processing, resilience, and scale. Azure Cosmos DB supports responsive, globally distributed applications with flexible NoSQL data models and managed scaling. These offerings give enterprises different foundations for evolving their applications, rather than requiring every workload to fit a single database architecture. Docusign puts the connection between operational data and AI into practice. Azure Cosmos DB and Azure Database for PostgreSQL manage agreement intelligence data alongside Microsoft Foundry, supporting a platform that processes more than 1 million agreement documents daily and helps customers turn that information into action. Moving enterprise applications forward We are grateful to the customers, database professionals, developers, and partners who put Microsoft databases to work every day and help shape what we build. Recognition from Gartner and IDC MarketScape is an important milestone for us. Our focus remains on helping enterprises run their critical applications with confidence, build on their existing investments, and manage the cost and complexity of their database environments. As applications evolve, that means building on the performance, resilience, and security depend on today, while creating new ways to put operational data to work, including in AI-powered experiences. Learn more about Azure Databases and get started with an Azure free account on your database modernization journey. Gartner, Magic Quadrant for Cloud Operational Database Management Systems, By Masud Miraz, Aaron Rosenbaum, Ramke Ramakrishnan, Xingyu Gu, Michael Gonzales, Prasad Pore, Robin Schumacher, 12 November 2026 Gartner does not endorse any company, vendor, product or service depicted in its publications, and does not advise technology users to select only those vendors with the highest ratings or other designation. Gartner publications consist of the opinions of Gartner’s business and technology insights organization and should not be construed as statements of fact. Gartner disclaims all warranties, expressed or implied, with respect to this publication, including any warranties of merchantability or fitness for a particular purpose. Gartner and Magic Quadrant are trademarks of Gartner, Inc., and/or its affiliates. This graphic was published by Gartner, Inc. as part of a larger research document and should be evaluated in the context of the entire document. The Gartner document is available upon request from Microsoft.90Views0likes0CommentsYour guide to FinOps for AI at Microsoft Ignite 2026
AI has moved from pilots to production, and the questions have changed with it. It is no longer enough to know what AI costs. Leaders want to know whether spend is predictable, who is driving it, and which investments are delivering real business value. That is the job of FinOps for AI: bringing finance, IT, engineering and business teams together to plan, control and optimize AI spend and value. At Microsoft Ignite, November 17–20, 2026, in San Francisco and online, FinOps for AI shows up across the agenda, from keynotes to breakouts, demos, lightning talks, table talks and hands-on labs. Whether you manage Microsoft 365 Copilot and agents, build on Microsoft Foundry and GitHub, or own the AI budget, there is a session for you. We've gathered them all in one place so you can plan your week. Innovation sessions Start with the big picture. These sessions will showcase how cost and value fit into Microsoft's broader AI vision, and what's new across the stack. INV642: Observability at every layer of the stack As AI and agents scale, visibility, trust, and security become business imperatives. Join Charles Lamanna, Executive Vice President, Copilot, Agents, and Platform, and Hayete Gallot, Executive Vice President, Microsoft Security, to explore how observability at every layer of the stack helps organizations understand where AI is being used, how agents are operating, what risks are emerging, and whether investments are delivering results. See how organizations can turn visibility into action to scale AI with confidence. Session page: https://ignite.microsoft.com/en-US/sessions/INV642 INV641: Harnessing Your IQ with a continuously improving agent platform Join Arun Ulag and Jay Parikh to discover how Microsoft IQ helps your organization activate, protect, and build on the knowledge that makes it unique. Learn how to keep improving as models evolve, with model choice and control intact. Explore how your data and expertise become AI that understands your business, so work runs faster, more accurately, and at lower cost. Session page: https://ignite.microsoft.com/en-US/sessions/INV641 Breakout sessions Breakouts go deeper, with technical content and live demos. We've grouped them by topics and scopes. Understand economics and value BRK537: From AI Ambition to Value at Scale As AI moves from experimentation into everyday business operations, growing usage alone does not tell leaders whether an investment is working. Learn how organizations can connect AI consumption to measurable business value, establish the visibility and accountability needed to manage it, and determine whether the economics continue to hold as adoption grows. Leave with a practical approach for deciding where AI has earned the right to scale, where to adjust, and where continued investment may not be justified. Session page: https://ignite.microsoft.com/en-US/sessions/BRK537 BRK308: How Microsoft IQ shapes the cost of enterprise AI Enterprise AI does not have one cost model. It has three: people, consumption, and capacity. Through a retail AI scenario and a live cost estimation demo, this session shows how Work IQ, Foundry IQ, Fabric IQ, and Web IQ create different cost shapes, and how to optimize each one for scale, value, and control. Session page: https://ignite.microsoft.com/en-US/sessions/BRK308 BRK260: The next evolution of AI FinOps: From cost to value Visibility into AI spend is just the beginning. Learn how leading organizations optimize investments across Microsoft 365 Copilot, Copilot Studio, and GitHub Copilot to maximize business impact. Discover how new capabilities, help you manage costs, prove value, and scale the AI initiatives that deliver the biggest results. Session page: https://ignite.microsoft.com/en-US/sessions/BRK260 Establish governance and guardrails BRK263: Master AI spend management with Agent 365: Govern your AI budget See the tools IT needs to govern, control, and optimize AI spend at scale. Join this deep dive into Agent 365 and Microsoft 365 Admin Center capabilities for AI FinOps. Learn how to establish guardrails with policies, monitor consumption across AI vendors, measure value, and confidently scale AI across your organization. This is the essential session for IT to understand the latest innovations in AI cost management and governance. Session page: https://ignite.microsoft.com/en-US/sessions/BRK263 BRK262: Scale agents, not risk: Governance and FinOps for the enterprise As agents move from experimentation to enterprise-wide deployment, IT needs a new approach to governance and FinOps. Learn how to build a scalable operating model across agent inventory, lifecycle, security, cost management, and optimization, giving teams the freedom to innovate while maintaining the visibility, guardrails, and financial discipline IT needs. Session page: https://ignite.microsoft.com/en-US/sessions/BRK262 BRK290: Humans, agents, and a game plan: AI governance with GitHub Enterprise Give developers, knowledge workers, and AI agents room to innovate with enterprise control. Follow an admin journey in GitHub Enterprise and Copilot: set model policies and managed settings, customize for teams, onboard fast, and manage access and spend. Review config changes via pull requests and use agent activity data to assess governance. See the roadmap linking policy, usage, and cost. Leave with a plan to set guardrails, measure impact, and grow AI adoption without friction. Session page: https://ignite.microsoft.com/en-US/sessions/BRK290 Optimize spend and technical choices BRK266: Maximize your Copilot Investment: Scale with flexibility and control AI investments are growing, but are organizations getting the most value from them? Learn not only how to gain visibility and control over AI spend, but also how to measure business value and continuously optimize. Explore new capabilities designed to help organizations manage spend against budget, allocate resources effectively, and maximize the value of their AI investments. Session page: https://ignite.microsoft.com/en-US/sessions/BRK266 BRK271: Manage GitHub Copilot spending and understand team adoption Make informed decisions about your Copilot investment. Explore how model choices, agent workflows, and GitHub Actions contribute to development costs, then use billing reports, budgets, and alerts to manage spending. Learn to interpret adoption and engagement trends, spot underused capabilities, and target support where teams need it. IT admins and engineering leaders will leave with practical steps to manage costs and help developers use Copilot effectively. Session page: https://ignite.microsoft.com/en-US/sessions/BRK271 BRK216: Multi-model AI in Copilot: Performance and value with built-in trust No single AI model is best for every task. As AI advances, organizations need access to the latest models without adding complexity for users, cost uncertainty for leaders, or administrative risk for administrators. Join us to see how Microsoft Copilot provides one governed front door to multi-model AI, with Microsoft evaluation and integration, intelligent routing with Auto, and cost management tools to you optimize AI value while maintaining security, compliance, and control. Session page: https://ignite.microsoft.com/en-US/sessions/BRK216 BRK280: Designing an agent harness that orchestrates models Choosing a model is becoming less important than deciding how and when models are used. Explore how routing can match models to different tasks, constraints, and stages of development. We’ll examine the signals and tradeoffs that guide these decisions, and approaches such as HydraFusion that coordinate models as a portfolio. Leave with a framework for building adaptable agent systems across quality, latency, cost, and control. Session page: https://ignite.microsoft.com/en-US/sessions/BRK280 BRK249: From traces to better agents: The Foundry improvement loop Building an agent is the start. Improving it in production is the real work. See how Microsoft Foundry connects traces, evaluations, and optimization to help teams find high-impact issues, test improvements, and re-measure results. Learn a repeatable loop to improve quality, manage cost, and ship better agents while developers stay in control. Session page: https://ignite.microsoft.com/en-US/sessions/BRK249 Session for partners BRK482: FinOps for AI: Partner Playbook for Building AI Solutions and Services AI is creating unprecedented opportunities for partners, but success requires more than innovative solutions. It requires managing the economics behind AI. In this session, Microsoft leaders and industry experts share a practical FinOps framework for AI to help partners anticipate and govern costs, optimize token consumption, and build repeatable, profitable services. Hear real-world partner examples and leave with actionable guidance to turn AI cost management into a competitive advantage. Session page: https://ignite.microsoft.com/en-US/sessions/BRK482 Theater sessions, lightning talks, table talks and labs Short on time or want to get hands-on? These shorter formats include product demos, focused talks, small-group discussions and labs. Labs require an RSVP, so reserve your seat early. Code Session Format Session page PREB23 Optimize your Copilot Investment Pre-day session https://ignite.microsoft.com/en-US/sessions/PREB23 THR865 Navigating AI spend across your organization Theater https://ignite.microsoft.com/en-US/sessions/THR865 THR895 AI for FinOps, continuous optimization for every workload Theater https://ignite.microsoft.com/en-US/sessions/THR895 THR967 AI FinOps in practice: what IT and business owe each other Theater https://ignite.microsoft.com/en-US/sessions/THR967 LTG1170 AI That Pays Off: New Ways to Measure Value and Optimize Spend Lightning talk https://ignite.microsoft.com/en-US/sessions/LTG1170 LTG1165 Preparing for usage-based billing Lightning talk https://ignite.microsoft.com/en-US/sessions/LTG1165 LTG1193 A practical guide to FinOps for GitHub Copilot Lightning talk https://ignite.microsoft.com/en-US/sessions/LTG1193 LTG1342 FinOps for AI: Unlocking value across the AI lifecycle Lightning talk https://ignite.microsoft.com/en-US/sessions/LTG1342 LTG1206 Agent FinOps: Designing agents that scale responsibly Lightning talk https://ignite.microsoft.com/en-US/sessions/LTG1206 TT1669 Agent ROI, optimization and FinOps Table talk https://ignite.microsoft.com/en-US/sessions/TT1669 LAB660 Configuring, monitoring, and managing AI spend with Agent 365 Hands-on lab https://ignite.microsoft.com/en-US/sessions/LAB660 LTG1201 Optimizing AI decisions with the model router in Foundry Models Lightning talk https://ignite.microsoft.com/en-US/sessions/LTG1201 Plan your FinOps for AI week Every session above maps to the same journey: plan AI spend so it's predictable, control it so costs stay visible and accountable, and optimize it to get more value from every AI investment. Add the sessions that match your role to your Ignite schedule and stop by to talk with our team. We look forward to seeing you at Ignite. Next steps Join us at Microsoft Ignite, November 17–20 in San Francisco to see it in action and go hands-on with the team that built it. Catch us on 'Live at Microsoft Ignite' which will be broadcasted on Ignite.com, starting Tuesday, November 17th, through Thursday, November 19th.1.3KViews0likes1Comment
Build faster apps: database caching patterns with Azure Managed Redis
When thousands of shoppers hit the same pages, your database answers the same question over and over. See how Azure Managed Redis takes on that repeat work, with eight caching patterns, architectures, how-to guides, and ready-to-deploy samples for Azure Database for PostgreSQL, Azure SQL Database, and Azure Cosmos DB.126Views1like0CommentsVisit Azure and AMD at Microsoft Ignite and SC26
AI workloads place different demands on infrastructure. Azure is continuing to partner closely with silicon partners including AMD to expand infrastructure choice across general purpose compute and AI accelerators. That choice includes three purpose built virtual machines (VMs): Azure HDv2-series virtual machines for the data preparation behind AI training, AMD Instinct™ MI300X accelerators for AI Inference and agents, generally available as managed endpoints in Microsoft Foundry or as Azure ND MI300X v5 VMs, and AMD Instinct™ MI455X accelerators in Azure for next generation AI infrastructure coming to Azure. In July, we shared how Azure is expanding its AI and HPC infrastructure with AMD. Here’s where to learn more at Microsoft Ignite and SC26. Azure HDv2: accelerating AI data processing, HPC, and agentic workloads Accelerators are only as productive as the data feeding them, and CPUs play an integral role in preparing that data. Microsoft has opened preview registration for Azure HDv2-series virtual machines, making Azure the first cloud to offer access to 6th Gen AMD EPYC™ (“Venice”) processors. HDv2 is built for AI data systems, with over 500 physical CPU cores, 3.8 TB of memory, 32 TB of local NVMe storage and 400 Gb Azure Boost networking. In benchmark testing on a preproduction AMD system with two “Venice” processors, an AI data-preparation pipeline prepared a 1.3 TB dataset for AI training in about 37 minutes 1 . HDv2 is projected to cut runtime by 49% compared with the next-best tested configuration (about 73 minutes), helping teams start training sooner and make better use of accelerator capacity. With over 500 cores, HDv2 can also speed compute-intensive HPC workloads such as engineering simulation and weather modeling. Customers can sign up to request access at aka.ms/HDv2Preview. AMD Instinct™ MI300X, on Azure today: a managed endpoint or your own VM AMD Instinct™ MI300X is generally available on Azure today. Through Microsoft Foundry Managed Compute, teams can deploy open models from the Foundry model catalog onto dedicated MI300X capacity, via a private endpoint. Microsoft manages the software needed to run each model, so teams do not need to set up or maintain it themselves. Capacity is billed by the GPU-hour, and billing stops when the instances are spun down deployment is deleted. In a third-party evaluation by Signal65, AMD Instinct™ MI300X on Microsoft Foundry Managed Compute deployed live endpoints in 14-24 minutes with no serving stack tuning across the leading family of models including gpt-oss, gemma and GLM. MI300X delivered strong results across performance, cost per session, and agent capacity for coding, document analysis and chat workloads 2 . Teams that want full control of the software stack, or that are fine-tuning and training their own models can use Azure ND MI300X v5 virtual machines, with eight AMD Instinct™ MI300X accelerators and 1.5 TB of HBM per VM. Each MI300X provides 192 GB of HBM3 memory, allowing large models to run on fewer accelerators. AMD Instinct™ MI455X accelerators in Azure: engineered as a complete system That same focus on purpose-built infrastructure extends to AI accelerators. Azure and AMD are working together on AI infrastructure built around AMD Instinct™ MI455X accelerators and AMD’s Helios™ reference design. Running AI at scale requires more than AI accelerator performance. Consistent with how we approach AI infrastructure, Azure and AMD work together to design this complete system, so it fits into our Azure datacenter without retrofitting, with power, cooling and networking designed and validated together as one system. Microsoft’s system-level engineering across custom and partner silicon helps us bring advanced AI infrastructure from production to deployment faster, meaning we deliver more capacity to meet Azure and AI demand. Join us at Microsoft Ignite and SC26 to learn more about how Azure and AMD are expanding infrastructure choice. Event Session Ignite BRKSP596: Optimize data, security, and AI with AMD on Azure Ignite BRKSP614: AMD Instinct on Azure: More models. More agents. More choice. Ignite LABSP830: Improve token efficiency with vLLM Semantic Router Ignite LABSP831: Fine-tune AI models locally with AMD Ryzen AI and Unsloth Ignite LABSP833: Build local AI agents on AMD Ryzen AI PCs SC26 Various: Visit Microsoft at Booth #3411 1 Projected HDv2 performance is based on benchmark results from a preproduction AMD system with two “Venice” processors, using recommended software and settings. Results may vary depending on workload, software, configuration and the final Azure environment. 2 Study commissioned by Microsoft. Signal65, Tables 3, 5–8, 8–9. GPU-only economics at sustained tested load and $7.91/GPU-hour. Throughput is aggregate. Gemma chat economics calculated from 1,065 output tok/s and 490 output tokens/request. 1K-input/490-output test. Different workloads; no quality ranking. Use cases are illustrative.261Views0likes0Comments
Join NVIDIA and Microsoft at Ignite 2026
Microsoft Ignite will run November 17 to 20 at Moscone Center in San Francisco and online (register for in-person or online attendance access here). Microsoft will open with the keynote on Tuesday, November 17, at 10:00 AM PT, and after Microsoft and NVIDIA will be there together in breakout sessions, in a hands-on lab, and on the show floor. In case you missed it Vera Rubin. In March, Microsoft became the first cloud to bring up an NVIDIA Vera Rubin NVL72 system for validation. In August, we delivered the first production Vera Rubin systems in our datacenters. Cloud to edge. In our October post, we shared how Azure and Azure Local, with NVIDIA accelerated computing, let you build AI in the cloud and run it where latency, data residency, or operational control matter. Where to hear more at Ignite AI infrastructure on Azure On Tuesday, November 17, at 3:15 PM PT, Power accelerated computing on Azure with NVIDIA will be led by Dave Salvator, Director of Accelerated Computing at NVIDIA, who will cover running AI, data science, and simulation workloads with NVIDIA GPUs, software, and services. Agentic AI with Microsoft Foundry and NVIDIA Nemotron On Wednesday, November 18, at 11:30 AM PT, Architect reliable and secure agentic AI at scale will show how to build agentic AI with Microsoft Foundry, NVIDIA Nemotron models, and NVIDIA infrastructure on Azure. To try it yourself, join LABSP840, a hands-on lab with Nemotron and Foundry. It's in person only and won't be recorded. Cloud to edge and physical AI Scaling intelligence cloud to edge with agentic AI factories will run Thursday, November 19, at 2:45 PM PT. Dion Harris, Senior Director of AI Infrastructure and HPC Solutions at NVIDIA, will walk through how NVIDIA and Microsoft co-engineer full-stack AI infrastructure for Azure datacenters and for Azure Local. He'll also cover token-per-watt efficiency and how NVIDIA open models and Open Agent Safety help secure agentic AI. Industries reimagined with physical AI will feature speakers from Microsoft and NVIDIA on Thursday, November 19, at 10:15 AM PT. The LTGSP1631 lightning talk will cover digital twins and physical AI with Azure, NVIDIA Omniverse libraries, and NVIDIA cuOpt. NVIDIA cuOpt is an open-source GPU-accelerated optimization engine delivering near real-time solutions for complex decision-making challenges. Both are in person only. BRKSP615 will be recorded; the lightning talk won't be. Schedule at a glance Times are subject to change, so please check each session page for the latest and add it to your schedule. When (PT) Session How to attend Tue 11/17 3:15 to 4:00 PM BRKSP630: Power accelerated computing on Azure with NVIDIA In person + online Wed 11/18 11:30 AM - 12:15 PM BRKSP597: Architect reliable and secure agentic AI at scale In person + online Thu 11/19 10:15 to 11:00 AM BRKSP615: Industries reimagined with physical AI In person only; recorded Thu 11/19 2:45 PM - 3:30 PM BRK480: Scaling intelligence cloud to edge with agentic AI factories In person + online Fri 11/20 10:15 to 11:00 AM BRK581: Model to mission: Azure Infra for agentic enterprise In person + online Tue 11/17, 2:30 PM - 3:45 PM LABSP840: Agentic AI with the NVIDIA Nemotron Open Models and Microsoft Foundry (lab) In person only; not recorded Wed 11/18, 9:25 AM - 9:40 AM LTGSP1631: From Digital Twins to Physical AI: Azure Meets NVIDIA Omniverse & cuOpt (lightning talk) In person only; not recorded On the show floor NVIDIA will be at booth 5644, with 30 in-person theater sessions Tuesday through Thursday, November 17 to 19. See you at Ignite If you're watching online, you can join sessions marked "In person + online" and catch recorded sessions on demand. For everything else, browse the full Ignite session catalog.457Views0likes0Comments
Building a Trusted Ecosystem for Sovereign Private Cloud: Azure Local validated partner solutions
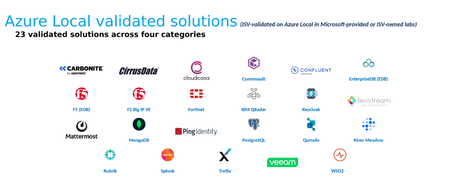
When organizations move critical workloads to Azure Local, the first question usually isn't about the platform. It's about everything that runs on and around it: Will my backup tool work? Can my Security Operations Center (SOC) still see the workloads it needs to monitor? Will my identity provider support authentication if the site loses its cloud connection? The answers can determine how confidently a sovereign or edge deployment moves to production. Customers want to run the independent software vendor (ISV) solutions they already trust, with confidence in how those solutions have been validated for their Azure Local environments. That's why we built the Azure Local Validated ISV Program. Why an ecosystem program, and why now Demand for Sovereign Private Cloud is increasing as organizations look for greater control over where and how their workloads operate. Governments, regulated industries, critical infrastructure providers and telecom operators want cloud-style operations while maintaining control of their data, security, compliance and operational boundaries. Azure Local supports a range of deployment architectures, including connected and disconnected operating models, and hyperconverged, disaggregated and multi-rack configurations. Infrastructure alone, however, does not make a production environment. Customers have invested for years in the tools that run their operations, including monitoring, security, data protection, identity and line-of-business applications. Successful adoption also depends on understanding how existing operational tools integrate with Azure Local and that need is growing now. As more sovereign and regulated workloads move to production on Azure Local, including disconnected and multi-rack deployments, customers need to know before they deploy that their existing tools are supported. That's why we're launching the program at Ignite with a published list of validated solutions and clear validation scope. How we validate We don't treat validation as a logo exercise. Our focus is on technical validation that gives customers greater clarity about supported configurations and integration scenarios. Each partner solution goes through a structured process: Architecture validation: Microsoft and the ISV review the solution architecture for Azure Local, including its deployment pattern, dependencies and integration points. Lab and product validation: Partner solutions undergo testing against defined scenarios and configurations to evaluate their operation on Azure Local. Deployment-specific validation: Validation scope is documented by supported deployment configuration, which may include connected, disconnected operations or multi-rack environments, as applicable. That last point matters. Every validated solution comes with documented information about the capabilities, scenarios and configurations evaluated. We'd rather be precise than broad, because customers make architecture and procurement decisions based on what we publish. Where we are today: 23 validated solutions across four solution categories The solutions are organized into four categories: Category Validated partners Security & Identity F5 BIG-IP Virtual Edition (VE), F5 eBPF Observability (EOB), Fortinet, IBM QRadar, Keycloak, Ping Identity, Splunk, Trellix, WSO2 Data Streaming & AI Confluent (Kafka), MongoDB, Qumulo Business Continuity & Migration Carbonite, Cirrus Data, CloudCasa / Catalogic, Commvault, RiverMeadow, Rubrik, Veeam Application Platform & DevOps EnterpriseDB (EDB), Leostream, Mattermost, PostgreSQL A few points stand out: Resiliency where it matters most. Validated backup, disaster recovery, and migration solutions provide customers with additional options for protecting and moving supported workloads. The capabilities available depend on the selected solution and its validated configuration. Identity for connected and disconnected environment: Five identity providers are validated. The five validated identity providers can support local authentication architectures for Azure Local workloads including certain disconnected scenarios where the required identity dependencies are available locally. Security across network and workload environments. F5 and Fortinet offer capabilities for application delivery, firewalling and deep network visibility. F5 EOB, for example, uses extended Berkeley Packet Filter (eBPF) technology to observe traffic in supported workload environments. Trellix provides endpoint security capabilities for supported workloads, subject to validated deployment configurations. Of the four categories, only Business Continuity & Migration provides workload resiliency directly. The other three contribute security, identity, observability, data and application-platform capabilities that support a well-run environment. We describe each category by the role it is validated to support so customers can design with accurate expectations. From validated products to repeatable solutions The next phase of the program goes beyond validating individual products. We're moving toward repeatable customer solutions. Our goal is to develop validated solution patterns that bring together Azure Local and complementary partner technologies for defined customer scenarios, such as a sovereign security operations center (SOC), a resilient manufacturing site, or a disconnected government deployment. The aim is to help customers evaluate solution compatibility and plan production deployments with greater confidence Get involved Customers: Talk to your Microsoft account team about which validated solutions fit your Azure Local deployment and confirm the validation scope for your configuration. Independent software vendors (ISVs): If your solution supports customers operating in sovereign, edge or regulated environments, we'd like to hear from you about joining the validation program. A platform is only as strong as the ecosystem around it. We're grateful to every partner who has invested engineering time to validate on Azure Local, and we're just getting started. Customers looking for help beyond Azure Local platforms or our partner ISV products can also work with global system integrators (GSIs). Your Microsoft account team can share a list of GSIs with specialized Azure Local expertise that offer services across the solution lifecycle, from design, deployment and integration to ongoing operations as a managed services partner. Validation applies to the specific capabilities and deployment configurations documented for each partner solution. Confirm the scope with your Microsoft or partner contact before making architecture or procurement decisions. For more information: Azure Local573Views1like1CommentJoin Intel and Microsoft at Ignite 2026
At Microsoft Ignite 2026, Intel and Microsoft are coming together to showcase ideas, experts, and real-world impact. Join us to connect with industry leaders and step inside Intel Foundry, explore sovereign cloud and confidential computing, discover security ecosystem innovations, and see how edge AI and intelligent automation connect digital intelligence with the physical world. Attend our sessions Attend our focus sessions and discover how Microsoft and Intel are advancing silicon, security, confidential computing, and edge AI. TUES NOV 17 1:00 PM - 3:00 PM Intel and Microsoft Innovation Lounge @ Dimes Gallery Intel Foundry Open House Step inside Intel Foundry and discover how advanced manufacturing, breakthrough packaging, and intelligent automation bring next-generation silicon to life. TUES NOV 17 2:00 PM - 2:25 PM Theater Session @ Ignite (THRSP1065) Local when it matters. Cloud when it counts. Learn how agentic AI can combine local and cloud capabilities without choosing one over the other. See how Intel and Microsoft are enabling AI experiences that bring together local models for speed, privacy, and efficiency with Azure intelligence for sophisticated reasoning and enterprise scale. TUES NOV 17 3:00 PM - 5:00 PM Intel and Microsoft Innovation Lounge @ Dimes Gallery Sovereignty & Confidential Compute Open House Experience how Intel and Microsoft enable sovereign cloud innovation with hardware-based confidential computing across private and public cloud environments. Join the 15-minute Lightning Talk: Your Cloud. Your Data. Your Control. during the open house. WED NOV 18 11:00 AM - 1:00 PM Intel and Microsoft Innovation Lounge @ Dimes Gallery Security Experience Zone Open House Discover how Intel, Microsoft, and security ecosystem innovations help protect AI agents, safeguard sensitive data, and detect emerging threats. Join the 15-minute Lightning Talk: Secure the Future of Agentic AI on Device during the open house. WED NOV 18 1:00 PM - 4:00 PM Intel and Microsoft Innovation Lounge @ Dimes Gallery Agentic Edge & Robotics Open House Experience how Intel-powered edge AI brings spatial awareness and intelligent automation to the physical world. Join the 15-minute Lightning Talk: AI beyond the screen. Intelligence in motion. during the open house. WED NOV 18 1:40 PM - 2:05 PM Theater Session @ Ignite (THRSP1086) Trust that travels starts on the endpoint AI agents now act, not just read, and that action lands on the endpoint. Join ASUS and Intel to see how cloud policy, platform telemetry, and hardware root of trust combine to strengthen protection when a device is at risk or lost, and why post-quantum readiness starts today, years ahead of your next refresh cycle. Visit Intel booth #5403 Engineering the agent era, together. Stop by the Intel booth at Microsoft Ignite, November 17–20 at the Moscone Center in San Francisco. Focused demos Scaling intelligent agentic AI to where work happens Powering a secure and sovereign cloud Re-imagining Azure infrastructure with Intel innovation In-booth theater sessions Catch Microsoft and Intel talks and demos in the booth theater. Intel-led sessions LIVE theater session: Local When It Matters, Cloud When It Counts Video on-demand session: Intel Assured Supply Chain Daily treats at the booth Tuesday: Boba tea (mid-afternoon) Wednesday: Smoothie bar in the morning and made-to-order crepes in the afternoon Connect with us Connect with Microsoft and Intel experts over drinks and conversation at our Innovation Lounge Happy Hour on Nov 16. The Innovation Lounge will be open from Nov 17 and 18 for our open houses. Happy Hour at the Innovation Lounge MONDAY NOV 16 4:00 PM - 6:00 PM Dimes Gallery | 667 Howard St, San Francisco, CA Innovation Lounge Hours TUESDAY NOV 17 1:00 PM - 5:00 PM WEDNESDAY NOV 18 11:00 AM - 4:00 PM Dimes Gallery | 667 Howard St, San Francisco, CA The Innovation Lounge offers an immersive experience at the nearby Dimes Gallery, with demos, customer briefings and executive engagements. We look forward to seeing you at Microsoft Ignite 2026.506Views1like0CommentsMigrate Arc-registered SQL Server instances to Azure without deploying the Arc agent
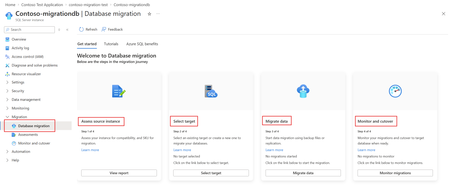
Agent deployment restrictions no longer need to block migration from Arc-registered SQL Server instances. Choose Azure SQL Managed Instance, SQL Server on Azure VMs, or Azure SQL Database, including Hyperscale. Start in the Azure portal, with options to skip assessment and manually add missing databases.258Views0likes0Comments