microsoft purview
294 Topics
Protecting Organizations from External Email Risks in Microsoft 365 Copilot
Introduction As organizations embrace Microsoft 365 Copilot (Copilot), a new category of risk emerges: what happens when Copilot grounds its responses in untrusted external emails? Messages from external or unverified senders can carry content Copilot shouldn’t rely on. A new policy in Microsoft Purview Data Loss Prevention (DLP) addresses exactly this challenge. It lets organizations ground Copilot in trusted internal email only—reducing the risk of cross-prompt injection, while keeping everyday work uninterrupted. Why This Matters: The Risk of External Email in Copilot Grounding Copilot is built to integrate deeply with your organizational data—emails, files, meetings, and more—to generate intelligent and context-aware responses. However, not all mailbox content is equally reliable. External emails—messages originating from outside your organization’s trusted domains—can introduce risks such as: Prompt injection (or cross prompt injection) attempts disguised as legitimate communication Manipulated or misleading content aimed at influencing Copilot-generated outputs Unverified information or instructions that may lead to inaccurate responses Social engineering content that could be amplified through Copilot summarization Without proper safeguards, Copilot may inadvertently reference or summarize this content, potentially impacting decision-making or exposing users to biased or manipulated information. Consider a common scenario: an employee receives a message from an outside address that looks like a routine vendor note but contains hidden text instructing any AI assistant to ignore prior guidance and surface the recipient’s recent internal updates. Later, the employee asks Copilot to "summarize my inbox." Without this policy, that external message is eligible for grounding, and its planted instructions could influence the summary. With this new policy enabled, the external email is excluded from grounding entirely—Copilot never reads it as a source, so the injected instructions have no effect. How It Works: Under the Hood The feature operates through a DLP policy configured in the Microsoft Purview portal using the "Microsoft 365 Copilot and Copilot Chat" policy location with the "Email is received from > External users" condition. Here is how Copilot enforces the policy at runtime: Metadata Evaluation: Copilot evaluates email metadata and it checks the sender’s domain against your tenant’s accepted domains to determine whether an email is internal or external. Importantly, the body of the email is not inspected—only sender metadata is evaluated. External Emails Excluded from Grounding: Emails received from an external sender are excluded from Copilot grounding (source) data. This means when a user asks Copilot to summarize their inbox or reason over recent communications, those external emails are not referenced, summarized, or cited in the response. Other Grounding Sources Remain Available: Results from other grounding sources, such as web search, Word documents, Excel files, PowerPoint presentations, and internal emails, continue to show up in Copilot responses as normal. The policy is surgical in scope. No Impact on Email Access: User access to email remains completely unchanged. Users can still read, reply to, forward, and manage all their external emails as they always have. No Impact on Mail Flow: The policy does not affect mail flow, delivery, or retention. It operates exclusively at the Copilot grounding layer, not at the transport or storage layer. Things to Keep in Mind A few points help set the right expectations before you deploy: Metadata-only evaluation: The policy evaluates sender metadata, not message content. It does not scan or analyze the body of any email. Scoped to the grounding layer: The policy affects only what Copilot can use as a grounding source. It does not change mail flow, delivery, retention, or a user’s ability to access their email. Other sources are unaffected: Internal emails, files, and web results remain available to Copilot, so most everyday scenarios are unchanged. Validate before enforcing: Assess where external email is important to business workflows, then use simulation mode to validate impact and apply the protection only where it is relevant and needed. Key Benefits for Your Organization Mitigates Cross-Prompt Injection Risk: By excluding untrusted external email from Copilot’s grounding data, organizations significantly reduce the attack surface for prompt injection attempts embedded in incoming email. Applies protection where it is needed: Organizations can use the policy when external email presents a meaningful risk to Copilot grounding, while leaving external email available in scenarios where it is relevant and trusted. Ensures Copilot Responses Are Grounded in Trusted Data: Copilot responses reflect only your organization’s internal, verified communications, building greater confidence in Copilot generated insights. Minimal Disruption to Productivity: The feature keeps everyday work uninterrupted. Users retain full access to all their emails, and Copilot continues to function using all other permitted data sources. Simple Policy-Based Administration: Configured through familiar Microsoft Purview DLP policy workflows, making it easy for compliance and security teams to deploy and manage. Transparent User Experience: Users receive clear notifications when organizational policies restrict content, maintaining trust and transparency in the Copilot experience. Prerequisites Before you begin, make sure you have: Permissions: An account with the Compliance Administrator or Data Loss Prevention administrator role, or equivalent permissions to create DLP policies in the Microsoft Purview portal. Accepted domains: Your tenant’s accepted (internal) domains configured correctly, since these determine which senders are treated as internal versus external. How to Set It Up Setting up this protection is straightforward: Sign in to the Microsoft Purview portal (https://purview.microsoft.com). Navigate to Data Loss Prevention > Policies and select + Create policy. Choose the Custom template, then Custom policy. On the Locations page, enable the Microsoft 365 Copilot and Copilot Chat location. Add a rule with the condition "Email is received from," and set the value to External users. Set the action to "Prevent Copilot from processing content". Deploy the policy in simulation (test) mode first, and review the impact to confirm only the intended external email is affected. Once validated, save and activate (enforce) the policy. Conclusion As M365 Copilot becomes central to enterprise productivity, organizations must control what data feeds its responses. This new policy features adds a critical layer of defense, grounding M365 Copilot in trusted internal data while keeping the door open to seamless collaboration. By deploying this DLP policy, you protect more than data—you protect the integrity and trustworthiness of every Copilot-generated insight your organization relies on. Ready to get started? Create the policy in simulation mode today, validate the impact, and enforce it once you’re confident—so every Copilot response your organization relies on is grounded in data you trust. Learn more: https://learn.microsoft.com/en-us/purview/dlp-microsoft365-copilot-location-learn-aboutWhy DLP for External Web Search in Microsoft 365 Copilot Matters?
Introduction Microsoft 365 Copilot (Copilot) grounds its responses in your organizational data—emails, files, chats—and, optionally, the public web. With web search enabled, Copilot fetches real-time information from the Bing search service to deliver richer, more current answers. But what happens when a user’s prompt contains sensitive data such as credit card numbers, passport numbers, or Social Security numbers? That’s where a new feature in Microsoft Purview Data Loss Prevention (DLP) becomes essential: it keeps sensitive information from reaching external web search during Copilot’s query generation, preventing inadvertent data leakage while preserving the productivity benefits of AI. At a Glance In short: admin and user toggles decide whether Copilot can search the web; Microsoft Purview DLP decides what data may leave when it does. . Admin and user toggles are binary on/off controls—they aren’t aware of sensitive data. Prevents Copilot from using external web search as a grounding source for that prompt. It does not block the prompt itself or prevent Copilot from generating a response using permitted sources. It works regardless of your web search configuration,even as a safety net if web search is disabled. The Web Search Landscape in Copilot Before diving into the DLP feature, it’s important to understand the web search controls already available in Copilot and how they interact with this DLP feature. How Web Search Works in Copilot When web search is enabled, Copilot parses user prompts and generates search queries sent to the Bing search service. These generated queries are different from the user’s original prompt—they consist of a few words informed by the prompt. Importantly: The user’s entire prompt is NOT sent to Bing (unless it’s very short) Entire Microsoft 365 files (emails, documents) are NOT included in the search query User and tenant identifiers are removed before queries reach Bing Web search queries are not used to improve Bing, create advertising profiles, or train AI models Queries are treated as customer confidential information Admin Controls for Web Search IT administrators have several options to manage web search through the "Allow web search in Copilot" policy in Cloud Policy service for Microsoft 365: Enabled in Microsoft 365 Copilot and Microsoft 365 Copilot Chat: Web search is available across all Copilot experiences. Users get the Web content toggle to control it personally. Disabled in Microsoft 365 Copilot and Microsoft 365 Copilot Chat: Web search is completely turned off. The Web content toggle is dimmed and unavailable to users. Disabled in Work mode; Enabled in Web mode and Copilot Chat: A hybrid approach where web search is blocked in Work mode (where organizational data is accessed) but available in Web mode and Copilot Chat. User-Level Control: The Web Content Toggle When the admin enables web search, users in Copilot (Work chat) have a "Web content" toggle that is ON by default. Users can turn it off to exclude web content from their Copilot responses. This toggle is NOT available in Copilot Chat. The Gap: Why Admin Controls and User Toggles Are Not Enough Here’s the critical question: What if your organization has web search enabled (for good reasons—better answers, real-time data, improved productivity) but a user inadvertently includes sensitive information in their prompt? Consider these scenarios: A user asks Copilot: "What are the compliance requirements for processing credit card number 4532-XXXX-XXXX-1234?" An employee types: "Find regulations related to passport number AB1234567 for our international transfer." A prompt includes a customer’s Social Security number while asking about tax filing procedures. In each case, if web search is enabled, Copilot might generate a search query informed by the sensitive data in the prompt. Even though Copilot doesn’t send the entire prompt to Bing, the generated search query could still be influenced by or contain fragments of sensitive information. This is the gap that DLP for external web search fills—and it works regardless of which web search configuration option your admin has chosen. The Solution: DLP Policy to Restrict Web Search When Prompts Contain Sensitive Data Microsoft Purview DLP allows you to create a policy that detects when a user’s prompt contains sensitive information types (SITs)—such as credit card numbers, passport numbers, Social Security numbers, or custom SITs defined by your organization—and automatically prevents Copilot from using external web search as a grounding source for that specific prompt. How It Works Real-Time Detection: The DLP policy evaluates each prompt in real time, checking for configured sensitive information types before Copilot generates any web search query. Surgical Blocking: Only the web search component is prevented for that specific prompt. Copilot continues to generate responses using permitted internal Microsoft 365 data sources (emails, files, chats) where applicable. Per-Prompt Enforcement: The restriction applies only to prompts that actually contain sensitive data. The next prompt from the same user (without sensitive data) will use web search normally. Supports various available SIT Types: Works with Microsoft-provided SITs (credit cards, passports, SSNs, etc.) and custom SITs defined by your organization. Clear User Notification: Users are informed that web search was restricted for their prompt due to organizational policy, maintaining transparency. Why This Feature Is Critical, Regardless of Your Web Search Configuration This is the key insight that every security and compliance team must understand: The DLP policy for external web search provides a fundamentally different layer of protection than the admin toggle or user toggle for web search. Scenario 1: Web Search Fully Enabled With web search enabled across all Copilot experiences—the most common setup—the DLP policy acts as a safety net. Normal prompts get full web-grounded answers, but the moment a prompt contains sensitive data, web search is blocked for that prompt alone. External web grounding is prevented for that prompt when the policy detects configured sensitive content. Scenario 2: Web Search Disabled in Work Mode, Enabled in Web Mode Even here, users in Web mode and Copilot Chat still have web search active. The mode-level toggle is binary (on/off) and can’t tell safe prompts from sensitive ones—so if a prompt in these modes contains sensitive data, DLP adds prompt-level, data-aware protection beyond binary web-search controls.. Scenario 3: Web Search Enabled with User Toggle Available Expecting users to toggle off web search before every sensitive prompt is unrealistic—they don’t always know when content counts as sensitive by compliance standards. The DLP policy removes that human error, detecting and blocking automatically on a per-prompt basis. Scenario 4: Even When Web Search Is Fully Disabled Even with web search disabled entirely, the DLP policy adds defense-in-depth. Configurations change, policies get modified, and new users join groups with different settings. If web search is ever re-enabled—intentionally or not—the policy keeps sensitive data protected. Comparing the Controls: A Side-by-Side View Control Scope Granularity Sensitive Data Aware? Admin Policy (Allow web search) Tenant/User Group Binary: On or Off per mode No User Web Content Toggle Individual User Binary: On or Off No DLP: Block Web Search for SITs (Recommended) Per Prompt (Real-Time) Layered defense-in-depth; Conditional Block: Only when SITs detected Yes Key Takeaway: The admin toggle and user toggle control whether web search is available. The DLP policy controls what data can be sent when web search is available. These are complementary, not overlapping controls. Prerequisites Before you configure the policy, make sure you have: Licensing: Microsoft 365 Copilot licenses for your users, plus Microsoft Purview Data Loss Prevention (included with Microsoft 365 E5 or E5 Compliance, or an equivalent plan). Permissions: An account with a role that can create DLP policies for the Copilot location, e.g. Compliance Administrator or the Purview Data Security AI Admin role. Sensitive information types: The Microsoft-provided or custom SITs you want to detect (credit card numbers, passport numbers, SSNs, and so on) identified ahead of time. How to Configure the DLP Policy Follow these steps to set up the protection in Microsoft Purview: Sign in to the Microsoft Purview portal (https://purview.microsoft.com). Go to Data Loss Prevention > Policies and select + Create policy. Select the Custom template, then Custom policy. On the Locations page, set the Microsoft 365 Copilot and Copilot Chat location to On. Add a rule with the "Content contains" > "Sensitive information types" condition and choose the SITs you want to detect (e.g., Credit Card Number, Passport Number, SSN, or custom SITs). In the same rule, set the action to "Prevent Copilot from processing content" > "Performing Web Searches". Save and turn on the policy. Policy Design note: Conditions based on sensitive information types and sensitivity labels must be configured in separate rules within the same policy. Note: DLP policy changes can take up to 4-8 hours to take effect in Copilot. Deploy in simulation (test) mode first to review the impact before you enforce the policy. Real-World Use Case: Contoso Contoso wants employees to use Copilot for productivity and has web search enabled to provide the best possible responses. However, they don’t want sensitive customer data—such as credit card numbers or national identification numbers—to be sent to external web search when Copilot grounds responses on the web. They configure a DLP policy targeting the Microsoft 365 Copilot and Copilot Chat location with a rule that detects their relevant SITs and sets the action to "Prevent Copilot from processing content" > "Performing Web Searches". Result: When a user submits a prompt containing those SITs, Copilot does not send the prompt to external web search. Copilot still returns a response grounded in internal Microsoft 365 data sources where the user has access. For all other prompts, web search works normally. Other prompts can continue to use web search, subject to applicable settings and policies Best Practices Deploy the DLP web search policy alongside your existing web search admin controls for defense-in-depth. Include both Microsoft-provided and custom SITs relevant to your industry and data classification. Use simulation mode first to understand the impact before enforcing the policy. Combine with the "Prevent sensitive information types in prompts" DLP action for comprehensive protection (note: these must be separate rules within the same policy). Regularly review DLP alerts to identify patterns of sensitive data in prompts that may indicate user training needs. Document your layered approach: admin toggle for broad control, DLP for data-aware conditional control. Conclusion The “Restrict Microsoft 365 Copilot from using external web search when prompts contain sensitive data” DLP capability fills a critical gap. Admin policies and user toggles give broad on/off control over web search availability, but they can’t tell a prompt that’s safe to ground on the web from one carrying sensitive information that must never leave your Microsoft 365 boundary. This DLP feature adds intelligent, real-time, per-prompt protection that works regardless of your web search configuration. Users keep the productivity benefits of web-grounded Copilot responses without compromising data security—a clear example of security enabling productivity rather than restricting it. Bottom line: If your organization uses M365 Copilot with web search in any capacity, this DLP policy isn’t optional—it’s essential. References DLP for Microsoft 365 Copilot, Copilot Chat and Cowork: https://learn.microsoft.com/en-us/purview/dlp-microsoft365-copilot-location-learn-about Data, Privacy, and Security for Web Search in Copilot: https://learn.microsoft.com/en-us/microsoft-365/copilot/manage-public-web-accessTeams Private Channels: Group-Based Compliance Model & Purview eDiscovery Considerations
Microsoft Teams Private Channels are undergoing an architectural change that will affect how your organisations uses Microsoft Purview eDiscovery to hold and discovery these messages going forward. In essence, copies of private channel messages will now be stored in the M365 Group mailbox, aligning their storage with how standard and shared channels work today. This shift, due to roll out from early October 2025 to December 2025, brings new benefits (like greatly expanded channel limits and meeting support) and has the potential to impact your Purview eDiscovery searches and legal holds workflows. In this blog post, we’ll break down what’s changing, what remains the same, and provide you with the information you need to review your own eDiscovery processes when working with private channel messages. What’s Changing? Private channel conversation history is moving to a group-based model. Historically, when users posted in a private channel, copies of those messages were stored in each member of the private channel’s Exchange Online mailbox (in a hidden folder). This meant that Microsoft Purview eDiscovery search and hold actions for private channel content had to be scoped to the member’s mailbox, which added complexity. Under the new model rolling out in late 2025, each private channel will get its own dedicated channel mailbox linked to the parent Teams’ M365 group mailbox. In other words, private channel messages will be stored similarly to shared channel messages; where the parent Teams’ M365 group mailbox is targeted in eDiscovery searches and holds, instead of targeting the mailboxes of all members of the private channel. Targeting the parent Teams’ M365 Group mailbox in a search or a hold will extend to all dedicated channel mailboxes for shared and private channels within the team as well as including any standard channels. After the transition, any new messages in a private channel will see the message copy being stored in the channel’s group mailbox, not in users’ mailboxes. Why the change? This aligns the retention and collection of private channel messages to standard and shared channel messages. Instead of having to include separate data sources depending on the type of Teams channel, eDiscovery practitioners can simply target the Team’s M365 Group mailbox and cover all its channel, no matter it’s type. This update will introduce major improvements to private channels themselves. This includes raising the limits on private channels and members, and enabling features that were previously missing: Maximum private channels per team: increasing from 30 to 1000. Maximum members in a private channel: increasing from 250 to 5000. Meeting scheduling in private channels: previously not supported, now allowed under the new model. The table below summarizes the old vs new model for Teams private channel messages: Aspect Before (User Mailbox Model) After (Group Mailbox Model) Message Storage Messages copied into each private channel member’s Exchange Online mailbox. Messages are stored in a channel mailbox associated with the parent Teams’ M365 group mailbox. eDiscovery Search Had to search private channel member’s mailboxes to find channel messages. Search the parent M365 group mailbox for new private channel messages and user mailboxes for any messages that were not migrated to the group mailbox. Legal Hold Placement Apply hold on private channel member’s mailbox to preserve messages. Apply hold on the parent M365 group mailbox. Existing holds may need to include both the M365 group mailbox and members mailboxes to cover new messages and messages that were not migrated to the group mailbox. Things to know about the changes During the migration of Teams private channel messages to the new group-based model, the process will transfer the latest version of each message from the private channel member’s mailbox to the private channel’s dedicated channel mailbox. However, it’s important to note that this process does not include the migration of held message versions; specifically, any messages that were edited or deleted prior to the migration. These held messages, due to a legal hold or retention policy, will remain in the individual user mailboxes where they were originally stored. As such, eDiscovery practitioners should consider, based on their need, including the user mailboxes in their search and hold scopes. Legal Holds for Private Channel Content Before the migration, if you needed to preserve a private channel’s messages, you placed a hold on the mailboxes of each member of the private channel. This ensured each user’s copy of the channel messages was held by the hold. Often, eDiscovery practitioners would also place a hold on the M365 group mailbox to also hold the messages from standard and shared channels After the migration, this workflow changes: you will instead place a hold on the parent Team’s M365 group mailbox that corresponds to the private channel. Before migration: It is recommended to update any existing hold that are intended to preserve private channel messages so that it includes the parent Team’s M365 group mailbox in addition to the private channel members’ mailboxes. This ensures continuity as any new messages (once the channel migrates) will be stored in the group mailbox. After migration: For any new eDiscovery hold involving a private channel, simply add the parent Teams’ M365 group mailbox to the hold. As previously discussed eDiscovery practitioners should consider, based on need, if the hold also needs to include the private channel members mailboxes due to non-migrated content. Any private channel messages currently held in the user mailbox will continue to be preserved by the existing hold, but to hold any future messages sent post migration will require a hold placed on the group mailbox. eDiscovery Search and Collection Performing searches related to private channel messages will change after the migration: Before Migration: To collect private channel messages, you targeted the private channel member’s mailbox as a data source in the search. After migration: The private channel messages will be stored in a channel mailbox associated with the parent Team’s M365 group mailbox. That means you include the Team’s M365 group mailbox as a data source in your search. As previously discussed eDiscovery practitioners should consider, based on need, if the search also needs to include the private channel members mailboxes due to non-migrated content. What Isn’t Changing? It’s important to emphasize that only Teams private channel messages are changing in this rollout. Other content locations in Teams remain as they were, so your existing eDiscovery processes remain unchanged: Standard channel messages: These are been stored in the Teams M365 group mailbox. You will continue to place holds on the Team’s M365 group mailbox for standard channel content and target it in searches to do collections. Shared channel messages: Shared channels messages are stored in a channel mailbox linked to the M365 group mailbox for the Team. You continue to place holds and undertake searches by targeting the M365 group mailbox for the Team that contains the shared channel. Teams chats (1:1 or group chats): Teams chats are stored in each user’s Exchange Online mailbox. For eDiscovery, you will continue to search individual user mailboxes for chats and place holds on user mailboxes to preserve chat content. Files and SharePoint data: Any file shared in teams message or uploaded to a SharePoint site associated with a channel remains as it is today. In conclusion For more information regarding timelines, refer to the to the Microsoft Teams blog post “New enhancements in Private Channels in Microsoft Teams unlock their full potential” as well as checking for updates via the Message Center Post MC1134737.Sensitivity Auto-labelling via Document Property
Why is this needed? Sensitivity labels are generally relevant within an organisation only. If a file is labelled within one environment and then moved to another environment, sensitivity label content markings may be visible, but by default, the applied sensitivity label will not be understood. This can lead to scenarios where information that has been generated externally is not adequately protected. My favourite analogy for these scenarios is to consider the parallels between receiving sensitive information and unpacking groceries. When unpacking groceries, you might sit your grocery bag on a counter or on the floor next to the pantry. You’ll likely then unpack each item, take a look at it and then decide where to place it. Without looking at an item to determine its correct location, you might place it in the wrong location. Porridge might be safe from the kids on the bottom shelf. If you place items that need to be protected, such as chocolate, on the bottom shelf, it’s not likely to last very long. So, I affectionately refer to information that hasn’t been evaluated as ‘porridge’, as until it has been checked, it will end up on the bottom shelf of the pantry where it is quite accessible. Label-based security controls, such as Data Loss Prevention (DLP) policies using conditions of ‘content contains sensitivity label’ will not apply to these items. To ensure the security of any contained sensitive information, we should look for potential clues to its sensitivity and then utilize these clues to ensure that the contained information is adequately protected - We take a closer look at the ‘porridge’, determine whether it’s an item that needs protection and if so, move it to a higher shelf in the pantry so that it’s out of reach for the kids. Effective use of Purview revolves around the use of ‘know your data’ strategies. We should be using as many methods as possible to try to determine the sensitivity of items. This can include the use of Sensitive Information Types (SITs) containing keyword or pattern-based classifiers, trainable classifiers, Exact Data Match, Document fingerprinting, etc. Matching items via SITs present in the items content can be problematic due to false positives. Keywords like ‘Sensitive’ or ‘Protected’ may be mentioned out of context, such as when referring to a classification or an environment. When classifications have been stamped via a property, it allows us to match via context rather than content. We don’t need to guess at an item’s sensitivity if another system has already established what the item’s classification is. These methods are much less prone to false positives. Why isn’t everyone doing this? Document properties are often not considered in Purview deployments. SharePoint metadata management seems to be a dying artform and most compliance or security resources completing Purview configurations don’t have this skill set. There’s also a lack of understanding of the relevance of checking for item properties. Microsoft haven’t helped as the documentation in this space is somewhat lacking and needs to be unpicked via some aligning DLP guidance (Create a DLP policy to protect documents with FCI or other properties). Many of these configurations will also be tied to regional requirements. Document properties being used by systems where I’m from, in Australia, will likely be very different to those used in other parts of the world. In the following sections, we’ll take a look at applicable use cases and walk through how to enable these configurations. Scenarios for use Labelling via document property isn’t for everyone. If your organisation is new to classification or you don’t have external partners that you collaborate with at higher sensitivity levels, then this likely isn’t for you. For those that collaborate heavily and have a shared classification framework, as is often seen across government, this is a must! This approach will also be highly relevant to multi-tenant organisations or conglomerates where information is regularly shared between environments. The following scenarios are examples of where this configuration will be relevant: 1. Migrating from 3 rd party classification tools If an item has been previously stamped by a 3 rd party classification tool, then evaluating its applied document properties will provide a clear picture of its security classification. These properties can then be used in service-based auto-labelling policies to effectively transition items from 3 rd party tools to Microsoft Purview sensitivity labels. As labels are applied to items, they will be brought into scope of label-based controls. 2. Detecting data spill Data spill is a term that is used to define situations where information that is of a higher than permitted security classification land in an environment. Consider a Microsoft 365 tenant that is approved for the storage of Official information but Top Secret files are uploaded to it. Document properties that align with higher than permitted classifications provide us with an almost guaranteed method of identifying spilled items. Pairing this document property with an auto-labelling policy allows for the application of encryption to lock unauthorized users out of the items. Tools like Content Explorer and eDiscovery can then be used to easily perform cleanup activities. If using document properties and auto-labelling for this purpose, keep in mind that you’ll need to create sensitivity labels for higher than permitted classifications in order to catch spilled items. These labels won’t impact usability as you won’t publish them to users. You will, however, need to publish them to a single user or break glass account so that they’re not ignored by auto-labelling. 3. Blocking access by AI tools If your organization was concerned about items with certain properties applied being accessed by generative AI tools, such as Copilot, you could use Auto-labelling to apply a sensitivity label that restricts EXTRACT permissions. You can find some information on this at Microsoft 365 Copilot data protection architecture | Microsoft Learn. This should be relevant for spilled data, but might also be useful in situations where there are certain records that have been marked via properties and which should not be Copilot accessible. 4. External Microsoft Purview Configurations Sensitivity labels are relevant internally only. A label, in its raw form, is essentially a piece of metadata with an ID (or GUID) that we stamp on pieces of information. These GUIDs are understood by your tenant only. If an item marked with a GUID shows up in another Microsoft 365 tenant, the GUID won’t correspond with any of that tenant’s labels or label-based controls. The art in Microsoft Purview lies in interpreting the sensitivity of items based on content markings and other identifiers, so that data security can be maintained. Document properties applied by Purview, such as ClassificationContentMarkingHeaderText are not relevant to a specific tenant, which makes them portable. We can use these properties to help maintain classifications as items move between environments. 5. Utilizing metadata applied by Records Management solutions Some EDRMS, Records or Content Management solutions will apply properties to items. If an item has been previously managed and then stamped with properties, potentially including a security classification, via one of these systems, we could use this information to inform sensitivity label application. 6. 3 rd party classification tools used externally Even if your organisation hasn’t been using 3rd party classification tools, you should consider that partner organisations, such as other Government departments, might be. Evaluating the properties applied by external organisations to items that you receive will allow you to extend protections to these items. If classification tools like Janus or Titus are used in your geography/industry, then you may want to consider checking for their properties. Regarding the use of auto-classification tools Some organisations, particularly those in Government, will have organisational policies that prevent the use of automatic classification capabilities. These policies are intended to ensure that each item is assessed by an actual person for risk of disclosure rather than via an automated service that could be prone to error. However, when auto-labelling is used to interpret and honour existing classifications, we are lowering rather than raising the risk profile. If the item’s existing classification (applied via property) is ignored, the item will be treated as porridge and is likely to be at risk. If auto-labelling is able to identify a high-risk item and apply the relevant label, it will then be within scope of Purview’s data security controls, including label-based DLP, groups and sites data out of place alerting, and potentially even item encryption. The outcome is that, through the use of auto-labelling, we are able to significantly reduce risk of inappropriate or unintended disclosure. Configuration Process Setting up document property-based auto-labelling is fairly straightforward. We need to setup a managed property and then utilize it an auto-labelling policy. Below, I've split this process into 6 steps: Step 1 – Prepare your files In order to make use of document properties, an item with the properties applied will first need to be indexed by SharePoint. SharePoint will record the properties as ‘crawled properties’, which we’ll then need to convert into ‘managed properties’ to make them useful. If you already have items with the relevant properties stored in SharePoint, then they are likely already indexed. If not, you’ll need to upload or create an item or items with the properties applied. For testing, you’ll want to create a file with each property/value combination so that you can confirm that your auto-labelling policies are all working correctly. This could require quite a few files depending on the number of properties you’re looking for. To kick off your crawled property generation though, you could create or upload a single file with the correct properties applied. For example: In the above, I’ve created properties for ClassificationContentMarkingHeaderText and ClassificationContentMarkingFooterText, which you’ll often see applied by Purview when an item has a sensitivity label content marking applied to it. I’ve also included properties to help identify items classified via JanusSeal, Titus and Objective. Step 2 – Index the files After creating or uploading your file, we then need SharePoint to index it. This should happen fairly quickly depending on the size of your environment. I'd expect to wait sometime between 10 minutes and 24 hrs. If you're not in a hurry, then I'd recommend just checking back the next day. You'll know when this has been completed when you head into SharePoint Admin > Search > Managed Search Schema > Crawled Properties and can find your newly indexed properties: Step 3 – Configure managed properties Next, the properties need to be configured as managed properties. To do this, go to SharePoint Admin > More features > Search > Managed Search Schema > Managed Properties. Create a new managed property and give it a name. Note that there are some character restrictions in naming, but you should be able to get it close to your document property name. Set the property’s type to text, select queryable and retrievable. Under ‘mappings to crawled properties’, choose add mapping, search for and select the property indexed from the file property. Note that the crawled property will have the same name as your document property, so there’s no need to browse through all of them: Repeat this so that you have a managed property for each document property that you want to look for. Step 4 – Configure Auto-labelling policies Next up, create some auto-labelling policies. You’ll need one for each label that you want to apply, not one per property as you can check multiple properties within the one auto-labelling policy. - From within Purview, head to Information Protection > Policies > Auto-labelling policies. - Create a new policy using the custom policy template. - Give your policy an appropriate name (e.g. Label PROTECTED via property). - Select the label that you want to apply (e.g. PROTECTED). - Select SharePoint based services (SharePoint and OneDrive). - Name your auto-labelling rules appropriately (e.g. SPO – Contains PROTECTED property) - Enter your conditions as a long string with property and value separated via a colon and multiple entries separated with a comma. For example: ClassificationContentMarkingHeaderText:PROTECTED,ClassificationContentMarkingFooterText:PROTECTED,Objective-Classification:PROTECTED,PMDisplay:PROTECTED,TitusSEC:PROTECTED Note that the properties that you are referencing are the Managed Property rather than the document property. This will be relevant if your managed property ended up having a different name due to character restrictions. After pasting in your string into the UI, the resultant rule should look something like this: When done, you can either leave your policy in simulation mode or save it and then turn it on from the auto-labelling policies screen. Just be aware of any potential impacts, such as accidently locking users out by automatically deploying a label with encryption configuration. You can reduce any potential impact by targeting your auto-labelling policy at a site or set of sites initially and then expanding its scope after testing. Step 5 - Test Testing your configuration will be as easy as uploading or creating a set of files with the relevant document properties in place. Once uploaded, you’ll need to give SharePoint some time to index the items and then the auto-labelling policy some time to apply sensitivity labels to them. To confirm label application, you can head to the document library where your test files are located and enable the sensitivity column. Files that have been auto-labelled will have their label listed: You could also check for auto-labelling activity in Purview via Activity explorer: Step 6 – Expand into DLP If you’ve spent the time setting up managed properties, then you really should consider capitalizing on them in your DLP configurations. DLP policy conditions can be configured in the same manner that we configured Auto-labelling in Step 3 above. The document property also gives us an anchor for DLP conditions that is independent of an item’s sensitivity label. You may wish to consider the following: DLP policies blocking external sharing of items with certain properties applied. This might be handy for situations where auto-labelling hasn’t yet labelled an item. DLP policies blocking the external sharing of items where the applied sensitivity label doesn’t match the applied document property. This could provide an indication of risky label downgrade. You could extend such policies into Insider Risk Management (IRM) by creating IRM policies that are aligned with the above DLP policies. This will allow for document properties to be considered in user risk calculation, which can inform controls like Adaptive Protection. Here's an example of a policy from the DLP rule summary screen that shows conditions of item contains a label or one of our configured document properties: Thanks for reading and I hope this article has been of use. If you have any questions or feedback, please feel free to reach out.4.8KViews9likes9Comments
Making AI Apps Enterprise-Ready with Microsoft Purview and Microsoft Foundry
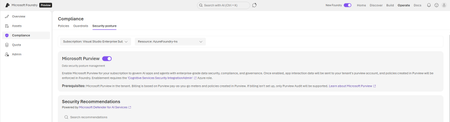
Building AI apps is easy. Shipping them to production is not. Microsoft Foundry lets developers bring powerful AI apps and agents to production in days. But managing safety, security, and compliance for each one quickly becomes the real bottleneck. Every enterprise AI project hits the same wall: security reviews, data classification, audit trails, DLP policies, retention requirements. Teams spend months building custom logging pipelines and governance systems that never quite keep up with the app itself. There is a faster way. Enable Purview & Ship Faster! Microsoft Foundry now includes native integration with Microsoft Purview. When you enable it, every AI interaction in your subscription flows into the same enterprise data governance infrastructure that already protects your Microsoft 365 and Azure data estate. No SDK changes. No custom middleware. No separate audit system to maintain. Here is what you get: Visibility within 24 hours. Data Security Posture Management (DSPM) shows you total interactions, sensitive data detected in prompts and responses, user activity across AI apps, and insider risk scoring. This dashboard exists the moment you flip the toggle. Automatic data classification. The same classification engine that scans your Microsoft 365 tenant now scans AI interactions. Credit card numbers, health information, SSNs, and your custom sensitive information types are all detected automatically. Audit logs you do not have to build. Every AI interaction is logged in the Purview unified audit log. Timestamps, user identity, the AI app involved, files accessed, sensitivity labels applied. When legal needs six months of AI interactions for an investigation, the data is already there. DLP policy enforcement. Configure policies that block prompts containing sensitive information before they reach the model. This uses the same DLP framework you already know. eDiscovery, retention, and communication compliance. Search AI interactions alongside email and Teams messages. Set retention policies by selecting "Enterprise AI apps" as the location. Detect harmful or unauthorized content in prompts. How to Enable Prerequisite: You need the “Azure AI Account Owner” role assigned by your Subscription Owner. Open the Microsoft Foundry portal (make sure you are in the new portal) Select Operate from the top navigation Select Compliance in the left pane Select the Security posture tab Select the Azure Subscription Enable the toggle next to Microsoft Purview Repeat the above steps for other subscriptions By enabling this toggle, data exchanged within Foundry apps and agents' starts flowing to Purview immediately. Purview reports populate within 24 hours. What shows up in Purview? Purview Data Security Admins: Go to the Microsoft Purview portal, open DSPM, and follow the recommendation to setup “Secure interactions from enterprise AI apps” . Navigate to DSPM > Discover > Apps and Agents to review and monitor the Foundry apps built in your organization Navigate to DSPM > Activity Explorer to review the activity on a given agent/application What About Cost? Enabling the integration is free. Audit Standard is included for Foundry apps. You will only be charged for data security policies you setup for governing Foundry data. A Real-World Scenario: The Internal HR Assistant Consider a healthcare company building an internal AI agent for HR questions. The Old Way: The developer team spends six weeks building a custom logging solution to strip PII/PHI from prompts to meet HIPAA requirements. They have to manually demonstrate these logs to compliance before launch. The Foundry Way: The team enables the Purview toggle. Detection: Purview automatically flags if an employee pastes a patient ID into the chat. Retention: The team selects "Enterprise AI Apps" in their retention policy, ensuring all chats are kept for the required legal period. Outcome: The app ships on schedule because Compliance trusts the controls are inherited, not bolted on. Takeaway Microsoft Purview DSPM is a gamechanger for organizations looking to adopt AI responsibly. By integrating with Microsoft Foundry, it provides a comprehensive framework to discover, protect, and govern AI interactions ensuring compliance, reducing risk, and enabling secure innovation. We built this integration because teams kept spending months on compliance controls that already exist in Microsoft's stack. The toggle is there. The capabilities are real. Your security team already trusts Purview. Your compliance team already knows the tools. Enable it. Ship your agent. Let the infrastructure do what infrastructure does best: work in the background while you focus on what your application does. Additional Resources Documentation: Use Microsoft Purview to manage data security & compliance for Microsoft Foundry | Microsoft LearnRegistration Open: Community-Led Purview Lightning Talks
Get ready for an electrifying event! The Microsoft Security Community proudly presents Purview Lightning Talks; an action-packed series featuring your fellow Microsoft users, partners and passionate Microsoft Security community members of all sorts. Each 3-12 minute talk cuts straight to the chase, delivering expert insights, real-world use cases, and even a few game-changing tips and tricks. Don’t miss this opportunity to learn, connect, and be inspired! Secure your spot now for the big day: April 30th at 8am Redmond Time. See agenda details below and follow this blog post (sign in and click the "follow" heart in the upper right) to receive notifications. ❗UPDATE❗This event is expected to last around 2 hours and 15 minutes, due to the incredible number of community sessions that were submitted! 💖 Please see the timing table below broken out into sections of four talks each, and plan to arrive 10 minutes before the section that interests you, OR stay for the whole time! Speakers will be available in the chat to answer your questions; please ask your questions during their session. Spillover Q&A forum links will also be shared. The full session recording will be indexed and posted to Microsoft Security Community YouTube within 24 hours after the event. Bookmark this page or follow this blog post for updates! Agenda Legend ↩️ Data Lifecycle Management 🔐 Information Protection 🚫 Data Loss Prevention (DLP) 🦾 Data Security Posture Management (DSPM) for AI 🤖 Purview for AI 👁️ Insider Risk Management (IRM) 🔍 eDiscovery 📊 Governance 🗒️ Compliance Manager 🛡️ Data Security All times are listed in US Pacific/Redmond Time. Session lengths are rounded to the nearest minute. AGENDA Section 1 - approximately 8:00 am - 8:43 am ↩️ The Day Offboarding Exposed Infinite Retention — Nikki Chapple Length: 10 minutes | Topic: Data Lifecycle Management A routine Purview request led to an unexpected discovery: more than 9,000 orphaned OneDrives and thousands of inactive mailboxes still storing content long after employees had left. This talk explains how a retain-only policy created hidden retention debt and how Adaptive Scopes can help organisations separate active users from leavers to avoid similar pitfalls. 🔐 The Purview Label Engine: Automated Classification, Translation, and co-Documentation for Enterprise Tenants — Michael Kirst-Neshva Length: 12 minutes | Topic: Information Protection Global enterprises face the challenge of implementing uniform data protection standards across borders and languages. In this talk, I’ll present a framework that makes Microsoft Purview labels truly scalable. Discover how to roll out parent and child label logics automatically, manage priorities with a single click, and generate instant compliance documentation for every business unit. 🗒️ What's In My Compliance Manager Toolbox: A Cloud Security Architect's Perspective — Jerrad Dahlager Length: 8 minutes | Topic: Compliance Manager A practical walkthrough of how I use Compliance Manager across real client engagements to map controls, track improvement actions, and simplify multi-framework compliance. No theory, just what works in the field. 🛡️ Stop, Think, Protect: Data Security in Real Life with Purview — Oliver Sahlmann Length: 8 minutes | Topic: Data Security With simple labels and matching DLP policies, Purview offers a practical and accessible way to approach data security. This lightning talk uses a real-life traffic light concept to show how a low barrier to adoption can still drive meaningful protection and awareness. Section 2 - approximately 8:44 am - 9:15 am 🔐 Using Purview to prevent oversharing with AI services — Viktor Hedberg Length: 10 minutes | Topic: Information Protection In this day and age, AI is the big thing. However, Copilot has access to everything you can access, including potentially sensitive data. In this session we will look at how to prevent Copilot to access highly sensitive data, using Information Protection. 🦾 How I Helped My Customers Understand their AI Usage (and protect their sensitive data) — Bram de Jager Length: 5 minutes | Topic: Data Security Posture Management (DSPM) for AI As AI tools explode across the web, many organizations still have no idea what’s actually happening in the browser—where employees type prompts, paste sensitive data, or visit public AI sites outside corporate governance. In this lightning talk, I’ll share how I helped customers shine a light on this issue. We’ll explore how Purview Data Security Posture Management (DSPM) can reveal which AI tools employees use, what types of data they input, and where sensitive information may leak through prompts. I’ll walk through real customer scenario where we detected risky AI usage patterns—such as employees pasting confidential documents into public chatbots. 🔐 Four Labels Max for Daily Use: Which Ones & Why? — Romain Dalle Length: 8 minutes | Topic: Information Protection Sensitivity labels are one of the most critical parts of a Purview Risk and compliance deployment, if not the most critical, because it directly impacts how end-users and business units should allow or restrict themselves to share their business data, internally and externally, on a daily basis. Labels have not other options than being precise, meaningful, and balanced in terms of embedded data security. Setting the right taxonomy is core to success, and is everything but a one-time project. 🚫 Data-driven Endpoint DLP Solution with Advanced Hunting — Tatu Seppälä Length: 8 minutes | Topic: Data Loss Prevention (DLP) This lightning talk shows you how to use KQL queries in advanced hunting to easily build initial sensitive service domain groups for authorized and unauthorized domains based on your organization's usage patterns. The same approach can be used for numerous other similar solution refinement and design purposes. Section 3 - approximately 9:16 am - 9:46 am 🔐 The Purview Hack No One Talks About: Container Sensitivity Labels That Fix Oversharing Fast — Nikki Chapple Length: 10 minutes | Topic: Information Protection Most organizations tackle oversharing with manual fixes, but the fastest solution is often overlooked. In this lightning talk, I show how container sensitivity labels automatically apply the right sharing and collaboration controls, ensuring every new Group, Team or SharePoint site starts secure by default. 🔍 Does M365 Support eDiscovery? — Julian Kusenberg Length: 11 minutes | Topic: eDiscovery A myth-busting session that separates perception from reality when it comes to Microsoft 365 eDiscovery capabilities. 📊 Improving Discovery, Trust, and Reuse of Analytics with Purview Data Products — Craig Wyndowe Length: 5 minutes | Topic: Governance This talk shows how bringing Power BI and Fabric assets into Microsoft Purview Governance Domains and Data Products creates a single, trusted view of enterprise analytics. By connecting reports, semantic models, and underlying data with shared metadata, ownership, and business context, organizations can make existing assets easy to discover and safe to reuse. 🔐 Why You Should Create Your Own Sensitive Information Types (SITs) — Niels Jakobsen Length: 5 minutes | Topic: Information Protection An in depth analysis of why Microsoft SITs are not one-size-fits-all, and how to create your own using what Microsoft has already built for you. Section 4 - approximately 9:47 am-10:30 am 👁️ From Zero to First Signal: Insider Risk Management Prerequisites That Actually Matter — Sathish Veerapandian Length: 8 minutes | Topic: Insider Risk Management (IRM) A focused live demo showing the real world prerequisites required for Microsoft Purview Insider Risk Management to work effectively. This session highlights the critical Entra ID, Intune, Microsoft Defender for Endpoint, and Purview DLP configurations that must be in place before creating IRM policies. 🤖 Securing data in the age of AI — Júlio César Gonçalves Vasconcelos Length: 11 minutes | Topic: Purview for AI AI will transform business as we know it; but without proper governance, it can introduce serious risks. We’ll show you how Microsoft Purview enables organizations to accelerate AI adoption while maintaining security, compliance, and transparency. 🔍 Beyond eDiscovery - Purview DSI for Security Investigation — Susantha Silva Length: 11 minutes | Topic: eDiscovery Most people hear “Microsoft Purview” and immediately think compliance, eDiscovery, or legal holds. But this session highlights Data Security Investigations, showing how DSI lets you take a DLP alert or insider risk signal and turn it into a structured investigation. 🚫 Elevating Purview DLP with a real world use case — Victor Wingsing Length: 14 minutes | Topic: Data Loss Prevention (DLP) Learn how I hardened Microsoft Purview DLP beyond out of the box defaults—closing real world data loss gaps, tuning policies to actual user behavior, and turning noisy alerts into protection that really blocks exfiltration. - Quick Closing/ Resource Sharing2.8KViews7likes2CommentsExtend data security to the network with Microsoft Purview and Microsoft Entra
Protection that keeps up with how data moves in the AI era Enterprise data used to be easier to contain. It lived in files, in apps you managed, within boundaries you controlled. Security teams could focus on endpoints and known systems, and that was often enough. That’s no longer the case. Today, data travels constantly between trusted endpoints and unmanaged web apps, SaaS apps, and most critically, generative AI tools over the network. Employees type and paste sensitive information into prompts, upload work-related files to external services or personal cloud storage, and interact with systems that sit entirely outside the traditional enterprise perimeter. AI has expanded the risk surface for potential enterprise data loss. That’s why Microsoft Purview and Microsoft Entra now integrate to extend data security to the network layer (available in public preview). Traditional data loss prevention (DLP) approaches lack real-time visibility and enforcement, flagging incidents after data has already left the organization. In other cases, vendors rely heavily on physical network appliances that are complex and expensive to deploy, or compute resources that can add significant latency. In the era of AI, that model breaks down quickly. Real-time data protection for how work happens today To adapt to how enterprise data moves in the AI era, we’re announcing the extension of data security to the network layer, powered by Microsoft Purview and Microsoft Entra, now in public preview. This integration brings together data context and identity-aware enforcement to help protect sensitive data in transit, in real time: Detect how sensitive data is shared to shadow AI tools, unmanaged SaaS apps, and personal cloud repositories Help block the sharing of sensitive data in real time based on identity, user activity, and data context, before data leakage occurs Unify investigation workflows by correlating identity, data, and insider risk signals across Purview, Entra, and Defender Prevent employees from sharing proprietary or sensitive organizational data to potentially risky locations such as consumer AI apps. By combining Purview data classification, DLP policies, and insider risk detection with identity-aware enforcement at the network layer through Entra, organizations can dynamically apply protections based on: The sensitivity of the data Who the user is How that user has interacted with sensitive data over time Together, Purview and Entra enable a modern approach to data protection that follows the data to prevent leakage instead of relying on at-rest controls alone. Not only that, but the same Purview classification and policies that you already leverage for the rest of your enterprise data can now be applied consistently across data in motion, at rest, and in use. Learn more in the detailed blog. See the capabilities in action here. Start your free trial of Purview Suite here.Microsoft Fabric Lakehouse sub-item metadata in Microsoft Purview
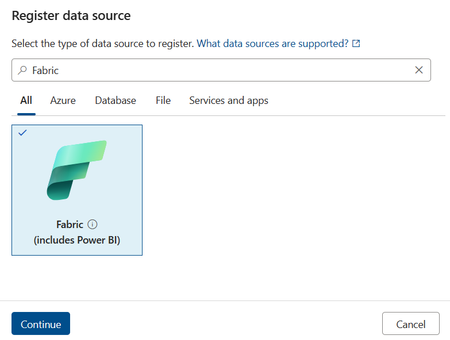
Working at the intersection of data security, engineering, and governance, the Microsoft Purview product team continually explores capabilities that reshape how organizations understand and manage their data estate. One such capability—the ability to scan and extract metadata from Microsoft Fabric Lakehouse—has generated genuine excitement and strong customer demand. We are pleased to announce the GA of Microsoft Fabric Lakehouse sub‑item metadata in Microsoft Purview. The Problem It Solves Anyone who has managed a growing data estate knows the pain: data sources and workspaces multiply, Lakehouse accumulate tables and files, and before long nobody has a clear, centralized picture of what data lives where, what it looks like, or how it flows. Data governance becomes a spreadsheet exercise. Audits become stressful. Trust in data erodes. Microsoft Purview directly addresses this by automatically scanning your Fabric tenant and bringing metadata into the Unified Catalog — without requiring your data teams to manually document anything. What Purview Actually Extracts Here is where it gets interesting from a product perspective. The integration distinguishes between two levels of metadata: Item-level metadata covers the top-level workspace artifacts — the Lakehouse, Warehouses etc. Each of these is treated as a single entity in Purview, inventoried automatically after a scan completes. Sub-item level metadata — and this is the exciting part — now extends into the Lakehouse itself. Purview can now scan tables (Delta format) and files within a Lakehouse, surfacing column-level detail, data types, and structural information directly in the Unified Catalog. For a data steward or data consumer, this is the difference between knowing "a Lakehouse called Sales Gold exists" and knowing "that Lakehouse contains a Delta table called fact orders with 14 columns including order date (date) and revenue (decimal)." That distinction matters enormously for data discoverability, data contracts, and onboarding new consumers onto your data products. Setting It Up — Simpler Than You Think Connecting Purview to your Fabric tenant in the same Microsoft Entra tenancy is refreshingly straightforward. At a high level, the steps are: Register your Fabric tenant as a data source in the Purview Data Map. Create a security group in Microsoft Entra ID, add your Purview Managed Identity (MSI) or service principal to it, and grant that group read-only Admin API access in the Fabric tenant admin portal. Enable the "Enhance admin APIs responses with detailed metadata" setting in the Fabric Admin portal. This is easy to miss but critical — without it, sub-item scanning won't function correctly. Configure and schedule your scan, scoping it to all workspaces or a targeted subset. Support for Managed Identity authentication is now available, which simplifies credential management for teams already invested in Azure's identity infrastructure. One practical note: if you are running multiple Fabric or Power BI scans simultaneously, you may encounter rate limiting. The recommended approach is to stagger scans across different time windows rather than running them in parallel. What You Can Do With It Once scanned, the metadata surfaces in Purview's Unified Catalog, where your teams can browse by source type, workspace, or Fabric experience, and search for specific assets by name, description, or other attributes. This makes it genuinely easy for data consumers to find and evaluate data before requesting access! From a governance standpoint, this unlocks several capabilities that matter to modern data teams: Data discoverability — analysts and data scientists can find Lakehouse tables in the catalog without relying on tribal knowledge or chasing down the engineer who built the pipeline six months ago. Are you ready to setup Microsoft Fabric scan in Microsoft Purview? Head over to the Microsoft Purview Portal and select Data Map. Learn more in the Register Microsoft Fabric in Microsoft Purview documentation.3.2KViews2likes2CommentsMicrosoft Purview enables developers with strong data security across AI apps and agents
Today, developers are at the center of a new wave of innovation—building AI applications and agents that are deeply connected to enterprise data. But with this opportunity comes a new and complex set of security challenges. AI systems operate across cloud platforms, third-party services, and even local and on-premises development environments, interacting dynamically with sensitive data such as customer records, financial information, and intellectual property. Traditional security approaches weren’t designed for this level of scale, autonomy, or fluid data movement—leaving developers to navigate fragmented tools, unclear policies, and the risk of unintentionally exposing sensitive information. At the same time, expectations are rising. Organizations need to ensure that AI applications and agents are compliant, auditable, and secure by default on an enterprise-level—not retrofitted after deployment. But for developers, adding security often means additional complexity, custom integrations, and slower time to market. This tension between speed and control has become one of the biggest barriers to moving AI from experimentation into production. Microsoft Purview is designed to help with this challenge by embedding data security and compliance controls across the development cycle. Purview provides a consistent way to govern how data is accessed, used, and shared—without requiring developers to become security experts. The result is a simpler path to building AI systems that are secure, compliant, and enterprise-ready by design. Extending data security and compliance to local agents and claws Local and endpoint agents, built in platforms such as GitHub Copilot CLI and OpenClaw, introduce a new class of data security challenges as they operate outside traditional control planes and directly on user machines. Unlike cloud systems, these agents can access local files, credentials, terminals, and enterprise apps simultaneously—often moving data across tools and environments. This expands data risks, from sensitive data being unintentionally stored, copied, or shared, to API keys and tokens being exposed, and autonomous workflows triggering data movement without explicit user intent. At the same time, many existing security controls were designed for browser or cloud-based activity, leaving a growing blind spot at the endpoint where agents are increasingly running. The result is a widening gap between how developers build agents to operate locally in the users machines, and how organizations can detect, govern, and protect the data those agents interact with. Microsoft Security and Windows are integrating management and security capabilities directly into the local agents’ development workflow, enabling security as an architectural guarantee rather than an implementation choice. At Build, we are thrilled to be extending Purview visibility and protection capabilities to local agents developed on GitHub Copilot CLI, Claude Code, OpenAI Codex, and OpenClaw - in Public Preview. Unlike traditional cloud applications, these agents operate closer to the data and often create new risks for data exposure. Purview addresses this challenge across all types of agent interactions with a clear, simplified set of scenarios: ▪ Observability: Visibility on Purview Data Security Posture Management (DSPM) across agent inventory, as well as into how local agents interact with sensitive data—across prompts, responses, and actions. ▪ Runtime data protection: Purview Data Loss Prevention (DLP) controls enforced directly into the agent execution flow, inspecting prompts and tool calls in real time to prevent sensitive data exfiltration. ▪ Agentic risk detection: Risky or anomalous agent behaviors detected through Insider Risk Management (IRM) signals, helping teams detect unsafe interactions early. ▪ Audit: Comprehensive, end-to-end logging of all local agent interactions—capturing prompts, responses, data access, and actions for data context. For example, a developer is using a local coding agent to generate code and accidentally includes sensitive credentials in a prompt. AI observability in DSPM surfaces the interaction and shows what data the agent accessed. DLP detects the sensitive data in real time and blocks it from being sent or processed (or sensitive files from being accessed and exfiltrated). At the same time, agentic risk detection flags the session as high risk based on the behavior pattern. All of this activity is captured in audit logs, enabling the security team to investigate and take action quickly. Developers and security teams gain visibility into agent activity and data interactions, while policies prevent sensitive data leakage. This ensures consistent security outcomes across both cloud and endpoint environments, without disrupting developer workflows. Strengthening visibility and controls for Foundry agents Foundry gives developers a central place to build and manage AI agents, but it also creates a need for data security context directly in that workflow—especially as prompts, model interactions, and downstream actions increasingly involve sensitive enterprise data. At Build, we are excited to announce the expansion of the Foundry integration with Purview. This includes Purview DLP runtime controls for prompt processing in Foundry, in Public Preview. As agents and applications built on Foundry increasingly interact with sensitive data, Purview ensures those interactions are governed by trusted controls, identifying Sensitive Information Types (SITs) in real time to detect and protect confidential data embedded in prompts. For example, if a user includes customer PII or financial data in a prompt, Purview can automatically identify the sensitive content and block that prompt from being processed by the model. This ensures that all Foundry apps and agents, regardless of how they’re built or deployed, inherit consistent data protection – allowing organizations to reduce risk of inadvertent data exposure, centralize compliance enforcement across AI workloads, and confidently scale AI adoption knowing sensitive data is protected by design. We’re also building up on the Purview coverage for Foundry shared at the last Microsoft Ignite by announcing Purview insights embedded directly into the Foundry Control Plane, in General Availability, bringing rich data security context to the plane where developers already work. Purview surfaces crucial signals—such as SITs detected in the agentic interactions, % of agentic interactions involving sensitive data, and spread of high-risk users — so Foundry admins can know how AI apps and agents are built in their environment. This shift enables developers to make faster, better decisions in the moment, reducing rework and closing security gaps early on. For customers, the value is clear: stronger security by design and at enterprise scale, accelerated development cycles, and reduced risk of data leaks or compliance issues—without slowing down innovation. Innovating for developers everywhere, at the pace of AI growth Microsoft is also expanding Purview’s reach across the broader developer ecosystem. New integrations help organizations apply consistent oversight to AI tools and platforms developers already use, without adding separate compliance workflows. GitHub Copilot is a critical productivity layer for developers, accelerating how code is written and shipped—making it equally important that developer interactions with GitHub Copilot are governed and secured with the same rigor as enterprise data. Microsoft Purview now extends data governance and compliance capabilities to GitHub Copilot interactions, in Public Preview, enabling GitHub Enterprise customers with Entra SSO to stream audit logs directly into Purview. This brings centralized visibility for AI activity, allowing security and compliance teams to analyze GitHub Copilot agent session activity alongside other AI workloads. With this native integration into GitHub workflows, Purview audits Copilot activity across repositories, pull requests, and developer sessions—ensuring AI-generated code aligns with enterprise data policies, compliance requirements, and secure development standards. By integrating Purview into existing workflows, organizations can govern GitHub AI usage without building parallel pipelines—reducing complexity while ensuring consistent compliance coverage across their entire data estate. Today’s AI agents aren’t built in just one ecosystem—they span custom apps, third-party platforms, and open-source frameworks. Without consistent controls, this creates blind spots where sensitive data can be exposed outside enterprise guardrails. That’s why extending Purview protection beyond Microsoft environments is critical: it ensures developers can apply the same data security, DLP policies, and compliance controls to any agent, anywhere—so innovation can scale without increasing risk. Developers already use Microsoft Purview APIs to embed data protection into enterprise workflows. Today, we’re introducing the Microsoft Purview SDK for .NET — a simple, drop-in toolkit that brings Purview capabilities directly into any application, in Public Preview. Instead of weeks spent wiring APIs, authentication, and error handling, developers can add content scanning, DLP checks, and sensitivity labeling in just a few lines of code. The SDK handles the heavy lifting — including auth, retries, caching, and telemetry — so teams can focus on building experiences. For AI apps and agents built outside of the Microsoft AI platforms, SDK adds built-in support and can evaluate prompts and responses in real time against DLP and content policies — helping prevent data exposure at runtime without custom logic. Designed for both real-time and asynchronous patterns, and for authenticated or anonymous flows, the SDK also feeds activity back into Purview to give security teams centralized visibility and control. The bottom line is- the Microsoft Purview SDK enables developers to build AI apps and agents that are secure and compliant by default — cutting integration time from weeks to days while ensuring data protection scales with AI. The SDK will be available in public preview within the next month. Together, these announcements represent a significant step forward in how developers build secure AI systems. Microsoft Purview is no longer just a data security and compliance solution—it is a first-class layer of the development process by protecting data across AI applications and agents, and enables a bridge between developers and security teams. As AI becomes more agentic, distributed, and deeply connected to enterprise data, the need for built-in security will only grow. With Purview, developers no longer must choose between speed and security—they can build both into every application from the start Getting connected with Microsoft Purview and learn more Learn more about Microsoft Purview on our website and Microsoft Learn. Explore Agent 365. Try Microsoft Purview data security. Learn more about Microsoft Purview SDK.