microsoft foundry sdk
20 Topics
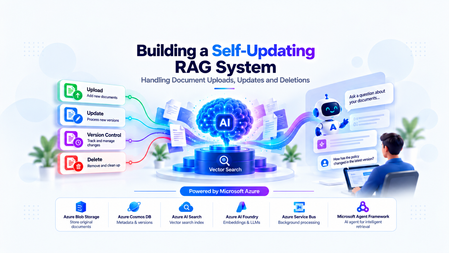
Building a Self-Updating RAG System: Handling Document Uploads, Updates and Deletions
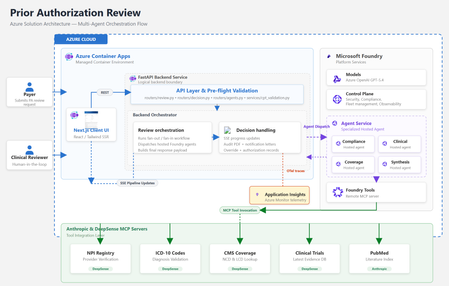
The Hidden Challenge of Production RAG Imagine your organization has deployed an AI assistant to answer questions about employee policies. An employee asks, “How many days of annual leave am I entitled to?” The assistant responds confidently: “15 days.” There is just one problem. The company updated its policy last week. Employees are now entitled to 20 days. The updated PDF was uploaded successfully. The storage service is healthy. The search index is responding. The language model is generating answers without errors. Yet the answer is wrong. This is a different kind of production failure. Nothing appears to be broken at the infrastructure level. The failure lies in the relationship between the source document and the information the AI retrieves. Retrieval-Augmented Generation (RAG) systems depend on external knowledge to ground their responses. But that knowledge is not static. Policies change, contracts get revised, product documentation evolves, and outdated documents are removed. When the underlying documents change, the associated chunks, embeddings, metadata, and search-index entries must be managed accordingly. Otherwise, the system can continue generating plausible answers from information that is no longer valid. Building a RAG pipeline is a retrieval problem. Keeping it correct as data changes is a data lifecycle engineering problem. In this article, we will design a self-updating RAG system that handles document creation, updates, and deletion while addressing asynchronous processing, version consistency, failed jobs, and stale retrieval results. The goal is not simply to index documents automatically. It is to make sure that the right version of the right document is available to the right user when a query is executed. Understand the Problem Before Designing the Architecture A basic RAG pipeline is relatively straightforward: Load a document. Extract its text. Split the text into smaller chunks. Generate an embedding for each chunk. Store the chunks and embeddings in a searchable index. Retrieve relevant chunks when a user asks a question. Pass the retrieved context to a language model to generate an answer. This works well when the document collection is relatively static. The difficulty begins when the source data changes after indexing. Consider three common scenarios. Scenario A: A document is uploaded A new policy is added to the knowledge base. The system must process it and make its content searchable. Until indexing finishes, the document may not be available to the chatbot. Scenario B: A document is updated The original policy allows 15 days of annual leave. A revised policy allows 20 days. If the new version is indexed without correctly deactivating the old version, both versions may appear in search results. The language model may then select the wrong passage or combine conflicting information. Scenario C: A document is deleted An administrator removes a document from the application. However, deleting the original PDF from storage does not automatically delete the corresponding records from Azure AI Search. The content may remain searchable until its indexed chunks are removed. Azure AI Search document deletion itself can also take time to be reflected in index statistics. Microsoft Learn: Delete documents in Azure AI Search These scenarios reveal an important design principle: The source document, its metadata, the background processing jobs, and the search index must be treated as parts of one logical lifecycle—even though they are separate systems. We need a design that can handle failures between these systems without exposing outdated or unauthorized content. Design the System Around Clear Responsibilities Rather than making the upload API responsible for every operation, we can separate the system into a document management path, an asynchronous processing path, and a query path. The Proposed Architecture The design uses the following components: Component Responsibility Azure Blob Storage Stores the original document files Azure Cosmos DB Maintains document metadata, versions, and lifecycle state Azure Service Bus Queues ingestion and deletion jobs Background worker Extracts text, creates chunks, generates embeddings, and updates the index Microsoft Foundry Provides the models used for embedding generation and response generation Azure AI Search Stores searchable document chunks, metadata, and vectors FastAPI Exposes document management and chat APIs Microsoft Agent Framework Supports agentic query workflows when multi-step reasoning or tool use is required The background worker can be implemented as a separate Python service or another suitable compute component. It does not have to be part of the FastAPI process. Why separate these responsibilities? Suppose a user uploads a 100-page contract. The application may need to extract text, split thousands of characters into chunks, generate embeddings, and send multiple indexing requests. Performing all of that synchronously inside the upload request increases latency and makes the API vulnerable to timeouts. Instead, FastAPI accepts the request, persists the document and its metadata, and arranges for the work to be processed asynchronously. The worker performs the expensive operations independently. This allows ingestion to scale separately from query traffic and makes retries easier to manage. The query path remains separate: it retrieves eligible, relevant chunks and uses them to ground the model's response. Establish a source of truth Azure Cosmos DB should hold the authoritative lifecycle metadata in this design. Azure AI Search is the retrieval index, not the authority on whether a document is currently active. For example, a document record might look like this: { "id": "policy-123", "documentId": "policy-123", "currentVersion": 2, "indexedVersion": 1, "status": "PROCESSING", "blobPath": "policies/leave-policy.pdf" } Here, version 2 is the desired version, but version 1 is still the last successfully indexed version. The application must not assume that the latest upload has already become searchable simply because the metadata record has been updated. This distinction between the desired version and the indexed version is central to reliable lifecycle management. Implementing Document Uploads A reliable upload operation involves more than storing a file and sending a message to a queue. It must establish a durable record of the document, identify the version being processed, and ensure that background processing can be retried safely. Step 1: Accept and persist the document When a client uploads a document, FastAPI validates the request, checks the user's permissions, and stores the original file in Azure Blob Storage. The application then creates or updates the document metadata in Cosmos DB. At this stage, the document can be marked as PROCESSING until the ingestion pipeline completes. Step 2: Schedule background processing The system creates an ingestion job containing enough information for the worker to locate the source and determine exactly which version to process. For example: { "operationId": "op-789", "operation": "INGEST", "documentId": "policy-123", "documentVersion": 2, "blobPath": "policies/leave-policy-v2.pdf" } The worker should process the specified version rather than blindly reading whatever file happens to exist at a mutable storage path. For systems that overwrite the same blob path, use blob versioning, an immutable version-specific path, or another mechanism that ensures the worker reads the intended content. Step 3: Extract, chunk, and embed The worker downloads the appropriate document and extracts its text. The extracted text is divided into chunks. Each chunk should carry identifiers that connect it to its parent document and version. For example: { "id": "policy-123-v2-chunk-001", "documentId": "policy-123", "documentVersion": 2, "chunkNumber": 1, "content": "Employees are entitled to 20 days of annual leave." } The worker generates an embedding for each chunk and writes the chunk, its metadata, and its vector to Azure AI Search. The exact index schema depends on the retrieval strategy, embedding dimensions, filtering requirements, and whether hybrid search is used. Step 4: Mark the version as indexed After the worker confirms that all required indexing operations succeeded, it updates the document metadata to record the indexed version and processing status. For example: { "id": "policy-123", "currentVersion": 2, "indexedVersion": 2, "status": "ACTIVE" } This update must be conditional on the document still being at version 2. If a newer version has already been uploaded, the older job must not mark itself as the current version. Why idempotency matters Distributed systems can deliver the same job more than once. A worker may finish indexing but fail before acknowledging the queue message. The message can then be delivered again. If every attempt creates new chunk IDs, duplicate content may accumulate in the index. A practical solution is to derive chunk IDs deterministically from the document ID, version, and chunk identifier. Reprocessing the same version then targets the same index records instead of creating a new set each time. This does not eliminate every failure mode, but it makes repeated indexing much safer. Azure Service Bus supports duplicate detection for eligible tiers, but queue-level duplicate detection is not a substitute for idempotent worker logic. Microsoft Learn: Duplicate detection Updating Documents Without Serving Stale Content Document updates are the most interesting part of the lifecycle because they introduce a consistency problem. Imagine the current leave policy is version 1, allowing 15 days. An administrator uploads version 2, allowing 20 days. The worker starts processing version 2, but embedding generation takes time. Meanwhile, users continue querying the application. What should those users see? There are two common strategies. The right choice depends on whether the system prioritizes availability or strict freshness. Strategy A: Make the new version active after indexing succeeds In this approach, the existing active version remains available while the new version is processed. The workflow is: Create version 2 and mark it as processing. Extract text and generate embeddings for version 2. Index all required version 2 chunks. Verify indexing success. Atomically update the authoritative metadata to make version 2 active. Clean up version 1's indexed chunks asynchronously. This minimizes the time during which the document is unavailable. However, it means that version 1 can remain available while version 2 is being processed. That may be acceptable for some knowledge bases but inappropriate for policies that must become effective immediately. Strategy B: Disable the old version as soon as an update is accepted For high-sensitivity documents, the application can immediately mark the old version as ineligible for retrieval. It then processes the new version and activates it only after successful indexing. The trade-off is that the document may temporarily have no eligible version. The application should return a clear message or use an approved fallback rather than silently serving obsolete information. Prevent old jobs from overwriting new versions Consider this sequence: Version 2 starts processing. Version 3 is uploaded before version 2 finishes. Version 3 finishes indexing first. Version 2 finishes later and attempts to update the metadata. Without version checks, the late version 2 job could incorrectly reactivate stale content. The worker must therefore use conditional updates or optimistic concurrency checks against the authoritative document version. A job may complete its indexing work, but it must not activate its version unless it is still eligible to do so. Handle the lack of a cross-service transaction Cosmos DB and Azure AI Search do not participate in a single distributed transaction in this architecture. A metadata update can succeed while an indexing request fails. An indexing request can succeed while the subsequent metadata update fails. The system should account for these partial failures using: Explicit lifecycle states. Conditional version updates. Retryable and idempotent operations. Periodic reconciliation between metadata and indexed records. The important engineering principle is to make incomplete operations detectable and recoverable, rather than assuming every multi-step workflow succeeds atomically. Deleting Documents Safely Deletion requires special treatment because removing a document from the source does not automatically remove its indexed content. More importantly, waiting for physical index cleanup before preventing retrieval creates a window in which content that should no longer be available may still be returned. Step 1: Make the document ineligible for retrieval When an authorized deletion request arrives, the application updates the authoritative metadata to indicate that the document is being deleted or has been logically deleted. The retrieval path must check that status before using retrieved content. For sensitive documents, this check must happen before the content is added to the LLM context. Merely hiding a document in the user interface is insufficient. Step 2: Schedule physical cleanup The application enqueues a deletion job that identifies the document and all indexed records associated with it. The worker queries or otherwise identifies the corresponding chunk keys and deletes those records from Azure AI Search. The deletion operation should be idempotent. Retrying a deletion for an already-removed chunk should not cause the workflow to fail unnecessarily. Step 3: Verify cleanup The worker checks whether the targeted records have been removed and records the cleanup result. If an operation fails, the job should be retried according to a defined policy. Jobs that continue failing should be sent to a dead-letter queue for investigation and controlled recovery. Azure AI Search supports deleting indexed documents by their document keys. Its documentation also describes how to verify deletion and why index statistics may not update immediately. Microsoft Learn: Delete documents A simplified FastAPI deletion endpoint The following example illustrates the API boundary. The helper functions represent application-specific implementations. from fastapi import FastAPI, HTTPException app = FastAPI() @app.delete("/documents/{document_id}") async def delete_document(document_id: str): document = await get_document_metadata(document_id) if document is None: raise HTTPException( status_code=404, detail="Document not found" ) # Must enforce authorization and use a # concurrency-safe lifecycle transition. await mark_document_deleting(document_id) # The job must be published reliably. await enqueue_deletion_job( document_id=document_id, document_version=document["currentVersion"] ) return { "documentId": document_id, "status": "DELETING" } This is an illustrative example, not a complete production implementation. In particular, the metadata transition and message publication must be coordinated reliably. One approach is the transactional outbox pattern: write the lifecycle change and an outbox event in the same Cosmos DB transactional batch when the data model and partitioning allow it, then publish the event asynchronously. The publisher can retry without losing the intent to schedule cleanup. Deletion must also account for in-flight queries Suppose a query retrieves a document's chunks just before the deletion request is processed. The query might still hold those chunks in memory even after the document is marked deleted. For stricter deletion guarantees, the application needs a defined policy for in-flight requests, cache invalidation, and authorization checks immediately before content is sent to the model. If the requirement is that no response may contain content after a deletion takes effect, that guarantee must explicitly cover requests already in progress. Physical cleanup and retrieval eligibility are separate responsibilities. Both matter. Coordinate Lifecycle Changes Reliably Once ingestion and deletion run asynchronously, the queue becomes part of the system's correctness model. A production worker should not assume that each message is delivered exactly once or that messages for a particular document always finish in order. Design for at-least-once processing A practical worker lifecycle is: Receive a message using a lock-based delivery mode. Validate the document ID, version, and operation. Check whether the operation is still eligible to run. Perform idempotent indexing or deletion. Update lifecycle metadata conditionally. Acknowledge the message only after successful processing. If the worker fails before acknowledging the message, the message may be delivered again. That is expected behavior and should be handled by the design. Add retry and dead-letter policies Not all failures should be treated equally. Transient network errors or throttling may succeed after a delay. Invalid documents, unsupported file formats, and persistent schema mismatches may require manual investigation. The system should use bounded retries with appropriate backoff, record meaningful failure details, and route repeatedly failing messages to a dead-letter queue. Use reconciliation as a safety net Even with retries, the system needs a way to detect inconsistencies that escaped the normal workflow. A reconciliation job can compare authoritative metadata against indexed document versions and lifecycle states. It can identify cases such as: A document marked active whose current version is not fully indexed. Chunks belonging to an obsolete version. Search records for a logically deleted document. An operation that remained in a processing state beyond its expected duration. Reconciliation should repair only states it can safely determine. It should not reactivate a version simply because its chunks exist in the index. For applications using Azure Cosmos DB change feed, document metadata changes can also drive incremental background processing. The change feed captures inserts and updates in its standard latest-version mode; capturing deletions requires selecting and configuring an appropriate supported mode or using explicit lifecycle events. Microsoft Learn: Cosmos DB change feed Where Microsoft Agent Framework Fits A common mistake is to assume that every part of an agentic RAG application should be implemented as an AI agent. Document uploads, version transitions, embedding generation, and index deletion are predictable operations with explicit success and failure conditions. These are generally best implemented with conventional application logic and background workers. Microsoft Agent Framework becomes useful when the query itself requires multi-step reasoning, tool selection, or orchestration. For example, a user might ask: “Compare the current leave policy with the previous version and explain the changes that affect employees.” An agent could use approved tools to retrieve the current policy and the permitted historical version, compare the relevant passages, and generate an evidence-based explanation. The application must still control which documents and versions are eligible for retrieval. The agent should not independently decide whether a deleted document is authorized for use. This distinction is important: deterministic workflows protect data integrity; agentic workflows help solve tasks that benefit from reasoning and tool use. Microsoft Agent Framework provides both agent and workflow capabilities, allowing developers to choose an appropriate orchestration model for the task. Microsoft Agent Framework documentation Production Readiness: What Should We Measure? A pipeline that successfully indexes a document once is not necessarily production-ready. The system needs observable lifecycle states and measurable recovery behavior. Area What to validate Ingestion Can a failed upload or indexing job be retried safely? Idempotency Does processing the same document version twice create duplicate records? Version consistency Can a delayed job reactivate an older version? Deletion Can logically deleted content enter the LLM context? Authorization Are tenant and document-level permissions enforced during retrieval? Recovery Can reconciliation detect and repair partial failures? Observability Can operators identify stuck jobs, indexing failures, and cleanup delays? Performance How long does it take for an accepted update to become searchable? Useful operational metrics include ingestion success rate, queue age, indexing latency, retry counts, dead-letter queue depth, time spent in each lifecycle state, and deletion cleanup latency. Also test race conditions deliberately. Upload a new version while an earlier job is still running. Delete a document while a query is in flight. Simulate an indexing failure after metadata has been updated. Restart a worker after it has indexed content but before it acknowledges the message. These tests expose the problems that a happy-path demonstration will not reveal. Bringing It All Together Keeping a RAG system accurate is not simply a matter of re-running embeddings whenever a file changes. It requires a deliberate lifecycle design that connects source documents, versioned metadata, asynchronous processing, search-index operations, and retrieval-time authorization. Azure Blob Storage can preserve the source documents, Cosmos DB can track authoritative lifecycle state, Service Bus can distribute background work, and Azure AI Search can provide retrieval. Microsoft Foundry supplies the models, while Microsoft Agent Framework can support the parts of the application that genuinely benefit from agentic orchestration. The architecture becomes reliable when it assumes that failures will happen: messages may be repeated, jobs may finish out of order, index operations may partially succeed, and cleanup may take time. Version checks, idempotent operations, explicit lifecycle states, reliable event publication, and reconciliation turn those failure modes into manageable engineering problems. The objective is not merely to keep the index populated. It is to ensure that every answer is grounded in information that is current, eligible, and authorized for the user who asked the question. Further Reading Azure AI Search: Delete documents Azure Cosmos DB: Change feed Azure Service Bus: Duplicate detection Microsoft Agent Framework I'd be interested to hear from engineers building production RAG systems: how do you coordinate document updates and deletions across your source of truth and search index?717Views4likes2Comments
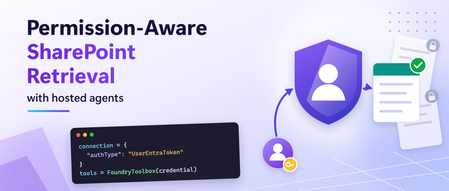
Building Permission-Aware Hosted Agents for SharePoint in Foundry Agent Service
Organizations increasingly publish agents to Microsoft Teams and Microsoft 365 Copilot that answer questions using internal knowledge sources. SharePoint is a very common source for this information; where many times access is different for every user. A finance employee, HR employee, and project manager may all ask the same question but have access to different documents. When an agent is hosted in Foundry Agent Service, the agent itself runs under its own identity. This creates an important challenge: how can retrieval respect the permissions of the person asking the question rather than the permissions of the agent? This post shows how to do that with built-in capabilities: a Foundry IQ knowledge base with a remote SharePoint knowledge source, connected to the agent through the Foundry toolbox. Foundry IQ is the knowledge layer for agents, built on Azure AI Search. A knowledge base is its top-level resource: it orchestrates retrieval across one or more knowledge sources, which are connections to indexed or remote content. In this solution the only knowledge source is SharePoint, queried live as the signed-in user through the On-Behalf-Of (OBO) pattern, and the agent reaches the knowledge base through a toolbox. Why agent identity is not enough Hosted agents run as their own agent identity. When Foundry Agent Service runs your Microsoft Agent Framework agent as a hosted agent, it authenticates as the agent, not as the person chatting with it. SharePoint permissions belong to users. Two people asking the same question may be allowed to see different documents. So grounded answers (RAG) need per-user retrieval. If retrieval runs as the agent, SharePoint can't check the asking user's access. Results are either empty or not filtered for that user. Therefore the user's token has to reach the retrieval step. Changing the model or the prompt can't fix this. The architecture has to carry the user's identity all the way to SharePoint. This is the key architectural principle behind this solution. The hosted agent keeps using its own identity for model inference, while retrieval runs with the signed-in user's identity. What you'll build A hosted agent, published to Microsoft Teams, that answers from one or more SharePoint sites. Answers limited to what each user can open in SharePoint, using On-Behalf-Of (identity passthrough) retrieval. Clickable citations back to the source documents. Built on out-of-the-box Foundry IQ and Foundry toolbox capabilities: no custom server to host, and no client secrets in the retrieval path. The complete sample is on GitHub: SharePoint knowledge base sample The sample repository contains the setup scripts and agent code used in this walkthrough. Before we run them, let’s trace how the user’s identity flows through the architecture and why it matters for permission trimming. Note: Remote SharePoint knowledge sources in Foundry IQ were in preview at the time this article was written. How it works The agent runs as itself. Retrieval runs as the user. Three pieces carry the user's identity end to end: FoundryToolbox in the agent sends the per-request call ID with each tool call, so Foundry knows which user the call belongs to. A UserEntraToken connection passes that user's Microsoft Entra ID token to the Foundry IQ knowledge base on Azure AI Search. This is identity passthrough (On-Behalf-Of): every request downstream runs as the signed-in user. A remote SharePoint knowledge source queries SharePoint live through the Microsoft 365 Copilot Retrieval API as that user, scoped to the site paths you choose. Nothing is copied into an index. Why not Work IQ? Work IQ is a good choice when an agent should reason over a user’s broader Microsoft 365 work context. This pattern is intended for scenarios where the agent should answer from specific SharePoint sites, treating those sites as a defined knowledge boundary. Use Work IQ when broad Microsoft 365 context is appropriate. Use this pattern when retrieval should be limited to selected SharePoint content. The right choice depends on the scope and behavior your scenario requires. Before building the sample, let’s check the services and permissions the setup requires. Before you start You need a Foundry project with a model deployment, an Azure AI Search service and a SharePoint site containing the content you want the agent to use.The Search service must be in a region that supports agentic retrieval, in the same Microsoft Entra tenant as Microsoft 365. Make sure the following permissions are in place: Role Required permissions Setup user Search Service Contributor on the Azure AI Search service, and rights to create connections and toolboxes in the Foundry project End users Search Index Data Reader on the Search service, Foundry Agent Consumer on the agent, a Microsoft 365 Copilot licence, and access to the documents in SharePoint With the concepts established, let's build the end-to-end solution. Build it in four steps Clone the sample repository before running the setup scripts. The commands below assume you are running them from the repository root: git clone https://github.com/Heenanl/hosted-agent-sharepoint-knowledge-base.git Set-Location hosted-agent-sharepoint-knowledge-base python -m pip install -r setup/requirements.txt Copy-Item setup/.env.example setup/.env Fill in setup/.env with your Foundry project, Azure AI Search, and SharePoint knowledge source values. The repository README contains the complete configuration and deployment instructions. The steps below highlight the key settings and decisions. 1. Create the knowledge base Run setup/create_knowledge_base.py . It creates a remote SharePoint knowledge source and a knowledge base. The setting that limits retrieval to your site is: "filterExpression": "Path:\"https://<TENANT>.sharepoint.com/sites/<SITE>/\"" 2. Connect it to Foundry with the user's identity Run setup/create_connection.py . It registers the knowledge base's MCP endpoint as a Foundry connection. The setting that matters most in the whole architecture is: "authType": "UserEntraToken" With UserEntraToken , Foundry forwards the signed-in user's token instead of a shared identity, so SharePoint can apply that user's permissions. Then run setup/create_toolbox.py . It wraps the connection in a toolbox that exposes only knowledge_base_retrieve . 3. Build the agent The agent itself is small. The key line is tools=FoundryToolbox(credential) : agent = Agent( client=FoundryChatClient(project_endpoint=endpoint, model=model, credential=credential), instructions=INSTRUCTIONS, tools=FoundryToolbox(credential), ) Two instructions in the agent's prompt made a visible difference in Teams: Cite every source as a markdown link, using the Title and uri fields the tool returns. If the tool returns nothing relevant, say that the available sources do not contain the answer. Do not guess. The first gives users clickable citations. The second stops the model from filling gaps when a user can't see a document. 4. Deploy and publish to Teams Follow the sample README to initialize the agent with azd ai agent init , set the required environment values, and deploy it with azd up . After deployment, publish the agent to Microsoft Teams and Microsoft 365 Copilot. The repository includes a publishing script, including support for Foundry projects on a private network. Users do not need a separate, tool-specific consent flow. Prove the permission trimming A good answer doesn't prove the right permissions were used. Test with two users and one document that only one of them can open: User SharePoint access Result in Teams A Can open the document Answer from the document, with a citation link B Cannot open the document "The available sources do not contain the answer." In our testing, both users' requests reached the knowledge base, but only user A got content from the document, because the Microsoft 365 Copilot Retrieval API ran as each user. Run the test in separate conversations, and repeat it after any permission change. Common pitfalls Using a managed identity for the connection The retrieval runs as the agent's managed identity, so SharePoint has no user to check permissions against. In our testing, a ProjectManagedIdentity connection failed with x-ms-query-source-authorization is invalid . Use UserEntraToken . Forgetting Search Index Data Reader Because each user's own token reaches Azure AI Search, every user needs this role, not just you. Otherwise the user can reach the agent, but retrieval fails for them. Assign the role to a security group once, replacing SEARCH_SERVICE , RESOURCE_GROUP and $GROUP_ID with your own values: $SEARCH_ID = az search service show -n SEARCH_SERVICE -g RESOURCE_GROUP --query id -o tsv az role assignment create --assignee $GROUP_ID --role 'Search Index Data Reader' --scope $SEARCH_ID Using a custom MCP client instead of FoundryToolbox A hand-built MCP client that attaches only the agent's credential drops the per-request call ID, which links a tool call to its user. In our testing with another OAuth tool, every user ended up running as whoever had consented first. FoundryToolbox fixed it. Building a custom MCP proxy A custom On-Behalf-Of (OBO) proxy can work, but you then own its hosting, secrets, token checks and patching. The knowledge base gives the same per-user retrieval with built-in components. Once the setup and permission checks are complete, use the sample repository to try the full flow in your own environment. The links below provide more detail on the Foundry IQ and toolbox building blocks. Get started Try it: clone the sample and follow the README end to end. Learn the building blocks: Create a remote SharePoint knowledge source Connect a Foundry IQ knowledge base to Foundry Agent Service Toolbox authentication What is a Foundry toolbox? Use a toolbox with a hosted agent Validate before rollout: use the two-user isolation checklist. Share your scenario: open an issue on the repo. Acknowledgements Thanks to Mahya Gheini and Linda Li from the Microsoft Foundry product team for their guidance on toolboxes and knowledge bases.717Views1like2CommentsMicrosoft Foundry Guardrails Getting in Your Way? Here’s How to Dial Them Down
How This All Started So here’s the story. I just got back from a trip and had a pile of footage sitting on my laptop. Being the lazy (sorry, efficient) person I am, I fired up OpenCode and asked GPT-6 Astra, running on Microsoft Foundry, to cut me a travelogue. Nothing fancy: under two minutes, nice lighting, clean transitions, no cringy effects, a quick QA before showing me, and the output in its own folder. Easy, right? Nope. This is what I got instead: “Image processing blocked due to content policy violation.” Seriously? It’s holiday footage! Nothing even remotely dodgy in there. This is a classic false positive from the default guardrails, and the good news is it’s totally fixable. Let me show you how. My Setup Quick context before we dive in: I’ve got two models deployed on Microsoft Foundry, gpt-6-astra and gpt-6-sol. Both were running on Microsoft’s out-of-the-box guardrail. Step 1: Find the Guardrails Page Head over to the Microsoft Foundry portal, click Build, then hit Guardrails in the left menu. You’ll see three guardrails that Microsoft gives you by default: Microsoft.Default, Microsoft.DefaultV2 and Microsoft.MAIDefault. Microsoft.DefaultV2 is the one every new deployment gets, which is why it’s sitting on both of my models. Here’s the catch: you can’t edit or delete these Microsoft-managed defaults. So instead of tweaking them, we’re going to build our own guardrail and swap it in. Step 2: Create Your Own Guardrail Smash that "Create" button and you’ll land on the Create guardrail page. This is where all the knobs and switches live: Every control has three bits: the risk type, the intervention point (does it check what you send in, what the model spits out, or both?) and the action. The magic trick for loosening things up is flipping the action from Block to Annotate. With Annotate, Foundry still scans the content and tags it in the API response, but it stops slamming the door on your request. So What Does Each Setting Actually Do? Before you go on a switching-off spree, it’s worth knowing what each of these does and what you’re giving up when you loosen it. Here’s the quick tour: Jailbreak: This one catches prompts trying to trick the model into ignoring its rules. On Block, those prompts get rejected outright. On Annotate, they go through with a flag. Turn it off completely and you’re trusting the model’s own training to keep it in line. Network (egress rules): Controls which outbound calls a hosted agent is allowed to make. As the portal points out, it only applies to hosted agents, so for plain model deployments like mine it doesn’t change a thing. Indirect prompt injections: Watches user input and tool responses (files, docs, web pages the model reads) for sneaky instructions someone has planted. Leave it on and your agents are protected when they read outside content; switch it off and a dodgy file could quietly hijack your model. For an agentic tool like OpenCode, which reads files and runs shell commands, I’d honestly keep this one on, even if it’s just on Annotate. Spotlighting (Preview): Tags external content inside the prompt so the model can tell your real instructions apart from random untrusted data. Think of it as an extra seatbelt against indirect attacks. Content harms (Hate, Sexual, Self-harm, Violence): Each of these has a severity slider that starts at Medium blocking, meaning anything rated medium or higher gets blocked. Slide it down to Lowest blocking and only the really nasty stuff gets stopped, which kills off most false positives like mine. The asterisk means these four are mandatory: you can turn the dial down, but you can’t switch them off. Blocklists: Want to ban specific words or phrases, like profanity or your competitor’s name? This is where you do it. It’s off by default. Protected material for code and text: Checks whether the model is about to spit out known copyrighted text (song lyrics, articles and so on) or code lifted from public repos. Block stops it; Annotate lets it through with a flag. Switch it off and you’re rolling the dice on your app reproducing someone else’s copyrighted work. Step 3: Pick Your Models Hit Next and Foundry asks which agents and models you want this guardrail on. Any model you’ve already deployed in your project shows up here. For me that’s gpt-6-astra and gpt-6-sol, so I ticked both. Step 4: Name It and Pick a Streaming Mode One more Next and you’re on the Review page. Give your guardrail a name (I went with NoGuardrails, because subtlety isn’t my thing) and pick a streaming mode. You’ve got two choices: Default: Foundry buffers the response and runs it through the guardrail before each chunk goes out. Nothing reaches the user until it’s been checked. Safest option, but you’ll feel a bit of lag when streaming. Asynchronous: Content streams back the moment it’s generated, with the filters running in the background. Much snappier, but flagged content might flash up briefly before the filter catches it, so your app has to clean up after the fact. Microsoft pitches this for low-latency stuff like internal dev tools, which is exactly my use case. Give the summary a quick once-over, then click Create. Done! Did It Work? Yep! With my shiny new guardrail in place, I fired off the exact same request, this time to GPT-6 Sol. And boom: no more content policy error. The model went straight to work scanning my footage and putting the video together. Wrapping Up Look, Microsoft’s default guardrails are a solid starting point, but they can be a bit trigger-happy when you’re doing perfectly legit stuff like video editing, creative work or internal tooling. Since you can’t touch the defaults, the trick is to roll your own: flip Block to Annotate where it makes sense, drag those content harm sliders down, pick the streaming mode that fits your app, and assign it to your deployments. That’s it! One friendly word of warning though: with great power comes great responsibility. Only loosen what you actually need, keep things like indirect prompt injection detection switched on for any agent that reads files or browses the web, and think twice before doing this on anything customer-facing. And if you want to go further than the portal lets you, like switching content filters off completely, you’ll need to apply to Microsoft for approval first. Happy building!482Views1like2Comments
Your Agents Need More Than a Place to Run
In architecture reviews with enterprise teams moving their first agentic applications toward production, I often hear the same plan: the team has containerized their agent and intends to run it on the managed Kubernetes cluster the organization already trusts. The reasoning is sensible, since the platform team knows the tooling and security has approved the network model, and for the first use case or two it is often the right call. Having watched this unfold in my years leading AgenticAI customer engineers and forward deployed engineers, and now helping customers reach production on Azure, I want to describe what happens next, before leaders commit rather than after. One thing to note is Azure supports multiple ways to build and operate agents. Foundry Agent Service provides an integrated managed runtime around your agent code. Azure Kubernetes Service supports teams that need Kubernetes-level control or want to extend an established platform, while Azure Container Apps provides managed container hosting. These services can work together. The decision is which capabilities and responsibilities best fit the workload. Where the cluster is the right answer A stateless retrieval application, a document extraction pipeline, or a classification job is a web service that happens to call a model, and a container platform runs web services well. A large retail customer of mine ran an invoice extraction agent on containers for over a year with almost no issues, and I never suggested they move it. The cluster remains the right home for several other situations as well. LLM invocations embedded inside existing microservices, event driven, or batch pipelines fit container platforms naturally. Genuine constraints such as air-gapped or sovereign environment, regions where a managed service is not yet offered are a good reason to run your own stack, and strong engineering team that already operates at that level can be a real asset. Even when the agents themselves move to a managed runtime, the tool servers, business APIs, and data services those agents call, often stay on your cluster, so they are complementary far more often than they are competitors. The problem is that these early wins can make agents seem like just another workload. Where the wheels come off The first failure is the state. A research agent that plans, searches, and synthesizes for ninety minutes is a long-running stateful process, while a Kubernetes pod is a disposable container the scheduler may restart at any time. A financial services team I worked with lost costly research run to a routine node upgrade, and responded as capable engineers do by building checkpointing, a durable store, and a resume mechanism. It worked, but they now owned a piece of infrastructure they had to keep correct as their agent's framework changed beneath it. A managed agent runtime absorbs this. Hosted agents in Foundry Agent Service, as one example, give every session a VM-isolated sandbox with a persistent file system, a durable state store that survives crashes and restarts and can hold checkpoints for frameworks such as LangGraph or Microsoft Agent Framework, and a resilient execution mode that recovers long-running work after a process interruption. The second is the human-in-the-loop. A commercial insurance customer’s claims agent needed sign-off from an adjuster and sometimes a second reviewer, with days between steps. Stopping an agent cleanly at the moment it needs a decision, holding its full session for four days without paying to keep it running, and resuming it correctly when the approval arrives is not something a container orchestrator gives out the box. The team built agent session suspend and resume, a queue, a durable state store, notifications, and an approval interface, and ended up with a small workflow engine nobody had planned to own. In hosted agents, an idle session is deprovisioned with its state persisted and restored onto fresh compute when the same session ID returns, so an agent waiting on an approval cost nothing while it waits, and sessions are retained for up to thirty days of inactivity. The approval experience remains yours to design, which is where your engineers' time should go. The third is multi-turn conversation, which quietly pushes teams into building their own context management system. The first version appends each turn to history, and within few turns the history outgrows the context window while cost and latency climb. So, the team adds truncation, then summarization, then retrieval of earlier turns, then per-user and per-tenant scoping, then expiry and deletion rules for privacy. An industrial customer's safety compliance assistant, with conversations stretching across days, followed exactly this path and ended up with a bespoke thread store and summarization pipeline nobody had budgeted for. Its first serious incident came when a summary silently dropped a compliance-relevant instruction. With the Responses protocol in hosted agents in Foundry, conversation history is a durable, platform-managed record keyed by a conversation ID and reachable from any channel, so the thread store is no longer yours to build, although deciding what to summarize or retrieve remains a design choice for your agent. The fourth is identity. On a cluster, the path of least resistance is a shared service account, and in one review a security architect asked which actions had been taken on behalf of which user, only to learn that the logs could not say. Hosted agents create a dedicated Microsoft Entra agent identity for each agent at deploy time, use on-behalf-of flows to act with the user's delegated permissions in interactive scenarios and the agent's own identity in autonomous ones, and keep the agent identifiable for audit in both cases. The fifth is per-user session isolation, which is the difference between an agent that serves many people and an agent that mixes them up. Agents read files, run code, and hold working data, and on a shared pod the default is that many users share a process, a file system, and often a cache. Giving every user session its own sandboxed environment and storage, so that one person's documents and intermediate results can never surface in another's, means engineering hard isolation boundaries and proving them to your security team. Hosted agents make a VM-isolated sandbox per session the default, and their durable state store can partition items per end user, so one store is safe to share across the users of a multitenant agent. And lastly, Evaluation and optimization are where the gap widens. The largest difference between teams that scale and those that stall is evaluation. Because agents are probabilistic and multi-step, staging tests often miss failures such as a wrong tool choice or a policy violation deep in a task. One customer’s agent passed every offline check but degraded unnoticed for weeks after a model update because evaluation stopped at release. Mature teams continuously evaluate production traces, combine automated judges with sampled human review, and red-team regularly.Once quality is measurable, teams can deliberately balance prompts, models, tools, latency, and cost. One team cut per-task cost by routing simple steps to smaller models after evaluation confirmed quality held. Self-built stacks require teams to assemble and maintain tracing, datasets, judges, and release gates. Hosted agents instead combines default OpenTelemetry traces with continuous evaluation, adversarial testing, and datasets generated from agent instructions. Staged closed-loop optimization uses those traces to improve instructions, tool descriptions, and model selection without extra plumbing. The real cost is the velocity gap Leaders usually expect me to quantify the initial build, and that is the smaller number. A team of four building the first agent often becomes ten or twelve within a year, and a growing share of them are maintaining a runtime for agents rather than building agents that serve the business. The enterprise has quietly created an internal agent infrastructure company in a field where the patterns for memory, tools, evaluation, and safety are rewritten every few months, while hyperscalers put hundreds of engineers on exactly this problem and ship at a cadence no single platform group can match. Foundry Agent Service, for instance, bundle content safety guardrails into the runtime and route outbound traffic through a customer virtual network, capabilities that platform teams otherwise assemble one integration at a time. This plumbing does not differentiate your organization, so the question is whether your scarcest engineers should spend years on it or on the workflows, data, and judgment only your company has. This is also why the technology companies held up as examples are a poor template. Many built their own runtimes because managed options did not yet exist and had large platform organizations to carry the load. Even they tend to invest in a custom runtime for the first handful of use cases and then migrate as managed services mature, because the maintenance burden compounds while the strategic value of owning the plumbing does not. What I would do as the leader I am not arguing against Kubernetes or for moving everything tomorrow. Comparable managed runtimes exist across the hyperscalers, and I use hosted agents as the running example only because it is the one I know best from the inside. Managed agent services are still maturing, some workloads have real data residency or customization needs, and abstraction always constrains something. What I am arguing for is a deliberate choice for each use case, guided by three questions: whether the agent must outlive a single request by running long, waiting on humans, or remembering across sessions whether it must act with its own identity, auditable delegation, and policy enforcement whether your team would be building anything a managed service already provides, and who will still maintain it in two years. Key takeaways Match the runtime to the workload. Containers on your existing cluster suit stateless, short-lived agents, while long-running, human-in-the-loop, and memory-dependent agents need capabilities your platform team was never hired to build. Count the hidden team. The real cost of self-hosting is the growing group of engineers maintaining state, identity, memory, guardrails, and tracing instead of solving business problems. Make evaluation continuous and connected to production traces. Pre-release testing alone will miss the drift and trajectory failures that hurt you, and optimization of quality, cost, and latency depends on that evaluation data. Follow the pattern of the leaders, not their early architecture. Companies that built custom runtimes did so before managed options matured, and most of them move toward managed services as those options improve. A practical place to begin is your roadmap for the next twelve months. Sort each use case into stateless and short-lived or long-running and human-dependent, and for every agent in the second group put a price on the engineers who would maintain the runtime rather than the business logic. I would like to hear how you have drawn this line, and where a managed service was not yet ready for something you needed.957Views2likes0CommentsModel Migration Process on Microsoft Foundry and Azure OpenAI
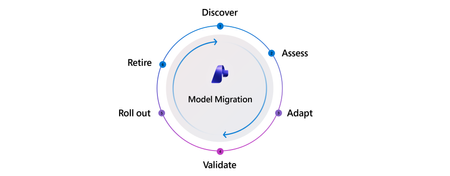
Every app built on an LLM will eventually move to a new model. The model you shipped may be retired, or a newer model may offer better quality, cost, or performance. Changing a model name in code from a retiring model such as gpt-4o to a newer one such as gpt-5.1 may take one line. That line hides a much larger migration. Model failures are often silent to the systems using the model and loud to users. Nothing crashes. Error rates stay flat. Every dashboard says the migration went fine. Meanwhile, responses change shape, summaries become longer and more hedged, JSON fields disappear, and tool calls fire in a different order. Users notice. Support queues grow. Downstream code that depended on the old behavior starts to break. A successful migration preserves the application's behavior or improves it in measurable ways. That requires a repeatable process to detect drift, adapt safely, and prove quality before broad rollout. The model migration process has six phases: Discover → Assess → Adapt → Validate → Roll out → Retire. This article explains what each phase looks like, which Microsoft Foundry tools support it today—including Azure OpenAI capabilities—and where teams still need to build around the platform. It then applies the process to a retail shopping assistant and points to additional resources in Go deeper at the end of this post! Why migrate now Every model has a retirement date. On Microsoft Foundry, generally available models typically ship with a retirement date about 18 months out, and older model families are actively replaced. For example, the model lifecycle and retirement schedule lists gpt-4o (2024-05-13) as retiring on October 1, 2026, with gpt-5.1 as its replacement. What happens at retirement depends on how you buy capacity: Standard, Global Standard, and Data Zone Standard (pay-as-you-go) deployments are auto-upgraded on a rolling, region-by-region schedule. You control the timing with versionUpgradeOption set to one of: OnceNewDefaultVersionAvailable, OnceCurrentVersionExpired, or NoAutoUpgrade. NoAutoUpgrade means the deployment stops working at retirement. Priority Processing follows the same path. Provisioned (PTU) deployments are not auto-upgraded. You migrate them yourself, either in-place (traffic moves over a 20–30 minute window with no downtime) or side-by-side (stand up the new deployment, test, shift traffic, delete the old one). Batch deployments follow the side-by-side path: deploy the new model, resubmit jobs, retire the old deployment. The developer problem is the same in every case: traffic eventually reaches a different model, but the platform cannot tell you whether the application still behaves as it did before. A responding endpoint does not prove that the app behaves correctly. A new model can change formatting, tone, tool-calling behavior, or JSON shape in ways that quietly break downstream code. When should I migrate? Start before the retirement date. Automatic upgrade handles the traffic transition for eligible deployments, but the team still owns behavioral validation. Provisioned deployments also require a manual migration. Microsoft typically makes a replacement available in Global Standard about 90 days before retirement, in provisioned regions about 30 days before retirement, and in standard regions about two weeks before retirement. That gives you time to evaluate the new model on your own terms. Retirement dates cannot be extended. You also do not need a deprecation notice to begin. If a newer model may improve quality, speed, or cost, run it through the process now. Waiting turns the switchover into a slow train wreck: responses drift, parsing becomes brittle, support tickets accumulate, and the team ends up debugging a model it did not choose on a date it did not pick. A deliberate migration makes the retirement date a formality and creates a process the team can reuse. Who this is for This process fits teams that own an LLM-powered feature inside a larger application and run migrations deliberately. It also applies to AI-native platform teams that centrally manage models for other application teams. The phases remain the same, though platform teams may run them faster and in parallel rather than in sequence. Fine-tuned workloads are out of scope here because they cannot be upgraded automatically, have separate training and deployment retirement schedules, and turn the Adapt phase into a distillation or retraining exercise rather than primarily prompt work. The six phases Phase Definition What success looks like Discover Learn that a model change is coming or needed. The team receives a timely, structured signal with the deprecation date, replacement model, and migration window. Assess Choose a target model and confirm that it is operationally available. The team understands the candidates and confirms capacity, region, and SKU before tuning starts. Adapt Replay the current workload on the new model, diagnose changes, and update prompts, parameters, tool definitions, output schemas, and calling code. The team runs side-by-side replay against real or representative traffic, can see the behavioral differences, and records every change. Validate Run the adapted workload against a quality rubric and decide whether it is safe to ship. The team has an evaluation suite that is affordable to run and trusted by application owners and reviewers. Roll out Promote the model through staged production exposure, monitor live behavior, and commit or roll back. Canary or weighted routing is in place, live quality is measured alongside latency and errors, and rollback remains possible. Retire Decommission the old deployment, free capacity, archive evaluation artifacts, and update internal documentation. The old SKU is gone, the deployment count falls, and the team carries what it learned into the next migration. Foundry tools at a glance Microsoft Foundry provide tools for each phase of the Model Migration Process. Phase Microsoft Foundry feature (including Azure OpenAI) Documentation Discover Model retirement schedule, lifecycle policy, Service Health alerts, and Models API lifecycleStatus Model retirement schedule Lifecycle policy Assess Model leaderboards and benchmarks for quality, safety, cost, throughput, and latency; trade-off charts; side-by-side comparison; suggested replacements Model leaderboards and benchmarks Side-by-side compare Adapt Prompt Optimizer in the Foundry Agent playground; agent optimization; simulator for synthetic data Prompt Optimizer Agent optimization Simulator Validate Azure AI Evaluation SDK with 30+ evaluators, LLM-as-judge, graders, and the portal evaluation wizard Azure AI Evaluation SDK Portal evaluation Roll out Automatic upgrade and versionUpgradeOption; provisioned in-place or side-by-side migration; continuous evaluation; Azure Monitor alerts Auto-upgrade with versionUpgradeOption Continuous evaluation Retire Models API to confirm 410 Gone; observability dashboard to track deployment count Models API Observability dashboard Breakdown of each phase 0. Prepare the test dataset Before starting the six phases, build a set of representative inputs, expected outputs, and agreed success criteria. This dataset gates the middle of the lifecycle: Adapt needs inputs for replay, and Validate needs ground truth and scoring criteria. Step 0 describes the workload rather than the candidate model, so it can begin during Discover, before the team selects a target. Build the dataset from captured production traffic or domain examples in .csv or .jsonl. If representative data is not available, use the simulator to generate synthetic inputs. Two practices determine whether this work pays off: Instrument capture before you need it. Production content capture is opt-in and never retroactive. Log prompts, responses, latency, and token counts now so the team has traffic to evaluate later. Freeze the dataset. Keep inputs, ground truths, and success criteria fixed throughout the migration. If they change, source and target results are no longer comparable. You also need an inventory of the model deployments your workload uses, including their deployment types (Standard, Provisioned, or Batch). For each source model, note its retirement date and suggested replacement from the Model retirement schedule. 1. Discover Discover begins when something forces the team to consider a model change: a deprecation notice, a new generally available model, a cost or latency problem, or a capability gap. The phase ends with a decision to begin migration or stay on the current model if it remains stable, performs well, and is not approaching retirement. Foundry tools. The model lifecycle and retirement schedule publishes retirement dates and suggested replacements. The Azure OpenAI model retirements documentation explains notification timing, including at least 60 days for generally available model retirements and at least 30 days for preview model retirements. It also explains how to configure Azure Service Health advisories and use the Models API for programmatic lifecycleStatus and deprecation checks. Those APIs provide the foundation for an internal discovery system. Where it breaks. Customers may learn about a retirement through email, a service health alert, or a production error. By the time the right team sees the signal, it may already be deep into the deprecation window and heading toward retirement. What your team provides. The schedule and Models API expose the data through a stable contract. Mature enterprises may add a thin notification layer that routes it to the right owners. 2. Assess The team chooses a candidate target model and confirms that it is usable: the correct region and SKU, enough quota, and availability alongside the current model so rollback remains possible. Assess also includes projecting monthly cost against historical traffic. Pricing structures change between model generations through reasoning tokens, cached input, structured-output overhead, and other factors. Those changes can move unit economics by 2x or more. For regulated workloads, compliance requirements such as BAA, FedRAMP, and regional Standard versus Global Standard availability may narrow the candidate list before quality testing begins. Foundry tools. Start with the replacement suggested in the retirement schedule, then build a shortlist with model benchmarks, which compare quality, safety, cost, throughput, and latency. Use trade-off charts such as quality versus cost and the side-by-side model comparison for up to three models. Compare context windows, feature support such as function calling, structured output, and vision, and available endpoints. Confirm SKU, region, quota, and upgrade mechanics in the model retirements documentation. Where it breaks. Teams face several plausible candidates, such as gpt-5.1, gpt-5.2, and a nano variant, without clear positioning between them. A selected model may be unavailable in the required region or SKU, a constraint that sometimes appears only after planning is underway. Historical traffic may also show that the new model costs substantially more, forcing an unplanned budget decision. What your team provides. Public benchmarks should filter the candidate list, not make the final decision. Confirm the shortlist against the team's own workload. Build the monthly cost view from token logs and current pricing. 3. Adapt Adapt is often the most time-consuming phase for embedded and product-facing workloads. Validate may take longer for regulated workloads. First, replay the existing workload on the new model without changing it. This isolates changes caused by the model. Diagnose shifts in verbosity, reasoning depth, structured-output adherence, tool-call shape, and latency. Then update the application until it recovers or improves on the previous behavior. Prompt editing is only one part of Adapt. A migration often changes four other surfaces: Parameters. temperature, top_p, max_tokens, and reasoning-effort controls may not map directly between generations. Some are unsupported by newer model families. Tool definitions. Argument names, descriptions, and required fields that reliably guided the old model may need clearer wording or tighter constraints. Output schemas. Structured-output behavior changes between models. A schema the old model followed loosely may need explicit constraints, or the new model may finally enforce it. Calling code. API and SDK differences, including Chat Completions versus Responses, streaming formats, and new or renamed request fields, can require code changes. Downstream parsers may also assume the old response shape. For agentic and workflow workloads, schema and tool-call changes can outweigh prompt changes. Foundry tools. Prompt Optimizer is available through the Optimize button below the system instructions field in the Agent playground. It restructures instructions, explains each change by paragraph, and supports iteration. For example, a team can add a constraint such as "keep the JSON schema exactly" and optimize again. It is a fast first pass for a prompt that would otherwise be rewritten by hand. For agent workloads, agent optimization tunes instructions, tools, and model selection together. Prompt Optimizer and agent optimization are available in Microsoft Foundry, not Azure OpenAI. When production data is unavailable, the simulator can generate synthetic and adversarial inputs. Where it breaks. Most migration time is spent in a manual diagnosis loop. Teams rerun prompts by hand, compare outputs by eye, and rarely record what changed or why. For agent builders, chat benchmarks may miss tool-call regressions such as extra fields, renamed arguments, or changed call sequences. Those problems appear only when the team replays real agent traces. Plan for three constraints: Start with the optimizers, then verify their output. They apply general practices in a single pass rather than fitting changes to the team's dataset. They tune instruction text, not tool definitions or output schemas. Copy the original prompt first because there is no version history, then evaluate the optimized prompt against the frozen dataset. Expect more manual work when moving between providers or model families. There is no "optimize for target model X" flow. Moving from one family to another, such as OpenAI to Claude, still requires deliberate prompt and schema translation. Record traffic before you need it. Replay is only as useful as the captured data. Existing traces are available as an evaluation source for agents today, while content capture is opt-in and never retroactive. Log prompts, responses, latency, and tokens now to prepare for the next Adapt phase. 4. Validate Run the adapted workload against a quality rubric on the frozen dataset. The rubric may combine rules, LLM-as-judge evaluation, human review, existing user-feedback signals, or a domain-specific scoring framework. Examples include a clinical summarization rubric for healthcare or a tool-call sequencing assertion for agents. Validation produces a pass-or-fail decision for production exposure. AI-native teams may run the same signal continuously on every commit rather than treating it as a one-time gate. The dataset is a dependency for both Adapt and Validate. Build and freeze it early, around Assess, even though its primary purpose belongs to this phase. Validation then has two touchpoints: Before Adapt, freeze the dataset and success criteria, then run the current model to establish the source baseline. After Adapt, run the target model against the same dataset and evaluators, compare it with the source baseline, and make the release decision. Prepare the evaluation runner early and apply the gate after Adapt. Both steps belong to Validate. Foundry tools. The Azure AI Evaluation SDK, installed with pip install azure-ai-evaluation, includes more than 30 evaluators. They cover grounding, relevance, retrieval, coherence, fluency, question answering, reference-based similarity, F1, BLEU, ROUGE, safety, agent behavior, and Azure OpenAI graders. Teams can also build custom LLM-as-judge evaluators for task-specific rubrics. The portal evaluation flow runs the same evaluators against model, agent, dataset, and trace targets. Run identical evaluators against source and target outputs on the frozen dataset so the results remain comparable. Measure the three dimensions used for sign-off: Quality: evaluator results Latency: leaderboard time to first token and throughput, plus operational latency from the workload Cost: (input tokens × input price) + (output tokens × output price) Where it breaks. Most teams do not have an evaluation suite. Teams that do often built it themselves and may not use platform evaluation tools. Regulated workloads add mandatory human review, which can become the bottleneck. For those teams, migrations often stall in Validate rather than Adapt. What your team provides. The evaluators are ready to run, but model workloads still require teams to curate a domain-relevant test set from production traffic. That is why Phase 0 pays for itself. 5. Roll out Promote the validated configuration in stages: non-production, then a canary or weighted percentage of production traffic, followed by broader exposure. Compare live latency, errors, and quality signals with the pre-migration baseline, then commit or roll back. Some workloads cannot expose a new model to customer traffic during testing, including flows involving protected health information or financial transactions. Use shadow or mirror mode instead: run the new model offline against production inputs and compare its outputs with the old model without affecting users. Foundry tools. Migration mechanics depend on the deployment SKU: Standard, Global Standard, and Data Zone Standard deployments upgrade automatically on a rolling schedule. Control timing with versionUpgradeOption: OnceNewDefaultVersionAvailable, OnceCurrentVersionExpired, or NoAutoUpgrade. Priority Processing follows the same path. Provisioned, Global Provisioned, and Data Zone Provisioned deployments migrate manually, either in place during a 20-to-30-minute Azure-managed traffic transition or through side-by-side deployments. Batch deployments migrate side by side. Deploy the new model, resubmit jobs, then retire the old deployment. Fine-tuned deployments do not upgrade automatically. They follow separate training and deployment retirement schedules, so plan retraining or distillation early. See the model retirements documentation for deployment-specific guidance. Use continuous evaluation to score a sample of production traffic in the Foundry Observability dashboard. Connect evaluation results to traces for root-cause analysis and configure Azure Monitor alerts for quality regressions. Where it breaks. Offline evaluation can miss production quality and latency regressions. Rollback decisions may also be forced by deprecation deadlines rather than evidence. What your team provides. Teams implement weighted routing between deployments in their application or gateway layer. They must also choose how long to keep the old deployment warm for rollback. Embedded copilot teams often target about 30 days. Design both mechanisms once and reuse them for future migrations. 6. Retire Retire is easy to forget. Decommission the old deployment, free its capacity, archive evaluation artifacts, update internal documentation, and communicate the change to downstream owners. That may include customer-facing documentation, marketing pages, support runbooks, and audit logs. Regulated workloads may need to retain artifacts for years. Retirement is also a governance step. Foundry tools. Use the Models API to confirm that the old version is retired through lifecycleStatus or 410 Gone. Use the observability dashboard to confirm that the active deployment count falls. Add useful production traces to the golden dataset so the next migration starts with better evidence. Where it breaks. Teams skip the phase. Zombie deployments accumulate, leaving teams with structural debris from migrations they never finished. What your team provides. The observability dashboard shows deployment count, but the team must decide which deployments still carry traffic. Create an explicit retirement ticket rather than relying on someone to remember. Embedded copilot teams also need to update public claims such as "powered by gpt-4o" after the model changes. Worked example: Zava's Shopping Assistant migrates from gpt-4o mini to gpt-5.x Zava is a fictional retailer used as a stand-in for a real customer story. The example reflects patterns observed in customer-facing embedded AI workloads. Zava's Shopping Assistant is one of the company's largest LLM workloads. It has two LLM stages: Per-review insight extraction identifies sentiment, attribute mentions, and defect signals across thousands of product reviews. Product-level summaries present those findings to shoppers on the product page. Together, the two stages account for a meaningful share of Zava's token volume. Discover Zava's central AI Platform team made gpt-5.x models available internally and notified feature teams. The Shopping Assistant team learned about the models through that channel and received a target migration window before gpt-4o mini's deprecation. Zava has an internal discovery layer built on the retirement schedule and Models API. Microsoft provides the underlying data, while Zava routes the signal to application owners. Assess The team compared gpt-5.4 nano, which offered lower latency and cost, with gpt-5.1 and gpt-5.2 using leaderboard trade-off charts. Selection remained difficult because of the rapid release cadence, unclear positioning between variants, and the lack of a behavioral benchmark for product question-and-answer workloads. Capacity planning required coordination with the AI Platform team. Both gpt-4o mini and the gpt-5.x candidate needed to remain available in the same regions so the team could roll back. Adapt The team ran its existing Shopping Assistant prompts against gpt-5.4 nano using a sanitized traffic sample. Customer queries were scrubbed of personally identifiable information before replay. The behavioral comparison found three problems: Summaries used more hedged language and sometimes contradicted the underlying review evidence, creating a shopper-trust risk. Insight counts varied across runs. The model sometimes extracted substantially more or fewer attribute mentions than gpt-4o mini, affecting downstream filtering. Latency varied more than expected on the synchronous product-page path. Prompt Optimizer helped restructure the summary prompt, but the team still diagnosed the differences manually. It built its own replay system and behavioral comparison on top of captured traffic. Reengineering took weeks and extended beyond prompts: parameters and downstream parsing for the insight-extraction output also changed. Validate The team scored outputs with Zava's Product Answer Quality (PAQ) rubric. Its nine criteria cover factual grounding, attribute accuracy, tone, and refusal behavior for questions outside the catalog. Zava implemented the rubric as custom evaluators in the Azure AI Evaluation SDK. Initial evaluations used unchanged prompts to isolate model behavior. The team reran them after each prompt change. Zava's QA team also completed a manual review, which the company requires for every new model used in a customer-facing workflow. The per-review insight extraction stage still has no automated evaluation, a gap the team has accepted for now. Roll out The validated configuration moved to non-production and then through staged exposure: employees first, followed by a small percentage of shoppers. The canary exposed latency regressions that offline evaluation had missed. The team rolled back the latency-sensitive synchronous product-page path while keeping the offline pregeneration path on the new model. Retire Retirement is not complete. The gpt-4o mini deployment remains warm for rollback. The team must resolve the synchronous-path latency regression before retiring it, which sends that code path back to Adapt. This split state is common. Retire can lag Roll out by weeks or months, and the old deployment remains visible in deployment-sprawl data. Lessons from the example Adapt consumed most of the schedule. Replay tooling, behavioral comparison, and prompt reengineering are the clearest opportunities for Microsoft to shorten migrations. Validate worked because Zava had invested in it. Most customers do not have an equivalent to PAQ. Making domain-specific evaluations cheaper to build would improve confidence in this phase. The migration is partially live and partially rolled back. The process must support split-state workloads rather than assuming a binary switch from old model to new. How to use this process The six phases can serve as a checklist and an interview script for teams creating or auditing a migration process. Documentation and process: Lead with the six phases. Most teams recognize them immediately. Investment priorities: Start with Adapt and Validate. Across customer stories, those phases consume the most time and confidence. Interviews and postmortems: For each phase, ask whether it happens, who owns it, which tool the team uses, where it failed last time, and what evidence would increase confidence. Metrics: Discover and Retire are the easiest phases to instrument through measures such as announcement reach and active deployment count. Adapt and Validate require purpose-built telemetry that most teams do not yet have. Go deeper Two companion resources turn the process into concrete implementation steps: Microsoft Learn guide: This article follows the six phases through identifying affected deployments, preparing a test dataset, adapting prompts, evaluating source and target models, and rolling out by deployment type. Foundry Models Accelerator: This community toolkit includes a deployment-inventory scanner, a feasibility and assessment playbook, code and API migration audit scripts, an A/B evaluation runner with golden datasets, and rollout guidance. It follows the same six-phase process. The Foundry Models Accelerator is a community-built toolkit provided as-is under the MIT License. It falls outside Microsoft Support. Always verify model availability and retirement dates against official documentation. Additionally, check out the Foundry Forgebook which hosts a plethora of recipes that walk through the required code changes to migrate from different source to target models, even across model families. The goal of a model migration is to change the model without changing your application’s behavior, or to change it measurably for the better. Lead with the six phases, invest first in Adapt and Validate phases, and treat the Retire phase as a governance step.1.1KViews0likes0CommentsAdding a Fallback Model to Hermes with Microsoft Foundry
So the plan was simple. Leave the Bedrock configuration untouched, then wire Microsoft Foundry in behind it as a fallback, so Hermes always has somewhere else to go when the primary provider is not responding. A few other reasons pushed me towards Foundry in particular: Redundancy that does not need me. If Bedrock is throttled or out of quota, I want Hermes to fail over on its own rather than waiting for me to notice. A catalogue I already pay for. Foundry puts the latest GPT models next to open-weight and partner models in one place, so I can pick a model that suits the task instead of settling for whatever a single provider happens to offer. Enterprise controls out of the box. Region pinning, private networking, content filters and per-deployment quota all sit in the same portal, which makes the setup far easier to defend to a security reviewer. Learning the mechanics before I need them. Working out how Hermes handles a provider chain is much nicer on a quiet Tuesday than during a live outage. Here is the short version, if you are deciding whether to read on. Time: about thirty minutes if nothing goes wrong. Cost: pay-as-you-go tokens only, and none at all while the fallback sits idle. Result: an assistant that keeps answering when your primary provider stops. Before you start, you will need three things: a machine with Hermes already installed and a working primary provider configured, an Azure subscription with access to Microsoft Foundry in a region you can actually deploy into, and enough quota in that region to create a deployment. One thing that made this easy to justify: Foundry deployments bill per token on the standard pay-as-you-go tier. A fallback provider that never gets invoked costs nothing beyond the requests it actually serves, so the insurance is close to free until the day you need it. Chat surface (CLI, messaging) → Hermes Gateway → Primary Amazon Bedrock → Fallback Microsoft Foundry Figure 1: Where the fallback sits. Every request goes through the Hermes gateway to the primary provider; only when that provider is unavailable does the chain continue to Microsoft Foundry. Part 1: Deploying a Model on Microsoft Foundry The first half of this job happens entirely inside the Microsoft Foundry portal and has nothing to do with Hermes yet. All you are really doing here is making sure your Azure subscription can serve a model, and that you hold an endpoint and key Hermes can authenticate with later. 1. Deploy model in Foundry → 2. Copy endpoint + key → 3. hermes fallback add → 4. Authenticate → 5. Select models, test Figure 2: The whole setup in five moves. The first two happen in the Microsoft Foundry portal (orange); the rest happen on the Hermes machine (blue). Go to Microsoft Foundry > Build > Models > Deploy > Deploy a base model. You can deploy a fine-tuned model instead if you already have one, which works just as well with Hermes. Check the region shown at the top of the portal before you commit, because both model availability and deployment quota differ from one region to the next. Then deploy the model you have selected: In this case I deployed gpt-5.6-sol, which is the model Hermes will fall back to. The choice was deliberate rather than exciting. My primary model on Bedrock is a general-purpose chat model, and a fallback is only useful if the answers it gives feel like a continuation of the same conversation rather than a different assistant wearing the same name. The gpt-5.6-sol deployment matches that behaviour closely, it was available in the region I wanted to pin, and the quota I was granted comfortably covers a day of normal use. If a fallback surprises you the first time it fires, it is the wrong fallback. Once the deployment finishes, open it and take note of two values: the target endpoint URI and the API key. Copy both somewhere safe now, because you will be pasting them into Hermes in the next part. If your organisation rotates keys on a schedule, use a key with the longest life you are allowed, since a fallback secured with a credential that expires quietly stops being a fallback. What to copy Where it lives in the portal Where Hermes asks for it Target endpoint URI Deployment > Endpoint > Target URI "Endpoint" prompt in hermes fallback add API key Deployment > Endpoint > Key "API key" prompt, or choose Entra ID instead Deployment name Deployment > Details > Name Shown in the model list Hermes returns Region Top of the portal, next to the resource Must match the region you deployed into Figure 3: Everything Hermes will ask for, and where to find each value before you leave the portal. Part 2: Adding Foundry to Hermes as a Fallback With the Foundry side sorted, everything from here happens in the Hermes CLI. One thing worth knowing before you start: this is the fallback command, not the primary model command, so your existing Bedrock configuration is left completely alone. Nothing in this section can break what is already working, which makes it a good one to try on a live setup. Run the Hermes fallback command: When Hermes asks which provider to add, choose Azure Foundry. The picker still carries the old name; it is the same service that the portal now calls Microsoft Foundry. Paste the target endpoint URI from your deployment, then authenticate with the API key you copied earlier. Hermes also offers Microsoft Entra ID at this prompt, which is the better option if your organisation would rather not have a static key sitting on the machine. If authentication fails here, check the endpoint before you start suspecting the key. In my experience the endpoint is wrong far more often than the credential is, usually because the deployment name at the end of the URI does not match the deployment you actually created. Once authentication succeeds, Hermes lists the deployments your Foundry resource exposes and asks which ones you want to use. You can select more than one, and the order is not cosmetic: Hermes walks down the chain from top to bottom whenever the provider above is unavailable. Treat that list as a priority order, not a shopping basket. What happens to the primary What Hermes does What you see in the chat Responds normally Routes every request to the primary and never touches the chain Nothing. The fallback stays idle Throttled or out of quota Retries the next provider down the chain on the same request A reply, served by the fallback model Endpoint unreachable Keeps failing over on each new request until the primary recovers Slightly different tone and latency, but a working assistant Every provider fails Returns the error rather than hanging An error worth chasing with hermes status Figure 4: The chain in practice. The fallback only earns its keep in the middle two rows, which is exactly why it is easy to forget you configured it. Part 3: Promoting Foundry to the Primary Model At this stage Foundry is sitting in the back seat as a backup. I wanted to reverse the arrangement and make Foundry the primary while Bedrock slides down into the fallback slot, partly because I preferred keeping day-to-day traffic inside my Azure subscription, and partly because I wanted proof the chain works in both directions. Before promotion After promotion Primary: Amazon Bedrock → Primary: Microsoft Foundry Fallback: Microsoft Foundry → Fallback: Amazon Bedrock Figure 5: The promotion, in effect. Nothing is added or removed; the two providers simply trade places in the chain. There is no dedicated "promote" command in Hermes, so the manual route is a short sequence of steps rather than a single instruction: Select the fallback provider/model as the new primary: hermes model Remove the now-duplicate model from the fallback chain: hermes fallback remove Optionally add the old primary model as a fallback: hermes fallback add Restart the messaging gateway: hermes gateway restart Verify the result: hermes status / hermes fallback list That sequence works, and it is good to know what is happening underneath. But since I already had a working provider configured, I would rather just ask Hermes to rearrange itself. This is the part I genuinely enjoy about the tool: the configuration is something you can talk to, not only something you type commands at. Prompt: Okay now please make the model I configured on Microsoft Foundry into the main model, and make the Bedrock one the fallback model! Hermes rewrites the provider chain on its own and confirms the swap once it is done, which is a great deal less error-prone than running the five commands by hand. Part 4: Testing the Switch Configuration you have not tested is just an assumption with extra steps, so the next thing is to confirm Hermes really is talking to Foundry. Type /model when running Hermes to bring up the model picker. You will be prompted to select a provider first. Pick the Microsoft Foundry entry, then choose the specific deployment from the list underneath it. The active model should switch straight away. Send it a plain "Hello" to check that the deployment actually responds, rather than just looking correct in the menu. Appearing in a dropdown and serving a request are two very different things. A second test is worth the thirty seconds it costs: run hermes status to confirm which provider is live, then hermes fallback list to confirm the chain is ordered the way you intended. The picker tells you what you selected; those two commands tell you what Hermes will actually do at three in the morning. Part 5: The Obstacle, and What It Actually Taught Me Every walkthrough has the part the author quietly leaves out. Here is mine: the wrinkle was not the model, it was capacity. My first attempt deployed into the region closest to me out of habit, and the portal turned it down because there was no capacity left for that model at the tier I asked for. The model was clearly listed in the catalogue; being listed and being deployable in your region, on your subscription, at your quota, are three separate questions. Redeploying in a different region fixed it in a couple of minutes, but it meant the endpoint URI changed, which in turn meant the value I had already pasted into Hermes was stale. Re-running hermes fallback add against the new endpoint sorted it out. The lesson is cheap enough to hand over for free: check quota and regional capacity for your specific subscription before you design a walkthrough, a demo or a production fallback around one deployment. In the Foundry portal, Management then Quota shows exactly what you have been granted per region and per model family, which is the only list that matters. Symptom Likely cause Fix Deployment rejected in the portal No capacity for that model at the tier you asked for, in that region Deploy in another region, or drop to a smaller tier Hermes rejects the credential Endpoint URI does not match the deployment you created Re-copy the target URI from the deployment, not the resource Provider authenticates but lists nothing Key belongs to a different Foundry resource Check you are in the right resource, then re-run hermes fallback add Fallback never fires Chain ordered the wrong way round hermes fallback list, then reorder Figure 6: The four things that went wrong, or nearly did, and what fixed each one. There is a silver lining worth stating plainly. Because the fallback chain was already in place, a deployment that refused to come up did not take the assistant down with it. That is precisely the scenario this whole exercise was meant to cover, and it turned up on day one without me having to simulate it. Command Cheat Sheet Everything used in this walkthrough, collected in one place: hermes fallback add: attach a provider to the fallback chain hermes fallback remove: drop a provider from the chain hermes fallback list: show the chain in priority order hermes model: set the primary model hermes gateway restart: restart the messaging gateway after a change hermes status: confirm which provider is currently live /model: switch models from inside a running session Conclusion Adding Microsoft Foundry as a fallback behind my existing Bedrock setup took an afternoon, and most of that was spent recovering from a regional capacity limit I should have checked first. The work itself is small: deploy a model, copy the endpoint and key, run hermes fallback add, authenticate, pick your deployments. The payoff is that Hermes no longer depends on one provider staying healthy. Three things are worth carrying away from this: Check quota, not just the catalogue. The Foundry catalogue shows what Microsoft offers. It does not show what your subscription and region can actually deploy today. Confirm that first, before you build anything on top of a specific deployment. Order your fallback chain deliberately. Hermes works down the list from top to bottom, so the sequence you choose during setup is the failover policy you are going to live with. Put the model you actually trust at the top. Treat the endpoint as part of the credential. Redeploying in a new region changes the endpoint URI, and a fallback pointed at an endpoint that no longer exists is not a fallback. Re-run the setup whenever the deployment moves. The switch from Bedrock primary to Foundry primary also proved the chain runs in both directions, which is the real point. Provider redundancy is only useful if you have watched it work. Next on my list is deliberately breaking the primary provider to confirm the failover triggers on its own, without me typing a single command. If you run this against a different model, region or provider pairing, I would genuinely like to know how it went, particularly if your quota experience was better than mine. Drop it in the comments.441Views0likes0CommentsFor the first time, real-time transcription goes multilingual
When we introduced Post-Stream Refinement earlier this year, it closed the oldest gap in real-time speech: you could finally get instant streaming results and a highly accurate final transcript, with no latency penalty. But it kept one hard requirement — you had to tell the service, up front, which single language to expect. Real-world speech does not work that way. People code-switch mid-sentence, product and brand names cross languages, and a global app serves users who simply speak differently from one session to the next. Today we remove that requirement. Multilingual Post-Stream Refinement enters public preview for Azure AI Speech in Microsoft Foundry, and for the first time ever a single real-time stream can transcribe multiple languages in one session — the spoken language is detected automatically, no locale is declared in advance, and the final transcript is refined for accuracy. Everything you already know about Post-Stream Refinement still applies; what changes is that the refinement pass itself is now multilingual. 📖 Read the Documentation What's New in This Release If you have already used Post-Stream Refinement, here is exactly what changes with the multilingual preview — and what stays the same: Quality Impact In internal testing and partner evaluations across Tier-1 locales, multilingual Post-Stream Refinement reduced word error rate (WER) by approximately 10% relative on average, with double-digit relative reductions on the hardest cases — long utterances, proper nouns, and multilingual or code-switched speech. Partial-result latency is unchanged; only the final transcript is refined. Gains are relative reductions versus the standard real-time model and vary by language, acoustic conditions, and content type. The refined final result may add a small amount of latency to the final segment; partial results are unaffected. Supported Languages and Regions The public preview supports 15 Tier-1 locales. Because language is detected automatically, a single stream can contain any mix of them: Available in these Azure regions: Real-World Impact Preview customers across industries — including travel, consumer electronics, automotive, aviation, and media — have reported positive gains in transcription quality. Customers testing multilingual and domain-specific audio have observed the clearest improvements on the hardest content: proper nouns, code-switching, and long-form speech. Several are actively validating the feature on their own audio ahead of general availability. Get Started Enabling multilingual Post-Stream Refinement is a small configuration change on your existing SpeechConfig. You will need: Speech SDK 1.50 or later. Earlier versions do not support the multilingual path. A Speech resource in one of the supported regions listed above. Auto-detect language configuration (open range) so the service identifies the language from the audio — no candidate list required. Set the post-processing option to PostRefinement and pass an open-range AutoDetectSourceLanguageConfig when you create the recognizer. Here is a complete, copy-paste Python example, including the optional end-of-utterance detection line: import azure.cognitiveservices.speech as speechsdk speech_config = speechsdk.SpeechConfig( subscription="YourSpeechKey", region="YourSpeechRegion") # 1) Refine the final transcript (Post-Stream Refinement) speech_config.set_property( speechsdk.PropertyId.SpeechServiceResponse_PostProcessingOption, "PostRefinement") # 2) Multilingual auto-detect - no candidate language list needed auto_detect_config = speechsdk.languageconfig.AutoDetectSourceLanguageConfig() audio_config = speechsdk.AudioConfig(use_default_microphone=True) recognizer = speechsdk.SpeechRecognizer( speech_config=speech_config, auto_detect_source_language_config=auto_detect_config, audio_config=audio_config) 💡 Tip: Refinement matters most for applications that store or process the final transcript — meeting notes, call analytics, compliance archives, AI summarization. If you only use partial results for a live display and discard them, your real-time UX (already fast) is unchanged, while any final transcript you keep improves. Try Multilingual Post-Stream Refinement Today Turn on higher-accuracy, language-aware transcription in your Azure AI Speech applications with a single configuration change. Available now in public preview in Microsoft Foundry. 📖 Read the Documentation We would love your feedback. Try Post-Stream Refinement in your applications and tell us how it improves your transcription quality.893Views0likes0CommentsMigrating to GPT-5.x Without Breaking GPT-4: A Practical, Backward-Compatible Playbook
The first request your service sends after swapping gpt-4o for gpt-5.1 in production will return HTTP 400. Not in two weeks. On the first call. And the parameter the error points to isn't one you set anywhere in your code - it's bound onto the request by a LangChain helper you've used for two years. This post walks through every breaking change between the GPT-4 and GPT-5 families on Azure OpenAI in Microsoft Foundry, the integration cliffs nobody warns you about, and the small set of files you need so the same call sites work against both model families without branching. Who this is for: engineers maintaining an existing production codebase that calls Azure OpenAI / OpenAI - directly or through LangChain - and needs to onboard GPT-5.x while keeping the GPT-4 deployments alive during rollout. What you'll leave with: one copy-paste compatibility module, a tiny LangChain subclass, a prompt-audit harness, and a 10-step rollout checklist. 1. Why this migration is different Every previous Azure OpenAI bump - 3.5 → 4, 4 → 4o, 4o → 4o-mini - was additive. You changed engine="gpt-4o" and everything kept working. GPT-5.x is the first generation that is subtractive: parameters you used to send now return 400 Unsupported parameter. The wire protocol itself changed because GPT-5 is a reasoning model - it spends tokens thinking internally before it answers, so the parameters that controlled the old sampling pipeline (temperature, top_p, presence_penalty, frequency_penalty) no longer exist on the request schema. What this means for production code: A passing test suite against gpt-4o will fail on the first call against gpt-5.1 with HTTP 400. A passing test suite against gpt-5.1 will fail on every legacy gpt-4* deployment because the new reasoning controls (reasoning_effort, verbosity) are not recognised there. LangChain helpers that worked unmodified for two years (notably create_sql_query_chain) silently bind stop=[...] onto your LLM and trigger the same 400. Source-grep won't find the offending line because it lives inside the library. The good news: the divergence is mechanical. With one detection helper, one parameter-builder, and one tiny LangChain subclass you can run the same code against both families. 2. The breaking-changes matrix Concern GPT-4 / GPT-4o (legacy) GPT-5.x / o1 / o3 (reasoning) Output budget max_tokens max_completion_tokens (rejects max_tokens) temperature 0.0–1.0 Only the default (1) is accepted - omit it top_p Supported Rejected presence_penalty, frequency_penalty Supported Rejected logprobs, logit_bias Supported Rejected stop sequences Supported Rejected on most reasoning deployments reasoning_effort Rejected New: minimal | low | medium | high verbosity Rejected New: low | medium | high (sometimes via extra_body) System instruction role system developer recommended; system still works as alias Output token cost Output tokens only Output + reasoning tokens count against your cap Recommended API version 2024-12-01-preview or earlier 2025-03-01-preview or later Two consequences are easy to miss: max_completion_tokens is a shared budget. GPT-5.1 can burn 2–4× more tokens internally before emitting the first response token. A cap of 4096 that comfortably held a SQL query on GPT-4o now silently truncates the answer mid-token on GPT-5.1. Multiply your legacy budgets by ~2.5× and add a floor (e.g. 4096) before sending. The stop parameter is the silent killer. Any helper that calls llm.bind(stop=[...]) - and there are several in langchain - will turn a working code path into a 400 the moment you swap deployments. 3. Compatibility strategy: detect, don't fork The temptation is to fork: one branch for GPT-4, one for GPT-5. Don't. The right unit of abstraction is one function that classifies the deployment into a family, and one function that builds a kwargs dict the SDK will accept for that family. Every call site - SDK, LangChain, raw HTTP - drains into the same kwargs builder. When you eventually retire GPT-4 you delete the legacy branch in one file, not in fifty. 4. The industry-agnostic compatibility module Drop the following file into your project. It has no Azure / OpenAI / LangChain imports at module load time, so the same file works from a web service, a serverless function, a notebook, or a CLI tool. 4.1 model_compat.py """ Model compatibility helper for GPT-5.x with GPT-4 backward compatibility. This module centralises the parameter translation needed to talk to the "reasoning" generation of OpenAI / Azure OpenAI models (GPT-5, GPT-5.1, o1, o3, o4) while keeping older deployments (gpt-4, gpt-4o, gpt-4-32k, gpt-3.5-turbo, etc.) working unchanged. """ from __future__ import annotations import logging import os import re from typing import Any, Dict, Iterable, Mapping, Optional # --------------------------------------------------------------------------- # Family detection # --------------------------------------------------------------------------- _REASONING_PATTERNS = ( # gpt-5, gpt5, gpt-5.1, gpt_5, GPT 5, gpt5mini-prod-eu, ... re.compile(r"(?i)(^|[^a-z0-9])gpt[-_ ]?5(\.\d+)?([^0-9]|$)"), # o1, o3, o4, o1-mini, o3-preview ... re.compile(r"(?i)(^|[^a-z0-9])o[134](-mini|-preview)?([^a-z0-9]|$)"), ) _LEGACY_PATTERNS = ( re.compile(r"(?i)gpt[-_ ]?4o"), re.compile(r"(?i)gpt[-_ ]?4(?!\d)"), re.compile(r"(?i)gpt[-_ ]?4[-_ ]?32k"), re.compile(r"(?i)gpt[-_ ]?3\.?5"), re.compile(r"(?i)gpt[-_ ]?35"), ) def get_model_family(model_or_deployment: Optional[str]) -> str: """Return ``"reasoning"`` for GPT-5.x / o-series, ``"legacy"`` otherwise. Honours an ``OPENAI_MODEL_FAMILY`` env-var override for deployments whose user-defined name does not embed the model family (e.g. ``prod-default``). """ override = (os.getenv("OPENAI_MODEL_FAMILY") or "").strip().lower() if override in {"reasoning", "gpt-5", "gpt5", "gpt-5.1", "o-series", "o1", "o3"}: return "reasoning" if override in {"legacy", "gpt-4", "gpt4", "gpt-3.5", "gpt35", "chat"}: return "legacy" name = (model_or_deployment or "").strip() if not name: # Fail closed: when we don't know, assume legacy so old code keeps # working. Misclassifying a reasoning deployment as legacy fails fast # with a clear "Unsupported parameter" 400; the reverse silently # drops parameters the caller expected. return "legacy" for pat in _REASONING_PATTERNS: if pat.search(name): return "reasoning" for pat in _LEGACY_PATTERNS: if pat.search(name): return "legacy" return "legacy" def is_reasoning_model(model_or_deployment: Optional[str]) -> bool: return get_model_family(model_or_deployment) == "reasoning" # --------------------------------------------------------------------------- # Reasoning controls # --------------------------------------------------------------------------- _VALID_REASONING_EFFORT = {"minimal", "low", "medium", "high"} _VALID_VERBOSITY = {"low", "medium", "high"} def _coerce_choice(raw: Optional[str], valid: Iterable[str]) -> Optional[str]: if raw is None: return None value = str(raw).strip().lower() if not value: return None if value not in set(valid): logging.warning( "Ignoring unsupported value '%s'; expected one of %s", raw, sorted(valid), ) return None return value def get_reasoning_effort(override: Optional[str] = None) -> Optional[str]: return _coerce_choice( override if override is not None else os.getenv("OPENAI_REASONING_EFFORT"), _VALID_REASONING_EFFORT, ) def get_verbosity(override: Optional[str] = None) -> Optional[str]: return _coerce_choice( override if override is not None else os.getenv("OPENAI_VERBOSITY"), _VALID_VERBOSITY, ) # --------------------------------------------------------------------------- # max_completion_tokens scaling # --------------------------------------------------------------------------- def _reasoning_token_scale() -> float: """Multiplier applied to legacy ``max_tokens`` when targeting a reasoning model.""" try: scale = float(os.getenv("OPENAI_REASONING_TOKEN_SCALE", "2.5")) except (TypeError, ValueError): scale = 2.5 return scale if scale > 0 else 1.0 def _reasoning_token_floor() -> int: try: floor = int(os.getenv("OPENAI_REASONING_TOKEN_FLOOR", "4096")) except (TypeError, ValueError): floor = 4096 return floor if floor > 0 else 4096 def scale_max_tokens_for_reasoning(max_tokens: Optional[int]) -> Optional[int]: """Scale a legacy ``max_tokens`` budget up for reasoning models. ``None`` and ``-1`` ("no explicit cap") are passed through. """ if max_tokens is None: return None if max_tokens == -1: return -1 return max(int(round(max_tokens * _reasoning_token_scale())), _reasoning_token_floor()) # --------------------------------------------------------------------------- # Kwargs builders # --------------------------------------------------------------------------- _SAMPLING_KEYS = ("temperature", "top_p", "presence_penalty", "frequency_penalty") def _drop_none(mapping: Mapping[str, Any]) -> Dict[str, Any]: return {k: v for k, v in mapping.items() if v is not None} def build_openai_chat_kwargs( model: str, *, max_tokens: Optional[int] = None, temperature: Optional[float] = None, top_p: Optional[float] = None, presence_penalty: Optional[float] = None, frequency_penalty: Optional[float] = None, reasoning_effort: Optional[str] = None, verbosity: Optional[str] = None, extra: Optional[Mapping[str, Any]] = None, ) -> Dict[str, Any]: """Build kwargs for ``openai.OpenAI / AzureOpenAI .chat.completions.create``. Splat the result directly: ``client.chat.completions.create(**kwargs)``. Unsupported parameters are silently omitted for reasoning models; legacy deployments retain the historical behaviour. """ family = get_model_family(model) kwargs: Dict[str, Any] = {"model": model} # ---- output budget ---- if max_tokens is not None and max_tokens != -1: if family == "reasoning": kwargs["max_completion_tokens"] = scale_max_tokens_for_reasoning(int(max_tokens)) else: kwargs["max_tokens"] = int(max_tokens) # ---- sampling ---- if family == "legacy": kwargs.update(_drop_none({ "temperature": temperature, "top_p": top_p, "presence_penalty": presence_penalty, "frequency_penalty": frequency_penalty, })) else: for key, value in ( ("temperature", temperature), ("top_p", top_p), ("presence_penalty", presence_penalty), ("frequency_penalty", frequency_penalty), ): if value is not None: logging.debug( "Dropping unsupported parameter '%s' for reasoning model '%s'", key, model, ) # ---- reasoning controls ---- if family == "reasoning": effort = get_reasoning_effort(reasoning_effort) if effort is not None: kwargs["reasoning_effort"] = effort verb = get_verbosity(verbosity) if verb is not None: # ``verbosity`` is not a top-level kwarg in openai-python <= 1.65.x; # route it via ``extra_body`` so it lands in the JSON without a # TypeError from the SDK. kwargs.setdefault("extra_body", {})["verbosity"] = verb # ---- caller-supplied extras (already filtered) ---- if extra: for key, value in extra.items(): if value is None: continue if family == "reasoning" and key in _SAMPLING_KEYS: continue kwargs[key] = value return kwargs def build_langchain_chat_kwargs( deployment_name: str, *, max_tokens: Optional[int] = None, temperature: Optional[float] = None, top_p: Optional[float] = None, reasoning_effort: Optional[str] = None, verbosity: Optional[str] = None, ) -> Dict[str, Any]: """Build kwargs for ``langchain_openai.AzureChatOpenAI`` / ``ChatOpenAI``. Older ``langchain-openai`` releases don't expose ``max_completion_tokens`` as a top-level kwarg, so we forward it through ``model_kwargs`` (which langchain passes straight to the SDK). """ family = get_model_family(deployment_name) kwargs: Dict[str, Any] = {} model_kwargs: Dict[str, Any] = {} if max_tokens is not None and max_tokens != -1: if family == "reasoning": model_kwargs["max_completion_tokens"] = scale_max_tokens_for_reasoning(int(max_tokens)) else: kwargs["max_tokens"] = int(max_tokens) if family == "reasoning": effort = get_reasoning_effort(reasoning_effort) if effort is not None: model_kwargs["reasoning_effort"] = effort verb = get_verbosity(verbosity) if verb is not None: model_kwargs.setdefault("extra_body", {})["verbosity"] = verb else: if temperature is not None: kwargs["temperature"] = temperature if top_p is not None: kwargs["top_p"] = top_p if model_kwargs: kwargs["model_kwargs"] = model_kwargs return kwargs def get_system_role(model_or_deployment: Optional[str] = None) -> str: """Return ``"developer"`` for reasoning models when opted in, ``"system"`` otherwise. Defaulting to ``"system"`` preserves compatibility with LangChain prompt templates and SDK helpers that don't yet recognise the new role. Opt in with ``OPENAI_USE_DEVELOPER_ROLE=1`` once your stack supports it. """ if not is_reasoning_model(model_or_deployment): return "system" raw = os.getenv("OPENAI_USE_DEVELOPER_ROLE", "") return "developer" if raw.strip().lower() in {"1", "true", "yes", "on"} else "system" 4.2 What this buys you Every direct-SDK call collapses to two lines: from openai import AzureOpenAI from model_compat import build_openai_chat_kwargs client = AzureOpenAI( azure_endpoint=os.environ["AZURE_OPENAI_ENDPOINT"], api_version=os.environ["OPENAI_API_VERSION"], api_key=os.environ["AZURE_OPENAI_API_KEY"], ) kwargs = build_openai_chat_kwargs( model=os.environ["OPENAI_ENGINE"], max_tokens=4096, # automatically becomes max_completion_tokens for GPT-5 temperature=0.2, # automatically dropped for GPT-5 reasoning_effort="low", # automatically dropped for GPT-4 ) response = client.chat.completions.create( messages=[ {"role": "system", "content": "You are a helpful assistant."}, {"role": "user", "content": user_input}, ], **kwargs, ) The same call site now correctly targets gpt-5.1, gpt-4o, gpt-4-32k, o3-mini, or any future deployment whose name embeds the family - and you can override with the OPENAI_MODEL_FAMILY env var when the deployment alias is opaque. 4.3 Raw HTTP call sites Some legacy code paths bypass the SDK and POST JSON directly. The same builder works there: import json import requests from model_compat import build_openai_chat_kwargs, get_system_role deployment = os.environ["OPENAI_ENGINE"] api_version = os.environ["OPENAI_API_VERSION"] endpoint = ( f"{os.environ['AZURE_OPENAI_ENDPOINT']}/openai/deployments/{deployment}" f"/chat/completions?api-version={api_version}" ) payload = { "messages": [ {"role": get_system_role(deployment), "content": system_prompt}, {"role": "user", "content": user_prompt}, ], } # Splat the kwargs into the payload, then strip the SDK-only ``model`` key. payload.update(build_openai_chat_kwargs( model=deployment, max_tokens=800, temperature=0.7, top_p=0.95, reasoning_effort="low", )) payload.pop("model", None) # ``model`` is encoded in the URL for Azure payload.pop("extra_body", None) # already on the payload root resp = requests.post( endpoint, headers={"Content-Type": "application/json", "api-key": api_key}, data=json.dumps(payload), timeout=60, ) resp.raise_for_status() 5. LangChain: the hidden stop parameter langchain.chains.sql_database.query.create_sql_query_chain calls llm.bind(stop=["\nSQLResult:"]) internally to terminate the model's output before the example block in its prompt. That stop value is forwarded to the SDK on every invocation. GPT-5.1 rejects it: openai.BadRequestError: Error code: 400 - {'error': { 'message': "Unsupported parameter: 'stop' is not supported with this model.", 'type': 'invalid_request_error', 'param': 'stop', }} You can't reach into the chain to disable it. The clean fix is a thin AzureChatOpenAI subclass that drops stop for reasoning models only: 5.1 langchain_compat.py """LangChain-side compatibility shim for reasoning-class deployments.""" from __future__ import annotations from typing import Any, List, Optional from langchain_core.callbacks.manager import ( AsyncCallbackManagerForLLMRun, CallbackManagerForLLMRun, ) from langchain_core.messages import BaseMessage from langchain_core.outputs import ChatResult from langchain_openai import AzureChatOpenAI # use ChatOpenAI for non-Azure from model_compat import is_reasoning_model class ReasoningSafeAzureChatOpenAI(AzureChatOpenAI): """``AzureChatOpenAI`` variant that hides parameters reasoning models reject. Reasoning models (GPT-5.x, o1/o3/o4) return HTTP 400 when a request payload carries ``stop``. LangChain's SQL helpers unconditionally bind it, so the unsupported parameter reaches the SDK regardless of how the caller configured the LLM. This subclass strips ``stop`` for reasoning deployments while forwarding it unchanged for legacy GPT-4 / GPT-3.5 deployments - the behaviour is byte-identical to upstream LangChain for those models. """ def _deployment_id(self) -> str: # ``langchain-openai`` >= 0.2 exposes ``azure_deployment``; older # releases use ``deployment_name``. Either may be set by the caller. return ( getattr(self, "azure_deployment", None) or getattr(self, "deployment_name", None) or "" ) def _generate( self, messages: List[BaseMessage], stop: Optional[List[str]] = None, run_manager: Optional[CallbackManagerForLLMRun] = None, **kwargs: Any, ) -> ChatResult: if is_reasoning_model(self._deployment_id()): stop = None return super()._generate(messages, stop=stop, run_manager=run_manager, **kwargs) async def _agenerate( self, messages: List[BaseMessage], stop: Optional[List[str]] = None, run_manager: Optional[AsyncCallbackManagerForLLMRun] = None, **kwargs: Any, ) -> ChatResult: if is_reasoning_model(self._deployment_id()): stop = None return await super()._agenerate(messages, stop=stop, run_manager=run_manager, **kwargs) Use it as a drop-in replacement: from langchain_compat import ReasoningSafeAzureChatOpenAI from model_compat import build_langchain_chat_kwargs llm_kwargs = build_langchain_chat_kwargs( deployment_name=os.environ["OPENAI_ENGINE"], max_tokens=6000, temperature=0, reasoning_effort="low", ) llm = ReasoningSafeAzureChatOpenAI( azure_endpoint=os.environ["AZURE_OPENAI_ENDPOINT"], azure_deployment=os.environ["OPENAI_ENGINE"], openai_api_version=os.environ["OPENAI_API_VERSION"], api_key=os.environ["AZURE_OPENAI_API_KEY"], **llm_kwargs, ) That single substitution makes create_sql_query_chain, SQLDatabaseChain, and the ChatOpenAI-based RAG helpers all work against GPT-5.1 without any other changes. 6. The second LangChain gotcha: prose where SQL should be create_sql_query_chain is documented to return the literal string "I don't know" (or a similar fallback) when the LLM cannot form a query. The default code path takes the chain output and runs it against the database: sql = chain.invoke({...}) # -> "I don't know" result = db.run(sql) # -> sends "I don't know" to pyodbc The database faithfully returns: [42000] Unclosed quotation mark after the character string 't know'. (105) Which surfaces to the end user as a misleading "SQL syntax error". The mitigation is a one-line guard that validates the chain output looks like SQL before execution: import re _SQL_START_RE = re.compile( r"^\s*(?:WITH|SELECT|INSERT|UPDATE|DELETE|CREATE|DROP|ALTER|MERGE|EXEC|EXECUTE|TRUNCATE)\b", re.IGNORECASE, ) def looks_like_sql(text: str) -> bool: """True only if ``text`` starts with a recognised SQL DML/DDL keyword.""" if not text or not text.strip(): return False return bool(_SQL_START_RE.match(text)) sql = extract_sql_query(chain.invoke({...})) if not looks_like_sql(sql): logging.warning("SQL chain returned a non-SQL response: %r", sql[:200]) return ( "I couldn't form a SQL query for that question. " "Please rephrase or add more context." ) result = db.run(sql) This isn't specific to GPT-5.1 - it's good hygiene for any LLM that backs a SQL agent - but the failure mode becomes much more frequent on reasoning models because they're better at refusing. 7. Cleaning Markdown out of create_sql_query_chain output Reasoning models like to wrap their answer in a markdown fence and append a "Note:" or "Explanation:" paragraph. None of that survives db.run(). A defensive extract_sql_query handles all the variants: import re def extract_sql_query(text: str) -> str: """Strip markdown fences, leading prose, and trailing explanations.""" # 1) Prefer SQL inside a markdown code fence. m = re.search(r"```(?:sql|SQL|Sql)?\s*\n(.*?)\n```", text, re.DOTALL) if m: text = m.group(1) text = text.strip() # 2) Drop any prose *before* the SQL by jumping to the first SQL keyword. m = re.search( r"(?im)^\s*(WITH|SELECT|INSERT|UPDATE|DELETE|CREATE|DROP|ALTER|MERGE|EXEC|EXECUTE|TRUNCATE)\b", text, ) if m: text = text[m.start(1):] # 3) Cut at the first "Explanation:" / "Note:" / "This query..." marker. m = re.compile( r"(?im)^\s*(?:Explanation|Note|Notes|Here(?:'|\u2019)?s|" r"This\s+(?:query|SQL|statement|returns|counts|selects|will|gets|finds)|" r"The\s+(?:query|SQL|above|result|statement)|" r"Result|Results|Description|Output|Answer)\b[^\n]*" ).search(text) if m: text = text[: m.start()].rstrip() # 4) Drop any trailing fence that survived step 1. if text.endswith("```"): text = text[:-3].rstrip() return text.strip() 8. Package versioning The bare minimum your requirements.txt / environment.yml needs: Package Last GPT-4-only version First GPT-5.x-safe version Notes openai 1.55.x 1.65.x (recommend 1.65.4+) Earlier versions reject max_completion_tokens and reasoning_effort as unknown kwargs langchain-openai 0.2.14 0.3.7+ 0.3.x line exposes azure_deployment and forwards model_kwargs correctly to the new SDK langchain 0.3.14 0.3.21+ Pin together with langchain-openai and langchain-core langchain-core 0.3.29 0.3.49+ Update in lockstep with the others langchain-community 0.3.14 0.3.20+ Mostly transitive; needed for SQLDatabase helpers tiktoken 0.7.x 0.8.0+ Encodings for GPT-5.1 ship in 0.8.0; older versions fall back to cl100k_base for unknown models tokencost (optional) 0.1.16 0.1.20+ Update for GPT-5.x price tables Azure OpenAI API version 2024-12-01-preview 2025-03-01-preview First version that ships reasoning_effort and the GPT-5.x routing Pin exact versions after testing - LangChain has a habit of moving public re-exports between minor releases. requirements.txt snippet: openai==1.65.4 langchain==0.3.21 langchain-core==0.3.49 langchain-openai==0.3.7 langchain-community==0.3.20 tiktoken==0.8.0 9. New GPT-5.x knobs worth using Once you're on a reasoning deployment, two new parameters become available. Both are optional, both default to a sensible value, and both are stripped by the kwargs builder above when the target is a legacy model. reasoning_effort minimal - one-shot lookups, classification. low - deterministic structured output (SQL, JSON-schema extraction, rule-based rewrites). Lowest cost overhead. medium (default) - RAG, summarisation, normal Q&A. high - multi-step analytical reasoning, complex code synthesis. A useful pattern is to choose the level by task profile rather than at the call site: TASK_EFFORT = { "sql": "low", "structured_extract": "low", "kg_cleaning": "low", "rag_qa": "medium", "vision": "medium", "analytical": "high", } verbosity low | medium | high. Controls the length of the response, not its substance. Useful for grounding chat UIs where you want crisp answers - set low for /answer endpoints and high for "explain like a senior engineer" panels. Note: in openai-python <= 1.65.x, verbosity is not yet a top-level keyword argument; pass it through extra_body (the builder above already does this). developer role GPT-5.x prefers {"role": "developer", "content": "..."} for instructions that previously used system. The change is non-breaking on the Azure side - system is still accepted as an alias - but some downstream LangChain prompt templates predate the role and will reject it on construction. Treat developer as opt-in (OPENAI_USE_DEVELOPER_ROLE=1) for now; flip the default after your prompt-template version is known good. 10. Auditing your existing prompts When the wire-level migration is done your service will talk to GPT-5.x - but that doesn't mean it says the right thing. Reasoning models read prompts differently in ways that won't show up as 400s: They take instructions more literally. A prompt that worked when GPT-4o rounded the corners may surface every edge case verbatim. They refuse more often. "I don't know" / "I cannot help with that" are more frequent because reasoning models are less willing to confabulate. They ignore "be concise" / "be terse". Use the new verbosity knob. Step-by-step / chain-of-thought instructions become redundant. The model already reasons internally; extra "think before you answer" prose competes with its own chain of thought and often hurts output quality. Negative-only instructions can backfire. "Never output X" prompts occasionally cause refusals where you'd rather have a workaround. 10.1 Build a prompt regression harness Capture every system+user prompt your service emits in a CSV, then replay each one against both deployments and diff the output. The diff is the single most useful artefact you can produce before the cutover: # prompt_audit.py - minimal differential tester import csv from openai import AzureOpenAI from model_compat import build_openai_chat_kwargs LEGACY = "gpt-4o" REASONING = "gpt-5.1" client = AzureOpenAI( azure_endpoint=os.environ["AZURE_OPENAI_ENDPOINT"], api_version=os.environ["OPENAI_API_VERSION"], api_key=os.environ["AZURE_OPENAI_API_KEY"], ) def run(model: str, system: str, user: str) -> str: kw = build_openai_chat_kwargs( model=model, max_tokens=4096, temperature=0.2, # auto-dropped for reasoning reasoning_effort="medium", # auto-dropped for legacy ) resp = client.chat.completions.create( messages=[ {"role": "system", "content": system}, {"role": "user", "content": user}, ], **kw, ) return resp.choices[0].message.content or "" with open("prompts.csv") as f_in, open("diff.tsv", "w", newline="") as f_out: writer = csv.writer(f_out, delimiter="\t") writer.writerow(["id", "legacy_first80", "reasoning_first80", "len_legacy", "len_new", "identical"]) for row in csv.DictReader(f_in): legacy = run(LEGACY, row["system"], row["user"]) new = run(REASONING, row["system"], row["user"]) writer.writerow([ row["id"], legacy[:80].replace("\n", " "), new[:80].replace("\n", " "), len(legacy), len(new), legacy.strip() == new.strip(), ]) Capture three signals per prompt - they're enough to triage 95% of drift: Format compliance. Did the output still parse as the expected JSON / YAML / Markdown / SQL? Run your existing downstream parser on both columns. Token cost delta. Reasoning models tend to be more verbose by default. Anything beyond +20% is a candidate for the verbosity="low" knob. Semantic drift. Spot-check 5–10% of rows by hand. You're looking for changes in intent, not changes in wording. 10.2 Common rewrites to make prompts model-agnostic The goal isn't to write two prompts. It's to write one prompt that produces correct output on both families by moving constraints out of the natural-language body and into the request shape. 10.2a. Format constraints belong in response_format, not the prose Don't: Output ONLY a JSON object with keys `name` and `score`. Do not include any explanation. Do not wrap in markdown. Do not say anything else. Do: resp = client.chat.completions.create( messages=[...], response_format={ "type": "json_schema", "json_schema": { "name": "scored_entity", "schema": { "type": "object", "properties": { "name": {"type": "string"}, "score": {"type": "number"}, }, "required": ["name", "score"], "additionalProperties": False, }, "strict": True, }, }, **kw, ) response_format is honoured by both gpt-4o (>= 2024-08-06) and the entire GPT-5.x line. The prompt loses three lines of brittle natural-language constraints and you get schema-validated output for free. 10.2b. Replace "think step by step" with reasoning_effort Don't: Let's think step by step. First identify the entity. Then find the category. Then compute the score. Then format the answer. Do: delete the prose and pass reasoning_effort="medium" (or "high") for reasoning deployments. The kwargs builder drops the parameter automatically for GPT-4 models, so the same prompt now produces: step-by-step reasoning internally on GPT-5.x (lower output token cost), the same final answer on GPT-4o that the verbose prompt used to elicit. 10.2c. Replace temperature-based variety with n sampling If your code relied on temperature=0.9 to get diverse completions, GPT-5.x will return roughly the same answer every time. Generate variety the explicit way: resp = client.chat.completions.create(messages=[...], n=5, **kw) candidates = [c.message.content for c in resp.choices] Or call the model N times with slightly different framings. Both patterns work against either family with no further code changes. 10.2d. Move procedural instructions to the developer role For multi-step workflows, the new developer role gives clearer separation between what the system enforces and what the user is asking: messages = [ {"role": get_system_role(deployment), "content": role_card_for_assistant}, {"role": "developer", "content": procedural_instructions}, {"role": "user", "content": user_question}, ] get_system_role returns "system" for legacy models and "developer" for reasoning models opted in via OPENAI_USE_DEVELOPER_ROLE=1. Once your LangChain templates support the new role you can flip the default. 10.2e. Add a literal-execution header for strict formats For prompts where the exact output shape matters (table generation, SQL with a fixed column order, structured incident reports), prepend an explicit literal-execution header so reasoning models don't drift into "helpful improvements": LITERAL_EXECUTION_HEADER = ( "Execution mode: follow the instructions below literally and in order. " "Do not infer intent, skip, reorder, merge, or add steps. Honour the " "exact formatting, tone, and verbosity specified. If a step is " "ambiguous, respond with the literal interpretation and flag the " "ambiguity instead of guessing." ) def apply_literal_execution(prompt: str) -> str: if LITERAL_EXECUTION_HEADER in prompt: return prompt return f"{LITERAL_EXECUTION_HEADER}\n\n{prompt}" It's a no-op on GPT-4o (the older models already follow instructions literally enough) and a meaningful guard rail on GPT-5.1. Wire it behind an OPENAI_LITERAL_EXECUTION flag so you can disable it without redeploying. 10.3 A prompt-shaped checklist Run every prompt your service emits past these questions: Question Action Does it specify output format in prose? Move to response_format (10.2a) Does it include "think step by step"? Remove; set reasoning_effort (10.2b) Does it set tone constraints ("be concise")? Use verbosity Does it use negative-only instructions ("never X")? Add positive alternative ("do Y instead") Does it embed example outputs with values that would change? Replace concrete values with placeholder tokens (<VALUE>) Does it rely on temperature > 0 for variety? Use n=K sampling (10.2c) Is the system prompt > 2k tokens? Split into role-card (system) + procedure (developer) Does output ordering matter? Add the literal-execution header (10.2e) 10.4 Score before you ship Don't approve a rewritten prompt by eyeballing one example. Score it: Format compliance rate. Percentage of N=50 outputs that pass your existing downstream parser / JSON schema validation. Token cost delta. Cap regression at +20% versus the legacy baseline. Beyond that, dial verbosity="low" or tighten the prompt. Latency p50 / p95 delta. Reasoning models add tail latency. If your SLA is tight, set reasoning_effort="low" for the path or move it to a background queue. A prompt that regresses on any of those by more than your tolerance window ships behind a feature flag with rollback wired in. 11. Testing strategy Two test layers catch >90% of regressions: Family-classification tests import pytest from model_compat import get_model_family, build_openai_chat_kwargs @pytest.mark.parametrize("name,expected", [ ("gpt-5.1", "reasoning"), ("gpt5", "reasoning"), ("gpt-5-prod-eu", "reasoning"), ("o3-mini", "reasoning"), ("o1", "reasoning"), ("gpt-4o", "legacy"), ("gpt-4", "legacy"), ("gpt-4-32k", "legacy"), ("gpt-35-turbo", "legacy"), ("", "legacy"), # unknown -> fail closed to legacy (None, "legacy"), ]) def test_family(name, expected): assert get_model_family(name) == expected def test_kwargs_for_reasoning_drops_temperature(): kw = build_openai_chat_kwargs( model="gpt-5.1", max_tokens=1000, temperature=0.2, top_p=0.9, reasoning_effort="low", ) assert "temperature" not in kw assert "top_p" not in kw assert kw["max_completion_tokens"] >= 4096 # floor applied assert kw["reasoning_effort"] == "low" def test_kwargs_for_legacy_keeps_temperature(): kw = build_openai_chat_kwargs( model="gpt-4o", max_tokens=1000, temperature=0.2, top_p=0.9, ) assert kw["max_tokens"] == 1000 assert kw["temperature"] == 0.2 assert kw["top_p"] == 0.9 assert "reasoning_effort" not in kw Wire-level smoke tests For each LLM call site you maintain, write a single integration test that exercises the chain against a real (or mocked) endpoint and asserts: HTTP 200, non-empty content, finish_reason != "length" (so you catch silent truncation), (optional) classifier-style assertions against a golden output. Run those tests once against the legacy deployment and once against the new one - same test code, two OPENAI_ENGINE values. 12. Things that don't change It's easy to over-correct. Several pieces of plumbing keep working without modification: Authentication. AAD token providers, managed identity, and API keys are unchanged. Embeddings. text-embedding-3-small, text-embedding-3-large, and text-embedding-ada-002 are not part of the reasoning generation; the embeddings call shape is identical. Function calling / tool use. Same JSON schema, same response shape. Streaming. SSE format is unchanged. Token counters. tiktoken still works, but bump to 0.8.0+ so the new model name resolves to the right encoding instead of silently falling back to cl100k_base. 13. Next steps If you only do four things from this post, do these - in order: Deploy a GPT-5.1 model side-by-side with your current GPT-4 deployment in Microsoft Foundry. Keep the GPT-4 deployment live; you'll need both for the parallel-run period. Drop model_compat.py and langchain_compat.py into your project (Sections 4 and 5). Replace every AzureChatOpenAI(...) construction with ReasoningSafeAzureChatOpenAI and route every kwargs literal through the builders. Run the prompt-audit harness (Section 10.1) against your top 50 most frequently invoked prompts. Triage the diff with the checklist in 10.3. Roll out behind a percentage-based flag. Start at 5% of traffic for 24 hours, compare quality and cost telemetry against the GPT-4o baseline, then ramp. Reference material Azure OpenAI in Microsoft Foundry - model overview Azure OpenAI model retirements and deprecations Reasoning models in Azure OpenAI Structured Outputs in Azure OpenAI openai-python SDK changelog langchain-openai release notes Talk to us Open an issue on the Microsoft Foundry GitHub samples repository if you hit a gap this post didn't cover. Share your migration story or numbers in the comments below - field data is the fastest way to make this guide better for the next team. If you operate a regulated workload (finance, health, public sector) and need help sequencing the rollout with your model retirement deadlines, reach out to your Microsoft account team or a Microsoft Foundry partner. GPT-5.x is the first major model bump in two years that requires code changes - but the changes collapse into one small compatibility module and a one-line LangChain subclass. With those in place your code is forwards-compatible (works on reasoning models today) and backwards- compatible (still works on every GPT-4 deployment you haven't migrated yet). The investment pays a recurring dividend: when the next reasoning bump ships, the only file that needs updating is model_compat.py. Appendix A - Minimal .env template # Endpoint and auth (unchanged between families) AZURE_OPENAI_ENDPOINT=https://<resource>.openai.azure.com AZURE_OPENAI_API_KEY=<key> # The deployment name decides the family. The classifier reads it. OPENAI_ENGINE=gpt-5.1 OPENAI_API_VERSION=2025-03-01-preview # Optional override for opaque deployment names # OPENAI_MODEL_FAMILY=reasoning # or "legacy" # Optional reasoning controls (ignored for legacy deployments) OPENAI_REASONING_EFFORT=medium OPENAI_VERBOSITY=medium OPENAI_REASONING_TOKEN_SCALE=2.5 OPENAI_REASONING_TOKEN_FLOOR=4096 # Flip when your LangChain templates support it # OPENAI_USE_DEVELOPER_ROLE=1 Appendix B - One-liner sanity checks # Does a deployment name classify correctly? python -c "from model_compat import get_model_family; print(get_model_family('gpt-5.1'))" # -> reasoning # Does the LangChain LLM strip ``stop`` when the deployment is GPT-5.1? python -c " from langchain_compat import ReasoningSafeAzureChatOpenAI import inspect; print(inspect.getsource(ReasoningSafeAzureChatOpenAI._generate)) " Companion repository: drop model_compat.py and langchain_compat.py next to each other in your utils/ package. They are zero-dependency on import, so you can vendor them into any service - web, function, batch job - without dragging Azure SDK or LangChain into module-load.1.6KViews2likes1Comment
Automate Prior Authorization with AI Agents - Now Available as a Foundry Template
By Amit Mukherjee · Principal Solutions Engineer, Microsoft Health & Life Sciences Lindsey Craft-Goins · Technology Leader - Cloud & AI Platforms, Health & Life Sciences Joel Borellis · Director Solutions Engineering - Cloud & AI Platforms, Health & Life Sciences Prior authorization (PA) is one of the most expensive bottlenecks in U.S. healthcare. Physicians complete an average of 39 PA requests per week, spending roughly 13 hours of physician-and-staff time on PA-related work (AMA 2024 Prior Authorization Physician Survey). Turnaround averages 5–14 business days, and PA alone accounts for an estimated $35 billion in annual administrative spending (Sahni et al., Health Affairs Scholar, 2024). The regulatory clock is now ticking. CMS-0057-F mandates electronic PA with 72-hour urgent response starting in 2026. Forty-nine states plus DC already have PA laws on the books, and at least half of all U.S. state legislatures introduced new PA reform bills this year, including laws specifically targeting AI use in PA decisions (KFF Health News, April 2026). Today we’re making the Prior Authorization Multi-Agent Solution Accelerator available as a Microsoft Foundry template. Health plan payers can deploy a working, four-agent PA review pipeline to Azure using the Azure Developer CLI (“azd”) with a single command in supported environments, then customize it to their policies, workflows, and EHR environment. Try it now: Find the template in the Foundry template gallery, or clone directly from github.com/microsoft/Prior-Authorization-Multi-Agent-Solution-Accelerator What the template delivers The accelerator deploys four specialist Foundry hosted agents (Compliance, Clinical Reviewer, Coverage, and Synthesis), each independently containerized and managed by Foundry. In internal testing with synthetic demo cases, the pipeline reduced review workflow, from beginning to completion in under 5 minutes per case. Agent Role Key capability Compliance Documentation check 10-item checklist with blocking/non-blocking flags Clinical Reviewer Clinical evidence ICD-10 validation, PubMed + ClinicalTrials.gov search Coverage Policy matching CMS NCD/LCD lookup, per-criterion MET/NOT_MET mapping Synthesis Decision rubric 3-gate APPROVE/PEND with weighted confidence scoring Compliance and Clinical run in parallel. Coverage runs after clinical findings are ready. Synthesis evaluates all three outputs through a three-gate rubric. The result is a structured recommendation with per-criterion confidence scores and a full audit trail, not a black-box answer. Solution architecture The accelerator runs entirely on Azure. The frontend and backend deploy as Azure Container Apps. The four specialist agents are hosted by Microsoft Foundry. Real-time healthcare data flows through third-party MCP servers. Figure 1: Azure solution architecture How the pipeline works The four agents execute in a structured parallel-then-sequential pipeline. Compliance and Clinical run simultaneously in Phase 1. Coverage runs after clinical findings are ready. The Synthesis agent applies a three-gate decision rubric over all prior outputs. Figure 2: Agentic architecture, hosted agent pipeline Compliance and Clinical run in parallel via asyncio.gather, since neither depends on the other. Coverage runs sequentially after Clinical because it needs the structured clinical profile for criterion mapping. Synthesis evaluates all three outputs through a three-gate rubric (Provider, Codes, Medical Necessity) with weighted confidence scoring: 40% coverage criteria + 30% clinical extraction + 20% compliance + 10% policy match. The total pipeline time is bound by the slowest parallel agent plus the sequential agents, not the sum. In internal testing with synthetic demo cases, this architecture indicated materially reduced processing time compared to sequential manual workflows. Under the hood For the architect in the room, here are four design decisions worth knowing about: Foundry hosted agents: Each agent is independently containerized, versioned, and managed by Foundry’s runtime. The FastAPI backend is a pure HTTP dispatcher. All reasoning happens inside the agent containers, and there are no code changes between local (Docker Compose) and production (Foundry); the environment variable is the only switch. Structured output: Every agent uses MAF’s response_format enforcement to produce typed Pydantic schemas at the token level. No JSON parsing, no malformed fences, no free-form text. The orchestrator receives typed Python objects; the frontend receives a stable API contract. Keyless security: DefaultAzureCredential throughout, so no API keys are stored anywhere. Managed Identity handles production; azd tokens handle local development. Role assignments are provisioned automatically by Bicep at deploy time. Observability: All agents emit OpenTelemetry traces to Azure Application Insights. The Foundry portal shows per-agent spans correlated by case ID. End-to-end latency, per-agent contribution, and error rates are visible from day one with no additional configuration. For the full architecture documentation, agent specifications, Pydantic schemas, and extension guides, see the GitHub repository. Why this matters now Human-in-the-loop by design The system runs in LENIENT mode by default: it produces only APPROVE or PEND and is not designed to produce automated DENY outcomes in its default configuration. Every recommendation requires a clinician to Accept or Override with documented rationale before the decision is finalized. Override records flow to the audit PDF, notification letters, and downstream systems. This directly addresses the emerging wave of state legislation governing AI use in PA decisions. Domain experts own the rules Agent behavior is defined in markdown skill files, not Python code. When CMS updates a coverage determination or a plan changes its commercial policy, a clinician or compliance officer edits a text file and redeploys. No engineering PR required. Real-time healthcare data via MCP Agents connect to five MCP servers for real-time data: ICD-10 codes, NPI Registry, CMS Coverage policies, PubMed, and ClinicalTrials.gov. This incorporates real‑time clinical reference data sources to inform agent recommendations. Third-party MCP servers are included for demonstration with synthetic data only. Their inclusion does not constitute an endorsement by Microsoft. See the GitHub repository for production migration guidance. Audit-ready from day one Every case generates an 8-section audit justification PDF with per-criterion evidence, data source attribution, timestamps, and confidence breakdowns. Clinician overrides are recorded in Section 9. Notification letters (approval and pend) are generated automatically. These artifacts are designed to support CMS-0057-F documentation requirements. Deploy in under 15 minutes From the Foundry template gallery or from the command line: git clone https://github.com/microsoft/Prior-Authorization-Multi-Agent-Solution-Accelerator cd Prior-Authorization-Multi-Agent-Solution-Accelerator azd up That single command provisions Foundry, Azure Container Registry, Container Apps, builds all Docker images, registers the four agents, and runs health checks. The demo is live with a synthetic sample case as soon as deployment completes. What’s included What you customize 4 Foundry hosted agents Payer-specific coverage policies FastAPI orchestrator + Next.js frontend EHR/FHIR integration for clinical notes 5 MCP healthcare data connections Self-hosted MCP servers for production PHI Audit PDF + notification letter generation Authentication (Microsoft Entra ID) Full Bicep infrastructure-as-code Persistent storage (Cosmos DB / PostgreSQL) OpenTelemetry + App Insights observability Additional agents (Pharmacy, Financial) Built on Microsoft Foundry + Foundry hosted agents · Microsoft Agent Framework (MAF) · Azure OpenAI gpt-5.4 · Azure Container Apps · Azure Developer CLI + Bicep · OpenTelemetry + Azure Application Insights · DefaultAzureCredential (keyless, no secrets) Full architecture documentation, agent specifications, and extension guides are in the GitHub repository. Get started Foundry template gallery: Search “AI-Powered Prior Authorization for Healthcare” in the Foundry template section GitHub: github.com/microsoft/Prior-Authorization-Multi-Agent-Solution-Accelerator Disclaimers Not a medical device. This solution accelerator is not a medical device, is not FDA-cleared, and is not intended for autonomous clinical decision-making. All AI recommendations require qualified clinical review before any authorization decision is finalized. Not production-ready software. This is an open-source reference architecture (MIT License), not a supported Microsoft product. Customers are solely responsible for testing, validation, regulatory compliance, security hardening, and production deployment. Performance figures are illustrative. Metrics cited (including processing time reductions) are based on internal testing with synthetic demo data. Actual results will vary based on case complexity, infrastructure, and configuration. Third-party services included for demonstration only; not endorsed by Microsoft. Customers should evaluate providers against their compliance and data residency requirements. The demo uses synthetic data only. Customers deploying real patient data are responsible for HIPAA compliance and establishing appropriate Business Associate Agreements. This accelerator is intended to help customers align documentation workflows with CMS‑0057‑F requirements but has not been independently validated or certified for regulatory compliance.2.9KViews3likes0CommentsMicrosoft Foundry: Unlock Adaptive, Personalized Agents with User-Scoped Persistent Memory
From Knowledgeable to Personalized: Why Memory Matters Most AI agents today are knowledgeable — they ground responses in enterprise data sources and rely on short‑term, session‑based memory to maintain conversational coherence. This works well within a single interaction. But once the session ends, the context disappears. The agent starts fresh, unable to recall prior interactions, user preferences, or previously established context. In reality, enterprise users don’t interact with agents exclusively in one‑off sessions. Conversations can span days, weeks, evolving across multiple interactions rather than isolated sessions. Without a way to persist and safely reuse relevant context across interactions, AI agents remain efficient in the short term be being stateful within a session, but lose continuity over time due to their statelessness across sessions. Bridging this gap between short-term efficiency and long‑term adaptation exposes a deeper challenge. Persisting memory across sessions is not just a technical decision; in enterprise environments, it introduces legitimate concerns around privacy, data isolation, governance, and compliance — especially when multiple users interact with the same agent. What seems like an obvious next step quickly becomes a complex architectural problem, requiring organizations to balance the ability for agents to learn and adapt over time with the need to preserve trust, enforce isolation boundaries, and meet enterprise compliance requirements. In this post, I’ll walk through a practical design pattern for user‑scoped persistent memory, including a reference architecture and a deployable sample implementation that demonstrates how to apply this pattern in a real enterprise setting while preserving isolation, governance, and compliance. The Challenge of Persistent Memory in Enterprise AI Agents Extending memory beyond a single session seems like a natural way to make AI agents more adaptive. Retaining relevant context over time — such as preferences, prior decisions, or recurring patterns — would allow an agent to progressively tailor its behavior to each user, moving from simple responsiveness toward genuine adaptation. In enterprise environments, however, persistence introduces a different class of risk. Storing and reusing user context across interactions raises questions of privacy, data isolation, governance, and compliance — particularly when multiple users interact with shared systems. Without clear ownership and isolation boundaries, naïvely persisted memory can lead to cross‑user data leakage, policy violations, or unclear retention guarantees. As a result, many systems default to ephemeral, session‑only memory. This approach prioritizes safety and simplicity — but does so at the cost of long‑term personalization and continuity. The challenge, then, is not whether agents should remember, but how memory can be introduced without violating enterprise trust boundaries. Persistent Memory: Trade‑offs Between Abstraction and Control As AI agents evolve toward more adaptive behavior, several approaches to agent memory are emerging across the ecosystem. Each reflects a different set of trade-offs between abstraction, flexibility, and control — making it useful to briefly acknowledge these patterns before introducing the design presented here. Microsoft Foundry Agent Service includes a built‑in memory capability (currently in Preview) that enables agents to retain context beyond a single interaction. This approach integrates tightly with the Foundry runtime and abstracts much of the underlying memory management, making it well suited for scenarios that align closely with the managed agent lifecycle. Another notable approach combines Mem0 with Azure AI Search, where memory entries are stored and retrieved through vector search. In this model, memory is treated as an embedding‑centric store that emphasizes semantic recall and relevance. Mem0 is intentionally opinionated, defining how memory is structured, summarized, and retrieved to optimize for ease of use and rapid iteration. Both approaches represent meaningful progress. At the same time, some enterprises require an approach where user memory is explicitly owned, scoped, and governed within their existing data architecture — rather than implicitly managed by an agent framework or memory library. These requirements often stem from stricter expectations around data isolation, compliance, and long‑term control. User-Scoped Persistent Memory with Azure Cosmos DB The solution presented in this post provides a practical reference implementation for organizations that require explicit control over how user memory is stored, scoped, and governed. Rather than embedding long‑term memory implicitly within the agent runtime, this design models memory as a first‑class system component built on Azure Cosmos DB. At a high level, the architecture introduces user‑scoped persistent memory: a durable memory layer in which each user’s context is isolated and managed independently. Persistent memory is stored in Azure Cosmos DB containers partitioned by user identity and consists of curated, long‑lived signals — such as preferences, recurring intent, or summarized outcomes from prior interactions — rather than raw conversational transcripts. This keeps memory intentional, auditable, and easy to evolve over time. Short‑term, in‑session conversation state remains managed by Microsoft Foundry on the server side through its built‑in conversation and thread model. By separating ephemeral session context from durable user memory, the system preserves conversational coherence while avoiding uncontrolled accumulation of long‑term state within the agent runtime. This design enables continuity and personalization across sessions while deliberately avoiding the risks associated with shared or global memory models, including cross‑user data leakage, unclear ownership, and unintended reuse of context. Azure Cosmos DB provides enterprises with direct control over memory isolation, data residency, retention policies, and operational characteristics such as consistency, availability, and scale. In this architecture, knowledge grounding and memory serve complementary roles. Knowledge grounding ensures correctness by anchoring responses in trusted enterprise data sources. User‑scoped persistent memory ensures relevance by tailoring interactions to the individual user over time. Together, they enable trustworthy, adaptive AI agents that improve with use — without compromising enterprise boundaries. Architecture Components and Responsibilities Identity and User Scoping Microsoft Entra ID (App Registrations) — provides the frontend a client ID and tenant ID so the Microsoft Authentication Library (MSAL) can authenticate users via browser redirect. The oid (Object ID) claim from the ID token is used as the user identifier throughout the system. Agent Runtime and Orchestration Microsoft Foundry — serves as the unified AI platform for hosting models, managing agents, and maintaining conversation state. Foundry manages in‑session and thread‑level memory on the server side, preserving conversational continuity while keeping ephemeral context separate from long‑term user memory. Backend Agent Service — implements the AI agent using Microsoft Foundry’s agent and conversation APIs. The agent is responsible for reasoning, tool‑calling decisions, and response generation, delegating memory and search operations to external MCP servers. Memory and Knowledge Services MCP‑Memory — MCP server that hosts tools for extracting structured memory signals from conversations, generating embeddings, and persisting user‑scoped memories. Memories are written to and retrieved from Azure Cosmos DB, enforcing strict per‑user isolation. MCP‑Search — MCP server exposing tools for querying enterprise knowledge sources via Azure AI Search. This separation ensures that knowledge grounding and memory retrieval remain distinct concerns. Azure Cosmos DB for NoSQL — provides the durable, serverless document store for user‑scoped persistent memory. Memory containers are partitioned by user ID, enabling isolation, auditable access, configurable retention policies, and predictable scalability. Vector search is used to support semantic recall over stored memory entries. Azure AI Search — supplies hybrid retrieval (keyword and vector) with semantic reranking over the enterprise knowledge index. An integrated vectorizer backed by an embedding model is used for query‑time vectorization. Models text‑embedding‑3‑large — used for generating vector embeddings for both user‑scoped memories and enterprise knowledge search. gpt‑5‑mini — used for lightweight analysis tasks, such as extracting structured memory facts from conversational context. gpt‑5.1 — powers the AI agent, handling multi‑turn conversations, tool invocation, and response synthesis. Application and Hosting Infrastructure Frontend Web Application — a React‑based web UI that handles user authentication and presents a conversational chat interface. Azure Container Apps Environment — provides a shared execution environment for all services, including networking, scaling, and observability. Azure Container Apps — hosts the frontend, backend agent service, and MCP servers as independently scalable containers. Azure Container Registry — stores container images for all application components. Try It Yourself Demonstration of user‑scoped persistent memory across sessions. To make these concepts concrete, I’ve published a working reference implementation that demonstrates the architecture and patterns described above. The complete solution is available in the Agent-Memory GitHub repository. The repository README includes prerequisites, environment setup notes, and configuration details. Start by cloning the repository and moving into the project directory: git clone https://github.com/mardianto-msft/azure-agent-memory.git cd azure-agent-memory Next, sign in to Azure using the Azure CLI: az login Then authenticate the Azure Developer CLI: azd auth login Once authenticated, deploy the solution: azd up After deployment is complete, sign in using the provided demo users and interact with the agent across multiple sessions. Each user’s preferences and prior context are retained independently, the interaction continues seamlessly after signing out and returning later, and user context remains fully isolated with no cross‑identity leakage. The solution also includes a knowledge index initialized with selected Microsoft Outlook Help documentation, which the agent uses for knowledge grounding. This index can be easily replaced or extended with your own publicly accessible URLs to adapt the solution to different domains. Looking Ahead: Personalized Memory as a Foundation for Adaptive Agents As enterprise AI agents evolve, many teams are looking beyond larger models and improved retrieval toward human‑centered personalization at scale — building agents that adapt to individual users while operating within clearly defined trust boundaries. User‑scoped persistent memory enables this shift. By treating memory as a first‑class, user‑owned component, agents can maintain continuity across sessions while preserving isolation, governance, and compliance. Personalization becomes an intentional design choice, aligning with Microsoft’s human‑centered approach to AI, where users retain control over how systems adapt to them. This solution demonstrates how knowledge grounding and personalized memory serve complementary roles. Knowledge grounding ensures correctness by anchoring responses in trusted enterprise data. Personalized memory ensures relevance by tailoring interactions to the individual user. Together, they enable context‑aware, adaptive, and personalized agents — without compromising enterprise trust. Finally, this solution is intentionally presented as a reference design pattern, not a prescriptive architecture. It offers a practical starting point for enterprises designing adaptive, personalized agents, illustrating how user‑scoped memory can be modeled, governed, and integrated as a foundational capability for scalable enterprise AI.1.7KViews1like1Comment