llm
94 TopicsTransforming Enterprise Documents into AI Knowledge with Agentic RAG
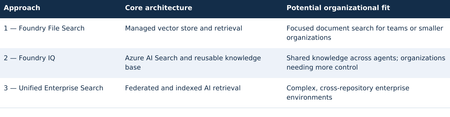
TECHNICAL RESEARCH PAPER Research Disclaimer: This article is a technical research paper intended solely for educational, research, and illustrative purposes. It reflects the author’s personal technical perspectives. All concepts, architectural designs, diagrams, and implementation approaches are provided “AS IS” for technical exploration and review, not as production-ready development guidance. Organizations considering implementing these approaches should consult their internal software development standards, enterprise architecture teams, corporate security policies, and governance requirements. Any production implementation must undergo appropriate end-to-end architectural, security, privacy, compliance, and responsible AI or ethics reviews, along with necessary testing and organizational approvals before deployment. Abstract. This research paper explores three independent approaches to transforming enterprise documents and knowledge repositories into AI-powered search experiences using Agentic Retrieval-Augmented Generation (RAG), Microsoft Foundry, and ASP.NET Core. Organizations can evaluate and adopt any one approach independently according to their business requirements, organizational size, document volume, technical complexity, available resources, and security considerations. Approach 1 — Microsoft Foundry File Search: A streamlined option with managed ingestion, vector storage, retrieval, and an optional ASP.NET Core/Blazor conversational web interface. It may be a sufficient standalone solution for focused document-search needs. Approach 2 — Microsoft Foundry IQ: A knowledge-centric option built around Azure AI Search and reusable knowledge bases, suitable for applications that need more configurable retrieval or shared knowledge across authorized agents. It does not require Approach 1 to be implemented first. Approach 3 — Unified Enterprise Agentic Search: A broader design combining federated and indexed retrieval across approved enterprise repositories, for organizations with extensive integration, authorization, governance, and cross-source search requirements. These are alternatives, not mandatory sequential stages. Approaches 1 and 2 may each be complete solutions. Organizations considering Approach 3 may optionally pilot Approach 1 or 2 to assess retrieval quality, citations, user experience, and operational readiness, but neither pilot is a prerequisite. The examples are research illustrations, not production-ready implementation instructions. 1. Three independent architectural approaches Select an approach based on organizational needs rather than following a required progression: Optional evaluation path: An enterprise exploring Approach 3 can run a focused File Search or Foundry IQ POC first. A small organization may stop at Approach 1 or 2 if its requirements are met. 2. Three independent implementations 3. How documents become AI-searchable For indexed sources, the broad workflow is similar across managed File Search and Foundry IQ-backed Azure AI Search, although ingestion details, formats, and service capabilities differ. Federated retrieval may query existing repositories without creating new embeddings. Indexed document processing and agent retrieval workflow The original document is not replaced by vectors alone: searchable text and source references are retained. Scanned PDFs and images may need OCR or multimodal processing. 3.1 Example: what happens to one PDF? Source: IIS-AppPool-Troubleshooting.pdf. Example passage: “If an IIS application pool repeatedly terminates, examine WAS events and investigate rapid-fail protection.” Illustrative document chunk, vector, and metadata A query such as “Why does my IIS application pool keep crashing?” may retrieve the relevant passage through semantic similarity. The agent uses the readable retrieved content to explain the issue and cite its source. Architecture note: This paper targets the new Microsoft Foundry Agent Service (Responses API-based), not classic Foundry agents or legacy Assistants API implementations. 4. Approach 1 — Microsoft Foundry File Search 4.1 Objective Explore a potentially standalone AI-powered search solution over 20 approved technical documents with limited ingestion configuration. Evaluate one Foundry File Search-enabled agent through the built-in Playground and/or a custom conversational web application. 4.2 Architecture flow Approach 1 — Microsoft Foundry File Search architecture 4.3 What is a managed vector store? A managed vector store exposes searchable passages, embeddings, and metadata while abstracting ingestion and retrieval. In standard Foundry Agent Service setup, files can remain in customer-managed Azure Storage and Azure AI Search can back the vector store; basic setup uses Microsoft-managed resources. Where supported, multiple agents in the same project can reference the same vector store ID through File Search tool configuration, subject to API and permission boundaries. 4.4 User experience options Option 1: Use the Foundry Agent Playground to ask questions, inspect citations, and evaluate multi-document synthesis. Option 2: Build an ASP.NET Core/Blazor portal using supported APIs/SDKs with multi-turn chat, streaming where supported, clickable citations, error handling, and Microsoft Entra ID sign-in. Keep privileged credentials on the server. 4.5 Illustrative implementation and deliverables • Prepare 20 approved documents and a fixed question set. • Configure a compatible Foundry project, model, agent, and File Search tool. • Upload files; verify managed processing and retrieval quality. • Test in the Playground; optionally implement and test the Blazor portal. • Evaluate answer grounding, citations, latency, ingestion behavior, and costs. Possible standalone deliverable: File Search agent, managed vector store, working selected interface(s), and an evaluation report. The custom portal is optional; Approach 2 is not required. 5. Approach 2 — Microsoft Foundry IQ 5.1 Objective Evaluate a reusable knowledge-base architecture with Azure AI Search-backed retrieval. This is an independent option: it can be built directly without first implementing Foundry File Search. For a comparative research exercise, the same 20 documents and questions may be reused. 5.2 Architecture flow Approach 2 — Microsoft Foundry IQ architecture 5.3 What is an Azure AI Search index? An Azure AI Search index is a structured, searchable collection of content extracted from enterprise data sources, including documents, websites, and other supported repositories. It stores searchable text, vector embeddings, metadata, and source references, enabling keyword, vector, hybrid, and semantic search to retrieve relevant information efficiently. During ingestion, documents can be processed, divided into smaller chunks, and converted into vector embeddings that represent their semantic meaning. When a user submits a natural-language question, Azure AI Search can combine keyword matching with vector similarity and semantic ranking to identify relevant passages, which an AI agent can use to generate grounded responses with citations to the original sources. 5.4 What Foundry IQ adds? Microsoft Foundry IQ builds on Azure AI Search by providing reusable knowledge bases and agentic retrieval capabilities across supported enterprise data sources. Multiple authorized AI agents can access the same knowledge base without duplicating document ingestion, while agentic retrieval can intelligently plan and execute searches to identify relevant information. Supported remote SharePoint knowledge sources can also be queried through the Copilot Retrieval API without creating a separate local vector index. This capability may require eligible Microsoft 365 Copilot licensing for end users, with access governed by source-specific permissions. For indexed content, document-level security trimming depends on supported knowledge-source capabilities and properly configured access control lists (ACLs) or security filters. 5.5 User experience and optional comparison A Foundry IQ solution may use the Agent Playground and/or its own ASP.NET Core/Blazor application. If an organization is comparing Approaches 1 and 2, it can optionally reuse a common web UI and provide an agent selector. Reusing Approach 1 is not a dependency. 5.6 Illustrative implementation and deliverables • Provision compatible Azure AI Search and Foundry resources. • Create the knowledge base and supported knowledge source; validate ingestion. • Connect a Foundry agent; evaluate retrieval and citations in the Playground. • Optionally build or reuse a Blazor interface for the same agent. • Measure relevance, knowledge reuse, latency, costs, and operational complexity. Direct-file ingestion may depend on preview, region, or API availability; Azure Blob ingestion may be needed. Possible standalone deliverable: reusable knowledge base, index, connected agent, selected interface(s), and evaluation report. 6. Foundry File Search versus Foundry IQ Section 6 — Foundry File Search versus Foundry IQ Key takeaway: Both File Search and Foundry IQ can support keyword, vector, and semantic relevance, with hybrid retrieval where supported. File Search emphasizes managed processing and search behavior; Foundry IQ provides reusable knowledge bases and more configurable Azure AI Search-backed sources. The distinction is control, source integration, and operations—not whether embeddings or semantic relevance exist. Both may be standalone solutions. 7. Approach 3 — Unified Enterprise Agentic Search 7.1 Objective Explore a comprehensive architecture for organizations requiring search across multiple repositories, with both federated and indexed retrieval, grounded answers, citations, and permission-aware access. This approach can be evaluated directly; smaller POCs are optional validation exercises, not prerequisites. 7.2 Unified enterprise architecture flow Section 7 — Unified Enterprise Agentic Search architecture 7.3 Option A — Federated enterprise search Query approved repositories through source APIs/connectors while retaining documents in place. Delegated access and source-native ACLs must be enforced for each connector. Remote SharePoint retrieval through Copilot Retrieval can require Microsoft 365 Copilot licenses for end users; source-specific permission behavior must be validated. Other repositories may require custom connectors or indexing. 7.4 Option B — Indexed enterprise AI search Index approved extracted text, vectors, metadata, and source references in Azure AI Search. Foundry IQ can provide reusable knowledge retrieval. OCR and complex layout extraction are not guaranteed by default File Search or every Foundry IQ knowledge source: test each format and add Azure AI Search OCR/Document Intelligence layout skills or other processing where needed. Derived indexed content requires explicit authorization and security trimming. 7.5 Combined example For “Find documentation explaining HTTP 503 errors in IIS and compare it with internal troubleshooting procedures,” the agent could retrieve current SharePoint guidance through Option A and indexed engineering articles through Option B, synthesize findings, and cite original sources. 8. A Unified UI for All Three Approaches: ASP.NET Core / Blazor Conversational Portal Section 8 — Unified ASP.NET Core/Blazor conversational portal for all three approaches The shared Blazor UI and ASP.NET Core backend can route requests to any of the three independent approaches. Approach 3 additionally coordinates federated and indexed retrieval; all paths return grounded answers and source citations. The retrieval router shown in the diagram is custom ASP.NET Core application/BFF logic, not a standalone Microsoft product. It selects the configured File Search, Foundry IQ, or federated/indexed enterprise path and normalizes citations. The architecture targets the new Microsoft Foundry Agent Service (Responses API-based). 9. Security and governance Section 9 — Security and governance Use approved noncustomer documents for initial research. Validate source permissions and prevent restricted content disclosure. Azure AI Search does not automatically preserve original repository ACLs when content is copied into an index. Indexed security trimming requires appropriate ACL fields and identity-aware filters or supported permission integration; not every knowledge source provides user-level trimming out of the box. Customer data requires organizational approvals. 10. Independent POC evaluation and success criteria Evaluate only the approach or approaches an organization is considering. A side-by-side comparison is optional, not a required sequence. If comparing File Search and Foundry IQ, use identical documents, questions, models, and prompts where possible. Section 10 — Independent POC evaluation and success criteria Illustrative acceptance target: at least 90% correct retrieval on a curated test set, valid citations for grounded responses, and reliable operation through the selected interface(s). These are proposed research criteria, not platform guarantees. Approach 3 additionally requires source-permission, cross-repository, and governance validation. 11. Independent estimates and potential deliverables Section 11 — Independent estimates and potential deliverables These are independent, illustrative POC estimates, not a cumulative rollout schedule. The Approach 2 estimate assumes compatible resources and an existing interface or Playground-only evaluation; building a new custom application can add effort. Approach 3 needs a separately scoped plan for connectors, access control, compliance reviews, testing, deployment, and operational readiness. 12. Research findings and needs-based architectural direction Approach 1: Consider Foundry File Search where a manageable document collection and simpler managed retrieval meet the organization’s requirements. Approach 2: Consider Foundry IQ where reusable knowledge, multiple agents, or greater search configurability are important. Approach 3: Consider unified enterprise retrieval where many systems, security boundaries, and content types must be integrated. No approach is universally preferred, and organization size alone is not a definitive selection criterion. A smaller organization may need advanced governance, while a large enterprise team may only need a focused File Search solution. Optional POCs using Approach 1 or 2 can inform an Approach 3 decision without becoming mandatory prerequisites. Envisioned outcome: A needs-appropriate, citation-grounded enterprise knowledge search experience built with Microsoft technologies, subject to technical validation, organizational security and privacy review, and responsible AI governance. The architectures remain independent research options rather than an endorsed implementation sequence. 13. Implementation notes and service lifecycle Current agent runtime: Target the current Microsoft Foundry Agent Service, not classic agents. Classic agents are deprecated and scheduled for retirement on March 31, 2027. Agentic retrieval: Foundry IQ query planning uses a supported model at low/medium reasoning effort. Minimal effort skips LLM query planning; model and API support must be checked. Availability and previews: Verify regional support, RBAC, API version, and GA-versus-preview status for File Search, Foundry IQ knowledge sources, and portal features before implementation. POC schedule: The illustrative estimates assume ready resources and a working Playground or reusable UI; region, permissions, and unsupported document formats can extend delivery. Technical validation: Microsoft Learn — Foundry File Search; Foundry IQ FAQ; Agentic Retrieval; Foundry Agent Service (classic) migration; Azure AI Search OCR and Document Layout skills.386Views0likes0Comments
How are people estimating LLM API costs before putting an AI application into production?
It's relatively easy to estimate the number of API requests, but I'm finding the token side more interesting because input and output usage can vary considerably between requests. Things get even more complicated when comparing different models or using long prompts and conversation history. Do you normally build a spreadsheet for this, use the provider's pricing information directly, or use a dedicated calculator? I'm especially interested in approaches that estimate monthly cost from expected requests, average input tokens, average output tokens, and the model being used.412Views1like4CommentsFrom Jev to Your Laptop: Building "System One" Decision Models in ONNX with Mobius
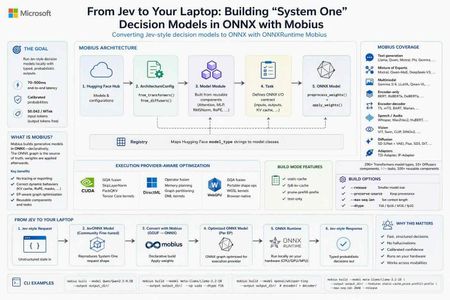
0. Why I'm writing this now Two things landed on my radar in the same week. First, TypeSafe AI published "Introducing System One Models & Jev" (Sep 15, 2026) and the developer community immediately started arguing about it. The pitch is unusual: instead of another chat model, Jev is described as "a new class of frontier models built to make fast, structured decisions that software can use directly." The post frames Jev as "a frontier-intelligence function call: unstructured state in, typed probabilistic decisions out" — and notes that while "Jev gives up string generation, it's optimized for structured outputs and can't hallucinate." The numbers in that post are what got everyone's attention: end-to-end response times of 70ms–500ms versus 3–329 seconds for frontier LLMs, input tokens at $0.042/MTok with output tokens free, and a claim that every answer arrives with a calibrated probability — "higher confidence means higher accuracy." The name itself is a thesis: TypeSafe named Jev after William Stanley Jevons, expecting that "every order of magnitude drop in the cost of intelligence unlocks orders of magnitude more use cases." Second — and this is the part that matters for anyone who builds on Microsoft's AI stack — onnxruntime/mobius has been quietly shipping at a furious pace. It's the piece of infrastructure that makes it realistic to take a model like this, in whatever format it arrives, and run it as an ONNX graph on hardware you control. So I built the bridge. kinfey/JevONNX takes an open, community-fine-tuned model that reproduces the System One request shape, converts it from GGUF to CPU ONNX with Mobius, and serves typed probabilistic decisions locally. This post covers three things: what Mobius is, how it differs from the ONNX Runtime GenAI Model Builder you may already be using, and how the JevONNX sample puts it together. 1. What is Mobius? Mobius builds generative models in ONNX. That preposition is the whole idea. From the repo's own description, Mobius provides "ONNX model definitions for GenAI using the onnxscript.nn API" — model definitions for "LLMs, MoE, multimodal, encoder-only, encoder-decoder, vision, audio, and diffusion models — built directly as ONNX graphs using onnxscript.nn.Module." The key sentence, and the one worth reading twice: "Rather than tracing or exporting PyTorch models, it constructs the ONNX graph declaratively, then applies pretrained HuggingFace weights." Why "declarative construction" is a big deal If you've ever exported a model to ONNX the traditional way, you know the failure modes. You run torch.onnx.export, the tracer executes one concrete path through Python control flow, and anything dynamic — a KV cache branch, a rotary embedding computed with a Python if, a sliding-window mask — either silently bakes in a constant or explodes into an unreadable subgraph. You then spend a week diffing graphs. Mobius inverts this. The graph is the source of truth, written as composable modules, and the weights are applied afterwards. The architecture in the README is four clean layers: HuggingFace Hub │ ▼ ArchitectureConfig ◄── from_transformers() / from_diffusers() │ ▼ Model Module ◄── Reusable Components (Attention, MLP, RMSNorm, RoPE, …) │ ▼ Task ◄── CausalLMTask, VisionLanguageTask, VAETask, DenoisingTask, … │ ▼ ONNX Model ◄── preprocess_weights() + apply_weights() Components — onnxscript.nn.Module building blocks (Attention, MLP, DecoderLayer, RoPE, VisionEncoder, MoELayer…) Models — full architectures composed from those components Tasks — define the ONNX graph's I/O contract (inputs, outputs, KV cache) Registry — maps HuggingFace model_type strings to model classes Adding a new architecture becomes writing a model definition, not debugging an exporter. Mobius even ships developer skills in .agents/skills/ (adding-a-new-model, reusable-components, moe-models, multimodal-models, writing-tests, writing-rewrite-rules) so an AI coding agent can do the legwork with you. Coverage This isn't a toy. The repo claims 290+ Transformers model types and 10 Diffusers component types across 40+ task types and 100+ reusable components, spanning: Category Examples Text generation Llama 2/3/4, Mistral, Qwen 2/2.5/3/3.5/3.6, Phi-3/3.5, Gemma 1/2/3/4, Granite, GPT-2, OPT, OLMo, SmolLM3 Mixture of Experts PhiMoE, GPTOSS, Mixtral, OLMoE, DeepSeek-V2/V3, Qwen2-MoE, Qwen3-MoE, Qwen3-Next, GLM-4-MoE, Arctic, DBRX, Jamba Multimodal Gemma 3/4, Phi-4MM (vision + audio + LoRA), LLaVA, InternVL2, MiniCPM-V 4.6, Qwen2.5-VL, Qwen3-VL, Pixtral Encoder-only BERT, RoBERTa, ALBERT, DeBERTa, DistilBERT, ELECTRA, XLNet Encoder-decoder BART, T5/mT5, Marian, M2M-100, Pegasus, BigBird-Pegasus Speech-to-text Whisper, Moonshine, Moonshine Streaming, FastConformer-RNNT, FunASR, GLM-ASR, Qwen3-ASR, SenseVoice Audio Wav2Vec2, HuBERT, WavLM, SpeechT5 Vision ViT, BEiT, DeiT, DINOv2, Swin, CLIP, SigLIP Diffusion Stable Diffusion (UNet + VAE + ControlNet), Flux, SD3, DiT, QwenImage / Qwen-Image-Edit-2509, HunyuanDiT, CogVideoX Adapters T2I-Adapter, IP-Adapter The five-minute version pip install -e . from mobius import build pkg = build("meta-llama/Llama-3.2-1B") pkg.save("output/llama-3.2-1b/") Static KV cache, when you know your max sequence length up front: from mobius import build, CausalLMTask task = CausalLMTask(static_cache=True, max_seq_len=2048) pkg = build("meta-llama/Llama-3.2-1B", task=task) pkg.save("output/llama-3.2-1b-static/") EP-aware optimization — the graph itself is tuned per execution provider, "each with the right set of fused kernels and lowering passes applied automatically": # CUDA: GQA fusion, SkipLayerNorm, PackQKV pkg = build("meta-llama/Llama-3.2-1B", execution_provider="cuda", dtype="f16") # WebGPU: GQA fusion, Shape ops replaced with portable alternatives pkg = build("meta-llama/Llama-3.2-1B", execution_provider="webgpu", dtype="f16") And the CLI, which is what we'll use later: mobius build --model Qwen/Qwen2.5-0.5B --output output_dir/ mobius build --model meta-llama/Llama-3.2-1B --output output_dir/ --ep cuda --dtype f16 mobius build --model openai/whisper-tiny --output output_dir/ # encoder/ + decoder/ Build-mode toggles use a cargo-style --features flag — available features are static-cache, fp8-kv-cache, prune-prefill-prefix, and text-only: mobius build --model meta-llama/Llama-3.2-1B --output output_dir/ \ --features static-cache,prune-prefill-prefix --max-seq-len 2048 --release strips build-time debug and provenance metadata to reduce saved model size, while preserving functional metadata keyed with the mobius. prefix. 2. Mobius vs. the ONNX Runtime GenAI Model Builder This is the question I get every time I demo Mobius, so let's be precise. Both are Microsoft tools, both produce ONNX, and they are not competitors — they sit at different points on the same pipeline. The ONNX Runtime GenAI Model Builder describes itself as the tool "for quickly creating optimized and quantized ONNX models within a few minutes that run with ONNX Runtime GenAI." Its output is a deployment-ready package: model.onnx plus genai_config.json plus tokenizer files, wired for the onnxruntime-genai runtime. Its architecture list is explicitly curated — AMD OLMo, ChatGLM, DeepSeek, ERNIE 4.5, Gemma, gpt-oss, Granite, Granite MoE Hybrid, HunYuan Dense V1, InternLM2, LFM2, LFM2 MoE, Llama, Mistral, Nemotron, Phi, Qwen, SmolLM3, Whisper — and the README states plainly that "it is intended for supporting the latest, popular state-of-the-art models." Mobius, by contrast, is a model-definition library: a component algebra for describing generative architectures as ONNX graphs, with a registry mapping HuggingFace model_type strings to model classes. Here's how I'd separate them: Dimension ORT GenAI Model Builder Mobius Primary goal Produce a deployment-ready GenAI package, fast Define and construct the ONNX graph itself Output contract model.onnx + genai_config.json + tokenizer, targeted at the ORT GenAI runtime ONNX model package; you choose the runtime (plain ORT sessions included) How the graph is made Per-architecture builder subclasses (LlamaModel, QwenModel, Phi3MiniModel, WhisperModel…) overriding make_layer / make_attention / make_moe Declarative onnxscript.nn.Module composition from reusable Components → Models → Tasks Breadth Curated list of ~19 popular families, text + Whisper 290+ Transformers types, 10 Diffusers component types, 40+ tasks — including vision, audio, and diffusion Extending it Add a builder subclass inside the onnxruntime-genai tree Add a model definition from existing components; shipped .agents/skills/ guide it Tuning surface Rich --extra_options for quantization and runtime behavior (QMoE, paged attention, KV-cache quantization, QDQ, CUDA/WebGPU graph capture…) --features build toggles + execution_provider= EP-aware graph lowering + dtype control Diffusion / multi-component pipelines Not the target First-class (--model Qwen/Qwen-Image-2512 builds all components) When I reach for it "I have a Phi/Llama/Qwen chat model and I want an int4 CPU/CUDA package running under ORT GenAI today" "My architecture is hybrid, unusual, multimodal, diffusion, or I need graph-level control over what gets emitted" Notably, the two overlap on real capabilities. The Model Builder also consumes GGUF and handles Qwen3.5-class features (compact state updates, recurrent-operator selection). Mobius also emits ORT-GenAI-compatible metadata — though the repo is honest about limits: for Mage-VL, "ORT GenAI export is currently rejected because the runtime cannot supply its required patch_positions input or Mage-VL's 1D decoder positions." That single line tells you exactly where the boundary sits: the Model Builder is bounded by what the GenAI runtime can express; Mobius is bounded by what ONNX can express. My rule of thumb as an advocate: if your model is on the Model Builder's supported list and you want the GenAI runtime's generation loop, use the Model Builder — it is faster and gives you a complete package. The moment you're off that list, or you need the graph itself to be a first-class artifact you can reason about and modify, Mobius is the tool. The JevONNX sample is squarely in the second category. Let's look at why. 3. The sample: converting a Jev-style decision model to CPU ONNX Repo: github.com/kinfey/JevONNX 3.1 The honest framing first Jev is TypeSafe's proprietary model. You can't download it and convert it, and this project doesn't pretend otherwise. What the community did do is interesting: n4ze3m/Qwen3.5-4B-Hmm is "an experimental open-model attempt to reproduce the central idea and request shape of the System One workflow introduced with Jev." It works by "fine-tuning Qwen3.5-4B to answer typed questions through option probabilities instead of ordinary generated text." The README of JevONNX is emphatic about the boundaries, and I want to repeat them here rather than bury them: "Hmm is not Jev, is not affiliated with TypeSafe AI, and does not reproduce Jev's proprietary model architecture, parallel sampler, performance, calibration, or type-safety guarantees. The Hmm model card explicitly states that it is less capable than Jev." And: "The reproduction is behavioral rather than architectural." The distinction, straight from the project's comparison table: Property Jev Hmm in this project Model design Native System One Model Qwen3.5-4B fine-tuned to reproduce the typed-decision concept Output mechanism Native typed probabilistic outputs First-token option-letter probabilities Multiple questions Designed for parallel sampling Jev-like request shape, implemented as one model pass per question Output types Schema-constrained structured values noul, choice, and score adapter Runtime here TypeSafe service Local ONNX Runtime CPU Guarantees As documented by TypeSafe No equivalent guarantee is claimed The mechanism is refreshingly legible: the adapter turns each typed question into an exact multiple-choice prompt, then "reads the first generated-token logits for A, B, C, and subsequent option letters and normalizes them into probabilities." No JSON parsing, no retry-on-malformed-output, no regex. The probability distribution is the answer. 3.2 Why this needs Mobius specifically Qwen3.5 is a hybrid architecture, and that's the whole reason this is a Mobius story. The exported model has 32 hybrid decoder layers. Linear-attention layers carry conv_state and recurrent_state; full-attention layers carry key/value caches. In this artifact, full-attention layers sit at indices 3, 7, 11, 15, 19, 23, 27, and 31. The practical consequence, quoted from the README: "The prompt is processed one token at a time while every present.* output is fed back into its corresponding past_key_values.* input. This differs from a conventional decoder-only example that can prefill an entire prompt in one call." That is a graph-shape problem. You cannot handwave it with a config flag — you need the exported graph's state contract to be explicit and inspectable, which is exactly what declarative construction gives you. The implementation "follows the structure of Mobius examples/text_generation.py while adding the hybrid-state handling required by Qwen3.5." 3.3 The conversion pipeline n4ze3m/Qwen3.5-4B-Hmm-Q4_K_M.gguf │ SHA-256 verification ▼ Mobius GGUF reader/importer │ metadata and tensor mapping │ Qwen3.5 hybrid graph construction │ Q4_K_M → packed quantized target storage │ CPU execution-provider optimization ▼ onnx_outputs/ ├── model.onnx ├── model.onnx.data ├── quantization_report.json ├── tokenizer.json ├── tokenizer_config.json ├── chat_template.jinja └── cpu_test_summary.json │ ▼ ONNX Runtime CPUExecutionProvider │ token-by-token hybrid-state prefill │ first-token A/B/C/… probabilities ▼ typed decision JSON response One command does the conversion: mobius build-gguf Qwen3.5-4B-Hmm-Q4_K_M.gguf \ --output onnx_outputs \ --ep cpu \ --dtype f32 \ --release Two details worth internalizing: --dequantize is intentionally not used. Keeping quantized storage "substantially reduc[es] the output size compared with a fully dequantized FP32 model." The external-data file is still ~2.6 GB — imagine it dequantized. Don't trust the preset, read the report. "Q4_K conversion can involve a lossy affine repack; inspect quantization_report.json rather than assuming source-preset fidelity." This is the kind of line that separates a demo from a deployment. 3.4 Reproducibility — the part I actually want you to copy Every pin, in a table, in the README: Component Revision GGUF repository n4ze3m/Qwen3.5-4B-Hmm GGUF revision c27fa3c627dfaced343c6ba9d3a0d00243a3be51 GGUF filename Qwen3.5-4B-Hmm-Q4_K_M.gguf GGUF SHA-256 5e03cb057049c56b421bd3c506d77fd8e0a77996bb8464148a02cfc3caac5229 Mobius revision 6b27a3f08b8b5d08ba9b14b416e3b435942bb0bd Tokenizer repository Qwen/Qwen3.5-4B Tokenizer revision 851bf6e806efd8d0a36b00ddf55e13ccb7b8cd0a The notebook builds a Mobius wheel from the pinned Git source rather than installing a prebuilt package. On a project moving at 500+ commits, that is not paranoia — that is the only way your conversion is still reproducible next month. 3.5 Running it Two files carry the project: Qwen3_5_4B_Hmm_GGUF_to_CPU_ONNX_Mobius_fixed.ipynb (the Colab conversion and validation workflow) and run_hmm_onnx.py (the standalone typed-decision runner). Run the notebook in a high-memory Colab CPU runtime; it writes to /content/onnx_outputs on Colab and .mobius_colab_run/onnx_outputs elsewhere. Then: python run_hmm_onnx.py --model-dir .mobius_colab_run/onnx_outputs python run_hmm_onnx.py --model-dir .mobius_colab_run/onnx_outputs --request request.json A request is state plus typed questions: { "state": "Help! My payouts have failed for 3 days. I need the money today.", "questions": { "is_urgent": { "type": "noul", "instructions": "Does this message convey urgency?" }, "department": { "type": "choice", "instructions": "Which team should handle this?", "criteria": { "billing": "Payments, invoicing, refunds", "technical": "Bugs, outages, integrations", "sales": "Pricing, upgrades, new accounts" } }, "priority": { "type": "score", "instructions": "How urgent is this request?", "criteria": ["Not urgent", "Normal", "Urgent", "Critical"] } } } From Python: from pathlib import Path from run_hmm_onnx import HmmOnnx model = HmmOnnx(Path(".mobius_colab_run/onnx_outputs")) response = model.decide({ "state": "Help! My payouts have failed for 3 days.", "questions": { "is_urgent": { "type": "noul", "instructions": "Does this message convey urgency?", } }, }) print(response) 3.6 The three decision types noul — a nullable-style yes/no probability; the probability of the true option: { "type": "noul", "noul": 0.9745 } choice — the highest-probability key, all normalized option probabilities, and a confidence value measuring how peaked the distribution is: { "type": "choice", "choice": "billing", "probabilities": { "billing": 0.7216, "technical": 0.2759, "sales": 0.0025 }, "confidence": 0.5823 } score — the expected numeric level, the level legend, normalized probabilities, and confidence: { "type": "score", "score": 2.6653, "legend": { "0": "Not urgent", "1": "Normal", "2": "Urgent", "3": "Critical" }, "probabilities": { "0": 0.0061, "1": 0.0361, "2": 0.2443, "3": 0.7135 }, "confidence": 0.618 } Look at that score output for a second. You don't get "this is critical." You get 2.6653 — a distribution leaning hard on Critical but with real mass on Urgent. That's a number your routing code can threshold on, log, and A/B test. It's the difference between an LLM that says it's confident and a distribution you can actually calibrate against. One constraint: Hmm is trained with 26 option letters. Larger option sets are handled by splitting them into groups of 25 and adding a none_of_these option to each group, matching the reference Hmm server strategy. 3.7 Does it actually run? Yes — the README reports the generated model executed directly on an Apple Silicon CPU with ONNX Runtime. A 4B hybrid-architecture model, converted from GGUF, running typed decisions on a laptop CPU with no service dependency. 4. What I'd tell a room of developers The System One idea is portable even where the model isn't. You can't run Jev locally, but the shape — state in, typed decisions with probabilities out — is something you can prototype today with an open model and an ONNX graph. As TypeSafe puts it, structured outputs "slot into ordinary software as fuzzy decision rules: classify, route, score, extract, or branch where hand-written logic is too brittle." That's a pattern, not a product. Probabilities are the actual product. The reason this class of model matters isn't speed alone. TypeSafe's argument is sharp: "If a model can do a task 95% of the time but doesn't say when it's in the 5%, it can't automate that task." Every engineer who has shipped an LLM feature has felt that exact wall. Set expectations honestly. JevONNX is an educational reproduction. It gives you noul/choice/score on a local CPU. It does not give you Jev's calibration, parallel sampler, or type-safety guarantees — and the project says so in its own README. Ship that caveat with your demo. Mobius is the infrastructure bet worth learning. When a new architecture shows up — hybrid attention, a novel MoE routing scheme, a three-model multimodal export — the question stops being "will the exporter support it?" and becomes "which components do I compose?" That is a much better question to be asking. Links Mobius — https://github.com/onnxruntime/mobius (docs: https://onnxruntime.github.io/mobius/) ONNX Runtime GenAI Model Builder — https://github.com/microsoft/onnxruntime-genai/tree/main/src/python/py/models JevONNX sample — https://github.com/kinfey/JevONNX Introducing System One Models & Jev — https://typesafe.ai/blog/introducing-system-one-models-and-jev Hugging face - https://huggingface.co/lokinfey/Qwen3_5_4B_Hmm_ONNX1.4KViews1like0Comments
GenRec Direct Learning: Moving Ranking from Feature Pipelines to Token-Native Sequence Modeling
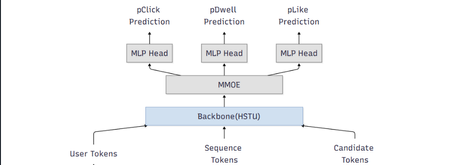
Authors: Chunlong Yu, Han Zheng, Jie Zhu, Neal Zhang, Li Xia, Lin Zhu, Sawyer Shen, Yulan Yan TL;DR Most modern ranking stacks rely on large generative models as feature extractors, flattening their outputs into vectors that are then fed into downstream rankers. While effective, this pattern introduces additional pipeline complexity and often dilutes token‑level semantics. GenRec Direct Learning (DirL) explores a different direction: using a generative, token‑native sequential model as the ranking engine itself. In this formulation, ranking becomes an end‑to‑end sequence modeling problem over user behavior, context, and candidate items—without an explicit feature‑extraction stage. Why revisit the classic L2 ranker design? Large‑scale recommender systems have historically evolved as layered pipelines: more signals lead to more feature plumbing, which in turn introduces more special cases. In our previous L2 ranking architecture, signals were split into dense and sparse branches and merged late in the stack (Fig. 1). As the system matured, three recurring issues became increasingly apparent. Figure 1: traditional ranking DNN 1) Growing pipeline surface area Each new signal expands the surrounding ecosystem—feature definitions, joins, normalization logic, validation, and offline/online parity checks. Over time, this ballooning surface area slows iteration, raises operational overhead, and increases the risk of subtle production inconsistencies. 2) Semantics diluted by flattening Generative models naturally capture rich structure: token‑level interactions, compositional meaning, and contextual dependencies. However, when these representations are flattened into sparse or dense feature vectors, much of that structure is lost—undermining the very semantics that make generative representations powerful. 3) Sequence modeling is treated as an add-on While traditional rankers can ingest history features, modeling long behavioral sequences and fine‑grained temporal interactions typically requires extensive manual feature engineering. As a result, sequence modeling is often bolted on rather than treated as a first‑class concern. DirL goal: treat ranking as native sequence learning, not as “MLP over engineered features.” What “Direct Learning” means in DirL The core shift behind Direct Learning (DirL) is simple but fundamental. Instead of the conventional pipeline: generative model → embeddings → downstream ranker, DirL adopts an end‑to‑end formulation: tokenized sequence → generative sequential model → ranking score(s). In DirL, user context, long‑term behavioral history, and candidate item information are all represented within a single, unified token sequence. Ranking is then performed directly by a generative, token‑native sequential model. This design enables several key capabilities: Long‑term behavior modeling beyond short summary windows The model operates over extended user histories, allowing it to capture long‑range dependencies and evolving interests that are difficult to represent with fixed‑size aggregates. Fine‑grained user–content interaction learning By modeling interactions at the token level, DirL learns detailed behavioral and content patterns rather than relying on coarse, pre‑engineered features. Preserved cross‑token semantics within the ranking model Semantic structure is maintained throughout the ranking process, instead of being collapsed into handcrafted dense or sparse vectors before scoring. Architecture overview (from signals to ranking) 1) Unified Tokenization All inputs in DirL are converted into a shared token embedding space, allowing heterogeneous signals to be modeled within a single sequential backbone. Conceptually, each input sequence consists of three token types: User / context tokens These tokens encode user or request‑level information, such as age or cohort‑like attributes, request or canvas context, temporal signals (e.g., day or time), and user‑level statistics like historical CTR. History tokens These represent prior user interactions over time, including signals such as engaged document IDs, semantic or embedding IDs, and topic‑like attributes. Each interaction is mapped to a token, preserving temporal order and enabling long‑range behavior modeling. Candidate tokens Each candidate item to be scored is represented as a token constructed from document features and user–item interaction features. These features are concatenated and projected into a fixed‑dimensional vector via an MLP, yielding a token compatible with the shared embedding space. Categorical features are embedded directly, while dense numerical signals are passed through MLP layers before being fused into their corresponding tokens. As a result, the model backbone consumes a sequence of the form: [1 user/context token] + [N history tokens] + [1 candidate token] 2) Long-sequence modeling backbone (HSTU) To model long input sequence, DirL adopts a sequential backbone designed to scale beyond naïve full attention. In the current setup, the backbone consists of stacked HSTU layers with multi‑head attention and dropout for regularization. The hidden state of the candidate token from the final HSTU layer is then fed into an MMoE module for scoring. 3) Multi-task prediction head (MMoE) Ranking typically optimizes multiple objectives (e.g., engagement‑related proxies). DirL employs a multi‑gate mixture‑of‑experts (MMoE) layer to support multi‑task prediction while sharing representation learning. The MMoE layer consists of N shared experts and one task‑specific expert per task. For each task, a gating network produces a weighted combination of the shared experts and the task‑specific expert. The aggregated representation is then fed into a task‑specific MLP head to produce the final prediction. Figure 2: DirL structure Early experiments: what worked and what didn’t What looked promising Early results indicate that a token‑native setup improves both inhouse evaluation metrics and online engagement (time spent per UU), suggesting that modeling long behavior sequences in a unified token space is directionally beneficial. The hard part: efficiency and scale The same design choices that improve expressiveness also raise practical hurdles: Training velocity slows down: long-sequence modeling and larger components can turn iteration cycles from hours into days, making ablations expensive. Serving and training costs increase: large sparse embedding tables + deep sequence stacks can dominate memory and compute. Capacity constraints limit rollout speed: Hardware availability and cost ceilings become a gating factor for expanding traffic and experimentation. In short: DirL’s main challenge isn’t “can it learn the right dependencies?”—it’s “can we make it cheap and fast enough to be a production workhorse?” Path to production viability: exploratory directions Our current work focuses on understanding how to keep the semantic benefits of token‑native modeling while exploring options that could help reduce overall cost. 1) Embedding tables consolidate and prune oversized sparse tables rely more on shared token representations where possible 2) Right-size the sequence model reduce backbone depth where marginal gains flatten evaluate minimal effective token sets—identify which tokens actually move metrics. explore sequence length vs. performance curves to find the “knee” 3) Inference and systems optimization dynamic batching tuned for token-native inference kernel fusion and graph optimizations quantization strategies that preserve ranking model behavior Why this direction matters DirL explores a broader shift in recommender systems—from feature‑heavy pipelines with shallow rankers toward foundation‑style sequential models that learn directly from user trajectories. If token‑native ranking can be made efficient, it unlocks several advantages: Simpler modeling interfaces, with fewer feature‑plumbing layers. Stronger semantic utilization, reducing information loss from aggressive flattening. A more natural path to long‑term behavior and intent modeling. Early signals are encouraging. The next phase is about translating this promise into practice—making the approach scalable, cost‑efficient, and fast enough to iterate as a production system. Using Microsoft Services to Enable Token‑Native Ranking Research This work was developed and validated within Microsoft’s internal machine learning and experimentation ecosystem. Training data was derived from seven days of MSN production logs and user behavior labels, encompassing thousands of features, including numerical, ID‑based, cross, and sequential features. Model training was performed using a PyTorch‑based deep learning framework built by the MSN infrastructure team and executed on Azure Machine Learning with a single A100 GPU. For online serving, the trained model was deployed on DLIS, Microsoft’s internal inference platform. Evaluation was conducted through controlled online experiments on the Azure Exp platform, enabling validation of user engagement signals under real production traffic. Although the implementation leverages Microsoft’s internal platforms, the core ideas behind DirL are broadly applicable. Practitioners interested in exploring similar approaches may consider the following high‑level steps: Construct a unified token space that captures user context, long‑term behavior sequences, and candidate items. Apply a long‑sequence modeling backbone to learn directly from extended user trajectories. Formulate ranking as a native sequence modeling problem, scoring candidates from token‑level representations. Evaluate both model effectiveness and system efficiency, balancing gains in expressiveness against training and serving cost. Call to action We encourage practitioners and researchers working on large‑scale recommender systems to experiment with token‑native ranking architectures alongside traditional feature‑heavy pipelines, compare trade‑offs in modeling power and system efficiency, and share insights on when direct sequence learning provides practical advantages in production environments. Acknowledgement: We would like to acknowledge the support and contributions from several colleagues who helped make this work possible. We thank Gaoyuan Jiang and Lightning Huang for their assistance with model deployment, Jianfei Wang for support with the training platform, Gong Cheng for ranker monitoring, Peiyuan Xu for sequential feature logging, and Chunhui Han and Peng Hu for valuable discussions on model design.Introducing Inside Microsoft Foundry: Quickstart 🎬
Discover Inside Microsoft Foundry: Quickstart, a new video series for developers building AI agents. Starting with "What does it really take to ship an AI agent?", the series explores real-world challenges such as model selection, grounding agents in data, evaluation, deployment, observability, and governance. Follow along as we show how the Microsoft Foundry ecosystem helps developers move from prototype to production, with new episodes released in the coming weeks.Adding a Fallback Model to Hermes with Microsoft Foundry
So the plan was simple. Leave the Bedrock configuration untouched, then wire Microsoft Foundry in behind it as a fallback, so Hermes always has somewhere else to go when the primary provider is not responding. A few other reasons pushed me towards Foundry in particular: Redundancy that does not need me. If Bedrock is throttled or out of quota, I want Hermes to fail over on its own rather than waiting for me to notice. A catalogue I already pay for. Foundry puts the latest GPT models next to open-weight and partner models in one place, so I can pick a model that suits the task instead of settling for whatever a single provider happens to offer. Enterprise controls out of the box. Region pinning, private networking, content filters and per-deployment quota all sit in the same portal, which makes the setup far easier to defend to a security reviewer. Learning the mechanics before I need them. Working out how Hermes handles a provider chain is much nicer on a quiet Tuesday than during a live outage. Here is the short version, if you are deciding whether to read on. Time: about thirty minutes if nothing goes wrong. Cost: pay-as-you-go tokens only, and none at all while the fallback sits idle. Result: an assistant that keeps answering when your primary provider stops. Before you start, you will need three things: a machine with Hermes already installed and a working primary provider configured, an Azure subscription with access to Microsoft Foundry in a region you can actually deploy into, and enough quota in that region to create a deployment. One thing that made this easy to justify: Foundry deployments bill per token on the standard pay-as-you-go tier. A fallback provider that never gets invoked costs nothing beyond the requests it actually serves, so the insurance is close to free until the day you need it. Chat surface (CLI, messaging) → Hermes Gateway → Primary Amazon Bedrock → Fallback Microsoft Foundry Figure 1: Where the fallback sits. Every request goes through the Hermes gateway to the primary provider; only when that provider is unavailable does the chain continue to Microsoft Foundry. Part 1: Deploying a Model on Microsoft Foundry The first half of this job happens entirely inside the Microsoft Foundry portal and has nothing to do with Hermes yet. All you are really doing here is making sure your Azure subscription can serve a model, and that you hold an endpoint and key Hermes can authenticate with later. 1. Deploy model in Foundry → 2. Copy endpoint + key → 3. hermes fallback add → 4. Authenticate → 5. Select models, test Figure 2: The whole setup in five moves. The first two happen in the Microsoft Foundry portal (orange); the rest happen on the Hermes machine (blue). Go to Microsoft Foundry > Build > Models > Deploy > Deploy a base model. You can deploy a fine-tuned model instead if you already have one, which works just as well with Hermes. Check the region shown at the top of the portal before you commit, because both model availability and deployment quota differ from one region to the next. Then deploy the model you have selected: In this case I deployed gpt-5.6-sol, which is the model Hermes will fall back to. The choice was deliberate rather than exciting. My primary model on Bedrock is a general-purpose chat model, and a fallback is only useful if the answers it gives feel like a continuation of the same conversation rather than a different assistant wearing the same name. The gpt-5.6-sol deployment matches that behaviour closely, it was available in the region I wanted to pin, and the quota I was granted comfortably covers a day of normal use. If a fallback surprises you the first time it fires, it is the wrong fallback. Once the deployment finishes, open it and take note of two values: the target endpoint URI and the API key. Copy both somewhere safe now, because you will be pasting them into Hermes in the next part. If your organisation rotates keys on a schedule, use a key with the longest life you are allowed, since a fallback secured with a credential that expires quietly stops being a fallback. What to copy Where it lives in the portal Where Hermes asks for it Target endpoint URI Deployment > Endpoint > Target URI "Endpoint" prompt in hermes fallback add API key Deployment > Endpoint > Key "API key" prompt, or choose Entra ID instead Deployment name Deployment > Details > Name Shown in the model list Hermes returns Region Top of the portal, next to the resource Must match the region you deployed into Figure 3: Everything Hermes will ask for, and where to find each value before you leave the portal. Part 2: Adding Foundry to Hermes as a Fallback With the Foundry side sorted, everything from here happens in the Hermes CLI. One thing worth knowing before you start: this is the fallback command, not the primary model command, so your existing Bedrock configuration is left completely alone. Nothing in this section can break what is already working, which makes it a good one to try on a live setup. Run the Hermes fallback command: When Hermes asks which provider to add, choose Azure Foundry. The picker still carries the old name; it is the same service that the portal now calls Microsoft Foundry. Paste the target endpoint URI from your deployment, then authenticate with the API key you copied earlier. Hermes also offers Microsoft Entra ID at this prompt, which is the better option if your organisation would rather not have a static key sitting on the machine. If authentication fails here, check the endpoint before you start suspecting the key. In my experience the endpoint is wrong far more often than the credential is, usually because the deployment name at the end of the URI does not match the deployment you actually created. Once authentication succeeds, Hermes lists the deployments your Foundry resource exposes and asks which ones you want to use. You can select more than one, and the order is not cosmetic: Hermes walks down the chain from top to bottom whenever the provider above is unavailable. Treat that list as a priority order, not a shopping basket. What happens to the primary What Hermes does What you see in the chat Responds normally Routes every request to the primary and never touches the chain Nothing. The fallback stays idle Throttled or out of quota Retries the next provider down the chain on the same request A reply, served by the fallback model Endpoint unreachable Keeps failing over on each new request until the primary recovers Slightly different tone and latency, but a working assistant Every provider fails Returns the error rather than hanging An error worth chasing with hermes status Figure 4: The chain in practice. The fallback only earns its keep in the middle two rows, which is exactly why it is easy to forget you configured it. Part 3: Promoting Foundry to the Primary Model At this stage Foundry is sitting in the back seat as a backup. I wanted to reverse the arrangement and make Foundry the primary while Bedrock slides down into the fallback slot, partly because I preferred keeping day-to-day traffic inside my Azure subscription, and partly because I wanted proof the chain works in both directions. Before promotion After promotion Primary: Amazon Bedrock → Primary: Microsoft Foundry Fallback: Microsoft Foundry → Fallback: Amazon Bedrock Figure 5: The promotion, in effect. Nothing is added or removed; the two providers simply trade places in the chain. There is no dedicated "promote" command in Hermes, so the manual route is a short sequence of steps rather than a single instruction: Select the fallback provider/model as the new primary: hermes model Remove the now-duplicate model from the fallback chain: hermes fallback remove Optionally add the old primary model as a fallback: hermes fallback add Restart the messaging gateway: hermes gateway restart Verify the result: hermes status / hermes fallback list That sequence works, and it is good to know what is happening underneath. But since I already had a working provider configured, I would rather just ask Hermes to rearrange itself. This is the part I genuinely enjoy about the tool: the configuration is something you can talk to, not only something you type commands at. Prompt: Okay now please make the model I configured on Microsoft Foundry into the main model, and make the Bedrock one the fallback model! Hermes rewrites the provider chain on its own and confirms the swap once it is done, which is a great deal less error-prone than running the five commands by hand. Part 4: Testing the Switch Configuration you have not tested is just an assumption with extra steps, so the next thing is to confirm Hermes really is talking to Foundry. Type /model when running Hermes to bring up the model picker. You will be prompted to select a provider first. Pick the Microsoft Foundry entry, then choose the specific deployment from the list underneath it. The active model should switch straight away. Send it a plain "Hello" to check that the deployment actually responds, rather than just looking correct in the menu. Appearing in a dropdown and serving a request are two very different things. A second test is worth the thirty seconds it costs: run hermes status to confirm which provider is live, then hermes fallback list to confirm the chain is ordered the way you intended. The picker tells you what you selected; those two commands tell you what Hermes will actually do at three in the morning. Part 5: The Obstacle, and What It Actually Taught Me Every walkthrough has the part the author quietly leaves out. Here is mine: the wrinkle was not the model, it was capacity. My first attempt deployed into the region closest to me out of habit, and the portal turned it down because there was no capacity left for that model at the tier I asked for. The model was clearly listed in the catalogue; being listed and being deployable in your region, on your subscription, at your quota, are three separate questions. Redeploying in a different region fixed it in a couple of minutes, but it meant the endpoint URI changed, which in turn meant the value I had already pasted into Hermes was stale. Re-running hermes fallback add against the new endpoint sorted it out. The lesson is cheap enough to hand over for free: check quota and regional capacity for your specific subscription before you design a walkthrough, a demo or a production fallback around one deployment. In the Foundry portal, Management then Quota shows exactly what you have been granted per region and per model family, which is the only list that matters. Symptom Likely cause Fix Deployment rejected in the portal No capacity for that model at the tier you asked for, in that region Deploy in another region, or drop to a smaller tier Hermes rejects the credential Endpoint URI does not match the deployment you created Re-copy the target URI from the deployment, not the resource Provider authenticates but lists nothing Key belongs to a different Foundry resource Check you are in the right resource, then re-run hermes fallback add Fallback never fires Chain ordered the wrong way round hermes fallback list, then reorder Figure 6: The four things that went wrong, or nearly did, and what fixed each one. There is a silver lining worth stating plainly. Because the fallback chain was already in place, a deployment that refused to come up did not take the assistant down with it. That is precisely the scenario this whole exercise was meant to cover, and it turned up on day one without me having to simulate it. Command Cheat Sheet Everything used in this walkthrough, collected in one place: hermes fallback add: attach a provider to the fallback chain hermes fallback remove: drop a provider from the chain hermes fallback list: show the chain in priority order hermes model: set the primary model hermes gateway restart: restart the messaging gateway after a change hermes status: confirm which provider is currently live /model: switch models from inside a running session Conclusion Adding Microsoft Foundry as a fallback behind my existing Bedrock setup took an afternoon, and most of that was spent recovering from a regional capacity limit I should have checked first. The work itself is small: deploy a model, copy the endpoint and key, run hermes fallback add, authenticate, pick your deployments. The payoff is that Hermes no longer depends on one provider staying healthy. Three things are worth carrying away from this: Check quota, not just the catalogue. The Foundry catalogue shows what Microsoft offers. It does not show what your subscription and region can actually deploy today. Confirm that first, before you build anything on top of a specific deployment. Order your fallback chain deliberately. Hermes works down the list from top to bottom, so the sequence you choose during setup is the failover policy you are going to live with. Put the model you actually trust at the top. Treat the endpoint as part of the credential. Redeploying in a new region changes the endpoint URI, and a fallback pointed at an endpoint that no longer exists is not a fallback. Re-run the setup whenever the deployment moves. The switch from Bedrock primary to Foundry primary also proved the chain runs in both directions, which is the real point. Provider redundancy is only useful if you have watched it work. Next on my list is deliberately breaking the primary provider to confirm the failover triggers on its own, without me typing a single command. If you run this against a different model, region or provider pairing, I would genuinely like to know how it went, particularly if your quota experience was better than mine. Drop it in the comments.416Views0likes0CommentsDistributing Agents to Microsoft Teams and Microsoft 365 Copilot Part 4/5
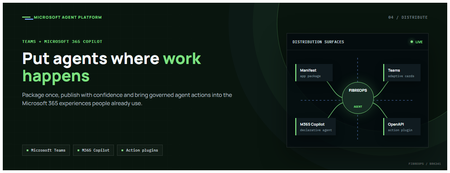
This is the fourth post in our series on the Microsoft agent platform. We cover the Distribute in M365 pillar — publishing your agents to Microsoft Teams and Microsoft 365 Copilot so they reach users where they already work. All examples reference the FibreOps repository, demonstrated at Microsoft Build BRK241. The Distribution Story Building a great agent is only half the challenge. The other half is getting it into the hands of users without asking them to learn a new tool, visit a new URL, or change their workflow. Microsoft 365 Copilot and Microsoft Teams are where enterprise users already spend their day, making them the natural distribution surface for agents. With the GA release, publishing an agent to Teams and M365 Copilot is a single command. No separate app registration portal, no manual manifest assembly, no multi-step approval workflow for development and testing. Publishing to Microsoft 365 Copilot (GA) FibreOps ships as a declarative agent + action plugin ready for sideload. A single CLI command produces the complete package: python -m fibreops.demo publish-m365 --out dist/m365 # Output: # ✓ wrote dist/m365/declarativeAgent.json # ✓ wrote dist/m365/fibreops-action.json # ✓ wrote dist/m365/manifest.json # ✓ wrote dist/m365/color.png (192x192) # ✓ wrote dist/m365/outline.png ( 32x32) # ✓ wrote dist/m365/fibreops-copilot.zip What Gets Generated File Purpose declarativeAgent.json Defines the agent's persona, capabilities, and conversation starters for M365 Copilot fibreops-action.json Action plugin that proxies tool calls to the deployed FastAPI backend via OpenAPI manifest.json Teams app manifest with publisher metadata, permissions, and capabilities color.png / outline.png App icons for Teams and M365 surfaces fibreops-copilot.zip Ready-to-upload package for Teams Admin Center Configuration Set the base URL to your deployed FastAPI app before publishing — the action plugin uses this to resolve the OpenAPI runtime: # Set the public HTTPS hostname of the deployed FastAPI app $env:M365_ACTION_BASE_URL = "https://fibreops-demo.azurewebsites.net" # Optional: customise publisher metadata $env:M365_PUBLISHER_NAME = "Contoso Network Operations" $env:M365_PUBLISHER_WEBSITE = "https://contoso.com/noc" # Generate the package python -m fibreops.demo publish-m365 --out dist/m365 Environment Variable Purpose M365_ACTION_BASE_URL Public HTTPS root for the FastAPI /openapi.json (e.g., Container Apps FQDN) M365_APP_ID Override the generated Teams app GUID (default: deterministic per repo) M365_PUBLISHER_NAME Publisher name shown in M365 Admin Center M365_PUBLISHER_WEBSITE Publisher website link Uploading the Package Upload the generated fibreops-copilot.zip through either path: Teams Admin Center → Manage apps → Upload new app M365 Admin Center → Integrated apps → Upload custom apps Once uploaded, the declarative agent: Inherits the publisher metadata you configured Advertises conversation starters from the FibreOps deck (e.g., "What is the current outage status?", "Dispatch an engineer to FN-LDN-001") Proxies tool calls to the deployed FastAPI app via the action plugin Appears in Microsoft 365 Copilot as a specialised agent users can invoke How Declarative Agents Work A declarative agent in Microsoft 365 Copilot is defined by metadata rather than code running in the M365 surface. The intelligence lives in your backend — Copilot handles the conversational UX, tool orchestration schema, and user authentication. The flow: User invokes the agent in Microsoft 365 Copilot or Teams Copilot renders conversation starters and accepts natural language input When the agent needs to act, Copilot calls the action plugin (your OpenAPI endpoint) Your FastAPI backend processes the request using the full agent pipeline Results return to the user in the Copilot/Teams UX This architecture means your agent logic stays in one place — the backend. The M365 surface is purely a distribution and interaction layer. Action Plugins and OpenAPI The action plugin ( fibreops-action.json ) references your FastAPI app's /openapi.json endpoint. FibreOps exposes a JSON API that the action plugin can call: /api/runs — List and query agent runs /api/optimiser — Get optimizer scores and suggestions /sdk/chat — Natural language interaction with the agent system /healthz — Liveness probe Because FastAPI auto-generates OpenAPI schemas from your typed Python endpoints, the action plugin gets accurate parameter descriptions, response schemas, and error codes without any manual specification work. Publishing as Autopilots (Public Preview) Autopilots take distribution one step further — agents that operate autonomously without requiring a user to initiate each interaction. An Autopilot can: React to events (e.g., a critical telemetry signal) without human initiation Take actions within defined guardrails Notify users only when human intervention is needed Operate continuously across Microsoft 365 surfaces For FibreOps, an Autopilot would monitor the Event Hub stream continuously and only surface to the NOC team when an incident exceeds automated resolution capability — a fully autonomous operations agent. Teams Adaptive Cards FibreOps posts rich Adaptive Card notifications to Microsoft Teams throughout the agent pipeline. This is separate from the declarative agent — it is a push notification channel for real-time operational awareness. # The NetOps agent posts an outage notice via Incoming Webhook def post_outage_notice(incident_id, node_id, severity, summary, engineer=None): card = { "type": "AdaptiveCard", "body": [ {"type": "TextBlock", "text": f"🚨 Outage: {node_id}", "weight": "Bolder", "size": "Large"}, {"type": "FactSet", "facts": [ {"title": "Severity", "value": severity.upper()}, {"title": "Incident", "value": incident_id}, {"title": "Summary", "value": summary}, ]}, ], "actions": [ {"type": "Action.OpenUrl", "title": "View in NOC Console", "url": f"{base_url}/runs/{incident_id}"} ] } # POST to Teams webhook or append to outbox for offline mode ... If TEAMS_WEBHOOK_URL is not configured, cards are appended to state/teams_outbox.jsonl for review in the NOC console's Teams panel. End-to-End: From Code to Copilot Here is the complete flow from development to distribution: Build — Develop agents with Microsoft Agent Framework, test locally with python -m fibreops.demo --backend local Publish agents — python -m fibreops.demo publish creates hosted Prompt Agents in Foundry Deploy infrastructure — azd up provisions App Service, ACR, Event Hub, Key Vault, and Application Insights Deploy hosted agent — azd env set FIBREOPS_DEPLOY_HOSTED true && azd up Generate M365 package — python -m fibreops.demo publish-m365 --out dist/m365 Upload to Teams — Upload fibreops-copilot.zip via Teams Admin Center Users interact — The agent is now available in Microsoft 365 Copilot and Teams Security Considerations Managed Identity — The deployed app uses system-assigned managed identity for all Azure service access. No secrets in code. Least privilege — Each role grant is scoped to the minimum required (Event Hubs Data Owner, Key Vault Secrets User, AcrPull, Azure AI Developer). Authentication — The M365 Copilot surface handles user authentication; your backend receives authenticated requests. Guardrails — Autopilots operate within defined boundaries; human-in-the-loop escalation is built into the Routine and agent decision logic. Key Takeaways Publishing to Teams and M365 Copilot is GA — a single command generates the complete package. Declarative agents separate distribution (M365) from intelligence (your backend). Action plugins leverage your existing FastAPI OpenAPI schema — no manual specification needed. Autopilots (Public Preview) enable fully autonomous operation within guardrails. Adaptive Cards provide real-time push notifications alongside the conversational agent surface. The same backend serves the NOC console, the Copilot SDK, and the M365 declarative agent. Next Steps Explore the FibreOps repository — try python -m fibreops.demo publish-m365 Microsoft 365 Copilot extensibility documentation Next in this series: Voice Live and Observability for Production Agent Systems