high availability
22 TopicsSeconds of Downtime, Hours of Confusion: Handling Transient Azure SQL Disconnects
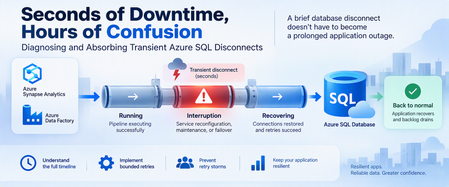
A database can recover in seconds while an application remains unavailable for much longer. Brief connectivity interruptions are expected failure modes that cloud applications should be designed to tolerate. With Azure SQL Database, transient connectivity errors can occur during short-lived service reconfiguration events. Microsoft notes that many such reconfiguration events complete in less than 60 seconds and recommends that applications implement retry logic rather than immediately surfacing transient failures to users. But the database interruption is only part of the story. An application might continue experiencing problems because of: Failed connections. Lost in-flight operations. Retry behavior. Connection-pool recovery. Authentication or token issues. Queued requests. Application instances retrying simultaneously. Backlogs that must drain after connectivity returns. This leads to an important troubleshooting principle: Database recovery and application recovery are separate milestones. Understanding that difference can turn a confusing availability incident into a defensible timeline and, more importantly, a more resilient application design. 1. Transient Does Not Mean Harmless A transient interruption is temporary, but its application impact doesn't have to be. Consider a simplified timeline: Time Event T0 Application healthy T1 Database connectivity is interrupted T2 Database connectivity becomes available again T3 Applications reconnect T4 Request backlog begins draining T5 Application returns to normal The actual database connectivity event is: T1 → T2 But users might experience impact across: T1 → T5 Calling the entire T1-to-T5 period a continuous database outage would be inaccurate unless evidence proves that the database itself remained unavailable. Instead, investigate the periods separately. 2. Build a Three-Layer Timeline A good post-incident investigation should correlate three timelines. Layer 1: Database/connectivity behavior Capture: Connection failures. Successful reconnections. Relevant Azure monitoring signals. Azure Service Health information when applicable. Database resource behavior. Layer 2: Client connectivity Capture: SQL exception number. Exception timestamp in UTC. Connection timeout. Retry attempts. Retry delays. Authentication failures. Network errors. Azure SQL troubleshooting guidance recommends logging failure timestamps and notes that SQL Database can return tracing information helpful during connectivity investigations. Layer 3: Application recovery Capture: Application health. Request failures. Queue depth. Retry volume. Connection-pool recovery. Backlog drain time. Time when users actually recovered. The timelines might reveal: Database connectivity restored │ ▼ Applications reconnect │ ▼ Backlog continues │ ▼ Application fully recovered That distinction is essential. 3. Classify the Failure Before Retrying It Not every SQL connectivity error means the same thing. Classify the symptom into categories such as: Transient availability/connectivity failure. Authentication failure. Token-related failure. Network-path problem. DNS problem. Firewall/configuration issue. Resource-governance condition. Application timeout. Long application recovery after SQL connectivity returns. Azure SQL Database documents multiple connectivity failure categories, including transient fault errors such as 40197 and 40613, authentication failures such as 18456, network termination conditions, firewall issues, and connection timeouts. The classification matters because: Not every failure should be retried in the same way. 4. Use Azure SQL Connectivity History Carefully Azure SQL Database exposes connectivity-event information through system views in the logical server's master database. One useful view is: sys.database_connection_stats It provides aggregated connection success and failure information in five-minute intervals. Connect to the logical server's master database and run: DECLARE @StartTime datetime2 = DATEADD(HOUR, -2, SYSUTCDATETIME()); SELECT database_name, start_time, end_time, success_count, total_failure_count, connection_failure_count FROM sys.database_connection_stats WHERE start_time >= @StartTime ORDER BY start_time DESC; This can help answer: Did connection failures occur? Which database was affected? In which five-minute interval? Were successful connections also occurring? But there's an important limitation. This is aggregated historical information, not a second-by-second outage trace. The data can also arrive later, with Microsoft documenting that it can take up to 24 hours for all information to appear. Therefore, don't use one five-minute bucket containing failures to claim: "The database was unavailable for five minutes." The evidence only tells you connection failures were recorded during that interval. 5. Look Deeper With sys.event_log For additional connectivity-event information, Azure SQL Database exposes: sys.event_log This view records successful database connections and connection failures and is intended to help track and troubleshoot Azure SQL Database connectivity activity. Again, connect to master. DECLARE @StartTime datetime2 = DATEADD(HOUR, -2, SYSUTCDATETIME()); SELECT database_name, start_time, end_time, event_category, event_type, event_subtype, event_subtype_desc, severity, event_count, description FROM sys.event_log WHERE start_time >= @StartTime AND event_category = N'connectivity' ORDER BY start_time DESC; Useful columns include: start_time end_time event_category event_type event_subtype_desc severity event_count description Microsoft cautions that querying sys.event_log can consume significant resources on logical servers with many databases or high login volumes, so keep the time range and other filters appropriately narrow. 6. Correlate SQL Evidence With Application Errors Now correlate the Azure SQL evidence with client telemetry. For every important application-side SQL exception, capture: UTC timestamp. SQL error number. Error message. Application instance. Operation. Retry attempt. Retry delay. Final outcome. Correlation or request ID when available. For example: UTC Layer Observation 10:00:02 Application SQL connection exception 10:00:04 Application Retry 1 fails 10:00:08 Application Retry 2 fails 10:00:15 SQL Connectivity succeeds 10:00:18 Application New connection succeeds 10:01:30 Application Queue still processing 10:05:00 Application Normal service restored Now you can separate: Connectivity interruption. Reconnection period. Application recovery period. That's substantially more useful than describing the full period as: "SQL was down." 7. Understand Connectivity and Reconfiguration Applications connect to the Azure SQL Database gateway, after which traffic is handled according to the effective connection policy and directed to the appropriate database environment. In a managed database service, applications must be designed for transient connectivity interruption. Microsoft specifically describes transient faults as conditions whose underlying cause resolves itself and notes that service reconfiguration can temporarily affect database connectivity. The application therefore shouldn't depend on one connection remaining valid indefinitely. Design for: Connections occasionally being terminated. New connection attempts occasionally failing. In-flight work requiring recovery. DNS and network paths needing to remain correctly configured. Authentication credentials or tokens remaining valid. Retry behavior that allows the system time to recover. Avoid guessing at undocumented platform internals when investigating an event. If evidence establishes only: "Connections failed briefly." Don't convert that into an unsupported explanation of why the platform changed state. 8. Retry Smartly, Not Aggressively Retry logic is essential for cloud applications that connect to Azure SQL Database. Microsoft explicitly recommends retry logic for transient connection failures. But a retry strategy needs boundaries. A good strategy considers: Number of attempts. Delay between attempts. Increasing delay. Random jitter. Maximum interval. Total retry budget. Whether the operation can safely be repeated. A bad strategy looks like: Failure ↓ Retry immediately ↓ Failure ↓ Retry immediately ↓ Failure ↓ Retry immediately... Across hundreds of application instances, this behavior can make recovery harder. A better pattern is: Failure ↓ Wait + jitter ↓ Retry ↓ Longer wait + jitter ↓ Retry ↓ Stop after bounded attempts 9. Use Microsoft.Data.SqlClient Retry Logic For .NET applications using Microsoft.Data.SqlClient, configurable retry logic is available in version 3.0 and later. Microsoft documents providers for configuring connection and command retries. A connection retry provider can be configured like this: var options = new SqlRetryLogicOption() { NumberOfTries = 5, DeltaTime = TimeSpan.FromSeconds(1), MaxTimeInterval = TimeSpan.FromSeconds(20) }; SqlRetryLogicBaseProvider provider = SqlConfigurableRetryFactory.CreateExponentialRetryProvider(options); using var connection = new SqlConnection(connectionString); connection.RetryLogicProvider = provider; connection.Open(); With this configuration: NumberOfTries = 5 Allows one initial attempt and up to four retries. DeltaTime Influences the delay between attempts. MaxTimeInterval Caps an individual retry delay. The exponential provider adds randomized jitter to retry intervals. The actual values should be tested against your application's: Latency requirements. Failure budget. Traffic volume. Concurrency. User experience. They're not universal service recommendations. 10. Connection Retry and Command Retry Are Different This is one of the most important resiliency distinctions. Suppose this fails: connection.Open(); Retrying the connection after an appropriate delay is generally straightforward for a transient connection condition. But suppose this fails: UPDATE dbo.Orders SET ProcessingStatus = N'Completed' WHERE OrderID = @OrderID; The application now has a harder question: Did the UPDATE execute before the connection was lost? Blindly repeating the command isn't always safe. Microsoft's Azure SQL guidance recommends establishing a fresh connection after a transient command failure before retrying, and retry logic must correctly account for the transaction's outcome. 11. Idempotency Matters Different operations require different retry treatment. Read-only operation For example: SELECT OrderID, ProcessingStatus FROM dbo.Orders WHERE OrderID = @OrderID; Repeating a read is often relatively straightforward, subject to your application's consistency requirements. Update operation For example: UPDATE dbo.Orders SET ProcessingStatus = N'Completed' WHERE OrderID = @OrderID; The client must determine whether repeating this operation is safe. Insert operation Consider: INSERT dbo.PaymentRequests ( RequestID, AccountID, Amount ) VALUES ( @RequestID, @AccountID, @Amount ); If the connection disappears after the server commits but before the client receives confirmation, an unconditional retry could create duplicate business activity unless the application and schema provide an idempotency mechanism. For example, a unique request identifier can make duplicate detection possible. The important principle is: Retryability is a business-operation property, not simply a SQL error property. 12. Transactions Need Special Treatment Be particularly careful with multi-statement transactions. Consider: BEGIN TRANSACTION; UPDATE dbo.Inventory SET Quantity = Quantity - @Quantity WHERE ProductID = @ProductID; INSERT dbo.ShipmentQueue ( RequestID, ProductID, Quantity ) VALUES ( @RequestID, @ProductID, @Quantity ); COMMIT TRANSACTION; If connectivity is interrupted, don't simply reconnect and retry the last statement. Your application needs a strategy that protects the integrity of the entire unit of work. Microsoft's retry documentation specifically cautions that if a transient failure invalidates an active transaction, the application should retry the entire transaction rather than only the failed statement. 13. Prevent the Retry Storm Imagine 500 application instances lose connectivity simultaneously. If every instance retries immediately: 500 requests fail ↓ 500 immediately retry ↓ Another synchronized wave ↓ Another synchronized wave Recovery traffic itself can become disruptive. Exponential backoff with jitter helps spread retries across time instead of concentrating them into synchronized bursts. The configurable retry provider in Microsoft.Data.SqlClient supports exponential retry behavior with randomized jitter. Also consider application-level resilience mechanisms such as: Circuit breakers. Back-pressure. Queueing. Controlled concurrency. Connection-pool recovery. Rate limiting. Load shedding where appropriate. The objective isn't: "Retry until SQL succeeds." It's: Recover gracefully without creating a second problem. 14. Don't Ignore the Network Path Not every SQL connection failure originates from the database. Azure SQL Database connectivity includes several components between the application and database, with connection behavior also influenced by the configured connection policy. Troubleshooting may need to include: DNS. Firewall configuration. Private endpoints. Network security rules. Client outbound connectivity. Connection policy. Authentication. Application host health. Azure SQL supports Redirect, Proxy, and Default connection-policy configurations depending on the environment and configuration. In Redirect mode, clients establish connections directly to the node hosting the database after the initial gateway interaction, which requires appropriate network access. This is another reason not to classify every connection exception as: "Azure SQL outage." 15. Test Resiliency Before an Incident Don't wait for a real platform event to discover whether your application's recovery logic works. Test controlled failure scenarios involving: New connections. Existing connections. Read-only requests. Writes. Multi-statement transactions. Multiple application instances. Queued workloads. Connection pools. Measure: Time to detect failure. First retry delay. Number of attempts. Time to establish a new connection. Failed user requests. Queue growth. Queue drain time. Full application recovery. The real success metric isn't merely: "Can I connect to the database again?" It's: "How quickly can the application return to normal service without compromising correctness?" 16. Write a Defensible Post-Incident Report A strong post-incident report separates facts, inferences, and unknowns. Confirmed facts Examples: Client connection failures were recorded during a specific UTC interval. Successful connections later resumed. Certain client instances continued failing after initial connectivity returned. Application backlog persisted beyond the connectivity event. Retry activity increased during recovery. Supported inference Example: Aggressive retry behavior likely contributed to slower application recovery. Use this classification only when application telemetry supports the relationship. Unknowns Examples: The exact internal platform operation responsible for a transient event. Whether an unrelated network event contributed. Whether a capacity change affected recovery. Don't fill gaps in telemetry with assumptions. 17. A Practical Decision Tree When an application reports an Azure SQL connectivity incident: 1. Is the database reachable now? No Check current Azure status and application connectivity. Validate networking, DNS, firewall, authentication, and Azure SQL availability. Yes Continue reconstructing the historical incident. 2. Did Azure SQL record connection failures? Yes Correlate: sys.event_log. sys.database_connection_stats. Application timestamps. Azure monitoring evidence. No or evidence isn't yet available Continue investigating application and network telemetry. Remember that historical connectivity data can arrive later. 3. Did the application retry? No Implement a bounded transient-fault handling strategy. Yes Evaluate: Retry count. Delay. Backoff. Jitter. Error classification. 4. Did many instances retry simultaneously? Yes Investigate: Retry synchronization. Circuit breaking. Back-pressure. Queue recovery. Connection pools. 5. Were writes or transactions interrupted? Yes Validate: Transaction outcome. Idempotency. Duplicate prevention. Whole-transaction retry behavior. 6. Did the application remain unhealthy after connections succeeded? Yes Measure application recovery separately from the original database connectivity event. Final Takeaway The hardest part of a transient Azure SQL event isn't always the interruption itself. Sometimes it's the application's response. A resilient architecture recognizes three separate timelines: Connectivity interruption Database/connectivity recovery Application recovery Azure SQL Database is designed as a cloud service where applications should expect and tolerate transient connectivity conditions. Microsoft recommends implementing retry logic rather than exposing appropriate transient failures directly to users. But resilient retry logic must be: Bounded. Delayed. Appropriately randomized. Error-aware. Transaction-aware. Idempotency-aware. Observable. And post-incident analysis should distinguish: What is confirmed. What is inferred. What remains unknown. Because: A brief database disconnect doesn't have to become a prolonged application outage. The objective isn't to design an application that never experiences a disconnected connection. The objective is to design an application that absorbs the interruption, recovers safely, and returns to normal operation predictably. Further reading Working with Transient Errors in Azure SQL Database Troubleshoot Common Connection Issues in Azure SQL Configure Retry Logic in Microsoft.Data.SqlClient Azure SQL Database Connectivity Architecture sys.event_log for Azure SQL Database sys.database_connection_stats for Azure SQL DatabaseJune 2025 Recap: Azure Database for PostgreSQL
Hello Azure Community, We have introduced a range of exciting new features and updates to Azure Database for PostgreSQL in June. From general availability of PG 17 to public preview of the SSD v2 storage tier for High Availability, there have been some significant feature announcements across multiple areas in the last month. Stay tuned as we dive deeper into each of these feature updates. Before that, let’s look at POSETTE 2025 highlights. POSETTE 2025 Highlights We hosted POSETTE: An Event for Postgres 2025 in June! This year marked our 4th annual event featuring 45 speakers and a total of 42 talks. PostgreSQL developers, contributors, and community members came together to share insights on topics covering everything from AI-powered applications to deep dives into PostgreSQL internals. If you missed it, you can catch up by watching the POSETTE livestream sessions. If this conference sounds interesting to you and want to be part of it next year, don’t forget to subscribe to POSETTE news. Feature Highlights General Availability of PostgreSQL 17 with 'In-Place' upgrade support General Availability of Online Migration Migration service support for PostgreSQL 17 Public Preview of SSD v2 High Availability New Region: Indonesia Central VS Code Extension for PostgreSQL enhancements Enhanced role management Ansible collection released for latest REST API version General Availability of PostgreSQL 17 with 'In-Place' upgrade support PostgreSQL 17 is now generally available on Azure Database for PostgreSQL flexible server, bringing key community innovations to your workloads. You’ll see faster vacuum operations, richer JSON processing, smarter query planning (including better join ordering and parallel execution), dynamic logical replication controls, and enhanced security & audit-logging features—backed by Azure’s five-year support policy. You can easily upgrade to PostgreSQL 17 using the in-place major version upgrade feature available through the Azure portal and CLI, without changing server endpoints or reconfiguring applications. The process includes built-in validations and rollback safety to help ensure a smooth and reliable upgrade experience. For more details, read the PostgreSQL 17 release announcement blog. General Availability of Online Migration We're excited to announce that Online Migration is now generally available for the Migration service for Azure Database for PostgreSQL! Online migration minimizes downtime by keeping your source database operational during the migration process, with continuous data synchronization until cut over. This is particularly beneficial for mission-critical applications that require minimal downtime during migration. This milestone brings production-ready online migration capabilities supporting various source environments including on-premises PostgreSQL, Azure VMs, Amazon RDS, Amazon Aurora, and Google Cloud SQL. For detailed information about the capabilities and how to get started, visit our Migration service documentation. Migration service support for PostgreSQL 17 Building on our PostgreSQL 17 general availability announcement, the Migration service for Azure Database for PostgreSQL now fully supports PostgreSQL 17. This means you can seamlessly migrate your existing PostgreSQL instances from various source platforms to Azure Database for PostgreSQL flexible server running PostgreSQL 17. With this support, organizations can take advantage of the latest PostgreSQL 17 features and performance improvements while leveraging our online migration capabilities for minimal downtime transitions. The migration service maintains full compatibility with PostgreSQL 17's enhanced security features, improved query planning, and other community innovations. Public Preview of SSD v2 High Availability We’re excited to announce the public preview High availability (HA) support for the Premium SSD v2 storage tier in Azure Database for PostgreSQL flexible server. This support allows you to enable Zone-Redundant HA using Premium SSD v2 during server deployments. In addition to high availability on SSDv2 you now get improved resiliency when using Premium SSD v2 with zone-redundant HA, helping customers build resilient, high-performance PostgreSQL applications with minimal overhead. This feature is particularly well-suited for mission-critical workloads, including those in financial services, real-time analytics, retail, and multi-tenant SaaS platforms. Key Benefits of Premium SSD v2: Flexible disk sizing: Scale from 32 GiB to 64 TiB in 1-GiB increments Fast failovers: Planned or unplanned failovers typically around 10 seconds Independent performance configuration: Achieve up to 80,000 IOPS and 1,200 Mbps throughput without resizing your disk. Baseline performance: Free throughput of 125 MB/s and 3,000 IOPS for disks up to 399 GiB, and 500 MB/s and 12,000 IOPS for disks 400 GiB and above at no additional cost. For more details, please refer to the Premium SSD v2 HA blog. New Region: Indonesia Central New region rollout! Azure Database for PostgreSQL flexible server is now available in Indonesia Central, giving customers in and around the region lower latency and data residency options. This continues our mission to bring Azure PostgreSQL closer to where you build and run your apps. For the full list of regions visit: Azure Database for PostgreSQL Regions. VS Code Extension for PostgreSQL enhancements The brand-new VS code extension for PostgreSQL launched in mid-May and has already garnered over 122K installs from the Visual Studio Marketplace! And the kickoff blog about this new IDE for PostgreSQL in VS Code has had over 150K views. This extension makes it easier for developers to seamlessly interact with PostgreSQL databases. We have been committed to make this experience better and have introduced several enhancements to improve reliability and compatibility updates. You can now have better control over service restarts and process terminations on supported operating systems. Additionally, we have added support for parsing additional connection-string formats in the “Create Connection” flow, making it more flexible and user-friendly. We also resolved Entra token-fetching failures for newly created accounts, ensuring a smoother onboarding experience. On the feature front, you can now leverage Entra Security Groups and guest accounts across multiple tenants when establishing new connections, streamlining permission management in complex Entra environments. Don’t forget to update to the latest version in the marketplace to take advantage of these enhancements and visit our GitHub repository to learn more about this month’s release. If you learn best by video, these 2 videos are a great way to learn more about this new VS Code extension: POSETTE 2025: Introducing Microsoft’s VS Code Extension for PostgreSQL Demo of using VS code extension for PostgreSQL Enhanced role management With the introduction of PostgreSQL 16, a strict role hierarchy structure has been implemented. As a result, GRANT statements that were functional in PostgreSQL 11-15 may no longer work in PostgreSQL 16. We have improved the administrative flexibility and addressed this limitation in Azure Database for PostgreSQL flexible server across all PostgreSQL versions. Members of ‘azure_pg_admin’ can now manage, and access objects owned by any role that is non-restricted, giving control and permission over user-defined roles. To learn more about this improvement, please refer to our documentation on roles. Ansible collection released for latest REST API version A new version of Ansible collection for Azure Database for PostgreSQL flexible server is now released. Version 3.6.0 now includes the latest GA REST API features. This update introduces several enhancements, such as support for virtual endpoints, on-demand backups, system-assigned identity, storage auto-grow, and seamless switchover of read replicas to a new site (Read Replicas - Switchover), among many other improvements. To get started with using please visit flexible server Ansible collection link. Azure Postgres Learning Bytes 🎓 Using PostgreSQL VS code extension with agent mode The VS Code extension for PostgreSQL has been trending amongst the developer community. In this month's Learning Bytes section, we want to share how to enable the extension and use GitHub Copilot to create a database in Agent Mode, add dummy data, and visualize it using the Agent Mode and VS Code extension. Step 1: Download the VS code Extension for PostgreSQL Step 2: Check GitHub Copilot and Agent mode is enabled Go to File -> Preferences -> Settings (Ctrl + ,). Search and enable "chat.agent.enabled" and "pgsql copilot.enable". Reload VS Code to apply changes. Step 3: Connect to Azure Database for PostgreSQL Use the extension to enter instance details and establish a connection. Create and view schemas under Databases -> Schemas. Step 4: Visualize and Populate Data Right-click the database to visualize schemas. Ask the agent to insert dummy data or run queries. Conclusion That's all for the June 2025 feature updates! We are dedicated to continuously improve Azure Database for PostgreSQL with every release. Stay updated with the latest updates to our features by following this link. Your feedback is important and helps us continue to improve. If you have any suggestions, ideas, or questions, we’d love to hear from you. Share your thoughts here: aka.ms/pgfeedback We look forward to bringing you even more exciting updates throughout the year, stay tuned!1.1KViews3likes0CommentsScaling Write Throughput in Azure Database for MySQL Using Application-Level Sharding
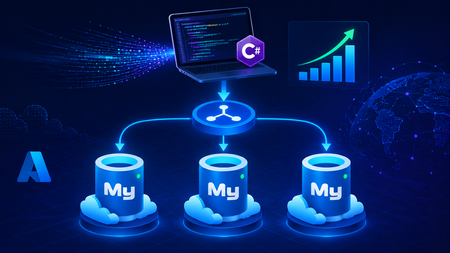
This blog post walks through scaling write throughput in Azure Database for MySQL using application level sharding. It starts with the why behind sharding and then builds a complete C# implementation that spreads writes across three Azure Database for MySQL Flexible Servers. Why Shard in the First Place? This post focuses specifically on scaling write throughput. A well-tuned single primary node can take you remarkably far, and techniques such as indexing strategies, write batching, redo log optimization, and vertical compute scaling each deliver real, lasting value. For many workloads, these optimizations are all you will ever need. That said, as write volume continues to grow, a single primary eventually approaches its practical capacity, and at that point the most durable way to keep scaling is to distribute the write workload across multiple primary instances. This architecture is what we call sharding. When you reach this inflection point, there are two primary patterns for managing multiple write nodes: Proxy or Middleware Layer Sharding: A sharding aware proxy sits between the application and a pool of Azure Database for MySQL instances, routing queries based on a shard key. While this abstracts the underlying topology from the application layer, it introduces an additional, complex component to operate, secure, scale, and patch. Application Layer Sharding: The application itself resolves the destination shard key and determines which of the N Azure Database for MySQL instances should receive a write before ever opening a database connection. Each backend target remains a completely standard, independent Azure Database for MySQL instance. This post explores the second approach. The core appeal of application layer sharding is architectural simplicity: it introduces zero infrastructure overhead and eliminates an extra network hop. Every shard behaves exactly like a standalone instance, meaning your existing backup, restore, monitoring pipelines, and the Azure portal function seamlessly without modification. The explicit tradeoff is that you forgo cross shard joins and distributed transactions in exchange for absolute predictability and control over data access patterns. The Plan We will build a small order management service that distributes its data across three Azure Database for MySQL instances that already exist. The application, written in C# on .NET 8, owns the partitioning logic. The premise: the three servers are already provisioned, the firewalls are configured, the network paths are established, and each server has its own administrative credentials. We are not provisioning infrastructure in this post. we are writing the application code that consumes it. mysql-shard-0.mysql.database.azure.com user: shard0_admin pwd: <secret-0> mysql-shard-1.mysql.database.azure.com user: shard1_admin pwd: <secret-1> mysql-shard-2.mysql.database.azure.com user: shard2_admin pwd: <secret-2> Each server hosts an identical appdb database with the same schema: CREATE TABLE users ( user_id BIGINT NOT NULL PRIMARY KEY, email VARCHAR(255) NOT NULL, created_at DATETIME NOT NULL DEFAULT CURRENT_TIMESTAMP, UNIQUE KEY uq_email (email) ); CREATE TABLE orders ( order_id BIGINT NOT NULL PRIMARY KEY, user_id BIGINT NOT NULL, amount_cents INT NOT NULL, created_at DATETIME NOT NULL DEFAULT CURRENT_TIMESTAMP, KEY ix_user (user_id) ); Two design decisions in this schema warrant explanation: No AUTO_INCREMENT for user_id or order_id. Two shards would otherwise generate the same value 42 independently. Instead, we assign identifiers in the application, using a scheme such as Snowflake, ULID, or UUIDv7. orders carries user_id, and we route by it. This is the single most important rule of sharding: choose a shard key that keeps related data colocated, so that the common queries remain on a single shard. A note on UNIQUE KEY uq_email. A unique index enforces uniqueness only within a single physical shard. Because we route by user_id, two users with different IDs and the same email may land on different shards, and both inserts will succeed. If you require globally unique emails, two options exist: (a) maintain a separate email → user_id lookup table on a single "directory" server and write to it first within an idempotent flow, or (b) shard the users table by a hash of email instead. We retain user_id routing throughout this post because it is the correct choice for orders, and we treat per shard email uniqueness as a best effort guard rather than a hard global invariant. How the Partitioning Works The naive approach to sharding is shard = hash(key) % N. This works until you need to add a fourth server, at which point roughly 75% of your data must move. In any system of meaningful size, that is prohibitively expensive. The established solution is virtual buckets. You hash the key into a large, fixed bucket space (here, 1024), then map buckets to physical shards. When you add capacity, you relocate only buckets; you never rehash the entire dataset. In production, the bucket_to_shard_map typically resides in a system such as Azure App Configuration or etcd, so that you can rebalance without redeploying. For this post, we keep it as an in-memory array seeded at startup, which is straightforward to replace later. The Project ShardingDemo/ ├── ShardingDemo.csproj ├── appsettings.json ├── Models.cs ├── ShardRouter.cs ├── UserRepository.cs └── Program.cs ShardingDemo.csproj <Project Sdk="Microsoft.NET.Sdk"> <PropertyGroup> <OutputType>Exe</OutputType> <TargetFramework>net8.0</TargetFramework> <Nullable>enable</Nullable> <ImplicitUsings>enable</ImplicitUsings> </PropertyGroup> <ItemGroup> <PackageReference Include="MySqlConnector" Version="2.6.0" /> <PackageReference Include="Microsoft.Extensions.Hosting" Version="8.0.0" /> <PackageReference Include="Microsoft.Extensions.Configuration.Binder" Version="8.0.0" /> </ItemGroup> <ItemGroup> <Content Include="appsettings.json" CopyToOutputDirectory="PreserveNewest" /> </ItemGroup> </Project> appsettings.json Shards is an ordered list, and a shard's position in the array is its logical ID. { "Shards": [ { "Host": "mysql-shard-0.mysql.database.azure.com", "Database": "appdb", "User": "shard0_admin", "Password": "REPLACE_ME_0" }, { "Host": "mysql-shard-1.mysql.database.azure.com", "Database": "appdb", "User": "shard1_admin", "Password": "REPLACE_ME_1" }, { "Host": "mysql-shard-2.mysql.database.azure.com", "Database": "appdb", "User": "shard2_admin", "Password": "REPLACE_ME_2" } ] } Models.cs namespace ShardingDemo; public sealed record User(long UserId, string Email, DateTime CreatedAt); public sealed record Order(long OrderId, long UserId, int AmountCents, DateTime CreatedAt); public sealed class ShardConfig { public required string Host { get; init; } public required string Database { get; init; } public required string User { get; init; } public required string Password { get; init; } } ShardRouter.cs using System.Security.Cryptography; using System.Text; using MySqlConnector; namespace ShardingDemo; public sealed class Shard : IAsyncDisposable { public int Id { get; } public MySqlDataSource DataSource { get; } public Shard(int id, ShardConfig cfg) { Id = id; var csb = new MySqlConnectionStringBuilder { Server = cfg.Host, Port = 3306, Database = cfg.Database, UserID = cfg.User, Password = cfg.Password, SslMode = MySqlSslMode.Required, Pooling = true, MinimumPoolSize = 2, MaximumPoolSize = 100, ConnectionTimeout = 10, DefaultCommandTimeout = 30, }; DataSource = new MySqlDataSourceBuilder(csb.ConnectionString).Build(); } public ValueTask DisposeAsync() => DataSource.DisposeAsync(); } public sealed class ShardRouter : IAsyncDisposable { private const int VirtualBuckets = 1024; private readonly IReadOnlyList<Shard> _shards; private readonly int[] _bucketToShardId; public ShardRouter(IEnumerable<ShardConfig> configs) { _shards = configs.Select((c, i) => new Shard(i, c)).ToList(); // Even distribution. Replace with a map loaded from your control plane for live rebalancing. _bucketToShardId = new int[VirtualBuckets]; for (int i = 0; i < VirtualBuckets; i++) _bucketToShardId[i] = i % _shards.Count; } public IReadOnlyList<Shard> AllShards => _shards; private static int BucketFor(long shardKey) { byte[] hash = MD5.HashData(Encoding.ASCII.GetBytes(shardKey.ToString())); // Use the first byte pair as an unsigned value, then map it into the bucket space. int value = (hash[0] << 8) | hash[1]; return value % VirtualBuckets; } public Shard ShardForKey(long shardKey) { int bucket = BucketFor(shardKey); return _shards[_bucketToShardId[bucket]]; } public async ValueTask DisposeAsync() { foreach (var s in _shards) await s.DisposeAsync(); } } UserRepository.cs Observe that every per user method calls ShardForKey(userId), even when inserting an order. This is the colocation rule at work. An order and its owning user always reside on the same shard, so queries for a single user only ever reach one shard. Only the cross-shard aggregate (TotalRevenueCentsAsync) must fan out. using MySqlConnector; namespace ShardingDemo; public sealed class UserRepository { private readonly ShardRouter _router; public UserRepository(ShardRouter router) { _router = router; } public async Task CreateUserAsync(long userId, string email, CancellationToken ct = default) { var shard = _router.ShardForKey(userId); await using var conn = await shard.DataSource.OpenConnectionAsync(ct); await using var cmd = conn.CreateCommand(); cmd.CommandText = "INSERT INTO users (user_id, email) VALUES (@id, Email)"; cmd.Parameters.AddWithValue("@id", userId); cmd.Parameters.AddWithValue("@email", email); await cmd.ExecuteNonQueryAsync(ct); } public async Task<User?> GetUserAsync(long userId, CancellationToken ct = default) { var shard = _router.ShardForKey(userId); await using var conn = await shard.DataSource.OpenConnectionAsync(ct); await using var cmd = conn.CreateCommand(); cmd.CommandText = "SELECT user_id, email, created_at FROM users WHERE user_id = ID"; cmd.Parameters.AddWithValue("@id", userId); await using var reader = await cmd.ExecuteReaderAsync(ct); if (!await reader.ReadAsync(ct)) return null; return new User(reader.GetInt64(0), reader.GetString(1), reader.GetDateTime(2)); } public async Task AddOrderAsync(long orderId, long userId, int amountCents, CancellationToken ct = default) { // Routed by user_id, so orders colocate with their owning user. var shard = _router.ShardForKey(userId); await using var conn = await shard.DataSource.OpenConnectionAsync(ct); await using var cmd = conn.CreateCommand(); cmd.CommandText = """ INSERT INTO orders (order_id, user_id, amount_cents) VALUES (@oid, @uid, amt) """; cmd.Parameters.AddWithValue("@oid", orderId); cmd.Parameters.AddWithValue("@uid", userId); cmd.Parameters.AddWithValue("@amt", amountCents); await cmd.ExecuteNonQueryAsync(ct); } public async Task<IReadOnlyList<Order>> GetOrdersForUserAsync(long userId, CancellationToken ct = default) { var shard = _router.ShardForKey(userId); await using var conn = await shard.DataSource.OpenConnectionAsync(ct); await using var cmd = conn.CreateCommand(); cmd.CommandText = """ SELECT order_id, user_id, amount_cents, created_at FROM orders WHERE user_id = @uid """; cmd.Parameters.AddWithValue("@uid", userId); var list = new List<Order>(); await using var reader = await cmd.ExecuteReaderAsync(ct); while (await reader.ReadAsync(ct)) { list.Add(new Order( reader.GetInt64(0), reader.GetInt64(1), reader.GetInt32(2), reader.GetDateTime(3))); } return list; } /// <summary>Cross shard fanout.</summary> public async Task<long> TotalRevenueCentsAsync(CancellationToken ct = default) { var tasks = _router.AllShards.Select(async shard => { await using var conn = await shard.DataSource.OpenConnectionAsync(ct); await using var cmd = conn.CreateCommand(); cmd.CommandText = "SELECT COALESCE(SUM(amount_cents), 0) FROM orders"; var result = await cmd.ExecuteScalarAsync(ct); return Convert.ToInt64(result); }); var perShard = await Task.WhenAll(tasks); return perShard.Sum(); } } Program.cs using Microsoft.Extensions.Configuration; using Microsoft.Extensions.DependencyInjection; using Microsoft.Extensions.Hosting; using ShardingDemo; var builder = Host.CreateApplicationBuilder(args); // Bind Shards:[] from appsettings.json (override with user-secrets / env vars / Key Vault) var shardConfigs = builder.Configuration .GetSection("Shards") .Get<List<ShardConfig>>() ?? throw new InvalidOperationException("No 'Shards' section configured."); if (shardConfigs.Count == 0) throw new InvalidOperationException("At least one shard must be configured."); builder.Services.AddSingleton(_ => new ShardRouter(shardConfigs)); builder.Services.AddSingleton<UserRepository>(); using var host = builder.Build(); var repo = host.Services.GetRequiredService<UserRepository>(); var router = host.Services.GetRequiredService<ShardRouter>(); (long Id, string Email)[] users = { (1001, "ada@example.com"), (2002, "linus@example.com"), (3003, "grace@example.com"), (4004, "alan@example.com"), }; foreach (var (id, email) in users) { await repo.CreateUserAsync(id, email); Console.WriteLine($"user {id} -> shard {router.ShardForKey(id).Id}"); } await repo.AddOrderAsync(orderId: 9001, userId: 1001, amountCents: 4999); await repo.AddOrderAsync(orderId: 9002, userId: 1001, amountCents: 1299); await repo.AddOrderAsync(orderId: 9003, userId: 2002, amountCents: 8800); Console.WriteLine($"\nAda: {await repo.GetUserAsync(1001)}"); Console.WriteLine($"Ada's orders: {(await repo.GetOrdersForUserAsync(1001)).Count}"); Console.WriteLine($"\nTotal revenue across 3 shards: " + $"${await repo.TotalRevenueCentsAsync() / 100m:F2}"); await router.DisposeAsync(); Tracing One Request End to End Consider GetOrdersForUserAsync(1001): ShardForKey(1001) → MD5("1001") → first two bytes as a number → % 1024 → a bucket in the range 0..1023. bucket % 3 → a physical shard → for example mysql-shard-2.mysql.database.azure.com. The MySqlDataSource provides a pooled, TLS encrypted connection authenticated as shard2_admin. The query runs against shard 2's local ix_user index, with no fan out and at single server speed. Every call with userId = 1001, whether GetUser, AddOrder, or GetOrdersForUser, lands on the same shard. That is why orders JOIN users ON orders.user_id = users.user_id WHERE user_id = 1001 executes within a single shard, with no cross-shard traffic. Conclusion The essential point is this. Once a single primary can no longer absorb your write load, sharding becomes a durable answer, and implementing it at the application layer keeps every part of the system explicit and comprehensible. When write volume or dataset size outgrows a single primary, application layer sharding provides several benefits. N independent Azure Database for MySQL instances, each absorbing 1/N of the write traffic. Queries by user that remain on a single shard and behave like an ordinary, modestly sized database. A bucket map approach that allows you to add a fourth, fifth, or Nth shard later by relocating slices of data rather than rehashing the entire dataset. A failure of one shard that affects 1/N of your users rather than all of them. These benefits come at a genuine cost. You must generate identifiers in the application, global uniqueness requires a secondary lookup table, and aggregate queries fan out across shards. A cross shard write, one that must atomically update data on two different shards, can no longer rely on a single database transaction. Instead it needs an orchestrated sequence of local transactions, where each step carries a compensating action that undoes its effect if a later step fails. None of these are insurmountable. They are simply responsibilities you now assume. Sharding is a deliberate step to take only once a single primary has genuinely exhausted its write headroom. When you reach that point, the implementation in this post is a representative blueprint. Stay Connected We welcome your feedback and invite you to share your experiences or suggestions at AskAzureDBforMySQL@service.microsoft.com Thank you for choosing Azure Database for MySQL!330Views2likes0Comments
Best practices for safely performing schema changes in Azure Database for MySQL
Azure Database for MySQL - Flexible Server is built on the open-source MySQL database engine, and the service supports MySQL 8.0 and newer versions. This means that users can take advantage of the flexibility and advanced capabilities of MySQL’s latest features while benefitting from a fully managed database service. While newer versions and features can provide a lot of value, the recent issues identified with MySQL versions 8.0+ makes it important to be aware of potential risks that can occur during certain operations, particularly if you are making online schema changes. Issues with data loss and duplicate keys with Online DDL Online Data Definition Language (DDL) operations are a powerful feature in MySQL, enabling schema changes like ALTER TABLE or OPTIMIZE TABLE with minimal impact on table availability. These operations are designed to reduce downtime by allowing concurrent reads and writes during schema modifications, making them an essential tool for managing active databases efficiently. However, a recent post on the Percona blog, Who Ate My MySQL Table Rows? highlights critical risks associated with MySQL 8.0.x versions after 8.0.27 and all versions beyond 8.4.y. Specifically, the open-source INPLACE algorithm, commonly used for online schema changes, can lead to data loss and duplicate key errors under certain conditions. These issues arise from constraints in the INPLACE algorithm, particularly during ALTER TABLE and OPTIMIZE TABLE operations, exposing vulnerabilities that compromise data integrity and system reliability. These risks are called out in the following bug reports: Bug #115511: Data loss during online ALTER operations with concurrent DML Bug #115608: Duplicate key errors caused by online ALTER operations Documented issues related to the INPLACE algorithm (used for online DDL) can cause: Data Loss: Rows may be accidentally deleted or become inaccessible. Duplicate Keys: Indexes can end up with duplicate entries, leading to data consistency issues and potential replication errors. Problems arise when INPLACE operations, such as ALTER TABLE or OPTIMIZE TABLE, run concurrently with: DML operations (INSERT, UPDATE, DELETE): Modifications to table data during the rebuild. A purge activity: Background cleanup operations for old row versions in InnoDB. These scenarios can lead to anomalies resulting from race conditions and incomplete synchronization between concurrent activities. Impact on Azure Database for MySQL - Flexible Server Customers For Azure Database for MySQL Flexible Server customers using MySQL 8.0+ and all versions after 8.4.y, this issue is particularly critical as it affects: Data Integrity: During schema changes such as ALTER TABLE or OPTIMIZE TABLE run using the INPLACE algorithm, data rows may be lost or duplicated if these operations run concurrently with a DML activity (e.g., INSERT, UPDATE, or DELETE) or background purge tasks. This can compromise the accuracy and reliability of the database, potentially leading to incorrect query results or the loss of critical business data. Replication Instability: Duplicate keys or missing rows can interrupt replication processes, which rely on a consistent data stream across the primary and replica servers. These issues can arise when there are concurrent insertions into the table during schema changes, leading to data inconsistencies between the primary and replicas. Such inconsistencies may result in replication lag, errors, or even a complete breakdown of high-availability setups, requiring manual intervention to restore synchronization. Operational Downtime: Resolving these issues often involves manually syncing data or restoring backups. These recovery efforts can be time-consuming and disruptive, leading to extended downtime for applications and potential business impact. Recommendations for safe schema changes on Azure Database for MySQL flexible servers To minimize the risks of data loss and duplicate keys while making schema changes, follow these best practices: Set old_alter_table=ON to Default to COPY Algorithm Enable the server parameter old_alter_table system variable so that ALTER TABLE operations without a specified ALGORITHM default to using the COPY algorithm instead of INPLACE. This reduces the risk for users who do not explicitly specify the ALGORITHM in their commands. Learn more on how configure server parameters in Azure Database for MySQL. Avoid using ALGORITHM=INPLACE Do not explicitly use ALGORITHM=INPLACE for ALTER TABLE commands, as it increases the risk of data loss or duplicate keys. Back up your data before schema changes Always perform a full on-demand backup of your server before executing schema changes. This precaution ensures data recoverability in case of unexpected issues. Learn more on how to take full on-demand backups for your server. Avoid Concurrent DML during schema changes Schedule schema changes like ALTER TABLE and OPTIMIZE TABLE during application maintenance windows when no concurrent writes activities occur. This minimizes race conditions and synchronization conflicts. Use External Tools for Safer Online Schema Changes Consider using external tools like pt-online-schema-change to modify table definitions without blocking concurrent changes. These tools enable you to make schema changes with minimal impact on availability and performance. Learn more about pt-online-schema-change. Disclaimer: The pt-online-schema-change tool is not managed or supported by Microsoft; use it at your discretion. Mitigation plans To address these risks, we’re actively working to integrate the necessary fixes to ensure a more robust and reliable experience for our customers. New Servers Fully Secured by End of February 2025 All new Azure Database for MySQL Flexible Server instances created after 1 st March 2025, will include the latest fixes, ensuring that schema changes are safeguarded against data loss and duplicate key risks. Rollout for Existing Servers For existing servers, we will roll out patches during upcoming maintenance windows by end of Q1 of Calendar Year 2025 We recommend monitoring your Azure portal for scheduled maintenance windows and Release notes for announcements about critical updates and patches. Priority updates available upon request If you require an urgent update outside of the scheduled maintenance windows, you can contact Azure Support. Provide the necessary server details and an appropriate maintenance window, and our team will work with you to prioritize the patching process. Note that priority patching will be available by February 2025. We recommend monitoring Release notes for announcements about critical updates and patches. Conclusion Safely managing schema changes on MySQL servers requires understanding the risks associated with online DDL operations, such as potential data loss and duplicate keys. To help safeguard data integrity and maintain server stability, implement best practices, for example enabling the COPY algorithm, using offline operations if feasible, or scheduling changes during low activity periods. Fixes are expected by the end of February 2025, and new Azure Database for MySQL flexible servers will be fully protected against these bugs. We will apply updates to existing servers during maintenance windows in Q1 2025. Following the recommendations above will help ensure that you can confidently make schema changes while preserving the reliability and performance of your server.1.5KViews0likes6CommentsBuilding a Restaurant Management System with Azure Database for MySQL
In this hands-on tutorial, we'll build a Restaurant Management System using Azure Database for MySQL. This project is perfect for beginners looking to understand cloud databases while creating something practical.1.8KViews5likes5CommentsIgnite 2022: Announcing new features in Azure Database for MySQL – Flexible Server
Today, we're pleased to announce a set of new and exciting features in Azure Database for MySQL - Flexible Server that further improve the service's availability, performance, security, management, and developer experiences!7KViews3likes0CommentsReal‑World Cloud & Azure SQL Database Examples Using Kepner‑Tregoe
The Kepner‑Tregoe (KT) methodology is especially effective in modern cloud environments like Azure SQL Database, where incidents are often multi‑dimensional, time‑bound, and affected by asynchronous and self‑healing behaviors. Below are practical examples illustrating how KT can be applied in real Azure SQL scenarios. Example 1: Azure SQL Geo‑Replication Lag Observed on Read‑Only Replica Scenario An application team reports that changes committed on the primary Azure SQL Database are not visible on the geo‑replica used for reporting for up to 30–40 minutes. The primary database performance remains healthy. Applying KT – Problem Analysis What is happening? Read‑only geo‑replica is temporarily behind the primary. What is not happening? No primary outage, no data corruption, no failover. Where does it occur? Only on the geo‑secondary, during specific time windows. When does it occur? Repeatedly around the same time each hour. What is the extent? Lag spikes, then returns to zero. KT Insight By separating data visibility delay from primary health, teams avoid misdiagnosing the issue as a platform outage. Public DMVs (such as sys.dm_geo_replication_link_status and sys.dm_database_replica_states) confirm this as a transient redo lag scenario, not a service availability issue. Example 2: Error 3947 – Transaction Aborted Due to HA Replica Redo Lag Scenario Applications intermittently hit error 3947 (“The transaction was aborted because the secondary failed to catch up redo”), while primary latency remains stable. Applying KT – Situation Appraisal What needs immediate action? Ensure application retry logic is functioning. What can wait? Deep analysis—since workload resumes normally after retries. What should not be escalated prematurely? Platform failover or data integrity concerns. KT Insight KT helps distinguish protective platform behavior from defects. Error 3947 is a deliberate safeguard in synchronous HA models to maintain consistency—not an outage or bug. Example 3: Performance Degradation During Business‑Critical Reporting Scenario Customer reports slow reporting queries on a readable secondary during peak hours, coinciding with replication lag spikes. Applying KT – Decision Analysis Possible actions: Route reporting queries back to primary during spike window Scale up replica resources Move batch processing off peak hours KT Decision Framework Musts: No data inconsistency, minimal user impact Wants: Low cost, fast mitigation, minimal architecture change Decision Temporarily route latency‑sensitive reads to the primary while continuing investigation. This decision is defensible, documented, and reversible. Example 4: Preventing Recurrence with Potential Problem Analysis Scenario Recurring redo lag spikes happen daily at the same minute past the hour. Applying KT – Potential Problem Analysis What could go wrong? Hourly batch job may generate large log bursts How likely is it? High (pattern repeats daily) What is the impact? Temporary stale reads on replicas Preventive actions: Break batch jobs into smaller units Shift non‑critical workloads outside reporting hours Monitor redo queue size proactively KT Insight Rather than responding reactively each day, teams use KT to anticipate and reduce the likelihood and impact of recurrence. Example 5: Coordinated Incident Management Across Regions Scenario An Azure SQL issue spans EMEA, APAC, and US support teams, with intermittent symptoms and high stakeholder visibility. Applying KT – Situation Appraisal KT helps teams: Prioritize which signals are critical vs. noise Decide when to involve engineering vs. continue monitoring Communicate clearly with customers using facts, not assumptions This prevents “analysis paralysis” or conflicting interpretations across time zones. Why KT Works Well in Cloud and Azure SQL Environments Cloud platforms contain self‑healing, asynchronous behaviors that can be misinterpreted Multiple metrics may conflict without structured reasoning KT brings discipline, shared language, and defensible conclusions It complements tooling (DMVs, metrics, alerts)—it doesn’t replace them Closing Thought In cloud operations, how you think is as important as what you observe. Kepner‑Tregoe provides a timeless, structured way to reason about complex Azure SQL Database behaviors—helping teams respond faster, communicate better, and avoid unnecessary escalations.218Views0likes0CommentsAzure SQL Database High Availability: Architecture, Design, and Built‑in Resilience
High availability (HA) is a core pillar of Azure SQL Database. Unlike traditional SQL Server deployments—where availability architectures must be designed, implemented, monitored, and maintained manually—Azure SQL Database delivers built‑in high availability by design. By abstracting infrastructure complexity while still offering enterprise‑grade resilience, Azure SQL Database enables customers to achieve strict availability SLAs with minimal operational overhead. In this article, we’ll cover: Azure SQL Database high‑availability design principles How HA is implemented across service tiers: General Purpose Business Critical Hyperscale Failover behavior and recovery mechanisms Architecture illustrations explaining how availability is achieved Supporting Microsoft Learn and documentation references What High Availability Means in Azure SQL Database High availability in Azure SQL Database ensures that: Databases remain accessible during infrastructure failures Hardware, software, and network faults are handled automatically Failover occurs without customer intervention Data durability is maintained using replication, quorum, and consensus models This is possible through the separation of: Compute Storage Control plane orchestration Azure SQL Database continuously monitors health signals across these layers and automatically initiates recovery or failover when required. Azure SQL Database High Availability – Shared Concepts Regardless of service tier, Azure SQL Database relies on common high‑availability principles: Redundant replicas Synchronous and asynchronous replication Automatic failover orchestration Built‑in quorum and consensus logic Transparent reconnect via the Azure SQL Gateway Applications connect through the Azure SQL Gateway, which automatically routes traffic to the current primary replica—shielding clients from underlying failover events. High Availability Architecture – General Purpose Tier The General-Purpose tier uses a compute–storage separation model, relying on Azure Premium Storage for data durability. Key Characteristics Single compute replica Storage replicated three times using Azure Storage Read‑Access Geo‑Redundant Storage (RA‑GRS) optional Stateless compute that can be restarted or moved Fast recovery using storage reattachment Architecture Diagram – General Purpose Tier Description: Clients connect via the Azure SQL Gateway, which routes traffic to the primary compute node. The compute layer is stateless, while Azure Premium Storage provides triple‑replicated durable storage. Failover Behavior Compute failure triggers creation of a new compute node Database files are reattached from storage Typical recovery time: seconds to minutes 📚 Reference: https://learn.microsoft.com/azure/azure-sql/database/service-tier-general-purpose High Availability Architecture – Business Critical Tier The Business-Critical tier is designed for mission‑critical workloads requiring low latency and fast failover. Key Characteristics Multiple replicas (1 primary + up to 3 secondaries) Always On availability group–like architecture Local SSD storage on each replica Synchronous replication Automatic failover within seconds Architecture Diagram – Business Critical Tier Description: The primary replica synchronously replicates data to secondary replicas. Read‑only replicas can offload read workloads. Azure SQL Gateway transparently routes traffic to the active primary replica. Failover Behavior If the primary replica fails, a secondary is promoted automatically No storage reattachment is required Client connections are redirected automatically Typical failover time: seconds 📚 Reference: https://learn.microsoft.com/azure/azure-sql/database/service-tier-business-critical High Availability Architecture – Hyperscale Tier The Hyperscale tier introduces a distributed storage and compute architecture, optimized for very large databases and rapid scaling scenarios. Key Characteristics Decoupled compute and page servers Multiple read replicas Fast scale‑out and fast recovery Durable log service ensures transaction integrity Architecture Diagram – Hyperscale Tier Description: The compute layer processes queries, while durable log services and distributed page servers manage data storage independently, enabling rapid failover and scaling. Failover Behavior Compute failure results in rapid creation of a new compute replica Page servers remain intact Log service ensures zero data loss 📚 Reference: https://learn.microsoft.com/azure/azure-sql/database/service-tier-hyperscale How Azure SQL Database Handles Failures Azure SQL Database continuously monitors critical health signals, including: Heartbeats IO latency Replica health Storage availability Automatic Recovery Actions Restarting failed processes Promoting secondary replicas Recreating compute nodes Redirecting client connections Applications should implement retry logic and transient‑fault handling to fully benefit from these mechanisms. 📚 Reference: https://learn.microsoft.com/azure/architecture/best-practices/transient-faults Zone Redundancy and High Availability Azure SQL Database can be configured with zone redundancy, distributing replicas across Availability Zones in the same region. Benefits Protection against datacenter‑level failures Increased SLA Transparent resilience without application changes 📚 Reference: https://learn.microsoft.com/azure/azure-sql/database/high-availability-sla Summary Azure SQL Database delivers high availability by default, removing the traditional operational burden associated with SQL Server HA designs. Service Tier HA Model Typical Failover General Purpose Storage‑based durability Minutes Business Critical Multi‑replica, synchronous Seconds Hyperscale Distributed compute & storage Seconds By selecting the appropriate service tier and enabling zone redundancy where required, customers can meet even the most demanding availability and resilience requirements with minimal complexity. Additional References Azure SQL Database HA overview https://learn.microsoft.com/azure/azure-sql/database/high-availability-overview Azure SQL Database SLAs https://azure.microsoft.com/support/legal/sla/azure-sql-database Application resiliency guidance https://learn.microsoft.com/azure/architecture/framework/resiliency1.9KViews0likes0CommentsUnlocking AI-Driven Data Access: Azure Database for MySQL Support via the Azure MCP Server
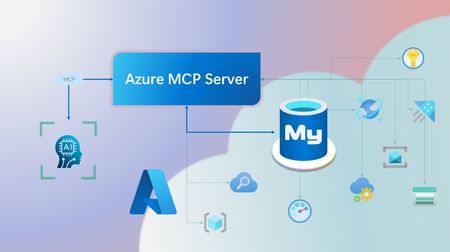
Step into a new era of data-driven intelligence with the fusion of Azure MCP Server and Azure Database for MySQL, where your MySQL data is no longer just stored, but instantly conversational, intelligent and action-ready. By harnessing the open-standard Model Context Protocol (MCP), your AI agents can now query, analyze and automate in natural language, accessing tables, surfacing insights and acting on your MySQL-driven business logic as easily as chatting with a colleague. It’s like giving your data a voice and your applications a brain, all within Azure’s trusted cloud platform. We are excited to announce that we have added support for Azure Database for MySQL in Azure MCP Server. The Azure MCP Server leverages the Model Context Protocol (MCP) to allow AI agents to seamlessly interact with various Azure services to perform context-aware operations such as querying databases and managing cloud resources. Building on this foundation, the Azure MCP Server now offers a set of tools that AI agents and apps can invoke to interact with Azure Database for MySQL - enabling them to list and query databases, retrieve schema details of tables, and access server configurations and parameters. These capabilities are delivered through the same standardized interface used for other Azure services, making it easier to the adopt the MCP standard for leveraging AI to work with your business data and operations across the Azure ecosystem. Before we delve into these new tools and explore how to get started with them, let’s take a moment to refresh our understanding of MCP and the Azure MCP Server - what they are, how they work, and why they matter. MCP architecture and key components The Model Context Protocol (MCP) is an emerging open protocol designed to integrate AI models with external data sources and services in a scalable, standardized, and secure manner. MCP dictates a client-server architecture with four key components: MCP Host, MCP Client, MCP Server and external data sources, services and APIs that provide the data context required to enhance AI models. To explain briefly, an MCP Host (AI apps and agents) includes an MCP client component that connects to one or more MCP Servers. These servers are lightweight programs that securely interface with external data sources, services and APIs and exposes them to MCP clients in the form of standardized capabilities called tools, resources and prompts. Learn more: MCP Documentation What is Azure MCP Server? Azure offers a multitude of cloud services that help developers build robust applications and AI solutions to address business needs. The Azure MCP Server aims to expose these powerful services for agentic usage, allowing AI systems to perform operations that are context-aware of your Azure resources and your business data within them, while ensuring adherence to the Model Context Protocol. It supports a wide range of Azure services and tools including Azure AI Search, Azure Cosmos DB, Azure Storage, Azure Monitor, Azure CLI and Developer CLI extensions. This means that you can empower AI agents, apps and tools to: Explore your Azure resources, such as listing and retrieving details on your Azure subscriptions, resource groups, services, databases, and tables. Search, query and analyze your data and logs. Execute CLI and Azure Developer CLI commands directly, and more! Learn more: Azure MCP Server GitHub Repository Introducing new Azure MCP Server tools to interact with Azure Database for MySQL The Azure MCP Server now includes the following tools that allow AI agents to interact with Azure Database for MySQL and your valuable business data residing in these servers, in accordance with the MCP standard: Tool Description Example Prompts azmcp_mysql_server_list List all MySQL servers in a subscription & resource group "List MySQL servers in resource group 'prod-rg'." "Show MySQL servers in region 'eastus'." azmcp_mysql_server_config_get Retrieve the configuration of a MySQL server "What is the backup retention period for server 'my-mysql-server'?" "Show storage allocation for server 'my-mysql-server'." azmcp_mysql_server_param_get Retrieve a specific parameter of a MySQL server "Is slow_query_log enabled on server my-mysql-server?" "Get innodb_buffer_pool_size for server my-mysql-server." azmcp_mysql_server_param_set Set a specific parameter of a MySQL server to a specific value "Set max_connections to 500 on server my-mysql-server." "Set wait_timeout to 300 on server my-mysql-server." azmcp_mysql_table_list List all tables in a MySQL database "List tables starting with 'tmp_' in database 'appdb'." "How many tables are in database 'analytics'?" azmcp_mysql_table_schema_get Get the schema of a specific table in a MySQL database "Show indexes for table 'transactions' in database 'billing'." "What is the primary key for table 'users' in database 'auth'?" azmcp_mysql_database_query Executes a SELECT query on a MySQL Database. The query must start with SELECT and cannot contain any destructive SQL operations for security reasons. “How many orders were placed in the last 30 days in the salesdb.orders table?” “Show the number of new users signed up in the last week in appdb.users grouped by day.” These interactions are secured using Microsoft Entra authentication, which enables seamless, identity-based access to Azure Database for MySQL - eliminating the need for password storage and enhancing overall security. How are these new tools in the Azure MCP Server different from the standalone MCP Server for Azure Database for MySQL? We have integrated the key capabilities of the Azure Database for MySQL MCP server into the Azure MCP Server, making it easier to connect your agentic apps not only to Azure Database for MySQL but also to other Azure services through one unified and secure interface! How to get started Installing and running the Azure MCP Server is quick and easy! Use GitHub Copilot in Visual Studio Code to gain meaningful insights from your business data in Azure Database for MySQL. Pre-requisites Install Visual Studio Code. Install GitHub Copilot and GitHub Copilot Chat extensions. An Azure Database for MySQL with Microsoft Entra authentication enabled. Ensure that the MCP Server is installed on a system with network connectivity and credentials to connect to Azure Database for MySQL. Installation and Testing Please use this guide for installation: Azure MCP Server Installation Guide Try the following prompts with your Azure Database for MySQL: Azure Database for MySQL tools for Azure MCP Server Try it out and share your feedback! Start using Azure MCP Server with the MySQL tools today and let our cloud services become your AI agent’s most powerful ally. We’re counting on your feedback - every comment, suggestion, or bug-report helps us build better tools together. Stay tuned: more features and capabilities are on the horizon! Feel free to comment below or write to us with your feedback and queries at AskAzureDBforMySQL@service.microsoft.com.572Views3likes0Comments