generative ai
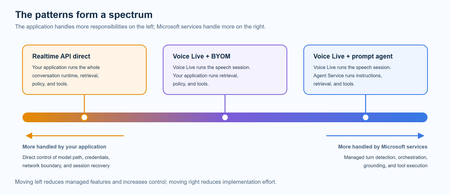
168 TopicsChoosing a real-time voice architecture on Microsoft Foundry: three enterprise patterns
A practical comparison of three real-time voice architectures on Microsoft Foundry, including implementation tradeoffs and four enterprise release gates for residency, networking, retrieval authorization, and tool credentials.604Views0likes0Comments
Tuesday Prompt Day | 6W + E Practical Experiment #3 — From AI Output to Business Decision
In our previous discussion, we explored an important idea: Prompt → Output → Evaluate → Refine → Better Output Today, let's take the next step. What happens when the goal is not simply to get a better answer from Copilot, but to get an answer that helps someone make a better decision? Let's look at a practical enterprise scenario. BASIC PROMPT "Review this project update and tell me if we are on track." It looks simple. But what does "on track" actually mean? On track against what? Who needs the answer? What decision are they trying to make? What evidence should Copilot consider? This is where 6W + E becomes useful. 6W + E PROMPT "Act as an enterprise program advisor. Review the project status information provided below and prepare an assessment for the project steering committee. WHY: The purpose is to determine whether the project is on track and whether leadership intervention is required. WHAT: Assess progress, major risks, dependencies, issues and upcoming milestones. WHO: The audience is senior business and IT leadership. WITH: Use only the information provided in the project status material. Do not invent missing facts. WAY: Present the response using these sections: Overall status Evidence supporting the status Key risks and their business impact Critical dependencies Decisions or actions required from leadership WIN: The output should allow a steering committee member to understand the situation quickly and identify where action is required. EVALUATE: Before finalizing the response, check whether each conclusion is supported by the source material. Clearly distinguish facts, observations and assumptions." Notice what changed. The prompt is not simply longer. The problem has become clearer. IMPROVED OUTPUT Instead of simply saying: "The project appears to be on track, although there are some risks." Copilot can be guided toward something more useful: Overall status: Amber - progress is continuing, but a dependency may affect the next milestone. Evidence: Current delivery remains aligned with the planned milestone. A key dependency is still unresolved. The available information does not confirm whether the dependency will be resolved before the milestone. Business impact: If the dependency remains unresolved, the next milestone may be delayed. Leadership action: Confirm ownership and resolution date for the dependency. Information gap: The source material does not provide a confirmed resolution date. That is a very different outcome. The AI is no longer just summarizing information. It is helping structure the information around a business decision. NOW EVALUATE Before accepting this output, ask: Are the conclusions supported by evidence? Did Copilot confuse an assumption with a fact? Is the business impact clear? Is the recommended action actually supported by the information? Can a decision-maker understand the situation quickly? What information is still missing? This is where EVALUATE becomes more than a final proofreading step. It becomes a quality-control mechanism. REFINE Suppose our evaluation identifies one problem: The response identifies the dependency, but the leadership action is still too generic. We can refine the instruction: "Refine the leadership action. Do not simply recommend monitoring the dependency. Identify the specific decision, owner or escalation required based only on the available information. If the source material does not provide enough information to identify an owner or decision, explicitly state what information is missing." Now we have another cycle: Prompt → Output → Evaluate → Refine → Better Output And this leads to a broader question. Are we really trying to teach people how to write better prompts? Or are we trying to teach people how to work effectively with AI? I believe there is an important difference. Prompt engineering may start with the prompt. But effective AI collaboration continues through evaluation, judgment and refinement. YOUR TURN Think about a Copilot interaction you use in your day-to-day work. Ask yourself: What decision is the output supposed to support? What evidence should Copilot use? What would make the answer genuinely useful? How would you evaluate the first response? What would you refine if the answer was only almost right? Share your experience without including confidential information. I'm especially interested in examples where Copilot produced a technically correct answer but the answer was not useful for the actual business decision. Those examples can teach us more than perfect prompts. This discussion continues the 6W + E practical experiment series. Please see the Resources section for the previous experiments and the original 6W + E framework. The goal of this series is not simply to create better prompts. It is to explore whether 6W + E can become a repeatable method for working with AI in real-world scenarios. What would you evaluate first in your next Copilot response?72Views0likes0CommentsBuilding Production-Ready AI Agents in Microsoft Foundry: 10 Lessons Learned
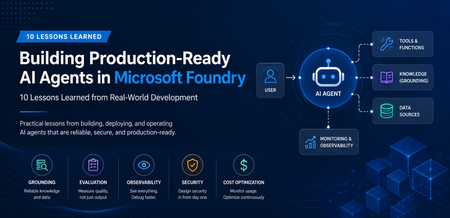
A Real-World Scenario Imagine a customer support agent that answers invoice questions. During testing, everything works perfectly. But in production: The Finance API occasionally times out. The knowledge base contains outdated information. Tool calls fail during peak traffic. Token consumption rises unexpectedly. The result isn't a broken AI model. It's an unreliable system. This is where Microsoft Foundry becomes critical. Building production-ready agents requires grounding, observability, resiliency, governance, and continuous monitoring. New challenges appear: Challenge Impact Hallucinated responses Reduced trust Missing citations Verification issues Tool failures Broken workflows High token consumption Increased cost Latency spikes Poor user experience Limited monitoring difficult troubleshooting Security concerns Compliance risks The lesson was clear: Production readiness is not about making the agent smarter. It is about making the agent reliable. My Observation While experimenting with AI agents in Microsoft Foundry, I found that model selection was rarely the primary challenge. Most production issues stemmed from grounding quality, tool reliability, observability, and security controls. Addressing these operational concerns often had a greater impact on user trust than changing the underlying model. Production AI Agent Reference Architecture A production-ready AI agent typically includes several components beyond the language model itself. Layer Technology User Interface Web App, Teams, Copilot Agent Runtime Microsoft Foundry Agent Service Knowledge Layer Azure AI Search Foundation Model GPT-4o Tool Integration APIs and Functions Monitoring Azure Monitor Security Managed Identity and Key Vault Request Flow Lesson 1: Start with the Use Case, Not the Model One of the most common mistakes is beginning with model selection. Many teams ask: Which model should I use? Should I choose GPT-4o? Should I use a larger context window? A more important question is: What business problem are we solving? Before evaluating models, define: Users Business goals Success metrics Compliance requirements Operational constraints An enterprise support agent and a financial compliance agent may use the same model but require completely different architectures. Key Takeaway Successful AI projects start with business outcomes, not model benchmarks. Lesson 2: Grounding Matters More Than Prompting Prompt engineering helps. Grounding drives trust. Without access to reliable enterprise data, even advanced models can generate confident but incorrect responses. Grounding Sources Azure AI Search SharePoint documents Internal knowledge bases Structured enterprise data Approved policy repositories Example from azure.ai.projects import AIProjectClient # Configure grounding with Azure AI Search agent = client.agents.create_agent( model="gpt-4o", name="support-agent", tools=[ { "type": "azure_ai_search", "azure_ai_search": { "index_name": "support-kb", "endpoint": "https://your-search.search.windows.net" } } ] ) In production environments, grounding through Azure AI Search helps agents retrieve trusted enterprise information rather than relying solely on model knowledge. This significantly improves response accuracy and trustworthiness. Try it yourself: Configure Azure AI Search as a knowledge source in Microsoft Foundry and compare grounded versus non-grounded responses. Key Takeaway Reliable retrieval is usually more valuable than sophisticated prompting. Lesson 3: Design Tool Usage Carefully AI agents become powerful when they can interact with external tools. Examples include: CRM systems Databases APIs Ticketing systems Business applications However, every tool increase complexity. Ask yourself: When should the agent call the tool? What happens if the tool is unavailable? How should failures be handled? Example Failure Scenario +-----------------------------+ | User asks for invoice status | +-------------+---------------+ | v +-----------------------------+ | Agent calls Finance API | +-------------+---------------+ | v +-----------------------------+ | API timeout detected | +-------------+---------------+ | v +-----------------------------+ | Fallback response returned | +-----------------------------+ Example Failure Scenario: A production-ready agent should gracefully handle external service failures and return a fallback response instead of failing completely. Key Takeaway Design for failure before designing for capability. Lesson 4: Evaluate Before Deployment Many teams test only for response quality. Production agents require broader evaluation. Evaluation Area Why It Matters Accuracy Correct answers Grounding Quality Faithful responses Latency User experience Safety Risk reduction Cost Sustainability Tool Success Rate Reliability Evaluation should become part of every deployment pipeline. Key Takeaway You cannot improve what you do not measure. Lesson 5: Make Observability a First-Class Feature Observability is often neglected until something breaks. Unfortunately, production systems always encounter unexpected behavior. Track metrics such as: Metric Purpose Request Volume Demand tracking Average Latency Performance Token Usage Cost visibility Grounding Success Rate Quality Tool Failure Rate Reliability User Satisfaction Business value Setting Up Tracing in Foundry from azure.ai.projects import AIProjectClient from azure.monitor.opentelemetry import configure_azure_monitor # Configure Azure Monitor for tracing configure_azure_monitor( connection_string="InstrumentationKey=xxx" ) # Run the agent response = agent.run( thread_id=thread.id, instructions="..." ) Tracing provides visibility into how an AI agent processes requests, invokes tools, and generates responses. By integrating Azure Monitor, teams can track latency, identify failed tool calls, analyze token usage, and troubleshoot unexpected agent behavior. This observability is essential for operating AI agents reliably in production environments. Try it yourself: Enabling tracing and monitoring for a Microsoft Foundry agent using Azure Monitor. Example Dashboard +-----------------------------+ | Production Monitoring Dashboard | +-----------------------------+ | Requests Today | 5,120 | | Average Latency | 3.2s | | Grounding Success | 97% | | Tool Failure Rate | 1% | | Average Tokens | 2,800 | +-----------------------------+ Monitoring production metrics helps teams understand agent performance, reliability, and cost efficiency. Key indicators such as latency, grounding success rate, tool failure rate, and token consumption provide valuable insights into the operational health of an AI agent and enable proactive troubleshooting before users are impacted. Key Takeaway What you can't observe, you can't effectively operate or improve. Tracing is a critical capability for maintaining production-ready AI agents. Lesson 6: Monitor Token Consumption Token usage directly impacts cost. A highly successful agent can quickly become expensive if token growth is unmanaged. Common optimization techniques: Optimization Benefit Prompt Compression Lower token usage Response Caching Reduced model calls RAG Filtering Focused context Context Trimming Smaller requests Model Selection Cost control Key Takeaway Cost optimization should be planned from day one. Lesson 7: Build Security into the Design Security should never be an afterthought. Enterprise AI systems must enforce the same security boundaries as traditional applications. Recommended Controls Control Purpose Managed Identity Secure authentication Azure Key Vault Secret management RBAC Authorization Audit Logs Compliance Content Filtering Safety Private Endpoints Network Security Guiding Principle An AI agent should never access data beyond a user's permissions. Key Takeaway Security is a design requirement, not a deployment task. Lesson 8: Expect Tool Failures External dependencies inevitably fail. Production-ready agents should anticipate: API downtime Authentication failures Network interruptions Rate limiting Unexpected responses Recommended Strategy Key Takeaway async def call_tool_with_resilience(tool_name, params): try: result = await tool_client.execute( tool_name, params, timeout=5.0 ) return result except TimeoutError: return await cache.get_fallback( tool_name, params ) Example Outcome: Introducing retry and fallback logic can significantly improve reliability. By handling temporary API failures gracefully and returning cached responses, when necessary, agents can reduce user-facing errors and provide a more consistent experience. Lesson 9: Evaluate the Process, Not Just the Output A correct answer does not always mean the process was correct. In production environments, teams should evaluate not only the final response but also the steps the agent took to generate that response. An answer may appear accurate even when it was based on incorrect retrieval results, unnecessary tool calls, or incomplete citations. Review: Retrieval quality Tool execution Citation accuracy Security compliance Reasoning path User Query | v Retrieval | v Tool Execution | v Reasoning | v Response For example, an agent might generate the correct answer by chance, even though it retrieved irrelevant documents or used an inefficient workflow. Without evaluating the process, these hidden issues may go unnoticed until they affect reliability, compliance, or user trust. Key Takeaway Inspect the entire workflow, not just the final answer. Lesson 10: Think Like a Production Engineer As adoption grows, operational excellence becomes the differentiator. Ask questions such as: Can we troubleshoot failures? Can we measure business impact? Can we control costs? Can we scale safely? Can we govern usage? These questions become more important than model selection over time. Key Takeaway Production success comes from engineering discipline, not model size. Microsoft Foundry Features That Helped Improve Reliability Foundry Capability Production Benefit Agent Service Agent orchestration Knowledge Sources Grounded responses Evaluations Quality measurement Tracing Workflow visibility Model Catalog Model flexibility Safety Systems Risk mitigation These capabilities help teams move beyond proofs of concept and build solutions that are ready for real-world adoption. Production Readiness Checklist Before releasing an AI agent, verify: ✅ Business goals defined ✅ Grounding strategy implemented ✅ Security controls enabled ✅ Evaluation pipeline established ✅ Monitoring configured ✅ Failure handling tested ✅ Cost optimization reviewed ✅ Governance process defined ✅ User feedback loop available ✅ Deployment rollback strategy prepared Get Started with Production-Ready Agents If you're building AI agents using Microsoft Foundry, start by focusing on grounding, observability, security, and evaluation from day one. Suggested next steps: Build your first agent in Microsoft Foundry Configure Azure AI Search grounding Enable tracing and monitoring Evaluate agent quality before deployment Add resilience and fallback strategies Which of these 10 lessons has been most valuable in your own AI agent journey? Share your experiences and insights in the comments.980Views5likes1CommentTuesday Prompt Day 🚀 | 6W + E Practical Experiment #2
In our previous practical experiment, we took a simple Copilot request and transformed it using the Six W + E framework. Today, let's focus on the part that can make the biggest difference: E = EVALUATE A common assumption is: Prompt → Copilot → Answer But in real-world enterprise work, I believe the process should be: Prompt → Output → Evaluate → Refine → Better Output Let's continue with the same scenario. 🔹 BASIC PROMPT "Create a summary of our cloud migration project." The response may be reasonable. But before accepting it, let's evaluate it. 🔹 EVALUATE Ask yourself: Did Copilot understand the intended audience? Did it focus on the business objective? Did it distinguish facts from assumptions? Did it surface the risks that actually matter? Can the intended audience act on the result? Suppose the answer is: "Mostly good, but the risks are too generic and the executive summary contains too much technical detail." That feedback is valuable. We now know what needs to change. 🔹 REFINE Instead of starting over, we refine the instruction: "Refine the previous response for senior business and IT leadership. Reduce technical implementation details. Prioritize the most significant business risks. For each risk, provide: Risk • Business impact • Current mitigation • Decision or action required Keep the executive summary concise. Do not introduce information that is not supported by the source material. Clearly identify any information that is unavailable." Now the interaction has changed. We are no longer simply asking Copilot for an answer. We are using the first answer to improve the next instruction. 🔹 IMPROVED OUTPUT The objective is not necessarily to make the prompt longer. The objective is to make the next interaction more precise. That distinction matters. A good prompt can produce a useful first response. But a good evaluation process helps us systematically improve the result. This is why I see EVALUATE as an important part of Six W + E. It creates a feedback loop: Think → Prompt → Output → Evaluate → Refine And this raises an interesting question for enterprise AI adoption: Should we teach people only how to write better prompts? Or should we teach them how to evaluate AI output and refine their interaction with AI? I believe the second capability is just as important. 💡 YOUR TURN Take one prompt you use with Copilot. Run it once. Then evaluate the response before rewriting the prompt. Share: What you originally asked What was missing or incorrect in the response What you changed in your prompt Whether the second result was actually better Please avoid sharing confidential or sensitive information. I'm particularly interested in examples where the first Copilot response looked correct but wasn't actually useful for the business problem. Those are often the most interesting examples. 🔗 This discussion continues our Six W + E journey. Start with the original framework discussion and then explore the practical experiment series from there. I'll use the strongest examples from this series to explore how Six W + E can evolve from a prompting framework into a practical method for working with AI.88Views0likes0CommentsModel router updates: new regions, a refreshed model pool, and understanding the hill climb
Across Microsoft, "hill climbing" has become shorthand for how real AI progress happens: not in one dramatic leap, but through a disciplined loop. Microsoft AI defines the hill climb as an organization that continuously improves, cycle after cycle, through more compute, better data, and sharper evaluation. Reinforcement fine-tuning in Foundry defines it as improving the deployable model package one measured step at a time across quality, latency, and cost. Different altitudes, same premise: progress is not a one-shot decision. It's a loop. For most teams, the decision of what model to use when is made manually or with custom routing tools. A developer picks a model based on benchmarks, familiarity, or the last launch that made headlines, ships it, and revisits the choice only when something breaks. In an ecosystem where the frontier moves monthly, that decision goes stale fast. Model router in Foundry Models brings the hill climb to the selection layer. What's new: a bigger pool, in more places This release expands where teams can deploy model router, broaden the supported model pool, and delivers updates through a stable endpoint. Together, these changes help teams run production workloads in more locations, match a wider range of tasks to suitable models, and adopt supported updates without changing the application integration. A refreshed model pool. The supported model list now includes Anthropic Claude Opus 4.8 — a high-capability model built for complex reasoning and long-form generation, for scenarios that demand depth, structure, and quality — and the GPT-5.6 family. Just as importantly, the pool is pruned: gpt-5-chat, gpt-5.2-chat, gpt-5.3-chat, Deepseek-V3.1 have been removed from the model router as models reach the end of their lifecycle and are deprecated in Foundry. New region availability. The model router is now available in 28 regions for global standard and 21 data zone regions. For many organizations, inference requests must stay within specific geographic boundaries for regulatory, governance, or customer-trust reasons — and intelligent routing shouldn't force a compromise on that. Find the full list of regions here. The most important detail is what you don't have to do: these updates occur automatically*. The endpoint remains stable as the supported model pool is refreshed, so teams do not need to redeploy the model router to receive the update. Applications can continue using the same integration while the model router evaluates requests against the current supported pool. Teams should continue monitoring routing traces and application outcomes to confirm that quality, cost, latency, and governance requirements are met. *Models from Anthropic still need to be deployed separately before they can be routed to through the model router. Interested in hearing more about what's new to the model router? Tune in for the next episode of Model Mondays with Sanjeev Jagtap and Lee Stott, where they talk all things model router from evaluations to hill climbing. Sign up here to watch live or view the replay: Model Mondays - Spotlight On Model router in Microsoft Foundry | Microsoft Reactor The selection-layer hill climb At the selection layer, a step is a routing decision. Each one is a micro-optimization against your objective, and each one is instrumented: every response from the model router includes a model field showing which underlying model was selected, so the climb leaves a complete, auditable trail. Model router supports three parts of the optimization loop: A/B testing to compare two router configurations to understand quality, cost, and latency tradeoffs; model decomposition to use routing results to decompose a single-model application into a multi-model or multi-agent design, and continuous routing to keep the router in production for continuous per-request selection. Each pattern turns model choice into a measured, repeatable process rather than a fixed decision. 1. A/B Testing Question: Which model or routing strategy should I use in production? A/B testing helps teams compare candidate models, model families, or router configurations against the same workload. Representative traffic is sent to competing deployments, and teams compare quality, cost, latency, and governance outcomes. The goal is to understand tradeoffs and identify the model or routing strategy that best meets workload requirements before promoting it to production. 2. Model Decomposition Question: What work is my application actually doing? Model decomposition uses model router as a diagnostic tool. By deploying the model router against a representative workload and examining routing telemetry, teams can see how requests naturally separate into different task classes. Simple retrieval, classification, and summarization requests may route to smaller models, while reasoning, planning, and agentic workflows may require more capable models. The goal is not to choose a winner, but to understand the structure of the workload and uncover opportunities for optimization, specialization, or architectural improvements. 3. Route continuously Question: Why choose a single model at all? Route continuously is the pattern model router was designed for but is not limited to. Rather than treating model selection as a one-time decision, teams leave the model router in production and allow the best-fit model to be selected for each request. As the supported model pool, regional availability, and platform capabilities evolve, teams can continue using the same endpoint while evaluating whether updates improve workload outcomes. Model selection becomes an ongoing optimization process rather than a project that must be repeated every time the model landscape changes. Together, these patterns illustrate a broader shift: the model router is more than a model. It is a tool for the optimization loop itself, helping teams evaluate tradeoffs, understand workload behavior, test hypotheses, and continuously refine model selection as requirements evolve. Whether used to compare candidate models, decompose applications into specialized tasks, or automate per-request routing in production, model router turns model selection into an observable, measurable, and repeatable process. As the model landscape continues to change, that optimization loop becomes a durable advantage. Getting Started Ready to start your own hill climb? Whether you're exploring the model router for the first time, evaluating routing strategies against your workload, or building a long-term optimization practice, these resources can help you move from experimentation to production with Microsoft Foundry. What's new in model router? Sign up for the next Model Mondays episode for a deep dive into new features, optimization patterns, and the latest model router updates. How do I build agents with model router? Check out the Model Router Agents Lab and build agent experiences with routing, retrieval, web search, tool calling, and multi-agent patterns. How do I evaluate model router? Compare model router against baseline models using your own prompts, then review quality, cost, latency, and routing decisions with the Auto Evaluation Toolkit. How do I optimize model router for my workload? Start your hill-climbing journey with the Model Mastery workshop, where you'll test one optimization lever at a time and measure how each change impacts workload outcomes. How do I build a model router optimization playbook? Explore the Model Releases repository to track new capabilities, understand the optimization question behind each release, and try focused notebooks that demonstrate one optimization lever at a time.2.6KViews2likes0CommentsTuesday Prompt Day 🚀 | 6W + E — Practical Experiment #1
Last Tuesday, I introduced a simple principle I’ve been developing for better AI prompting: WHY → WHAT → WHO → WITH → WAY → WIN → EVALUATE 6W + E. 🔗 If you missed the original discussion: https://techcommunity.microsoft.com/discussions/6b6b9aaa-f41d-42fa-b90a-e1bb1d97a954/is-your-ai-prompt-missing-the-real-problem--introducing-the-6w--e-framework/4546006 Today, I don't want to explain the framework again. I want to test it. Let’s take a common Copilot request: “Create a summary of our cloud migration project.” Seems simple. But before asking Copilot to produce the answer, let's think about the problem. WHY are we creating the summary? WHAT exactly should it communicate? WHO will read it? WITH what information should Copilot work? WAY should the information be presented? WIN — what would make the result successful? And finally: EVALUATE — did Copilot actually give us what we needed? Now compare that with a more intentional prompt: “You are an enterprise cloud solution architect preparing an executive update. Create a concise summary of our cloud migration project for senior business and IT leadership. The objective is to communicate progress, business impact, key risks and the next priorities. Focus on the current quarter. Structure the response into: Executive summary • Business impact • Key achievements • Current risks • Next priorities • Decisions required from leadership Keep the language business-friendly and avoid unnecessary technical detail. Where information is missing, clearly identify the gap rather than inventing details.” The interesting part isn't simply that the second prompt is longer. The interesting part is that we have given Copilot a clearer way to understand the problem. And this brings us back to the final part of 6W + E: E = EVALUATE. I don't believe good prompting ends when Copilot gives us an answer. The real cycle is: Think → Prompt → Evaluate → Refine Sometimes the first response is good. Sometimes it isn't. Sometimes the problem isn't the AI's capability. Sometimes we haven't given AI enough direction to solve the right problem. So, here's today's community challenge 👇 Take ONE prompt you regularly use with Copilot. Don't share anything confidential. Share: Your original prompt What you wanted Copilot to achieve Which part of 6W + E was missing How you would improve the prompt Let's see whether we can improve real-world Copilot interactions together. I'll use the best examples from this discussion as we continue developing the 6W + E learning series. And this is only Experiment #1. Next, we'll look at what happens when we deliberately use EVALUATE to improve the first response. What has been your experience? Do you usually refine your Copilot response, or accept the first answer? #MicrosoftCopilot #GenerativeAI #PromptEngineering #MicrosoftCommunity #EnterpriseAI #AITransformation106Views0likes0CommentsGenAI Knowledge Byte | KB-002
Understanding AI Hallucinations: Why AI Sometimes Gets Things Wrong 🤖 Generative AI is incredibly powerful, but it's not always correct. One of the biggest challenges with AI is hallucination—when an AI model generates information that sounds convincing but is actually incorrect, misleading, or completely fabricated. 💡 Why do hallucinations happen? AI predicts the most likely next word based on patterns it learned during training. It doesn't "know" facts the way humans do, so when information is missing or ambiguous, it may confidently generate inaccurate answers. 🚨 Common causes ✅ Ambiguous or incomplete prompts ✅ Outdated training data ✅ Missing business context ✅ Complex reasoning across multiple topics 🛡️ How to reduce AI hallucinations ✔️ Provide clear and specific prompts ✔️ Include relevant context and reference material ✔️ Ask the model to cite sources when appropriate ✔️ Verify important information before making decisions ✔️ Use enterprise AI solutions like Microsoft 365 Copilot, which ground responses in your organization's authorized data while respecting permissions. 💼 Microsoft Perspective Microsoft's Copilot experience combines Large Language Models with enterprise data through grounding techniques, helping improve response relevance while still encouraging users to validate critical outputs. 🎯 Key Takeaway AI is an intelligent assistant—not an infallible expert. The best results come from combining AI with human judgment. 💬 Discussion: Have you ever encountered an AI hallucination? What techniques do you use to verify AI-generated content?66Views0likes0Comments🚀 Prompt Tuesday | Write Prompts Like a Pro
Prompt Tuesday | PT-002 | A small change in your prompt can dramatically improve AI responses. Instead of asking: ❌ "Summarize this document." Try this: ✅ "Summarize this document into 5 key points. Highlight risks, action items, and decisions. Keep the response under 200 words and format it as a table." 💡 Prompt Formula Role + Task + Context + Constraints + Output Format Example: Act as a Microsoft Solutions Architect. Review the following Azure migration proposal. Identify technical risks, suggest improvements, and present the findings in a table with Risk, Impact, and Recommendation. Why it works ✔ Gives AI a clear role ✔ Provides context ✔ Defines expectations ✔ Specifies the output format The more specific your prompt, the better the results. 💬 Challenge: Share one prompt that saves you time at work. Let's learn from each other!81Views0likes0Comments🧠 What is Retrieval-Augmented Generation (RAG)?
Have you ever wondered how AI tools answer questions using your company's documents instead of making things up? That's where Retrieval-Augmented Generation (RAG) comes in. Instead of relying only on what the AI learned during training, RAG first searches trusted sources—such as PDFs, SharePoint libraries, knowledge bases, or internal documentation—and then uses that information to generate a response. Why organizations use RAG ✅ Reduces hallucinations ✅ Uses the latest company knowledge ✅ Keeps responses grounded in trusted data ✅ Improves enterprise AI accuracy Common Microsoft stack Azure AI Search Azure OpenAI Microsoft Copilot SharePoint Microsoft Fabric RAG is one of the key building blocks behind modern enterprise AI assistants. 💬 Discussion: Have you implemented a RAG solution in your organization, or are you planning one?175Views0likes1Comment